
Text abstract generation method based on input sharing
A text and abstract technology, applied in the field of text abstract generation based on input sharing, to achieve the effect of improving training speed, improving model effect, and reducing memory usage
Patent Information
- Authority / Receiving Office
- CN · China
- Patent Type
- Applications(China)
- Current Assignee / Owner
- Publication Date
- 2022-07-22
Smart Images
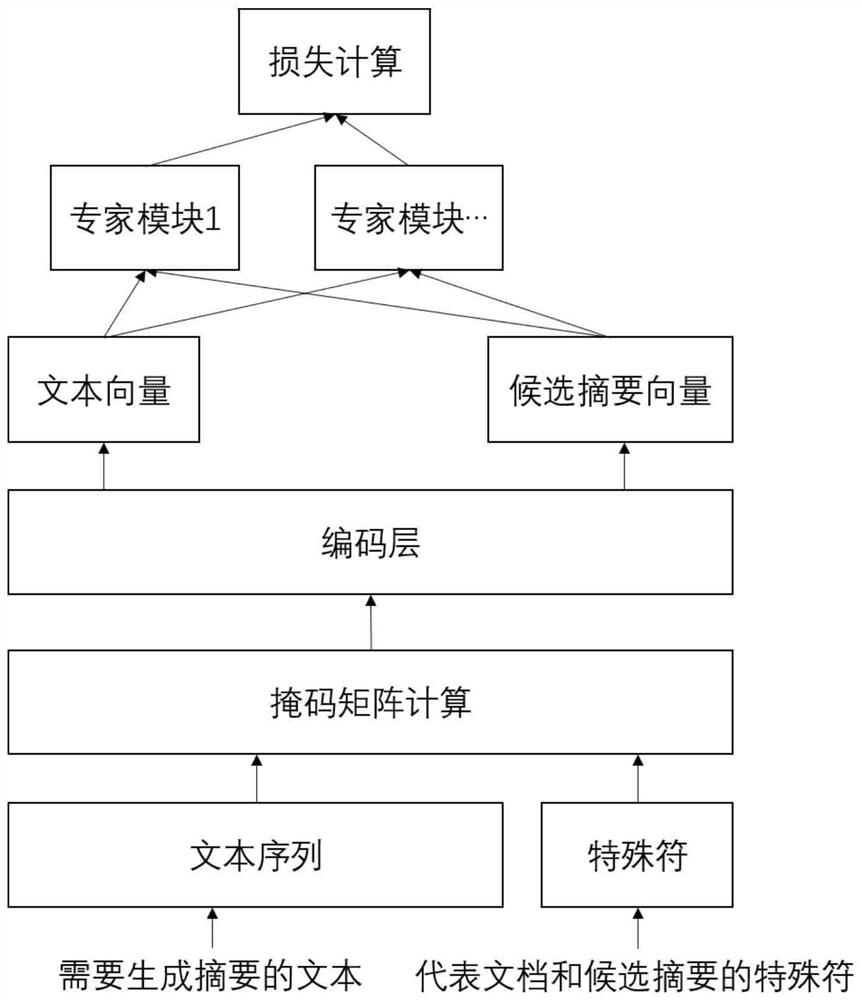
Figure 1 
Figure 2 
Figure 3
Abstract
Description
technical field
[0001] The present invention relates to deep learning and natural language processing, in particular to a method for generating text summaries based on input sharing. Background technique
[0002] Automatic text summarization refers to the process of using programs to process long texts to obtain summaries that retain the main semantics. With the entry into the era of big data with rapidly increasing data volume, automatic text summarization methods that can effectively reduce the number of words that need to be read have attracted more and more attention. The current automatic text summarization methods can be divided into two categories: generative summarization methods and extractive summarization methods. The generative summarization method generates a summary based on the original text, and can generate new words that are not in the original text, while the extractive summarization method extracts from the original text. Take part of sentences or snippe...
Examples
Embodiment 1
[0063] A text summarization method based on input sharing, such as figure 1 shown, including the following steps:
[0064] S1. An extractive summary generation algorithm based on the sentence level, calculates the text to obtain a sentence, and combines the sentences to obtain a plurality of candidate summary texts, and then obtains a candidate summary data set, as follows:
[0065] Obtain multiple texts and use an open-source sentence-level extractive text summary generation algorithm. In this embodiment, BertSumExt (Text Summarization with Pretrained Encoders) is used to process and calculate each text, and obtain a high score in the text. The maximum number of sentences is 10, and then T candidate summary texts corresponding to the text are obtained for every 2 sentences or every 3 sentences of the obtained sentences;
[0066] Obtain the real scores of the T candidate abstract texts corresponding to each text, and obtain a candidate abstract data set including the original...
Embodiment 2
[0111] In this embodiment, the difference from Embodiment 1 is that in step S1, DiscoBert (Discourse-Aware Neural Extractive Text Summarization) is used to process and calculate each text, and obtain the text with the highest score ranking in the text. 10 sentences, and then combine every 2 sentences or every 3 sentences of the obtained sentences to obtain T candidate abstract texts corresponding to the text;
[0112] Obtain the real scores of the T candidate abstract texts corresponding to each text, and obtain a candidate abstract data set including the original text, the T candidate abstract texts corresponding to the original text, and the real scores of the T candidate abstract texts corresponding to the original text.
[0113] Obtain the reference abstract corresponding to the text, compare the candidate abstract text with the reference abstract, calculate the ROUGE-1 score, ROUGE-2 score and ROUGE-L score respectively, and calculate the average of the three as the real s...
Embodiment 3
[0116] In this embodiment, the difference from Embodiment 1 is that in step S1, Hetformer (Hetformer: Heterogeneous transformer with sparse attention for long-text extractivesummarization) is used to process and calculate each text to obtain the Score up to 10 sentences with high rankings, and then obtain T candidate summary texts corresponding to the text for every 2 sentences or every 3 sentence combinations of the obtained sentences;
[0117]Obtain the real scores of the T candidate abstract texts corresponding to each text, and obtain a candidate abstract data set including the original text, the T candidate abstract texts corresponding to the original text, and the real scores of the T candidate abstract texts corresponding to the original text.
[0118] Obtain the reference abstract corresponding to the text, compare the candidate abstract text with the reference abstract, calculate the ROUGE-1 score, ROUGE-2 score and ROUGE-L score respectively, and calculate the average...