
Improved multidimensional scaling heterogeneous cost-sensitive decision tree building method
A cost-sensitive, construction method technology, applied in structured data retrieval, special data processing applications, instruments, etc., can solve the problem of low test cost, reduce the cost of misclassification, improve efficiency, and strengthen the classification ability.
Patent Information
- Authority / Receiving Office
- CN · China
- Current Assignee / Owner
- Publication Date
- 2017-05-03
- Estimated Expiration
- Not applicable · inactive patent
Smart Images
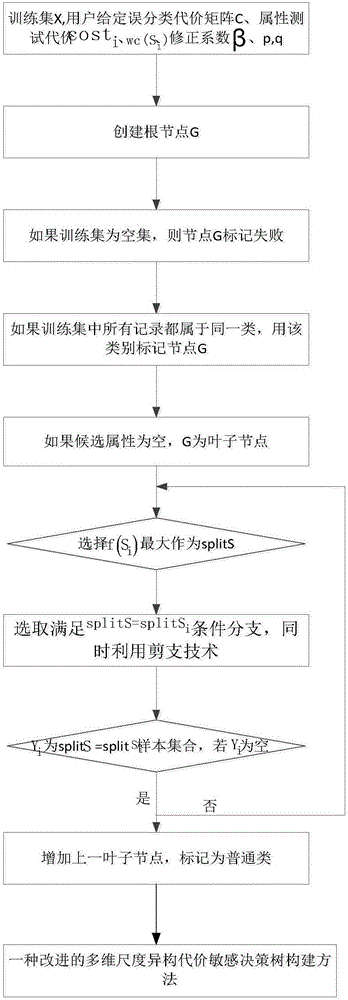
Figure 1 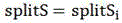
Figure 2 
Figure 3
Abstract
Description
technical field
[0001] The invention relates to the fields of machine learning, artificial intelligence and data mining. Background technique
[0002] The topic of decision trees is an important and active research topic in data mining and machine learning. The proposed algorithm is widely and successfully applied in practical problems such as ID 3 , CART and C4.5, classic algorithms such as decision trees mainly study the problem of accuracy, and the generated decision trees have higher accuracy. In the existing algorithms, some only consider the test cost, and some only consider the misclassification error cost. This type is called one-dimensional scale cost sensitive, and the decision tree constructed by it cannot solve the comprehensive problem in real cases. For example, in cost-sensitive learning, in addition to the impact of test cost and misclassification cost on classification, the impact of waiting time cost on classification prediction also needs to be considere...
Examples
Embodiment Construction
[0031] Aiming at solving the problem of constructing a multi-dimensional scale decision tree process by considering the test cost, misclassification cost and waiting time cost influencing factors at the same time, the test cost is lower, the decision tree has better scalability, and the difference in cost The final decision tree generated by the unit mechanism problem better avoids the overfitting problem, combined with figure 1 The present invention has been described in detail, and its specific implementation steps are as follows:
[0032] Step 1: Suppose there are X samples in the training set, and the number of attributes is n, that is, n=(S 1 , S 2 ,…S n ), while splitting the attribute S i Corresponds to m classes L, where L r ∈(L 1 , L 2 ...,L m ), i ∈ (1, 2..., n), r ∈ (1, 2..., m). Users in related fields set the misclassification cost matrix C and attribute S i The test cost is cost i ,,wc(S i )—relative waiting time cost value, correction coefficient β, a...