
Small file storage method based on Hadoop distributed file system
A distributed file and small file technology, applied in the computer field, can solve the problem of low memory usage and storage access efficiency, and achieve the effect of satisfying low-latency access, reducing storage burden, and high efficiency
Patent Information
- Authority / Receiving Office
- CN · China
- Current Assignee / Owner
- Publication Date
- 2014-06-11
Smart Images
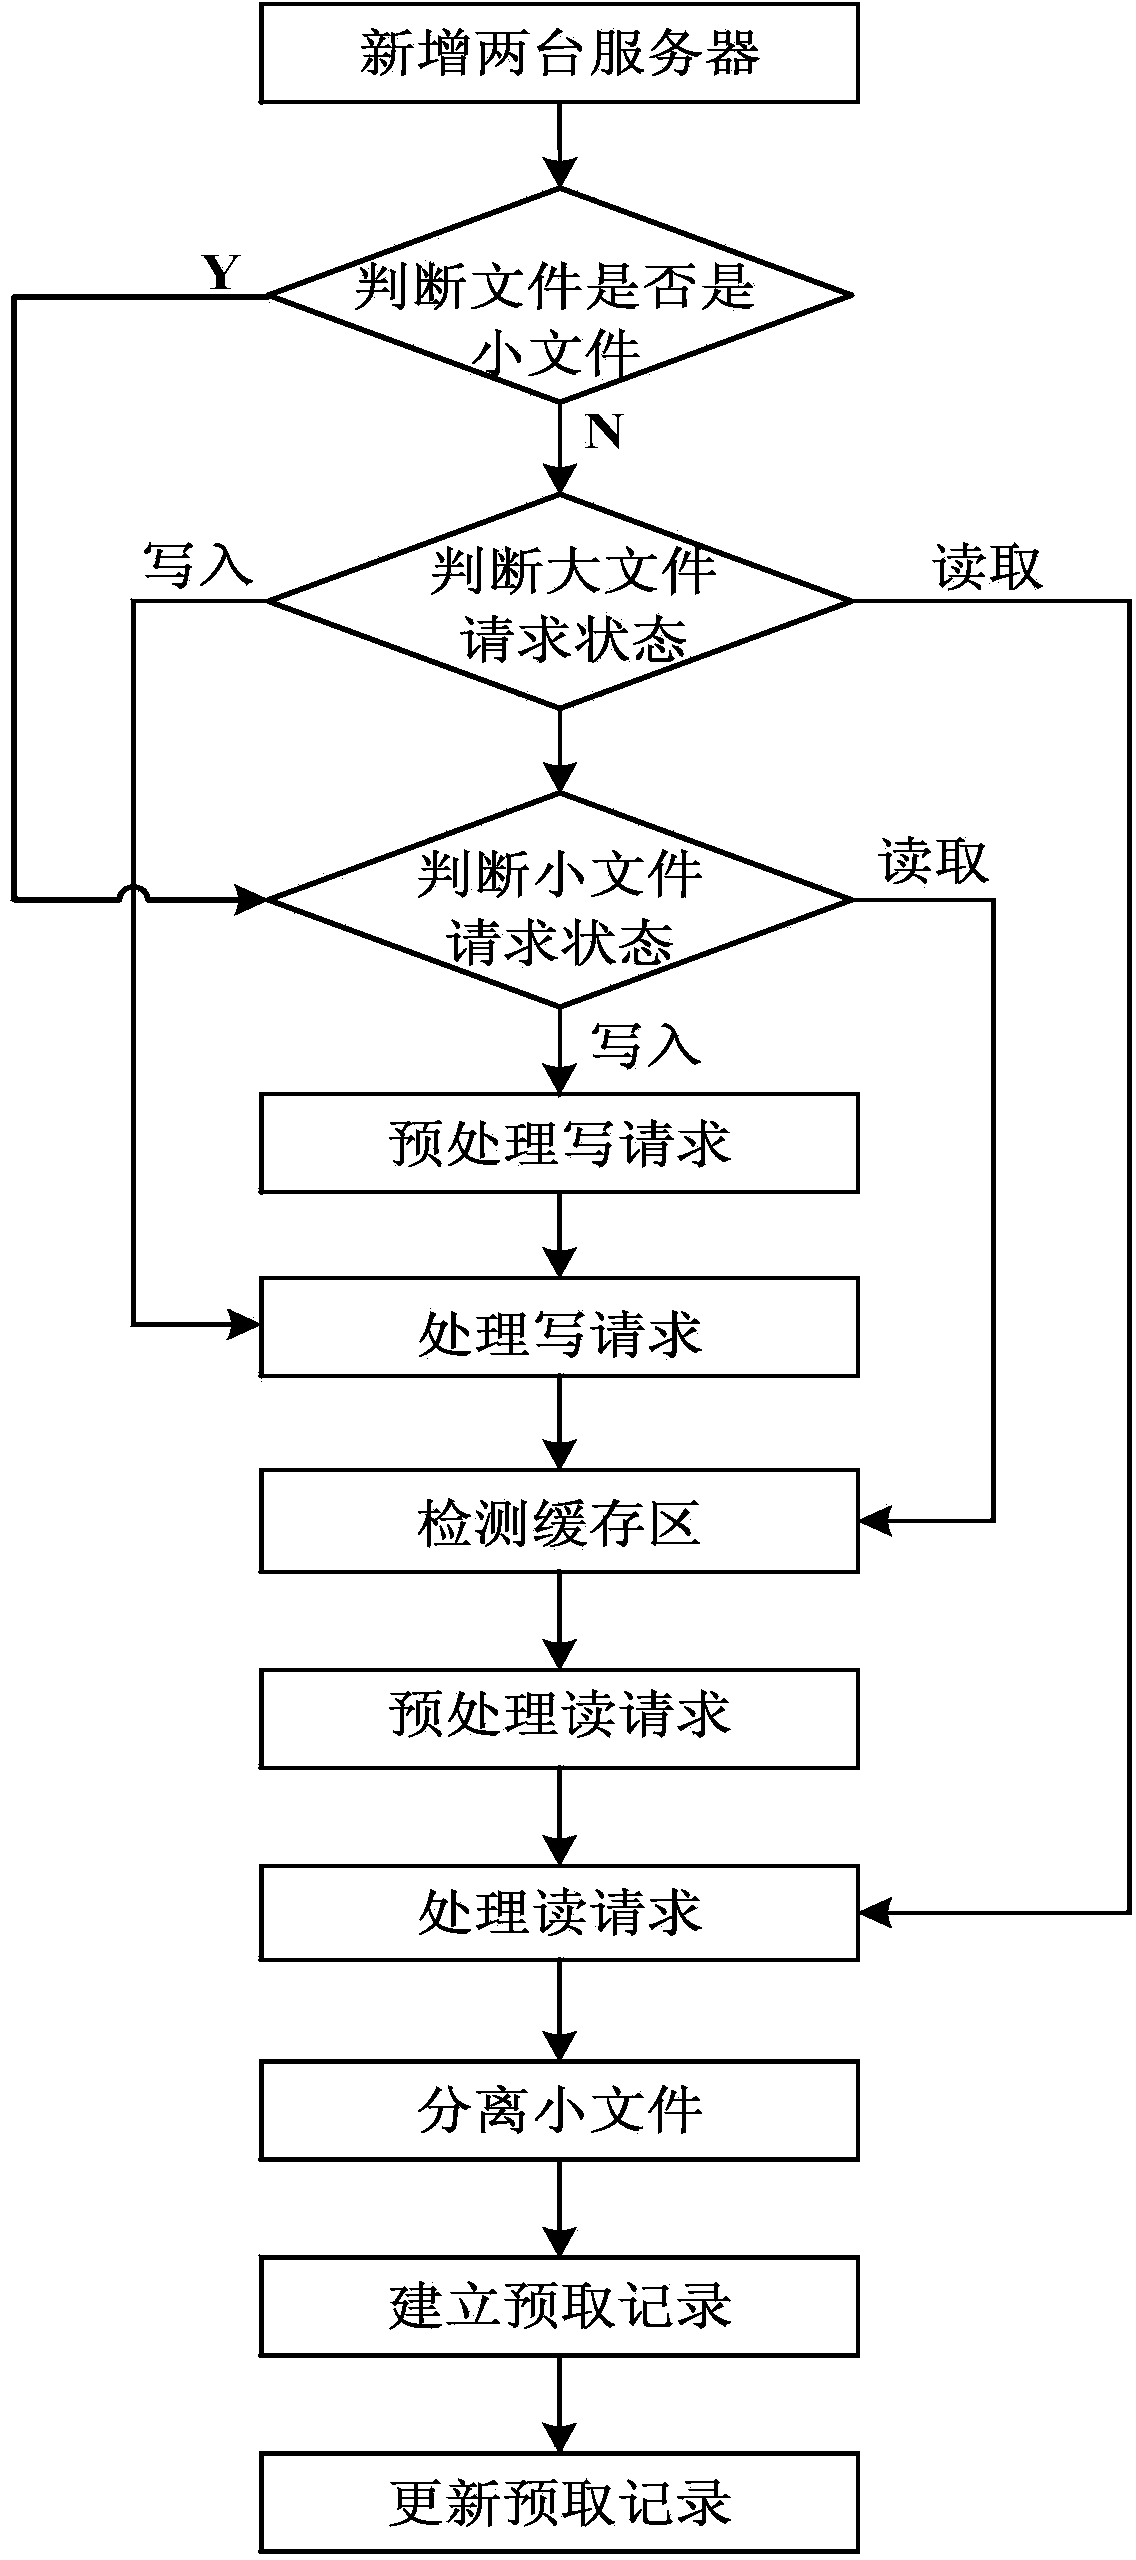
Figure 1 
Figure 2 
Figure 3
Abstract
Description
technical field
[0001] The invention belongs to the field of computer technology, and further relates to a small file storage method based on a Hadoop distributed file system (Distributed File System DFS) in the field of computer distributed data optimization storage. The invention uses a small file processing server independent of the HDFS system to perform operations such as merging, mapping, and prefetching of small files, and can be applied to efficiently store and access a large number of small files. Background technique
[0002] Hadoop Distributed File System, HDFS for short, is a distributed file system. At present, in the field of distributed file storage technology represented by HDFS, HDFS is widely used to efficiently process various large files. However, with the change of user needs, the number of small files is increasing, and the interaction between users and Namenode is becoming more and more frequent. . Due to HDFS's own master-slave structure and metadat...
Examples
Embodiment Construction
[0042] The present invention will be further described below in conjunction with the accompanying drawings.
[0043] refer to figure 1 , the specific implementation steps of the present invention are as follows:
[0044] Step 1, add two new services.
[0045] In addition to the Hadoop distributed file system HDFS, add a web server Websever for monitoring file read and write requests, and add a small file processing server for processing small files: the system architecture of the present invention consists of web server Websever, The small file processing server and the original HDFS system are composed of three parts. The small file processing server mainly performs operations such as file merging, file mapping, and file prefetching on small files.
[0046] Step 2, judging whether the file is a small file.
[0047] The web server Websever judges whether the monitored request file is a file smaller than 16M, if it is smaller than 16M, it is regarded as a small file, and ste...