
A method and system for constructing a distributed log of big data
A distributed, big data technology, applied in the field of big data processing, can solve problems such as inability to meet real-time performance, performance bottlenecks, log data loss, etc., to achieve flexibility and reliability, good scalability and stability, and system internal The effect of flexible networking
Patent Information
- Authority / Receiving Office
- CN · China
- Patent Type
- Patents(China)
- Current Assignee / Owner
- Publication Date
- 2019-02-26
Smart Images
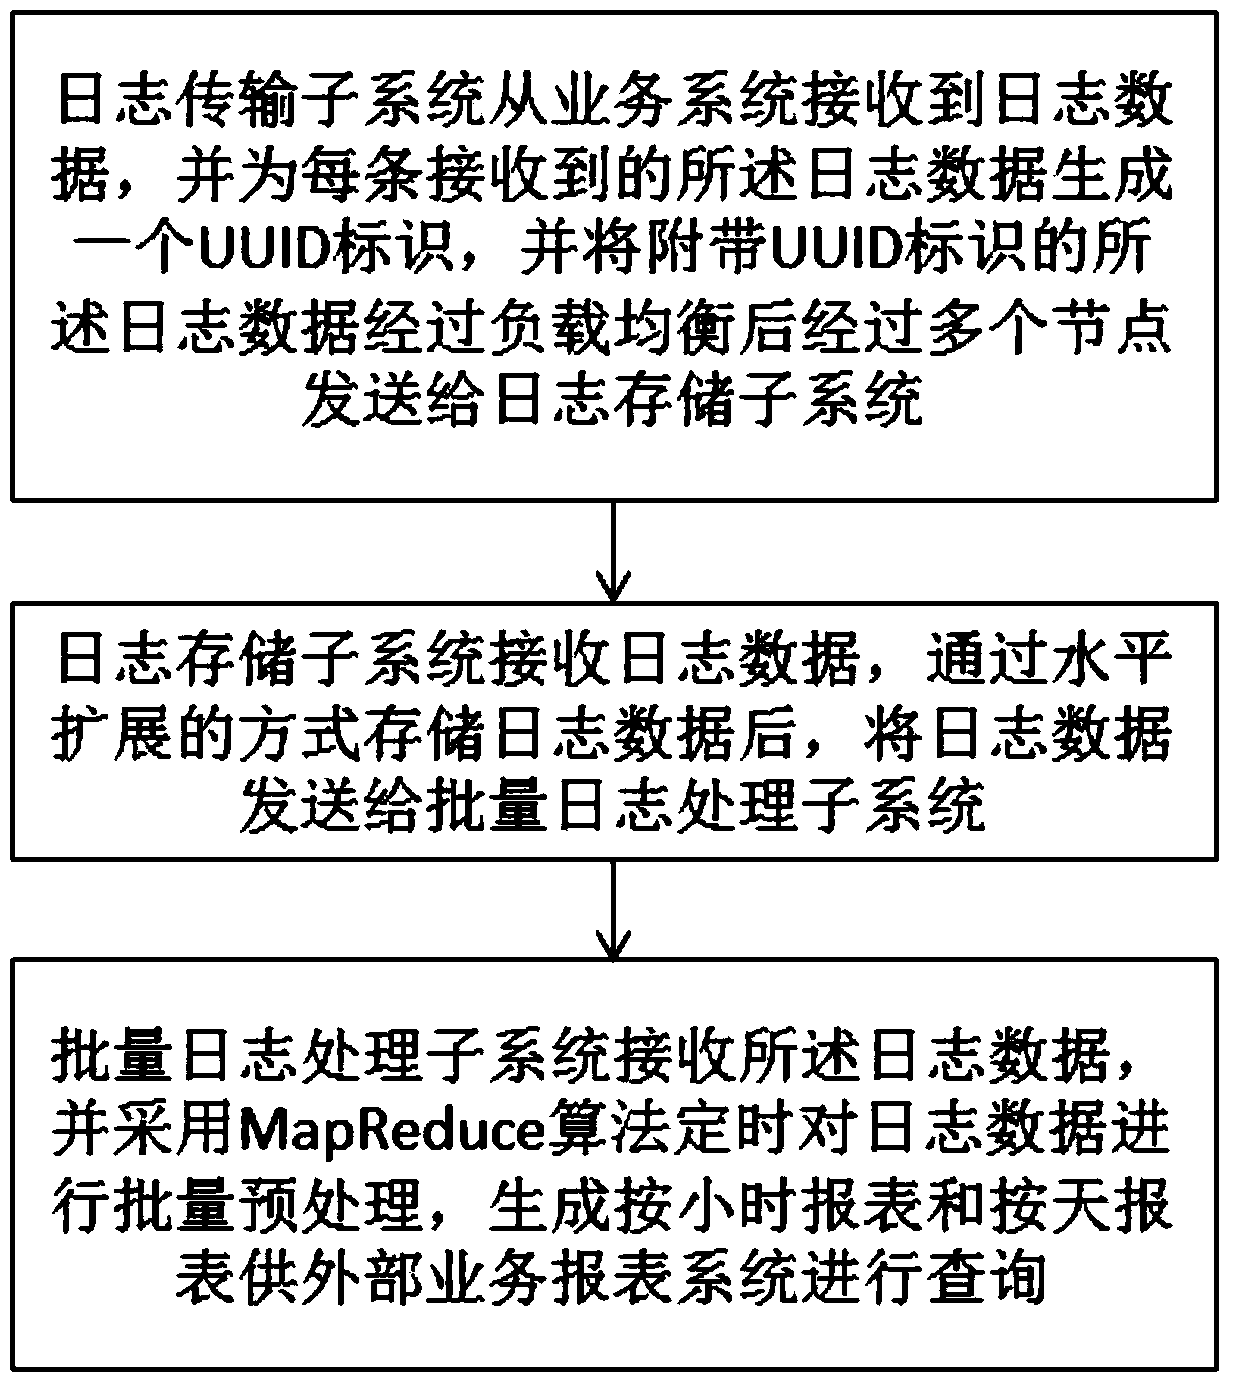
Figure 1 
Figure 2 
Figure 3
Abstract
Description
technical field
[0001] The invention relates to the field of big data processing, in particular to a method and system for constructing a big data distributed log. Background technique
[0002] In general software systems, there is no special independent system for processing logs. Existing software systems simply write logs to local disks or synchronize them to relational databases for future retrieval needs. However, in a large-scale system with a large business volume, high concurrency, and many server clusters, the above simple log processing method can no longer meet the requirements. The above log processing method has the following disadvantages:
[0003] The first is unreliability; because a large-scale system is a cluster composed of many servers, it is common for a server node in the cluster to fail, and the important log data stored on the failed server may be lost, and the traditional The current log backup method is generally to perform regular backups every da...
Examples
Embodiment Construction
[0057] The principles and features of the present invention are described below in conjunction with the accompanying drawings, and the examples given are only used to explain the present invention, and are not intended to limit the scope of the present invention.
[0058] figure 1 It is a flow chart of the method for constructing a big data distributed log according to the present invention.
[0059] Such as figure 1 As shown, a method for constructing a distributed log of big data includes the following steps:
[0060] Step S1, the log transmission subsystem receives the log data from the business system, generates a UUID identifier for each received log data, and sends the log data with the UUID identifier through multiple nodes after load balancing to the log storage subsystem;
[0061] Step S2, the log storage subsystem receives the log data, stores the log data through horizontal expansion, and then sends the log data to the batch log processing subsystem;
[0062] St...