
Patents
Literature
36 results about "Language independence" patented technology
Efficacy Topic
Property
Owner
Technical Advancement
Application Domain
Technology Topic
Technology Field Word
Patent Country/Region
Patent Type
Patent Status
Application Year
Inventor
This term Language Independent means one can create an application using various languages. (OLE & ActiveX) to present .Net.Let us see in detail. Advantages of Language Independent: First, it helps in split up large systems into manageable subsystems early in the design phase.
Systems for and methods of modeling, step-testing, and adaptively controlling in-situ building components
InactiveUS20150178421A1Efficient and accurateQuick exportGeometric CADSpace heating and ventilation safety systemsEnvironmental SettingMeasuring output
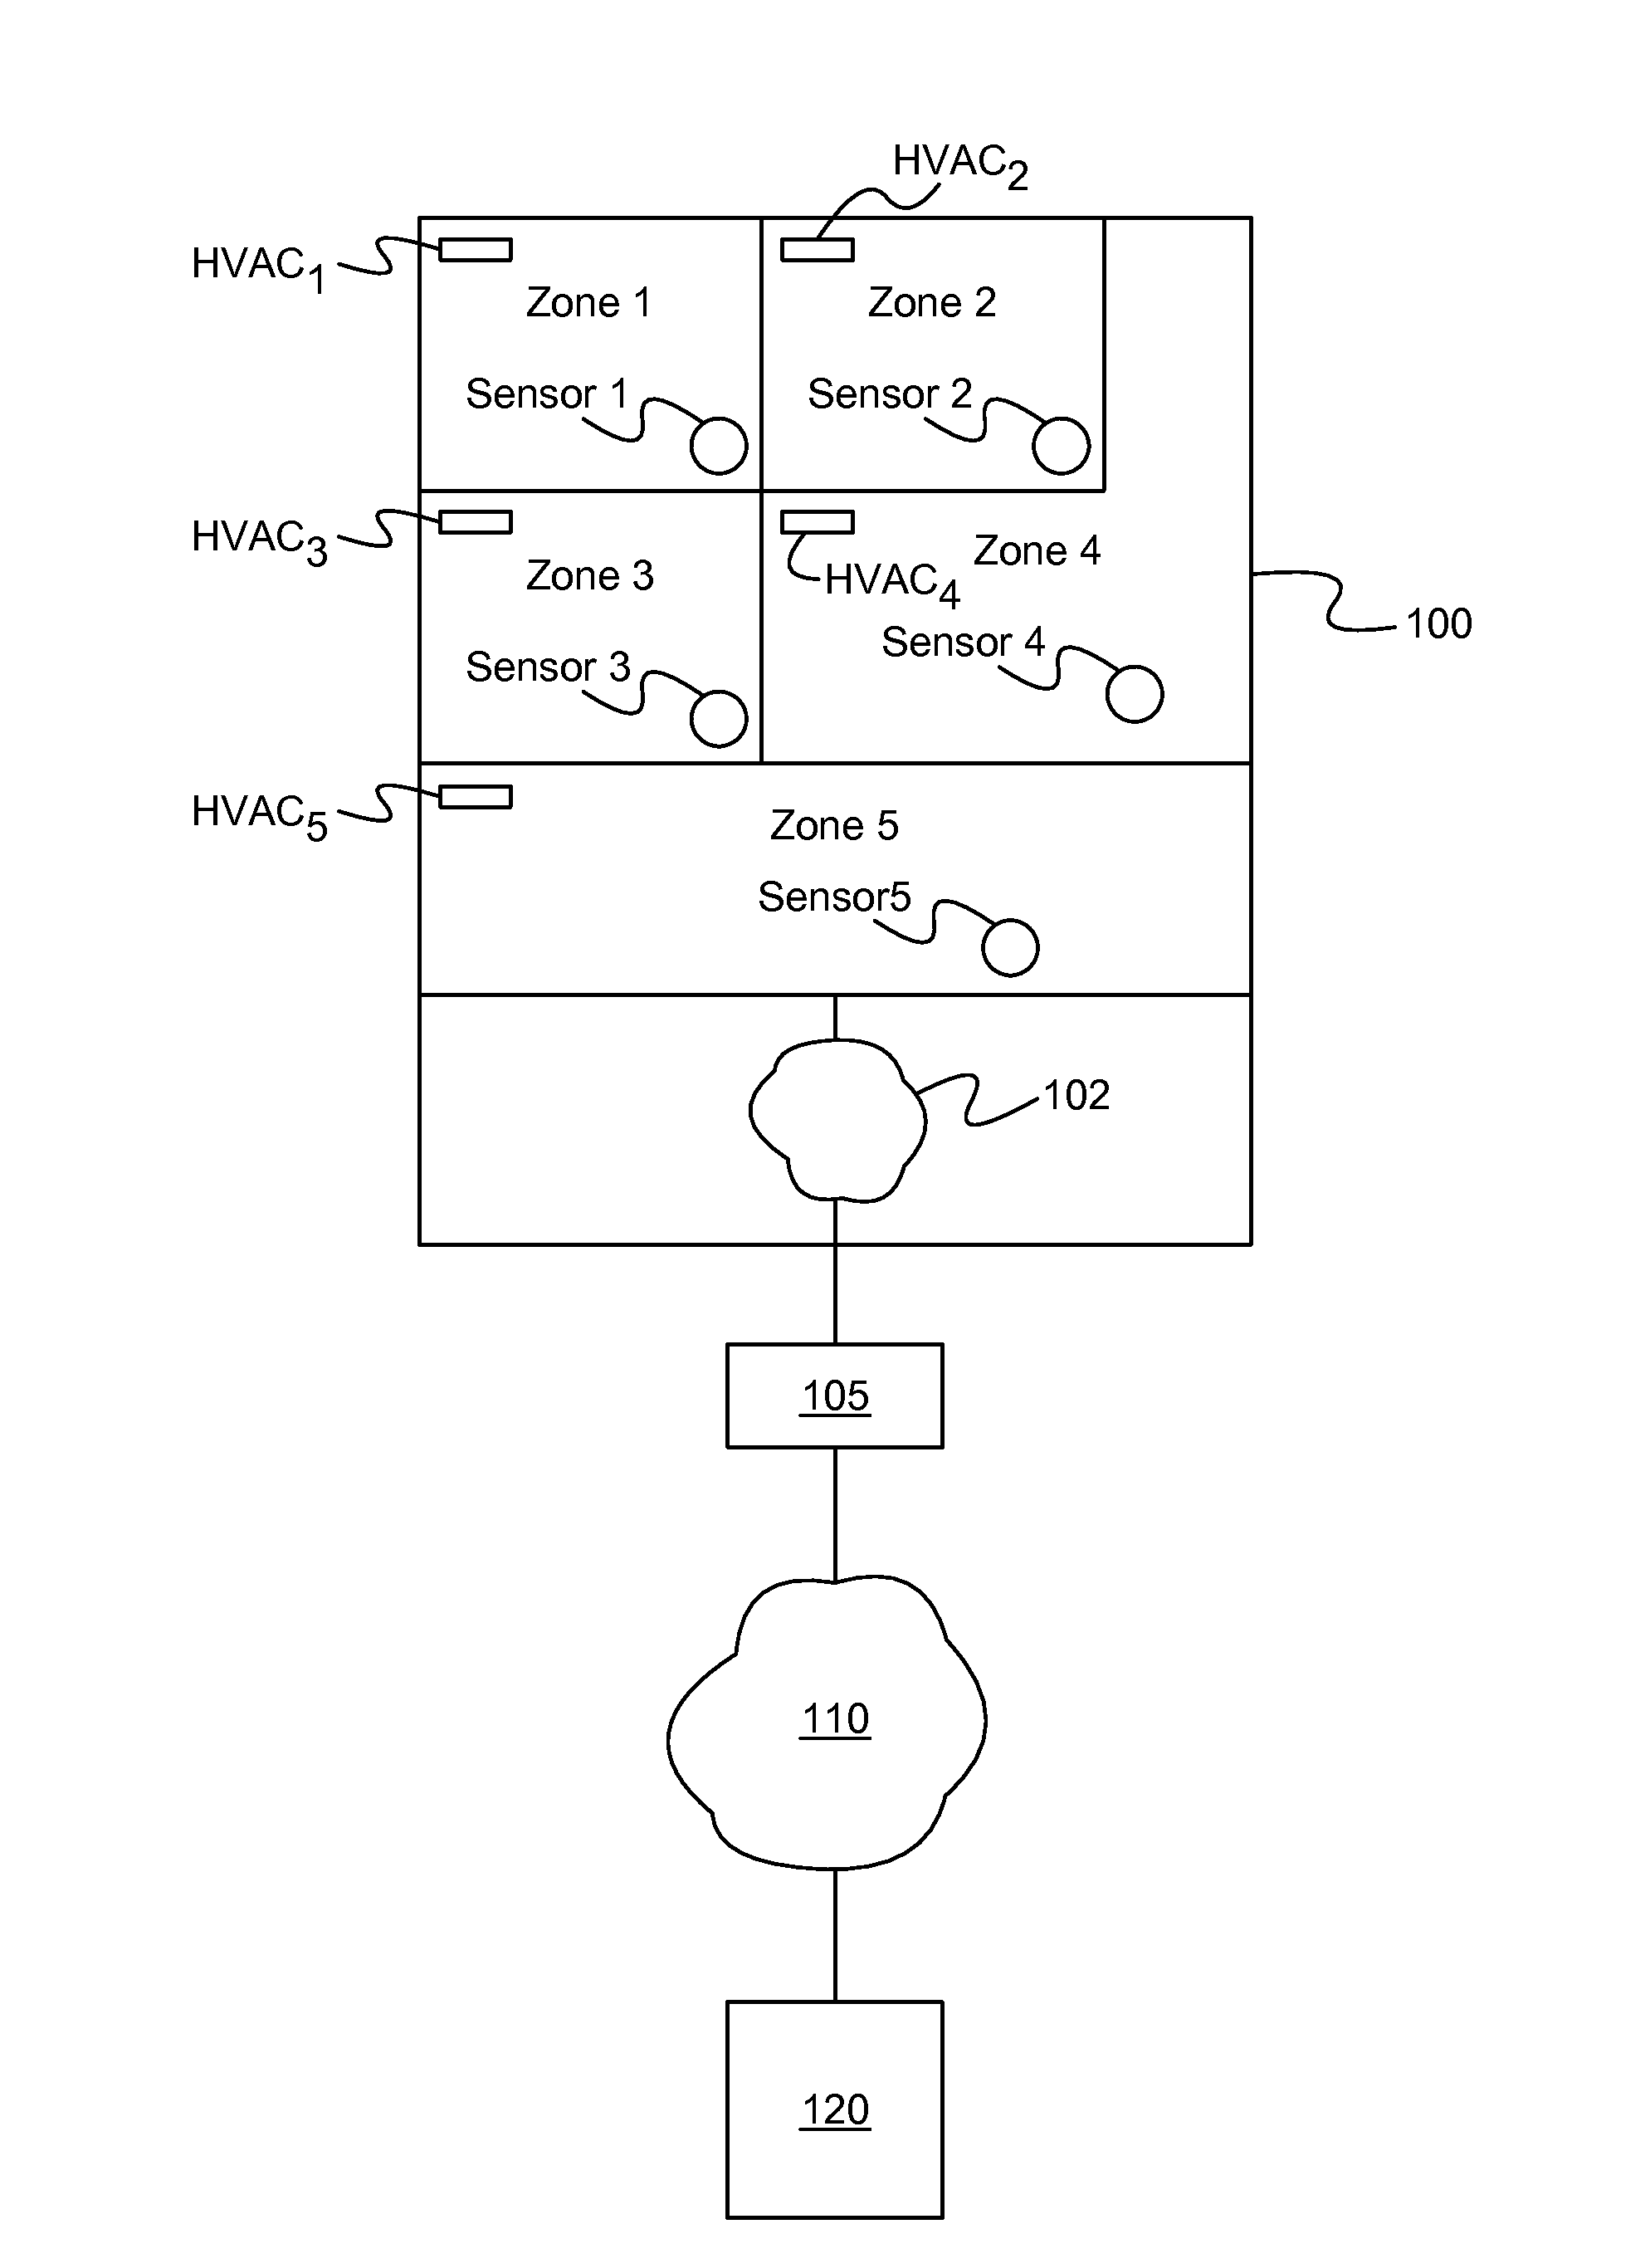
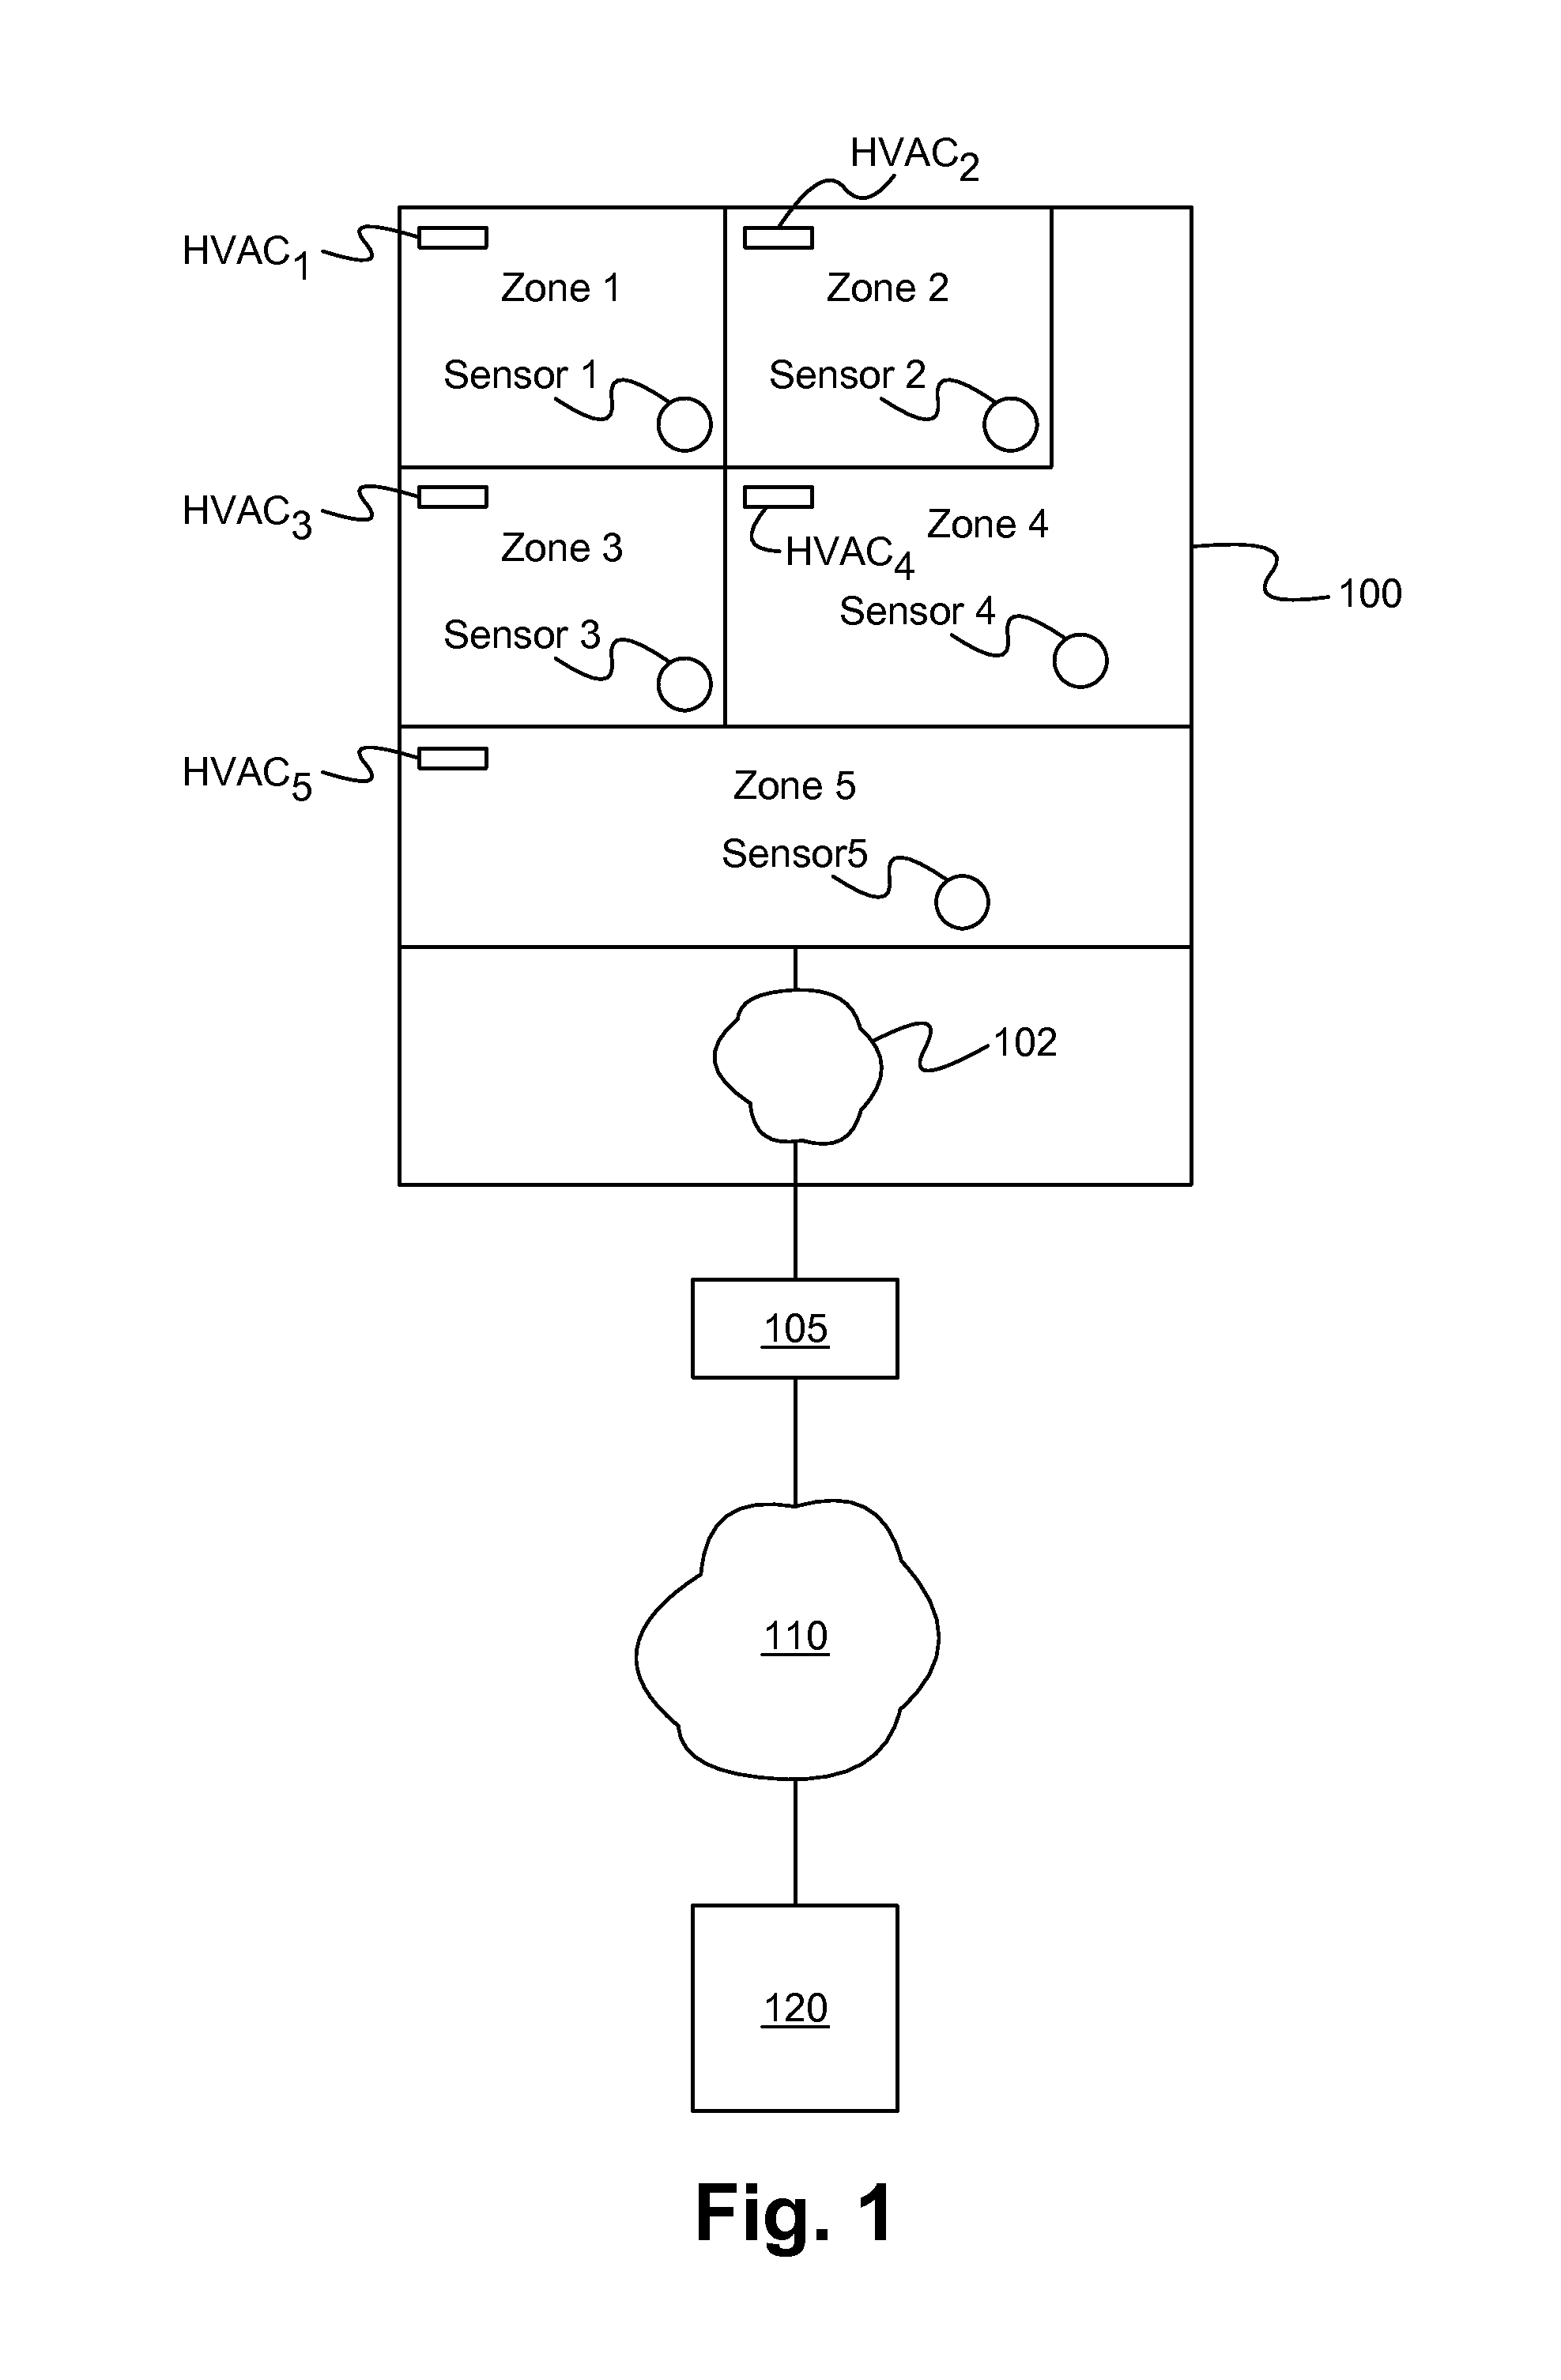
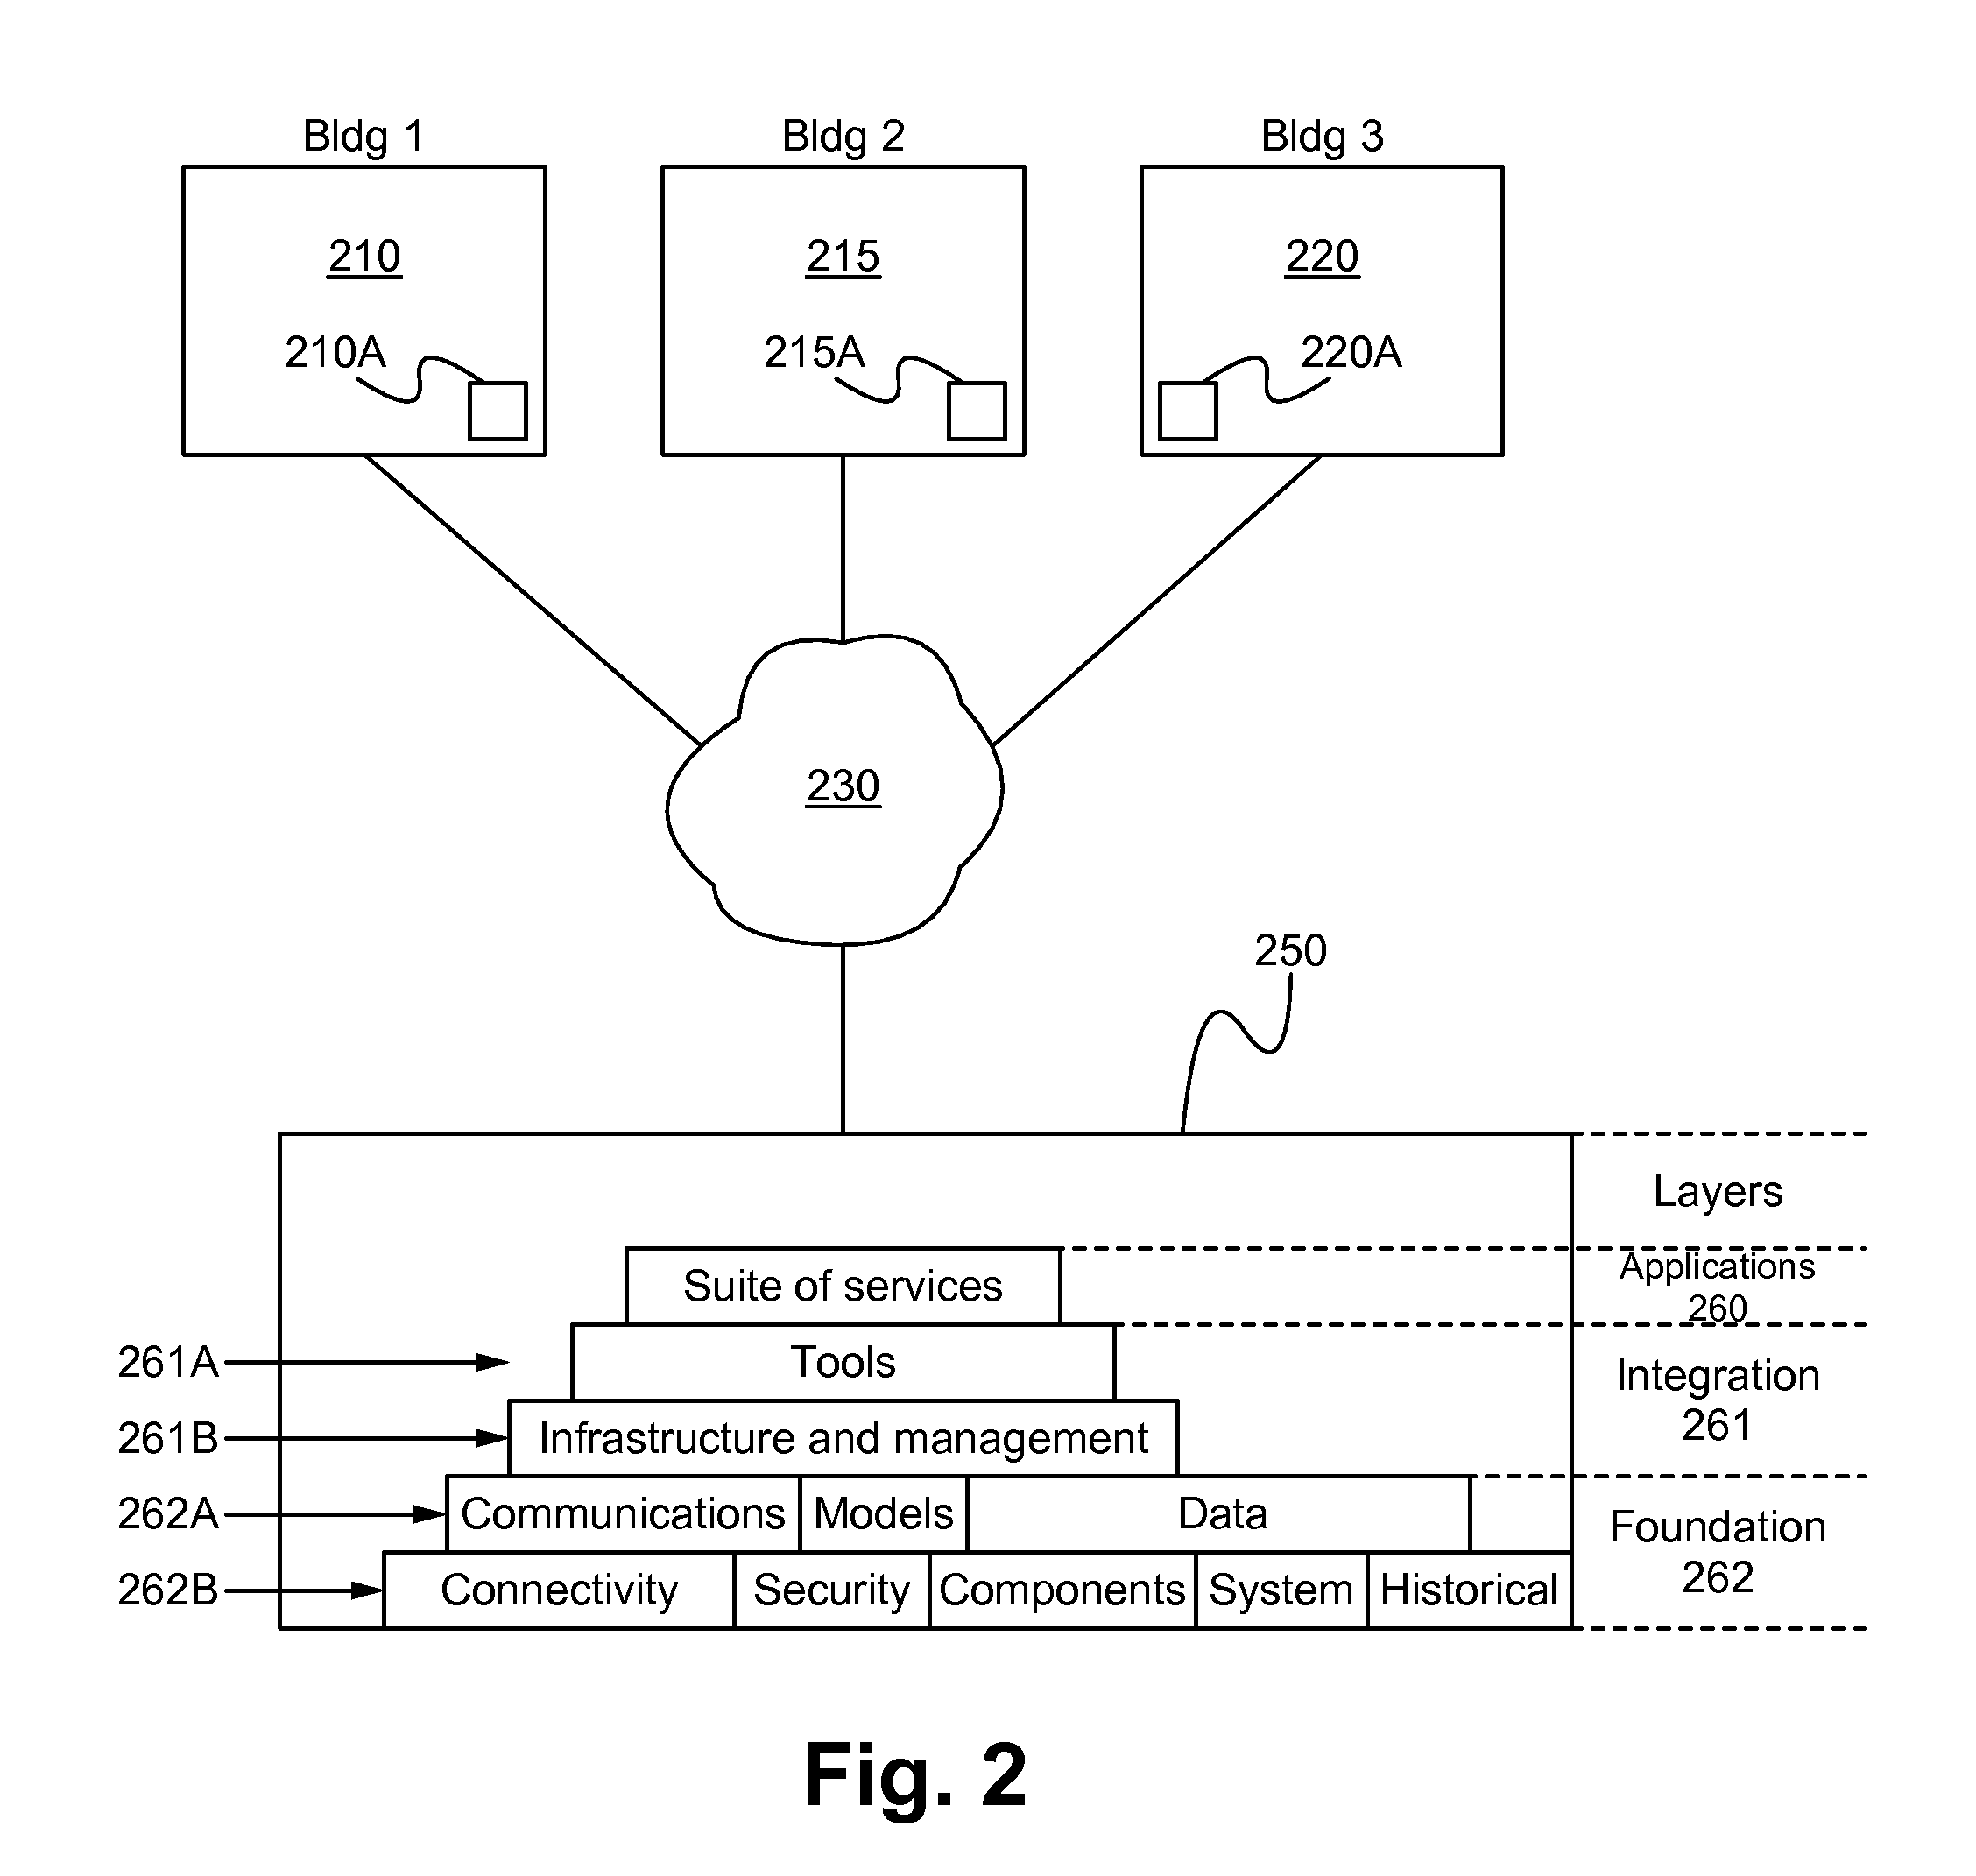
A system for and method of modeling thermal performance characteristics of HVAC components in a building uses the building power or other meter to measure power consumed by the components. The models are used to test the components, preferably during off hours, to ensure proper and efficient operation. Preferably, the testing software is written in a high-level interpretive language that is independent of the HVAC component being modeled. The models are adaptively maintained by periodically ensuring that their measured output matches the predicted output. When the two do not match, the model parameters are updated. These models can also be used to generate reports comparing costs and cost savings for different temperature and other environmental settings within selected zones in the building.
Owner:NEXTRACKER LLC
System and method to permit language independence for web interfaces
ActiveUS20110209047A1Natural language data processingExecution for user interfacesEvent triggerDocumentation
A device user interface in which language is decoupled from a document is disclosed. The language content is stored separately from the document structure and may be located on a content specific server or on a language server. The language server permits centralized collection of language-related content and language services. The document without the language content acts like a template that can be populated with any type of language-related content. The language content can be provided in a separate file together with associated identifiers, and can be loaded into a cache or document object model (DOM) for processing. An XML file may be used for the language file, and the document may be constructed using HTML code. Document components can be assigned event handlers that cause pop-up boxes to be loaded and displayed with language-related content upon an event trigger.


Owner:SANGOMA US INC
System and method for platform-independent, script-based application generation for spreadsheet software
A script-based application generation for spreadsheet software reads from one or more spreadsheets rendered by a spreadsheet program, description written in said text-based language, the text-based language for describing user interfaces, data models and / or workflow models or combinations thereof The text-based language is independent of the spreadsheet program. The description is parsed and from the description one or more user interfaces, data model or workflow model or combinations thereof are generated in the spreadsheet program.


Owner:IBM CORP
Automatically Identifying Unique Language Independent Keys Correlated With Appropriate Text Strings of Various Locales By Value and Key Searches
InactiveUS20090030674A1Improve efficiencyShorten the timeNatural language data processingExecution for user interfacesText stringLanguage independence
A method, system and computer program product for automatically identifying unique language independent keys. A “value search” is performed which provides a listing of values for a locale. Upon the user selecting a value in the listing, a “key search” is performed to search for various language independent keys associated with the selected value. A second locale is suggested as well as a listing of values for the second locale that are the same in meaning as the value selected by the user for the first locale in order to narrow the number of language independent keys displayed in connection with the value selected for the first locale. Upon the user selecting a value for the second locale, a subsequent key search is performed on the language independent keys displayed in connection with the first value. A unique language independent key may be identified based on this subsequent key search.


Owner:IBM CORP
Generalized Language Independent Index Storage System And Searching Method
InactiveUS20080263015A1Television system detailsDigital data information retrievalLanguage independenceDatabase
The invention may be embodied as a system having and / or a method utilizing a searchable database of index information. Each index in the database may have (a) at least one descriptor, which matches an entry that a user might provide in order to identify an item, (b) a first pointer which identifies a location of the item, and (c) a second pointer which identifies a location of information that may be helpful to the user in deciding whether to request retrieval of the item. The first pointers of one index may be the same as first pointers in a different index. The second pointer may identify a general class to which an item belongs.


Owner:ZI CORPORATION OF CANADA INC
Language translating method and system
InactiveCN1530861ANatural language translationDigital data processing detailsWireless mobile devicesLanguage independence


Owner:MICROSOFT TECH LICENSING LLC
Automatic language independent triphone training using a phonetic table
ActiveUS7289958B2Optimal clustering of the triphone phonetic model parametersImprove speech recognition performanceSpeech recognitionVocal tractAcoustic model
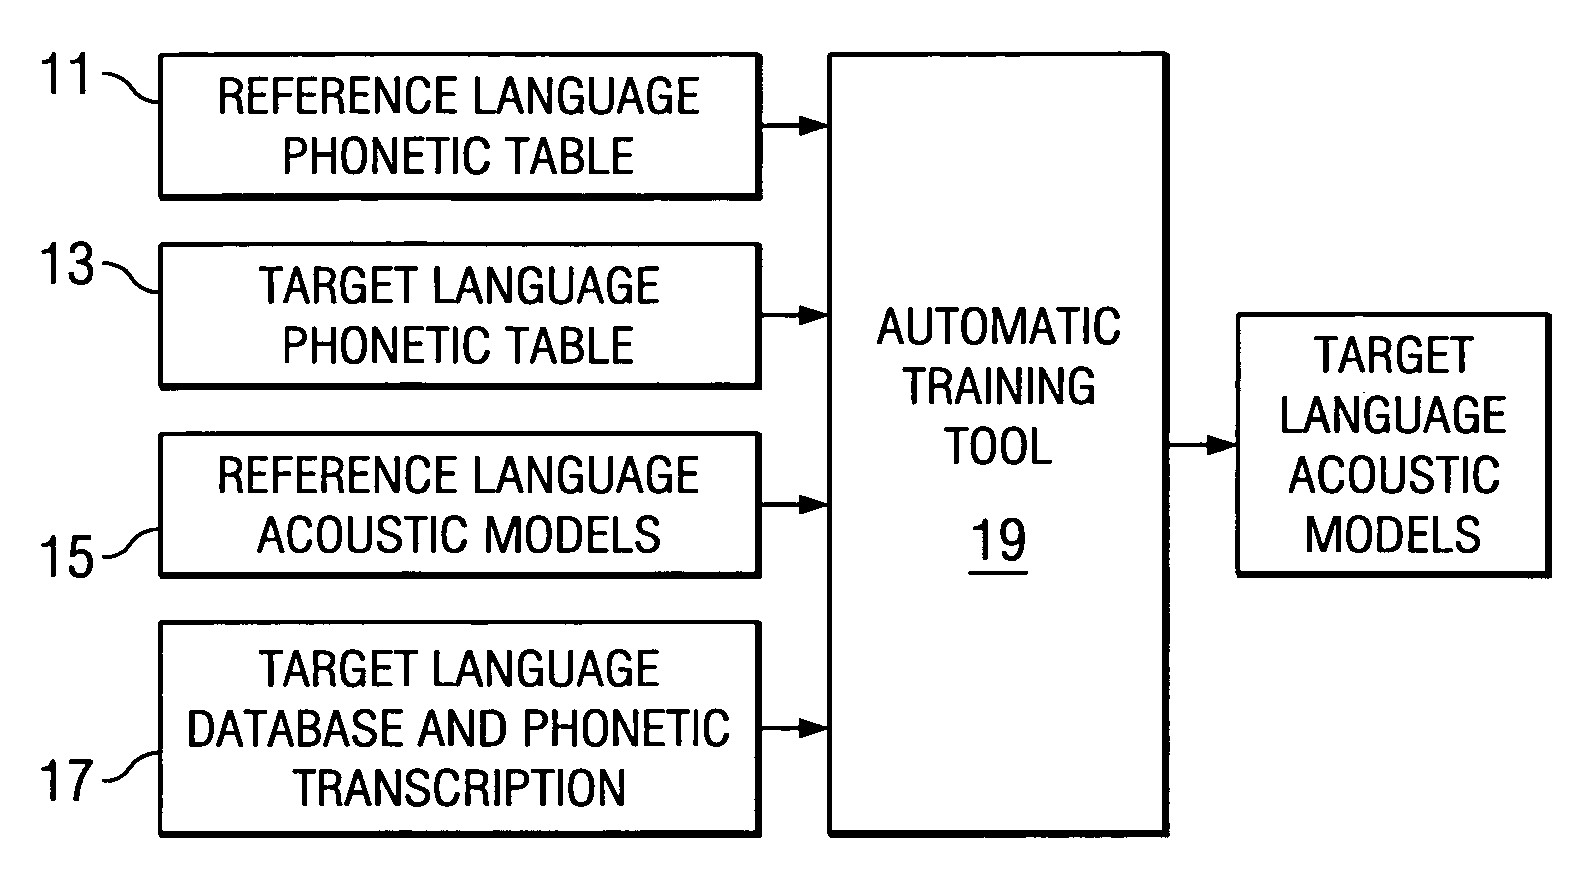
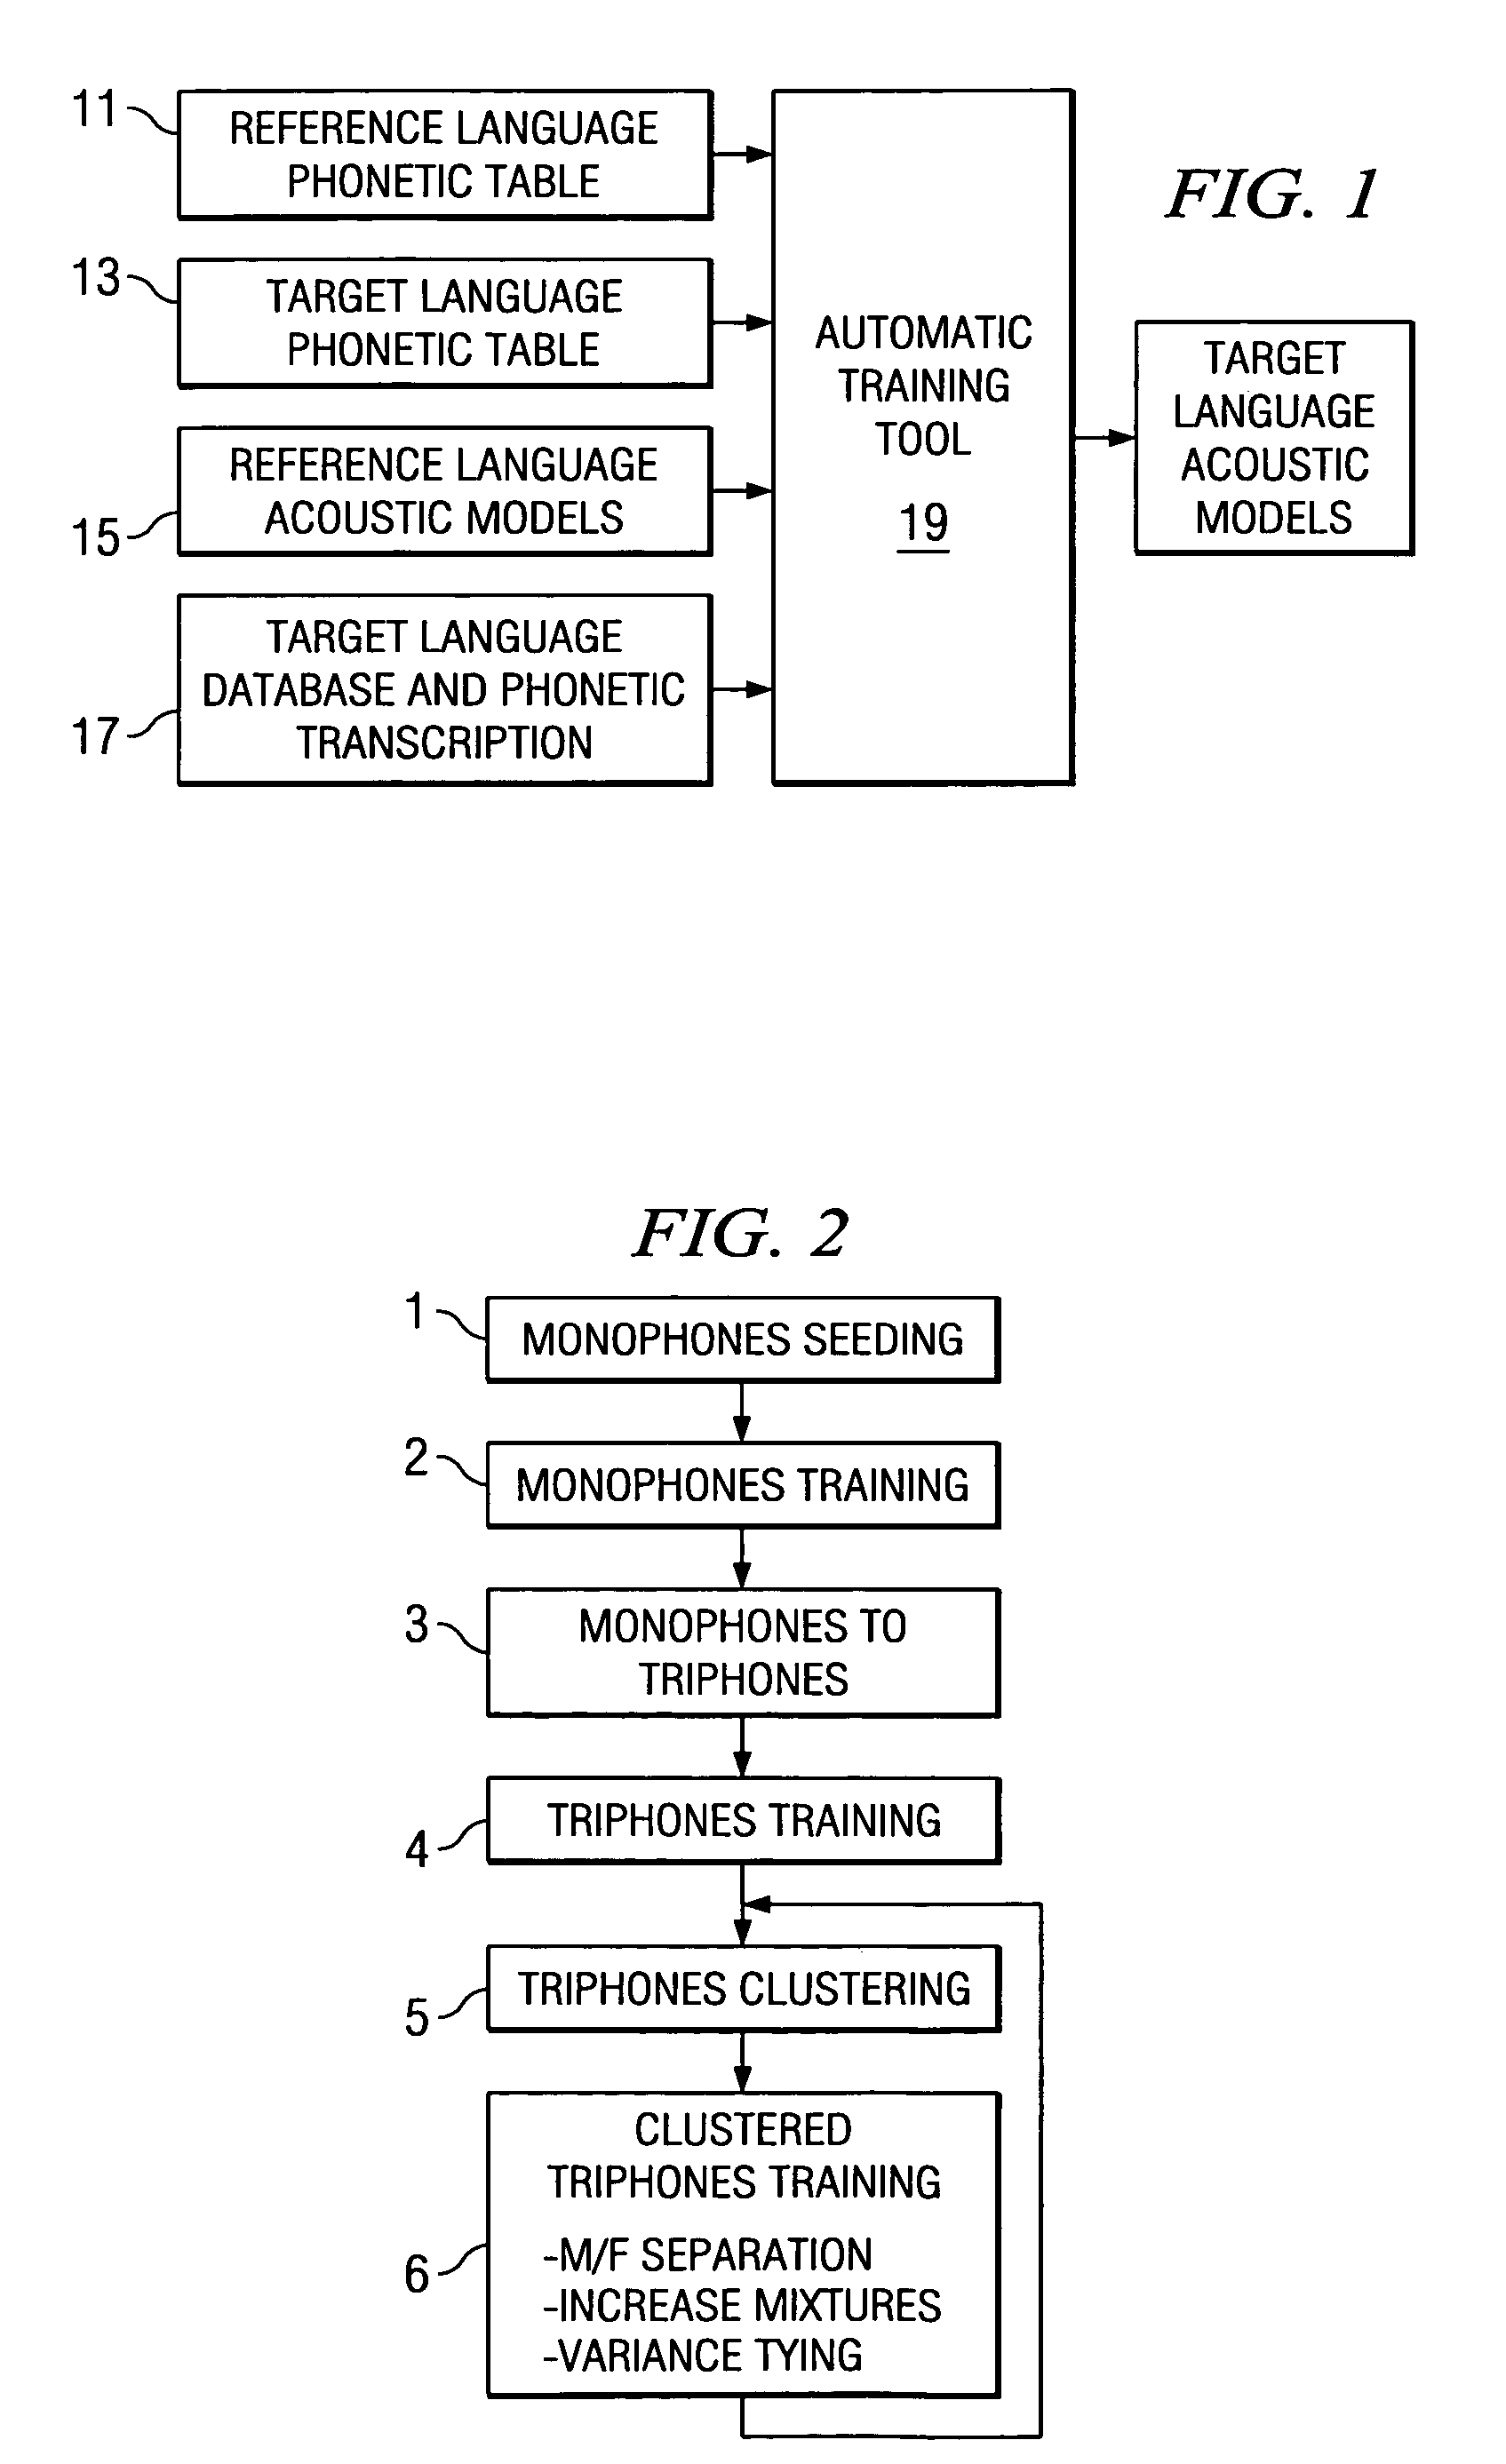
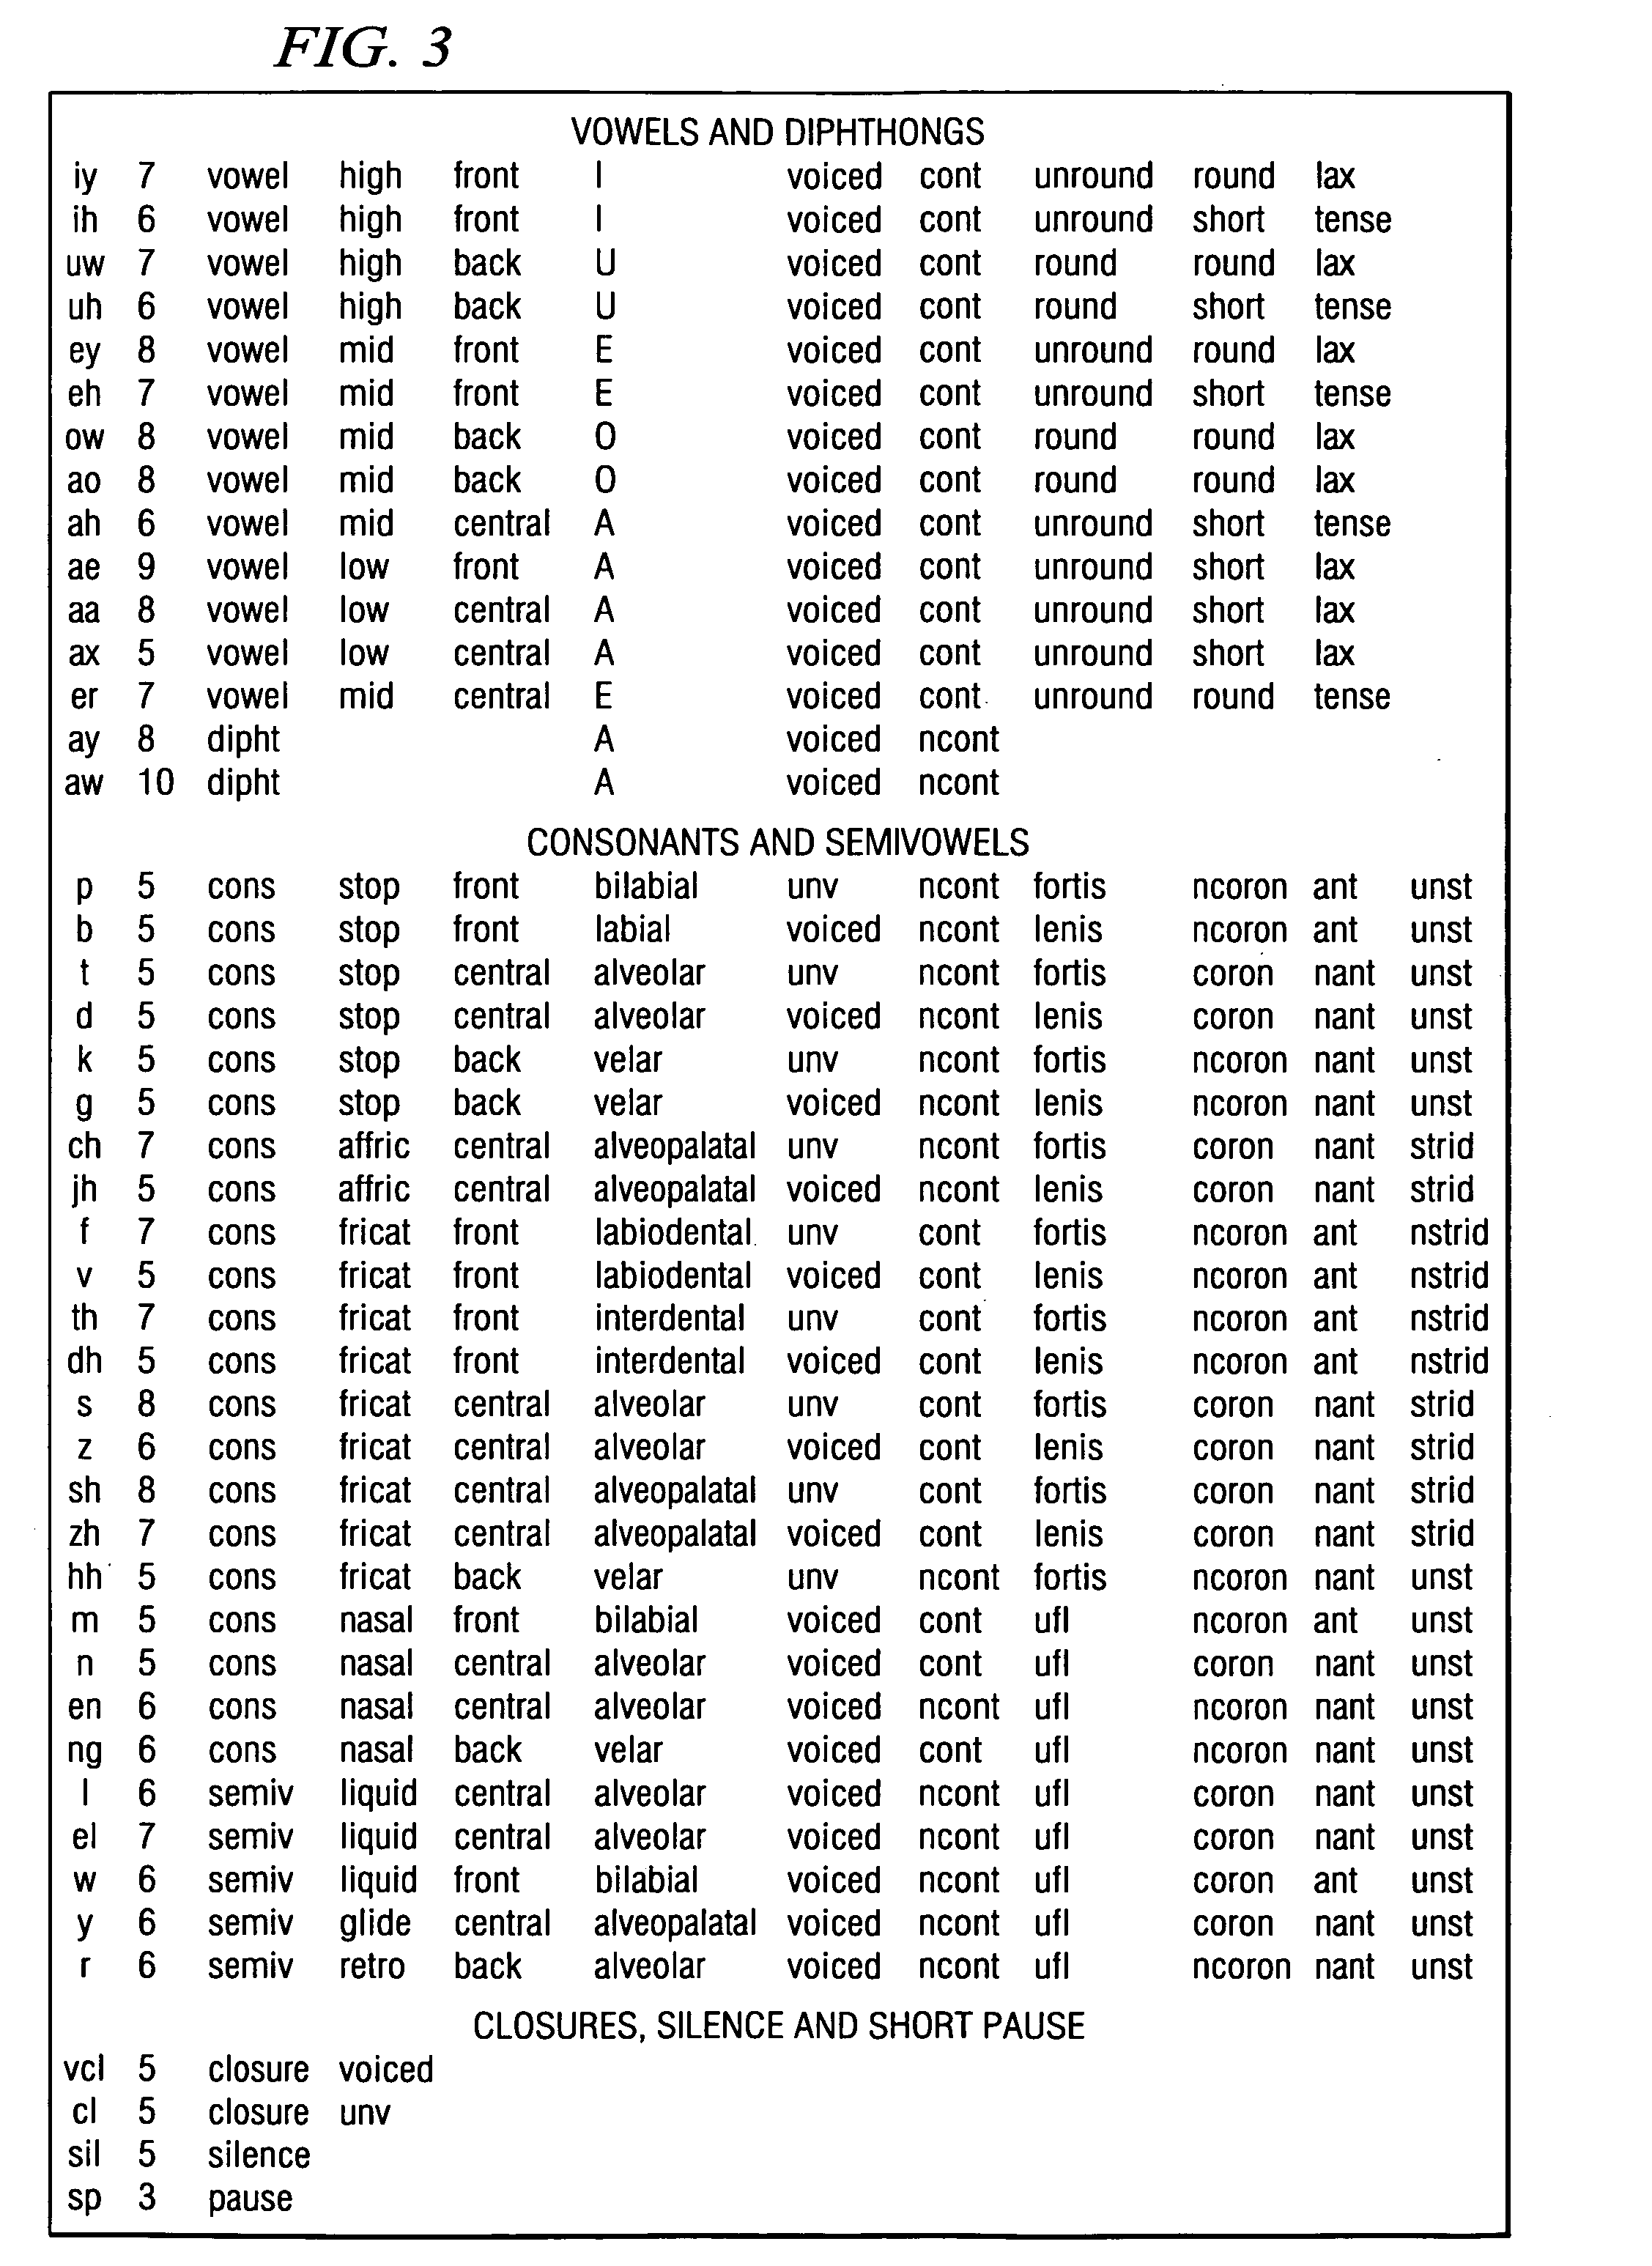
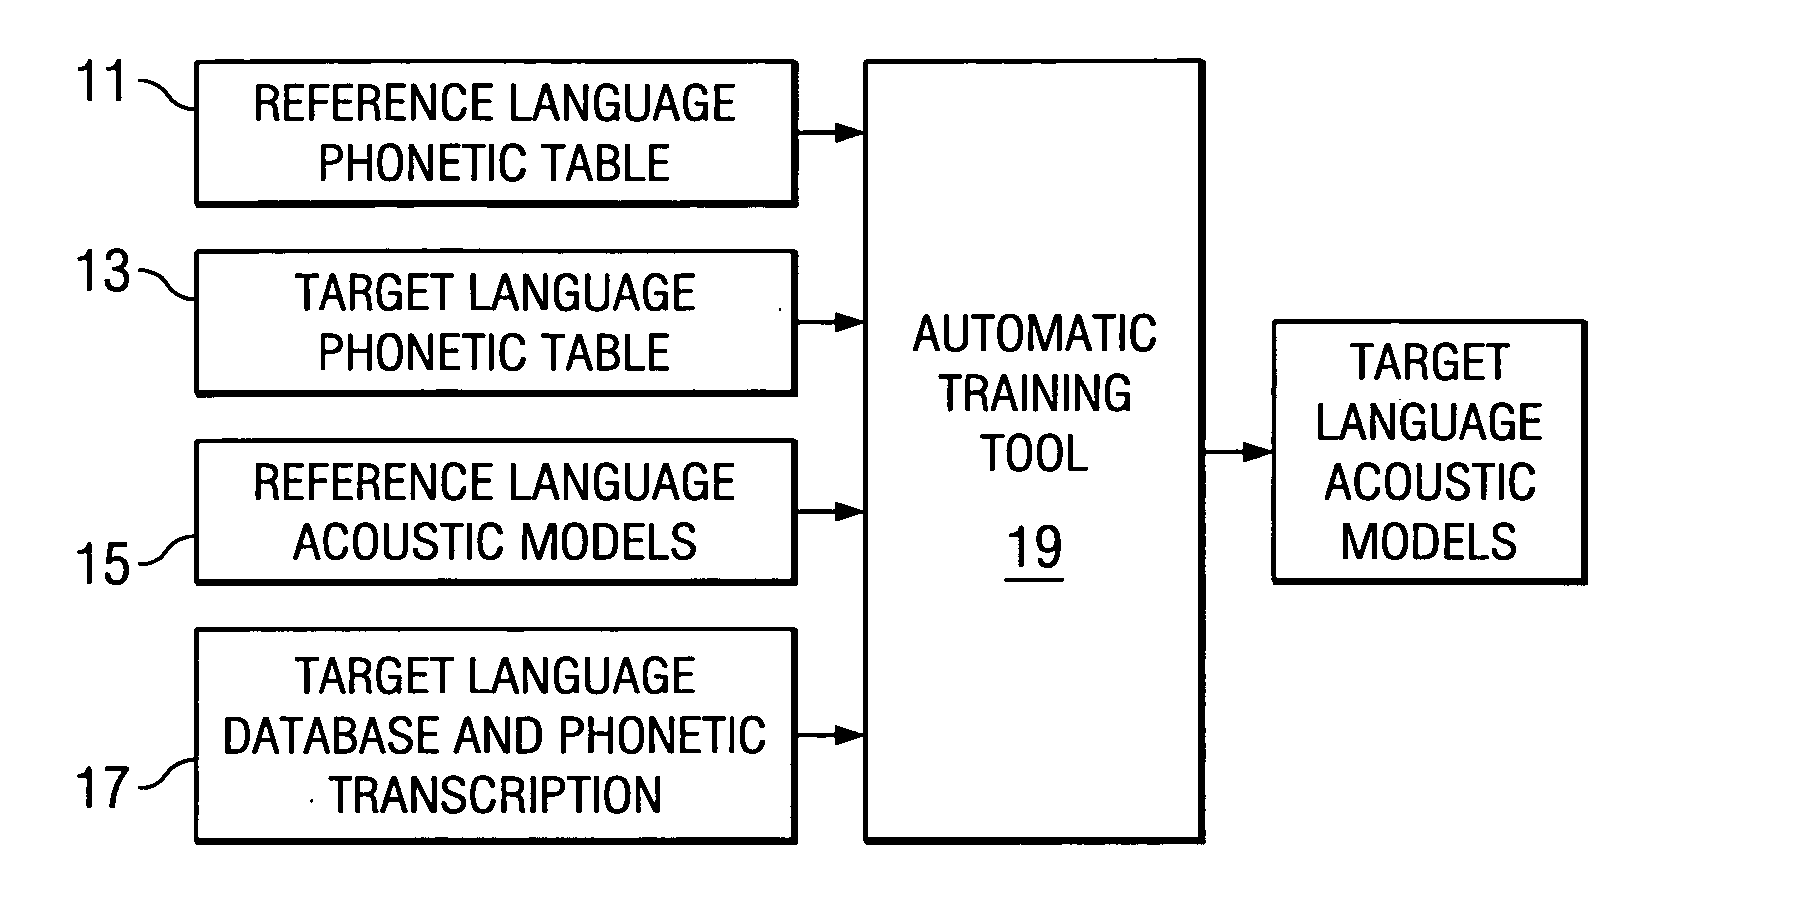
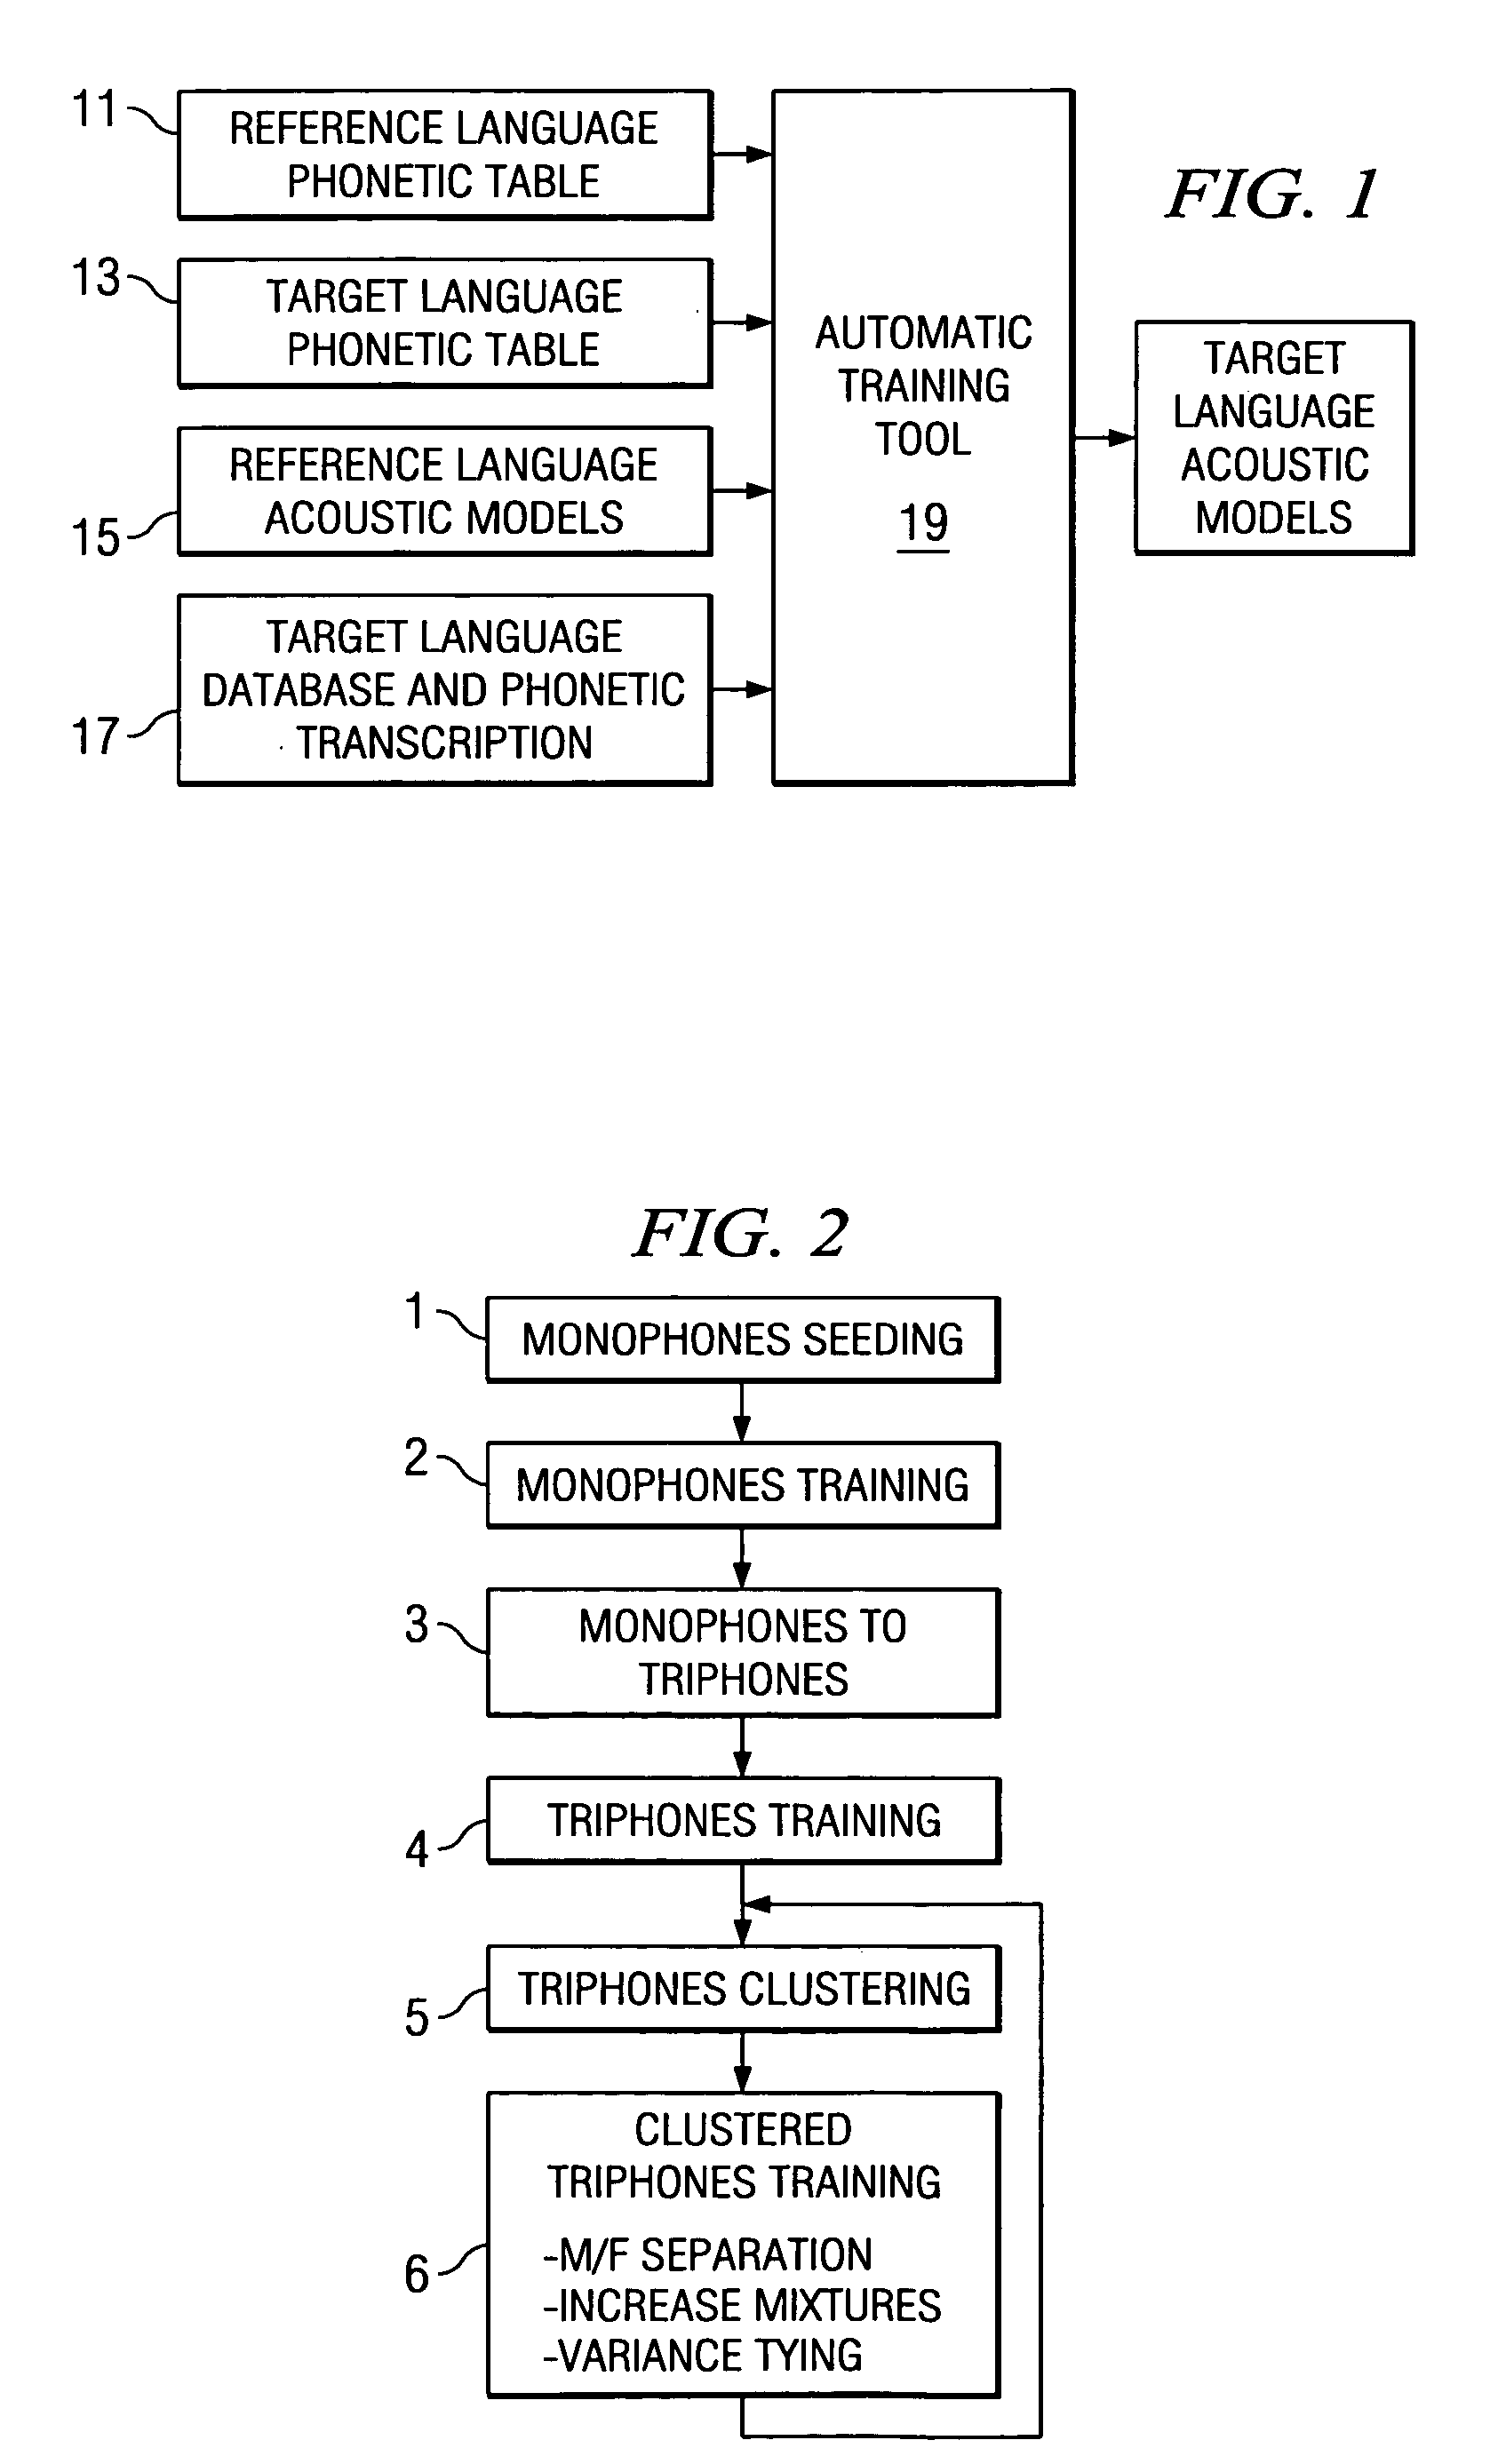
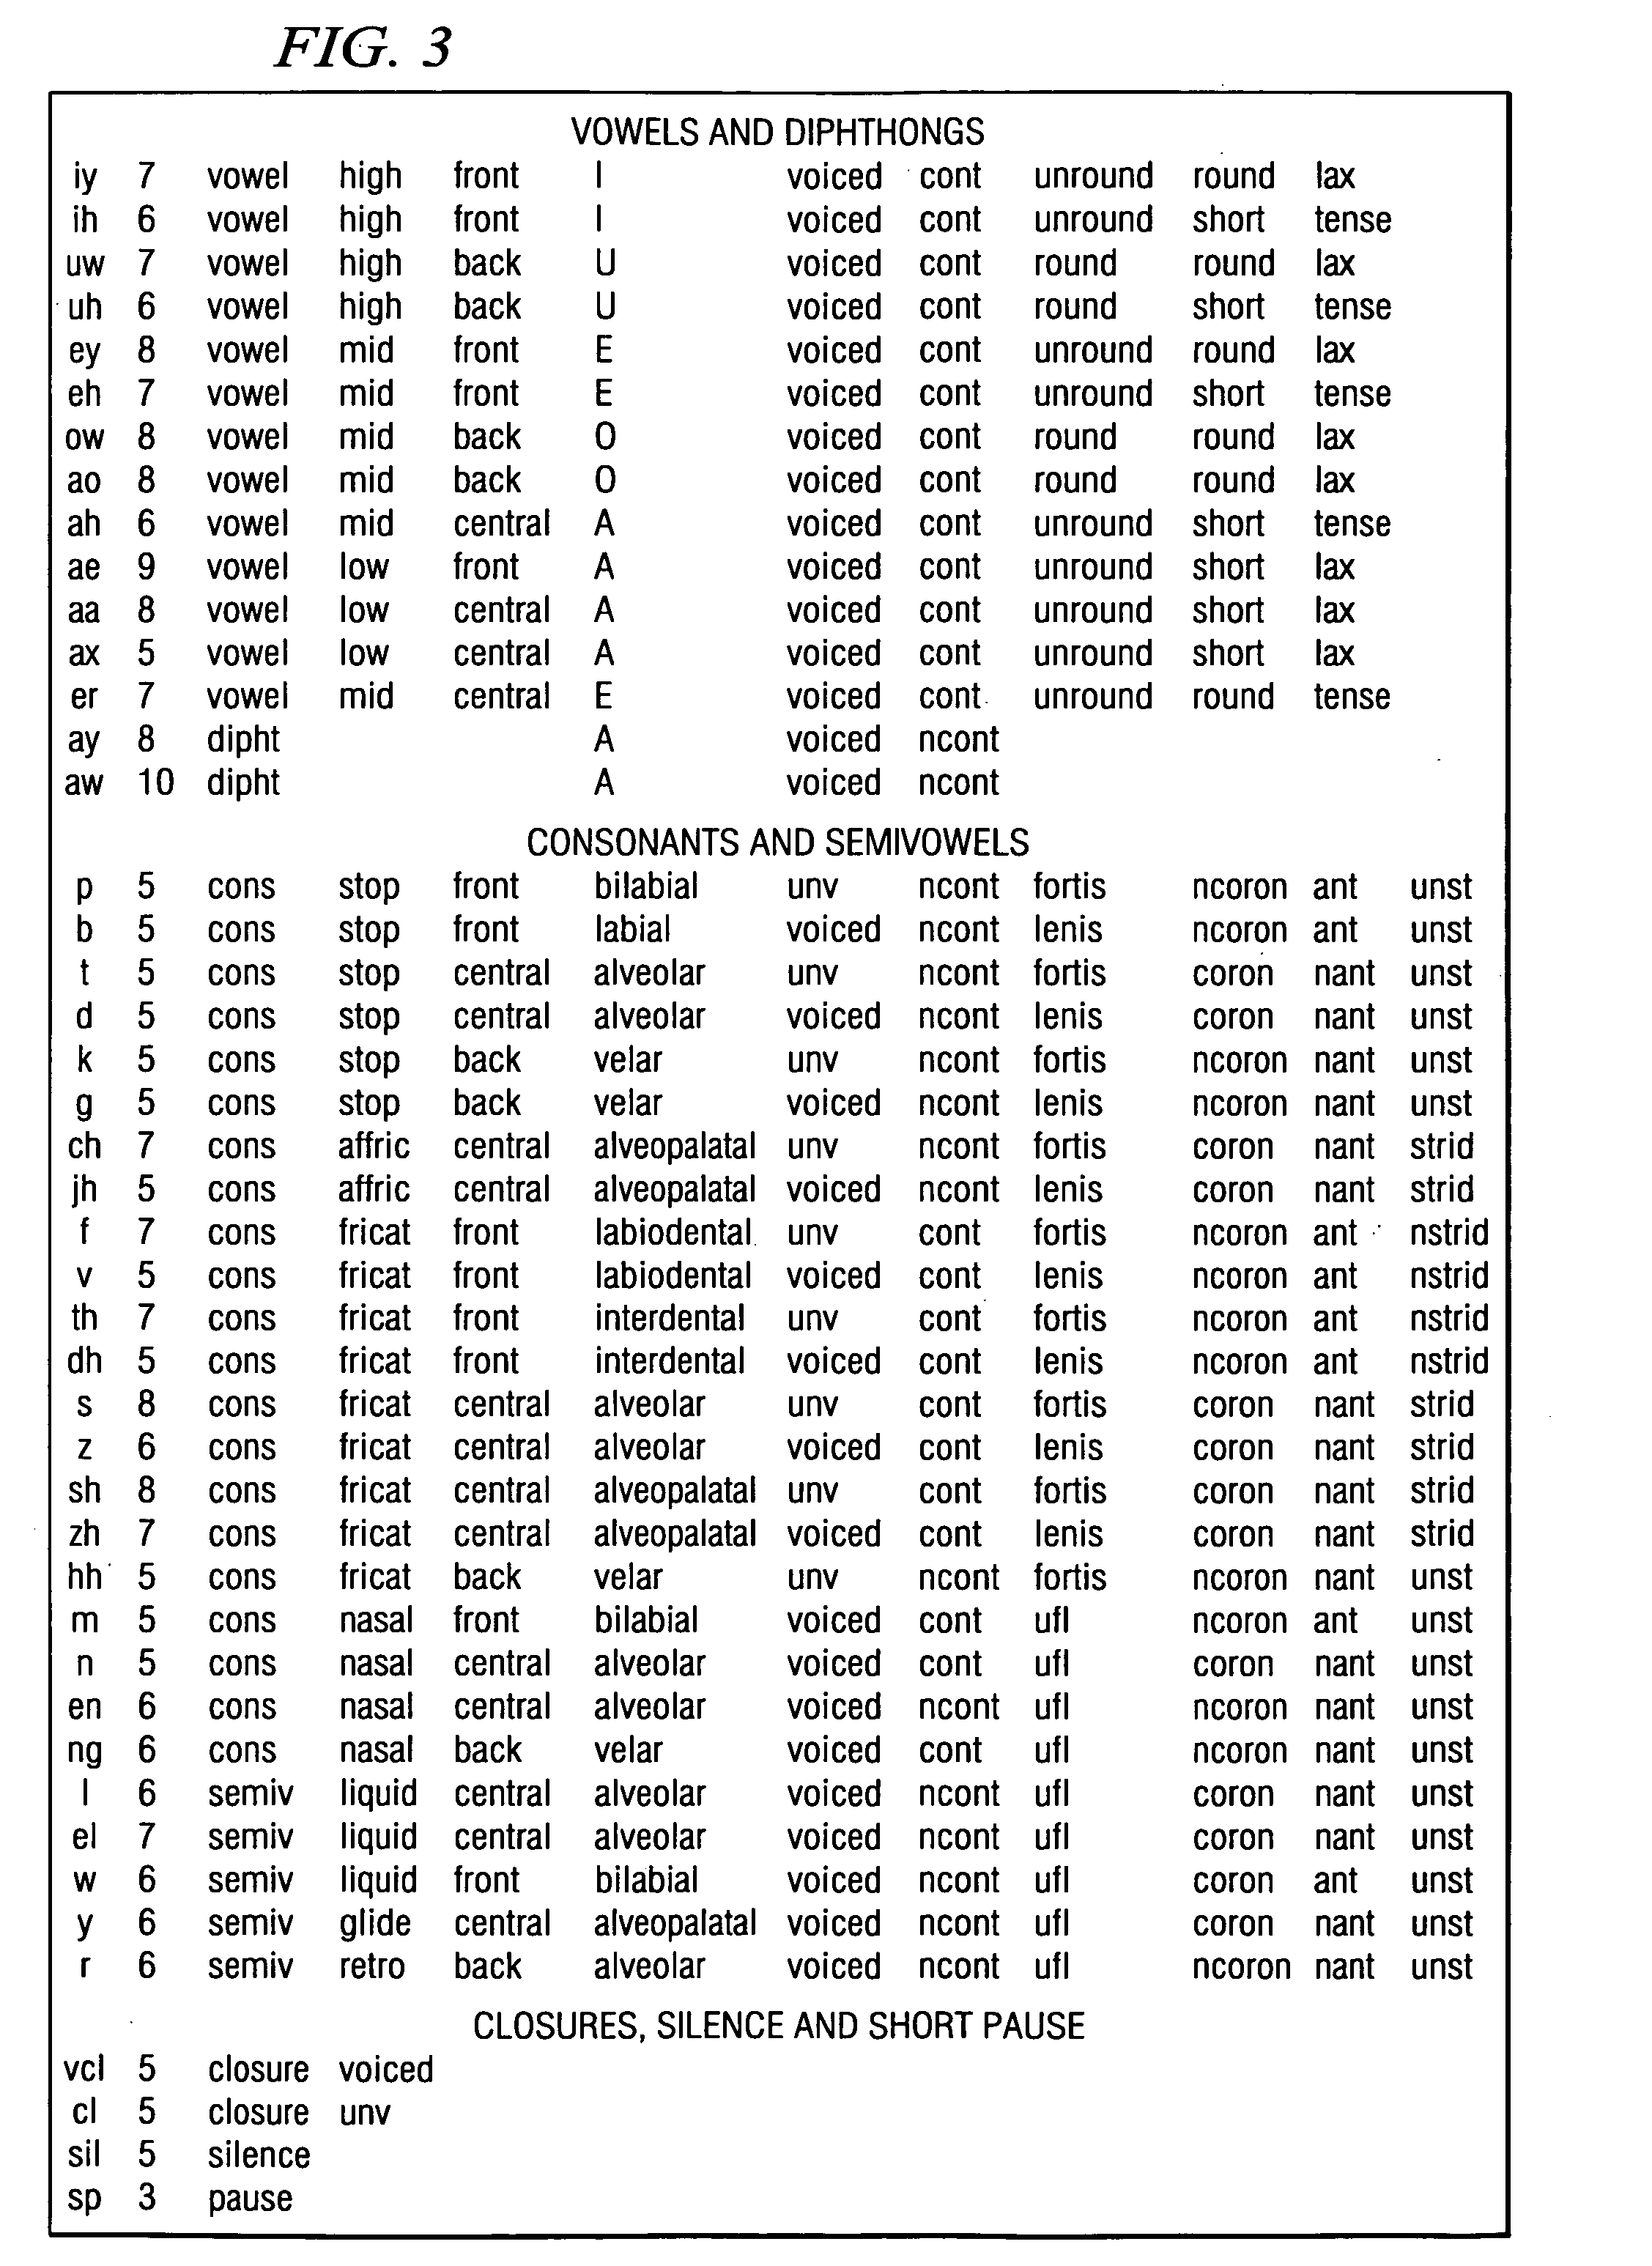
A method for training acoustic models for a new target language is provided using a phonetic table, which characterizes the phones, used in one or more reference language(s) with respect to their articulatory properties; a phonetic table, which characterizes the phones used in the target language with respect to their articulatory properties; a set of trained monophones for the reference language(s); and a database of sentences in the target language and its phonetic transcription. With these inputs, the new method completely and automatically takes care of the steps of monophone seeding and triphone clustering and machine intensive training steps involved in triphone acoustic training.
Owner:TEXAS INSTR INC
Application development tool using graphic objects to bind object sets of different distinct divisions of a design pattern
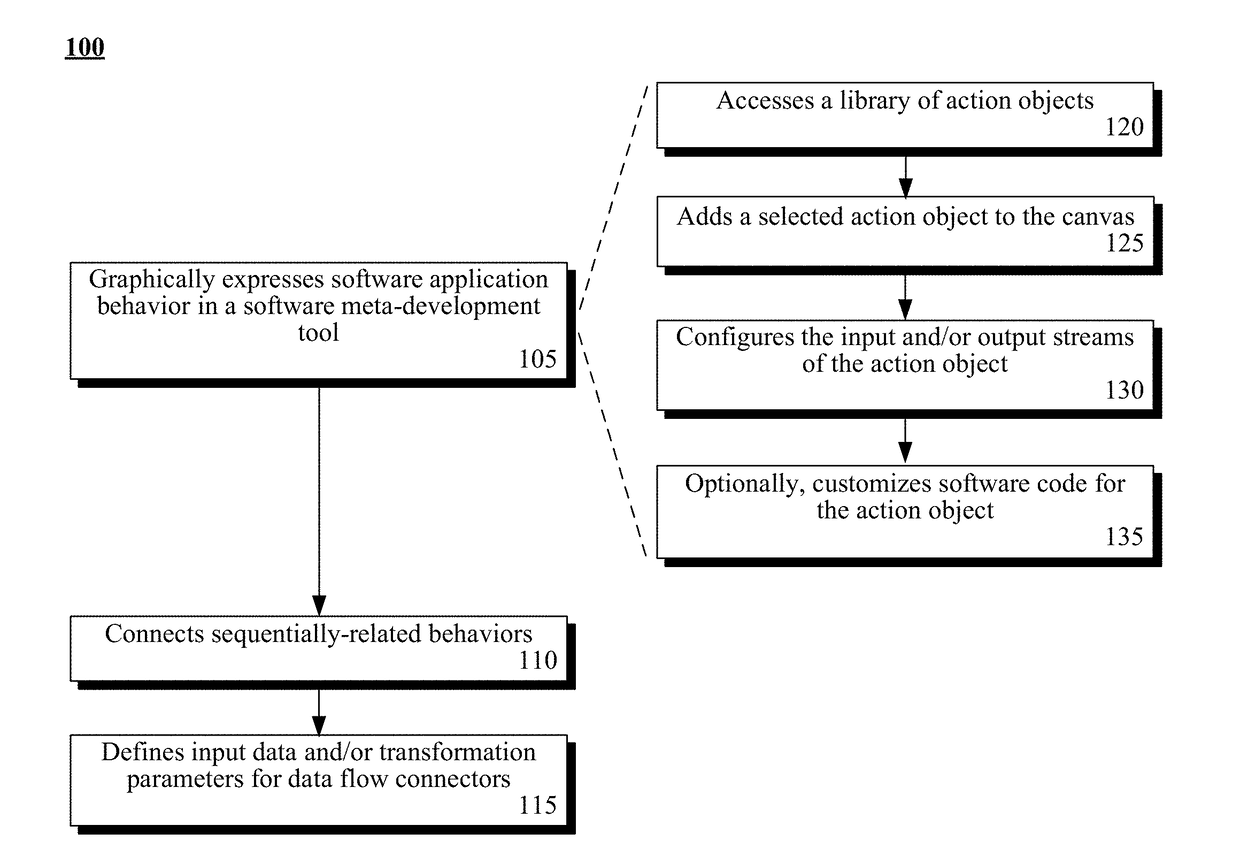
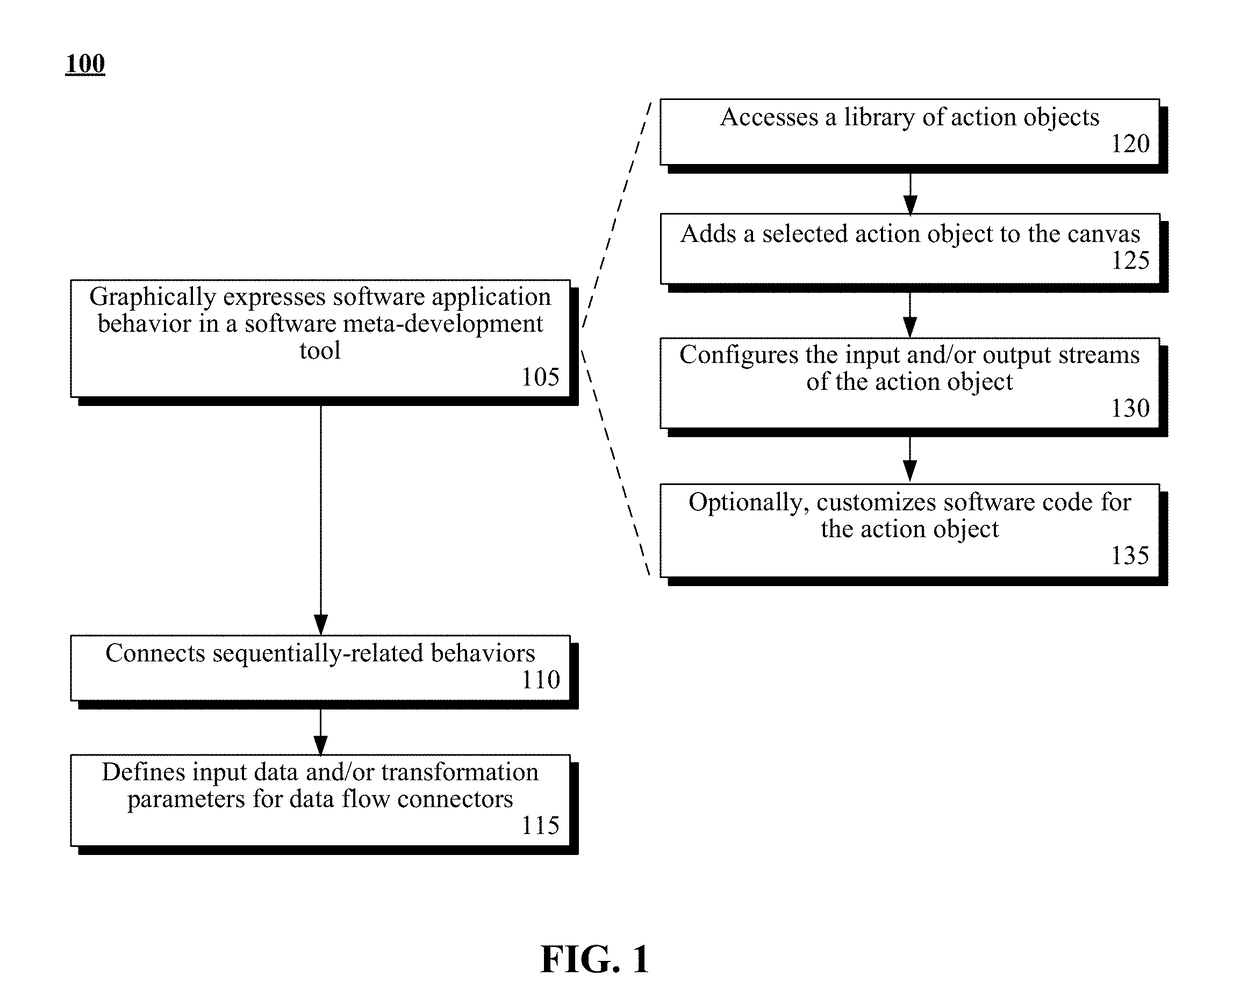
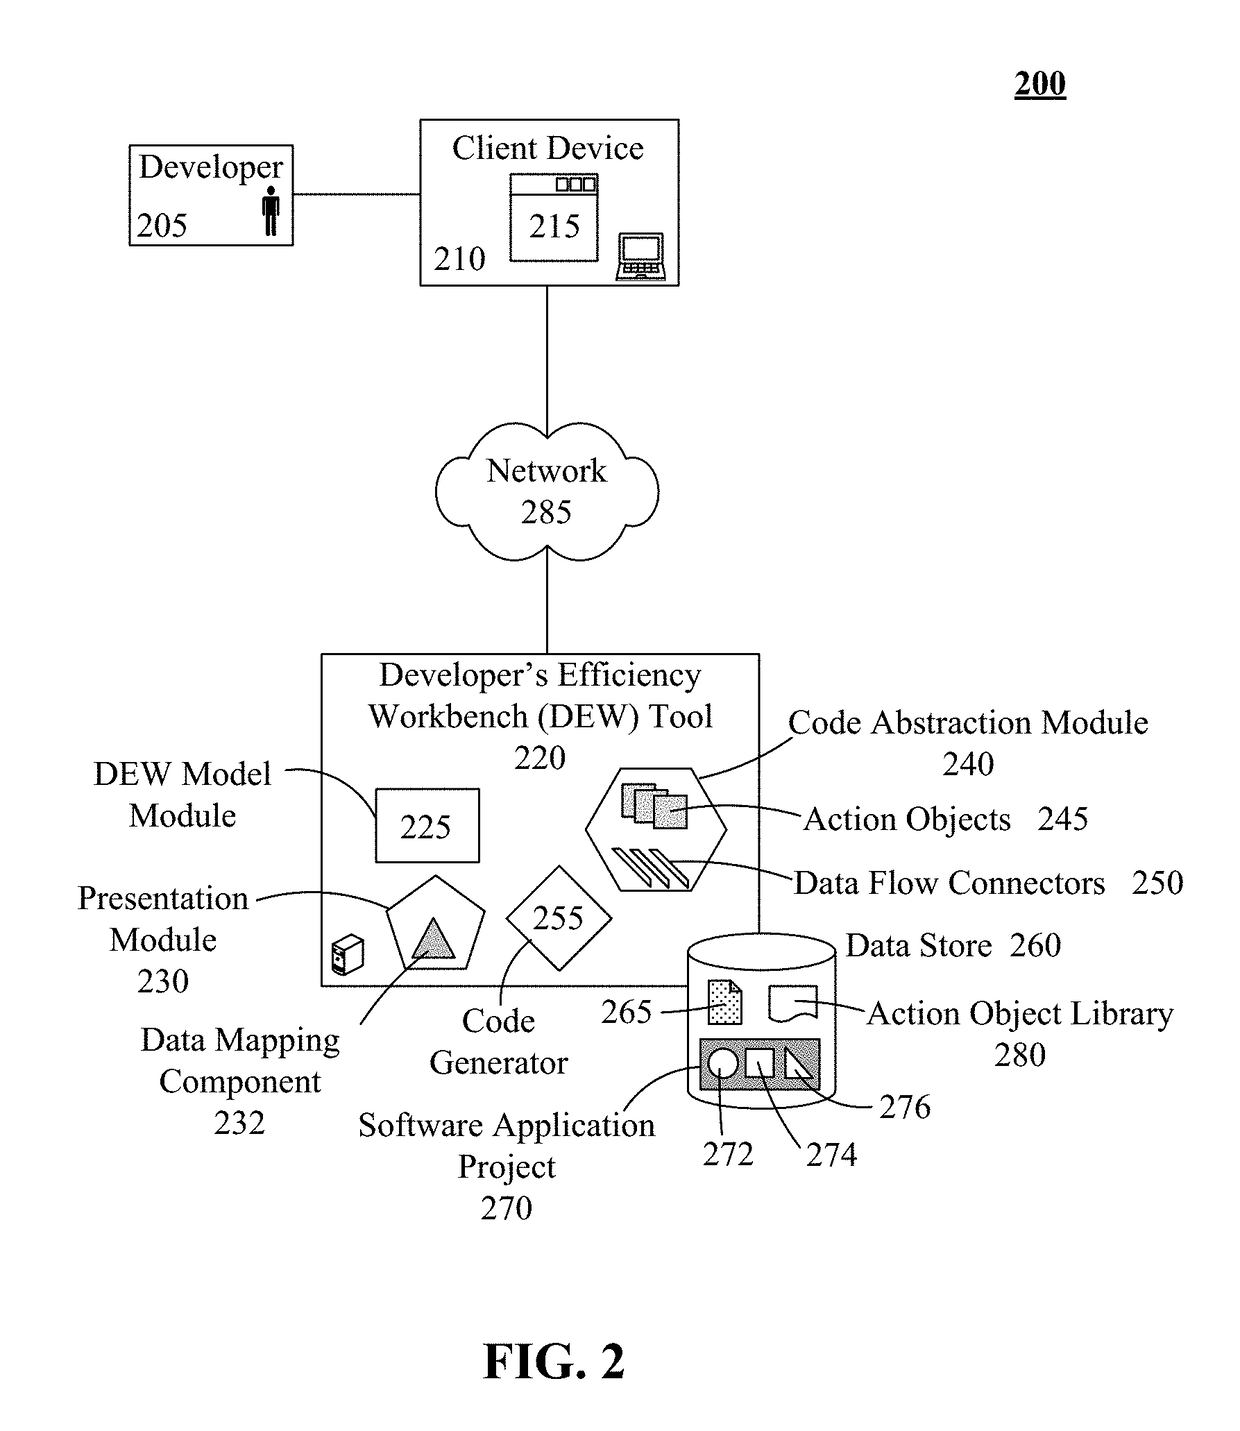
A code abstraction can be created within a software meta-development tool as a platform and programming language independent representation of a software application. The code abstraction can be comprised of action objects and data flow connectors. An action object can be a graphical placeholder representing software code that implements software behavior. Each action object can have an input and an output stream that are unconstrained by data type. A data flow connector can connect the output stream of one action object to the input stream of another sequentially-related action object. The data flow connector can graphically express a directional relationship and can define input data and transformation parameters. The data flow connector can implicitly represent the operations necessary to convert the input data in accordance with the transformation parameters. Authoring of the software code associated with the code abstraction by a user of the software meta-development tool can be unnecessary.
Owner:TECHREV LLC
Improving speaker verification across locations, languages, and/or dialects
ActiveUS10403291B2Improve distributionWidely distributedSpeech analysisUser deviceSpeaker verification
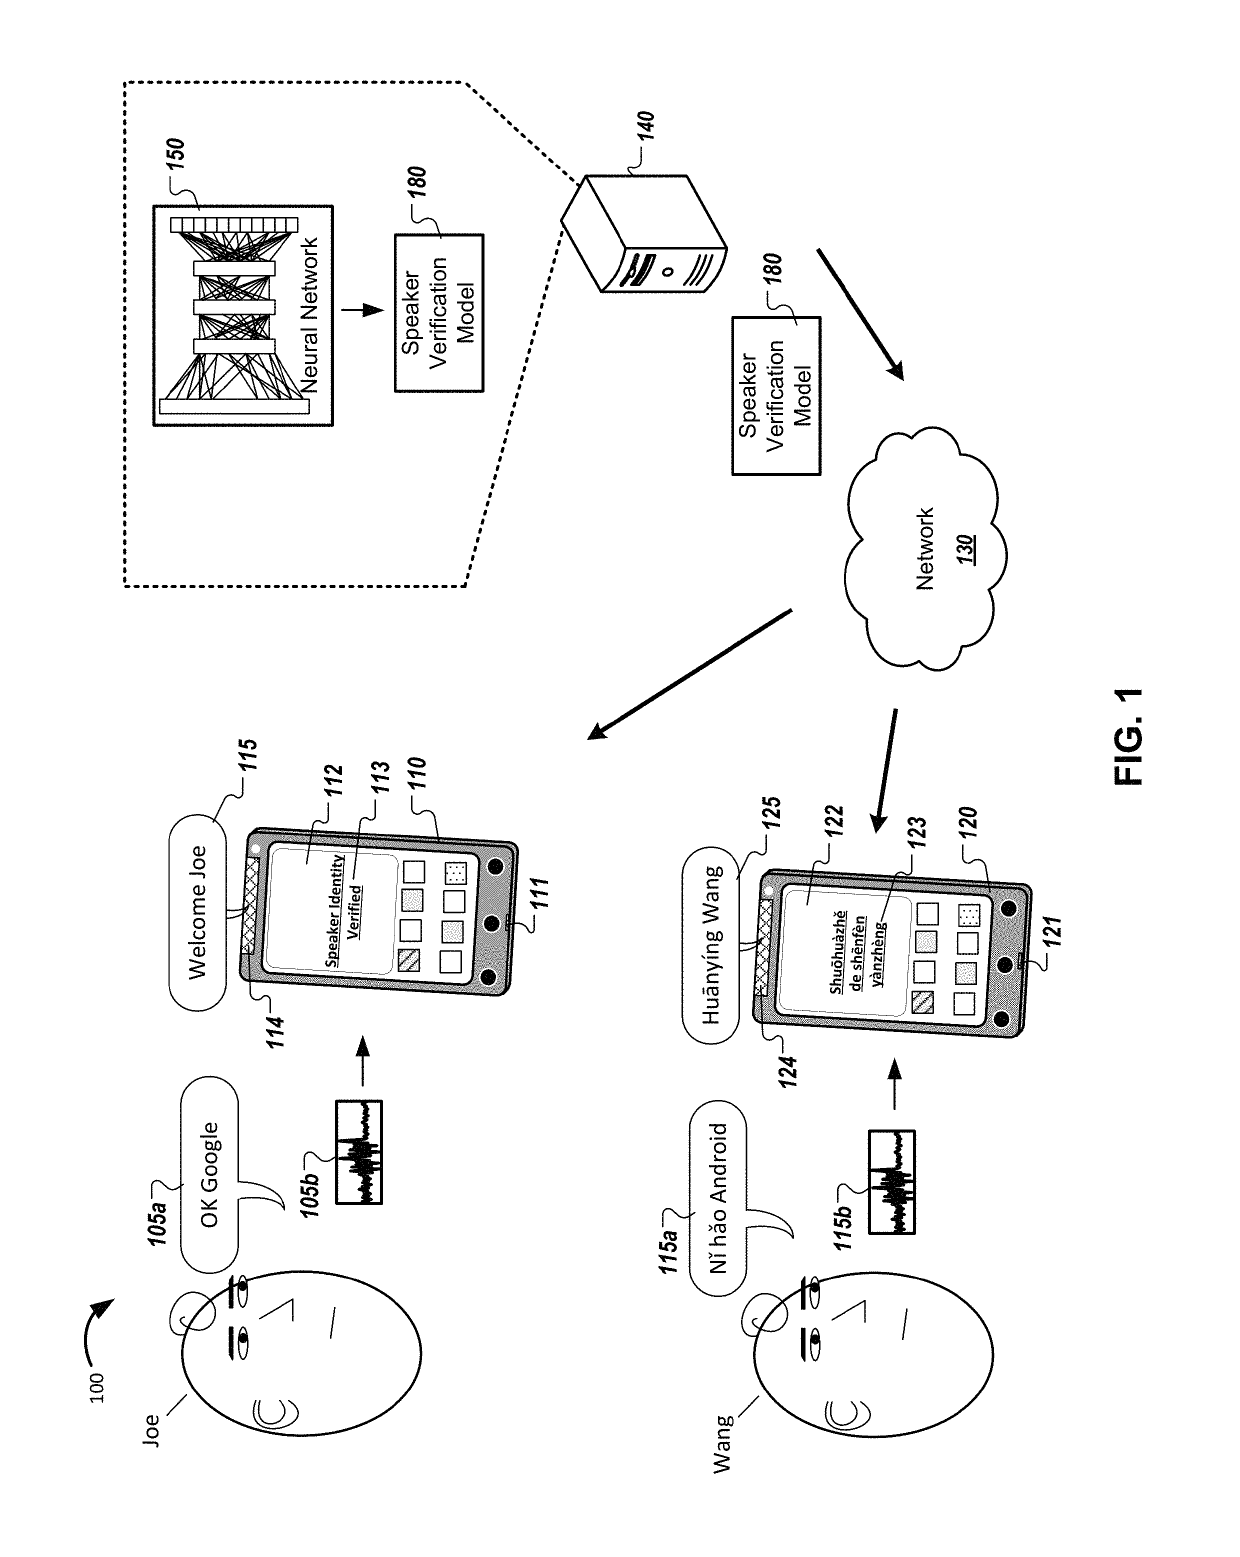
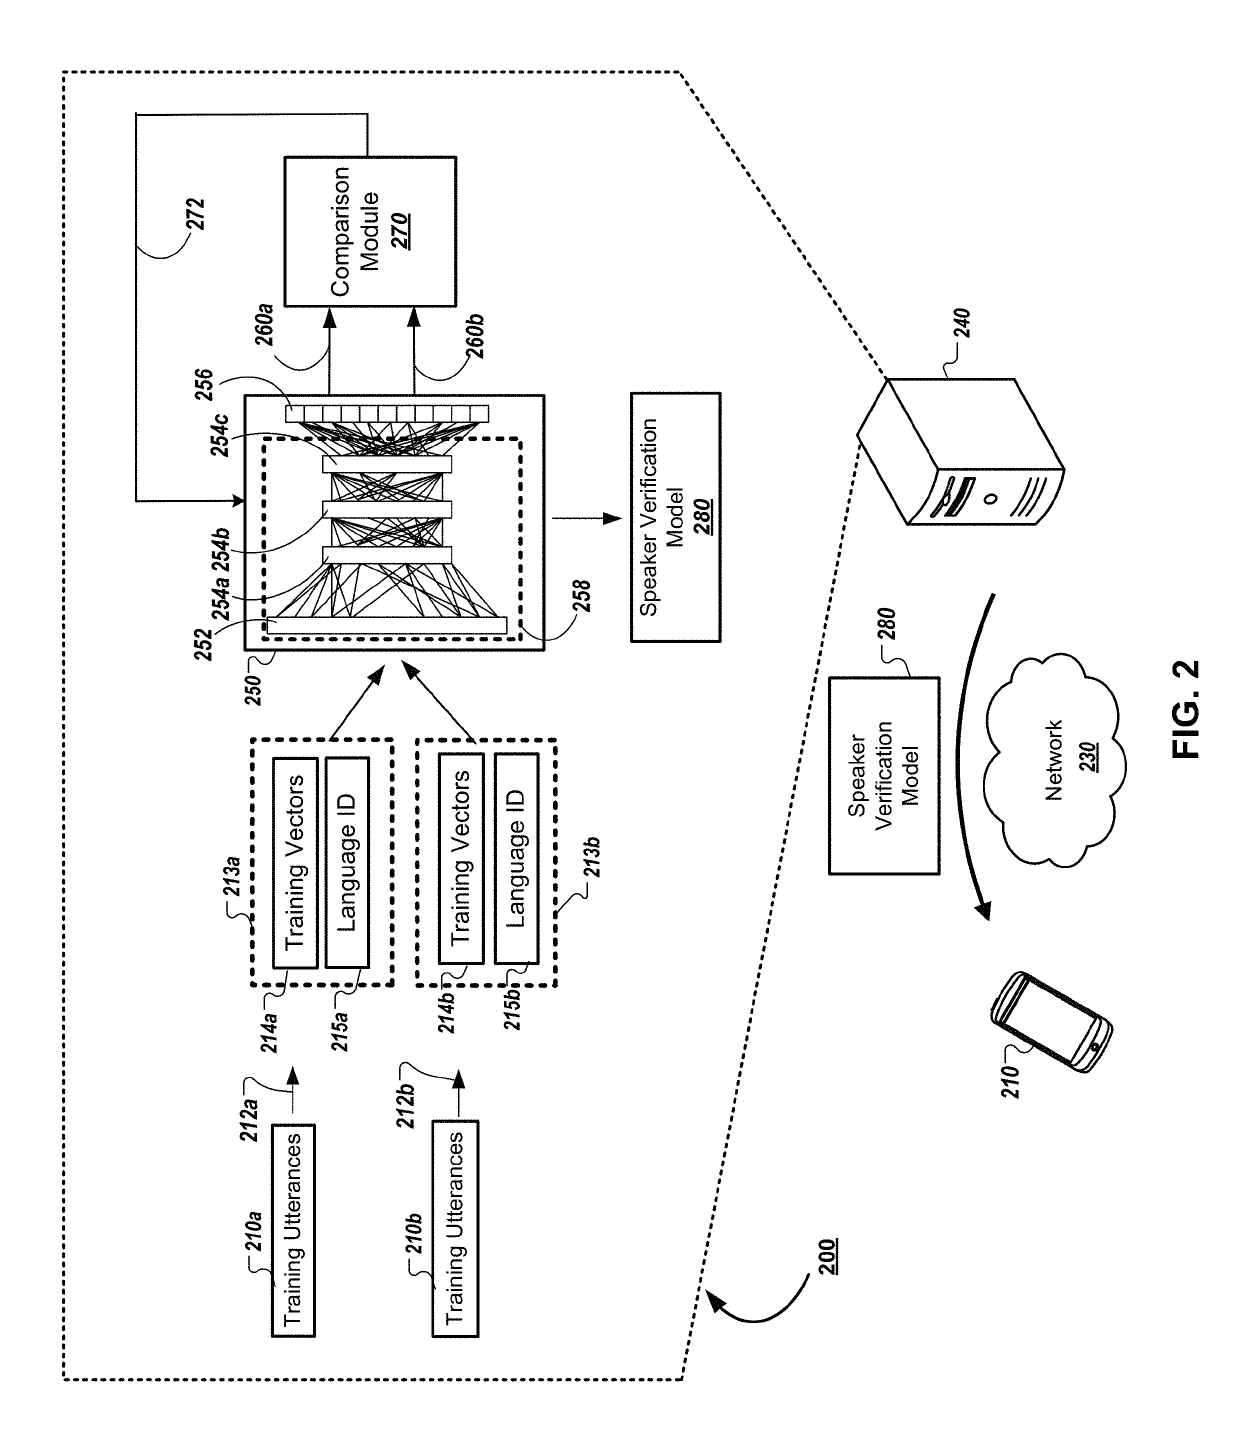
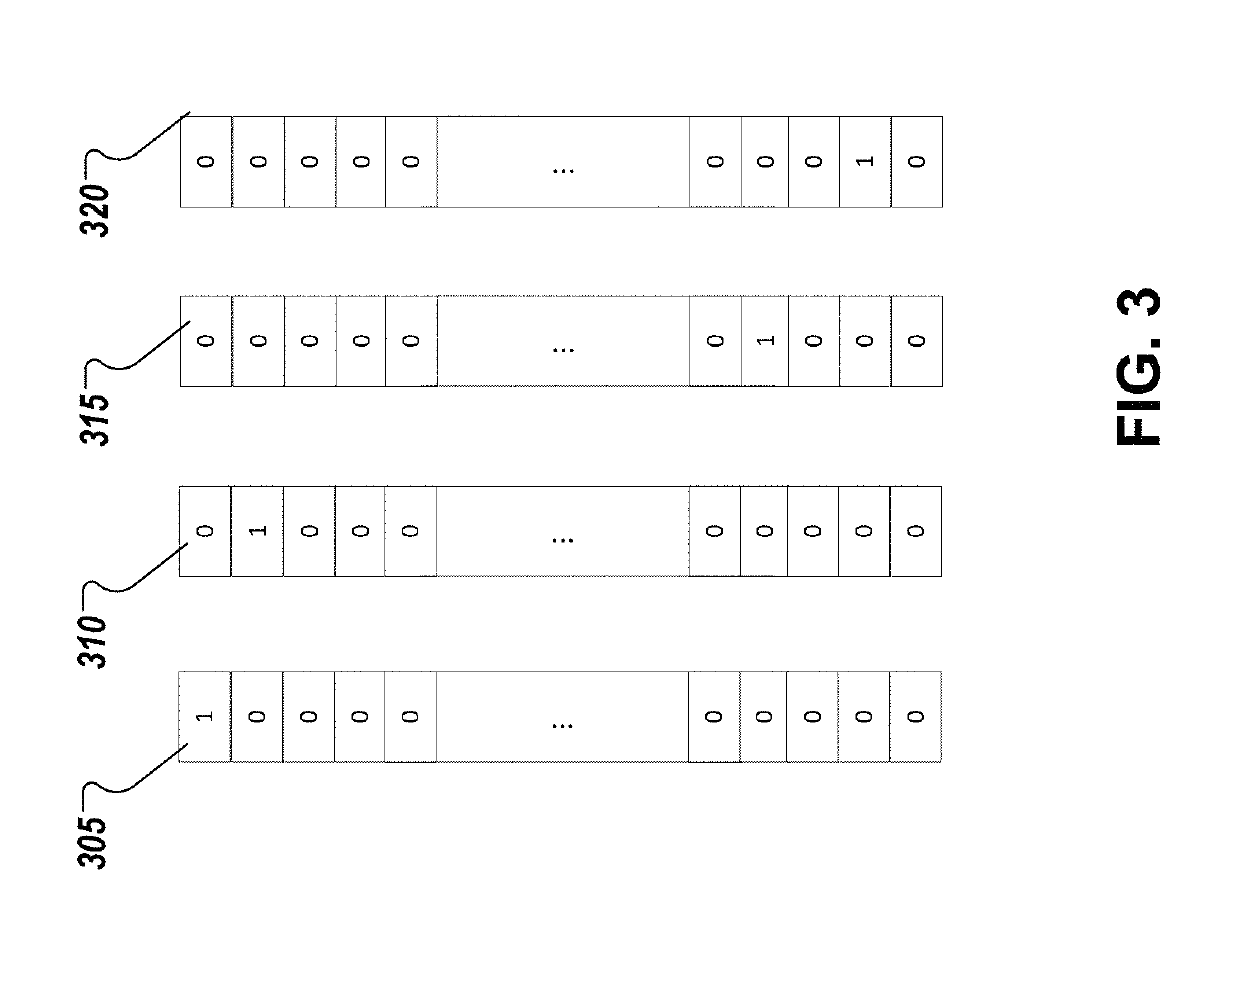
Methods, systems, apparatus, including computer programs encoded on computer storage medium, to facilitate language independent-speaker verification. In one aspect, a method includes actions of receiving, by a user device, audio data representing an utterance of a user. Other actions may include providing, to a neural network stored on the user device, input data derived from the audio data and a language identifier. The neural network may be trained using speech data representing speech in different languages or dialects. The method may include additional actions of generating, based on output of the neural network, a speaker representation and determining, based on the speaker representation and a second representation, that the utterance is an utterance of the user. The method may provide the user with access to the user device based on determining that the utterance is an utterance of the user.
Owner:GOOGLE LLC
Automatically identifying unique language independent keys correlated with appropriate text strings of various locales by key search
InactiveUS20090030673A1Shorten the timeImprove efficiencyNatural language data processingExecution for user interfacesText stringLanguage independence
A method, system and computer program product for automatically identifying unique language independent keys. A “key search” is performed which searches for various language independent keys in a properties file associated with a value or text string entered in a first locale. A second locale is suggested to narrow the number of language independent keys displayed in connection with the value entered in the first locale. Upon receiving the value for the second locale, another key search is performed, where this key search is performed on the language independent keys displayed in connection with the first value entered in association with the first locale. A unique language independent key may be identified based on this subsequent key search. By performing key searches and suggesting a second locale to narrow the number of language independent keys, the time in identifying a unique language independent key is reduced and efficiency is improved.


Owner:IBM CORP
Automatic language independent triphone training using a phonetic table
ActiveUS20050075887A1Optimal clustering of the triphone phonetic model parametersImprove speech recognition performanceSpeech recognitionAcoustic modelSpeech sound
A method for training acoustic models for a new target language is provided using a phonetic table, which characterizes the phones, used in one or more reference language(s) with respect to their articulatory properties; a phonetic table, which characterizes the phones used in the target language with respect to their articulatory properties; a set of trained monophones for the reference language(s); and a database of sentences in the target language and its phonetic transcription. With these inputs, the new method completely and automatically takes care of the steps of monophone seeding and triphone clustering and machine intensive training steps involved in triphone acoustic training.
Owner:TEXAS INSTR INC
Graphical software meta-development tool
A developer's efficiency workbench (DEW) tool can include a DEW model module, a presentation module, a code abstraction module, a language library, and a code generator. The DEW model module can allow creation of a DEW model, a list of user-defined data entities. The presentation module can allow the creation of presentations that define graphical user interfaces (GUIs) whose elements can be linked with the DEW model. The code abstraction module can allow the creation of a code abstraction; a high-level, graphical, platform and programming language independent representation of the behaviors performed by the software application. Elements of the code abstraction can be linked to DEW model or presentations. The language library can store syntax and / or software code for programming languages. The code generator can use the language library to synthesize the DEW model, presentations, and code abstraction into executable software code without manual authoring by a user.


Owner:TECHREV LLC
System and method for platform-independent, script-based application generation for spreadsheet software
A script-based application generation for spreadsheet software reads from one or more spreadsheets rendered by a spreadsheet program, description written in said text-based language, the text-based language for describing user interfaces, data models and / or workflow models or combinations thereof. The text-based language is independent of the spreadsheet program. The description is parsed and from the description one or more user interfaces, data model or workflow model or combinations thereof are generated in the spreadsheet program.


Owner:IBM CORP
Method and system for analyzing and translating various languages with use of semantic hierarchy
A method and computer system for analyzing sentences of various languages and constructing a language-independent semantic structure are provided. On the basis of comprehensive knowledge about languages and semantics, exhaustive linguistic descriptions are created, and lexical, morphological, syntactic, and semantic analyses for one or more sentences of a natural or artificial language are performed. A computer system is also provided to implement, analyze and store various linguistic structures and to perform lexical, morphological, syntactic, and semantic analyses. As result, a generalized data structure, such as a semantic structure, is generated and used to describe the meaning of one or more sentences in language-independent form, applicable to automated abstracting, machine translation, control systems, Internet information retrieval, etc.


Owner:ABBYY DEV INC
A Method for Semantic Processing of Natural Language Using Graphical Interlingua
InactiveCN102272755ANatural language translationNatural language analysisGraphicsLanguage independence
This paper describes a method for processing natural language using a language processing system. Enter written or spoken text into a language processing system. The method includes the step of analyzing the grammar of the text. The next step is to select the components of the text and their interrelationships within said text. A graphical or graphical representation of the text is generated or used as a language-independent representation of the meaning of the text. Such diagrammatic or graphical representations are used to perform modeling, knowledge representation and processing in language processing systems. Additionally, systems for processing natural language and methods for developing language processing systems are described.


Owner:MATROKS PROFESHNL INK
Voiced Interval Command Interpretation
InactiveUS20130290000A1Small volumnGuaranteed economic efficiencySpeech analysisMicrocontrollerMeasurement device
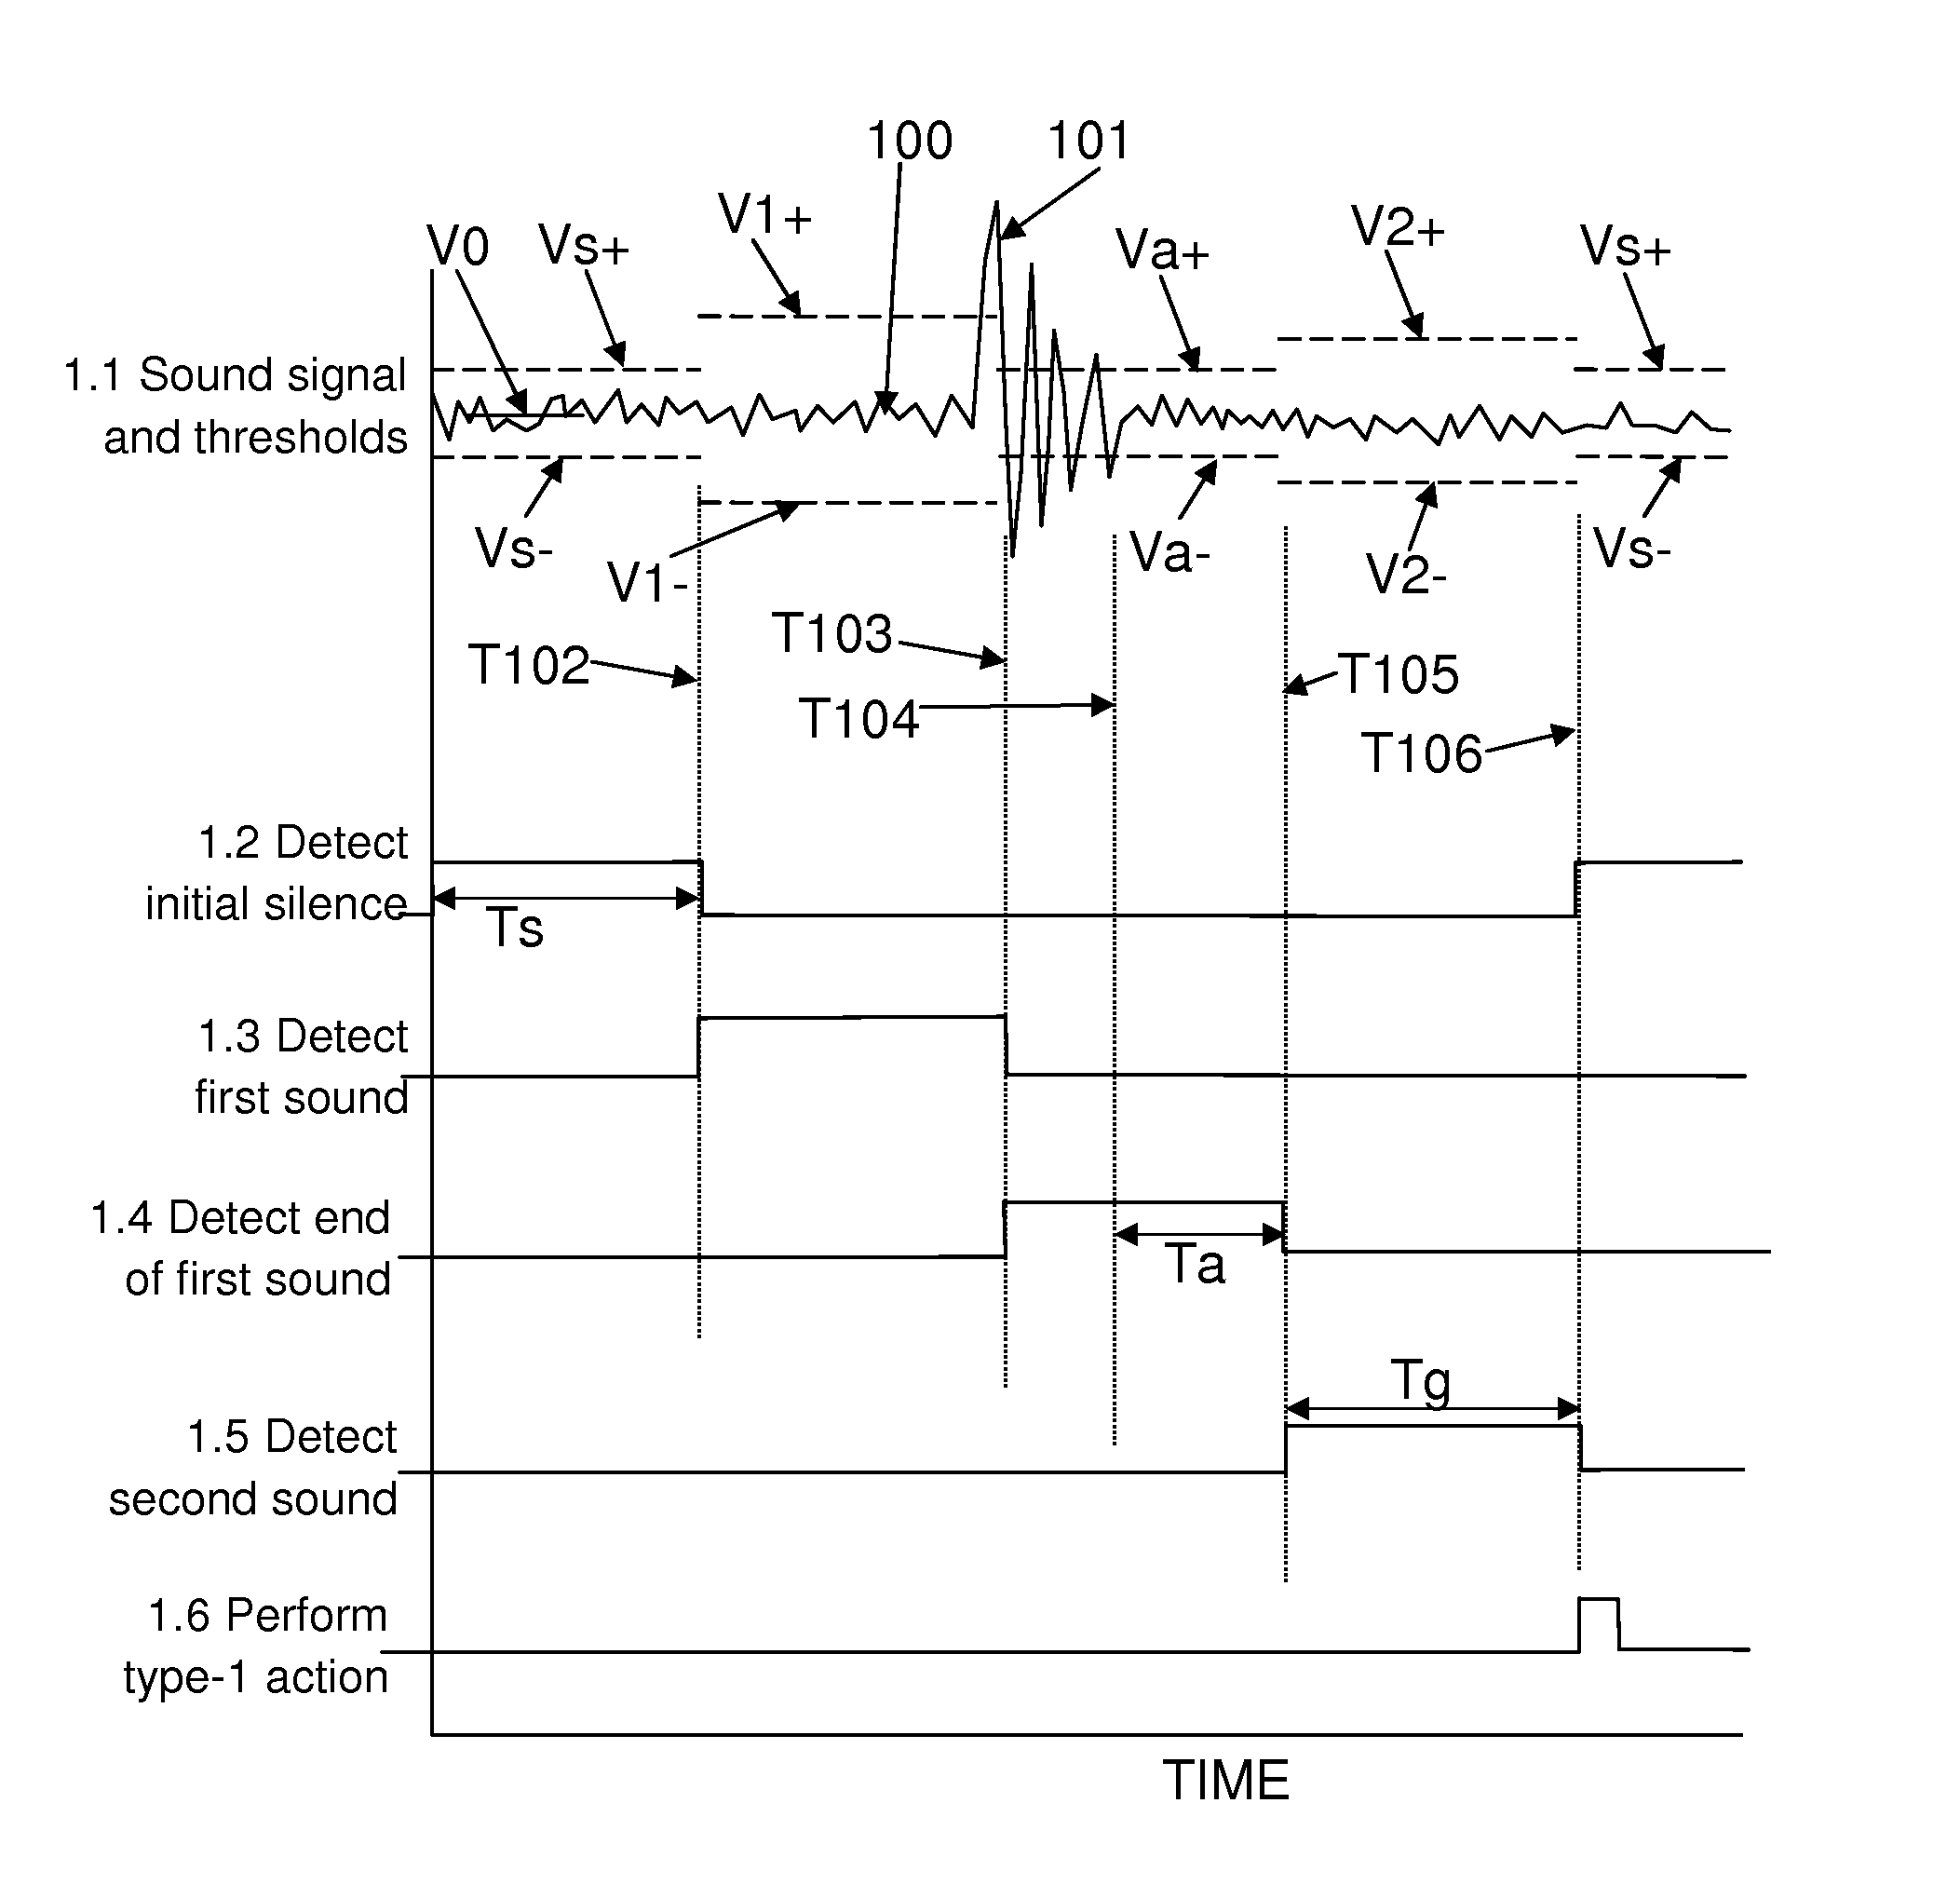
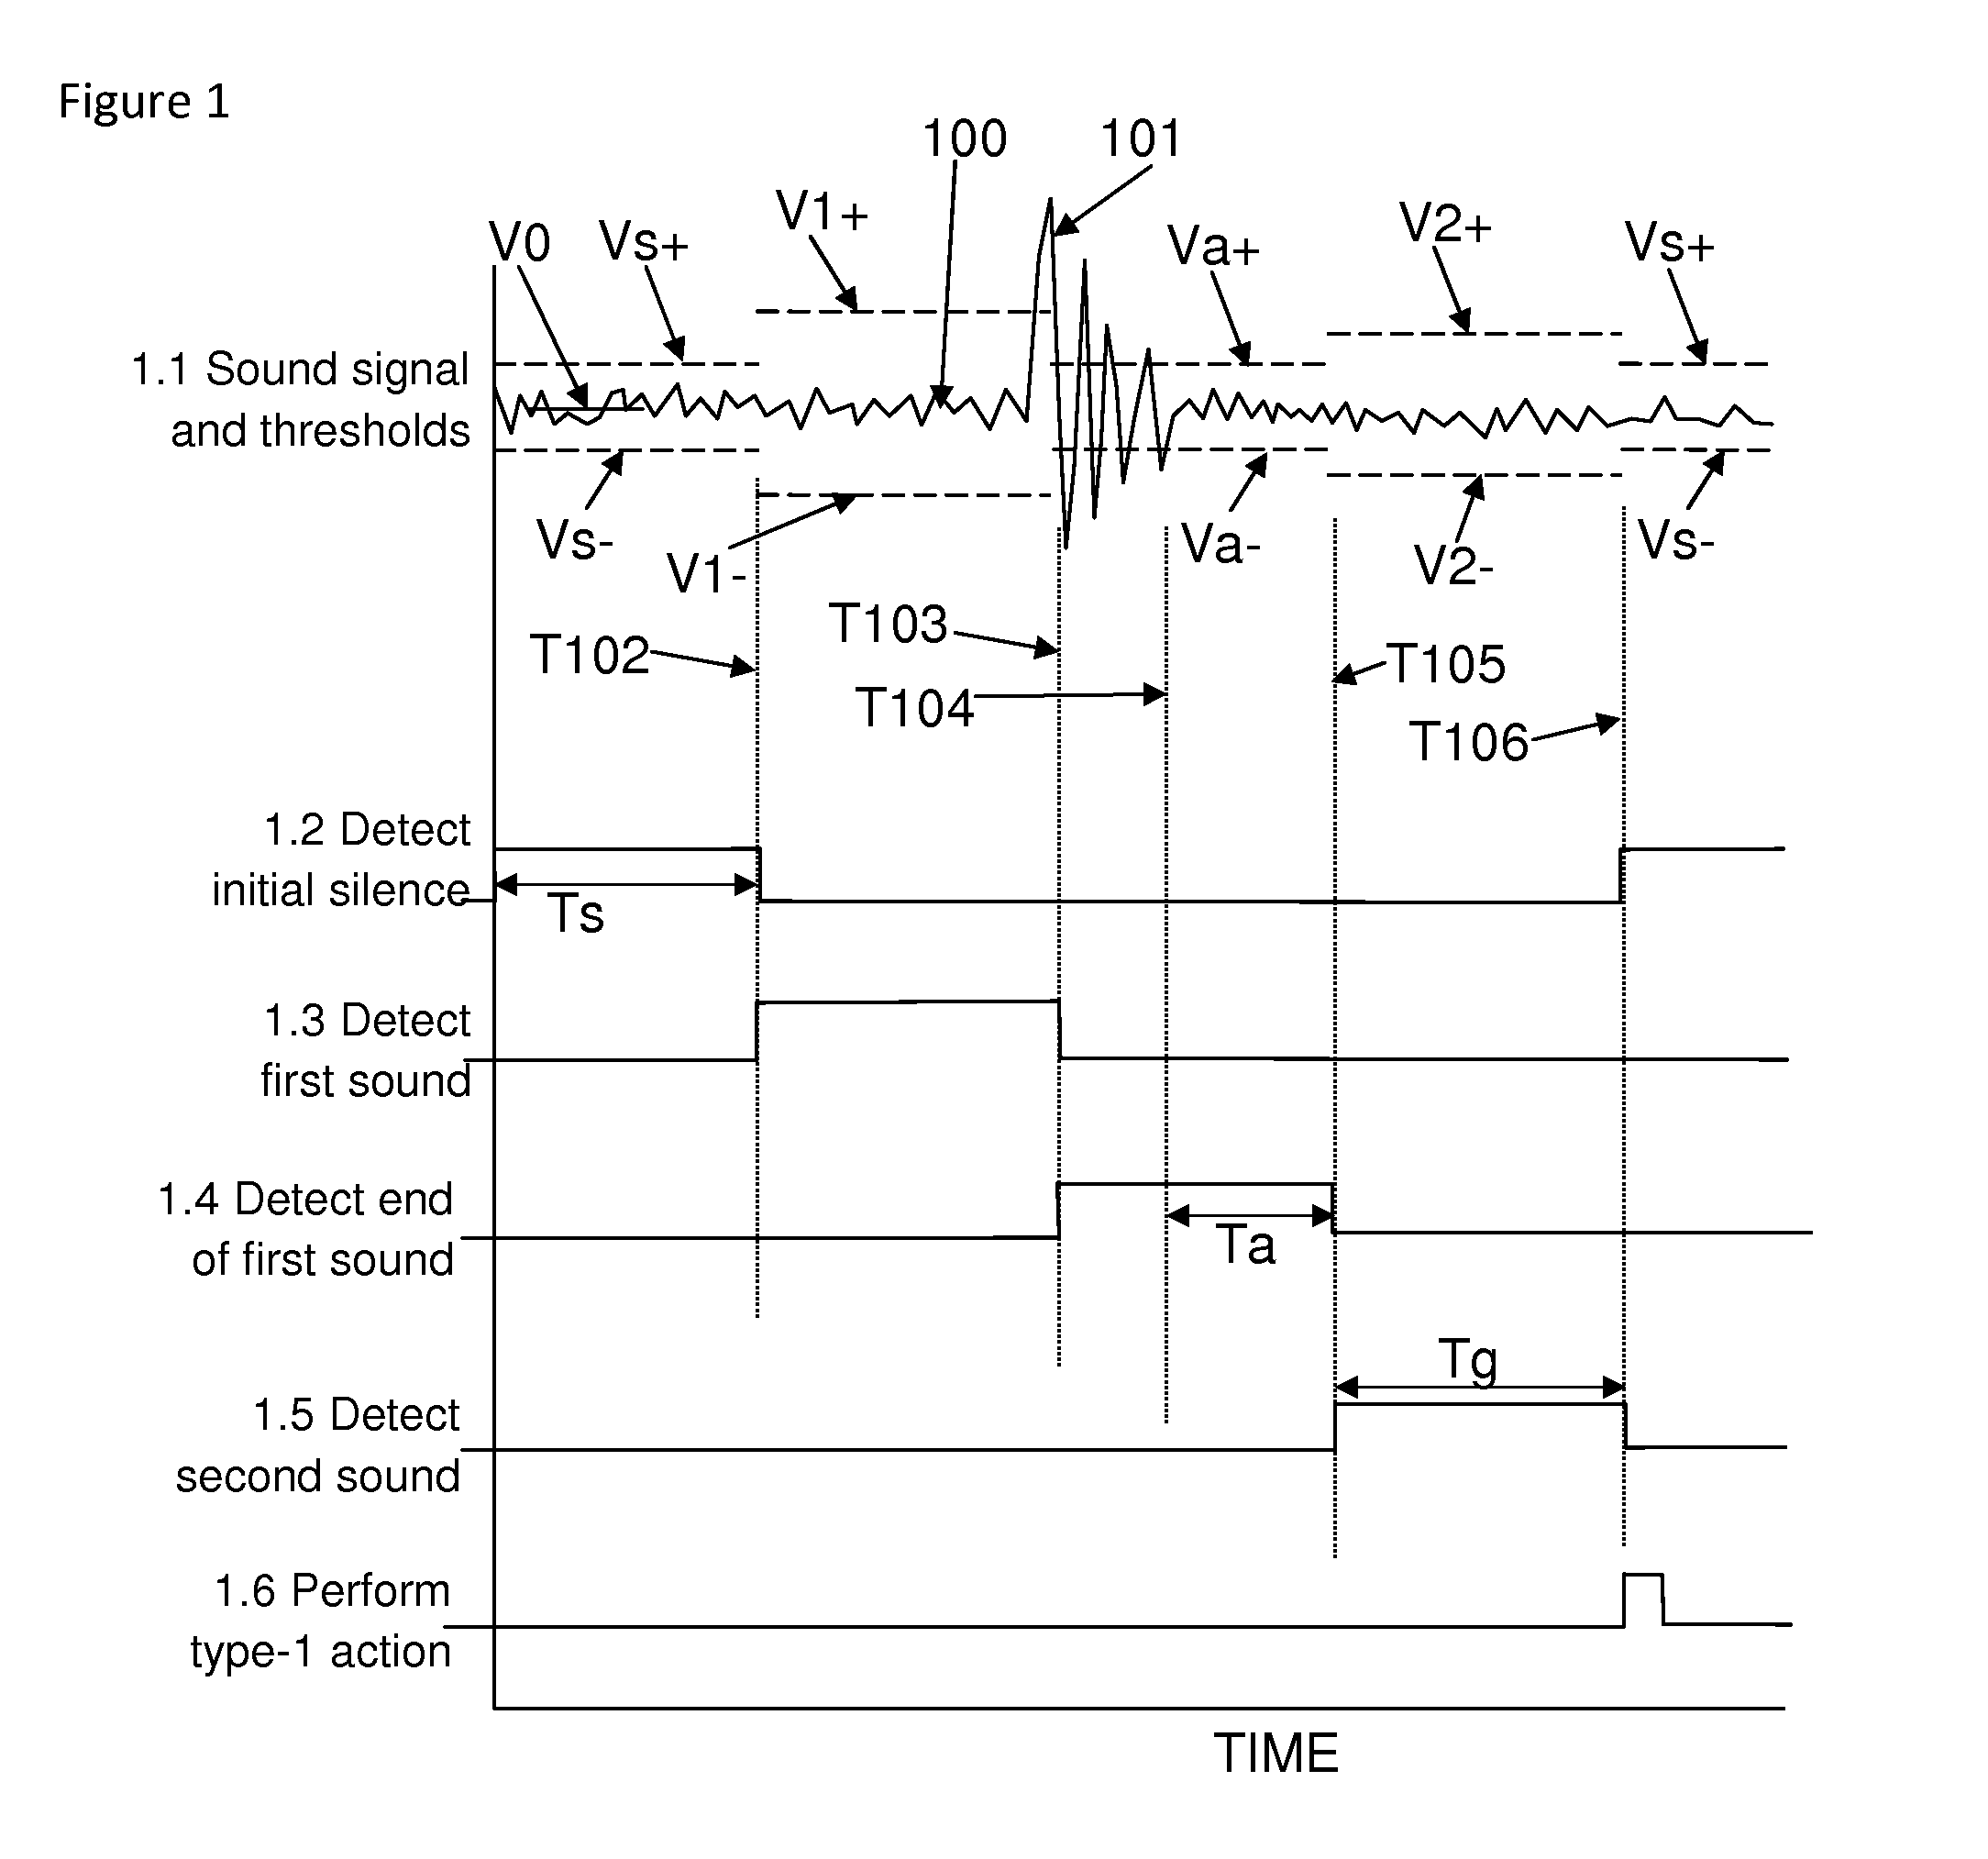
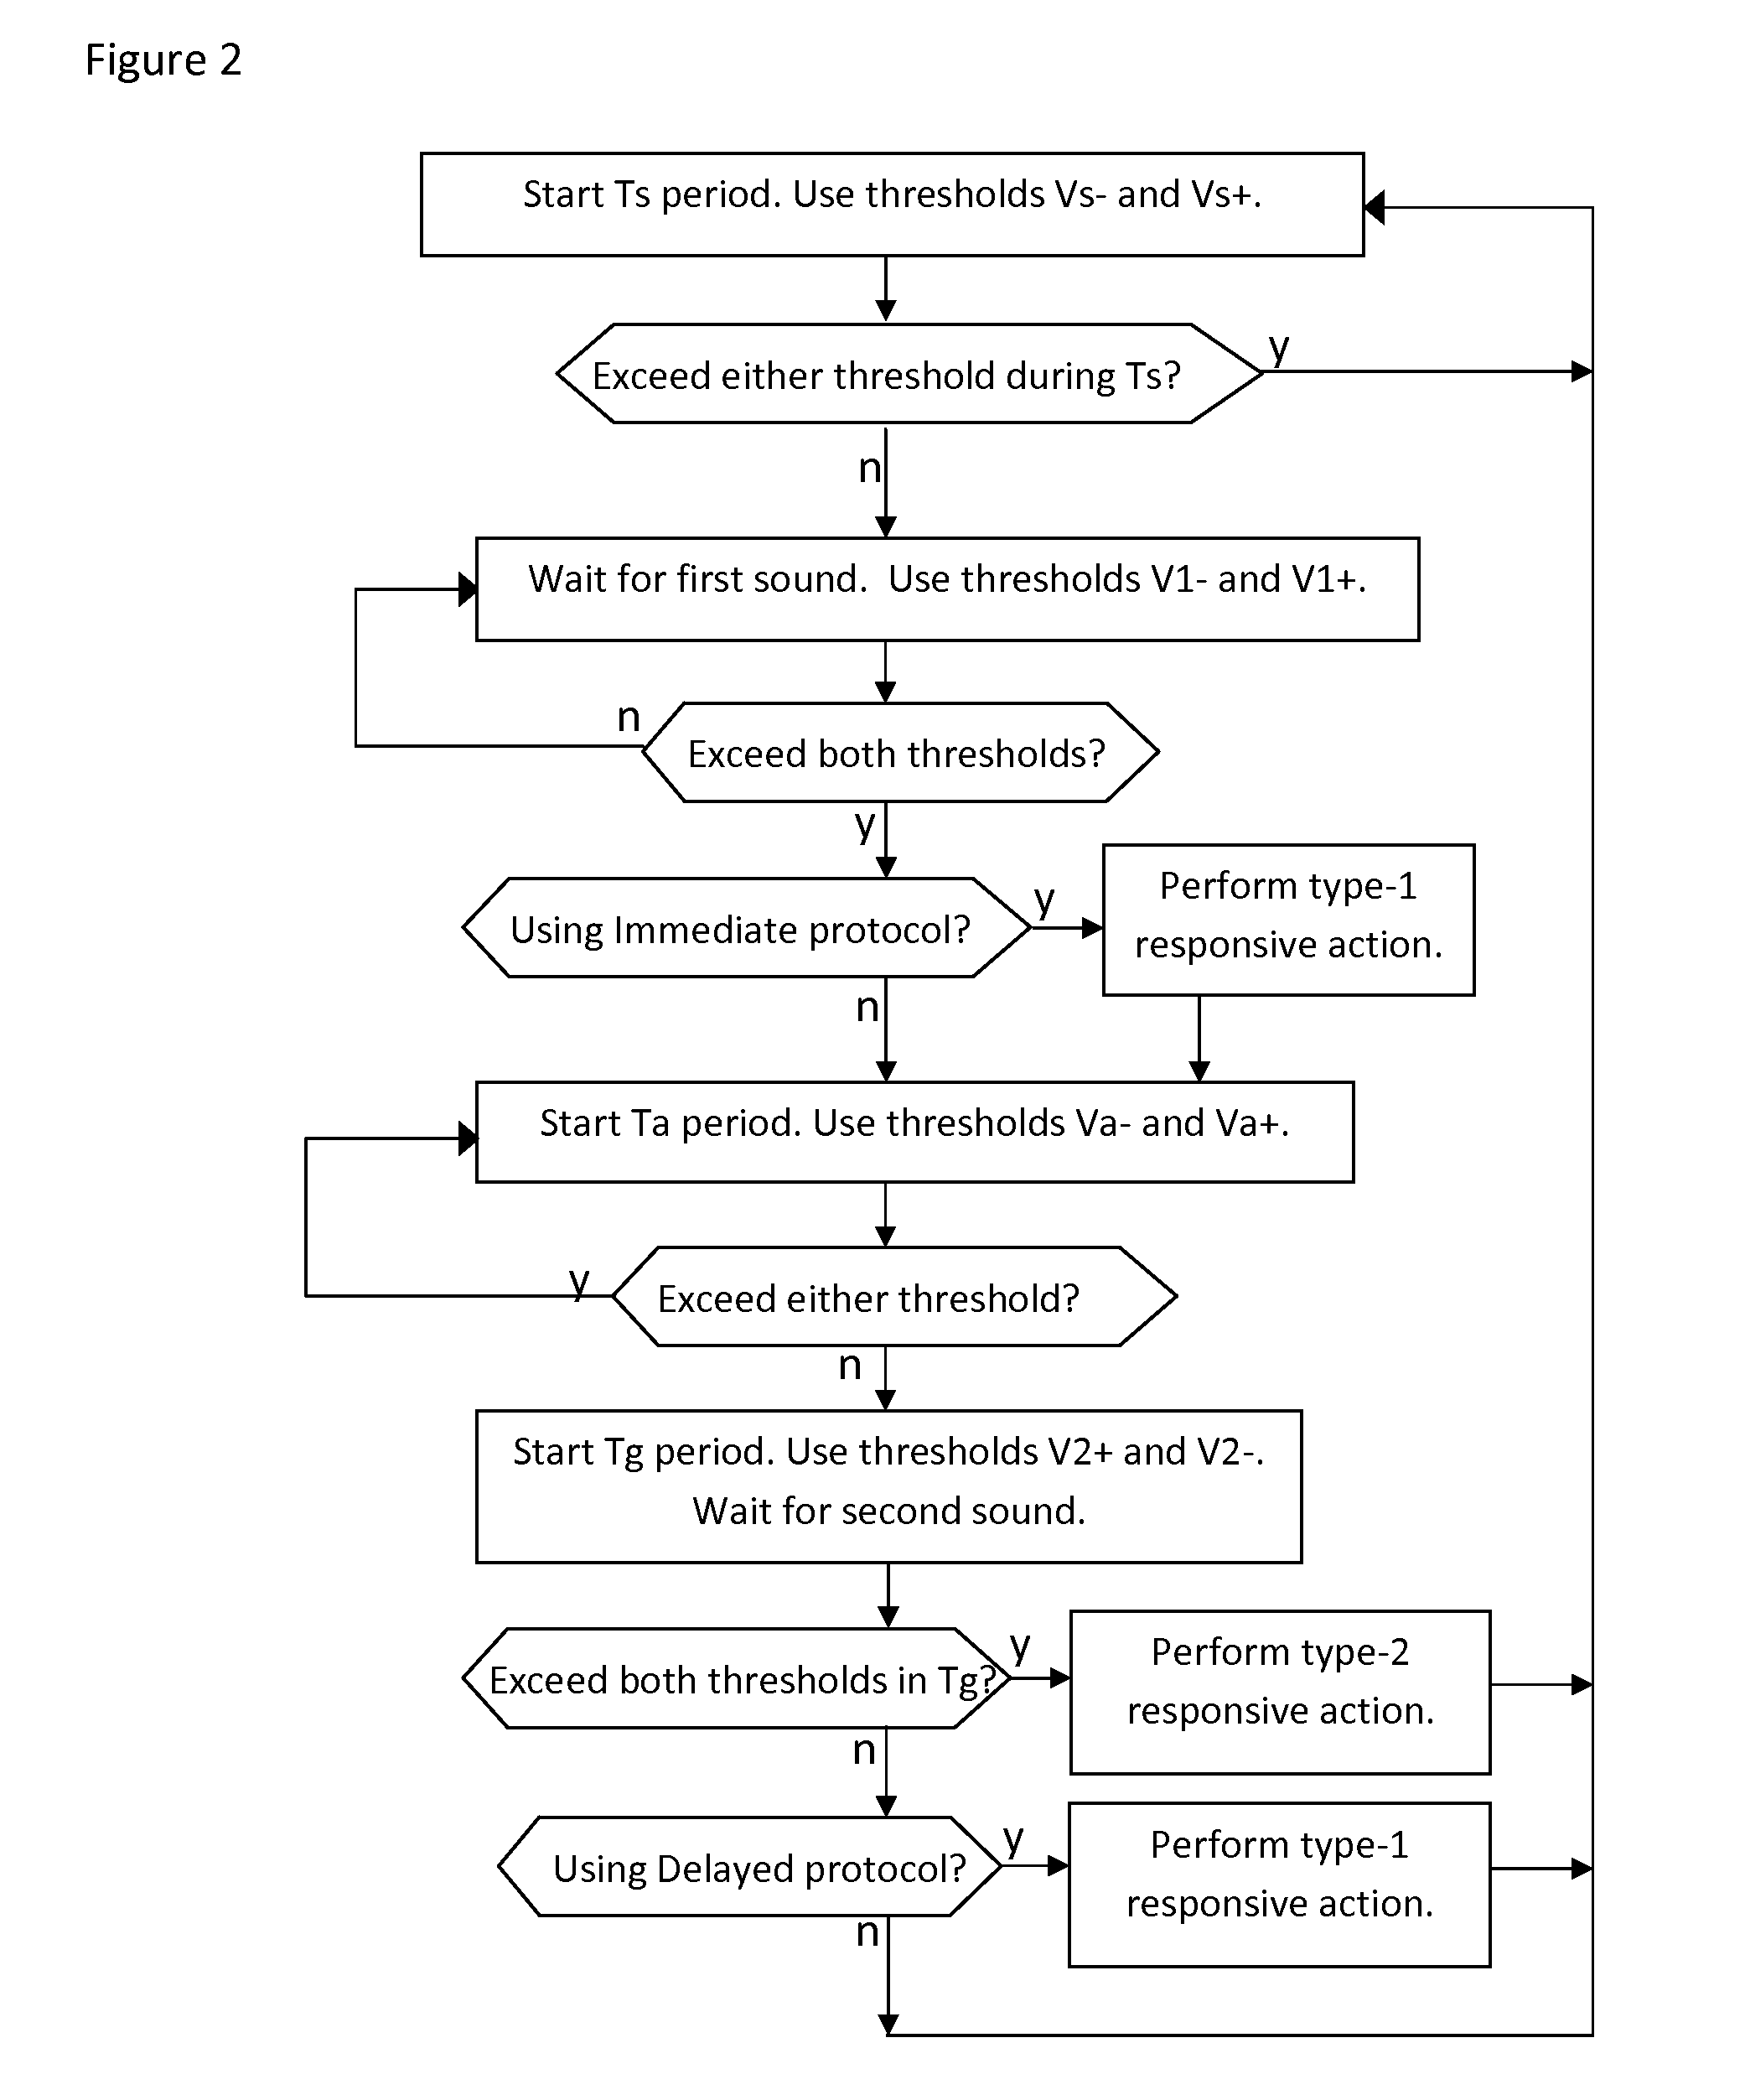
A method is disclosed for controlling a voice-activated device by interpreting a spoken command as a series of voiced and non-voiced intervals. A responsive action is then performed according to the number of voiced intervals in the command. The method is well-suited to applications having a small number of specific voice-activated response functions. Applications using the inventive method offer numerous advantages over traditional speech recognition systems including speaker universality, language independence, no training or calibration needed, implementation with simple microcontrollers, and extremely low cost. For time-critical applications such as pulsers and measurement devices, where fast reaction is crucial to catch a transient event, the method provides near-instantaneous command response, yet versatile voice control.
Owner:ELOQUI VOICE SYST LLC
FM based radio data system information data messaging
InactiveUS20050282560A1Suitable for useRadio data system/radio broadcast data systemBroadcast specific applicationsReal-time dataExtensible markup
A data messaging system is provided utilizing the FM based radio data system that utilizes existing RDS receiver hardware enabled to receive location specific traffic and / or weather information. An extensible markup language (XML) is used to enable the existing hardware capabilities of RDS capable FM radios. Utilization of XML technology will allow RDS display of various applications that are language independent, particularly, real time data messaging of traffic messages generated as XML output.


Owner:E RADIO USA
Voiced interval command interpretation
InactiveUS8781821B2Small volumnGuaranteed economic efficiencySpeech recognitionMicrocontrollerMeasurement device
A method is disclosed for controlling a voice-activated device by interpreting a spoken command as a series of voiced and non-voiced intervals. A responsive action is then performed according to the number of voiced intervals in the command. The method is well-suited to applications having a small number of specific voice-activated response functions. Applications using the inventive method offer numerous advantages over traditional speech recognition systems including speaker universality, language independence, no training or calibration needed, implementation with simple microcontrollers, and extremely low cost. For time-critical applications such as pulsers and measurement devices, where fast reaction is crucial to catch a transient event, the method provides near-instantaneous command response, yet versatile voice control.


Owner:ELOQUI VOICE SYST LLC
System and method to permit language independence for web interfaces
ActiveUS7958442B2Natural language data processingExecution for user interfacesDocumentation procedureEvent trigger


Owner:SANGOMA US INC
Generalized language independent index storage system and searching method
InactiveUS8099416B2Television system detailsDigital data information retrievalLanguage independenceDatabase
The invention may be embodied as a system having and / or a method utilizing a searchable database of index information. Each index in the database may have (a) at least one descriptor, which matches an entry that a user might provide in order to identify an item, (b) a first pointer which identifies a location of the item, and (c) a second pointer which identifies a location of information that may be helpful to the user in deciding whether to request retrieval of the item. The first pointers of one index may be the same as first pointers in a different index. The second pointer may identify a general class to which an item belongs.


Owner:ZI CORPORATION OF CANADA INC
System and method to permit language independence for web interfaces
ActiveUS8869015B2Natural language data processingExecution for user interfacesDocumentation procedureEvent trigger
A device user interface in which language is decoupled from a document is disclosed. The language content is stored separately from the document structure and may be located on a content specific server or on a language server. The language server permits centralized collection of language-related content and language services. The document without the language content acts like a template that can be populated with any type of language-related content. The language content can be provided in a separate file together with associated identifiers, and can be loaded into a cache or document object model (DOM) for processing. An XML file may be used for the language file, and the document may be constructed using HTML code. Document components can be assigned event handlers that cause pop-up boxes to be loaded and displayed with language-related content upon an event trigger.


Owner:SANGOMA US INC
Code level component assembly method based on grammar reconstruction
InactiveCN101446895BGuaranteed reusabilityImprove reusabilitySpecific program execution arrangementsProcess integrationSoftware engineering
The invention relates to the technical field of software engineering, in particular to a code level component assembly method based on grammar reconstruction in software development. The code level component assembly method based on the grammar reconstruction comprises the following steps: 1) expanding a normative grammar of a program language and establishing a new normative grammar which causesthe language to be capable of being constructed and assembled; and 2) assembling the code level components created according to the new normative grammar. The assembly method has the advantage of independent language, and can be used for software reuse in various fields. The method can support business process integration and reuse in different application fields and the customization and the integration of personalized services oriented to users by combining with a field component library.


Owner:ZHEJIANG UNIV
Method and apparatus for language independent voice indexing and searching
InactiveCN101636732ADigital data information retrievalSpeech recognitionDialog managerLanguage representation
A method and apparatus for language independent voice searching in a mobile communication device is disclosed. The method may include receiving a search query from a user of the mobile communication device (4200), converting speech parts in the search query into linguistic representations (4300) which covers at least one languages, generating a search phoneme lattice based on the linguistic representations (4400), extracting query features from the search phoneme lattice (4500), generating query feature vectors based on the extracted features (4600), performing a coarse search using the query feature vectors and the indexing feature vectors from the indexing database (4700), performing a fine search using the results of the coarse search and the indexing phoneme lattices stored in the indexing database (4800), and outputting the fine search results to a dialog manager (4900).


Owner:MOTOROLA INC
Automatically identifying unique language independent keys correlated with appropriate text strings of various locales by key search
InactiveUS7953591B2Shorten the timeImprove efficiencyNatural language data processingExecution for user interfacesText stringLanguage independence
A method, system and computer program product for automatically identifying unique language independent keys. A “key search” is performed which searches for various language independent keys in a properties file associated with a value or text string entered in a first locale. A second locale is suggested to narrow the number of language independent keys displayed in connection with the value entered in the first locale. Upon receiving the value for the second locale, another key search is performed, where this key search is performed on the language independent keys displayed in connection with the first value entered in association with the first locale. A unique language independent key may be identified based on this subsequent key search. By performing key searches and suggesting a second locale to narrow the number of language independent keys, the time in identifying a unique language independent key is reduced and efficiency is improved.


Owner:IBM CORP
Language-independent legal contract and intelligent contract consistency measurement method
ActiveCN111651977AConsistent and Effective DistinctionData processing applicationsNatural language data processingSmart contractLanguage independence
The invention discloses a language-independent legal contract and intelligent contract consistency measurement method. The consistency of a legal contract and an intelligent contract is accurately measured. Firstly, partial consistency and complete consistency definitions and measurement indexes of a legal contract and an intelligent contract are proposed; then, rewriting logic and language-independent symbolic execution are fused, a language-independent legal contract and intelligent contract consistency measurement method is provided, and the specific calculable part of the legal contract and the corresponding intelligent contract code are accurately measured to be partially consistent and completely consistent. The method provided by the invention can be used for measuring the consistency of legal contracts described by any language and intelligent contracts developed by any language in a block chain.


Owner:武汉力龙信息科技股份有限公司
Language independent login
InactiveUS8752164B2Safe and secureEasy to mergeElectric signal transmission systemsDigital data processing detailsLanguage independenceComputer science
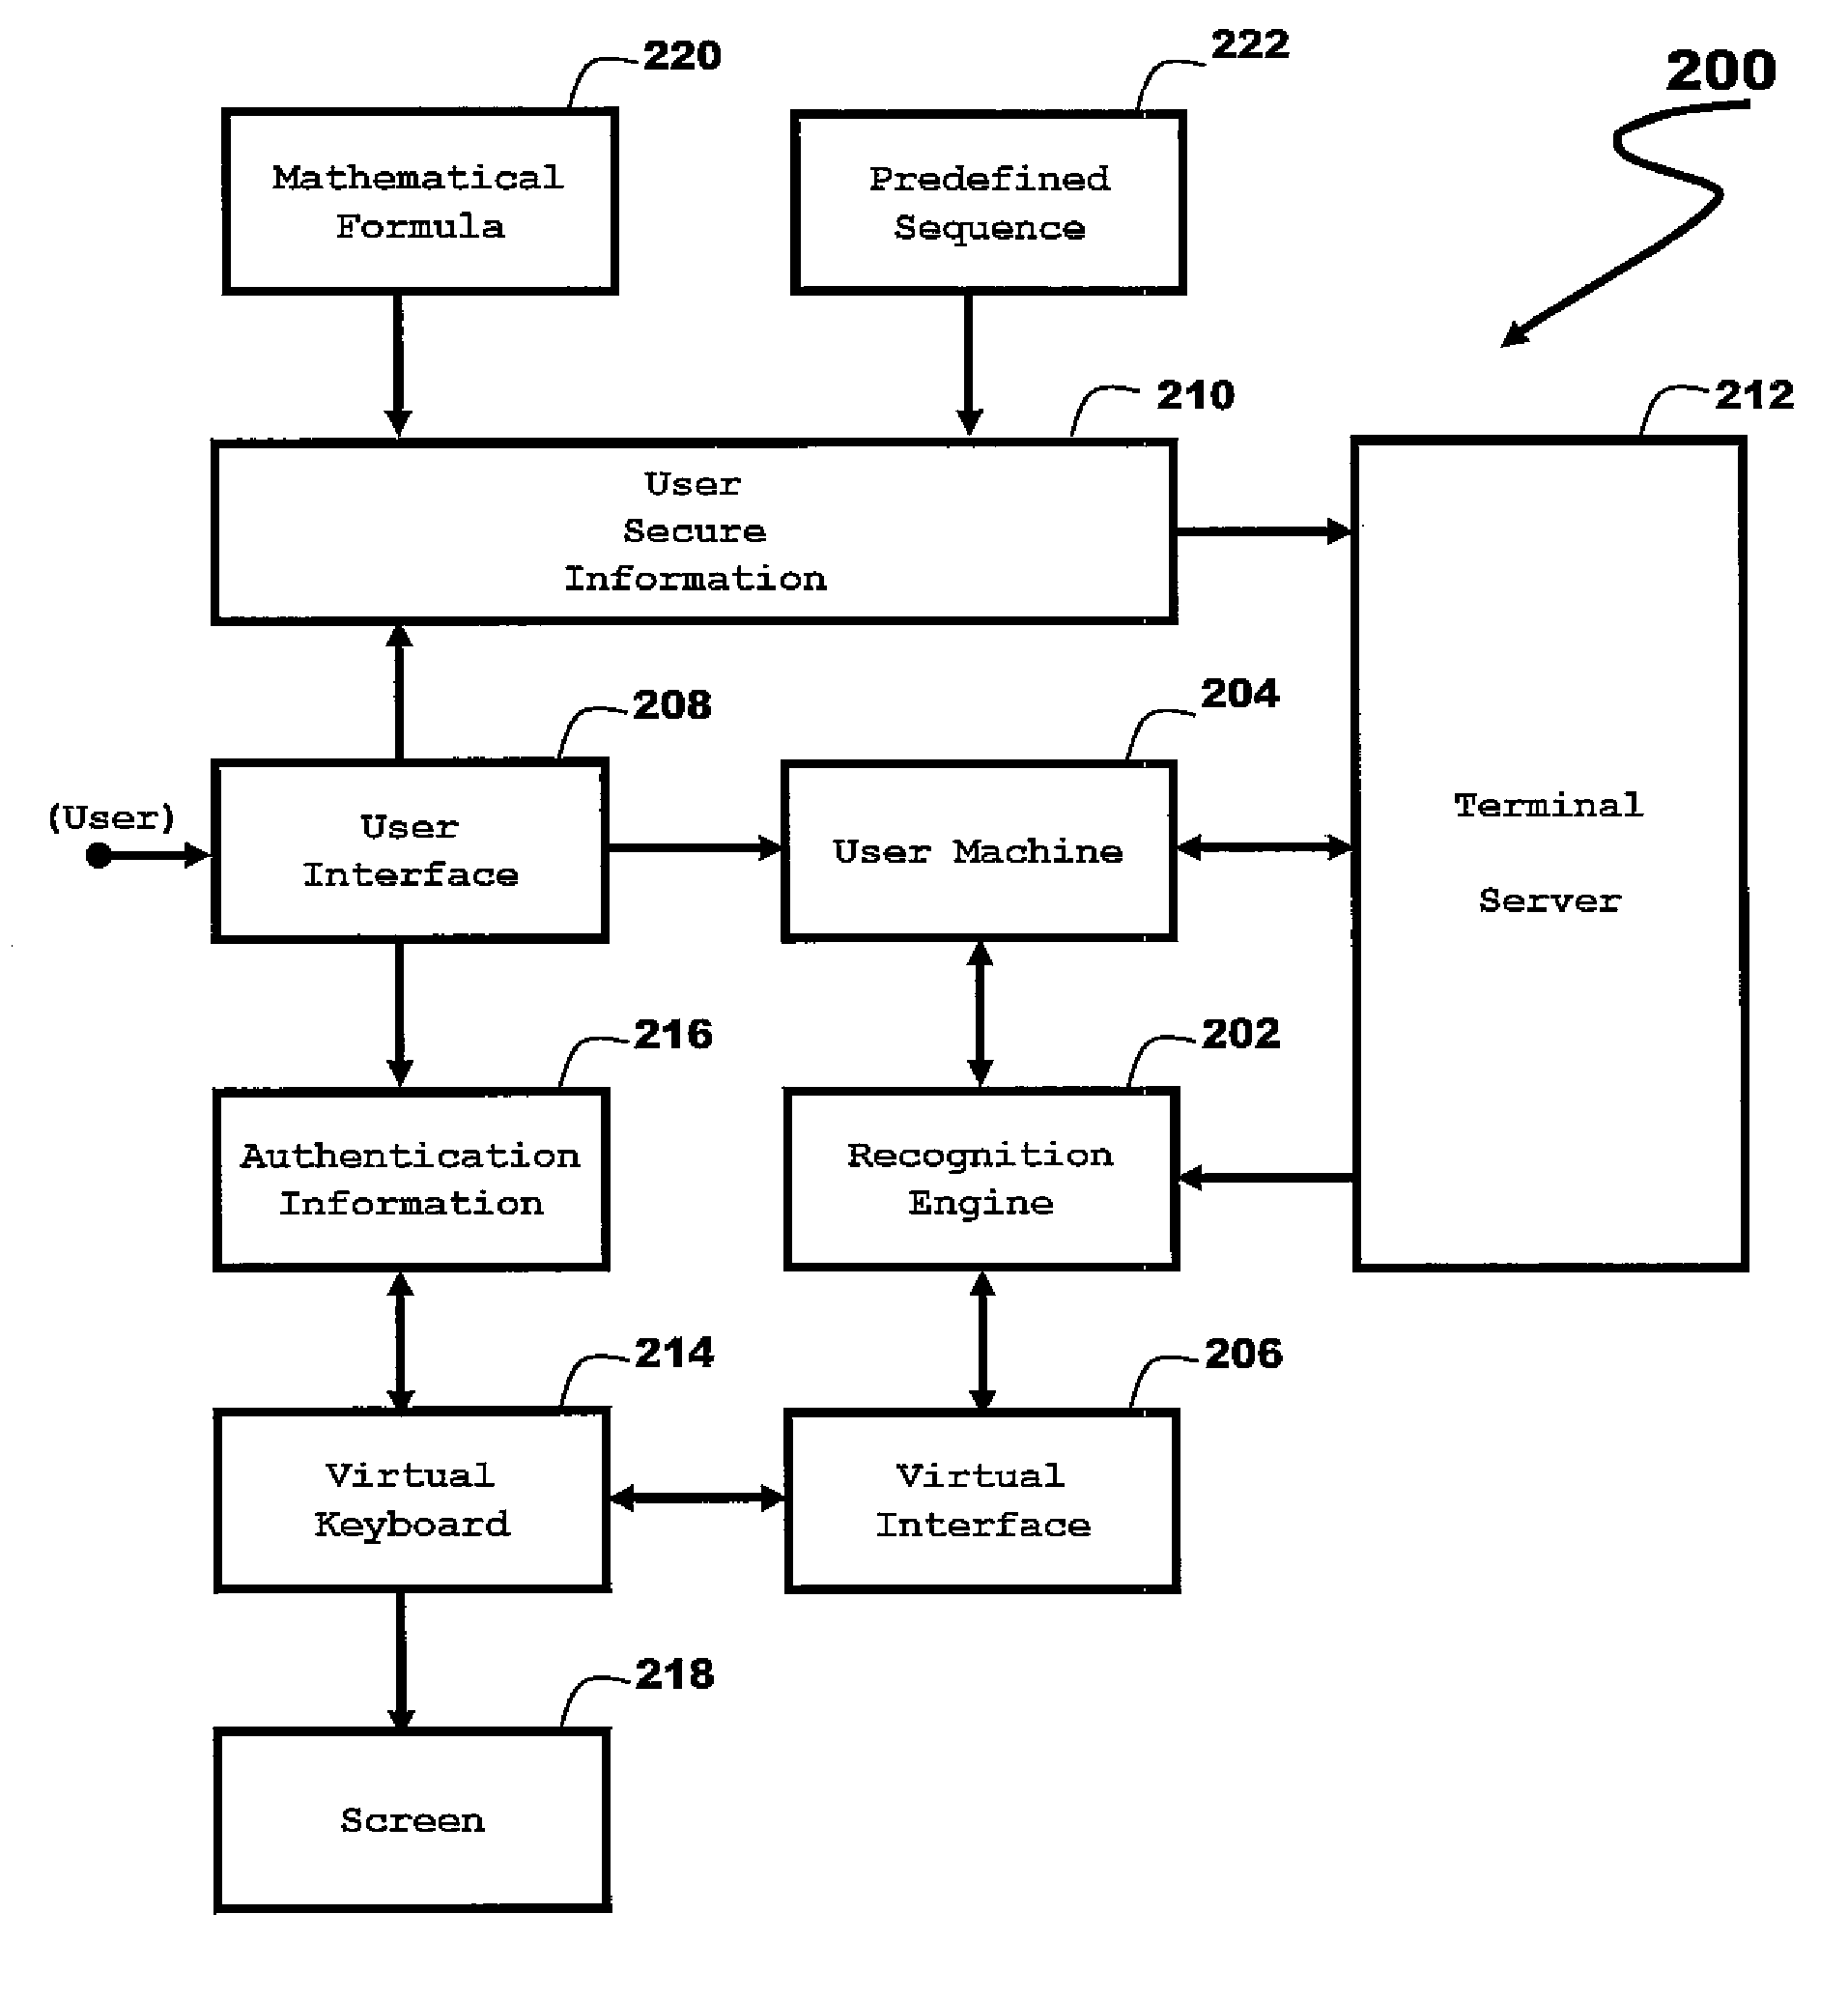
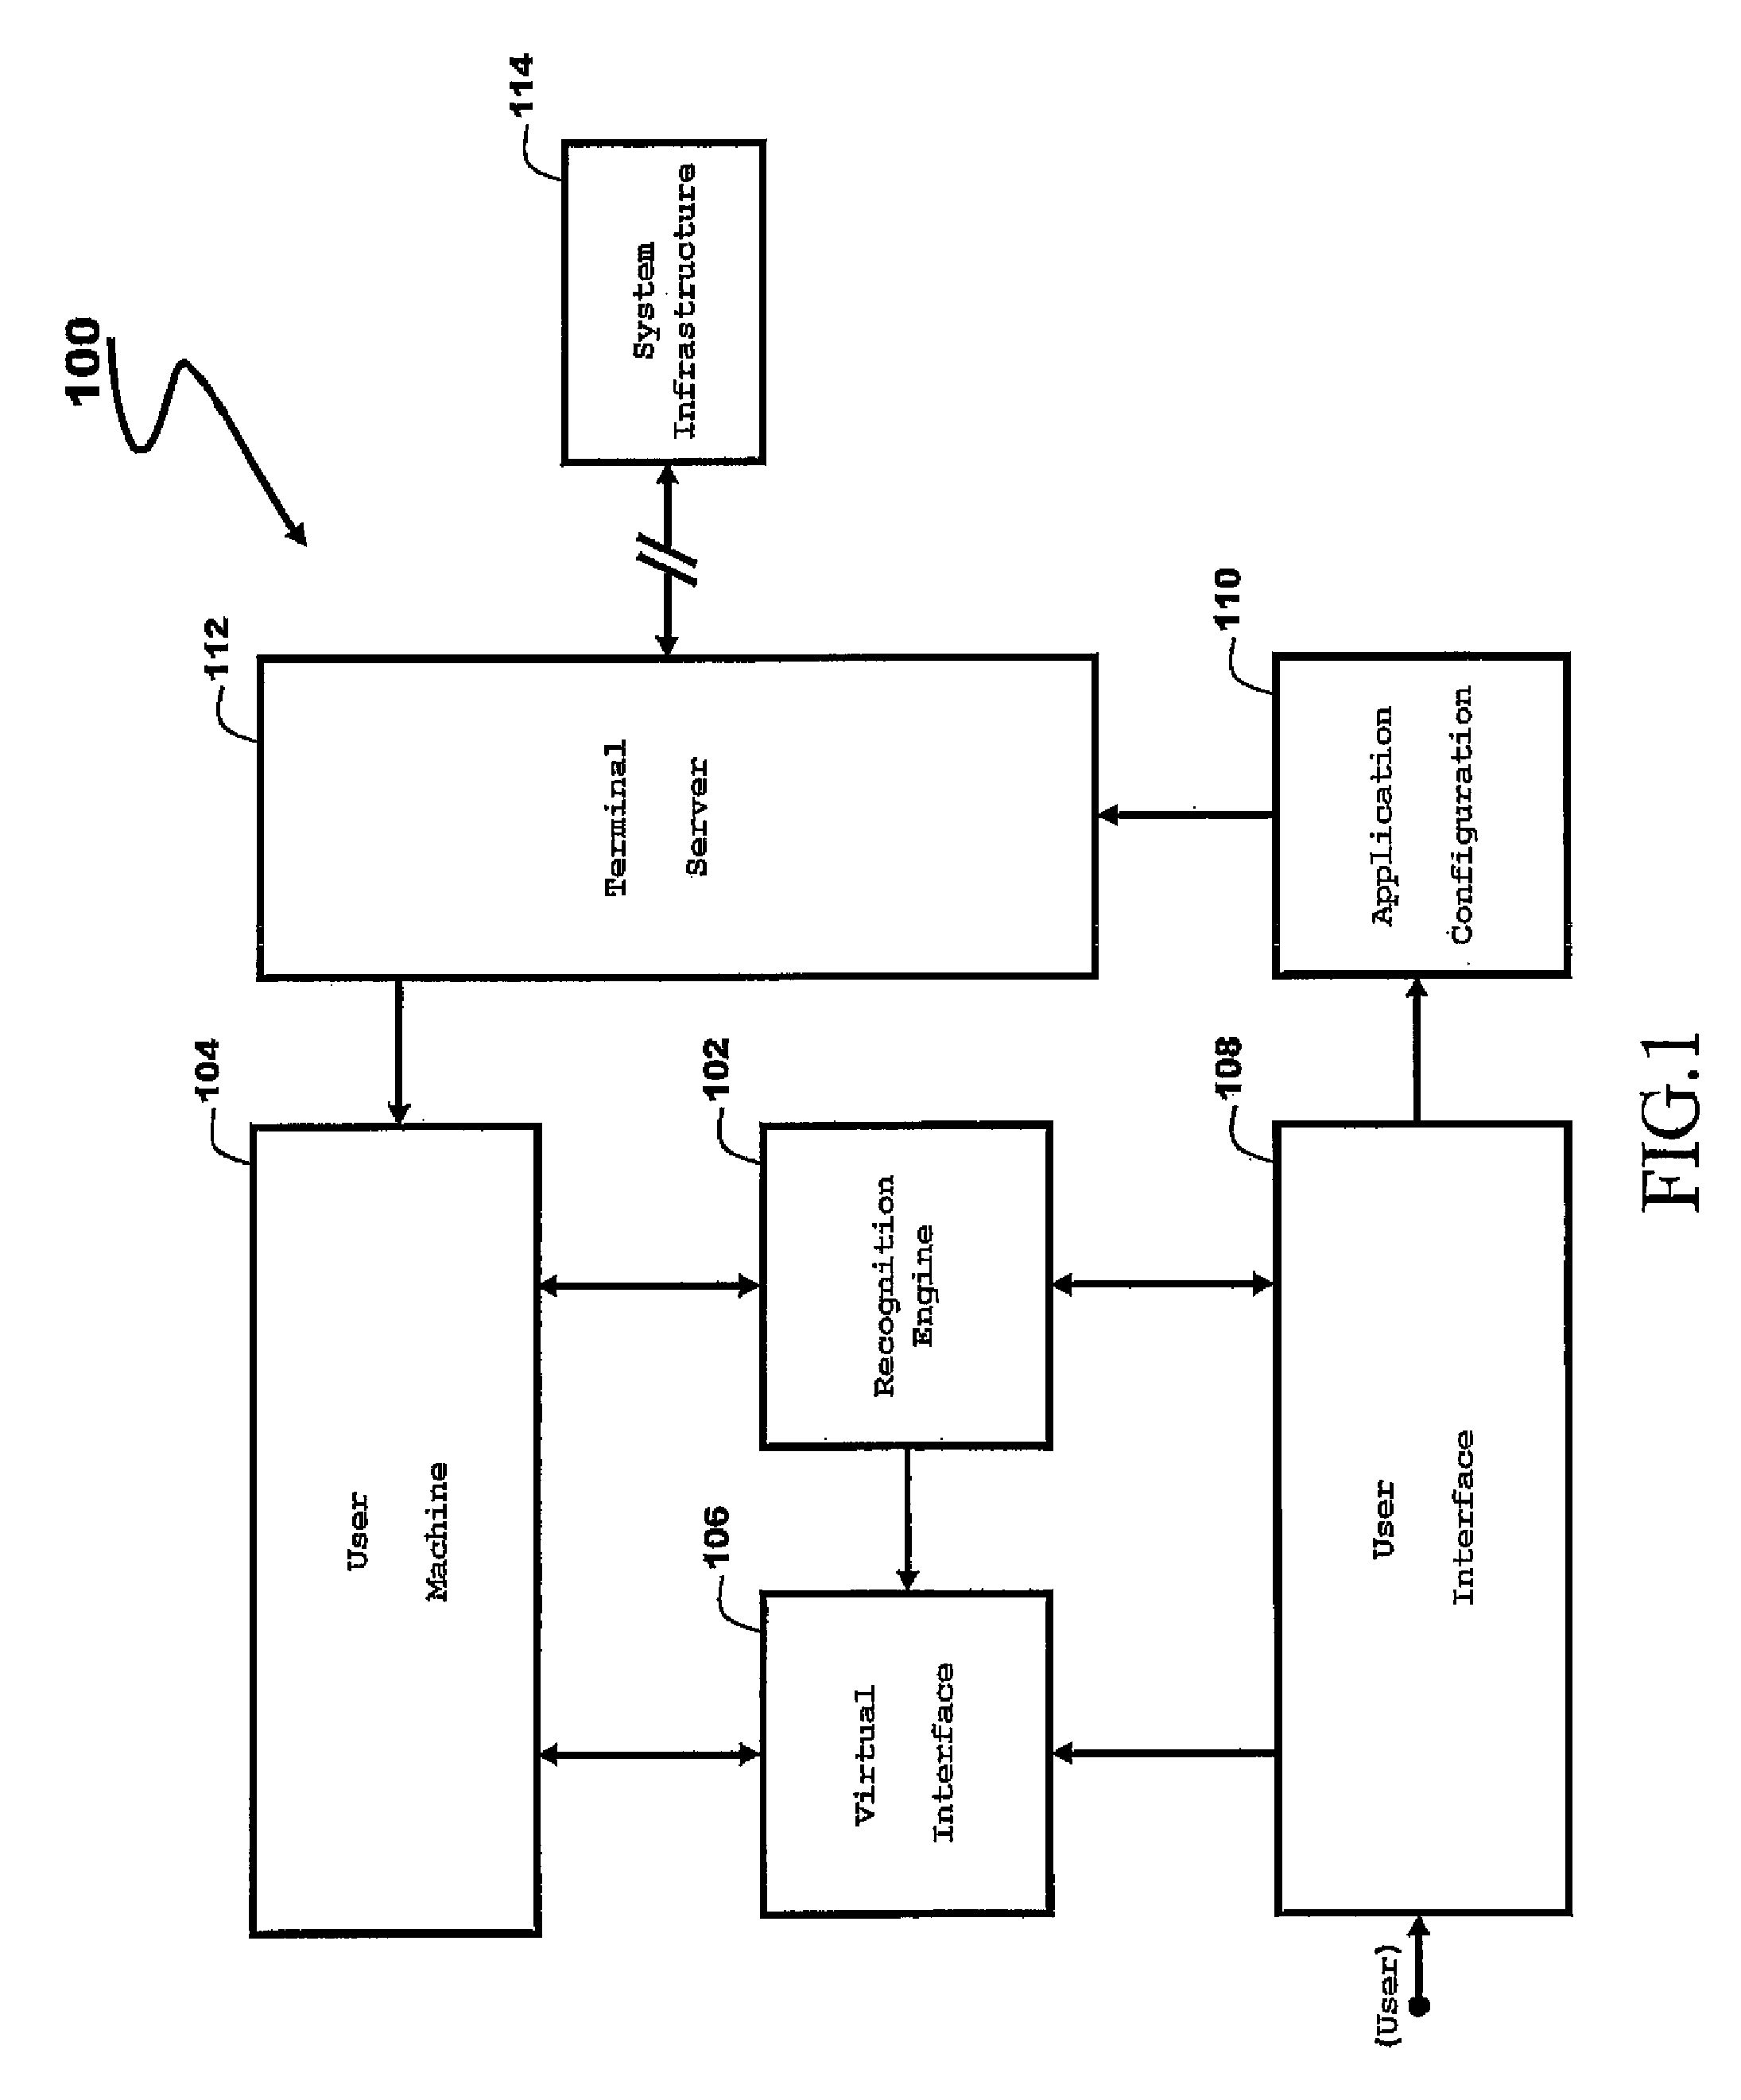
The present invention prevents illegitimate access to a user computing machine. A method in accordance with an embodiment includes: setting an authentication routine in the user computing machine; generating a virtual keyboard on the user computing machine; entering a user identification through the virtual keyboard, the user identification being entered according to a virtual keyboard form factor; comparing the entered user identification with a secure user identification previously stored in the user computing machine; and validating the user access to the user computing machine if a match occurs, otherwise denying access.
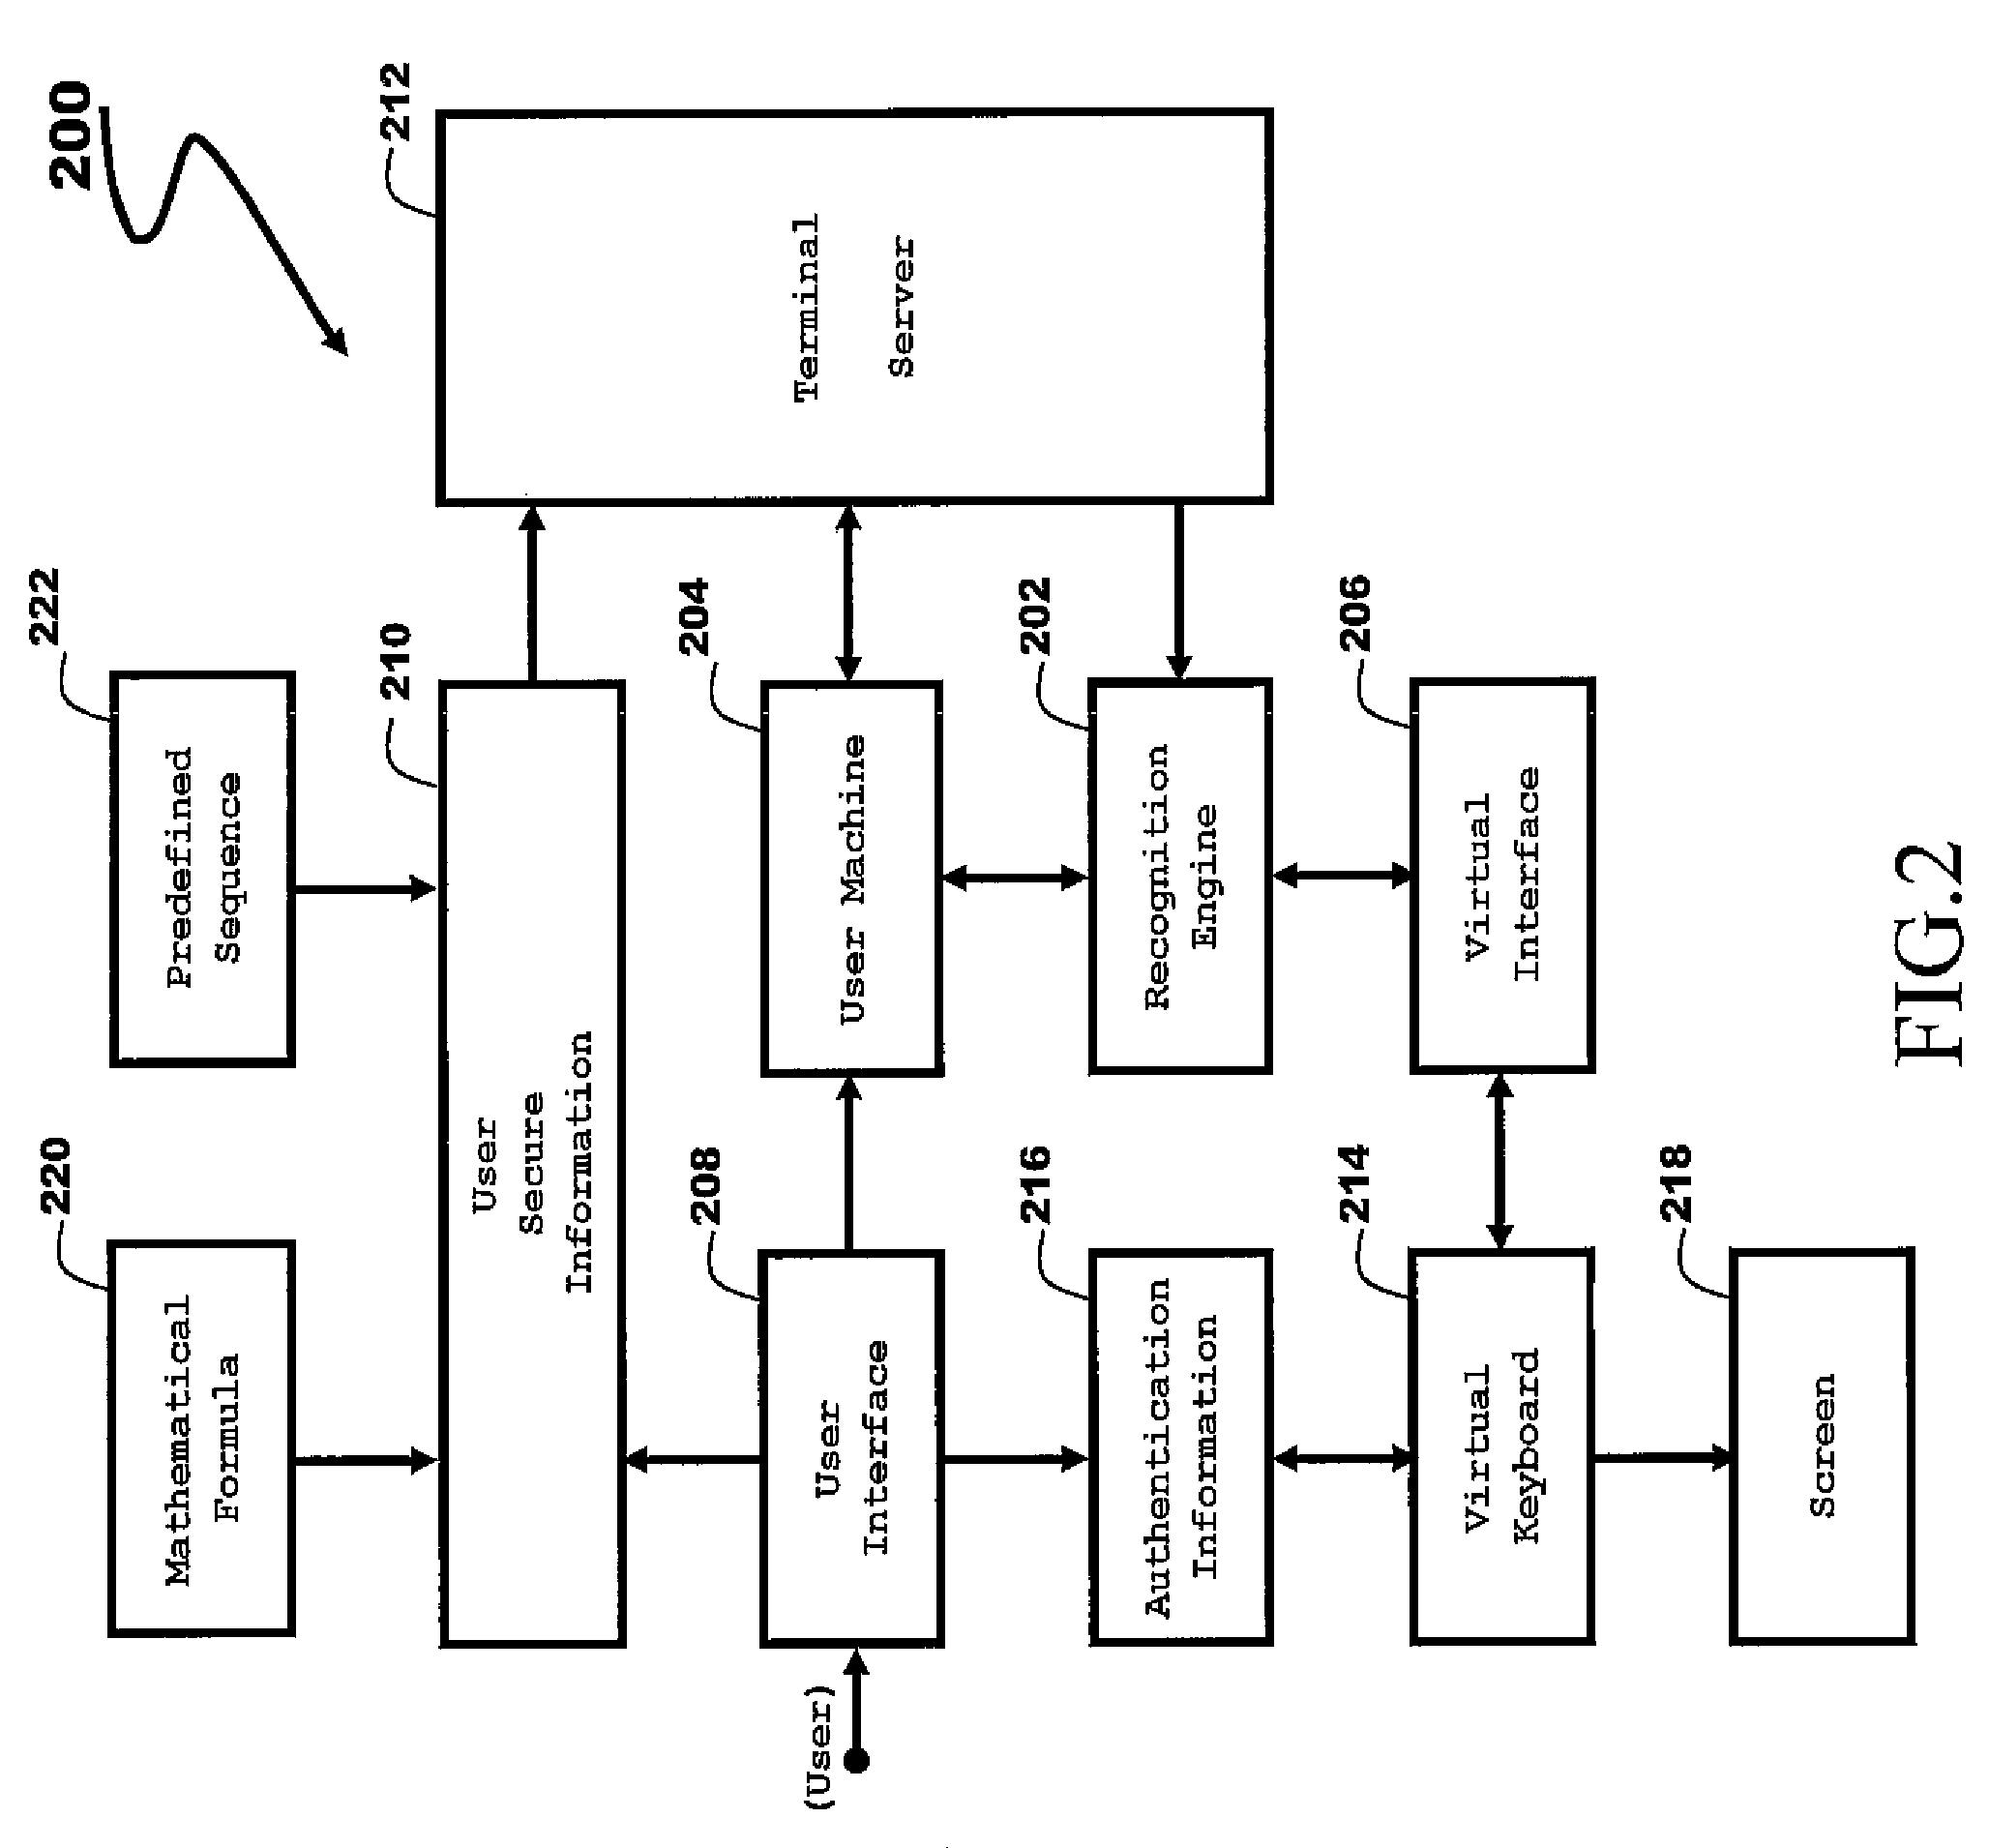
Owner:IBM CORP
Language data preprocessing method for multilingual and complex scene
The invention relates to the technical field of language data processing, and discloses a language data preprocessing method in a multilingual and complex scene, which is a voice data preprocessing system in the multilingual and complex scene based on an AutoPrep framework, integrates five modules, namely a voice enhancement module, a voice segmentation module, a speaker clustering module, a target voice extraction module and a quality filtering module. According to the scheme, differential suppression of steady-state noise and transient-state noise in multilingual voice signals is realized, and particularly in a small language (such as Kazakh and Talanx) scene, the voice signal-to-noise ratio and the language independence of voice features are effectively improved, so that the voice data can be automatically and structurally processed, and the voice signal-to-noise ratio and the language independence of the voice features can be effectively improved. The problem that in the prior art, the phoneme mapping error rate is high due to the fact that small languages lack an exclusive phoneme system processing module is solved, and the availability and the processing effect of low-resource language data are enhanced.

Owner:SHENYI FUTURE TECHNOLOGY (GUANGDONG HENGQIN) CO LTD
Function generation method and device, equipment and medium
PendingCN111651146AImprove experienceFlexible demandProgramming languages/paradigmsCode compilationUser needsSoftware engineering
The invention discloses a function generation method and device, equipment and a medium, and the method comprises that: a client side responds to a function node creation instruction, creates a function node in the client side, and transmits operation data during the creation of the function node to a server, so that the server can also create function nodes with the same parameters in an addressspace. And after the client acquires the function code edited by the user, a value is assigned to a function node in the client, and operation data during function assignment is sent to the server, sothat the server can assign the value to the function node in the address space to obtain an operable function with a logic function. According to the method provided by the embodiment of the invention, the function creation right can be given to the user, the flexible and changeable user requirements can be better met, and the user experience is improved. In addition, in the method, the functioncodes can be hosted through a function, namely a platform, so that a user can select a proper language to realize code logic, and language independence is achieved.


Owner:NINGBO GEELY AUTOMOBILE RES & DEV CO LTD +1
A language-independent measure of consistency between legal contracts and smart contracts
ActiveCN111651977BConsistent and Effective DistinctionData processing applicationsNatural language data processingSmart contractLanguage independence
The invention discloses a language-independent method for measuring the consistency of legal contracts and smart contracts, which accurately measures the consistency of legal contracts and smart contracts. Firstly, the partial consistency and complete consistency definitions and measurement indicators of legal contracts and smart contracts are proposed, and then the rewriting logic and language-independent symbolic execution are combined to propose a language-independent measurement method for the consistency of legal contracts and smart contracts to accurately measure specific Partial and full consistency of computable parts of legal contracts and corresponding smart contract code. The method proposed by the present invention can be used to measure the consistency between legal contracts described in any language and smart contracts developed in any language in the blockchain.


Owner:武汉力龙信息科技股份有限公司
Application development method and device of intelligent robot, terminal equipment and medium
ActiveCN109995711AAchieve independenceReduce the difficulty of application developmentTransmissionApplication programming interfaceTerminal equipment
The invention is suitable for the technical field of robots, and provides an application development method of an intelligent robot, terminal equipment and a medium, and the method comprises the steps: starting a remote procedure call protocol RPC client pre-installed on the terminal equipment; establishing a communication connection with an intelligent robot running an RPC server through the RPCclient; obtaining associated data corresponding to an application program developed by a user on the terminal equipment; and transmitting the associated data to the intelligent robot, so that the intelligent robot calls an application programming interface API function corresponding to the associated data in a preset SDK library. In the invention, a user does not need to burn the developed executable program to the intelligent robot, so that the operation complexity of application development is reduced; moreover, the user only needs to develop the robot application on the terminal equipment of the user, so that platform independence and language independence of application development are realized, and the application development difficulty of the user on the intelligent robot is reduced.


Owner:上海优必杰教育科技有限公司