

Patents
Literature
125 results about "Language representation" patented technology
Efficacy Topic
Property
Owner
Technical Advancement
Application Domain
Technology Topic
Technology Field Word
Patent Country/Region
Patent Type
Patent Status
Application Year
Inventor
Representation is the production of meaning through language. Representation is an essential part of the process by which meaning is produced and exchanged between members of a culture. It does involve the use of language, of signs and images which stand for or represent things.
Web application internationalization
InactiveUS7784026B1Eliminate needEasy constructionExecution for user interfacesMemory systemsMeta levelWeb page
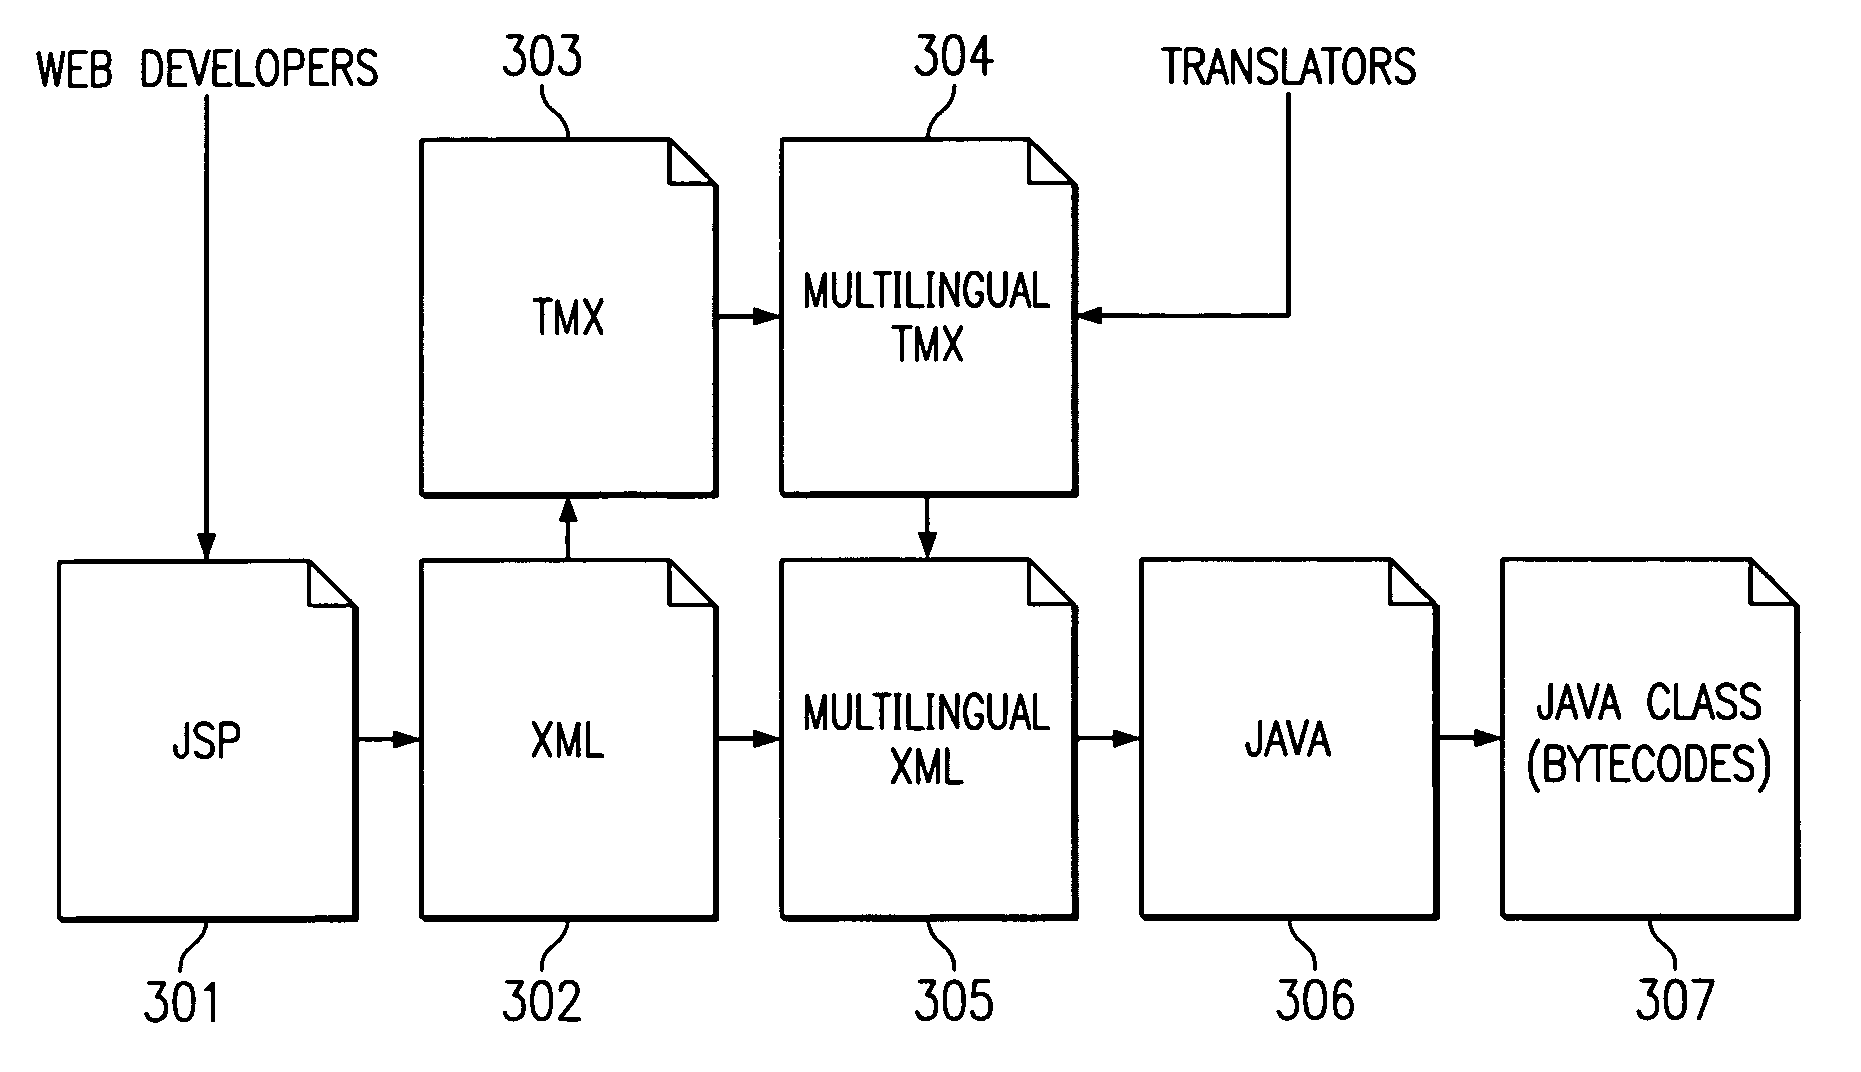
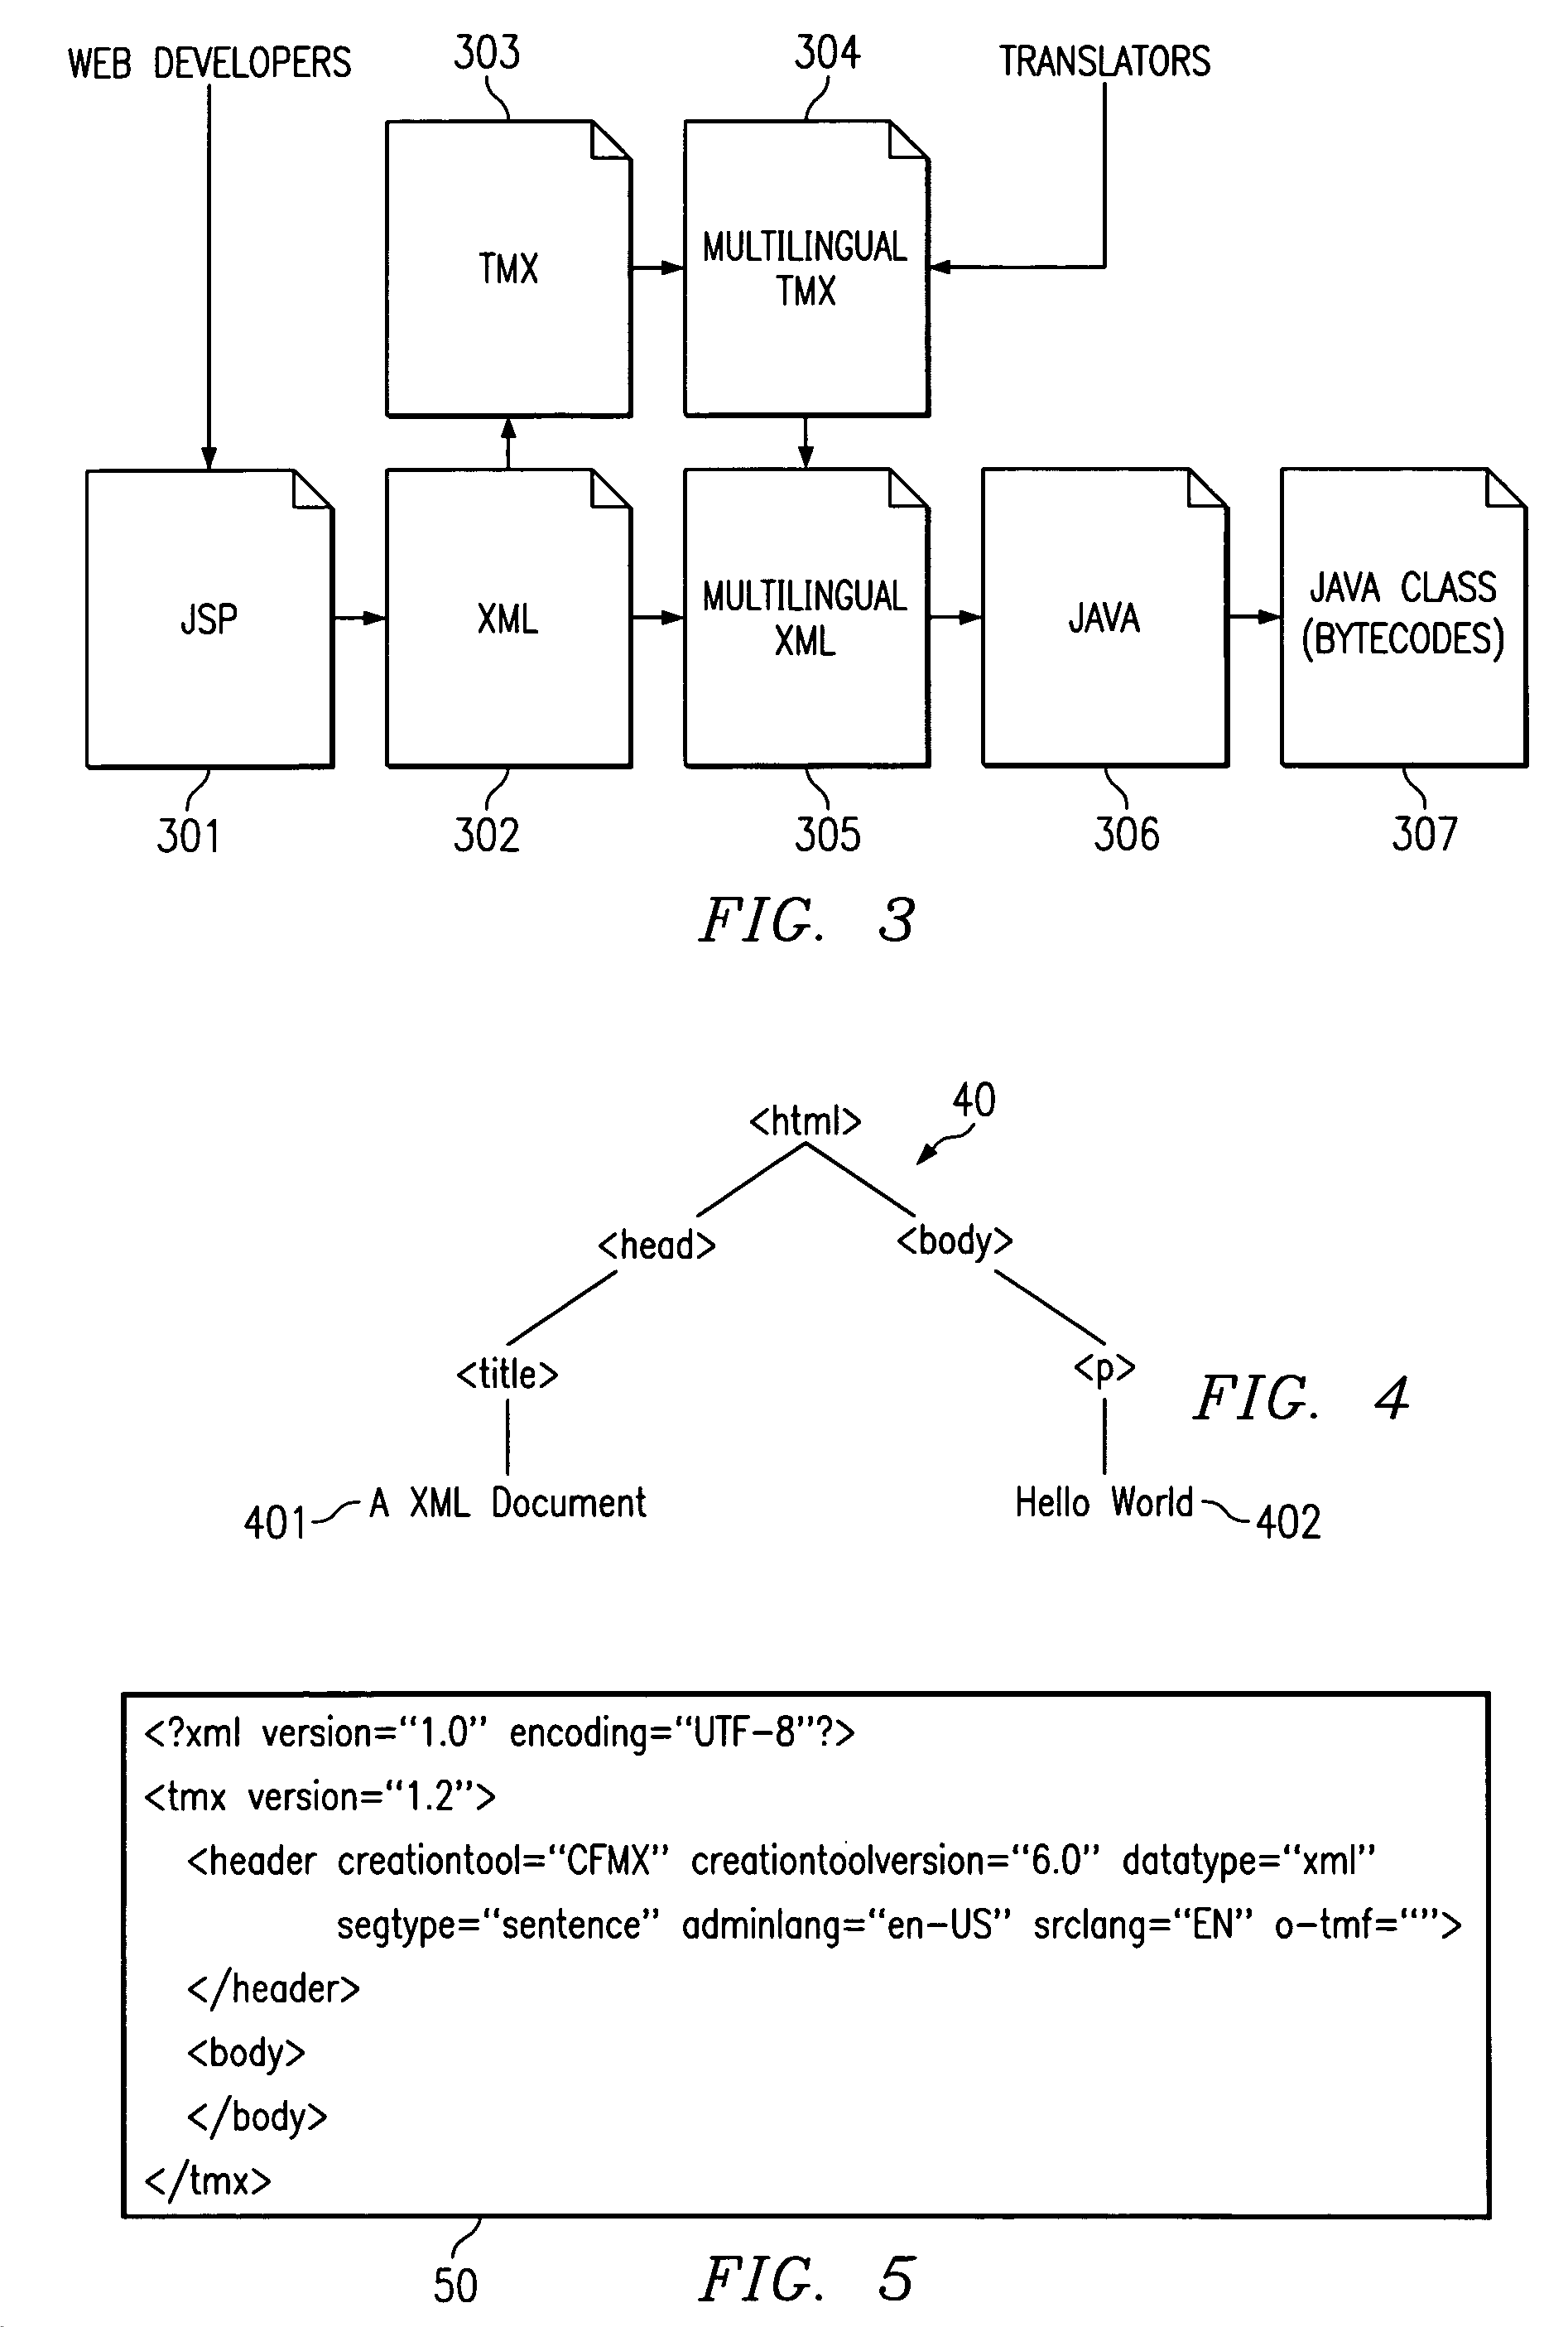
A system and method is described for internationalization of web pages by extracting translatable content from extensible mark-up language (XML), or similar data-centric meta-language representations of web pages or data used to build web pages. The extracted translatable content is stored in a translation task repository (TTR) accessible by the web developer and the translator. The XML representation is then modified to include selection control logic to select the appropriate translations for insertion into the final web page. The translator accesses the TTR to translate the appropriate content and saves the translations back to the TTR associated with the original translatable data. The translations are obtained from the TTR as selection cases for the selection control logic of the XML representation. As the XML is converted into the web source code, the selection logic and translations are embedded therein facilitating building the web site in multiple different languages.
Owner:ADOBE INC
Self-adaptive software vulnerability repairing system based on deep learning
ActiveCN120086865APlatform integrity maintainanceNeural learning methodsSelf adaptive softwareSyntax
The invention discloses a self-adaptive software vulnerability repair system based on deep learning. The self-adaptive software vulnerability repair system comprises a multi-modal feature fusion engine, a spatio-temporal joint modeling module, a vulnerability repair strategy generator and a cross-language representation model. The multi-modal feature fusion engine generates a mixed feature vector of a code, inputs the mixed feature vector into the spatio-temporal joint modeling module, captures code structure and time sequence dependence, and identifies risk features; the vulnerability repair strategy generator generates a repair scheme based on the risk features and optimizes the repair scheme through static verification; and the cross-language representation module performs feedback training by using the newly added sample and outputs a final detection result and a repair scheme. According to the method, the vulnerability trigger points can be accurately positioned, all the associated code snippets are extracted, a solid foundation is provided for subsequent vulnerability analysis, and the repaired codes conform to grammatical rules and keep original semantic consistency.

Owner:ANHUI PERCEPTION FUTURE ELECTRONIC TECH CO LTD
Systems and methods for vision-and-language representation learning
ActiveUS12271792B2Natural language analysisCharacter and pattern recognitionPattern recognitionComputer vision

Owner:SALESFORCE INC
Systems and Methods for Language-Based Three-Dimensional Interactive Environment Construction and Interaction
A computing system may include a communication interface configured to receive from a first client machine a natural language description of a three-dimensional environment. A path embedding generator may determine a path language representation of a three-dimensional virtual environment based on the natural language description and via a large language model interface. The path language representation may be generated in accordance with a path language definition and may include one or more entities to include within the three-dimensional virtual environment. An entity of the entities may include a three-dimensional model of the entity and an entity animation rig for animating the entity. The path language representation may include a script governing behavior of the one or more entities and including one or more events. The three-dimensional virtual environment may be presented at a second client machine upon request.

Owner:POLYUP INC
Knowledge graph construction method and device for target culture resources and electronic equipment
PendingCN119539044Aquality improvementSemantic analysisKnowledge representationLinguistic modelEngineering
The invention belongs to the technical field of computers, and particularly discloses a knowledge graph construction method and device for target culture resources and electronic device.The method comprises the steps that knowledge graphs of multiple different fields are obtained, and a big language model is trained based on the knowledge graphs to obtain a big language model; integrating the structured information of the knowledge graph into the language representation of a large language model; obtaining target culture resource related text data, and performing fine tuning on the large language model based on the target culture resource related text data; performing knowledge extraction on the target cultural resource related text data through the fine-tuned large language model to obtain related knowledge in a triple form; and constructing the knowledge graph based on the related knowledge in the triple form, so that the problem that the knowledge graph construction presentation result is relatively poor due to the sparse target culture resource data sample in the prior art can be solved.

Owner:HAINAN UNIV
Natural language generation
Techniques for determining when speech is directed at another individual of a dialog, and storing a representation of such user-directed speech for use as context when processing subsequently-received system-directed speech are described. A system receives audio data and / or video data and determines therefrom that speech in the audio data is user-directed. Based on this, the system determine whether the speech is able to be used to perform an action by the system. If the speech is able to be used to perform an action, the system stores a natural language representation of the speech. Thereafter, when the system receives system-directed speech, the system generates a rewrite of a natural language representation of the system-directed speech based on the previously-received user-directed speech. The system then determines output data responsive to the system-directed speech using the rewritten natural language representation.

Owner:AMAZON TECH INC
Retrieval augmentation system for unstructured tabular documents
ActiveUS12511320B1Natural language data processingText database indexingSpread sheetLinguistic model
A system for extracting a number of data elements from one or more data sources. A text representing tables using a markdown language is extracted from spreadsheets and or other grid-based documents. The text is provided to a language model with a prompt. The prompt may be a chain-of-thoughts prompt. The prompt includes several requests and / or steps that cause the language model to extract one or more tables from the spreadsheet and output the tables using the markdown language or a different markdown language. The tables extracted from the spreadsheet are converted into table chunks and indexed for retrieval by a retrieval augmented architecture. When a prompt to extract particular information from the spreadsheet is provided, one or more relevant table chunks are identified and provided to a language model for extraction. Using the language model to separate tables improves information extraction accuracy while maintaining downstream instructions.

Owner:AMERICAN INTERNATIONAL GROUP INC
Method and system for integrating code structure into large model based on multiple modes
ActiveCN119576389Aeasy to handleSoftware maintainance/managementEnergy efficient computingLinguistic modelData stream
The invention belongs to the technical field of computers, and particularly discloses a method and system for integrating a code structure into a large model based on multiple modalities, and the method comprises the steps: obtaining a code attribute graph corresponding to a code text; inputting the code attribute graph to a graph encoder, and obtaining a graph structure representation output by the graph encoder; the code text and the graph structure representation are input to a large language model, a code processing result output by the large language model is obtained, and the large language model is used for processing the code according to the code processing task based on the code text and the graph structure representation; wherein the graph structure representation and the serialization language representation are kept aligned in a representation space, and the serialization language representation is obtained by performing serialization processing on a code text by a text encoder in a large language model. According to the method, the multi-modal encoder is introduced, so that different modal information, such as grammar, semantics, control flow and data flow, of the code can be fused and processed, and the understanding ability of a large model to a code structure can be remarkably improved.


Owner:武汉金银湖实验室
Diffusion counterfeit face detection and positioning method based on multi-domain visual language reconstruction
The invention relates to the technical field of counterfeited face detection methods, in particular to a diffusion counterfeited face detection and positioning method based on multi-domain visual language reconstruction. The method comprises the following steps: firstly, carrying out spatial information learning on a diffusion counterfeit face image to respectively extract local and global spatial image features, carrying out prompt learning on a fine-grained text corresponding to the image to extract global language representation, and then reconstructing the image by utilizing the local spatial features to enhance spatial representation and obtain a residual image; the method comprises the following steps of: firstly, acquiring a residual image, learning the residual image to extract a residual feature, then combining the image feature with the residual feature to obtain a visual manipulation feature, reconstructing global language representation to reinforce language representation, and finally combining the language feature with the visual feature to learn multi-modal representation of a diffusion counterfeit face. And utilizing the model to learn visual manipulation features of the diffusion counterfeit face to realize detection and positioning of the diffusion counterfeit face. According to the method, the counterfeit detection and positioning efficiency and the cross-modal detection capability can be improved.

Owner:QILU UNIVERSITY OF TECHNOLOGY (SHANDONG ACADEMY OF SCIENCES) +2
Systems and methods for language-based three-dimensional interactive environment construction and interaction
PCT designated stage expiredWO2025024353A2Natural language analysisNeural learning methodsPathPingCommunication interface
A computing system may include a communication interface configured to receive from a first client machine a natural language description of a three-dimensional environment. A path embedding generator may determine a path language representation of a three-dimensional virtual environment based on the natural language description and via a large language model interface. The path language representation may be generated in accordance with a path language definition and may include one or more entities to include within the three-dimensional virtual environment. An entity of the entities may include a three-dimensional model of the entity and an entity animation rig for animating the entity. The path language representation may include a script governing behavior of the one or more entities and including one or more events. The three-dimensional virtual environment may be presented at a second client machine upon request.

Owner:POLYUP INC
System and method for deploying large language model (LLM) on one or more edge devices
PCT designated stage expiredWO2025079104A1Machine learningNeural learning methodsData sourceEngineering
The present disclosure relates to a method for deploying an LLM on one or more edge devices by one or more processors (202) The method includes selecting at least one of, a server and one or more resources from a server pool. Further, the method includes collecting textual data from one or more data sources upon selecting the at least one of, the server and the one or more resources. Further, the method includes pre-training the LLM with a corpus of textual data to enable the LLM to learn general language representation. Further, the method includes training the pre-trained model with the collected textual data using at least one of, the server and the one or more resources. Further, the method includes compressing the trained model. Further, the method includes deploying the compressed trained model onto one or more edge devices.

Owner:JIO PLATFORMS LTD
Chinese grammar error correction method based on detection and pinyin joint enhancement
PendingCN119203998AInternal combustion piston enginesBiological modelsPhonological codingEngineering
The invention relates to a Chinese grammar error correction method based on detection and pinyin joint enhancement, and belongs to the technical field of natural language processing. According to the method, firstly, an end-to-end grammar error correction basic model is constructed by utilizing an original pre-training language model BART, and the model can improve the error correction performance by utilizing the strong language representation capability of the BART. And then, after the coding stage of the BART model is finished, an error detection layer is added, and the detection layer aims to alleviate the problem of over-correction of the model by accurately identifying errors. Meanwhile, a private pinyin encoder is used for learning pinyin information representation of characters, the representation is combined with text information representation through a cross attention mechanism, and then text representation fused with pinyin information is obtained. And finally, a self-adaptive gating mechanism is adopted to filter out harmful components in the pinyin information, so that the accuracy and the reliability of the finally obtained text information representation are ensured.

Owner:KUNMING UNIV OF SCI & TECH
Document classification method and system, computer equipment and storage medium
InactiveCN119493861ANatural language data processingSpecial data processing applicationsEngineeringSemantics encoding
The invention provides a document classification method, which belongs to the field of data classification, and comprises the following steps: collecting original documents of different languages from a plurality of channels, and converting texts of different languages into a unified language representation form; extracting keywords in the document after language conversion, calculating word frequency and inverse document frequency of each keyword in the corresponding document, weighting the word frequency by adopting the inverse document frequency to obtain a plurality of TF-IDF weights, and converting the plurality of TF-IDF weights into a plurality of word embedding features; meanwhile, text data similar to the embedding features of the multiple words in the original document are labeled; inputting the plurality of word embedding features into a natural language processing model to train the model, and training the trained model again through the labeled document data to obtain a semantic encoder; and inputting the to-be-classified documents of different languages into a semantic encoder, and outputting a classification result. According to the method, the documents of different languages can be accurately classified by adopting two hierarchical training models, so that the document classification efficiency is improved.

Owner:CHUANGYUN RONGDA INFORMATION TECH (TIANJIN) CO LTD
Methods for real-time accent conversion and systems thereof
Techniques for real-time accent conversion are described herein. An example computing device receives an indication of a first accent and a second accent. The computing device further receives, via at least one microphone, speech content having the first accent. The computing device is configured to derive, using a first machine-learning algorithm trained with audio data including the first accent, a linguistic representation of the received speech content having the first accent. The computing device is configured to, based on the derived linguistic representation of the received speech content having the first accent, synthesize, using a second machine learning-algorithm trained with (i) audio data comprising the first accent and (ii) audio data including the second accent, audio data representative of the received speech content having the second accent. The computing device is configured to convert the synthesized audio data into a synthesized version of the received speech content having the second accent.

Owner:SANAS AI INC
Text audio multi-mode emotion recognition method based on weight strategy
PendingCN119249196Aaccurate captureimprove accuracySpeech analysisBiological modelsEmotion classificationNoise reduction
The invention discloses a text audio multi-mode emotion recognition method based on a weight strategy, which adopts a text processing method based on an ERNIE model, utilizes a knowledge-based language representation technology to effectively capture semantic information in a text, and designs a text emotion recognition model of a multi-attention mechanism to recognize the emotion of the text audio. The weight is dynamically adjusted, and key emotion information in the text is captured in a multi-level manner, so that an emotion classification result is accurately output. The method comprises the following steps: preprocessing audio data, including noise reduction, segmentation and normalization, ensuring the accuracy of subsequent feature extraction, extracting MFCC and GFCC features from the audio data, performing normalization processing and splicing to form a high-dimensional feature vector, and outputting an emotion classification result of the audio. Through a weight strategy based on deep learning, the model can automatically learn and optimize the fusion weight of the text and audio features, and finally the text and audio features are non-linearly fused to generate optimal fusion feature representation.

Owner:BEIJING UNIV OF TECH
Time sequence prediction method based on multi-modal contrast learning technology
According to the time series prediction method based on the multi-modal contrast learning technology, original multivariable time series data are converted into structured visual representation and language representation, multi-modal representation with consistent inner performance can be constructed without depending on external natural language or real image data, and the time series prediction method is high in practicability. The deep semantic understanding capability of the model on the complex operation state of the rail transit is effectively enhanced; a multi-modal contrast learning mechanism is introduced, visual and text modal representation is aligned in a shared embedding space, positive sample consistency is maximized through InfoNCE loss, negative sample interference is suppressed, and the robustness and generalization ability of time sequence features are remarkably improved; and the importance of each variable on a prediction task is dynamically evaluated by using the aligned multi-modal representation, and key variables are automatically screened, so that the redundant information interference is reduced, and the prediction precision and the calculation efficiency of the model in a high-dimensional multi-variable scene are also improved.

Owner:CRRC CHANGCHUN RAILWAY VEHICLES CO LTD
Knowledge graph fused semantic feature expression method and device
PendingCN119514551Aimprove accuracyImprove efficiencySemantic analysisKnowledge representationEntity linkingConditional random field
The invention provides a semantic feature expression method and device for fusing a knowledge graph, and the method comprises the steps: carrying out the preprocessing of multi-source heterogeneous data, and obtaining a text sequence; performing named entity recognition on the text sequence through a bidirectional long-short-term memory network and a conditional random field to obtain an entity of the text sequence; performing relation extraction on the text sequence through a pre-trained language representation model to obtain an entity relation of the text sequence; mapping knowledge domain embedding generation is carried out based on the entity and entity relation, and mapping knowledge domain entity vectors are obtained; performing feature extraction on the text sequence through a RoBERTa model to obtain deep feature representation of the text sequence; performing entity recognition on the deep feature representation to obtain a text feature entity vector of the deep feature representation; performing entity linking and feature fusion based on the text feature entity vector and the knowledge graph entity vector to obtain a fused semantic feature vector; according to the invention, the accuracy and relevance of feature representation can be improved.

Owner:BEIJING RES CENT FOR INFORMATION TECH & AGRI
Urban park perception value evaluation method based on multi-modal data fusion
The invention discloses an urban park perception value evaluation method based on multi-modal data fusion, and the method comprises the steps: extracting a multi-dimensional perception tag and an emotion intensity score from park social media text comment data through a pre-trained language model, and carrying out the aggregation of the multi-dimensional perception tag and the emotion intensity score, and generating a subjective perception result; performing element identification on the image comment data of the park social media by using the three models to obtain different scene element coverage rates, character / facility counts and language representations of visual elements; constructing a plurality of objective environment indexes to describe different environment states, extracting variable information from three model output results, POI data, remote sensing land class proportion and road network information, and constructing mapping with the corresponding objective environment indexes to quantify each objective environment index; and aligning and outputting the subjective perception result and the objective environment index in the park and period dimensions. According to the method, automatic quantitative evaluation of subjective and objective characteristics of urban parks can be realized on the national scale, and standardized technical support is provided for urban renewal and ecological management.

Owner:NANJING INST OF GEOGRAPHY & LIMNOLOGY
Intelligent event allocation method and device based on machine learning
PendingCN119557448AImprove processing efficiencyimprove accuracyDigital data information retrievalNatural language data processingEvent typeOpen source
The invention discloses an intelligent event allocation method and device based on machine learning, and the method comprises the steps: loading the weight and architecture of a pre-training model from a model library, and enabling the pre-training model to be a language representation model; the event text data is input into a pre-training model, a gradient descent method is used for updating the weight of the pre-training model, an intelligent event distribution model is obtained, and the training and deployment process of the intelligent event distribution model is directly completed at the front end based on an open source library TensorFlow.js; under the condition that the input event information is detected, word segmentation processing is carried out on the input event information according to the intelligent event distribution model to obtain a prediction result, and the prediction result comprises an event type corresponding to the input event information; and updating the intelligent event allocation model based on the input event information and a corresponding event type result obtained by interaction with the user.

Owner:WUHAN HONGXIN TECH SERVICE CO LTD
Low-quality medical image classification method, system and device and medium
The invention discloses a low-quality medical image classification method, system and device and a medium, belongs to the technical field of artificial intelligence medicine, and aims to solve the technical problem of low accuracy of benign and malignant classification of low-quality medical images in the prior art. Comprising the steps of obtaining a sample image, performing probabilistic language conversion, constructing an nmODE network model, training the nmODE network model and performing real-time image classification. When probability language conversion is carried out, a probability language term set is constructed, and different brightness degrees of an image are described by using different probability languages in the probability language term set; carrying out probability language conversion on the obtained sample image by utilizing the probability language term set to obtain a single-channel probability language representation result of the sample image; and according to a plurality of single-channel probability language representation results of the sample image, obtaining a multi-channel feature map which can be input into the model. Through probabilistic language conversion, the language expression ability of low-quality medical image features can be enhanced, and the accuracy of low-quality medical image classification is improved.

Owner:SICHUAN UNIV
Systems and Methods for Video Generation via Language-Based Three-Dimensional Interactive Environment Construction
A computing system may include a communication interface configured to receive from a first client machine a natural language description of a three-dimensional environment. A path embedding generator may determine a path language representation of a three-dimensional virtual environment based on the natural language description and via a large language model interface. The path language representation may be generated in accordance with a path language definition and may include one or more entities to include within the three-dimensional virtual environment. The path language representation may include a script governing behavior of the one or more entities and including one or more events. A video may be rendered based on the path representation.


Owner:POLYUP INC
Cybersecurity event handling and enrichment system
A Cybersecurity Event Handling Processor (CEHP) and method for processing security alerts includes: a File System containing a Universal Target Schema (UTS) of target language representations (UTS JSONs); a Normalizer running Feature Extraction and Word Embeddings algorithms; a Tree Converter; and a Transformer running linguistic and structural matching algorithms. The CEHP: (a) captures threat events in one or more native formats generated by cybersecurity tools; (b) runs Feature Extraction and Word Embeddings algorithms for tokenization and categorization of the captured events to create normalized events; (c) converts the normalized events into trees and then translates the trees into event representations in JSON (or XML) format (Event JSONs); and (d) runs nearest neighbor and / or linguistic and structural matching algorithms to compare the Event JSONs to the UTS JSONs to generate output JSONs (Translation JSONs) from the UTS corresponding to the captured events.

Owner:NUHARBOR SECURITY INC
Model training method and device, equipment and storage medium
The invention discloses a model training method and device, equipment and a storage medium. The method comprises the steps that text information of documents in the material field and an entity type tag sequence corresponding to the text information are acquired; the text information is subjected to word segmentation and word embedding processing through a language representation model, word vectors corresponding to the multiple words are obtained, and the language representation model comprises a pre-training model for the material field; performing entity type identification on the plurality of words based on the word vectors to obtain entity type identification results corresponding to the plurality of words; according to the entity type recognition result and the entity type label sequence, an entity recognition model is trained, the trained entity recognition model for the material field text information is obtained, and the entity recognition model comprises a language representation model. According to the scheme provided by the embodiment of the invention, the entity type of the text information in the literature in the material field can be effectively identified, so that useful information can be extracted from the text information.

Owner:CONTEMPORARY AMPEREX TECHNOLOGY CO LTD
A small sample-based general image counting method and device
A small sample based general image counting method, comprising: performing feature extraction on a first image to obtain first features; performing attention calculation based on the first features, a general language representation and a general visual representation to obtain first example features of a first example target, wherein the general language representation is used to describe categories of different objects, the general visual representation is used to describe visual information of different objects, the first example target is an object related to an example frame in the first image, and the first example features include a first language representation and a first visual representation, the first language representation is used to describe a category of the first example target, and the first visual representation is used to describe visual information of the first example target; performing matching on the first example features and the first features to obtain a correlation feature map; and obtaining a first counting result related to the first example target based on the correlation feature map. The method can greatly improve the generalization of the counting algorithm.

Owner:HUAWEI TECH CO LTD
Translating programs from a first programming language to a second programming language
PendingUS20260133782A1Code compilationSource to sourceProgramming languageTheoretical computer science
A program translation system may generate a first program source internal representation expressed using a source language representation of a source programming language and a first program target internal representation that is expressed using a target language representation of a target programming language. The system may interpret the first program source and target internal representations with first program data to generate a first program source and target results. The system may, when the source and target results are inconsistent, modify the target language representation. The system may, when the source and target results are consistent, generate a second program source internal representation of a second program. The system may use the second program source internal representation to generate a second program target internal representation of the second program. The system may use the second program target internal representation to generate a second program in the target programming language.

Owner:SCHLUMBERGER TECH CORP
A city park perception value evaluation method based on multi-modal data fusion
The application discloses a kind of urban park perception value evaluation methods based on multi-modal data fusion, utilize pre-trained language model to park social media text comment data extraction multidimensional perception label and sentiment intensity score, and subjective perception result is aggregated and generated;Park social media image comment data is identified using three kinds of models, obtain different scene element coverage, figure / facility count, and language representation of visual elements;A plurality of objective environment indexes are constructed to describe different environmental conditions, variable information is extracted from the output results of the three models, POI data, remote sensing land class proportion and road network information, and a corresponding objective environment index is constructed to map to quantify each objective environment index;Subjective perception result and objective environment index are aligned in park and period dimension and output.The present application can realize the automatic quantification evaluation of subjective and objective characteristics of urban park at national scale, and provide standardized technical support for urban renewal and ecological management.

Owner:NANJING INST OF GEOGRAPHY & LIMNOLOGY
Method for training a language representation model, method and apparatus for searching for a statement
Embodiments of the present application provide a method for training a language representation model, a method for searching for a statement, and an apparatus. The method includes: obtaining a target training statement, where the target training statement is obtained by collecting statements in a target field to which the language representation model is applied; training a pre-trained language representation model according to the target training statement to obtain a target language representation model, where the pre-trained language representation model sequentially includes a phrase feature extraction layer, a syntactic feature extraction layer, and a semantic feature extraction layer, and the input of some nodes in the i-th layer of the semantic feature extraction layer is the output of the j-th layer of the phrase feature extraction layer, and i and j are integers greater than or equal to 1. Through some embodiments of the present application, the running speed of the language representation model can be improved, and the parameters in the target language representation model can be made more suitable for application in the target field, thereby improving the accuracy of the language representation model.

Owner:阳光保险集团股份有限公司
Diffusion forged face detection and localization method based on multi-domain visual language reconstruction
ActiveCN119206838BImprove detection accuracyImprove generalization abilityCharacter and pattern recognitionPattern recognitionFace detection
The present invention relates to the technical field of forged face detection methods, and in particular to a method for detecting and locating diffuse forged faces based on multi-domain visual language reconstruction. First, spatial information learning is performed on a diffuse forged face image to extract local and global spatial image features respectively, and the fine-grained text prompt corresponding to the image is learned to extract the global language representation, and then the image is reconstructed using the local spatial features to enhance the spatial representation and obtain the residual image, and the residual image is learned to extract the residual features, and then the image features are combined with the residual features to obtain the visual manipulation features, and the global language representation is reconstructed to strengthen the language representation, and finally the language features are combined with the visual features to learn the multimodal representation of the diffuse forged face, and in the inference stage, the diffuse forged face is used to learn the visual manipulation features to realize the detection and positioning of the diffuse forged face. This method can improve the efficiency of forged detection and positioning and the cross-modal detection capability.

Owner:QILU UNIVERSITY OF TECHNOLOGY (SHANDONG ACADEMY OF SCIENCES) +2
A method and device for training a reaction condition prediction model
The present application provides a method and apparatus for training a reaction condition prediction model. The method includes: optimizing a language representation network layer; obtaining model training samples of the reaction condition prediction model; inputting the model training samples into a reaction condition prediction model to be trained; invoking the language representation network layer to process a chemical reaction SMILES, so as to obtain a hidden tensor corresponding to each word in the chemical reaction SMILES and representing a chemical reaction sequence with attention weight information; invoking a masked multi-head attention network in a reaction condition decoder to perform attention representation on a reaction condition sequence to obtain a corresponding condition sequence feature, and obtaining a predicted reaction condition sequence based on the hidden tensor and the condition sequence feature tensor; calculating a loss value of the reaction condition prediction model to be trained based on the reaction condition sequence and the predicted reaction condition sequence; and obtaining a final reaction condition prediction model when the loss value is within a preset range. The present application significantly improves the prediction accuracy on a large reaction condition prediction data set.

Owner:HANGZHOU CARBON SILICON SMART TECH DEV CO LTD
Natural language processing system based on reinforcement learning
InactiveCN119229854Aenhance the sense of interactionMachine learningSpeech recognitionComputer architectureData acquisition
The invention discloses a natural language processing system based on reinforcement learning, and relates to the technical field of language intelligent processing, the natural language processing system comprises a language library building module, an identification and authentication module, a data acquisition module, a data analysis module and an instruction execution module, the language library building module builds a language library of language information by means of a language representation model, and a plurality of execution instructions are stored; the language library building module is set to be in a continuous updating state and has a continuous learning function, the identification and authentication module is used for pre-inputting specific characteristics and identity information held by a vehicle driver, the data acquisition module is used for carrying out data identification and acquisition, and the data analysis module is in signal connection with the data acquisition module and is used for analyzing the vehicle driver. The language information extraction module is in signal connection with the language library building module and is used for extracting language information corresponding to execution instructions in the language library building module, the instruction execution module is in signal connection with the language library building module and is used for executing corresponding instructions, and simplification and accuracy of language information expression are improved through arrangement of the system.

Owner:DONGGUAN JINGSHU TECHNOLOGY CO LTD