
Patents
Literature
4825results about "Digital computer details" patented technology
Efficacy Topic
Property
Owner
Technical Advancement
Application Domain
Technology Topic
Technology Field Word
Patent Country/Region
Patent Type
Patent Status
Application Year
Inventor
Image processing apparatus and method, and storage medium
InactiveUS7372594B1Quality improvementDegradation of image qualityDigitally marking record carriersDigital computer detailsImaging qualityComputer graphics (images)
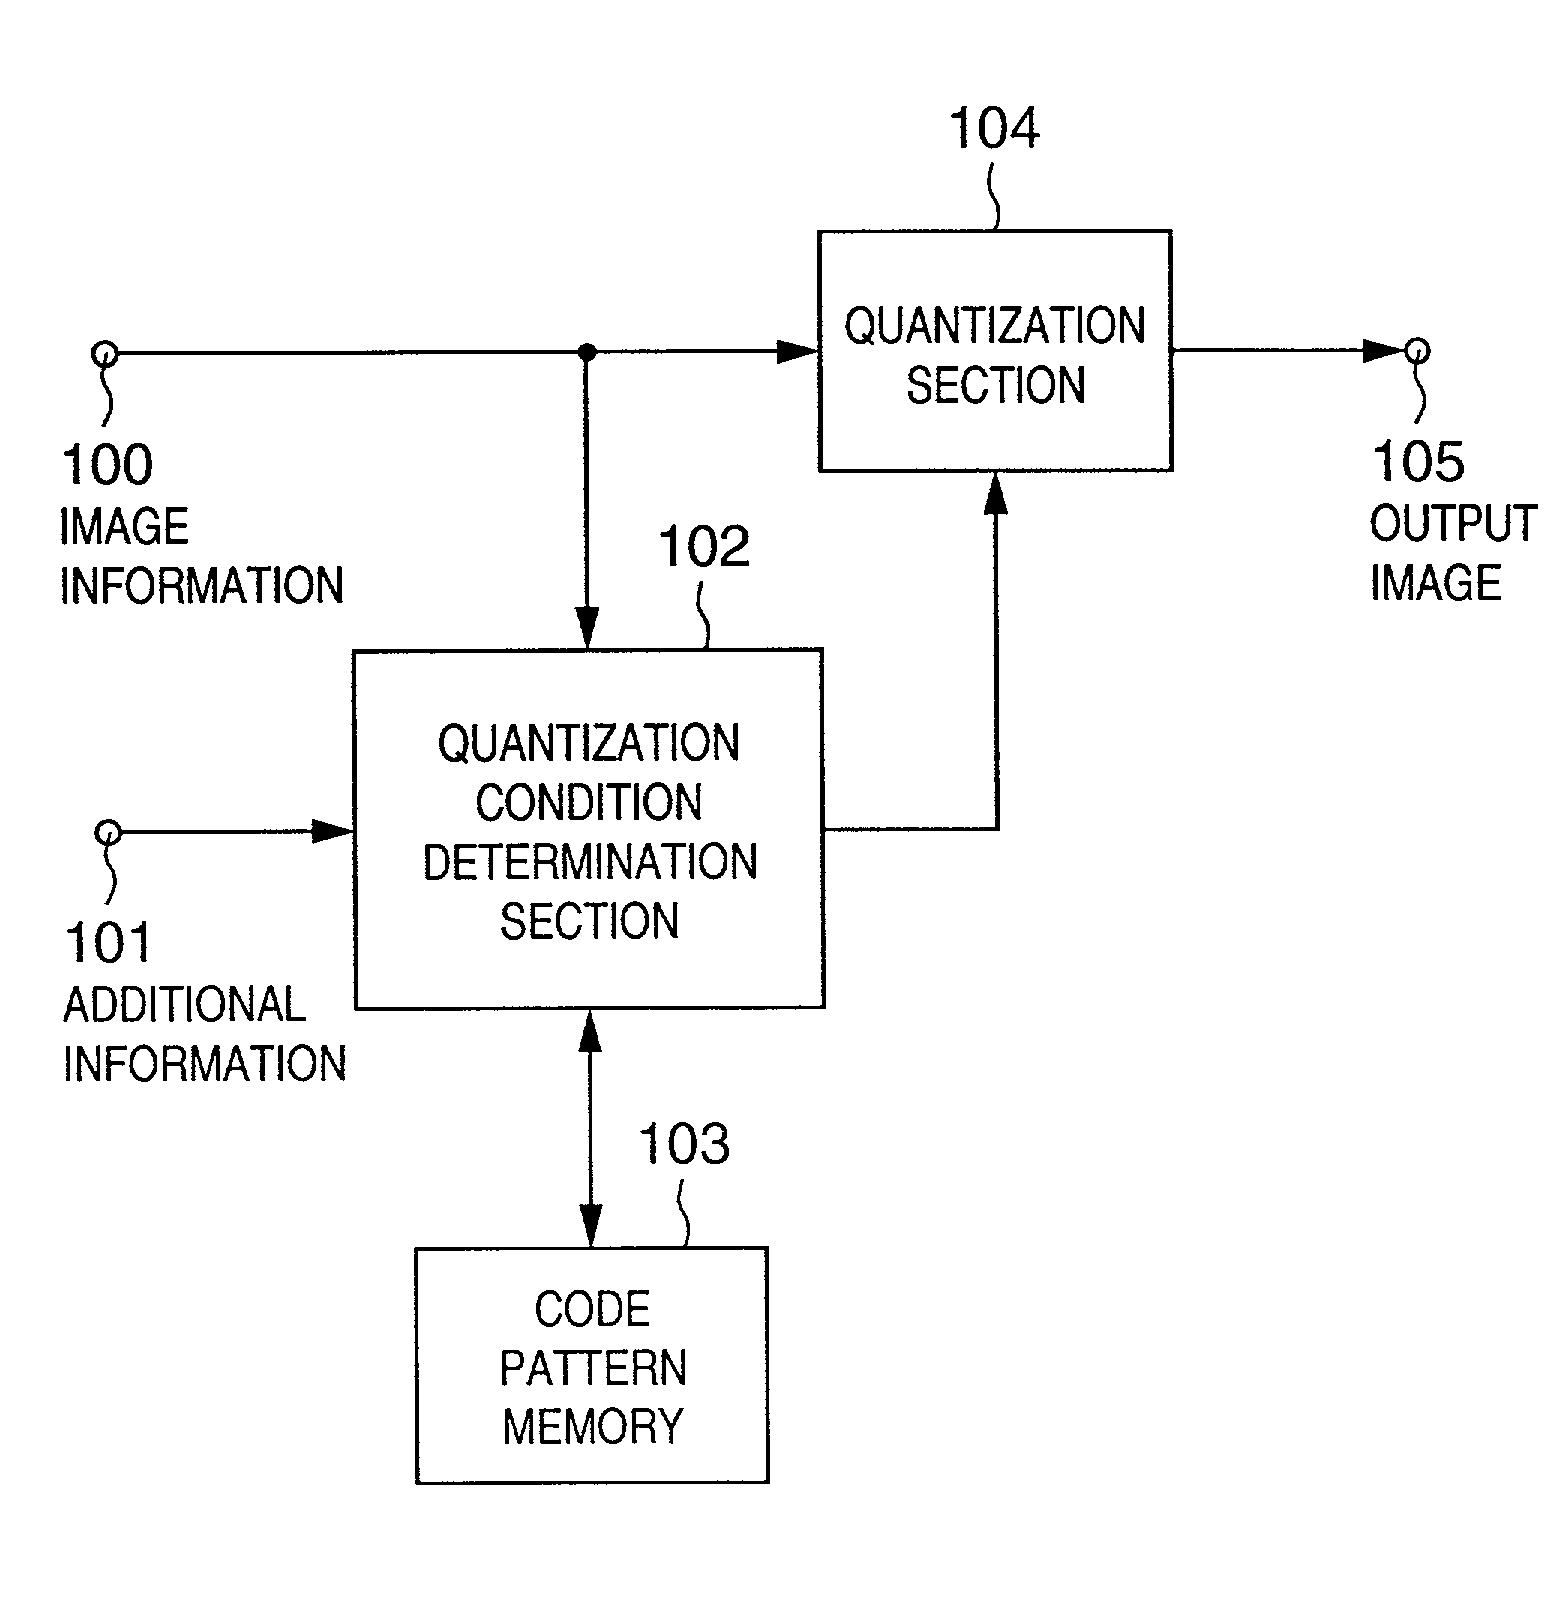
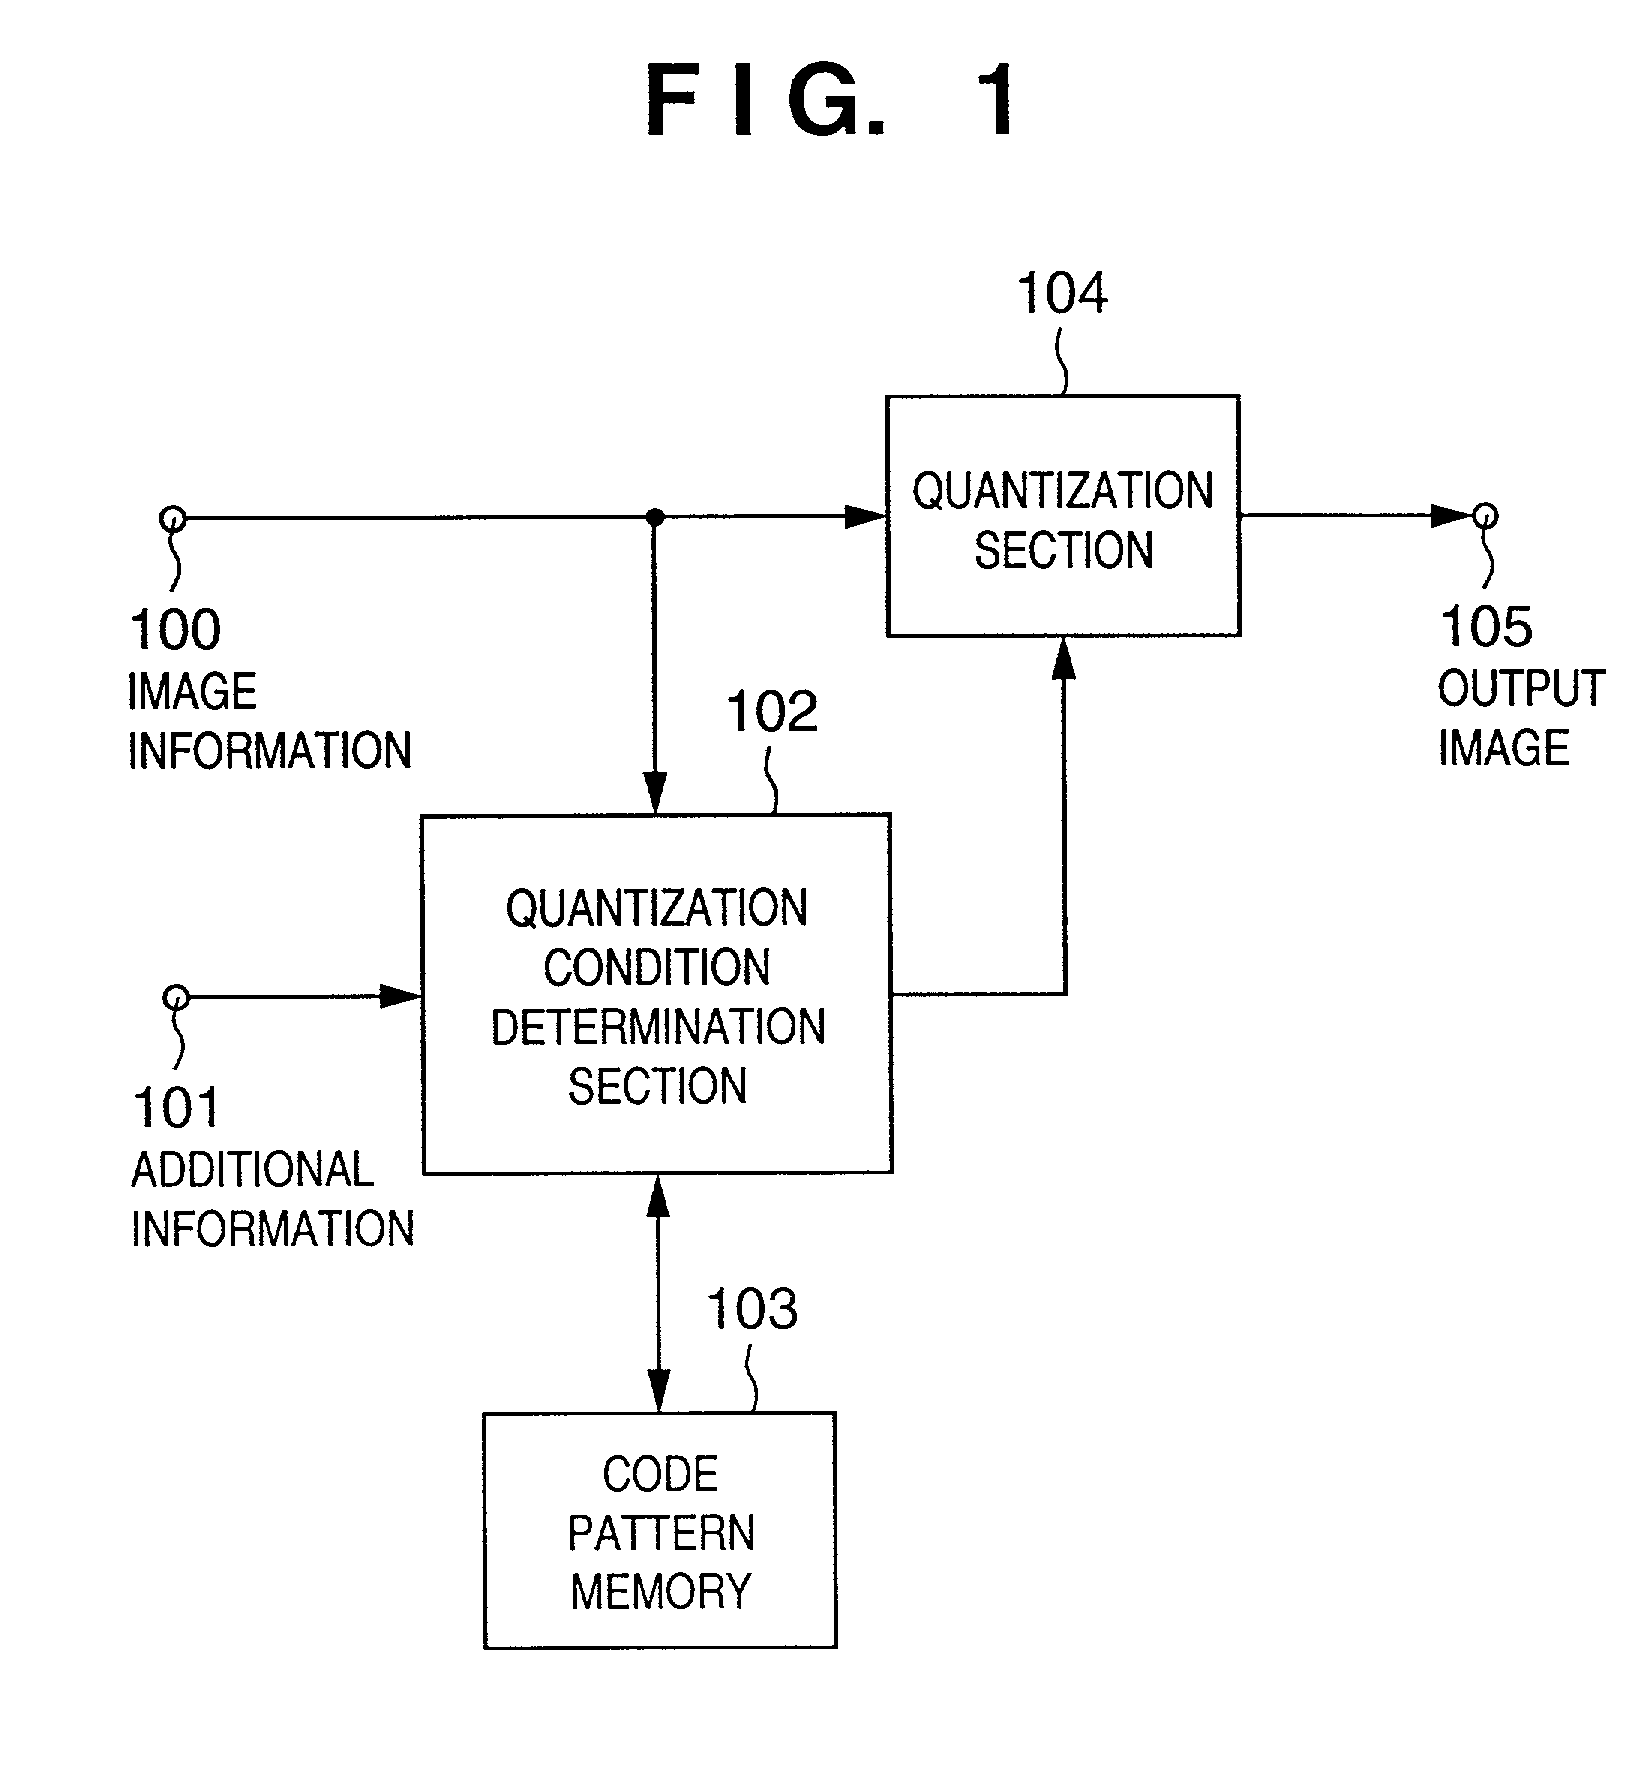
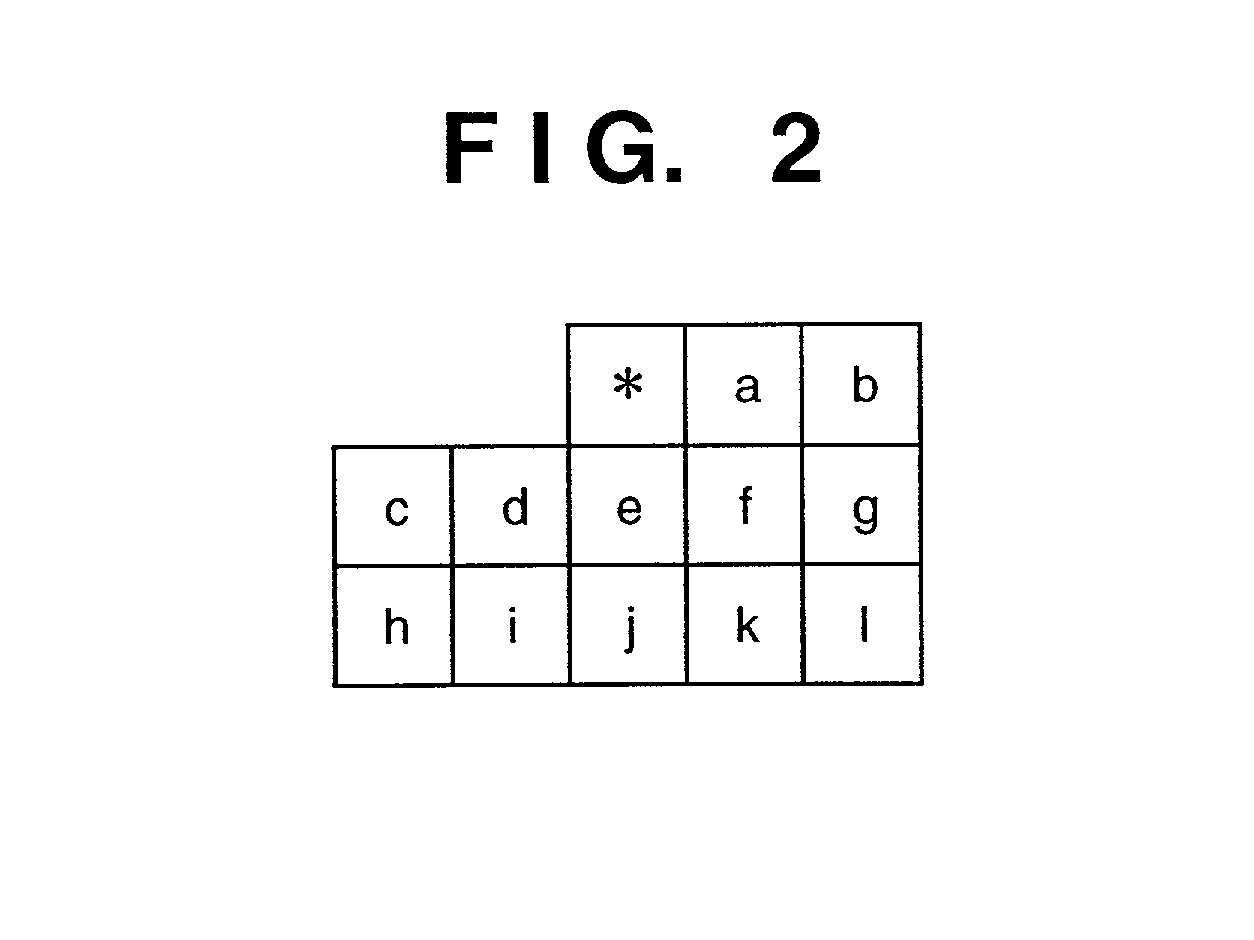
A pattern which does not appear at a flat portion in normal binarization processing is set as a code pattern, and a code formed from this pattern is attached. At this time, code attachment with little degradation in image quality is implemented by selecting an unnoticeable pattern.
Owner:CANON KK
Efficient remote pointer sharing for enhanced access to key-value stores
A method to share remote DMA (RDMA) pointers to a key-value store among a plurality of clients. The method allocates a shared memory and accesses the key-value store with a key from a client and receives an information from the key-value store. The method further generates a RDMA pointer from the information, maps the key to a location in the shared memory, and generates a RDMA pointer record at the location. The method further stores the RDMA pointer and the key in the RDMA pointer record and shares the RDMA pointer record among the plurality of clients.


Owner:IBM CORP
Ai-based energy edge platforms, systems, and methods
PCT designated stageWO2026024918A1Market predictionsEnsemble learningData miningArtificial Intelligence System
In some embodiments, a configured artificial intelligence system includes a plurality of intelligence models; a scoring system configured to generate know-your-model scores that quantify suitability for specific tasks of each model; a model execution system configured to provide standardized execution environment for the plurality of intelligence models; a training and reinforcement system configured to monitor outcomes relating to decisions or predictions made by the plurality of intelligence models and use outcome data as feedback to reinforce model performance; and a governance and analysis system configured to ensure model operations comply with governance standards. The intelligence controller may be configured to receive task requests, analyze task complexity, decompose tasks into manageable subtasks, and dynamically select appropriate models from the plurality of intelligence models to execute each subtask based on model suitability and performance characteristics.

Owner:STRONG FORCE EE PORTFOLIO 2022 LLC
Intelligent (self-learning) subsystem in access networks
An intelligent (self-learning) sensor-aware and / or context-aware subsystem comprising (i) a System-on-a-Chip (SoC), (ii) a radio transceiver, (iii) a microphone, (iv) a voice processing module, (v) a (bio-inspired) neuromorphic event camera or a hyperspectral camera, (vi) a first set of computer implemental instructions in artificial neural networks (ANN) (which may include a transformer model / diffusion model or Poisson flow generative model++ (PFGM++)), (vii) a second set of computer implementable instructions to analyze and interpret contextual data and (viii) an autonomous artificial intelligence (AI) agent is disclosed.

Owner:MAZED MOHAMMAD A
Lossless and lossy automatic hardware compression in graphics-to-graphics network links
An apparatus to facilitate lossless and lossy automatic hardware compression in graphics-to-graphics network links is disclosed. The apparatus includes compressor / decompressor circuitry (CDC) integrated with physical layer (PHY) intellectual property (IP) hardware circuitry for a graphics processor unit (GPU)-to-GPU communication link communicably coupling a first GPU to one or more other GPUs, the CDC to: receive a data message from the first GPU, wherein the data message is in an uncompressed format; determine that a compression process is to be applied to the data message; apply the compression process to the data message to generate a compressed data message; and cause a GPU link IP hardware circuitry that comprises the PHY IP hardware circuitry to transmit the compressed data message over the GPU-to-GPU communication link.

Owner:INTEL CORP
Multipathing with remote direct memory access connections
Multipathing for session-based remote direct memory access (SRDMA) may be used for congestion management. A given SRDMA session group may be associated with multiple SRDMA sessions, each having its own unique 5-tuple. A queue pair (QP) associated with the SRDMA session group may provide a packet for transmission using the SRDMA session group. The SRDMA session group may enable the packet to be transmitted using any of the associated SRDMA sessions. Congestion levels for each of the SRDMA sessions may be monitored and weighted. Therefore, when a packet is received, an SRDMA session may be selected based, at least, on the weight to enable routing of packets to reduce latency and improve overall system efficiency.

Owner:MELLANOX TECHNOLOGIES LTD(IL)
Computing node, computing system, control method, device, equipment and medium
PendingCN120277025ADigital computer detailsElectric digital data processingCommunication interfaceController (computing)
The invention discloses a computing node, a computing system, a control method, a control device, equipment and a medium, and relates to the technical field of computers, a plurality of acceleration cards are interconnected through an Ethernet switching module, and low-order channels of serializer / deserializer interfaces of the acceleration cards are connected with the Ethernet switching module through retimers. A high-order channel of at least one serializer / deserializer interface of each accelerator card is connected with the Ethernet switching module through a retimer, and the working mode of the retimer is configured through a first controller on a computing node according to the signal rate of the accelerator cards, so that a framework that communication interfaces between the accelerator cards are fully interconnected is realized. Any two acceleration cards can be directly connected, the communication bandwidth between the acceleration cards is improved, meanwhile, the number of the acceleration cards can be flexibly expanded, longitudinal expansion and transverse expansion of a computing system can be conveniently achieved, the problem that a traditional acceleration card interconnection scheme is not easy to expand is solved, and the method can adapt to service requirements and flexibly adjust working loads.

Owner:INSPUR SUZHOU INTELLIGENT TECH CO LTD
Method and system for scalable reliable connection transport for rdma
In some implementations, the system may include one or more processors, coupled to memory, the processor configured to set in the memory a pool of shared send queues (SSQs), each SSQ in the pool of SSQs is configured for use as a send queue (SQ) for one or more queue pairs (QPs). The one or more processors may allocate at least one of SSQs from the pool of SSQs to the QP, the SSQ set for a process having a plurality of connections to a plurality of remote processes. The one or more processors may send by the SSQ, via the plurality of connections, outgoing messages to separate remote processes of the plurality of remote processes. Also, the system may include implementations where the pool is set responsive to a first number of the QPs reaching a threshold. The system may include implementations where the pool of SSQs is pinned in the memory.

Owner:AVAGO TECHNOLOGIES INTERNATIONAL SALES PTE LTD
Remote memory access systems and methods
PendingUS20250291760A1Digital computer detailsElectric digital data processingComputer architectureRemote memory access
The present disclosure relates to systems and methods remote memory access between systems. In particular, some implementations relate to remote memory access using data processing units that can reduce loads on central processing units or other system components. Some implementations utilize scheduling algorithms to optimize memory transfers. Some implementations relate to data processing unit hardware that includes programmable logic, which can be configured for scheduling, data processing, and the like.

Owner:THE ALIGNED CO
Remote memory exchange system with non-inductive cold and hot perception of user
The invention discloses a user-noninductive cold and hot sensing remote memory exchange system, which belongs to the field of computer storage, and is characterized in that cluster nodes are divided into extensible remote memory service nodes and computing client nodes according to roles; the remote memory node comprises a remote memory exchange server and a memory resource registration module; the computing client node comprises a FrontSwap-based remote memory exchange client, and a remote memory exchange server side is registered as a memory resource which is non-inductive to a user; furthermore, popularity statistics based on a popularity histogram is realized in a kernel mode; the memory exchange behavior is guided through the dynamic decision-making module based on online reinforcement learning, the memory management efficiency and the system performance are remarkably improved, and efficient and non-inductive memory expansion service is provided for user application.

Owner:HUAZHONG UNIV OF SCI & TECH
Chiplet communication using an optical communication substrate
Described herein are a computing systems comprising a photonic interposer having an optical network comprising a plurality of waveguides and a plurality of controllable optical switches; an electronic die having a surface bonded to the photonic interposer, an inner interface comprising a first plurality of ports electrically coupling the electronic die to the photonic interposer through the surface; and an outer interface comprising a second plurality of ports electrically coupling the electronic die to the photonic interposer through the surface, wherein the outer interface at least partially encloses the inner interface.

Owner:LIGHTMATTER INC
SOC interconnection system, method and device for SOC interconnection system, and storage medium
PendingCN120104554ADigital computer detailsElectric digital data processingAccess frequencyInterconnection
The invention discloses an SOC interconnection system, a method for the SOC interconnection system, electronic equipment and a storage medium. The SOC interconnection system includes: a plurality of computing devices configured as a plurality of computing device groups; wherein the plurality of computing device groups are groups of the plurality of computing devices based on mutual access frequencies among the plurality of computing devices, each computing device group in the plurality of computing device groups is provided with a corresponding routing device, and each computing device in each computing device group is coupled with the corresponding routing device. The plurality of routing devices corresponding to the plurality of computing device groups are mutually coupled. According to the SOC interconnection system, the wiring congestion risk can be reduced, and the realization of the physical architecture of the SOC is facilitated.

Owner:BEIJING ESWIN COMPUTING TECH CO LTD
Neural network on-chip mapping method and apparatus based on TABU search algorithm
PendingUS20250165760A1Digital computer detailsNeural architecturesIterative searchTheoretical computer science
A neural network on-chip mapping method and apparatus based on a tabu search algorithm are provided. The method includes: constructing a tabu search table and using a heuristic-based iterative search process to select local computing cores of a network-on-chip as candidates, establishing an integer programming model and solving an optimal solution, continuously reducing an objective cost function of a mapping solution by loop iteration, and finally obtaining an approximately optimal deployment scheme.

Owner:ZHEJIANG LAB +1
Multi-core heterogeneous system and data processing method thereof
The embodiment of the invention discloses a multi-core heterogeneous system and a data processing method thereof. The method comprises the steps that a plurality of kernel functions corresponding to a device end in the multi-kernel heterogeneous system are configured, a corresponding special register is reserved for each kernel function, the special registers store parameter taking address pointers, the parameter taking address pointers point to kernel function parameters stored in a public memory of the device end, and in the kernel function compiling process, the parameter taking address pointers point to the kernel function parameters stored in the public memory of the device end; according to the method, the parameter fetching address of the kernel function is initialized into the parameter fetching address pointer stored in the special register, so that when the target kernel function is started, the target parameter fetching address pointer can be determined according to the target special register corresponding to the target kernel function, then the parameter of the target kernel function is fetched, and finally the target kernel function is executed according to the fetched parameter. And obtaining a corresponding data processing result. The parameters are directly read from the public memory of the device end through the special register of the kernel function, the kernel function parameter transmission process is simplified, the starting time delay of the kernel function is shortened, and the data processing efficiency is improved.

Owner:STREAM COMPUTING INC
Inter-core-particle communication control method, device, equipment, medium and product
The invention discloses an inter-core-particle communication control method, device, equipment, medium and product, the method is applied to a wafer-level chip, the wafer-level chip comprises a plurality of core particles, and the method comprises the following steps: determining transmission data and target transmission parameter information of a target receiving end core particle through a sending end core particle, performing transmission judgment on the transmission data, and determining a transmission judgment result; when the transmission judgment result is that transmission can be carried out, transmitting the transmission data to the target receiving end core particle based on the target transmission parameter information, and adjusting the target transmission parameter information; the method comprises the following steps: determining receiving end congestion information through a receiving end core grain according to received transmission data, generating a return message and feeding back the return message to a sending end core grain; and adjusting the to-be-adjusted transmission parameter information according to the return message through the sending end core grain to obtain the adjusted transmission parameter information. Flow control is actively carried out through the core particles at the sending end, the problem of transmission congestion of the core particles is avoided, and therefore the performance advantages of the wafer-level chip are brought into full play.

Owner:SHANGHAI ARTIFICIAL INTELLIGENCE INNOVATION CENT +1
Data processing chip based on heterogeneous computing architecture
PendingCN120596409ADigital computer detailsElectric digital data processingComputer architectureRedundant code
The invention discloses a data processing chip based on a heterogeneous computing architecture, and relates to the technical field. The data processing chip based on the heterogeneous computing architecture comprises a data processing unit for receiving and preprocessing data to be transmitted; the clustering compression engine is used for carrying out clustering compression processing on the preprocessed data to be transmitted; the modulation and coding control unit is used for carrying out modulation and coding processing on the data to be transmitted after clustering compression processing; the redundant coding unit is used for carrying out redundant coding processing on the modulated and coded data to be transmitted; and outputting the to-be-transmitted data subjected to redundant coding processing to a protocol stack and interface unit of external equipment according to a set communication protocol. Through collaborative design of a clustering compression engine in a chip and a modulation coding control unit, clustering compression aiming at data structure characteristics and modulation strategy matching in a dynamic channel state are realized; the problems of fixed compression and modulation modes and lack of cooperation in the prior art are solved.

Owner:SHENZHEN JINCHAO CLOUD CONTROL TECH CO LTD
AI server data processing optimization system and method based on distributed heterogeneous computing
The invention discloses an AI server data processing optimization system and method based on distributed heterogeneous computing, and relates to the technical field of artificial intelligence and distributed heterogeneous computing, the AI server data processing optimization system comprises a distributed heterogeneous computing cluster, a dynamic collaborative scheduling subsystem and a double-layer closed loop verification subsystem; the distributed heterogeneous computing cluster is characterized in that the distributed heterogeneous computing cluster comprises a plurality of computing nodes which are interconnected, and each node integrates at least two hardware units. According to the AI server data processing optimization system and method based on distributed heterogeneous computing, deep collaborative optimization of computing resource scheduling and data stream transmission is achieved by constructing a hardware-data-task ternary graph model and a space-time collaborative propagation algorithm, so that end-to-end processing delay is shortened, and the heterogeneous resource utilization rate is maximized.

Owner:LOGOSDATA
Intelligent edge computing cooperative processing system based on integrated circuit
InactiveCN120950449AProgram initiation/switchingDigital computer detailsPathPingComputer architecture
The invention relates to the technical field of edge computing, and discloses an intelligent edge computing co-processing system based on an integrated circuit, which comprises a heterogeneous computing cluster module, a hardware computing unit set, a multi-core control processor based on RISC-V, a programmable pulse tensor computing array and a reconfigurable engine oriented to streaming processing, according to the intelligent edge computing cooperative processing system based on the integrated circuit, zero-delay data exchange is realized through silicon intermediate layer integration of the heterogeneous computing cluster module and a snakelike data channel, and traditional bus arbitration delay is eliminated through real-time operation code analysis and optimal optical communication path mapping of the hardware task routing matrix (TRF) module; the priority path distribution of the task scheduling subsystem is synchronously coordinated with the time-sensitive task, so that the collaborative efficiency of the computing unit is improved in multiple dimensions, the non-blocking transmission of the high-priority task is ensured, and the effect of enhancing the overall processing capability and response speed of the intelligent edge computing is achieved.

Owner:QIQIHAR QISAN MACHINE TOOL
Remote Memory Filling
A network adapter includes a port and circuitry. The port is to connect to a communication network. The circuitry is to send to a remote network adapter, via the communication network, a remote memory-set instruction that instructs the remote network adapter to fill one or more address ranges in a memory with multiple copies of one or more fill-data values.

Owner:MELLANOX TECHNOLOGIES LTD(IL)
DPU (Data Processing Unit)-based RDMA (Remote Direct Memory Access) virtualized memory address conversion and data transmission method and system
The invention provides a DPU (Data Processing Unit)-based RDMA (Remote Direct Memory Access) virtualized memory address conversion and data transmission method and a DPU-based RDMA virtualized memory address conversion and data transmission system. The method comprises the following steps that: a user process specifies a client virtual address and a corresponding memory The virtual machine kernel generates a first memory conversion table, and the first memory conversion table records conversion from the client virtual address to the client physical address. When the drive program of the remote direct memory access device obtains the first memory conversion table, a preset instruction is triggered to enable the execution control right to be switched to the virtual machine supervision program from the virtual machine kernel. The customer physical address is converted into the host virtual address in the switching process. The virtual machine supervision program obtains mapping from the host virtual address to the host physical address through the host system information, and a second memory conversion table containing the conversion relation from the client virtual address to the host physical address is obtained. The execution control right is switched back to the kernel of the virtual machine, and the second memory conversion table is configured to the remote direct memory access device DPU. According to the method, address conversion can be simplified, hardware dependence is reduced, and RDMA performance is improved.

Owner:YUSUR TECH CO LTD
Parallel computing method and device, electronic equipment and storage medium
ActiveCN121210139AResource allocationInterprogram communicationComputer architectureConcurrent computation
The invention provides a parallel computing method and device, electronic equipment and a storage medium, and relates to the technical field of parallel computing, and the method comprises the steps: carrying out the first protocol operation of a target tensor based on each computing core in each stream processor cluster, and generating a data block containing the computing result of each computing core; writing a data block generated by each stream processor cluster into a shared cache; under the condition that each stream processor cluster completes the first protocol operation, reading a data block written by each stream processor cluster from the shared cache; and executing a second protocol operation on the data block read from the shared cache to generate a calculation result of the target tensor. According to the method and device provided by the invention, the parallel architecture and memory access characteristics of the artificial intelligence chip can be better matched, the unnecessary calculation delay and synchronization overhead of the cross-flow processor cluster in the parallel calculation process are reduced, the bandwidth utilization rate of the shared cache is improved, and the overall performance and calculation efficiency of parallel calculation are remarkably improved.

Owner:SHANGHAI BIREN TECH CO LTD
Chip system and access method
The invention provides a chip system and an access method, relates to the technical field of chips, and improves the data access performance of a high-performance computing system. According to the specific scheme, the chip system comprises a snoop filter, a plurality of processor cluster nodes and a plurality of memories, the processor cluster nodes are coupled through a bus, the snoop filter is coupled with the bus, the processor cluster nodes are in one-to-one correspondence with the memories, and the snoop filter adopts a unified directory format. The snoop filter is used for obtaining an access request initiated by the processor cluster node, and the access request comprises address information. The snoop filter is further used for determining an access mode of the access request based on the address information, wherein the access mode comprises a unified memory access mode and a non-unified memory access mode. The processor cluster node is to access the memory based on the access pattern and the access request. The embodiment of the invention is used for the process of accessing the memory by the processor cluster node.

Owner:HUAWEI TECH CO LTD
RDMA (Remote Direct Memory Access) data transmission method, network equipment, system and electronic equipment
The invention provides an RDMA data transmission method, network equipment and a system, and relates to the technical field of communication, in particular to the technical fields of chip processors, computing power clusters, ensemble communication operation, large models and the like. The method is applied to a network device comprising an xPU and an RNIC, the xPU comprises a first engine, and the RNIC comprises a second engine communicating with the first engine, a WQE Buffer and an RDMA engine communicating with the second engine. The method comprises the steps that a first engine assembles a WE based on a hardware unloading asynchronous copy instruction set and transmits the WE to a second engine; the second engine stores the WE in a WQE Buffer and transmits the WE to the RDMA engine; the RDMA engine executes data processing based on the WE, wherein the data processing comprises data transmission, memory access and queue management; the first engine receives feedback of data processing transmitted via the second engine. The RDMA data transmission task is directly unloaded to the special engine through the hardware asynchronous instruction set, decoupling of the RDMA data transmission task and computing resources of the system is achieved, and an efficient and low-delay RDMA data transmission solution which does not depend on CPU / GPU resources is provided for data transmission intensive scenes such as an MoE model.

Owner:BEIJING BAIDU NETCOM SCI & TECH CO LTD
Inter-core communication method, system and device based on heterogeneous asymmetric processor and medium
PendingCN120277022AProgram initiation/switchingResource allocationData synchronizationTransmission protocol
The invention discloses an inter-core communication method, system and device based on a heterogeneous asymmetric processor and a medium, and the method comprises the steps: carrying out the classification and feature extraction of a target task, constructing a task feature vector, and mapping the target task to a processor core; the load is detected in real time, when the real-time load exceeds a threshold value, a task migration strategy is executed through atomic operation and a breakpoint management mechanism, and the voltage and frequency of a processor core are adjusted according to a target task; a trusted execution environment is divided in a processor core, a dynamic session key is generated, the dynamic session key is transmitted through a physical isolation bus, cross-core communication data is encrypted, resources are allocated according to a three-dimensional dynamic resource matrix, and cross-core data synchronization is achieved through a two-channel redundancy transmission protocol. According to the method, the software collaboration framework of the heterogeneous asymmetric processor is optimally designed, so that the performance of the heterogeneous asymmetric processor is improved, and the method can be widely applied to the technical field of inter-core communication.

Owner:GUANGZHOU KETENG INFORMATION TECH
Storage system, method and device, electronic equipment, medium and product
ActiveCN120447838AInput/output to record carriersDigital computer detailsComputer hardwareData management
The invention discloses a storage system, method and apparatus, an electronic device, a medium and a product, relates to the technical field of data management, and uses a memory device outside a controller to store write-in data without being limited by the controller, thereby improving the expansibility of the storage system.

Owner:INSPUR SUZHOU INTELLIGENT TECH CO LTD
Neural network processing device, electronic apparatus, and operation method
PCT designated stage expiredWO2025098491A1Digital computer detailsPhysical realisationComputer hardwareImaging processing
A neural network processing device, an electronic apparatus, and an operation method The neural network processing device comprises a storage module, an input data processing module, a plurality of matrix compute-in-memory units, an output data processing module, and a control module, wherein the storage module comprises: a first storage sub-module configured to store an input feature map for neural network processing, and a second storage sub-module configured to store an intermediate feature map for neural network processing; and the plurality of matrix compute-in-memory units are configured to store the weight of at least one network layer of a neural network and use the weight to perform matrix-vector multiplication computation of the neural network. The neural network processing device can be applied to a compute-in-memory system for image processing, thereby lowering the computation delay, and reducing the area and power consumption.

Owner:TSINGHUA UNIVERSITY
Data transmission method based on remote direct memory access, computer equipment and medium
The invention relates to the technical field of computers and provides a data transmission method based on remote direct memory access, computer equipment and a medium. The method comprises the following steps: when a sending side sends a plurality of request messages associated with a remote direct memory access transmission request, respectively writing a queue index value of a first queue at a receiving side into respective extension heads of the request messages; on the receiving side, based on the queue index value of the first queue in the extension header of the received request message, the message content is written into the position corresponding to the queue index value in the first queue, and the effective identifier of the corresponding position is set to be effective; and on the receiving side, when the effective identifier of the first position in the first queue is effective, reading contents in the positions with the effective identifiers being effective in the first queue one by one according to the sequence of the first queue, so as to generate a plurality of response messages. Therefore, the problem of out-of-order receiving is solved, and resources are saved.

Owner:ZHUHAI XINGYUN ZHILIAN TECH CO LTD
GPU BOX, server, interconnection system and high-speed interconnection and data interaction method
PendingCN120705096ADigital computer detailsElectric digital data processingComputer architectureData transport
The embodiment of the invention discloses a GPU BOX, a server, an interconnection system and a high-speed interconnection and data interaction method. The GPU BOX high-speed interconnection method is characterized in that the GPU BOX comprises a GPU and a control mainboard, an internal PCIe switch, an internal storage device, a first DMA controller and a system controller are integrated in the control mainboard, and a second DMA controller is integrated in the GPU; the system controller receives the reading instruction and performs data read-write initialization on the first DMA controller and the second DMA controller based on the reading instruction; the first DMA controller after data read-write initialization reads cache data from the internal storage device, and transmits the cache data to the GPU via the internal PCIe switch through the established GDS connection; wherein the GDS connection between the GPU and the internal storage device is established through the system controller, the second DMA controller, the internal PCIe switch and the first DMA controller. According to the method, high-speed direct data transmission of the GPU BOX can be achieved, CPU data transfer is not needed, and the data transmission efficiency is greatly improved.

Owner:BEIJING RONGXIN ZHIYUAN TECHNOLOGY CO LTD
Communication method of multi-core system and multi-core system
PendingCN120316052ADigital computer detailsProgram loading/initiatingComputer hardwareHardware modules
The invention aims to provide a communication method of a multi-core system and the multi-core system, and relates to the technical field of computers. The method applied to the Mailbox hardware module in the multi-core system comprises the following steps: receiving an operation configuration instruction of a processor core to the Mailbox hardware module; under the condition that an interrupt trigger signal of the processor core corresponding to the source address is received, sending an interrupt request signal to the processor core corresponding to the destination address according to a communication channel expected to be used so as to transmit the data to be sent until a first preset condition is met, and sending a source interrupt signal to the processor core corresponding to the source address; the first preset condition is that the communication channels of the mailbox source registers recording the source addresses are all used, and the destination addresses recorded by the mailbox target registers of the communication channels are all transmitted. Therefore, the communication concurrency and throughput of the multi-core system can be improved. And meanwhile, the communication reliability of the multi-core system can be improved.

Owner:VERISILICON MICROELECTRONICS (CHENGDU) CO LTD +4
In-network message aggregation for efficient small message transport

Owner:NVIDIA CORP