
Patents
Literature
11828 results about "Parallel computing" patented technology
Efficacy Topic
Property
Owner
Technical Advancement
Application Domain
Technology Topic
Technology Field Word
Patent Country/Region
Patent Type
Patent Status
Application Year
Inventor
Parallel computing is a type of computation in which many calculations or the execution of processes are carried out simultaneously. Large problems can often be divided into smaller ones, which can then be solved at the same time. There are several different forms of parallel computing: bit-level, instruction-level, data, and task parallelism. Parallelism has long been employed in high-performance computing, but it's gaining broader interest due to the physical constraints preventing frequency scaling. As power consumption (and consequently heat generation) by computers has become a concern in recent years, parallel computing has become the dominant paradigm in computer architecture, mainly in the form of multi-core processors.
Method for automatically drawing OpenGL program by using Vulkan
PendingCN121169663AImage memory managementProcessor architectures/configurationVideo memoryProgram instruction
The invention discloses a method for automatically drawing an OpenGL (Open Graphics Library) program by using Vulkan. The method comprises the following steps of: creating a context used by the Vulkan, initializing each module, processing an OpenGL instruction related to texture and data buffering, and managing storage of texture and data buffering resources in a video memory; a shader program used by the OpenGL is preprocessed into a format acceptable to Vulkan, and an OpenGL shader program instruction is created and destroyed; processing an OpenGL (Open Graphics Library) instruction related to frame buffering to generate structural body information required by Vulkan dynamic rendering; an OpenGL instruction of the sampler is also created; processing an OpenGL (Open Graphics Library) instruction for creating a vertex input format and managing a vertex data buffer area, and maintaining vertex input information, a vertex buffer area and an index buffer area required by Vulkan; and finally, drawing or calculating, distributing and calling Vulkan on the basis of all the instructions.

Owner:ZHEJIANG UNIV +1
Heterogeneous AI computing power resource scheduling method and system
The invention discloses a heterogeneous AI computing power resource scheduling method and system, and the method comprises the steps: constructing a heterogeneous AI computing power resource pool, wherein the heterogeneous AI computing power resource pool integrates the computing resources of a plurality of heterogeneous AI acceleration chips; obtaining a scheduling demand of the AI task, wherein the scheduling demand comprises a task type, a resource request quantity, a priority identifier and a task group association relationship; generating a multi-dimensional scheduling strategy according to task requirements, wherein the scheduling strategy comprises a priority scheduling rule, an affinity scheduling rule and a resource preemption rule; based on a multi-dimensional scheduling strategy, the AI tasks are dynamically allocated to target computing power nodes of the heterogeneous AI computing power resource pool, and the task execution state and the resource utilization rate are monitored in real time; and dynamically adjusting computing resource allocation according to the resource utilization rate. Through the heterogeneous AI computing power resource pool, the resource utilization rate is remarkably improved, dynamic resource allocation is realized through a multi-dimensional scheduling strategy, and meanwhile, a communication path is optimized through an affinity scheduling strategy, so that the problem of task starvation caused by resource fragmentation is avoided.

Owner:EASYSTACK INC
GPU computing power resource scheduling method and system
The invention relates to the technical field of data analysis, and discloses a GPU computing power resource scheduling method and system, and the method comprises the steps: collecting node hardware parameters and dynamic load indexes of a GPU cluster to construct a multi-dimensional resource feature vector of the GPU cluster, and constructing a resource portrait of the GPU cluster; establishing a node health degree scoring model of the GPU cluster, and generating a health degree score of a cluster node corresponding to the GPU cluster; analyzing a video memory demand of the GPU task request, and calculating an intensive identifier and a communication dependency relationship; determining the SLA weight of the GPU task request, calculating the resource shortage sensitivity of the GPU task request based on the video memory demand, and calculating the target task priority of the GPU task request in combination with the SLA weight; and determining a resource scheduling node group requested by the GPU task in the resource portrait, generating resource scheduling parameters of the resource scheduling node group, and executing scheduling of computing power resources of the GPU cluster based on the resource scheduling parameters. According to the method, the scheduling efficiency of the GPU computing power resources can be improved.

Owner:SHENZHEN DIXI YUNLIAN TECH CO LTD
Large model data distributed management method and device, equipment and storage medium
The invention discloses a large model data distributed management method and device, equipment and a storage medium, and relates to the technical field of data processing, and the method comprises the steps: segmenting large model training data to obtain a plurality of data blocks, and determining a predicted access frequency based on a long short-term memory network model and the historical access frequency of the data blocks; caching the large model training data corresponding to the data block to a corresponding data cache layer by utilizing the predicted access frequency; constructing a resource portrait by using the static attribute and the dynamic index of the GPU node, and allocating the large model training task to a target GPU node by using a preset hybrid strategy and the resource portrait based on the predicted access frequency and the storage position corresponding to the data block in the data cache layer; when it is monitored that the large model training task on the target GPU node is executed, periodic snapshot is conducted on the large model training task through a distributed snapshot algorithm, and the obtained complete data state is stored in a distributed storage center. And the resource vacancy rate is reduced.

Owner:SHANDONG LANGCHAO YUNTOU INFORMATION TECH CO LTD
Adaptive Network Framework For Modular, Dynamic, and Decentralized Systems
PendingUS20260010525A1Hierarchical databasesSpecial data processing applicationsParallel computingModularity
A distributed indexing and resolution architecture is disclosed for decentralized systems requiring modular, trust-scoped mutation control and dynamic alias governance. The system comprises a plurality of index entries arranged in a parent-child hierarchy, each associated with a structured alias and governed by one or more anchor nodes. Anchors perform localized resolution, mutation validation, and restructuring operations under deterministic policy constraints, enabling semantic scope enforcement and entropy-sensitive adaptation without requiring global consensus or centralized control. The architecture supports scoped alias traversal, asynchronous mutation proposals, and elastic anchor registration based on system state metrics. The indexing substrate may be integrated into heterogeneous infrastructures, including systems comprising distributed software agents, semantic execution platforms, or pseudonymous identity frameworks. Anchors coordinate within defined trust domains to ensure lineage continuity, dynamic rekeying, and semantic integrity across independently governed segments of a decentralized namespace.

Owner:CLARK NICHOLAS
Chip post-simulation verification acceleration method, system and device and storage medium
The invention relates to the technical field of chip development, and discloses a chip post-simulation verification acceleration method, system and device and a storage medium, and the method comprises the steps: collecting multi-dimensional data of a large-scale chip; collecting all module names of a given chip; establishing a mapping relation between a redundant module RTL and a corresponding gate-level netlist, ensuring that interfaces before and after replacement are completely consistent, and designing an automatic script identification and processing parameterization module; establishing a post-simulation verification environment, verifying the consistency of output responses before and after replacement, analyzing the time delay change of a key path, calculating the dynamic power consumption and static power consumption of each functional module before and after replacement, and generating a simulation verification result. According to the method, the hybrid simulation model is constructed, and part of the gate-level netlist irrelevant to the current simulation function is replaced with the RTL, so that the actual simulation scale of a chip is reduced, the problem of overlong simulation time after a large-scale integrated circuit is remarkably solved, and the simulation efficiency is effectively improved.

Owner:SHANDONG INSPUR SCI RES INST CO LTD
Method for compatible operation of Android camera HAL in container based on memory access virtualization
The invention discloses a compatible operation method for an Android camera HAL in a container based on memory access virtualization, and the method comprises the steps: taking a DMA-Buf memory heap of a Linux kernel host system as a target memory heap, taking an ION memory heap of an Android container system as a source memory heap, building a process exclusive memory management context, an FD cache table and a synchronous fence pool, and carrying out the execution of the process exclusive memory management context, the FD cache table and the synchronous fence pool; kernel registration and node binding of virtual ION equipment, pre-allocation of a first memory pool and access hook registration of kernel layer equipment are completed, and when an ION file descriptor is obtained in an HAL process, legality of a container process is verified, and context binding is initialized to the file descriptor; intercepting a memory allocation request of the HAL process, analyzing and adapting parameters, and preferentially multiplexing first memory pool resources to obtain an ION handle; when a data sharing request is processed, matching an FD cache or generating a new FD through an ION handle; when the HAL process releases the memory, resources are recycled according to a memory source, and when the HAL process exits, the context is cached or destroyed, so that cross-system memory operation compatibility is realized.

Owner:北京麟卓信息科技有限公司
Multi-task dynamic resource sharing method and system for universal graphics processing unit
The invention provides a multi-task dynamic resource sharing method and system for a universal graphics processor, and belongs to the technical field of computing graphics process.The method comprises the steps that a plurality of computing tasks are distributed to processing subunits in a cooperative processing unit respectively; obtaining the load state of the computing resource in each processing subunit, and determining the available computing resource capacity of each processing subunit according to the load state; according to the available computing resource capacity, marking the processing subunit of which the current execution thread beam instruction queue length exceeds the own available computing resource capacity as a source processing subunit, and marking the processing subunit with idle computing resources as a target processing subunit; and migrating part or all of the to-be-executed thread beam instructions in the to-be-executed thread beam instruction queue of the source processing subunit to the idle computing resources of the target processing subunit for execution. According to the method and the device, the cross-processing subunit dynamic migration is carried out on the thread beam instruction based on real-time load monitoring, so that the throughput rate and the computing resource utilization rate are improved.

Owner:YUANQIXIN (SHANDONG) SEMICONDUCTOR TECHNOLOGY CO LTD
Page progressive rendering method and system based on streaming data
PendingCN120687692AWebsite content managementSpecial data processing applicationsComputational scienceStreaming data
The invention relates to the technical field of page rendering, and discloses a progressive page rendering method and system based on streaming data, and the method comprises the steps: carrying out the data segmentation through obtaining a data stream, user interaction data and equipment performance parameters, and obtaining data blocks; then, performing cache management in combination with the data, and constructing a multi-level cache pool; thirdly, performing priority grading and sorting on the data blocks to form a rendering task queue; and according to the equipment performance parameters, optimizing a task sequence and obtaining an optimized task sequence. Next, combining the optimized task sequence and user interaction data, predicting data about to enter a viewport, and generating a viewport pre-rendering task; and finally, according to the viewport pre-rendering task, the multi-level cache pool and the equipment performance parameters, performing rendering strategy optimization to obtain a dynamically adjusted rendering task flow. The method can realize dynamic resource scheduling.

Owner:DEEP BLUE INTERNET (BEIJING) TECHNOLOGY CO LTD
Memory access method and graphics processor
PendingCN120541006AMemory architecture accessing/allocationMemory systemsComputer hardwareMemory address
The embodiment of the invention provides a memory access method and device, electronic equipment and a readable storage medium. The method comprises the following steps: receiving a cache line access request; extracting label information from a target memory address corresponding to the cache line access request, wherein the label information comprises a shared label, a private label, a group index, inter-block offset and intra-block offset; querying whether the cache line access request hits the L1 cache or not based on the label information; the group index is used for determining a target group, the shared tag and the private tag are used for determining a target cache line in the target group, and the inter-block offset is used for determining a target cache block in the target cache line; and if the cache line access request hits the L1 cache, determining a target data position in a hit target cache block based on the in-block offset, and executing a corresponding memory access request based on the target data position. According to the embodiment of the invention, on the basis of ensuring the data access efficiency, the storage space of the cache line is fully utilized, and the waste of the cache space is reduced.

Owner:LOONGSON TECH CORP
Tensor core matrix multiplication and accumulation with hardware-based statistics collection and outlier suppression
PCT designated stageWO2025193812A1Digital data processing detailsConcurrent instruction executionComputer hardwareParallel computing
An apparatus providing tensor core matrix multiplication and accumulation (MMA) with hardware-based statistics collection and outlier suppression is disclosed. The apparatus includes processor circuitry comprising at least one processor core comprising matrix multiplication circuitry to: execute a matrix multiplication operation on first input data from a first set of registers and on second input data from a second set of registers; collect, as part of executing the matrix multiplication operation via statistics collection hardware circuitry of the matrix multiplication circuitry, output statistics data corresponding to the matrix multiplication operation; and output the output statistics data along with a result of the matrix multiplication operation; and output statistics storage to store the output statistics data.

Owner:INTEL CORP
Cache management method and device, storage medium and electronic equipment
The invention provides a cache management method, a cache management device, a computer storage medium and electronic equipment, and relates to the technical field of computers. The method comprises the steps of receiving a reasoning task request and distributing the reasoning task request to a target storage page; key value cache information of the first round of reasoning task is stored in a hard disk cache, and when the second round of reasoning task is executed, key value cache information generated before the second round of reasoning task is preloaded layer by layer from the hard disk cache; when the last round of reasoning task is received, storing first target key value cache information correspondingly generated by the last round of reasoning task into the matched target physical block; and performing hybrid grouping compression on key cache information and value cache information in the first target key value cache information to obtain second target key value cache information after quantization compression. According to the invention, triple balance of video memory-calculation performance-precision can be realized.

Owner:CHINA TELECOM CORP LTD TECHNOLOGY INNOVATION CENTER +1
In-memory computing circuit chip based on magnetic cache and computing device
PendingCN113539318AHigh densityLarge capacityDigital storageNeural architecturesData needsEngineering
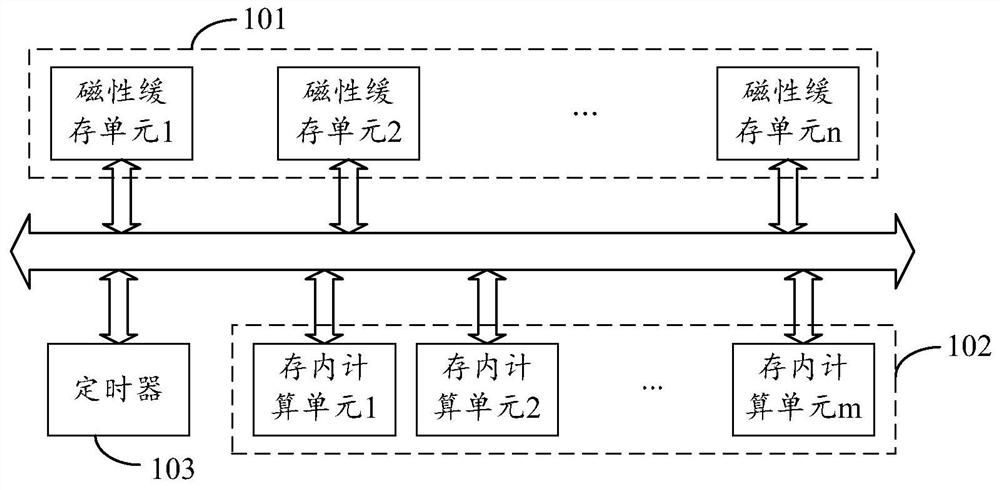
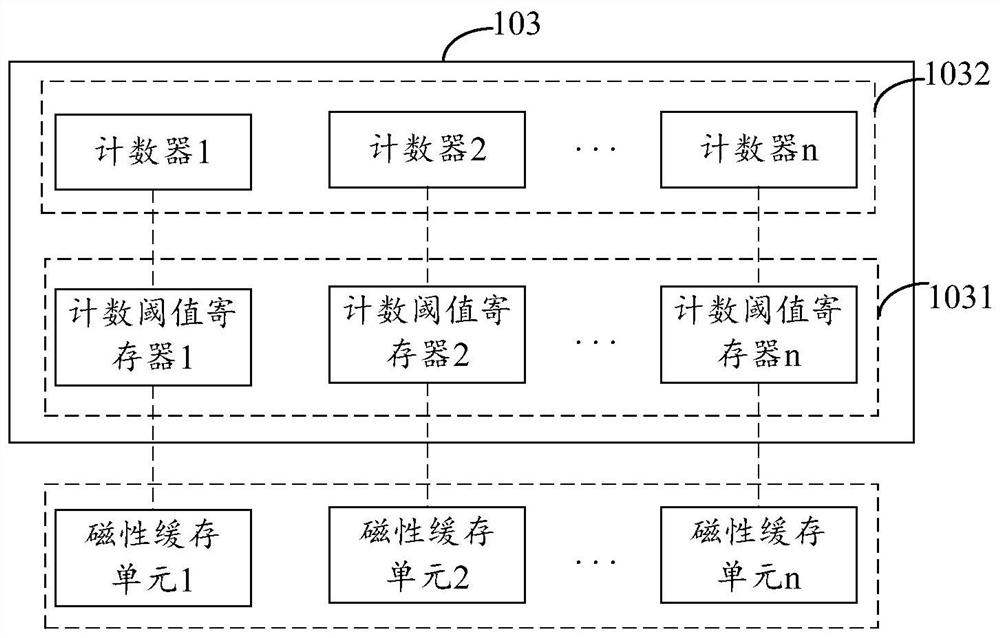
The embodiment of the invention discloses an in-memory computing circuit based on a magnetic cache, and the circuit comprises at least one magnetic cache unit, at least one in-memory computing unit, and a timer. The magnetic cache unit in the at least one magnetic cache unit is used for caching data output by the corresponding in-memory computing unit as to-be-processed data within the corresponding data retention time; the timer is used for respectively setting data retention time for the at least one magnetic cache unit; and the in-memory computing unit in the at least one in-memory computing unit is used for extracting the data to be processed from the corresponding magnetic cache unit for calculation and outputting the computed data to other magnetic cache units. According to the embodiment of the invention, the invention achieves the flexible adjustment of the data retention time of the magnetic cache unit in various in-memory calculation scenes, and achieves the provision of a high-capacity cache for the data needed by in-memory computing under the lower power consumption.
Owner:NANJING HOUMO TECH CO LTD
Intelligent dynamic management method for GPU (Graphics Processing Unit) computing power and cloud platform
The invention is suitable for the field of GPU management, and provides an intelligent dynamic management method for GPU computing power and a cloud platform, and the method comprises the following steps: collecting task data and GPU state data, and generating a task queue and a resource allocation strategy in combination with a scheduling plug-in; based on the task queue and the GPU real-time load, dynamically adjusting a resource allocation proportion through reinforcement learning to analyze a task dependency relationship and generate a migration plan; optimizing a communication path and adjusting asynchronous transmission delay according to the task dependency relationship and the GPU communication topology, and outputting a synchronous state mark; and monitoring abnormity in combination with the synchronization state and the GPU hardware state, executing thermal migration according to the migration plan, performing video memory recovery, and updating the resource idle list. According to the invention, through algorithm innovation and hardware collaborative optimization, intelligent, dynamic and efficient resource scheduling in the multi-GPU system is realized.

Owner:ZHEJIANG XIANGONG CLOUD TECH CO LTD
Data processor, data processing method, electronic device and storage medium
PCT designated stageWO2025189855A1Digital data processing detailsImage memory managementComputer hardwareParallel computing
Provided in the present disclosure are a data processor, a data processing method, an electronic device and a non-transitory computer-readable storage medium. The data processor comprises a tensor operation unit and N compute units, wherein the tensor operation unit is configured to execute tensor computation on input data, so as to obtain tensor computation results; and the N compute units are configured to execute at least one of a vector operation of the tensor computation results and the generation of input data, wherein first data transmission channels are provided between the tensor operation unit and at least some compute units among the N compute units, and the first data transmission channels are used for directly providing the tensor computation results to the compute units, and directly providing the input data from the compute units to the tensor operation unit. By means of the data processor, access to a global memory can be reduced, the waste of resources is reduced, the data transmission delay is shortened, the overall efficiency of operators is significantly improved, the strong computing power of a tensor operation unit itself is effectively used, and the computation efficiency of the data processor is improved.


Owner:SHANGHAI BIREN TECH CO LTD
Task disassembly and multi-agent arrangement execution system and method based on large language model
The invention provides a task disassembly and multi-agent arrangement execution system and method based on a large language model, and belongs to the technical field of computers, and the system comprises an instruction analysis module, a DAG construction module, a scheduling execution module and a cache optimization module. Analysis is carried out according to the dependency relationship between the tasks, a task execution DAG is automatically constructed, and concurrent calling is carried out on the sub-modules without dependency; by caching an authentication result, a context reasoning result and the like, a universal module is executed in advance, the result is reused, and repeated calculation is reduced; the maintainability and the expandability of the system are improved through graph structure visualization and node element information injection; and performing context analysis and scheduling optimization in combination with the reasoning ability of the language model to realize an intelligent decision execution path.
Owner:INSPUR ZHUOSHU BIG DATA IND DEV CO LTD
Heterogeneous GPU resource management scheduling method
ActiveCN121455696AProgram initiation/switchingResource allocationResource assignmentParallel computing
The invention provides a heterogeneous GPU resource management scheduling method, and relates to the technical field of GPU resource allocation, heterogeneous equipment management and unified abstract modeling are carried out, GPU resources of different architectures are registered to a container arrangement platform, and a unified abstract layer is constructed to shield bottom layer hardware differences; gPU cluster optimization management based on a multi-dimensional real-time monitoring and intelligent scheduling strategy is carried out, GPU operation indexes are collected, priorities are dynamically calibrated for tasks, and task performance portraits are constructed; scheduling decision making is carried out through multi-strategy cooperation, and optimal GPU resources are distributed for tasks; carrying out fine-grained resource allocation, carrying out space or time segmentation on the GPU, and dynamically adjusting resource allocation according to a load state; aPI conversion of cross-architecture tasks is realized through a unified runtime library, and task execution data is collected to feed back an optimization scheduling model; automatic detection, isolation and task migration of GPU faults are carried out, and unified monitoring and alarm are provided.

Owner:TAIJI COMPUTER CORPORATION LIMITED
Calculation task allocation method and device, equipment, storage medium and product
PendingCN120560804AProgram initiation/switchingResource allocationParallel computingTopological sorting
The invention discloses a calculation task allocation method and device, equipment, a storage medium and a product, and relates to the technical field of artificial intelligence, and the method comprises the steps: obtaining a to-be-executed calculation task, and extracting the features of the to-be-executed task to obtain a feature label; decomposing the to-be-executed calculation task based on the feature labels to obtain sub-tasks; constructing a directed acyclic graph based on the dependency matrix of each sub-task, and performing topological sorting on each sub-task to obtain a priority and an execution sequence; according to the method, a to-be-executed calculation task is decomposed into a plurality of sub-tasks through feature labeling, a directed acyclic graph is constructed according to the dependency relationship among the sub-tasks, and the sub-tasks are distributed according to the reference execution time, the priority and the execution sequence. The priority and the execution sequence of each sub-task are determined by utilizing topological sorting, and the sub-tasks are allocated to each GPU for execution in combination with the reference execution time of each sub-task on different GPUs, so that the calculation efficiency of the calculation task is effectively improved.

Owner:中移信息技术有限公司 +1
Multi-level cache optimization method and system based on data popularity adaptive adjustment
PendingCN120872240AInput/output to record carriersEnergy efficient computingCloud systemsCache optimization
The invention discloses a multi-level cache optimization method and system based on data popularity self-adaptive adjustment, relates to the technical field of data storage, and aims to solve the problems that a cache mechanism in an existing desktop cloud system is static, initialization is slow, and cold and hot data are difficult to recognize. The adopted scheme comprises the steps that a three-level cache structure of a local cache L1, a distributed cache L2 and a database L3 is set; constructing a data popularity scoring model based on the access frequency, the time decay and the user priority; dividing the data into hot data, temperature data and cold data according to the popularity score, and dynamically determining migration and elimination strategies of the data in L1, L2 and L3; the hot data are loaded to the upper-level cache T in advance through a prediction mechanism, and container-level cache preheating is supported; a cache preheating strategy is integrated to a Kubernetes life cycle, and hot data loading and cold data degradation are achieved; visual strategy configuration and monitoring during operation are supported, and cache strategies are managed in real time. The method is suitable for an access optimization scene of a large-scale desktop cloud system.

Owner:INSPUR COMM TECH CO LTD
Timed task execution optimization method and system
PendingCN121210072AProgram initiation/switchingResource allocationFeature extractionParallel computing
The invention provides a timed task execution optimization method and system, and aims to solve the problems of inflexible static priority scheduling, unintelligent resource allocation and the like in the prior art. According to the method, a distributed timed task intelligent scheduling framework is constructed and comprises five core components including a task management console, a scheduling decision engine, a resource monitoring agent, a task execution cluster and metadata storage. Task basic information is obtained through task feature extraction, a dynamic priority score is calculated based on decision factors such as SLA urgency, resource matching degree and service weight, and task priority ranking is achieved. And performing intelligent task allocation by adopting a BestFit algorithm, and allocating the task to the optimal execution node. The system monitors the CPU utilization rate, the memory occupation and the IO waiting time of the nodes in real time, and when the CPU utilization rate exceeds 85%, an elastic resource allocation strategy is triggered. And when the task execution time exceeds the pre-estimated duration, performing task splitting and rescheduling based on a dynamic fragmentation algorithm.

Owner:BEIJING YULORE INNOVATION TECH
Management system data caching and batch synchronization method and system based on multi-level cache
ActiveCN120723845ADatabase management systemsDatabase distribution/replicationData ingestionParallel computing
The invention belongs to the technical field of data caching and batch synchronization, and discloses a management system data caching and batch synchronization method and system.The method comprises the steps that caching processing is conducted on pre-obtained data through a caching strategy based on a pre-constructed caching architecture, operation data are extracted through the cached data, and the operation data are stored in a database; carrying out local operation processing and operation type judgment by combining a transaction engine and an operation classifier; acquiring storage state data of the cache architecture in real time, performing synchronization strategy optimization on a preset synchronization strategy by using a decision tree algorithm, and performing batch synchronization processing in combination with a chained version number mechanism; and acquiring operation state data of the cache architecture, constructing a cache performance index system by using the operation state data, and performing data storage alarm processing by combining an autoregression integral moving average model and an association rule. According to the method, the high-frequency operation response speed is obviously optimized, the load of a back-end server is effectively reduced, and efficient utilization of hardware resources is realized.

Owner:SHANDONG FUTURE NETWORK RES INST (PURPLE MOUNTAIN LAB IND INTERNET INNOVATION APPL BASE)
Matrix storage operator optimization method and device, computer equipment and readable storage medium
PendingCN120892670AResource allocationComplex mathematical operationsMemory addressParallel computing
The invention relates to a matrix storage operator optimization method and device, computer equipment and a readable storage medium. The method comprises the following steps: allocating memory resources for target data; determining a logic structure corresponding to the source data, establishing a first mapping relation between each logic index in the logic structure and a register address of the source data, and establishing a second mapping relation between each logic index in the logic structure and a memory address of the target data; and determining a corresponding relationship between a memory address of the target data and a register address of the source data based on the first mapping relationship and the second mapping relationship, and storing the source data stored in a register into a memory resource corresponding to the target data based on the corresponding relationship. By adopting the method, the generalization ability of the matrix storage operator can be improved.

Owner:SHANGHAI BIREN TECH CO LTD
Large language model accelerator architecture based on three-dimensional NAND flash memory
The invention discloses a large language model accelerator architecture based on a three-dimensional NAND flash memory, and belongs to the technical field of calculation, reckoning or counting. The architecture comprises a three-dimensional NAND flash memory used for executing feedforward neural network calculation; the auxiliary calculation unit is used for executing attention mechanism calculation; the DRAM chip is used for storing attention mechanism related weights and KV cache; and the interconnection resource is used for realizing data interaction among the components. Wherein the three-dimensional NAND flash memory comprises a logic chip and an NAND array chip, the logic chip is used for controlling and executing calculation, and the NAND array chip is used for storing weights and participating in calculation. The invention further provides a scheduling method based on KV cache awareness. The scheduling method comprises decomposition and dynamic allocation of calculation tasks. Through collaborative design of the hardware architecture and the scheduling method, the memory wall bottleneck in large language model calculation can be relieved, the energy consumption is reduced, and the overall calculation performance is improved.

Owner:SOUTHEAST UNIV
Parallel task scheduling algorithm for heterogeneous multi-core processor
PendingCN121166312AProgram initiation/switchingResource allocationDynamic load balancingConcurrent computation
The invention relates to the technical field of computer architecture and parallel computing, and discloses a parallel task scheduling algorithm for a heterogeneous multi-core processor, which comprises the steps of task modeling, resource mapping, dynamic load balancing, communication optimization, task scheduling decision and execution monitoring. Task allocation is adjusted in real time through dynamic load balancing, cross-core communication delay is reduced in combination with communication optimization, and an efficient task allocation sequence is generated by using an improved genetic algorithm. According to the method, the resource utilization rate and the task execution efficiency of the heterogeneous multi-core processor in a high-performance computing scene can be improved, meanwhile, the robustness and adaptability of an algorithm are enhanced, and the task allocation problem in a complex computing scene is effectively solved.


Owner:SUZHOU DUXUEKEZHENG INTELLIGENT TECH CO LTD
Multi-thread high-throughput data flow channel separation method and system based on zero copy
The invention belongs to the technical field of data transmission and processing, and discloses a zero-copy-based multi-thread high-throughput data stream channel separation method and system, and the method comprises the steps: directly writing a mixed data stream into a front-end buffer region configured as an annular structure through a data receiving module by adopting direct memory access; then, a multi-thread processing module dynamically allocates a plurality of processing threads from a thread pool to separate channel data in parallel, each thread adopts a zero copy algorithm based on pointer offset, positions the channel data in a memory, creates pointer reference and associates the channel data to a corresponding rear-end buffer area, and logic separation is achieved without physical copy; and finally, the data storage module efficiently writes the separated data into persistent storage in an asynchronous I / O mode. According to the method, zero-copy, multi-thread parallel and two-stage dynamic buffering strategies are combined, the data separation efficiency is remarkably improved, CPU occupation and memory bandwidth are greatly reduced, and the real-time performance and stability of high-throughput data processing are guaranteed.

Owner:CHINA JILIANG UNIV
Apparatus and method for block-friendly ray traversal
PendingUS20250308128A1Image memory managementProcessor architectures/configurationComputer hardwareGraphics
Apparatus and method for efficient storage of BVH nodes in blocks. For example, one embodiment of an apparatus comprises: bounding volume hierarchy (BVH) construction circuitry to construct a BVH based on primitives of a graphics scene; and block allocation hardware logic coupled to or integral to the BVH construction circuitry, the block allocation hardware logic to allocate a plurality of nodes of the BVH into a plurality of blocks for storage in a cache or memory subsystem, the block allocation hardware logic to maximize a number of blocks which include a leading parent node and one or more corresponding child nodes of the plurality of nodes.

Owner:INTEL CORP
Asynchronous parallel reasoning method, system and equipment for hybrid expert model and medium
The invention discloses an asynchronous parallel reasoning method, system and equipment for a hybrid expert model and a medium, which are corresponding schemes: decoupling synchronization of calculation and communication between GPUs (Graphics Processing Unit) caused by all-to-all set communication in expert parallelism, allowing asynchronous parallelism of model calculation and lexical metadata communication, and solving the problem of asynchronous parallelism of the model calculation and lexical metadata communication. Data communication overhead caused by expert parallelization is fully masked, and synchronization waiting overhead is eliminated; aiming at the phenomenon of uneven cold and heat of experts in reasoning, the hot experts are preferentially placed in the GPU, the cold experts are laterally loaded in the CPU so as to release the video memory space of the GPU, and the calculation efficiency of the GPU can be improved by increasing the batch size during reasoning; efficient resource scheduling is realized by dynamically selecting a computing unit which is most suitable for execution and a cold expert which needs to be loaded; generally speaking, the communication overhead and the waiting overhead during parallel reasoning of experts can be remarkably reduced, meanwhile, the calculation efficiency of the GPU is improved, and the overall throughput performance in the reasoning process is optimized.

Owner:UNIV OF SCI & TECH OF CHINA
Digital twin platform GPU rendering resource dynamic scheduling method and system
ActiveCN120580334AProgram initiation/switchingResource allocationResource assignmentDynamic resource
The invention relates to a digital twin platform GPU rendering resource dynamic scheduling method and system, and the method comprises the steps: S1, collecting a rendering task feature signal of a current frame in real time, and collecting a GPU multi-dimensional resource consumption signal; s2, based on the rendering task feature signal, the historical resource consumption signal and the scene dynamic change signal, generating a GPU resource demand prediction signal and a load fluctuation trend signal of a future frame; s3, predicting a signal, a task dependency relationship signal, a user priority signal and a real-time resource bottleneck type signal according to the GPU resource demand; s4, executing the dynamic resource allocation instruction signal; and S5, generating a parameter self-optimization signal for updating the prediction and scheduling logic of a subsequent frame according to the actual resource consumption signal of the current frame and the scheduling effect evaluation signal. According to the dynamic scheduling method and system for the GPU rendering resources of the digital twin platform, the problem that the GPU resource utilization rate is low and the real-time performance is difficult to consider at the same time under the dynamic load can be solved.

Owner:ZHONGKE HUIZHI (BEIJING) TECH CO LTD
Direct3D rendering model compatible method based on dynamic template pool
The invention discloses a Direct3D rendering model compatible method based on a dynamic template pool, which comprises the following steps: establishing three types of mapping tables between D3D and Vulkan when compiling DXVK, constructing resource metadata, and creating a core, extended and temporary three-level template pool according to the mapping tables after starting; when the D3D application creates resources, metadata is initialized, parameters are verified, physical memories are allocated and grouped, resource groups are pre-verified, a batch binding command is generated, memory binding is completed, and the metadata is updated; when a resource view is created, a template is matched from a template pool, a handle is generated after instantiation, a resource handle is associated, and a descriptor is bound; when a rendering state is set and a rendering instruction is executed, the rendering state and the rendering instruction are respectively converted into a Vulkan related state and a Vulkan related instruction through a mapping table, a handle is bound after a PSO cache is inquired, a command buffer area is submitted to a GPU queue to execute drawing, and compatible operation of the D3D application on a platform supporting a Vulkan operating system is realized under the condition that the GPU does not support VKKHRmaintence5 and VKKHRmaintence6 extension.

Owner:北京麟卓信息科技有限公司
Data processing method and system based on cloud computing
The invention provides a data processing method and system based on cloud computing, belongs to the technical field of data processing, and realizes high concurrent processing and automatic load balancing by dynamically scheduling computing power through elastic resource allocation and a distributed computing framework and combining a storage and computing separation framework. The system supports cross-node disaster recovery backup and multi-layer encryption, and data security is guaranteed; and an on-demand payment mode is adopted, so that the hardware input cost is reduced, the resource utilization rate is improved, and the large-scale data processing efficiency and the system expandability are remarkably improved.

Owner:ZHONGKE NUOXIN BEIJING HI TECH