
Patents
Literature
137195 results about "Computer graphics (images)" patented technology
Efficacy Topic
Property
Owner
Technical Advancement
Application Domain
Technology Topic
Technology Field Word
Patent Country/Region
Patent Type
Patent Status
Application Year
Inventor
Computer graphics are pictures and films created using computers. Usually, the term refers to computer-generated image data created with the help of specialized graphical hardware and software. It is a vast and recently developed area of computer science. The phrase was coined in 1960, by computer graphics researchers Verne Hudson and William Fetter of Boeing. It is often abbreviated as CG, though sometimes erroneously referred to as computer-generated imagery (CGI).
Real scene three-dimensional modeling method and system fusing laser point cloud and image
ActiveCN120147563AImage analysisInternal combustion piston enginesPoint cloudComputer graphics (images)
The invention provides a real scene three-dimensional modeling method and system fusing laser point cloud and images, and belongs to the technical field of urban three-dimensional modeling. According to the method, laser point cloud data and multi-view image data of a target scene are acquired through a synchronous acquisition device, and joint calibration is performed on a laser radar and a camera to generate space-time synchronization parameters. And a dynamic weight registration algorithm is utilized to dynamically adjust the registration weight according to the point cloud density distribution and the image texture complexity so as to realize the multi-level registration of the laser point cloud and the image data. The registered data is used for constructing a three-dimensional geometric model and generating a seamless texture map, meanwhile, semantic-driven hole repairing is carried out on a model missing area, and finally a complete three-dimensional model is output. According to the real-scene three-dimensional modeling method and system fusing the laser point cloud and the image, the limitation of single data source modeling is solved, and real-scene three-dimensional modeling with high precision, high integrity and real-time updating is realized.

Owner:CHINA JK INST OF ENG INVESTIGATION & DESIGN
Display screen or portion thereof with graphical user interface

Owner:MASIMO CORP
AI visual special effect dynamic generation system fused with multi-modal perception
ActiveCN120318379ABiological modelsCharacter and pattern recognitionData setComputer graphics (images)
The invention belongs to the technical field of visual special effects, and discloses an AI visual special effect dynamic generation system fusing multi-modal perception. Through cooperative work of six core modules of multi-modal input processing, importance analysis, parameter configuration, parameterized rendering, parameter optimization and rendering and output, deep fusion of special effects and contents is realized. An image sequence, audio data and scene parameters can be processed at the same time, a multi-modal feature data set is constructed, a scene key visual area is scientifically recognized, a visual importance distribution map is generated, and the special effect parameter configuration and rendering process is guided. An improved neural radiation field technology and a physical constraint model are adopted to ensure the consistency and reality of the special effect at different visual angles; and a multi-dimensional quality evaluation and parameter automatic optimization mechanism is introduced, so that the visual expressive force and the artistic value of the special effect are guaranteed. The creation threshold is remarkably reduced, the cooperative expression ability of the special effect and the content is improved, and the special effect becomes a powerful tool for enhancing the narration and enhancing the emotion.

Owner:SHENZHEN XINGHUO MUTUAL ENTERTAINMENT DIGITAL TECH CO LTD
Chatbot with LLM and vectorized database
An example operation may include one or more of receiving an input from a user during a conversation that includes a plurality of prompts between the user and a chatbot within a chat window of a software application, converting text content within the received input into a vector, executing a large language model (LLM) on the vector and a database of vectorized responses to identify a vectorized response to output from among the plurality of vectorized responses within the database, converting the vectorized response into a text response, and displaying the text response output by the chatbot within the chat window of the software application.

Owner:THE TORONTO DOMINION BANK
Image processing apparatus and method, and storage medium
InactiveUS7372594B1Quality improvementDegradation of image qualityDigitally marking record carriersDigital computer detailsImaging qualityComputer graphics (images)
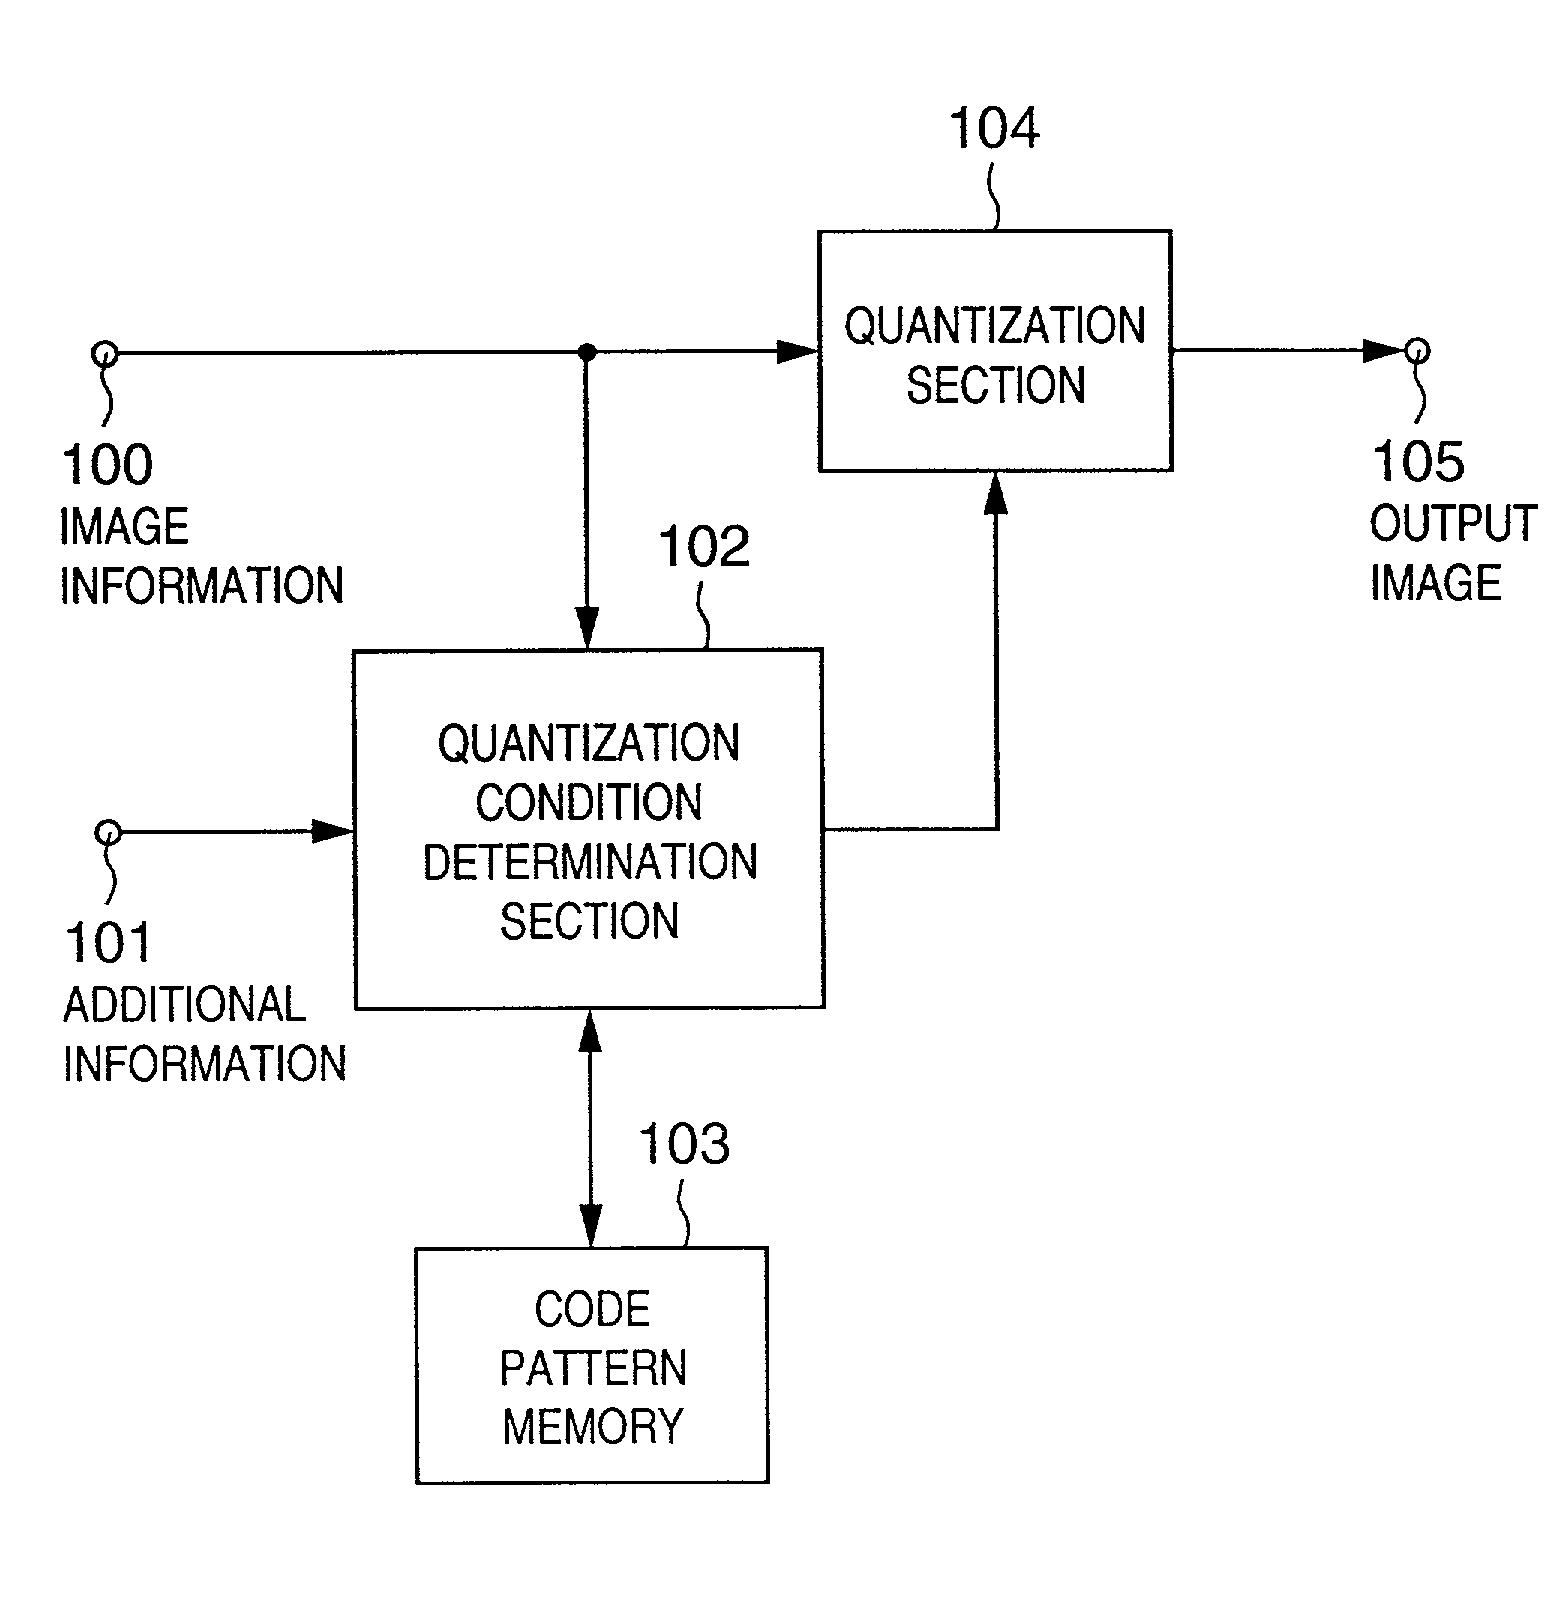
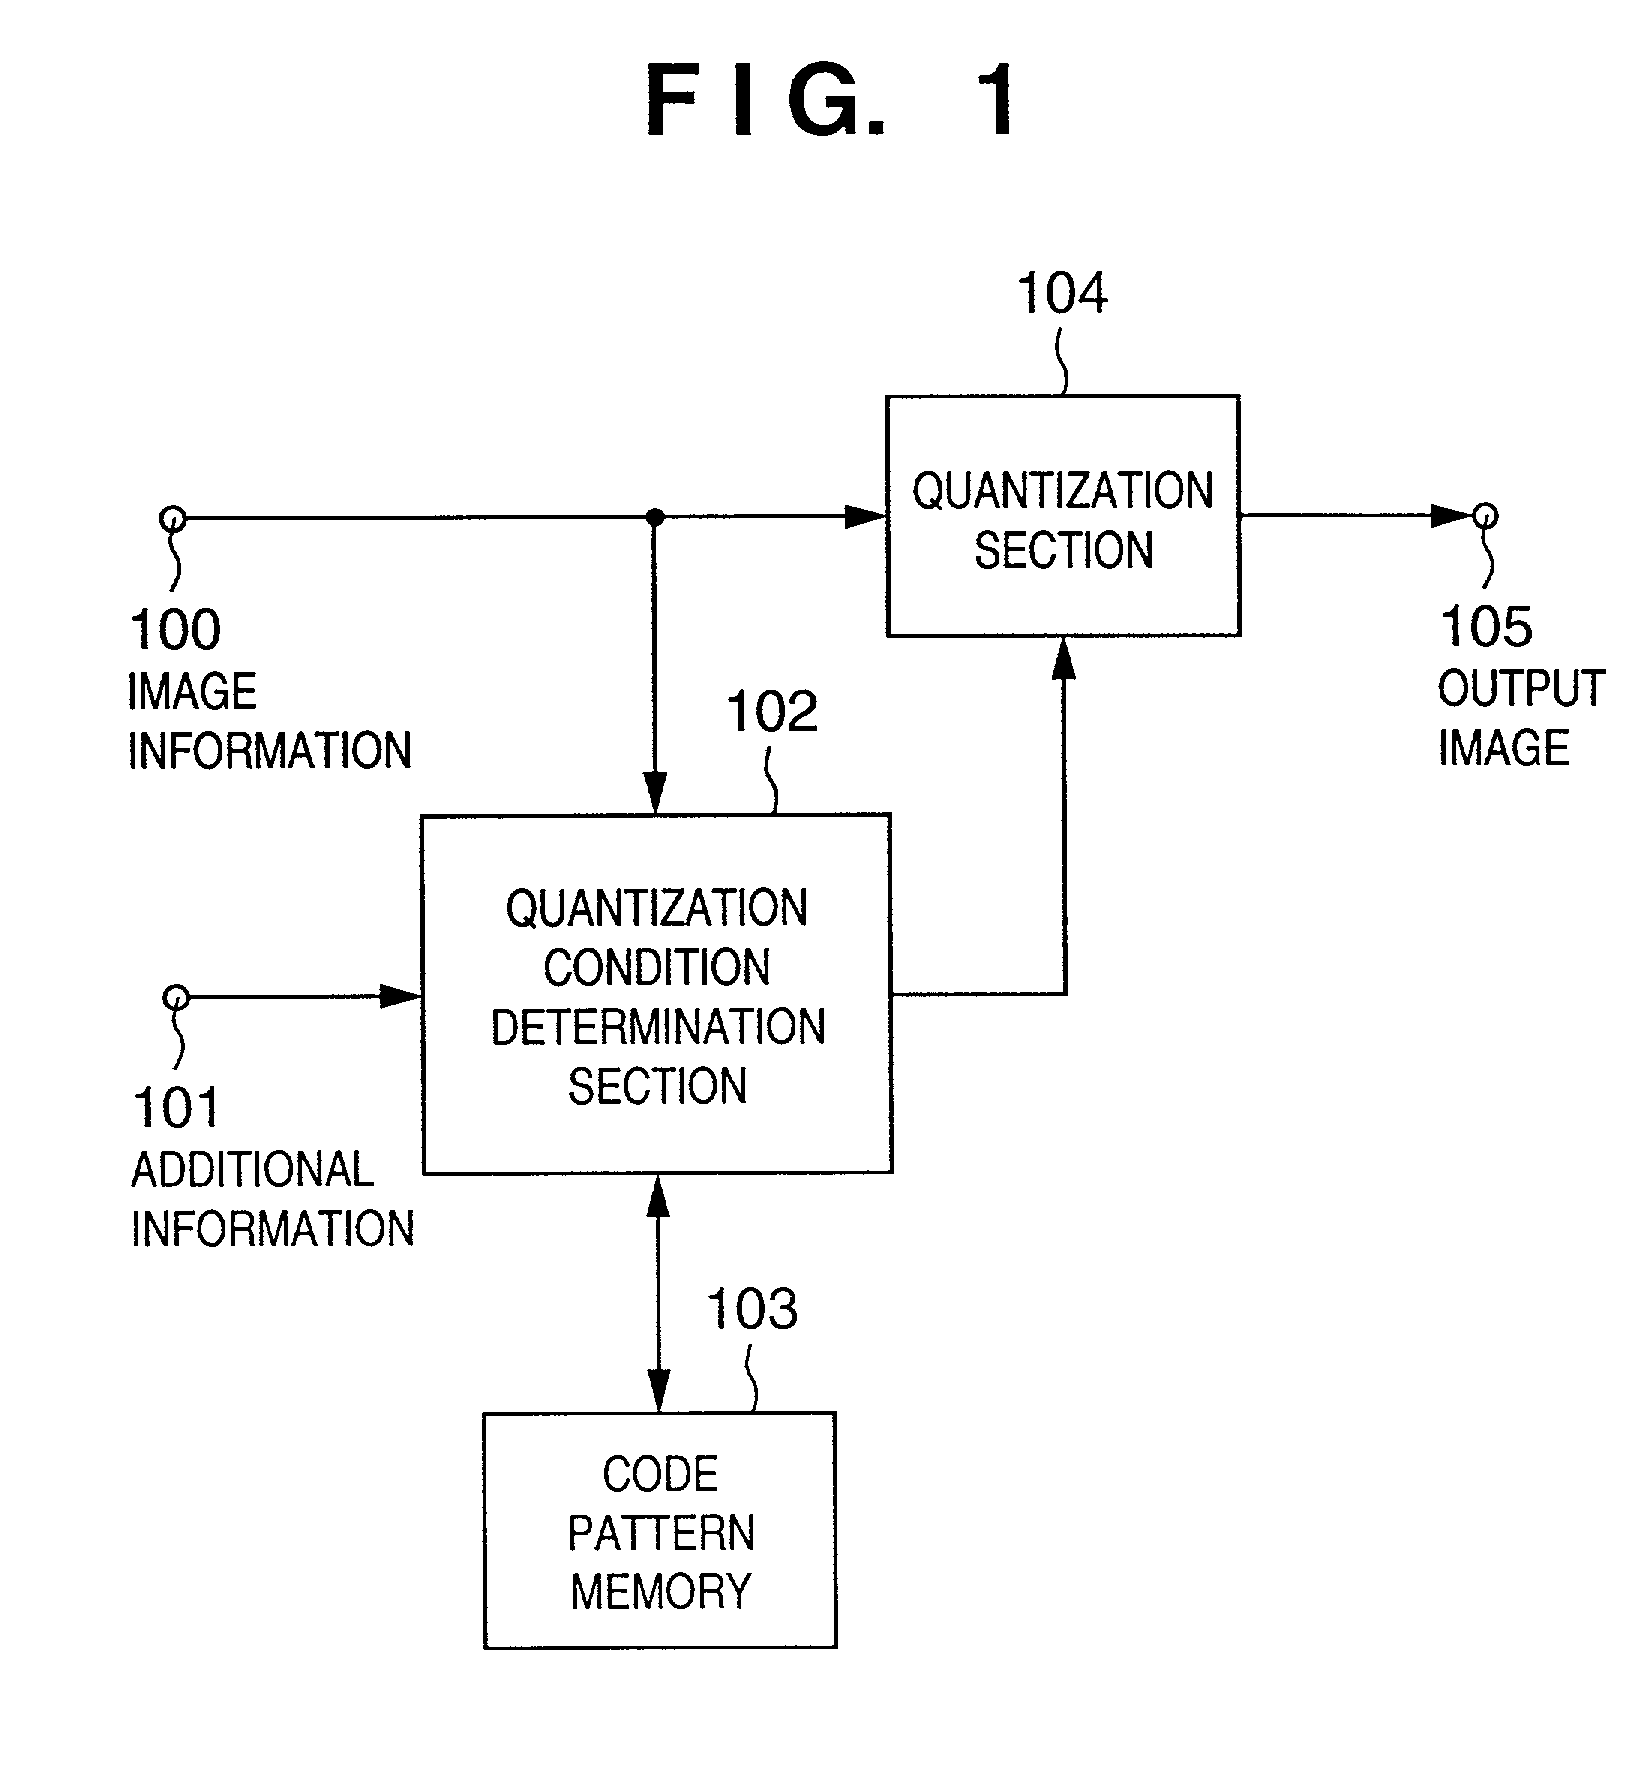
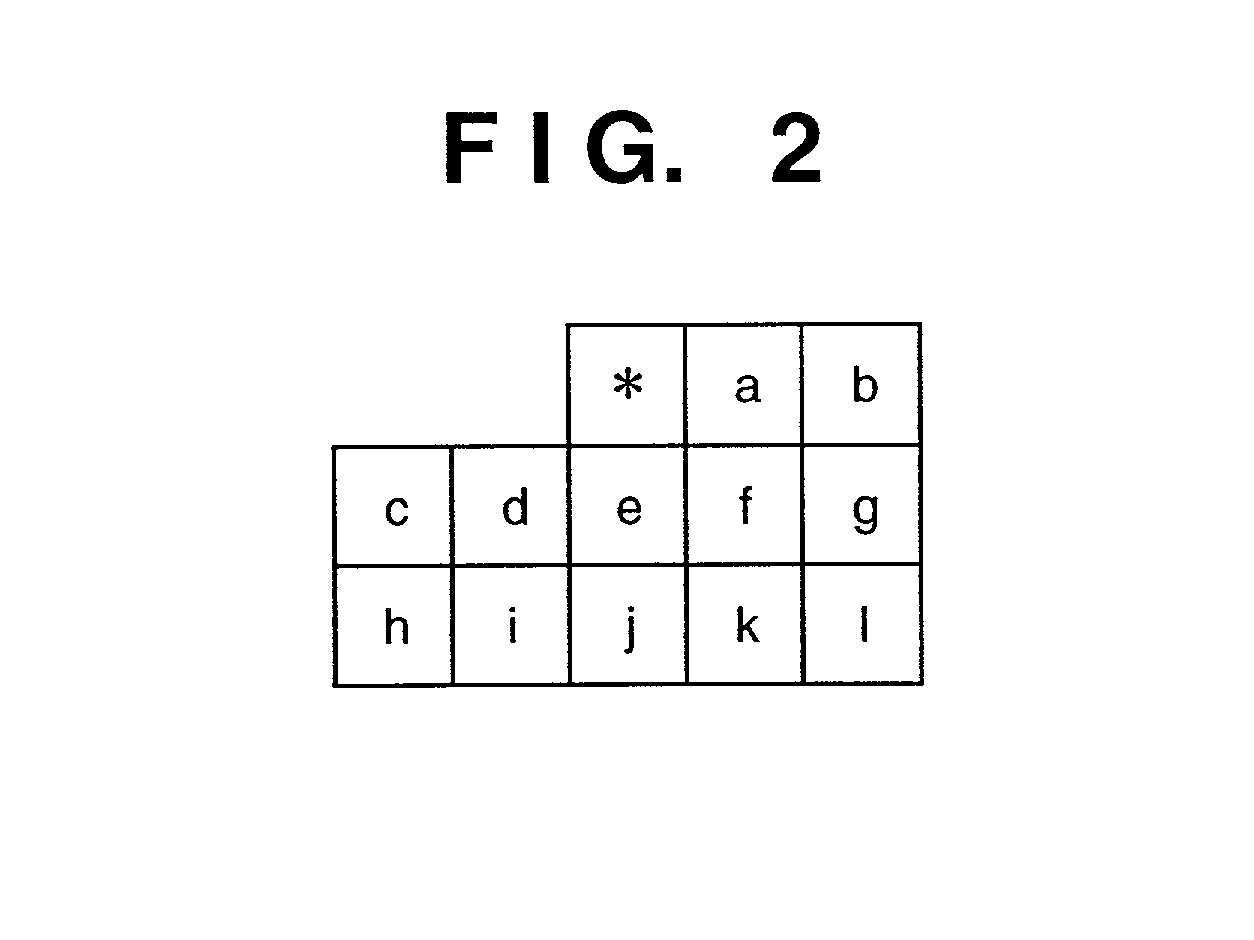
A pattern which does not appear at a flat portion in normal binarization processing is set as a code pattern, and a code formed from this pattern is attached. At this time, code attachment with little degradation in image quality is implemented by selecting an unnoticeable pattern.
Owner:CANON KK
Dynamic human modeling method based on three-dimensional gaussians
Disclosed in the present invention is a dynamic human modeling method based on three-dimensional Gaussians. In the present method, a multi-view human video is given firstly, and in order to correct and transform the dynamic human appearance, a latent code and a set of blend weights are added to each Gaussian; and the latent code and a target pose are inputted to an MLP to correct the Gaussian in a canonical space, so as to capture an appearance change under the target pose. The corrected Gaussian is transformed into the target pose by means of the blend weights thereof in a linear blend skinning (LBS) manner. Finally, a realistic human image at a new viewing angle or a new pose can be rendered in real time by means of Gaussian splatting. Compared with an existing method based on an implicit neural radiance field (NeRF), the three-dimensional Gaussian representation of the present invention can better capture high-frequency details while achieving optimal rendering performance.

Owner:ZHEJIANG UNIV

Methods for manipulating objects in an environment
PendingUS20250157136A1Input/output for user-computer interactionGraph readingComputer graphics (images)Human–computer interaction

Owner:APPLE INC
Display screen or portion thereof with graphical user interface

Owner:MASIMO CORP
Face image restoration method based on state space model
The present application discloses a face image restoration method based on a state space model, which includes inputting the to-be-restored face image to a restoration model to obtain a restored face image; the restoration model includes an encoder and a decoder; the encoder sequentially includes a first image fusion module, a first multi-scale state space module, a second image fusion module, a second multi-scale state space module, a third image fusion module, and a third multi-scale state space module; the decoder sequentially includes a fourth multi-scale state space module, a first multi-scale attention fusion module, a fifth multi-scale state space module, a second multi-scale attention fusion module, a sixth multi-scale state space module, and a third multi-scale attention fusion module. This method ensures the consistency of face semantic information while restoring the detailed texture, especially low quality face images in real degraded scenes can achieve better restoration results.

Owner:NANJING UNIV OF POSTS & TELECOMM
Methods for managing overlapping windows and applying visual effects
ActiveUS20250118038A1Input/output for user-computer interactionExecution for user interfacesComputer graphics (images)Engineering
In some embodiments, a computer system changes a visual prominence of a respective virtual object in response to detecting a threshold amount of overlap between a first virtual object and a second virtual object. In some embodiments, a computer system changes a visual prominence of a respective virtual object based on a change in spatial location of a first virtual object with respect to a second virtual object. In some embodiments, a computer system applies visual effects to representations of physical objects, virtual environments, and / or physical environments. In some embodiments, a computer system changes a visual prominence of a virtual object relative to a three-dimensional environment based on display of overlapping objects of different types in the three-dimensional environment. In some embodiments, a computer system changes a level of opacity of a first virtual object overlapping a second virtual object in response to movement of the first virtual object.

Owner:APPLE INC
Reconstruction method of three-dimensional reconstruction model based on two-dimensional Gaussian splashing
The invention provides a reconstruction method of a three-dimensional reconstruction model based on two-dimensional Gaussian splashing, which comprises the following steps: S1, carrying out sparse reconstruction on an input image sequence through a multi-view stereoscopic vision algorithm to generate an initial sparse three-dimensional point cloud and a corresponding camera pose parameter; s2, inputting an improved two-dimensional Gaussian radiation field by using the sparse three-dimensional point cloud and the camera pose as information; s3, dynamically screening a visible anchor point subset based on the current view angle parameter, and generating a rendered image through a differentiable rendering pipeline; s4, calculating a loss function of the rendering image of the training track and the input image to optimize a reconstruction scene; and S5, starting a special visualization tool, and inputting a rendering result. According to the method, by introducing a trimmable anchor point parameterization framework and a multi-scale feature fusion mechanism, light-weight and high-precision three-dimensional scene modeling is achieved, and the problems that traditional 2D Gaussian sputtering is insufficient in multi-view geometric consistency, storage overhead and weak texture region reconstruction and an existing 2D Gaussian splashing method is insufficient in self-adaptive mechanism are solved.

Owner:GUANGDONG BOHUA UHD INNOVATION CENT CO LTD
Historical block scene three-dimensional reconstruction method and system based on Gaussian sputtering
The invention discloses a historical block scene three-dimensional reconstruction method and system based on Gaussian sputtering, and the method comprises the steps: collecting a historical block video sequence through a lightweight panorama camera, extracting a multi-frame panorama, and generating an image data set through a projection converter; monocular depth and normal estimation is carried out through a pre-training visual model, and a prior depth and normal graph data set of a historical block scene is constructed; sparse reconstruction is carried out on the multi-view image data set based on the SfM technology, initial point cloud and camera pose information are acquired, and a Gaussian ellipsoid is optimized in combination with prior depth and normal information; dynamically calculating the geometric width estimation value of the street, and guiding and adjusting the adaptive density of the Gaussian ellipsoids of the vertical surfaces on the two sides; rendering the optimized Gaussian ellipsoid through an improved rasterization renderer; and designing a multi-modal loss function and a regularization mechanism to optimize reconstruction and rendering results. According to the method, high-fidelity three-dimensional reconstruction of the historical block scene is realized, and the adaptability of the Gaussian sputtering method to the complex block scene is enhanced.

Owner:BEIJING UNIV OF CIVIL ENG & ARCHITECTURE
Image enhancement method and system in complex coal mine environment
ActiveCN120495604ACharacter and pattern recognitionBiological modelsImaging processingImaging quality
The invention discloses an image enhancement method and system in a complex coal mine environment, and relates to the technical field of image processing, and the method comprises the steps: carrying out the preprocessing of a collected coal mine image of a target region, and dividing the coal mine image into different semantic regions, including a bright region, a dark region and a dust shielding region, through a deep learning semantic segmentation model; according to semantic region characteristics, a differentiation enhancement strategy is made; a traditional Retinex model is improved, non-local mean filtering is introduced, and an illumination component and a reflection component are decomposed through pixel similarity matching. According to the method, the image is divided into the bright area, the dark area and the dust shielding area through the deep learning semantic segmentation model, differential enhancement strategies are formulated according to different area characteristics, detail distortion caused by global adjustment is avoided, local contrast suppression is adopted in the bright area, illumination compensation is enhanced in the dark area, and the image quality is improved. Noise diffusion of the dust shielding area is inhibited through edge preservation smoothing, the image quality of each area is remarkably improved, and it is ensured that image details in a complex coal mine environment are clear and visible.

Owner:CHINA COAL TECH GRP INFORMATION TECH CO LTD
Digital human video generation method based on multi-modal large model
PendingCN120472059ADetails involving 3D image dataArtificial lifeComputer graphics (images)Business enterprise
The invention belongs to the technical field of virtual person generation, and particularly relates to a digital person video generation method based on a multi-modal large model, and the method comprises the following steps: 1, constructing a multi-modal data system; 2, multi-modal large model training and adaptation are carried out; 3, constructing a digital human three-dimensional model; step 4, performing semantic analysis and modal mapping; 5, generating a time sequence action and a mouth shape; step 6, building and rendering a virtual scene; step 7, audio and video synchronous rendering and synthesis; step 8, quality optimization and defect repair; and step 9, performing user interaction and iterative optimization. Through technical innovation and engineering, the core pain point in digital human video generation is solved, efficient, vivid and customizable content production capacity is provided for virtual anchors, intelligent customer service, enterprise training and other scenes, and the AI digital human technology is promoted to be applied to large-scale business from experiments.


Owner:ZHE JIANG YAN HUANG KE JI YOU XIAN GONG SI
Video super-resolution reconstruction method and system
The invention discloses a video super-resolution reconstruction method and system, and relates to the technical field of video restoration processing, and the method comprises the steps: collecting a to-be-reconstructed video frame sequence and a reference frame sequence; extracting a dense optical flow field between the reference frame and the target frame; performing geometric alignment on the target frame to the reference frame according to the dense optical flow field to obtain a motion consistency feature; performing feature extraction on the video frame sequence through a parameterized residual scaling module; inputting the extracted features into a bidirectional propagation module to process forward and backward image sequences respectively, extracting time sequence forward features and time sequence reverse features, and fusing the features to obtain detail features; carrying out adaptive fusion on the motion consistency features and the detail features, and sending the fused features into a reconstruction network to obtain deep visual features; pixel-level adaptive reconstruction is realized according to the deep visual features, and a super-resolution video sequence is obtained; according to the method, the feature space consistency is kept, and meanwhile, the feature matching precision in a complex motion scene is remarkably improved.

Owner:BEIJING UNIV OF TECH
Intelligent MV generation method, system and device based on AIGC and medium
The invention relates to an intelligent MV generation method, system and device based on AIGC and a medium, and belongs to the technical field of artificial intelligence content generation. The method comprises the following steps: receiving an original music file input by a user and a user instruction; performing audio preprocessing on the original music file to generate a standardized audio signal, and mapping a user instruction into a semantic vector; rhythm features and emotion features are extracted, music feature vectors are generated and subjected to feature alignment with semantic vectors, and an initial key frame sequence is generated based on a diffusion model; performing particle effect density dynamic adjustment and shot switching point generation on the initial key frame sequence, outputting an enhanced key frame sequence, performing optical flow frame insertion and long time sequence prediction, and generating an optimized video frame sequence; and performing block parallel rendering on the optimized video frame sequence according to the target platform parameters to generate an MV file and metadata. According to the invention, deep fusion of audio and visual contents can be realized, and high-quality video contents can be generated according to individual demands of users.

Owner:GOLDEN TIMES CULTURE COMM
Four-dimensional object and scene model synthesis using generative models
In various examples, systems and methods are disclosed relating to generation of four-dimensional (4D) content models, such as 4D content models to render realistic sequences of frames of 3D data. The systems can initialize a 3D component of the 4D content model, such as a 3D Gaussian splatting representation, based at least on a prompt for the 4D content. The system can configure motion and / or dynamics for the sequence of frames by evaluating frames rendered from the 4D content model using one or more latent diffusion models (LDMs), including a video LDM. The system can perform operations such as autoregressive generation of frames to create long sequences of content, motion amplification to facilitate realistic, dynamic motion generation, and regularization to facilitate generation of complex dynamics.

Owner:NVIDIA CORP
Devices, methods and graphical user interfaces for three-dimensional preview of objects
PendingUS20250199656A1Input/output for user-computer interactionImage data processingGraphical user interfaceComputer graphics (images)
A three-dimensional preview of content can be generated and presented at an electronic device in a three-dimensional environment. The three-dimensional preview of content can be presented concurrently with a two-dimensional representation of the content in a content generation environment presented in the three-dimensional environment. While the three-dimensional preview of content is presented in the three-dimensional environment, one or more affordances can be provided for interacting with the one or more computer-generated virtual objects of the three-dimensional preview. The one or more affordances may be displayed with the three-dimensional preview of content in the three-dimensional environment. The three-dimensional preview of content may be presented on a three-dimensional tray and the one or more affordances may be presented in a control bar or other grouping of controls outside the perimeter of the tray and / or along the perimeter of the tray.

Owner:APPLE INC
Scene reconstruction method based on delayed rendering and three-dimensional Gaussian
The invention provides a scene reconstruction method based on delayed rendering and three-dimensional Gaussian. The method comprises the following steps: S1, generating initial three-dimensional point cloud data based on a multi-view image; s2, constructing a trainable structural body for three-dimensional Gaussian modeling; s3, normal initialization and residual optimization are carried out on the Gaussian ellipsoid primitives, depth consistency constraint is combined, and a differentiable and learnable normal reconstruction mechanism is realized, so that the geometric expression ability of illumination modeling is enhanced; s4, introducing a reflection training mechanism based on ambient light and a reflection direction, and generating a Gaussian attribute based on a visual angle; and S5, a final image is generated through a differentiable Gaussian sputtering rendering algorithm, and optimization is carried out through pixel loss of the final image and a real image. According to the method, the reality sense and geometric consistency of the Gaussian sputtering model under the complex illumination condition are remarkably improved, and the technical problems of unreal rendering effect, inaccurate surface normal estimation, weak propagation capability and the like of the existing three-dimensional Gaussian sputtering model under the complex illumination condition are solved.

Owner:GUANGDONG BOHUA UHD INNOVATION CENT CO LTD
Methods for manipulating a virtual object
ActiveUS20250224811A1Input/output for user-computer interactionGraph readingObject basedComputer graphics (images)
In some embodiments, a computer system performs virtual object manipulation operations using respective portions of the user's body and / or input device(s). In some embodiments, a computer system manipulates a virtual object based on input from a hand of a user and / or a handheld device. In some embodiments, a computer system manipulates a virtual object directly or indirectly.

Owner:APPLE INC
Tunnel surrounding rock grading method and system
The invention relates to the technical field of tunnel engineering, in particular to a tunnel surrounding rock grading method and system, comprising intelligent sensing and data acquisition, multi-source data fusion and modeling, hybrid model dynamic grading, real-time decision and support optimization, online learning and dynamic feedback, and risk early warning and emergency response. Compared with the prior art that a geological data acquisition mode combining manual drilling coring and low-resolution geophysical prospecting is adopted, efficiency is low, subjective errors are large, and a complex geological structure is difficult to cover, unmanned aerial vehicle LiDAR scanning, intelligent rock core image analysis and a high-density IoT sensor network work cooperatively, and the working efficiency is greatly improved. Real-time dynamic acquisition of full-section geological information is achieved, manual intervention errors are eliminated in combination with a multi-source data fusion algorithm, the automation level and three-dimensional space representation precision of data acquisition are remarkably improved, and a high-resolution holographic data base is provided for surrounding rock classification.


Owner:CHONGQING YICHENG CONSTRUCTION ENGINEERING CO LTD
Three-dimensional environment reconstruction optimization method based on multi-sensor fusion data
The invention discloses a three-dimensional environment reconstruction optimization method based on multi-sensor fusion data, and relates to the field of three-dimensional environment reconstruction optimization, and the three-dimensional environment reconstruction optimization method based on the multi-sensor fusion data comprises the following steps: S1, collecting multi-source sensor data, and constructing a data set under a unified coordinate system; s2, generating dense visual point cloud, and extracting laser point cloud features to construct a model; s3, establishing a local three-dimensional model, and generating a local environment image; s4, shadow parameters are extracted through shadow geometric analysis, and time sequence optimization is carried out; s5, consistency verification and correction are carried out, and three-dimensional reconstruction data are output; and S6, comparing the reconstruction data with the navigation map database, and carrying out map optimization updating. According to the method, time synchronization and space calibration are carried out on data acquired by the depth camera and the laser radar, complete and accurate three-dimensional information modeling of the target environment is realized, and the geometric precision of environment reconstruction and the image detail reduction capability are improved.

Owner:NORTH CHINA UNIV OF WATER RESOURCES & ELECTRIC POWER
Display screen with a graphical user interface for electronic messaging

Owner:CITIBANK N A
Curtain wall defect detection system based on computer vision
The invention relates to the technical field of defect detection, in particular to a curtain wall defect detection system based on computer vision, which comprises an image acquisition module, a texture analysis module, a dynamic defect tracking module, a defect positioning module and a defect identification module. According to the invention, a multi-angle curtain wall data set is collected through the arranged fixed camera and the angle-adjustable camera, the coverage range of the whole and details of the building curtain wall is increased, the accurate adjustment of synchronous shooting parameters and the deep analysis of each frame of image enable the data collection to be more complete, and the high-quality image data is ensured. The system is allowed to perform local texture feature analysis and dynamic trajectory tracking, so that the automation degree of defect detection is improved, the manual intervention requirement is reduced, the detection efficiency and accuracy are improved, an abnormal motion area is automatically marked and analyzed, the system can find potential structural safety problems in time, and the safety of the system is improved. Accurate data support is provided for maintenance and repair, and maintenance cost and building safety risks are reduced.

Owner:DECORATION CO LTD OF CHINA CONSTR 3RD ENG BUREAU
Systems and methods for dashcam installation
ActiveUS12344168B1Character and pattern recognitionVehicle componentsComputer graphics (images)Image capture
The present disclosure is related to systems and methods of dashcam installation for providing instructions on placing a dashcam for a person or dashcam installer. Aspects of the present disclosure are related to providing a digital assistant for installing the dashcam in an acceptable position, where the dashcam can capture images of objects with acceptable quality (e.g., as determined by a machine learning model). In some embodiments, the dashcam detects a driver and provides inferences related to the current dashcam position. The inferences can be based on analyzing images captured by the dashcam in the current position, where the analysis can utilize a machine learning model. The inferences can also provide one or more instructions to move and / or tilt the dashcam to the acceptable installation position.

Owner:SAMSARA INC
WebGL-based cloud collaborative three-dimensional building modeling rendering method and system
The invention provides a cloud collaborative three-dimensional building modeling rendering method and system based on WebGL (Web Graphics Library). The method comprises the following steps: acquiring design parameters of a target building, analyzing the design parameters into geometric topological data of a plurality of independent components on the basis of a functional attribute division rule, and generating a multi-stage detail geometric model; adding material physical attributes to the surface vertex data, calculating a diffuse reflection coefficient and specular reflection intensity through a ray tracing algorithm, and generating lightweight component data carrying physical rendering parameters; in response to a view angle switching instruction of a terminal user, according to a space block corresponding to a current view angle, a main GPU node is distributed from a distributed GPU cluster, the main GPU node is divided according to the space block, adjacent blocks of the space block are distributed to edge GPU nodes, parallel ray tracing calculation is executed based on a WebGL protocol, and the parallel ray tracing calculation is executed based on the WebGL protocol. And returning to the main GPU node synthesis terminal display image and displaying. According to the technical scheme provided by the invention, the response speed is remarkably improved while the physical-level rendering effect is kept.

Owner:BEIJING GREATMAP TECH
Display screen or portion thereof with transitional graphical user interface

Owner:OTSUKA MEDICAL DEVICES
Display screen or portion thereof with transitional graphical user interface

Owner:ARISTOCRAT TECHNOLOGIES INC
Window resizing and virtual object rearrangement in 3D environments
ActiveUS12394167B1Input/output for user-computer interactionGraph readingComputational scienceComputer graphics (images)
Methods for counter-scaling windows and rearranging objects within those counter-scaled windows in a 3D computer-generated environment is disclosed. The windows can be counter-scaled in accordance with changes to their depth within the 3D computer-generated environment. Objects within the window can be presented at their actual size and with their correct scale relative to each other and with respect to the 3D computer-generated environment, and can maintain their actual size and scale relative to each other and the environment regardless of the depth of the window in the environment. Some embodiments of the disclosure rearrange the layout of the objects to present more or fewer objects in the window as the size of the window changes due to counter-scaling. Depth-dependent window resizing and object rearrangement while preserving actual object size and scale within the 3D computer-generated environment can provide a more authentic viewing experience and can encourage increased user interaction.

Owner:APPLE INC