
Patents
Literature
155977results about "Image analysis" patented technology
Efficacy Topic
Property
Owner
Technical Advancement
Application Domain
Technology Topic
Technology Field Word
Patent Country/Region
Patent Type
Patent Status
Application Year
Inventor
System and Method for Multi-Modal Hyperspectral Image Generation with Cross-Modal Attention and Adaptive Quality Assurance
A system and method are disclosed for generating hyperspectral images from multi-modal sensor data including RGB, LiDAR, thermal, and near-infrared inputs. Training data includes hyperspectral images and corresponding multi-modal measurements. Spectral band grouping is performed based on correlation coefficients. A multi-modal decomposition network with cross-modal attention mechanisms generate reconstructed hyperspectral images by fusing complementary sensor information. A fine-tuning network creates reconstructed RGB images. A comprehensive quality assurance system analyzes spectral consistency, cross-modal coherence, and fusion artifacts to generate quality metrics. Missing data compensation strategies handle corrupted sensor inputs using information from other modalities. The system includes temporal integration for video sequences and multi-resolution processing for different sensor resolutions. Quality metrics guide network weight adjustments to improve reconstruction accuracy while maintaining robustness to sensor failures and environmental variations.

Owner:ATOMBEAM TECH INC
Salient contour matching-based method for target measurement in severe imaging environment
Disclosed in the present invention is a salient contour matching-based method for target measurement in a severe imaging environment. The method specifically comprises: (1) acquiring a binocular image of a target; (2) establishing a global-local joint constraint-based background light estimation model, and removing a scattering effect of a medium in an imaging environment to obtain a restored left eye image and a restored right eye image; (3) learning an original image, and on the basis of a residual between a network reconstructed image and the original image, obtaining target localization prediction maps of the left eye image and the right eye image; and (4) respectively extracting contour lines of the target in the left eye image and the right eye image, constructing feature matching descriptors of contour points, performing stereo matching on the two sets of contour lines by minimizing matching cost, and performing three-dimensional reconstruction on the contour lines in light of calibrated intrinsic and extrinsic parameters to complete the measurement of a key size. According to the present invention, the key sizes of different targets in a severe environment can be accurately measured, thereby providing an effective solution for the problem of measuring the sizes of targets in a severe environment.

Owner:STATE GRID JIANGSU ELECTRIC POWER CO LTD YANCHENG POWER SUPPLY BRANCH
Visible light and infrared image fusion method based on cross-modal dynamic collaboration
The invention discloses a visible light and infrared image fusion method based on cross-modal dynamic collaboration. The method comprises the following steps: respectively extracting texture detail features of a visible light image and thermal radiation features of an infrared image through a visible light encoder and an infrared encoder; spatial alignment and channel complementarity optimization of cross-modal features are realized by using a heterogeneous attention collaboration module; and performing layered fusion on deep semantics and shallow detail features through a dynamic gating multi-scale decoder to generate a high-resolution fusion image. According to the method, the problems of feature dislocation, detail loss and unreasonable fusion weight distribution caused by modal difference in the prior art are solved, the detail fidelity, the thermal target saliency and the complex scene adaptability of the fusion image can be remarkably improved, and a high-robustness fusion result is provided for low-illumination environment perception and multi-modal target recognition.

Owner:ZHEJIANG SCI-TECH UNIV
High-precision image processing method and system based on illumination adaptive compensation
The invention discloses a high-precision image processing method and system based on illumination adaptive compensation, and relates to the technical field of computer vision and image processing, and the method comprises the steps: inputting an original image, and dividing the image into a high-frequency edge layer, an intermediate-frequency texture layer and a low-frequency illumination layer through a multi-scale residual network; acquiring illumination intensity, color temperature and scene categories in real time by using an ambient light sensor and a scene semantic segmentation model, and generating dynamic compensation parameters; carrying out dynamic range expansion on a low-frequency illumination layer based on a physical illumination model, and adjusting the weight of highlight suppression and dark area enhancement through a self-adaptive S-shaped exposure curve; a double-branch generative adversarial network is adopted, noise suppression and super-resolution reconstruction are carried out on the high-frequency layer, and texture detail enhancement is carried out on the intermediate-frequency layer; aligning the data of the depth camera and the infrared sensor with the visible light image through a cross-modal fusion module; and performing tone mapping on the fused image based on human visual characteristics, and outputting an enhanced image with a high dynamic range and reserved details.

Owner:SHANXI UNIV
High-performance loosely-coupled multi-modal data fusion system for smart driving environmental perception system and vehicle-mounted device
PCT designated stageWO2025241308A1Image enhancementInstruments for road network navigationData setTracking model
Disclosed are a high-performance loosely-coupled multi-modal data fusion system for a smart driving environmental perception system and a vehicle-mounted device, comprising: a fusion detection model based on a modality-independent feature interaction strategy, which is configured for converting a LiDAR point cloud, a camera image, and a millimeter-wave radar point cloud into a unified bird's-eye view representation, and performing multi-modal fusion; and a fusion tracking model based on a motion-appearance feature cascaded coupling data association strategy, which is configured for performing subsequent trajectory tracking and matching according to multi-modal fusion feature information. A VoD data set and a K-Radar data set are selected for training, verifying, and testing the comprehensive performance of the models, and a TensorRT accelerated inference model is applied, then quantized, and deployed to a vehicle-mounted computational testing platform. The present invention is compatible with mainstream sensor deployment solutions, and achieves the efficient complementary fusion of multi-source heterogeneous sensor information, significantly improving the reliability, accuracy, and adaptability of vehicle-mounted perception systems, thereby effectively responding to extreme operating conditions such as complex traffic scenarios and inclement weather.

Owner:JIANGSU UNIV
Deep learning-based facial recognition system with privacy-preserving features
The present invention provides a facial recognition system using deep learning methodologies while integrating privacy-preserving capabilities. This system employs convolutional neural networks (CNNs) to extract and classify facial features, ensuring high accuracy in recognition tasks. Moreover, the system addresses privacy concerns by incorporating techniques such as facial feature encryption and anonymization, thereby enhancing user privacy and data security. This invention is applicable across various domains, including security, surveillance, access control, and personalized services, where facial recognition is utilized while preserving individual privacy.

Owner:TRIPATHI BHASKAR +11
Defect detection method for high-voltage equipment based on deep learning and multispectral image fusion
The invention relates to a high-voltage equipment defect detection method based on deep learning and multispectral image fusion, and relates to the technical field of electric power high-voltage equipment state detection. The method comprises the following steps: acquiring an ultraviolet image, an infrared image and a visible light image of the surface of the high-voltage equipment; carrying out image pixel feature-based fusion processing on the ultraviolet image, the infrared image and the visible light image through an image fusion method; establishing a high-voltage equipment defect detection model, and training the high-voltage equipment defect detection model by using the fused image data to obtain a high-voltage equipment defect identification model based on the YOLO-STrans multispectral fusion network; and inputting the ultraviolet image, the infrared image and the visible light image of the outer surface of the power high-voltage equipment into a high-voltage equipment defect identification model to obtain a fault identification result of the to-be-detected power high-voltage equipment. The method can improve the recognition precision of the extremely early insulation degradation and temperature anomaly defects of the surface of the high-voltage power equipment.

Owner:ANHUI NANRUI JIYUAN POWER GRID TECH CO LTD
Adaptive sensing-based lightweight monitoring method for fine crack in complex background region
The present invention relates to an adaptive sensing-based lightweight monitoring method for a fine crack in a complex background region. The method comprises the following steps: step S1, on the basis of region division, performing automatic acquisition of crack information, wherein PTZ camera sensors are used to automatically perform block-wise acquisition on crack regions; step S2, performing an adaptive complex scale calibration process, using a multi-scale template matching algorithm to adaptively correct distortion information of all regions, and performing real-scale conversion from pixel precision; step S3, constructing a lightweight crack segmentation network to process data processed in step S2; and step S4, by means of a quantitative crack-tracking algorithm based on Euclidean distance similarity classification, performing real-time monitoring on each piece of crack dynamic information. Compared with the prior art, the present invention has advantages such as achieving efficient, accurate, and online monitoring and analysis of cracks.

Owner:SOUTHEAST UNIV
Defect detection method for semiconductor packaging material based on deep learning
The invention relates to the field of semiconductor packaging material defect detection, in particular to a semiconductor packaging material defect detection method based on deep learning, which comprises the following steps: acquiring a surface image, and extracting a two-dimensional contour and a feature point set; preprocessing the image, and separating a packaging material main body area; constructing a two-dimensional defect identification model based on Transform, and outputting a two-dimensional detection result; scanning suspected and unknown defect areas to obtain three-dimensional point cloud data, and extracting geometric and texture features; fusing two-dimensional and three-dimensional data through a space-time alignment model; utilizing the multi-modal fusion model to output defect positions and types; and evaluating the defect importance based on the material node connectivity and the stress distribution, and generating a visual detection report. According to the invention, high-precision detection of semiconductor packaging material defects is realized, the defect identification rate, the positioning precision and the detection efficiency are improved through multi-modal data fusion and a deep learning model, and a visual report can be generated based on material structure quantification defect importance.

Owner:XIAN UNIV OF POSTS & TELECOMM
LED display defect prediction and process adjustment method and system based on multi-modal fusion
The invention relates to the technical field of LED display, solves the problem that the existing LED display defect detection and parameter adjustment technology is lack of multi-modal information fusion and intelligent process control capability and is difficult to meet the quality control requirement of a high-precision display product, and provides an LED display defect prediction and process adjustment method and system based on multi-modal fusion. The method comprises the following steps: performing multi-modal data fusion processing on optical image data, electrical test data and thermal infrared imaging data corresponding to a to-be-tested LED display screen to obtain fused data; inputting the fused data into a pre-trained defect recognition model to obtain a defect recognition result; according to a process parameter adjustment strategy corresponding to the defect identification result, adjusting the original process parameter to obtain a target process parameter; and according to the target process parameters, process flow correction processing is carried out, and a qualified LED display screen is produced. According to the method, the defect identification precision is improved, and the quality control requirement of high-precision LED display screen production is met.

Owner:XIAMEN PROD QUALITY SUPERVISION & INSPECTION INST +1
Auxiliary dental implant generation method based on diffusion model
The present invention relates to the technical field of stomatology. Provided is an auxiliary dental implant generation method based on a diffusion model. The method in the present invention comprises: acquiring oral CBCT image data of historical patients, preprocessing the oral CBCT image data of the historical patients to obtain a CBCT image dataset, using the CBCT image dataset to train a multi-task segmentation network, and using the segmentation network to obtain an intraoral tissue segmentation result; using the intraoral tissue segmentation result to train detection networks from the three dimensions of a cross-sectional plane, a coronal plane and a sagittal plane, respectively; using the detection networks to obtain detection results in the three directions of the cross-sectional plane, the coronal plane and the sagittal plane; fusing the detection results in the three directions of the cross-sectional plane, the coronal plane and the sagittal plane, and using a majority voting algorithm to construct a three-dimensional bounding box, so as to acquire an edentulous area; and using the intraoral segmentation result and the edentulous area as prompt information to guide, by means of an iterative process, a network to generate a post-implantation effect. The implantation effect obtained by the present invention is highly accurate, thereby providing a more precise auxiliary tool for stomatology.

Owner:CHONGQING UNIV OF POSTS & TELECOMM
Reconstruction method of three-dimensional reconstruction model based on two-dimensional Gaussian splashing
The invention provides a reconstruction method of a three-dimensional reconstruction model based on two-dimensional Gaussian splashing, which comprises the following steps: S1, carrying out sparse reconstruction on an input image sequence through a multi-view stereoscopic vision algorithm to generate an initial sparse three-dimensional point cloud and a corresponding camera pose parameter; s2, inputting an improved two-dimensional Gaussian radiation field by using the sparse three-dimensional point cloud and the camera pose as information; s3, dynamically screening a visible anchor point subset based on the current view angle parameter, and generating a rendered image through a differentiable rendering pipeline; s4, calculating a loss function of the rendering image of the training track and the input image to optimize a reconstruction scene; and S5, starting a special visualization tool, and inputting a rendering result. According to the method, by introducing a trimmable anchor point parameterization framework and a multi-scale feature fusion mechanism, light-weight and high-precision three-dimensional scene modeling is achieved, and the problems that traditional 2D Gaussian sputtering is insufficient in multi-view geometric consistency, storage overhead and weak texture region reconstruction and an existing 2D Gaussian splashing method is insufficient in self-adaptive mechanism are solved.

Owner:GUANGDONG BOHUA UHD INNOVATION CENT CO LTD
Large-scene three-dimensional reconstruction method based on three-dimensional Gaussian sputtering
ActiveCN120472121AImage analysisCharacter and pattern recognitionPattern recognitionReconstruction method
The invention discloses a large-scene three-dimensional reconstruction method based on three-dimensional Gaussian sputtering, and relates to computer graphics. The method comprises the following steps: collecting a multi-view image set of a large scene; obtaining a scene sparse point cloud according to the multi-view image set; performing monocular depth estimation on the multi-view image by using a pre-trained depth prediction network to obtain monocular depth estimation priori; the method comprises the following steps of: performing global training on a scene by utilizing scene sparse point cloud and monocular depth estimation prior to obtain an initial three-dimensional Gaussian model, and performing space grid division on the initial three-dimensional Gaussian model to obtain a plurality of scene blocks with axis alignment bounding boxes; setting image view angle data of each scene block; performing deep supervised training on the Gaussian ellipsoids in the plurality of scene blocks by using a parallel GPU (Graphics Processing Unit); combining the trained scene blocks to obtain a final three-dimensional Gaussian model; in view of low geometric structure reconstruction precision caused by only depending on color information of a multi-view image in large-scene three-dimensional rendering, the method improves the reconstruction precision of large-scene rendering.

Owner:JSTI GRP CO LTD +2
Semi-supervised medical image segmentation method and system based on visual language model
SOLUTION: A semi-supervised medical image segmentation method based on a visual language model includes the steps of: obtaining a medical image; inputting an unlabeled image and a text description into a visual language model, and obtaining a text-guided mask based on obtained dense image embedding and text embedding; inputting a labeled image into a student model, and calculating supervised loss by using obtained labeled image prediction; respectively inputting the unlabeled image into the student model and a teacher model to obtain unlabeled image prediction and a pseudo label, merging the text-guided mask with the pseudo label, and calculating semi-supervised loss by using the merged pseudo label and unlabeled image prediction; and performing medical image segmentation by using a trained student model on the basis of the supervised loss and the semi-supervised loss.EFFECT: A target segmentation region can be accurately identified by using advantages of text descriptions.SELECTED DRAWING: Figure 1

Owner:SHANDONG UNIV
Resistor disc defect online detection system and grading method based on machine vision
The invention discloses a machine vision-based resistor disc defect online detection system and a grading method, relates to the technical field of industrial machine vision detection, and solves the defect problems in the aspects of multi-scale defect dynamic perception, cross-level feature interaction and process adaptive optimization in the prior art. According to the scheme, metal reflection interference is inhibited through Retinex illumination correction and a combined denoising model; adopting a deformable convolution kernel and cavity space pyramid pooling to realize gradient entropy driving dynamic sensing of the multi-scale defect; constructing a bidirectional cross-layer attention network to realize early fusion of high-resolution details and high-level semantics; modeling local-global feature physical association based on a graph attention network and a self-supervised message passing mechanism; integrating reinforcement learning and a memristor random calculation unit to form a closed-loop parameter optimization system; according to the method, the multi-scale defect detection precision, the cross-modal feature fusion efficiency and the system adaptive capacity under complex working conditions are remarkably improved.

Owner:NANYANG GOLDEN CROWN IND CO LTD
PCB (Printed Circuit Board) defect detection method and system based on image recognition
The invention relates to the field of defect detection, in particular to a PCB defect detection method and system based on image recognition. The method comprises the following steps: collecting a multidirectional PCB detection image, carrying out pixel-level registration correction and adaptive pixel stability compensation, and constructing a space-time stability compensation image sequence; performing reverse pyramid structure division on the space-time stability compensation image sequence, performing normalized similarity probability calculation, and constructing an initial region classification result; based on an initial region classification result, depth image visual analysis is carried out, pseudo defect comprehensive elimination optimization is carried out, and a pseudo defect purification high-confidence image is constructed; pCB connection defect identification is carried out on the pseudo defect purification high-confidence image, global defect point distribution marking is carried out, and a defect point space distribution diagram is constructed. According to the invention, high-credibility, high-precision and high-closed-loop PCB defect detection is realized.

Owner:SHENZHEN HTWY TECH CO LTD
Adaptive Real Time Image and Video Processing Using PCM-Enhanced Visual Strategy Caching and Multi-Stage Cognitive Routing
A system and method for adaptive image and video processing using a Persistent Cognitive Machine (PCM) architecture with visual strategy caching. The system receives degraded input media and extracts degradation fingerprints to query a PCM-based visual strategy cache containing previously successful processing strategies. When matching cached strategies are found above a relevance threshold, they are retrieved and applied directly. When no match exists, the input is processed through transform-domain networks to generate new strategies. A pattern synthesizer combines multiple strategies for complex degradation types. The system evaluates processing effectiveness using a feedback controller and stores successful strategies in the hierarchical cache. This cognitive approach enables real-time processing with continuously improving performance as the cache learns from successful patterns. The adaptive architecture eliminates redundant processing while maintaining high-quality output, making it suitable for diverse imaging and video applications requiring efficient enhancement capabilities with superior performance over traditional methods.

Owner:ATOMBEAM TECH INC
PCB (Printed Circuit Board) defect detection method and system
The invention relates to the technical field of PCB detection, and discloses a PCB defect detection method and system, and the method comprises the steps: collecting multispectral imaging data through an image collection module, and generating an original image data set; the defect analysis server receives the synchronous imaging data to construct a three-dimensional surface topology matrix; in combination with the original image data set and the real-time imaging data, performing multi-scale decomposition on the three-dimensional surface topological matrix, extracting texture features, positioning a defect region, outputting defect type space distribution features through a layered recognition model, and updating the original image data set; and dynamically calibrating the detection parameters according to the feature categories. The system comprises an image acquisition module group, a data transmission module, a three-dimensional modeling module, a defect identification module and a parameter calibration module. According to the scheme, the accuracy, comprehensiveness and efficiency of defect detection are improved, and the detection requirements of modern PCB production are met.

Owner:SHENZHEN UNITED MULTILAYER CIRCUIT BOARD CO LTD
Apparatus and methods for predicting wafer-level defect printability
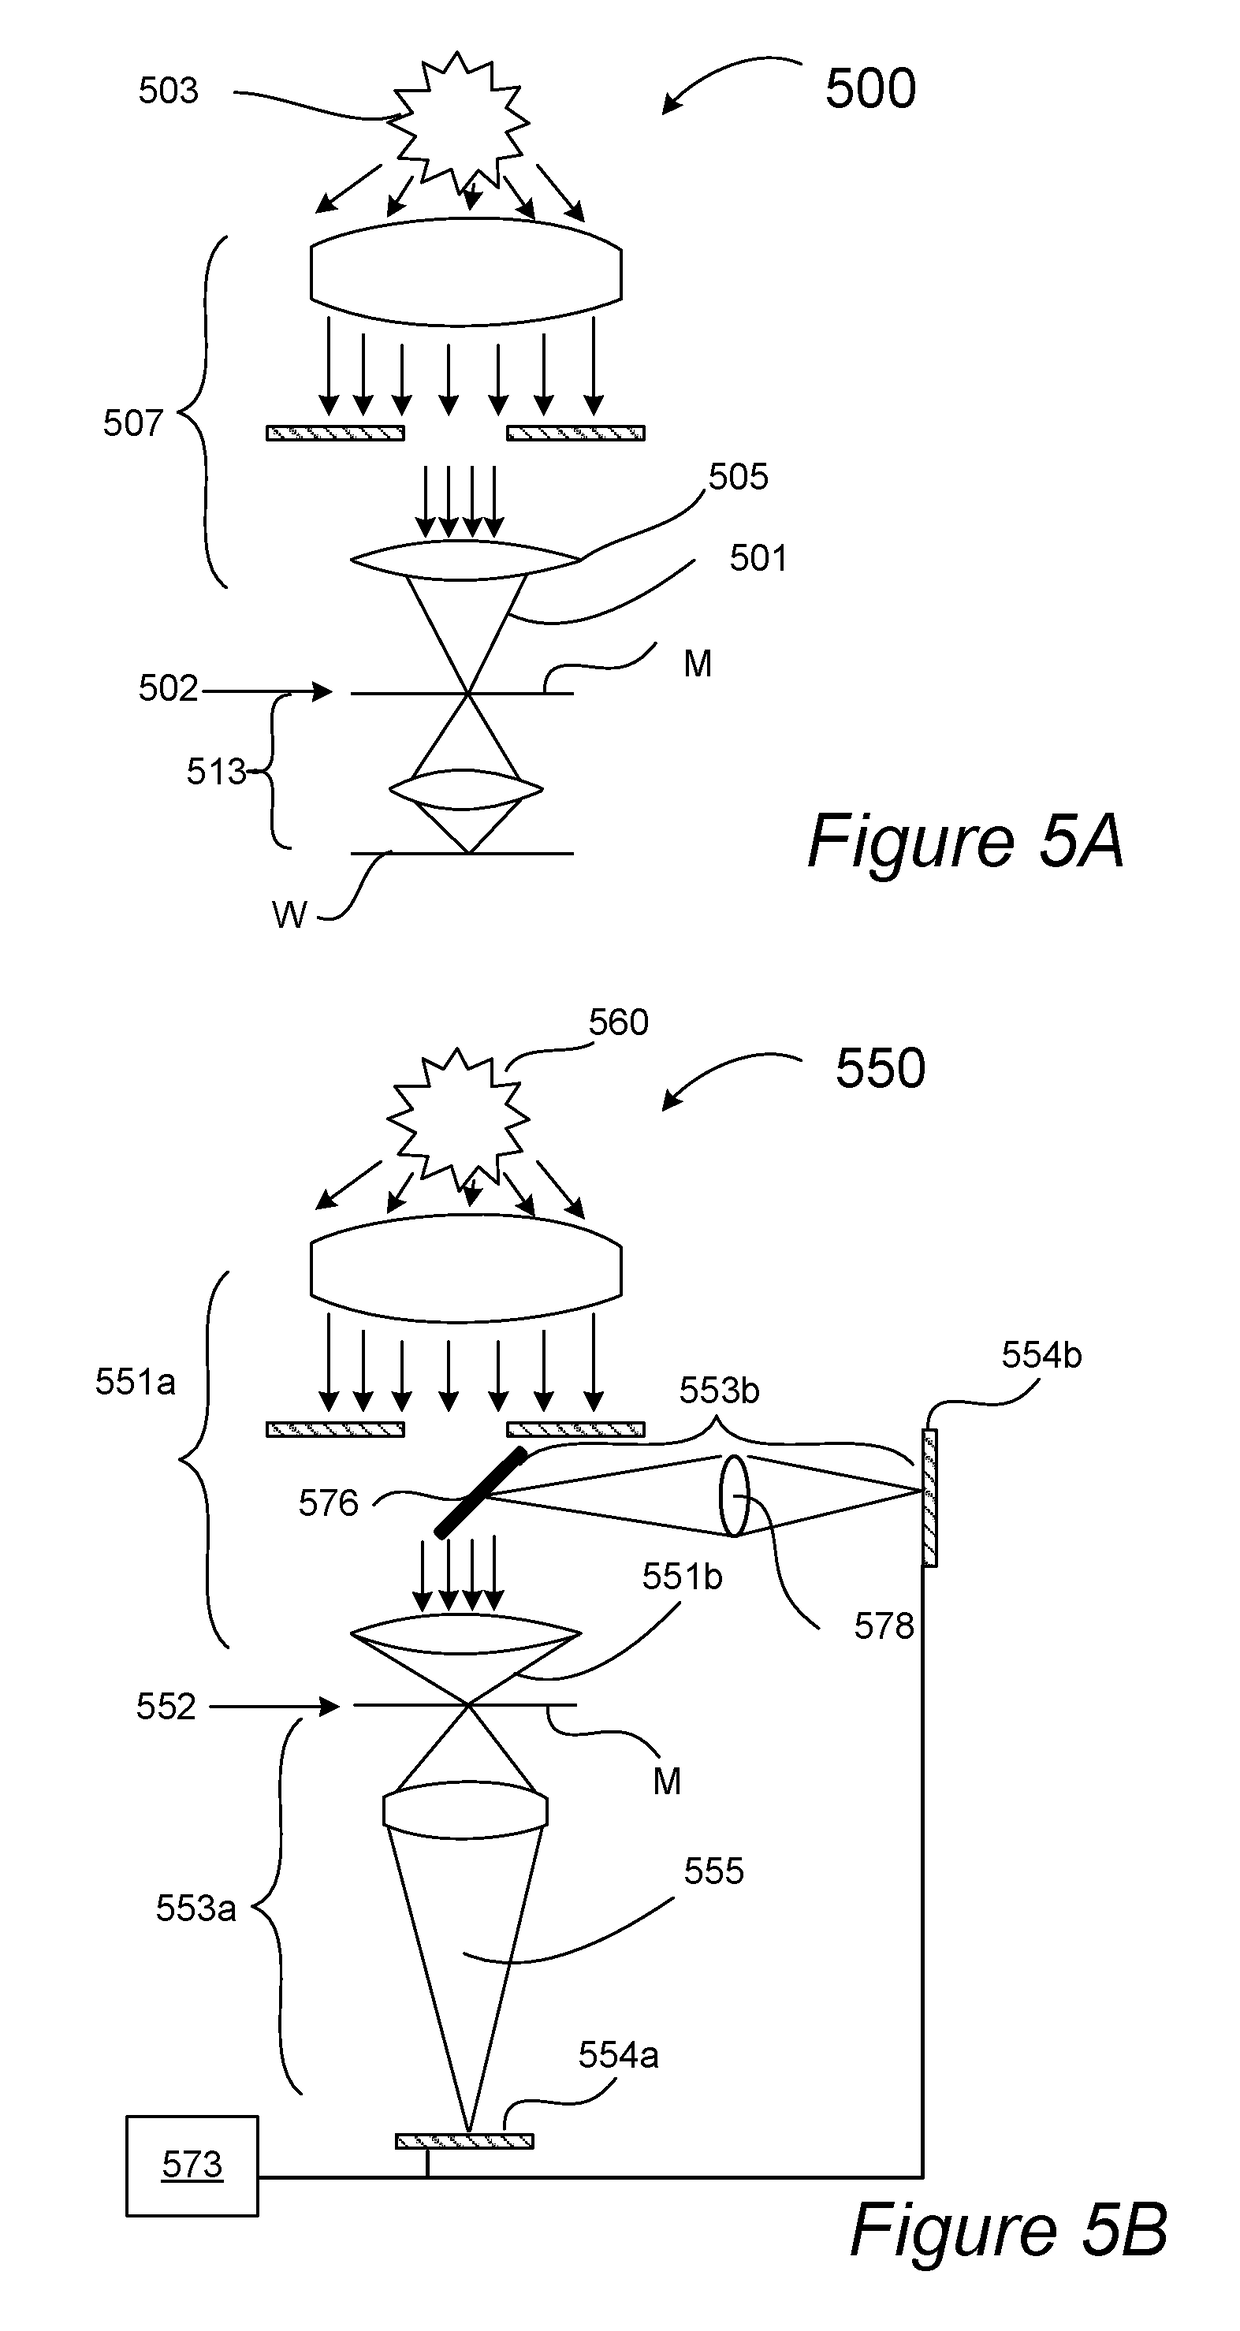
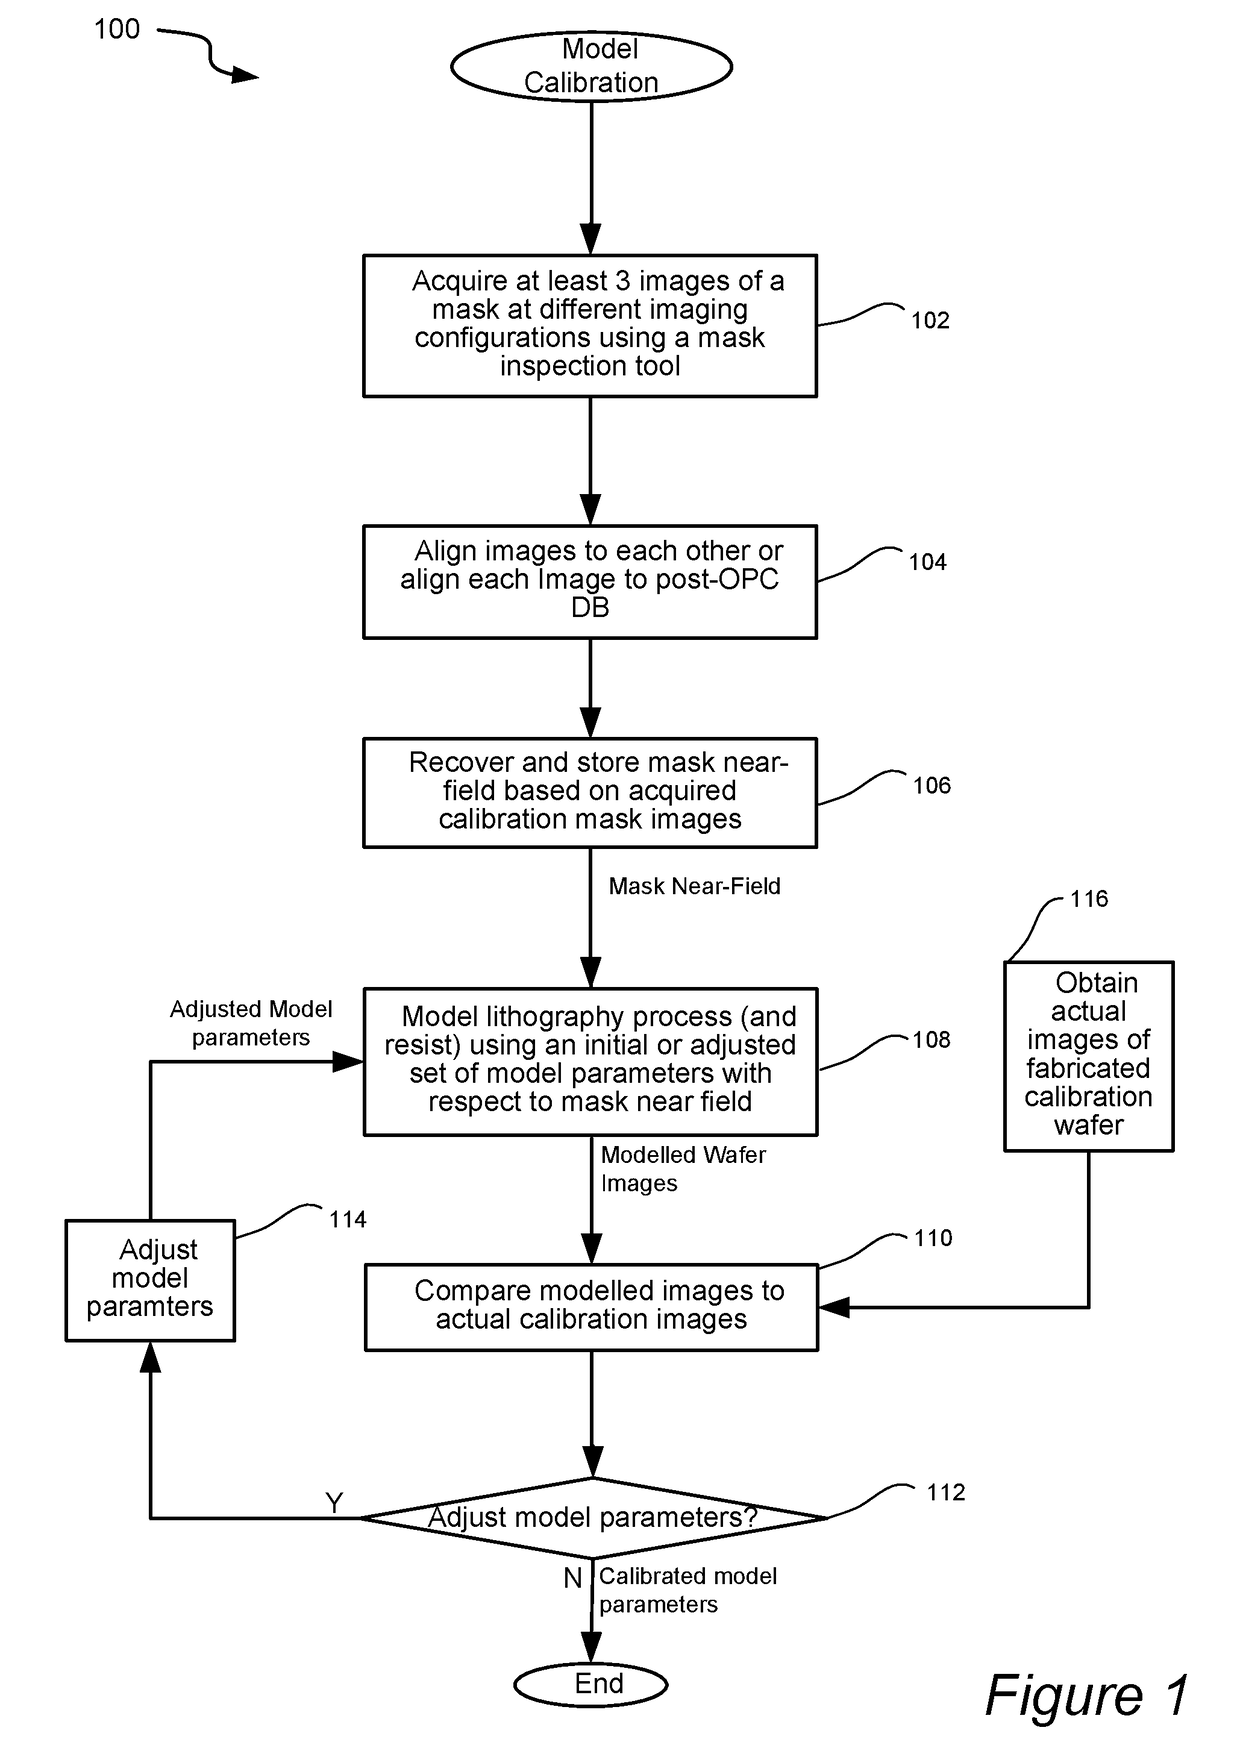
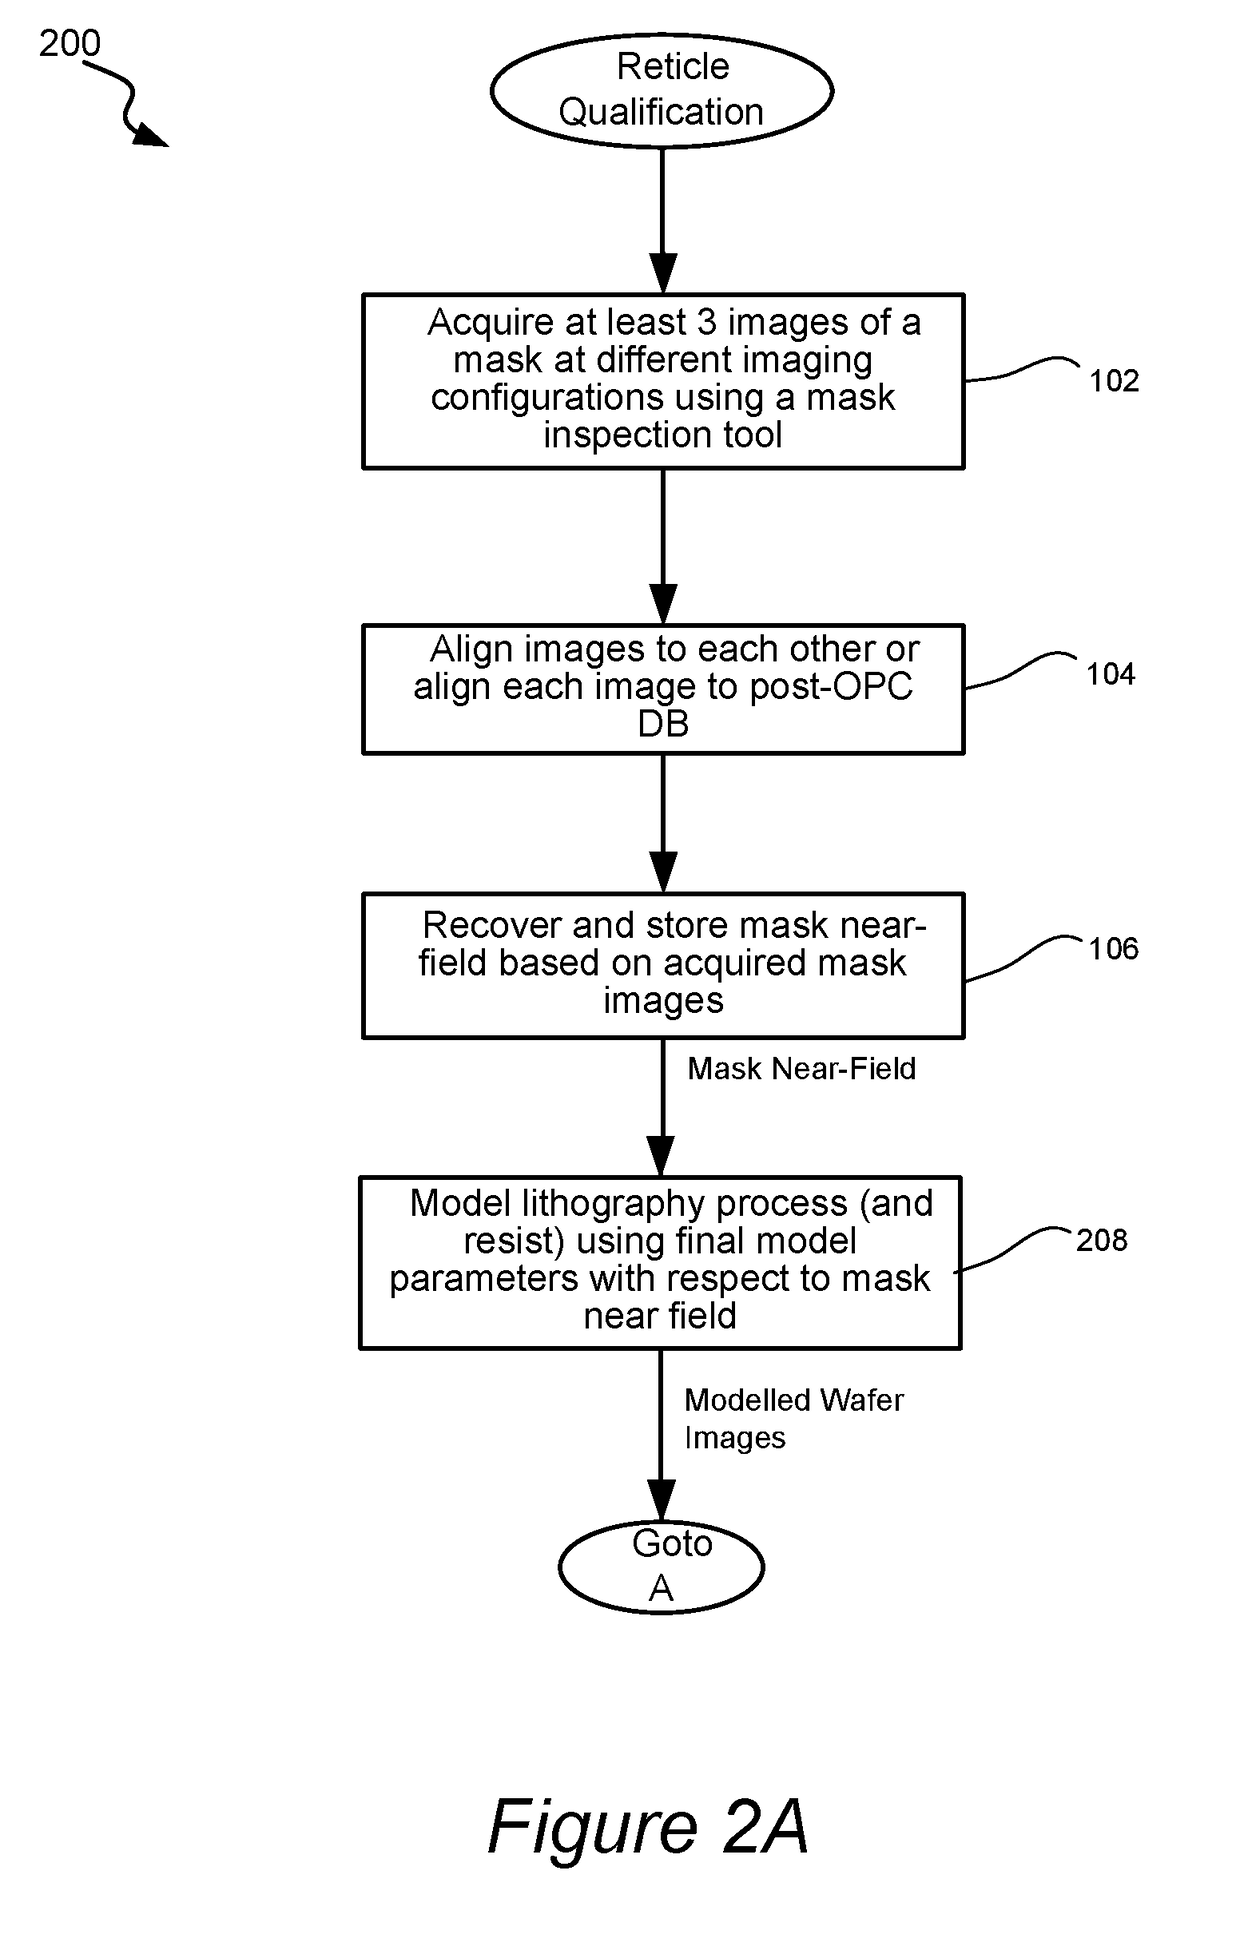
Disclosed are methods and apparatus for qualifying a photolithographic reticle. A reticle inspection tool is used to acquire images at different imaging configurations from each of a plurality of pattern areas of a test reticle. A reticle near field for each of the pattern areas of the test reticle is recovered based on the acquired images from each pattern area of the test reticle. A lithography model is applied to the reticle near field for the test reticle to simulate a plurality of test wafer images, and the simulated test wafer images are analyzed to determine whether the test reticle will likely result in an unstable or defective wafer.
Owner:KLA TENCOR CORP
Multi-modal medical image data intelligent processing system
The invention discloses a multi-modal medical image data intelligent processing system, relates to the field of medical image analysis, and is applied to multi-modal medical image whole-process analysis of CT, MRI, PET, ultrasound and the like. According to the system, different modal image features are extracted and fused through a cross-modal manifold fusion network; a semantic guidance dynamic registration engine optimizes registration parameters to ensure that the registration error is less than or equal to 1.5 mm; the multi-task collaborative diagnosis network realizes multiple tasks such as disease classification; the clinical knowledge embedding and interpretable module generates a structured report and is in butt joint with an HIS system. Meanwhile, the model is optimized through a federated learning architecture, the adaptability of newly added data is improved by more than or equal to 20%, and intelligent processing and analysis of multi-modal medical images are realized.

Owner:SHANDONG JUNKANGLIN MEDICAL TECHNOLOGY CO LTD
Classification of Image Data from Synthetic Aperture Radar Images and Electro-Optical Images with Multi-Modal Fusion
Systems and methods are disclosed for classifying objects using electro-optical and synthetic aperture radar images through multi-modal feature alignment and fusion. A computing system acquires and preprocesses image data, then aligns features across modalities using a multi-modal alignment engine. A cross-modal attention fusion network extracts and integrates complementary information using transformer-based attention mechanisms. A modality-specific feature extraction framework processes EO and SAR images through specialized branches, ensuring optimal feature representation. An adaptive fusion decision system dynamically determines the best fusion strategy based on image quality and confidence scores. A self-supervised consistency controller enforces alignment between EO and SAR features using contrastive learning. The fused representations are processed by a neural network to generate object classifications. This system improves accuracy and robustness in environments where one modality may be degraded or missing, enhancing applications such as remote sensing, surveillance, and autonomous navigation.

Owner:ATOMBEAM TECH INC
Apparatus for automatically setting measurement reference element and measuring geometric feature of image
InactiveUS20020057828A1automatic measurement of the geometric feature of the object image can be efficientlyefficient measurementImage enhancementImage analysisReference imageImaging data
In a measurement processing apparatus for measuring a geometric feature of an object image: a measurement-reference-element setting unit automatically sets at least one first measurement reference element for use in measurement of the geometric feature of the object image, at at least one first position on the object image based on first image data representing the object image and position information indicating at least one second position of at least one second measurement reference element which is set on a measurement reference image corresponding to the object image; and a geometric-feature measurement unit measures the geometric feature of the object image based on the at least one first position of the at least one first measurement reference element.
Owner:FUJIFILM CORP
Deep learning-based tiny target defect identification model training method
The invention discloses a deep learning-based small target defect recognition model training method, relates to the technical field of defect recognition model training, and aims at meeting small defect detection requirements, starting with high-resolution diversified data construction and accurate labeling, highlighting weak targets through multi-scale feature fusion and spatial attention, and realizing high-resolution target defect recognition. A hard case scene is processed in cooperation with layer-by-layer screening and secondary intensified training, real-time iterative optimization is achieved through multi-model fusion and online dynamic adjustment and optimization, finally, multi-mode and time sequence dimensions are expanded to capture deeper and dynamic defect information, the missing detection and false detection rate is greatly reduced, and the detection efficiency is improved. The detection efficiency and adaptability of micron-sized defects under a complex process background are improved; furthermore, by means of multi-source data such as infrared, X-ray or 3D morphology and a time sequence modeling means, multiple dimensions are fused, and hidden or early cracks are brought into a detection and prediction range, so that a high-reliability and evolvable intelligent recognition system for the tiny target defects is constructed.

Owner:TONGJI UNIV
PCBA board defect detection method and system based on image processing
The invention relates to the technical field of image detection, in particular to a PCBA board defect detection method and system based on image processing, and the method comprises the following steps: carrying out the meshing calculation of a gray scale deviation after a gray scale image is subjected to Gaussian filtering denoising, generating change rate data, carrying out the statistics of a frequency number, constructing a histogram, combining with an Otsu algorithm, and generating a candidate mask; extracting pixels based on a mask, calculating a gradient modulus, screening edge candidate points, carrying out gradient direction connection and morphological processing to generate a complete edge structure, expanding a connected domain through a region growing algorithm, aligning the connected domain with a template contour, and outputting defect coordinates. According to the method, the defect identification sensitivity is improved through combination of gray level image gridding processing and dynamic threshold calculation, a candidate mask is generated through grid gray level change rate statistics and an Otsu algorithm to avoid over-segmentation missing detection, and the contour precision is improved through combination of gradient modulus difference screening and morphological closed operation optimization. The region growing algorithm and template dynamic alignment reduce deformation misjudgment, and staged dimension reduction and feature enhancement reduce calculation complexity and solve resource waste.

Owner:广东德智矩阵科技有限公司
Three-dimensional Gaussian sputtering scene reconstruction method based on structure perception refined Gaussian
The invention discloses a three-dimensional Gaussian sputtering scene reconstruction method based on structure perception refined Gaussian, and aims to solve the problems of Gaussian drift, edge blur, structure artifacts and the like of a reconstruction model due to the fact that sparse point cloud contains outliers, Gaussian morphology and normal are mismatched and a multi-dimensional optimization target is lacked in an existing three-dimensional Gaussian sputtering reconstruction method. A key frame is extracted by collecting target scene video data, sparse three-dimensional point clouds are reconstructed by using an SfM algorithm, a depth map and a normal map are generated through a Lotus model, three-dimensional Gaussian distribution is initialized after the sparse point clouds are filtered, a Gaussian covariance matrix is adjusted by using a normal consistency regular term, and the sparse point clouds are extracted. And after structure attribute analysis is carried out, a comprehensive scoring function is constructed to screen Gaussian points, and finally, a combined training framework including luminosity, normal consistency and structure continuity loss is adopted to optimize and generate a three-dimensional Gaussian scene model. The method is mainly applied to the field of three-dimensional reconstruction and multi-view rendering, and scene reconstruction precision and geometric consistency can be improved.

Owner:GUILIN UNIVERSITY OF TECHNOLOGY
Rapid point cloud data processing system based on 3D vision
The invention discloses a point cloud data rapid processing system based on 3D vision, and relates to the technical field of point cloud data processing. The binocular acquisition module generates an anti-interference high-precision point cloud; the preprocessing module is used for reducing noise and dimensionality and retaining key geometric features; the hierarchical feature extraction module fuses curvature weight and a non-maximum suppression strategy, and improves the robustness of an ORB algorithm in rotation, scale and noise scenes; the industrial scene segmentation module accurately separates stacked objects through normal vector clustering and a dynamic region growing algorithm, and secondarily verifies boundaries in combination with a lightweight semantic model; the two-stage registration module dynamically adjusts a threshold value based on error feedback to realize pose optimization from coarse registration to fine registration; the coordinate mapping module establishes a space mapping model through multi-attitude calibration and robot multi-axis linkage trajectory optimization. The problem that in the prior art, a 3D machine vision algorithm is high in time delay is solved, the real-time performance and rapidity of 3D model recognition and feature extraction are improved, and the efficiency requirement of industrial production is met.

Owner:GUANGXI TECHCAL COLLEGE OF MACHINERY & ELECTRICITY
Visual image-based welding seam defect detection method
The invention belongs to the technical field of welding quality detection, and particularly relates to a visual image-based welding seam defect detection method, which comprises the steps of image acquisition, image preprocessing, data analysis, data output, defect classification and decision making, system closed-loop optimization and the like. According to the method, by synchronously collecting two-dimensional images, three-dimensional shapes and heat distribution data of metal welding seams and adopting a polarization filter and annular LED light source combination scheme, multi-dimensional conjoint analysis of physical defects and thermodynamic characteristics is achieved, basic characteristic data are extracted through primary processing, quantifiable defect coefficient indexes are generated through secondary processing, and the detection accuracy is improved. And finally, generating a comprehensive defect index through a multi-modal fusion algorithm, constructing a well-arranged intelligent analysis decision chain, and establishing a self-evolution mechanism of data acquisition-analysis decision-model iteration through real-time interaction of a detection result and an algorithm model. The system can continuously optimize the detection threshold value and the characteristic weight parameter according to the actual working condition of the production line, and the continuous improvement of the detection sensitivity is kept.

Owner:JINING LIANWEI WHEEL MFG CO LTD
Vehicle multi-modal trajectory prediction method based on improved attention network
The invention discloses a vehicle multi-modal trajectory prediction method based on an improved attention network, and belongs to the technical field of intelligent vehicle trajectory prediction, and the method comprises the steps: collecting historical trajectory data of a target vehicle and surrounding vehicles as an input sequence; secondly, constructing a vehicle multi-modal trajectory prediction model which comprises a motion feature extraction module, a space-time interaction module, a space-time fusion module and a trajectory output module; the motion feature extraction module uses a multi-scale convolution attention network and a gating circulation unit for processing, the space-time interaction module uses a dynamic graph attention network for extracting vehicle interaction information, and the space-time fusion module splices and fuses target vehicle motion features and space-time interaction features to obtain space-time fusion features; the track output module inputs the fusion features into a gating circulation unit, decodes the fusion features and then inputs the fusion features into a mixed density network, and multi-mode output of vehicle tracks is achieved; and finally, a proper loss function is selected for training, so that the prediction precision and the convergence speed of the model are improved.

Owner:SHANDONG UNIV OF SCI & TECH
Backlight effect image edge enhancement method based on intelligent identification
The invention relates to the technical field of image processing, and discloses a backlight effect image edge enhancement method based on intelligent identification, which comprises the following steps of: judging a field environment type; performing global optimization on the original image based on a set environment perception type enhancement mechanism according to the judged field environment type, and outputting a global pre-processing image; constructing a backlight area segmentation model for the globally preprocessed image; outputting a local enhanced image; designing a structure perception type local adaptive threshold algorithm for the local enhanced image, and outputting a binary image keeping structural continuity; extracting an edge image of the binarized image through an edge detection algorithm, and optimizing a topological structure of a contour in the binarized image; and comparing with a wood template processing standard feature library, outputting an edge quality evaluation result and feeding back to a processing control system. Defect detection and machining control depth linkage is achieved, passive detection is changed into active optimization, and the production efficiency and the yield are improved.


Owner:四川省建筑机械化工程有限公司
IMU (Inertial Measurement Unit)-assisted deep SLAM (Simultaneous Localization and Mapping) method and system fusing language-vision multi-mode perception
The invention provides an IMU (inertial measurement unit)-assisted depth SLAM (simultaneous localization and mapping) method and system fusing language-vision multi-mode perception, and the system comprises functional modules such as initial calibration and semantic map initialization, pre-integration prediction and key frame judgment, dense point cloud reconstruction and relative pose estimation, semantic embedding extraction, semantic guidance loopback detection and semantic three-dimensional map incremental updating. IMU motion priori, depth geometric constraint and language model semantic factors are subjected to combined modeling through a graph optimization framework, and high-precision positioning and labeled map construction in a complex dynamic environment are achieved. Compared with the prior art which only depends on geometric or inertial information, the method has the advantages that the loop-back mismatching rate is reduced, the closed-loop convergence efficiency and the long-time relocation robustness are improved, and a semantic interface is provided for upper-layer tasks such as natural language navigation and target retrieval. The method can be widely applied to the fields of service robots, security inspection, intelligent driving, post-disaster search and rescue and the like.

Owner:XIAN TECH UNIV