
Patents
Literature
613results about How to "Reduce overhead" patented technology
Efficacy Topic
Property
Owner
Technical Advancement
Application Domain
Technology Topic
Technology Field Word
Patent Country/Region
Patent Type
Patent Status
Application Year
Inventor
System and Method for Utilizing Available Best Effort Hardware Mechanisms for Supporting Transactional Memory
ActiveUS20090282386A1Reduce difficultyReduce overheadSpecific program execution arrangementsMemory systemsTransactional memoryApplication software
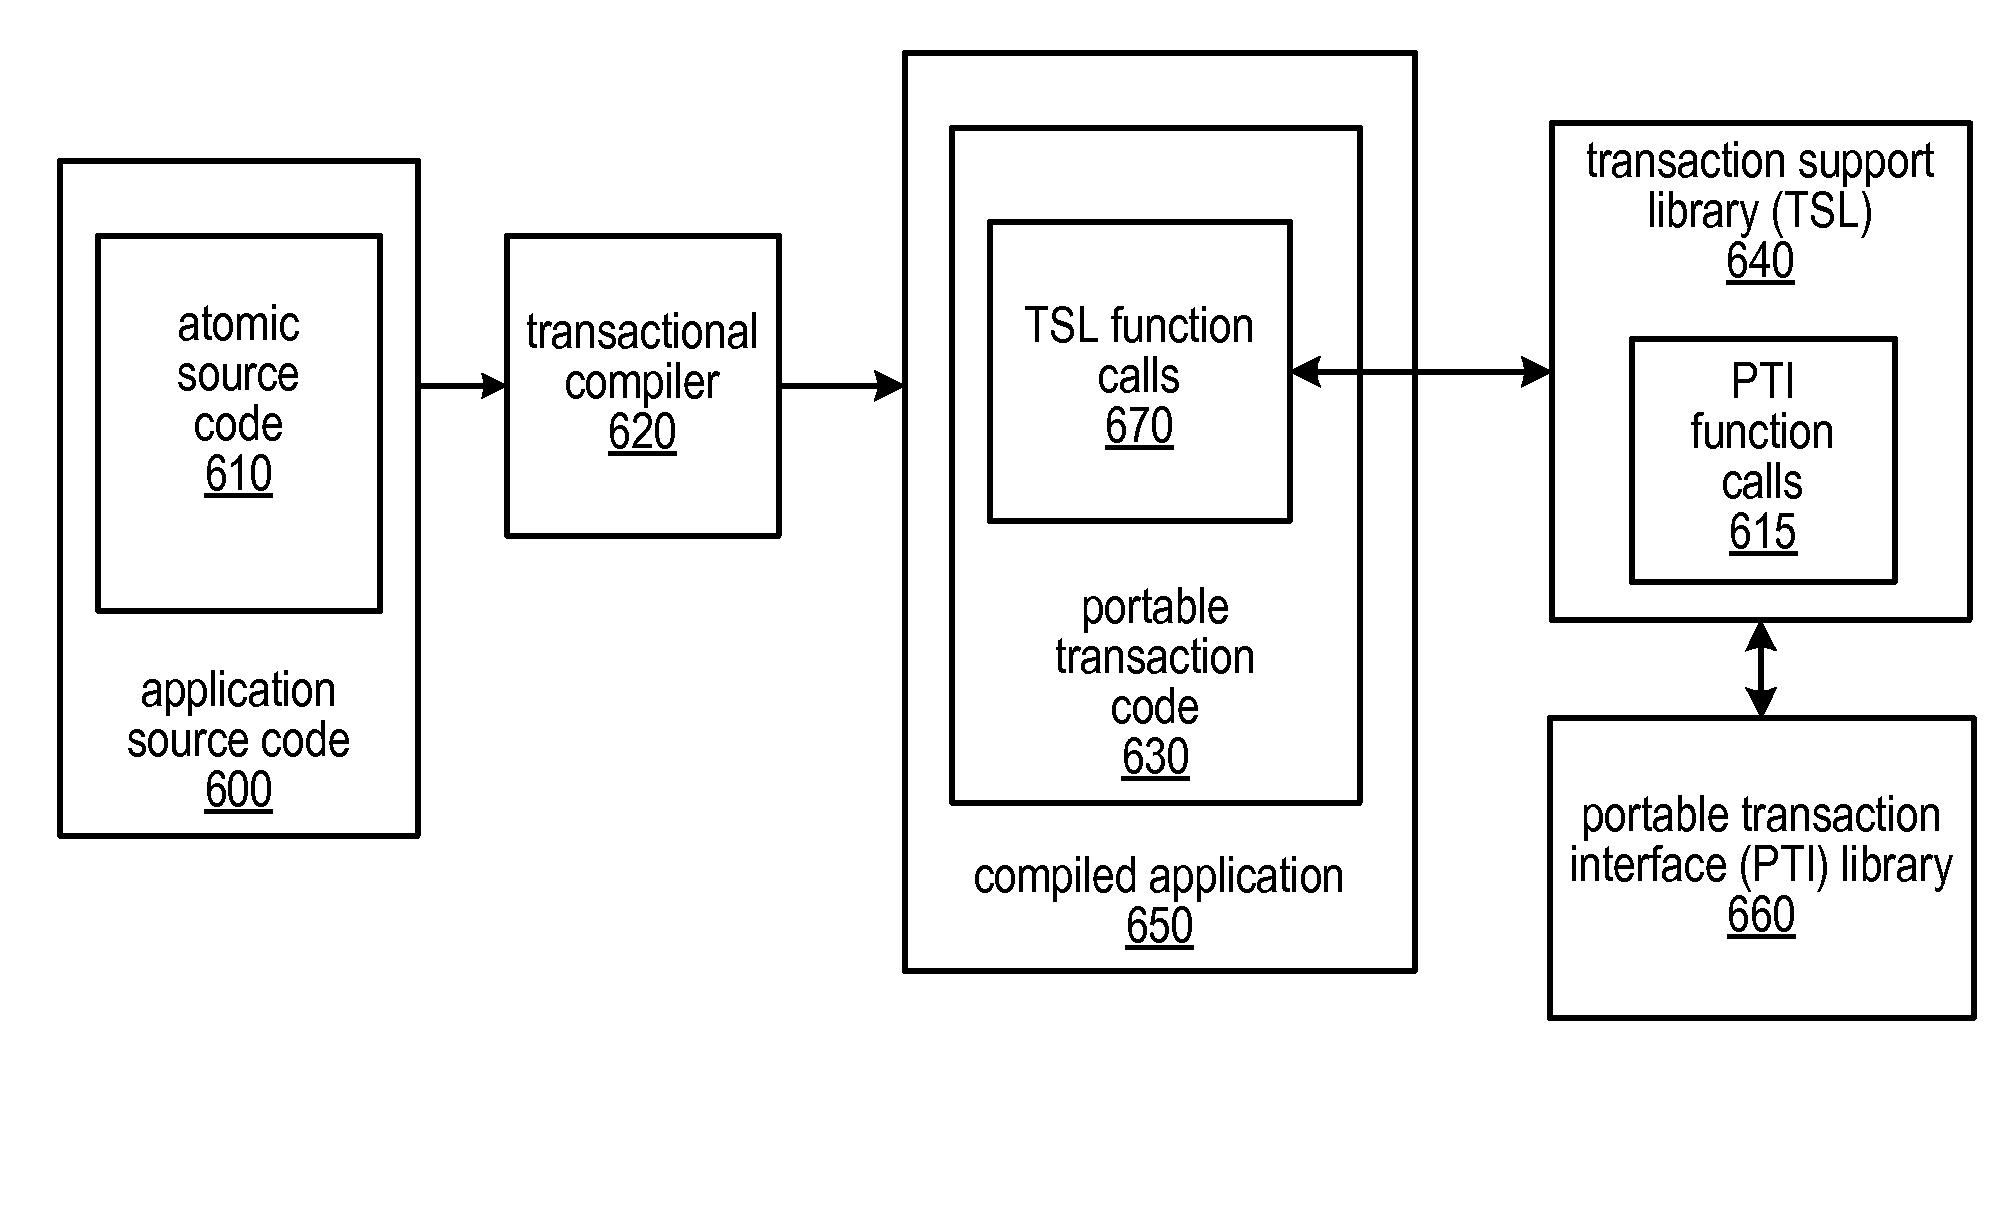
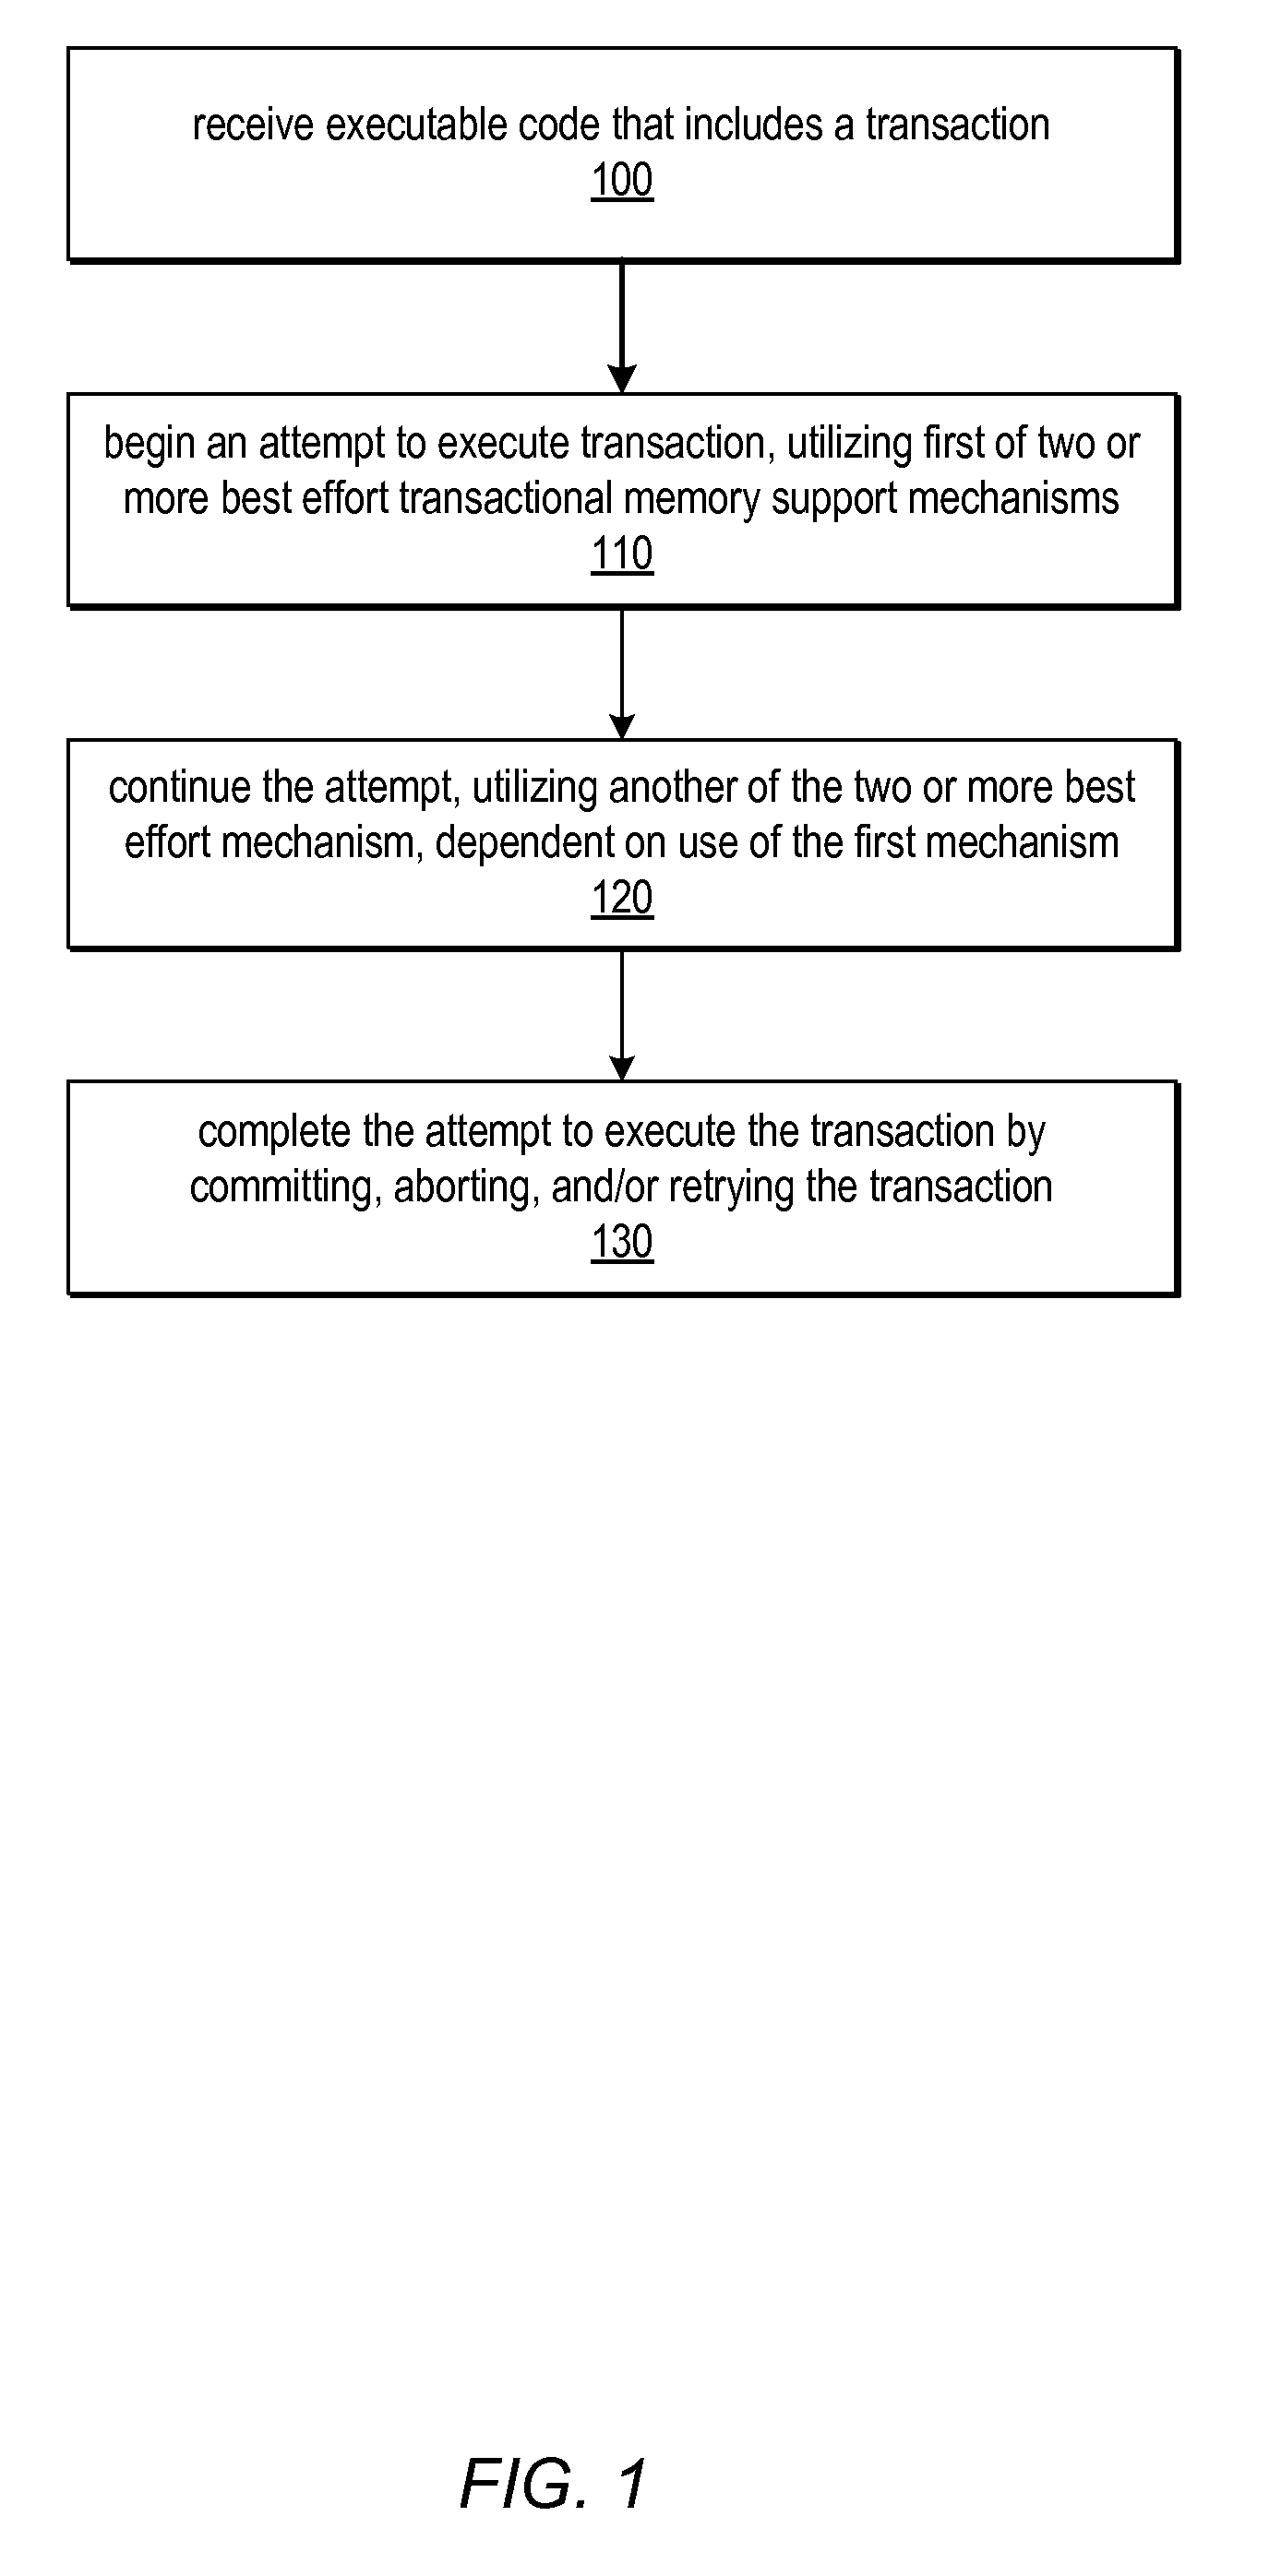
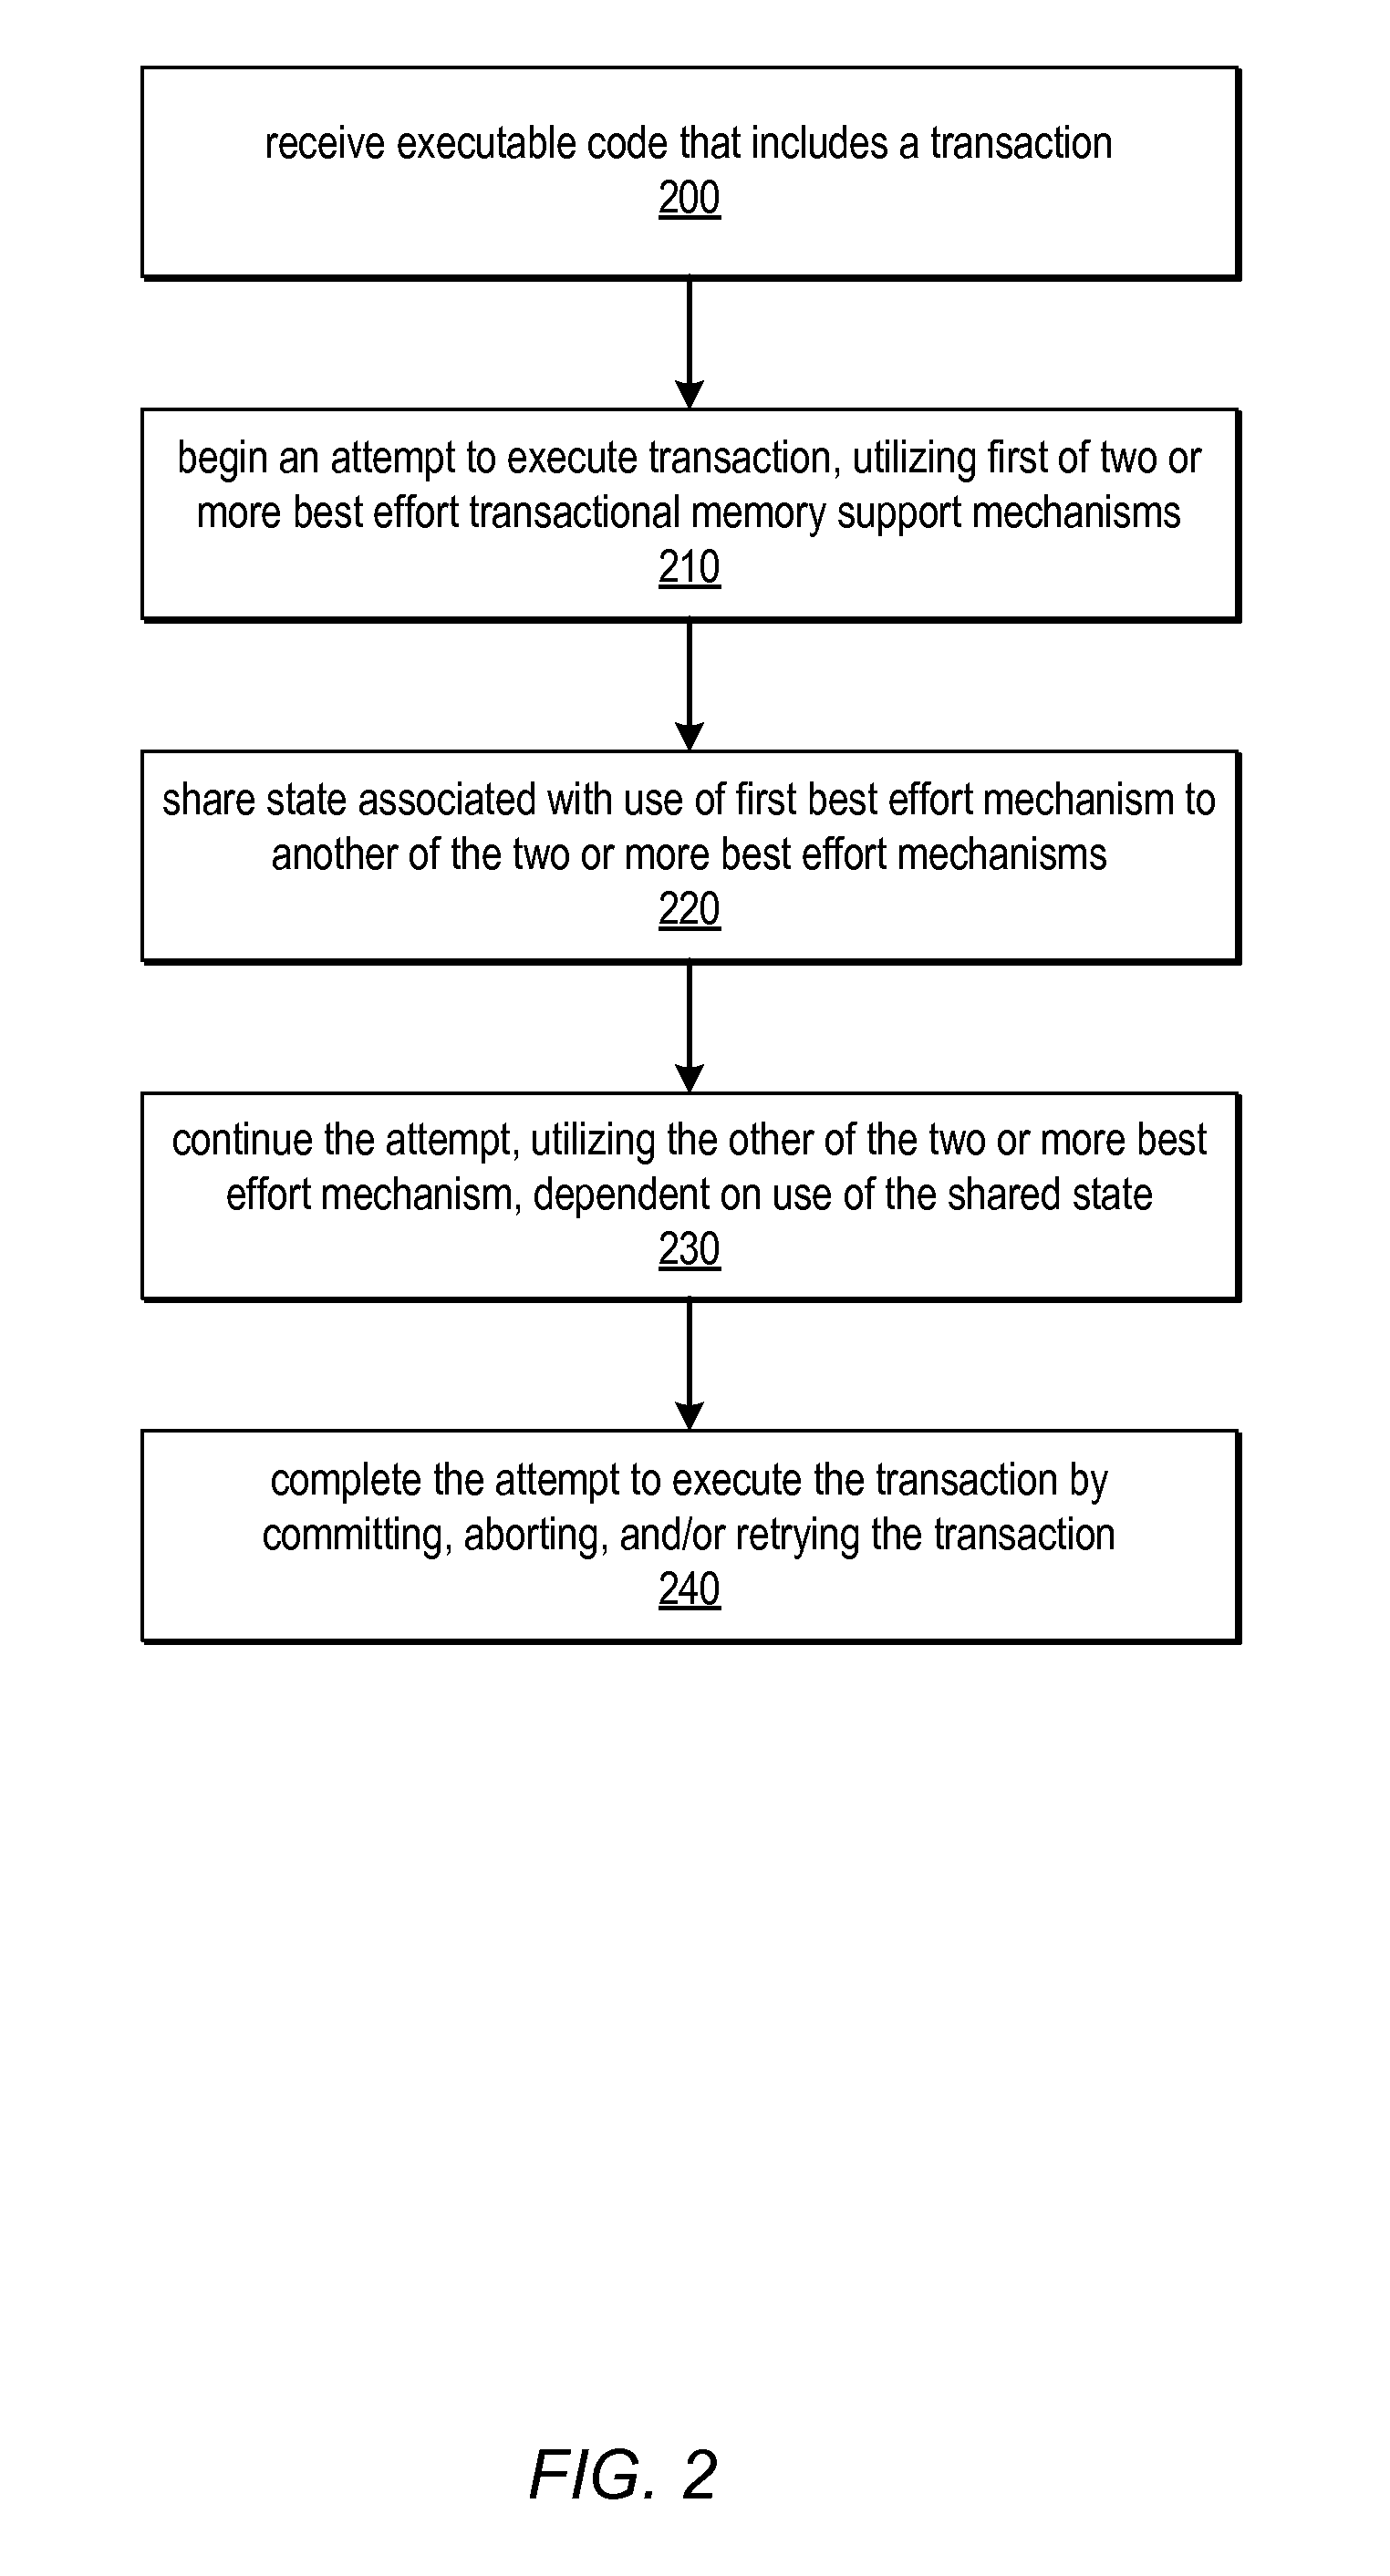
Systems and methods for managing divergence of best effort transactional support mechanisms in various transactional memory implementations using a portable transaction interface are described. This interface may be implemented by various combinations of best effort hardware features, including none at all. Because the features offered by this interface may be best effort, a default (e.g., software) implementation may always be possible without the need for special hardware support. Software may be written to the interface, and may be executable on a variety of platforms, taking advantage of best effort hardware features included on each one, while not depending on any particular mechanism. Multiple implementations of each operation defined by the interface may be included in one or more portable transaction interface libraries. Systems and / or application software may be written as platform-independent and / or portable, and may call functions of these libraries to implement the operations for a targeted execution environment.
Owner:ORACLE INT CORP
Block chain database data management system for traceability application
PendingCN121958236AImplement forced bindingOptimize physical distributionDatabase distribution/replicationDigital data protectionPathPingTamper resistance
The invention discloses a traceability application-oriented block chain database data management system, particularly relates to the technical field of block chain database data management, and is used for solving the problems of easy data tampering and low verification efficiency caused by traceability data logic association and physical storage splitting. The method comprises the following steps: firstly, matching a parent physical sector offset through an association analysis module, determining a storage partition, and assembling a write-in instruction; then, a topology binding module executes a disk write operation, synchronously reads parent node hash and performs combinatorial operation in combination with a physical address to generate a topology binding check value bound with the physical position; the aggregation anchoring module uses a Merkel tree aggregation check value to generate a root fingerprint and perform uplink, and establishes an anchoring voucher; and finally, a path verification module positions a physical position according to the certificate, executes reverse recursive addressing and step-by-step Hash recalculation, and assembles a pedigree verification packet, so that a closed-loop trust system from physical storage to chain certificate storage is constructed, and the tamper-proof capability and verification efficiency of the traceability data are improved.

Owner:NANCHANG FEYNMAN SMART TECH CO LTD
Key value storage system indexing method oriented to NVM-NVMe SSD hybrid architecture
PendingCN121807220AEfficient identificationPrevent mixed storageInput/output to record carriersComputer architectureHigh availability
The invention discloses a key value storage system indexing method oriented to an NVM-NVMe SSD (Non-Volatile Memory-Non-Volatile Memory Express Solid State Disk) hybrid architecture, which comprises the following steps of: constructing a heterogeneous storage architecture taking cold and hot data perception as a core driving mechanism, coordinating and managing two types of storage media, namely a non-volatile memory NVM and a solid state disk NVMe SSD, and realizing efficient identification, layered writing and dynamic migration of cold and hot data. According to the method, the characteristics of low delay, durability and byte addressing of the NVM are utilized, the frequency and I / O overhead of Flush and Compaction operations are reduced in a data write-in path, meanwhile, the problem of mixed storage of cold and hot data is avoided, and therefore the overall performance and storage efficiency of a system are remarkably improved. In addition, by introducing an asynchronous migration module, the method can dynamically adapt to the change of data popularity along with time evolution, and effectively support high performance and high availability of the key value system in long-term operation.

Owner:ANHUI UNIV
Electric power marketing business abnormity real-time detection method and system based on stream-oriented computing
PendingCN121997220Aimprove accuracyImprove recallData processing applicationsInterprogram communicationBatch processingElectric power system
The invention relates to an electric power marketing business abnormity real-time detection method and system based on stream-oriented computation, and belongs to the technical field of electric power system optimizing.The method comprises the steps that data snapshots are extracted from an electric power marketing business system, difference comparison is conducted on the data snapshots and historical snapshots of an intermediate library, and standardized increment events are generated and stored; capturing an incremental event in real time through a data change capturing tool and pushing the incremental event to a message queue; a streaming computation engine consumes the event stream, sequentially performs data cleaning, association with a static dimension table and sliding window statistical feature calculation, and constructs a feature vector; and performing parallel analysis and weighted fusion on the feature vectors based on a business rule base and an online machine learning model to generate a comprehensive risk score, and outputting an abnormal event when the score exceeds a threshold value. According to the method, the problems of exception identification lagging and complex work order process in a traditional batch processing mode are solved, the crossing of the business risk from hour-level detection to minute-level real-time perception is realized, and the timeliness and accuracy of power marketing risk management and control are improved.

Owner:FUJIAN ELECTRIC POWER CO LTD XIAMEN ELECTRIC POWER SUPPLY CO +1
Anaphora disambiguation method and system based on big language model enhanced text and structured query language generation
PendingCN121958307AResolve field value matching deviationImprove matching accuracyDigital data information retrievalSemantic analysisTable (database)Linguistic model
The invention discloses an anaphora disambiguation method and system based on big language model enhanced text and structured query language generation. The method comprises the following steps: receiving a natural language question of a user, and analyzing and generating structured table field information through mode information; identifying and rewriting fuzzy time expression in the problem; extracting ambiguous entities, and replacing the ambiguous entities with database standard values through semantic matching and fuzzy matching; synthesizing the information to generate a structured query language statement and executing the structured query language statement; and if the execution result is null, automatically triggering an anaphora disambiguation process, performing error correction and re-matching on field values in the statement through a dual matching mechanism, and generating and executing a corrected query statement. According to the method, the problems of fuzzy anaphora, indefinite time expression, low matching accuracy, resource waste and the like in a traditional SQL system are effectively solved through a strategy of combining pre-processing and post-processing, and the accuracy, robustness and execution efficiency of complex query are remarkably improved.

Owner:CHINA TELECOM DIGITAL INTELLIGENCE TECH CO LTD
Branch prediction unit power consumption management method and device
PendingCN121996051Areduce overheadGet rid of dependenceDigital data processing detailsConcurrent instruction executionLow power dissipationMicroarchitecture
The invention discloses a branch prediction unit power consumption management method and device, and the method comprises the steps: setting a multi-stage branch predictor and a low-power-consumption control logic coupled with the multi-stage branch predictor in a processor core micro-architecture, and enabling the multi-stage branch predictor to comprise three stages of predictors which are sequentially accessed in an assembly line, the hardware resource consumption and the prediction accuracy of each predictor are gradually increased from front to back; monitoring the prediction condition of each predictor in real time through low-power-consumption control logic, and closing all predictors behind the first predictor meeting the prediction requirement within a first preset time according to a front-to-back sequence; branch jump addresses are divided into high-order address fields and low-order address fields by BTBs in the multiple levels of predictors except the first-level predictor to be stored in different storage blocks, and label registers used for taking the high-order addresses as label indexes are arranged. The power consumption unit of each predictor can be finely controlled, the energy consumption is greatly reduced, system-level cooperation is not needed, and the universality is high.

Owner:NANJING YINGQI INTELLIGENT TECH CO LTD
Multi-layer memory management method and device, storage medium and electronic equipment
ActiveCN121957911AReduce the number of updatesreduce overheadResource allocationData packAccess frequency
The invention discloses a multi-layer memory management method and device, a storage medium and electronic equipment, and relates to the technical field of memory management, and the method comprises the steps that a prediction frequency set of storage equipment is obtained through prediction by using a reference information set corresponding to the storage equipment, and the storage equipment comprises a first memory and a second memory; the first delay of the first memory is smaller than the second delay of the second memory; determining a plurality of target sub-data contained in the target data of the storage device, and determining predicted access frequencies corresponding to the plurality of target sub-data based on the predicted frequency set; under the condition that the predicted access frequencies corresponding to the multiple pieces of target sub-data meet a preset splitting condition, splitting the target data into multiple pieces of target sub-data; and storing the target sub-data with the predicted access frequency greater than the frequency threshold in the first memory, and storing the target sub-data with the predicted access frequency less than the frequency threshold in the second memory. The technical problem that a memory management method in the related technology is low in resource utilization rate is solved.

Owner:JINAN INSPUR DATA TECH CO LTD
MoE expert deployment system and method based on wafer-level chip
ActiveCN121981181Areduce overheadImprove utilization efficiencyConstraint-based CADPhysical realisationEngineeringArtificial intelligence
The invention discloses an MoE expert deployment system and method based on a wafer-level chip, and the system comprises a statistical module which is used for carrying out the statistics of expert co-activation probability distribution reflecting the cross-layer cooperative activation relation between experts in MoE and the communication demands of a calculation core on the wafer-level chip; and the clustering module is used for performing clustering based on the expert co-activation probability distribution and communication requirements by taking the minimization of communication traffic across physical regions and the minimization of intra-group communication load difference of expert groups borne by the physical regions as targets to obtain an expert grouping scheme of MoE and a physical region layout mapping scheme corresponding to wafer-level chips. According to the method, clustering can be carried out according to the cross-layer co-occurrence rule of the experts, and the experts subjected to high-frequency cooperative activation are constrained in the same physical region, so that a large amount of global communication is converted into local exchange, and the overhead of long-distance and high-delay cross-region communication is remarkably reduced. Meanwhile, load distribution is optimized in combination with communication requirements, and local hotspots are effectively avoided.

Owner:BEIJING TSINGMICRO INTELLIGENT TECH CO LTD
Universal method for realizing multiple conditions and search based on LDAP (Lightweight Directory Access Point)
PendingCN121958347AReduce revision frequencylower the thresholdDatabase distribution/replicationSpecial data processing applicationsProgramming languageData retrieval
The invention provides a universal method for realizing multi-condition and search based on LDAP, and belongs to the technical field of data retrieval of directory service and identity management. A user defines query conditions including attributes, values and logical relationships through a configuration file, a visual interface or an interface; the system parses the query condition model into a query condition model supporting nested combination of AND, OR and NOT by using a parser, and performs legality check and error prompt; and then a generator dynamically generates a filtering statement conforming to the LDAP grammar specification according to the model, and query is executed through an LDAP client. In order to improve the performance, common condition caching and high-frequency statement pre-compiling optimization are introduced, and an asynchronous query mode is supported. And the query result is returned in the form of structured data, and is matched with a display interface to support screening, sorting and exporting, so that the flexibility and maintainability of multi-condition query are improved.

Owner:UNICLOUD TECH CO LTD
Data forwarding method based on vehicle-mounted passive optical network and related device
ActiveCN121940674Areduce overheadImprove bandwidth utilizationMultiplex system selection arrangementsBus networksIn vehicleEngineering
The invention provides a data forwarding method based on a vehicle-mounted passive optical network and a related device, and relates to the technical field of vehicle communication. In the data forwarding method, the first ONU gateway aggregates and packages the received multiple frames of messages into the same uplink GEM frame, so that the multiple frames of messages share the same GEM frame header, the frame header overhead in the low-speed data transmission process is effectively reduced, and the bandwidth utilization rate of the vehicle-mounted PON network is improved. Meanwhile, message grouping, uplink GEM frame packaging and uplink burst frame coding are directly completed through the first ONU gateway, the uplink burst frame is sent to the OLT, time delay and system resource consumption are reduced, the high real-time requirement of low-speed data (such as a sensor and a control signaling) in a vehicle-mounted scene is met, and therefore efficient and low-delay bearing of the low-speed data on a vehicle-mounted PON network is achieved.

Owner:CHONGQING CHANGAN AUTOMOBILE CO LTD
Operating system IO processing method supporting random IO merging, operating system and storage system
PendingCN121785542AReduce individual processingreduce occupancyInput/output to record carriersProgram controlComputer hardwareOperational system
The invention discloses an operating system IO processing method supporting random IO merging, an operating system and a storage system, and belongs to the field of computer operating systems. The method comprises the steps that in a user mode, only one parameter copy is reserved for the same parameters of a plurality of random IO requests and recorded in a shared structure A, respectively recording different parameters of each random IO request into the shared structure body B to obtain a pseudo sequence request; the pseudo-sequence requests are issued to a system kernel, corresponding operations are executed on the pseudo-sequence requests in all layers of the system kernel in sequence, the batch operations are only executed once, and the non-batch operations are executed once for all the random IO requests respectively; the batch operation and the non-batch operation are operations executed for parameters in the shared structure body A and the shared structure body B respectively; and splitting the pseudo sequence request into random IO requests in an equipment driving layer of the kernel system, generating a corresponding equipment command, and submitting the equipment command to storage equipment. According to the invention, kernel overhead under the condition of high throughput can be relieved, so that the throughput is improved.

Owner:HUAZHONG UNIV OF SCI & TECH
High-visibility stream-by-stream data packet sampling method and system based on priority
The invention relates to a priority-based high-visibility stream-by-stream data packet sampling method and system. Comprising the following steps: step 1, flow initiation and priority marking; step 2, flow establishment and controller decision making; step 3, rule issuing and strategy execution; and step 4, data forwarding, scheduling and sampling: a priority scheduling mechanism of a data plane and global optimization of a control plane are decoupled and coordinated. In a data plane, a terminal host marks a degradation priority for a data packet according to the number of bytes sent by a stream, and a switch performs strict queue scheduling and probability sampling based on the priority. In a control plane, a controller carries out collaborative modeling on the configuration of routing, sampling probability and degradation threshold as a nonlinear optimization problem with maximization of sampling utility as a target, and an efficient online primitive-dual interior point method is adopted for solving. According to the method, high visibility and load balancing are finally ensured, and meanwhile, the control and calculation overhead is remarkably reduced.

Owner:QILU UNIVERSITY OF TECHNOLOGY (SHANDONG ACADEMY OF SCIENCES) +2
Random noise-driven post-processing federal long-tail classifier calibration method and device
PendingCN121861379ACorrect weight biaseasy to identifyCharacter and pattern recognitionDigital data protectionFeature extractionTest sample
The invention provides a post-processing federated long-tail classifier calibration method and device based on random noise driving, and the method comprises the steps: carrying out the multi-round federated learning training between a central server and a plurality of clients, and carrying out the aggregation to obtain a pre-training global model comprising a feature extractor and a classifier; at the central server side, freezing the feature extractor, and constructing a virtual balance data set based on random noise sampling and uniform label sampling; optimizing parameters of the classifier by using the virtual balance data set and a calibration loss function to obtain a calibrated classifier; and for a to-be-classified test sample, predicting the to-be-classified test sample by using the feature extractor of the central server side and the calibrated classifier. The method is applied to an image classification task in federated learning, classifier deviation caused by long-tail distribution can be effectively calibrated under the conditions that data privacy is completely protected and no auxiliary information is needed, and the recognition performance and the overall prediction calibration degree of the model on the tail category are remarkably improved.

Owner:JILIN UNIVERSITY
An AR-based video label dynamic superimposition anti-shake method and system
PendingCN122293995AImprove visual stabilityImprove Mapping AccuracyComputer graphics (images)Superimposition
This invention discloses a video tag dynamic overlay anti-shake method and system based on AR, comprising: acquiring real-time video stream and device pose parameters at corresponding timestamps; constructing a dynamic perspective projection model based on the device pose parameters and calculating the initial pixel coordinates of the target AR tag in the current video frame; planning a local feature search window based on the initial pixel coordinates; calculating the average pixel displacement vector of image feature points in the local feature search window of the current and adjacent historical video frames; performing reverse displacement compensation on the average pixel displacement vector to obtain the target rendering coordinates, and rendering the target AR tag to the current video frame based on the target rendering coordinates. Compared with the prior art, this invention can overcome the shortcomings of large drift errors caused by simply relying on mechanical pose, high computational power consumption caused by global matching, and high-frequency jitter of tags caused by slight device vibrations, thereby improving tag mapping accuracy, reducing system computational power consumption, and improving the visual stability of video overlay.

Owner:广西信安锐达科技有限公司
A circuit and method for long sequence data sorting
ActiveCN115268830BStable linear order time complexityspeed efficientRegister arrangementsData sortingComputer hardwareParallel computing
The application discloses a circuit and method for long sequence data sorting. The circuit is used for sorting N data in K base, and the maximum element in the data contains m bits in K base. The circuit comprises a radix counting unit, a first address generating unit, a data distribution unit and two sorting buffers. The two sorting buffers are used as a source buffer and a target buffer respectively, and can read data in a given address or write a data into a specified address. The radix counting unit, the first address generating unit and the data distribution unit are connected in sequence. The two sorting buffers are connected with the data distribution unit and the radix counting unit respectively. The data sorting circuit of the application has simple structure, can be flexibly adjusted according to specific requirements, and the data sorting method has linear order time complexity and short sorting time.

Owner:NANJING UNIV
A database log archiving method, device, equipment and medium
This invention relates to the field of data processing and discloses a database log archiving method, apparatus, device, and medium, comprising: identifying a target redo log file to be archived from the database; creating a preliminary redo log file with the same attributes as the target redo log file and empty content within the same logical disk as the target redo log file; moving the target redo log file to a preset archiving directory located within the same logical disk via MV operations; changing the filename and storage path of the preliminary redo log file to the original filename and storage path of the target redo log file via MV operations; and mounting the revised preliminary redo log file to the database. This invention solves the problems of high I / O consumption and low archiving efficiency in existing database log archiving technologies.

Owner:SHENZHEN INST OF COMPUTING SCI
An open unmanned vehicle navigation control software architecture implementation method
ActiveCN115755974BStable internal performanceImprove the development effectVehicle position/course/altitude controlPosition/direction controlMessage deliverySoftware architecture
The present application relates to the technical field of unmanned aerial vehicle software architecture, and particularly relates to an open unmanned vehicle navigation control software architecture implementation method, which comprises a functional node group, a node manager, a message transmission manager, a parameter server and a control algorithm library. The functional node group is a cluster of several independent functional nodes, the architecture unifies the external interface function form of each node and is uniformly managed by the node manager; the message manager is a low-overhead high-real-time message transmission mode used for message interaction between nodes; the software architecture is built-in with a parameter server capable of realizing parameter registration, storage and reading functions; meanwhile, some commonly used control algorithm libraries are configured for use by each node. The unmanned vehicle navigation control software architecture has the characteristics of low hardware overhead, high real-time performance, good scalability, supports multi-person collaborative development and can effectively reduce the software development threshold and cycle.

Owner:THE 715TH RES INST OF CHINA SHIPBUILDING IND CORP
Method and system for evaluating the security of a cipher based on variable partitioning of a quadratic boolean equation
ActiveCN121150971BFacilitate subsequent searcheseasy searchSecuring communicationComplex mathematical operationsEvaluation resultCiphertext
The application discloses a password security evaluation method and system based on quadratic Boolean equation variable segmentation, and belongs to the technical field of password security evaluation. The method comprises the following steps: constructing a quadratic Boolean equation set about a password algorithm to be evaluated; constructing a mixed integer linear programming model of the quadratic Boolean equation set; solving the mixed integer linear programming model based on a set target function, to obtain an optimal segmentation result of x variables in the quadratic Boolean equation set; performing quadratic Boolean equation set solving based on the segmentation result of the x variables, to obtain a plurality of groups of candidate solutions; and decrypting the ciphertext according to the candidate solutions, to obtain a security evaluation result of the password algorithm to be evaluated. The application can provide security evaluation efficiency of the password algorithm.

Owner:INSTITUTE OF INFORMATION ENGINEERING CHINESE ACADEMY OF SCIENCES
A dam three-dimensional simulation analysis achievement real-time rendering system
This invention relates to the field of model simulation calculation, and particularly to a real-time rendering system for 3D simulation analysis results of dams. The system server, through a simulation model management module, transmits a 3D finite element mesh model, obtains calculation conditions from the system client, performs simulation based on these conditions, outputs calculation results, and transmits the calculation result data to the system client after processing it using an 8-bit compression method. A three-level indexing system is constructed. The calculation result management module manages the calculation results. The system client renders a multi-dimensional physical field cloud map. During precise queries, the system server returns lossless calculation results to the system client based on the three-level indexing system. This invention leverages the long-connection characteristics of WebSocket to achieve on-demand incremental transmission of fragmented data, resolving network congestion caused by full transmission. Through the synergy of data compression and progressive rendering, network utilization is optimized while ensuring the real-time performance and stability of the front-end visualization effects.

Owner:CHINA THREE GORGES PROJECTS DEV CO LTD +1
Uplink service message identification processing method and device, terminal and medium
PendingCN121814696Aaccurate classificationquick classificationTransmissionEngineeringMessage processing
The invention discloses an uplink service message identification processing method and device, a terminal and a medium. The method comprises the following steps: acquiring core feature information corresponding to an uplink service message; obtaining a target message core data structural body according to the core feature information; obtaining a PDU session identifier corresponding to an uplink service message based on the target message core data structure body; obtaining a QoS flow identifier based on the PDU session identifier and the target message core data structure body; based on the QoS flow identifier, obtaining an uplink service message after scheduling processing; performing query processing on the QoS flow identifier to obtain a target packet data convergence protocol instance; and completing a QoS identification processing flow of the uplink service message based on the target packet data convergence protocol instance. The invention aims to realize rapid QoS identification, classification and processing of the uplink service message, improve the message processing efficiency and accuracy, and reduce the system resource overhead.

Owner:BEIJING CHANGKUN TECHNOLOGY LTD
Sparse large language model weight refinement method, system and device and storage medium
PendingCN121858980Areduce overheadReduce confusionInference methodsNeural learning methodsAlgorithmTheoretical computer science
The invention discloses a sparse large language model weight refinement method, system and device and a storage medium, which are corresponding schemes, and the scheme realizes training-free and plug-and-play refinement of sparse weight after one-time pruning, significantly reduces the confusion degree, improves the zero sample task performance, and especially has an outstanding effect in a high sparse rate scene. The space is optimized in a unified mode through global soft constraint, heterogeneous Hessian inversion is avoided, pruning prior is effectively utilized in combination with historical momentum, Neumann series extrapolation solution is adopted, iteration time can be remarkably shortened, and expenses of computing resources and memory resources are reduced. The method is oriented to online and operation and maintenance processes of inference services such as text generation, question and answer, classification and retrieval enhanced question and answer and the like, and accesses the current network through hot update or gray release after completing intra-layer weight refinement; the existing word segmentation coding, service gateway and monitoring and rollback mechanisms are reused in the whole process, and it is ensured that the method can be implemented under real service distribution and resource budget.

Owner:UNIV OF SCI & TECH OF CHINA
Method and system for edge data migration based on SDWN and UAV edge in-network storage
PendingCN122554380ABalance transmission loadreduce competition
This invention discloses a method and system for migrating edge-based on-network storage data based on SDWN and UAVs. Under the SDWN architecture, multiple UAVs are used as destination nodes for data migration. The multi-UAV-assisted on-network storage data migration problem is modeled as an NP-hard combinatorial optimization model of many-to-many communication routing planning. A two-stage solution method is designed: first, a node similarity matrix is obtained based on the average comprehensive network state score between nodes, and spectral clustering k-means is used to obtain reasonable data file allocation decision variables and UAV access node decision variables. Then, for the path selection of many-to-many communication routing planning when multiple data files are transmitted in parallel, the whale optimization algorithm is used to solve the problem, effectively reducing link contention and shortening the maximum migration time of the system. Experimental results show that, on different topologies, after determining reasonable parameter settings, the algorithm of this invention outperforms the benchmark method in data migration efficiency and has lower migration time overhead, demonstrating the effectiveness and applicability of the algorithm.

Owner:GUILIN UNIV OF ELECTRONIC TECH
Underwater CSK-OFDM modulation and detection method based on LED linear constraint
PendingCN121966723ASolve signal distortionImprove robustnessElectromagnetic transmission optical aspectsMulti-frequency code systemsGlobal optimalTransmitter
The invention discloses an underwater CSK-OFDM modulation and detection method based on LED linear constraint, and the method comprises the steps: enabling a transmitter to map a data bit stream of a constellation diagram into a complex symbol stream, converting the complex symbol stream into a real number time domain sequence through an ACO-OFDM module, carrying out the LED amplitude limiting of the time domain sequence, and obtaining a time domain clipping sequence; transmitting the time domain clipping sequence in a UOWC channel through a corresponding LED, introducing symbol timing deviation and amplitude limiting noise into a frequency domain by a receiver, and processing the time domain clipping sequence by using an ACO-OFDM module again to obtain a received signal; under the maximum expectation framework, the probability from each alternative constellation diagram is calculated, symbol timing deviation and additive white Gaussian noise variance are estimated, a globally optimal solution is obtained, and a constellation diagram recognition result is output through maximum likelihood demodulation. According to the method, the linear range constraint of the LED and the complex environment under the UOWC scene are comprehensively considered.

Owner:SUN YAT SEN UNIV
Method for establishing end-to-end secure communication of unmanned aerial vehicle under cloud network architecture
ActiveCN117376911Breduce overheadReasonable allocation of resourcesSecure communicationEnd to end security
The application discloses a method for establishing end-to-end secure communication of unmanned aerial vehicle under cloud network architecture, and takes cloud server as a security service center to provide full-process authentication service for unmanned aerial vehicle end system; the cloud server only issues public authentication materials to unmanned aerial vehicles, and session key negotiation and establishment of end-to-end secure communication are realized between unmanned aerial vehicles; the unmanned aerial vehicle end system does not need to store authentication materials of other unmanned aerial vehicles in advance, the cloud server is driven by specific tasks, and specific authentication materials required for key negotiation are issued to unmanned aerial vehicles which need to be securely cooperated according to task requirements. The application only requires that the cloud server and any one of the unmanned aerial vehicles for key negotiation establish a communication connection, and the authentication materials issued by the cloud server can make the unmanned aerial vehicles realize key negotiation and establish an end-to-end secure channel in a specific range; different temporary public keys are used for each request message, which can effectively prevent the harm caused by long-term and short-term secret leakage.

Owner:XIDIAN UNIV
A power distribution internet of things communication and device management system based on dynamic optimization algorithm
This invention discloses a power distribution IoT communication and equipment management system based on dynamic optimization algorithms. It adopts a four-layer architecture: a perception layer, an edge layer, a platform layer, and an application layer. The end devices in the perception layer are used to collect power distribution data and execute control commands. The edge devices in the edge layer, and their managed sub-devices, are used for protocol conversion, data preprocessing, and executing dynamic optimization algorithms. The platform layer is used for message parsing, algorithm optimization, device management, and data storage. The application layer provides a visual user interface. Through dynamic optimization algorithms and a full lifecycle device management scheme, the system significantly improves the reliability of power distribution IoT data transmission, optimizes network resource utilization, enhances equipment operating efficiency, ensures the real-time performance of critical services, and features strong compatibility, security, and concurrent processing capabilities.

Owner:CHINA ELECTRIC POWER RESEARCH INSTITUTE CO LTD
Multi-thread dynamic task scheduling circuit, computing chip and computing system
PendingCN121858247Aincrease flexibilityMaximize utilizationProgram initiation/switchingResource allocationArithmetic logic unitComputer architecture
The invention relates to a multi-thread dynamic task scheduling circuit, a computing chip and a computing system, which are integrated in a parallel computing chip, and comprise a plurality of thread management units which are respectively used for storing context information of each task thread, reading an instruction stream from a memory through an internal instruction reading and transmitting unit, and decoding and transmitting the instruction stream; the arithmetic logic unit is used for executing arithmetic and logic operation instructions of the thread management unit so as to realize dynamic parameter derivation during operation; the task distribution unit is used for arbitrating the task configuration information transmitted by the plurality of thread management units and distributing the task configuration information to each processing unit in the chip; and the synchronization unit is used for synchronizing primitives through hardware so as to realize synchronization among the plurality of thread management units and synchronization between the thread management units and the processing unit. Each thread is programmable and adapts to complex scenes such as dynamic image sizes and dynamic calculation processes.

Owner:SHANGHAI JIAOTONG UNIV
Resource scheduling method, database system and electronic equipment
PendingCN121807530Aget quicklyeasy to handleResource allocationDatabase distribution/replicationTheoretical computer scienceEngineering
The invention discloses a resource scheduling method, a database system and electronic equipment, and relates to the technical field of cloud computing, the database system comprises a main node, a first segment node group and a second segment node group, and the first segment node group and the second segment node group both comprise all segment instances of the database system. The segmented instances include a main instance and a mirror instance. The main instance in the first segment node group corresponds to the mirror instance in the second segment node group. The mirror instances in the first segmented node group correspond to the main instances in the second segmented node group. And the main node calls the segment instance in the first segment node group or the segment instance in the second segment node group to perform data processing in response to the data processing request. By applying the technical scheme of the invention, only the resources of a part of segment nodes need to be called during data processing, so that the resource overhead is reduced, and the data processing performance of a database system is improved.

Owner:CHINA MOBILE GROUP DESIGN INST +1
Interface display method and device, computer equipment, readable storage medium and program product
PendingCN121997888Areduce overheadimprove performanceNatural language data processingComputer hardwareInformation control
The invention relates to an interface display method and device, computer equipment, a readable storage medium and a program product. The method comprises the following steps: configuring a physiological parameter block comprising a text display container and a text measurement container; the text display container is used for displaying the physiological parameter information in a web display interface, and the text display container has preset container size parameters; measuring display size information of the physiological parameter information received in real time through a text measurement container; determining a size adjustment coefficient for the physiological parameter information based on the container size parameter and the display size information; adjusting the physiological parameter information based on the size adjustment coefficient to obtain target physiological parameter information, and controlling the text display container to display the target physiological parameter information. According to the method, one-time determination of the size of the target physiological parameter information is realized, and the determined target physiological parameter information does not exceed the boundary of the text display container, so that the memory overhead can be reduced, and the performance is improved.

Owner:WUHAN UNITED IMAGING HEALTHCARE SURGICAL TECH CO LTD
Data classification method based on self-attention mechanism in iscc system
The application provides a data classification method based on a self-attention mechanism in an ISCC system, belongs to the field of perception communication and computing integration, and comprises the following steps: introducing attention weights by using the self-attention mechanism to measure the information amount of each ISAC device, fusing the local features of each ISAC device into global queries, taking the local features of each ISAC device as a key function and a value function, and using dot product to calculate the similarity to obtain the attention weights of the ISAC device; and determining whether the data of the device is transmitted to an edge server to participate in training of a classification model by judging whether the attention weight value reaches a set threshold value or not; the method improves the subsequent classification accuracy, reduces the calculation amount, avoids unnecessary waste of communication resources caused by transmission of redundant features, and balances the contradiction between the subsequent classifier and the number of feature selection. The method not only reduces the communication and calculation resource consumption but also improves the accuracy of the classification reasoning model.

Owner:NORTHEASTERN UNIV CHINA
A provincial meteorological and administrative collaborative wind speed prediction method based on dynamic federated learning
PendingCN122260538AOvercome difficulties that are difficult to advancebreak out
The application provides a provincial meteorological and administrative collaborative wind speed prediction method based on dynamic federal learning, relates to the cross technical field of artificial intelligence and energy meteorology, S1, basic data of N meteorological monitoring stations in a province is acquired, is divided into M initial subgraphs according to the administrative boundary of a prefecture-level city and is allocated an edge server, each collaborative subgraph pair is determined according to the Pearson correlation coefficient of the wind speed sequence of the station, the time sequence data deviation of the synchronized subgraph is synchronized through a dynamic time warping algorithm after every 3 rounds of federal iteration, and the subgraph data after synchronization is output. Through an endogenous decision and optimization framework, three links of dynamic coordination of cross-domain collaboration, local learning and gradient transmission are coordinated, and finally a global optimal provincial meteorological and administrative collaborative wind speed prediction method based on dynamic federal learning is achieved among multiple targets such as prediction accuracy, convergence speed and communication cost.

Owner:SHANGHAI INVESTIGATION DESIGN & RES INST CO LTD +1