
Patents
Literature
18592 results about "Computer architecture" patented technology
Efficacy Topic
Property
Owner
Technical Advancement
Application Domain
Technology Topic
Technology Field Word
Patent Country/Region
Patent Type
Patent Status
Application Year
Inventor
In computer engineering, computer architecture is a set of rules and methods that describe the functionality, organization, and implementation of computer systems. Some definitions of architecture define it as describing the capabilities and programming model of a computer but not a particular implementation. In other definitions computer architecture involves instruction set architecture design, microarchitecture design, logic design, and implementation.
AI-Optimized Memory Fabric for Large Contexts and Multimodal Workloads
PendingUS20260046317A1Program initiation/switchingResource allocationQuality of serviceComputer architecture
A coherent, intelligent, packet-switched memory fabric enables predictive, cache-coherent access across distributed compute, accelerator, and memory resources using a Memory-Fabric Transaction Layer Protocol (MF-TLP). MF-TLP defines routable packet formats for read, write, vectorized, atomic, reduction, collective, and predictive-prefetch transactions executed by memory-centric network interface controllers (MC-NICs). Each MC-NIC performs packet parsing, address translation, coherence management, and near-memory arithmetic or tensor operations while coordinating with MF-TLP-aware switches providing hierarchical directory control, multi-path routing, and in-network aggregation. Vectorized and multimodal packets encode multiple addresses or tensor offsets to reduce scatter / gather overhead, and programmable caching and quality-of-service modules manage tiered memory and tenant fairness. MF-TLP supports extension headers for predictive prefetch, collective coordination, and tenant governance, operating across hierarchical leaf-spine topologies using Ultra-Ethernet Transport, InfiniBand, or CXL fabrics. The system delivers scalable, low-latency, memory-centric orchestration for large-language-model training, multimodal AI, and data-intensive analytics.

Owner:QOMPLX INC
AI Serving Hardware and Software Frontier Enhancements
PendingUS20250390352A1Memory architecture accessing/allocationResource allocationComputer hardwareComputer architecture
A computer system implements a unified framework integrating an adaptive elastic funnel (AEF) with a convergent intelligence fabric (CIF) for multi-agent AI collaboration. The system provides a universal multi-modal key-value subsystem for sharing partial computations, implements hybrid placement strategies for dynamic memory management, and incorporates quantum-resistant secure enclaves. The architecture integrates hardware acceleration through GPU-FPGA hybrid caching and neuromorphic processors, applies adaptive energy and thermal management across hardware generations, and implements autonomous flash resource orchestration with multi-dimensional wear management. The system orchestrates tensor workflows using hierarchical scheduling, enables cross-agent collaboration with privacy preservation, and supports continuous learning without catastrophic forgetting. This integration delivers unprecedented computational efficiency and security in high-dimensional decision-making environments while supporting incremental adoption through modular interfaces.

Owner:QOMPLX INC
Platform for orchestrating a scalable, privacy-enabled network of collaborative and negotiating agents utilizing modular hybrid computing architecture
A scalable platform for orchestrating networks of collaborative AI agents utilizing modular hybrid computing architecture. The platform integrates classical, quantum, and neuromorphic computing paradigms through hardware-accelerated translation layers and cross-paradigm coordination mechanisms. A central orchestration engine manages interactions between domain-specific AI agents, dynamically distributing workloads across heterogeneous computing cores based on task complexity, computational requirements, and resource availability. The platform employs hardware-accelerated translation between paradigms, enabling efficient cross-paradigm information exchange while maintaining semantic consistency and computation integrity across different architectures. Specialized monitoring and optimization systems continuously adjust resource allocation and fine-tune performance across computing paradigms. Advanced cache management and fault tolerance mechanisms ensure reliable operation, while privacy-preservation techniques enable secure collaboration. The platform's modular architecture supports integration of different computational approaches, enabling complex multi-domain problem solving that leverages the unique advantages of each paradigm while maintaining system-wide efficiency, scalability, and coherence.

Owner:QOMPLX INC
Adaptive Real Time Image and Video Processing Using PCM-Enhanced Visual Strategy Caching and Multi-Stage Cognitive Routing
A system and method for adaptive image and video processing using a Persistent Cognitive Machine (PCM) architecture with visual strategy caching. The system receives degraded input media and extracts degradation fingerprints to query a PCM-based visual strategy cache containing previously successful processing strategies. When matching cached strategies are found above a relevance threshold, they are retrieved and applied directly. When no match exists, the input is processed through transform-domain networks to generate new strategies. A pattern synthesizer combines multiple strategies for complex degradation types. The system evaluates processing effectiveness using a feedback controller and stores successful strategies in the hierarchical cache. This cognitive approach enables real-time processing with continuously improving performance as the cache learns from successful patterns. The adaptive architecture eliminates redundant processing while maintaining high-quality output, making it suitable for diverse imaging and video applications requiring efficient enhancement capabilities with superior performance over traditional methods.

Owner:ATOMBEAM TECH INC
Methods for delta-QP signaling for decoder parallelization in hevc
ActiveUS20120183049A1Color television with pulse code modulationColor television with bandwidth reductionComputer architectureCoded block flag
By implementing a new bitstream for a Delta-Quantization Parameter (DQP), a decoder is able to implement parallel decoding of multiple coding units within a largest coding unit. In some embodiments, the DQP is placed immediately after the mode information of the first coding unit. In some embodiments, the DQP is placed after the mode information of the first non-skipped coding unit. In some embodiments, the DQP is placed after the first non-zero coded block flag.
Owner:SONY GROUP CORP
Processor and electronic equipment
The invention discloses a processor and electronic equipment. The processor includes a computing unit including a tensor core configured to perform a matrix multiplication operation using a scaling factor, and a memory, the computing unit further including a scaling factor processing module configured to determine and cache a scaling factor for each tensor associated with the matrix multiplication operation, the computing unit further comprises at least one storage module arranged on a data path between the tensor core and the memory, and the at least one storage module is exclusively occupied by the tensor core when the tensor core executes tensor related operation. And the scaling factor processing module is arranged on the at least one storage module. At present, scaling factors and floating-point number quantization are completed by a vector calculation core, so that performance is reduced, and delay becomes high, and a scaling factor processing module arranged on a storage module in a calculation unit can improve the overall execution efficiency of low-precision matrix multiplication using the scaling factors.

Owner:SHANGHAI BIREN TECH CO LTD
Memory fault repairing method and device, equipment, medium and computer program product
The invention discloses a memory fault repairing method and device, equipment, a medium and a computer program product, and relates to the technical field of computers.The memory fault repairing method includes the steps that memory error information sent by a memory controller is obtained, a fault target memory page can be positioned, and a standby memory page is obtained from a standby memory pool; the memory address mapping table is updated, the physical address of the target memory page with the fault is mapped to the physical address of the standby memory page, the repairing process does not depend on triggering of a system management interrupt mechanism, memory repairing in the system running stage is achieved, the system downtime caused by memory fault repairing is shortened, and therefore the memory repairing efficiency is improved. The problem of high delay in memory fault processing can be solved, and the technical effect of improving the memory fault repairing efficiency is achieved.

Owner:INSPUR SUZHOU INTELLIGENT TECH CO LTD
Expansion equipment function configuration method and device, computer equipment and storage medium
PendingCN120353745AResource allocationProgram loading/initiatingComputer architectureDynamic resource
The invention discloses an extension equipment function configuration method and device, computer equipment and a storage medium, and relates to the technical field of data processing. According to the method, a hardware and firmware collaborative dynamic configuration framework is constructed, and a receiving queue is adopted at an extension equipment end to trigger a central processing unit firmware processing mechanism; in combination with virtualization design of a shadow configuration space and a shadow register, dynamic reconstruction of configuration parameters and an address mapping strategy during operation is realized; a host end supports configuration space access, base address register remapping and memory data transmission interaction through a transaction generation and routing mechanism driven by an event type. Hardware solidification limitation of traditional extension equipment is broken through through software and hardware decoupling design, the problems that function extension capacity is insufficient, resource dynamic allocation is difficult and protocol updating and virtualization scenes cannot be adapted are solved, and the technical effects of improving configuration reconstruction efficiency and address space utilization rate and supporting virtual function creation are achieved. And the adaptability of the equipment in cloud computing and edge computing environments is enhanced.

Owner:SHANDONG YUNHAI GUOCHUANG CLOUD COMPUTING EQUIP IND INNOVATION CENT CO LTD
Method and apparatus for efficient access to multidimensional data structures and / or other large data blocks
ActiveUS12499052B2Memory architecture accessing/allocationProgram synchronisationMemory addressComputer architecture
A parallel processing unit comprises a plurality of processors each being coupled to a memory access hardware circuitry. Each memory access hardware circuitry is configured to receive, from the coupled processor, a memory access request specifying a coordinate of a multidimensional data structure, wherein the memory access hardware circuit is one of a plurality of memory access circuitry each coupled to a respective one of the processors; and, in response to the memory access request, translate the coordinate of the multidimensional data structure into plural memory addresses for the multidimensional data structure and using the plural memory addresses, asynchronously transfer at least a portion of the multidimensional data structure for processing by at least the coupled processor. The memory locations may be in the shared memory of the coupled processor and / or an external memory.

Owner:NVIDIA CORP
Multi-protocol dynamic switching method and system based on FPGA
The invention relates to the field of electronic communication, and provides a multi-protocol dynamic switching method and system based on an FPGA. The method comprises the following steps: carrying out regional division on an FPGA chip through a layout planning tool to obtain a static logic region and a plurality of reconfigurable logic partitions; performing hanging processing on the current protocol module based on the protocol switching trigger signal, and writing running state data of the current protocol module into a state cache unit to obtain protocol context snapshot data; according to the target protocol type, bit stream loading is carried out on the corresponding reconfigurable logic partition through configuration of an access port, and a reconfiguration protocol module is obtained; and reading protocol context snapshot data, and performing state recovery on the reconstruction protocol module to obtain a target protocol data path. According to the invention, rapid protocol switching is realized, the utilization rate of hardware resources is improved, and the system deployment cost is reduced.

Owner:TIANJIN JINHANG COMP TECH RES INST
Memory access method, program product, equipment and medium
The invention discloses a memory access method, a program product, equipment and a medium, and relates to the technical field of computers, firmware is utilized to determine to-be-reserved physical memory information, the to-be-reserved physical memory information is analyzed and continuously split to obtain physical memory segments, and the physical memory segments are divided and aligned; dividing the virtual address space, and performing alignment processing on the divided virtual address space; performing memory mapping on the processed physical memory segment and a physical address space corresponding to the processed virtual address space; generating a page table by utilizing a physical address space corresponding to the mapped and processed virtual address space; when an access instruction of a user is obtained, the corresponding target physical address space is screened from the page table to determine the mapped target physical memory segment, so that the user accesses the target physical memory segment based on the user mode process, the range and capacity of the memory segment are dynamically configured, the stability of the memory during key load operation is guaranteed, and the memory access performance is improved.

Owner:LANGCHAO ELECTRONIC INFORMATION IND CO LTD
Multi-task dynamic resource sharing method and system for universal graphics processing unit
The invention provides a multi-task dynamic resource sharing method and system for a universal graphics processor, and belongs to the technical field of computing graphics process.The method comprises the steps that a plurality of computing tasks are distributed to processing subunits in a cooperative processing unit respectively; obtaining the load state of the computing resource in each processing subunit, and determining the available computing resource capacity of each processing subunit according to the load state; according to the available computing resource capacity, marking the processing subunit of which the current execution thread beam instruction queue length exceeds the own available computing resource capacity as a source processing subunit, and marking the processing subunit with idle computing resources as a target processing subunit; and migrating part or all of the to-be-executed thread beam instructions in the to-be-executed thread beam instruction queue of the source processing subunit to the idle computing resources of the target processing subunit for execution. According to the method and the device, the cross-processing subunit dynamic migration is carried out on the thread beam instruction based on real-time load monitoring, so that the throughput rate and the computing resource utilization rate are improved.

Owner:YUANQIXIN (SHANDONG) SEMICONDUCTOR TECHNOLOGY CO LTD
Lossless and lossy automatic hardware compression in graphics-to-graphics network links
An apparatus to facilitate lossless and lossy automatic hardware compression in graphics-to-graphics network links is disclosed. The apparatus includes compressor / decompressor circuitry (CDC) integrated with physical layer (PHY) intellectual property (IP) hardware circuitry for a graphics processor unit (GPU)-to-GPU communication link communicably coupling a first GPU to one or more other GPUs, the CDC to: receive a data message from the first GPU, wherein the data message is in an uncompressed format; determine that a compression process is to be applied to the data message; apply the compression process to the data message to generate a compressed data message; and cause a GPU link IP hardware circuitry that comprises the PHY IP hardware circuitry to transmit the compressed data message over the GPU-to-GPU communication link.

Owner:INTEL CORP
Internet-of-things multi-protocol fusion limo intelligent control system
The invention discloses an internet of things multi-protocol fusion limo intelligent control system, which relates to the field of limo intelligent control and comprises a hardware irrelevant layer, a multi-protocol adaptation layer, a data abstraction layer, a programmable logic layer, a security and redundancy mechanism and an edge AI module. According to the invention, a physical bus is packaged into an independent module, an MCU / SoC and a protocol transceiver are built in, hot plugging is realized through a standardized PC I e / EdgeConn backboard, a core processing board only exposes a unified backboard interface, module drive localization execution is realized, master control firmware does not need to sense protocol details, only the module needs to be replaced when a protocol is newly added, and the master control firmware or upper software does not need to be modified. The defect that the whole vehicle firmware needs to be refreshed when a bus is replaced in a traditional system is overcome, each protocol corresponds to an independent drive micro-service deployed in a containerization mode, the drive micro-service analyzes a message into a unified data model and uploads the unified data model to a data abstraction layer, a downlink control instruction is packaged and issued according to a target protocol, and it is guaranteed that the protocols are diversified and interfaces are consistent.

Owner:南京极屿房车科技有限公司
Secure debugging method of embedded microprocessor and embedded microprocessor
PendingCN120407507AInternal/peripheral component protectionArchitecture with single central processing unitComputer architectureData access
The invention relates to the technical field of microprocessors, and discloses a safety debugging method of an embedded microprocessor and the embedded microprocessor, the method comprises the following steps: implanting a random module in the microprocessor, constructing a resistance network array through random distribution of silicon substrate lattice defects to generate a disordered sequence, and if microprocessor data access is carried out, starting the random module; if physical intrusion is detected, a debugging session is established, three types of physical characteristics are synchronously generated to construct a composite key, a triple dynamic confusion layer is constructed in the microprocessor, the dynamic confusion layer and the composite key construct physical logic linkage protection, a probe access instruction logic address is called, if physical intrusion is detected, a probe triggers an invisible check point, and the probe accesses the invisible check point. The integrity of an execution environment is verified, if abnormal debugging is detected, a hardware defense mechanism is triggered, an access attack model is established, confusion parameters are trained and optimized, and a module interconnection mode is changed, so that the learning cycle of an attacker is broken, and the risk of attacking a processor in a machine learning mode is reduced.

Owner:KUNSHAN ZHONGYIFENG PHOTOELECTRIC TECH CO LTD +1
Hardware accelerated synchronization with asynchronous transaction support
ActiveUS12536056B2Program synchronisationInput/output processes for data processingComputer hardwareComputer architecture
A new transaction barrier synchronization primitive enables executing threads and asynchronous transactions to synchronize across parallel processors. The asynchronous transactions may include transactions resulting from, for example, hardware data movement units such as direct memory units, etc. A hardware synchronization circuit may provide for the synchronization primitive to be stored in a cache memory so that barrier operations may be accelerated by the circuit. A new wait mechanism reduces software overhead associated with waiting on a barrier.

Owner:NVIDIA CORP
Memory mapping and CXL translation to exploit unused remote memory in a multi-host system
ActiveUS12423226B2Memory architecture accessing/allocationMemory adressing/allocation/relocationComputer architectureEngineering
This invention pertains to a system optimized for reutilizing allocated underutilized or unused allocated DRAM, comprising a first host, a second host, and a resource composer, interconnected via CXL. Both hosts run packaged computing environments (PCEs), which may be containers or virtual machines, and are equipped to handle respective processes, P1 and P2. The resource composer is tasked with receiving data related to P1's memory usage from a kernel module on the first host, identifying underutilized DRAM mapped to P1, and subsequently remapping it to P2's address space on the second host. This process involves the use of CXL.mem commands, which are then translated into appropriate CXL.cache or CXL.io commands for DRAM access based on the mapping.

Owner:UNIFABRIX LTD
Video display and storage method and system based on wayland protocol and storage medium
PendingCN120935406ADigital video signal modificationSelective content distributionComputer hardwareOverlay
The invention belongs to the technical field of computers, and provides a video display and storage method and system based on a wayland protocol and a storage medium in order to solve the problems that an existing wayland video system is high in rendering delay, high in CPU load, low in storage efficiency and poor in cross-platform compatibility. Video frames are directly written into an Overlay layer through DRM-KMS and mixed by bypassing a synthesizer, meanwhile, CPU memory amplitude overhead is eliminated through zero copy transmission, an ISP-GPU-VPU direct transmission assembly line is constructed, full-link DMA-BUF direct transmission is achieved, and delay is greatly reduced; iSP preprocessing, GPU shader scaling and VPU coding are all executed by special hardware, so that the load is reduced, and the multi-path processing capability is improved; vPU dynamic code rate compression is utilized, segmented storage is carried out according to events / time, metadata is synchronized to a database, redundant storage is avoided, and space is saved.

Owner:CHANGSHA YINGBEIDI ELECTRONIC TECH CO LTD
In-memory computing circuit chip based on magnetic cache and computing device
PendingCN113539318AHigh densityLarge capacityDigital storageNeural architecturesData needsEngineering
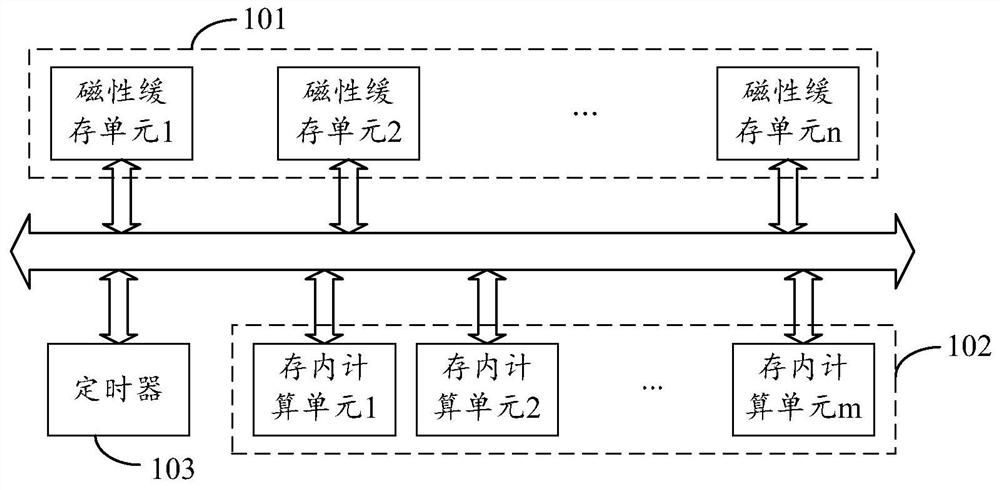
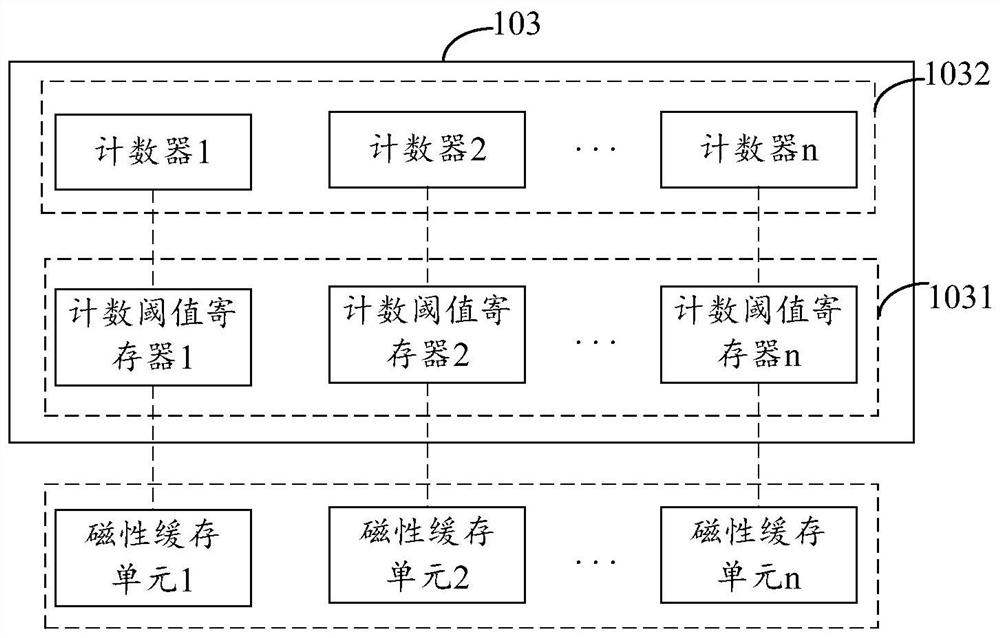
The embodiment of the invention discloses an in-memory computing circuit based on a magnetic cache, and the circuit comprises at least one magnetic cache unit, at least one in-memory computing unit, and a timer. The magnetic cache unit in the at least one magnetic cache unit is used for caching data output by the corresponding in-memory computing unit as to-be-processed data within the corresponding data retention time; the timer is used for respectively setting data retention time for the at least one magnetic cache unit; and the in-memory computing unit in the at least one in-memory computing unit is used for extracting the data to be processed from the corresponding magnetic cache unit for calculation and outputting the computed data to other magnetic cache units. According to the embodiment of the invention, the invention achieves the flexible adjustment of the data retention time of the magnetic cache unit in various in-memory calculation scenes, and achieves the provision of a high-capacity cache for the data needed by in-memory computing under the lower power consumption.
Owner:NANJING HOUMO TECH CO LTD
Robotic Emulation Device
ActiveUS20250249599A1Programme-controlled manipulatorArtificial lifeComputer architectureTransceiver
A robotic emulation device includes a processor, memory and multimedia interfaces to capture a video signal from a target device, analyze it, and transmit manipulation control signals to the target device input by emulating a peripheral input device, wherein the manipulation control signals determine manipulation or selection of a target interface control associated with a first user interface encoded and transmitted in the video signal. Furthermore, the robotic emulation device may be connected via an embedded transceiver to at least one computer or computer tenant for relaying the captured video data for analysis, and based on the analysis, applying inferred manipulation semantics.

Owner:LUCOMM TECHNOLOGIES INC
Industrial personal computer and multi-graphics card collaborative parallel operation acceleration system
The invention discloses an industrial personal computer and multi-graphics card collaborative parallel computation acceleration system, which relates to the technical field of industrial resource allocation and parallel computation, and comprises a resource monitoring and predicting module, a resource management module and a prediction type resource preparation module, the task splitting and collaborative execution module comprises a task splitting module, a cross-node collaborative module and a collaborative operation engine; the intelligent scheduling and dynamic resource allocation module comprises an intelligent scheduler, a dynamic resource allocation module and a conflict avoidance module. According to the method, the GPU video memory utilization rate, the core utilization rate, the temperature, the video memory fragment rate, the available video memory total amount, the CPU core total utilization rate, the load condition and the idle core number index are collected in real time through a resource monitoring module, and the video memory capacity, the GPU core occupancy rate and the CPU load requirement are predicted in advance before a task is submitted in combination with a gradient boosting decision tree and a neural network prediction model; and resources are reserved, so that the scheduling delay is remarkably reduced, and the scheduling hit rate is improved.

Owner:ZHUHAI SHININGDA TECH CO LTD
Large model training-oriented GPU (Graphics Processing Unit) cluster computing power optimization architecture
InactiveCN120448030AResource allocationSoftware simulation/interpretation/emulationComputer architecturePower optimization
A GPU cluster computing power optimization architecture oriented to large model training is characterized in that a computing power resource management module is used for monitoring and managing the computing power resource state of each GPU in a GPU cluster in real time, a task scheduling module is used for allocating GPU resources according to the requirements of training tasks, and a computing power optimization module is used for dynamically optimizing the computing power of the GPU cluster in the task execution process. And the result feedback module is used for collecting and analyzing the optimized computing power use condition so as to adjust a subsequent task scheduling strategy. According to the method, the computing power resource state of the GPU cluster is monitored and managed in real time, the GPU resources are dynamically allocated according to the demand of the training task, and the computing power of the GPU cluster is dynamically optimized in the task execution process, so that the computing power utilization efficiency of the GPU cluster is effectively improved, and the training cost is reduced.

Owner:XIANGTAN UNIV
Photonic memory fabric for system memory interconnection
ActiveUS20250258606A1Multiplex system selection arrangementsInput/output to record carriersComputer hardwareComputer architecture

Owner:SICILY MERGER SUB II INC
Two-level context caching and eviction for scatter-gather DMA
ActiveUS12561261B1Concurrent instruction executionMemory systemsProcessing InstructionComputer architecture
One aspect of the instant disclosure may provide a system and method for processing scatter-gather direct memory access (S-G DMA) instructions. During operation, the system may receive an S-G DMA instruction associated with a message and gather instruction context for the S-G DMA instruction. An S-G DMA processor may process the S-G DMA instruction based on the gathered instruction context and determine whether there exists a pending S-G DMA instruction associated with the message. In response to the presence of the pending S-G DMA instruction, the system stores the instruction context in a hot context cache at an address corresponding to the pending S-G DMA instruction. In response to the absence of the pending S-G DMA instruction, the system stores the instruction context in a cold context cache.

Owner:HEWLETT PACKARD ENTERPRISE DEV LP
SECS / GEM protocol-based semiconductor device communication system and method
The invention discloses a semiconductor device communication system and method based on an SECS / GEM protocol. The system comprises an SECS / GEM protocol processing module, a PLC communication module and a service logic processing module. The protocol processing module realizes message coding and decoding and state management through an HSMS / GEM layered architecture, and supports equipment capability dynamic negotiation; the PLC communication module adopts a factory mode to adapt to a multi-manufacturer controller to realize online mapping of a physical register and a logic address; and the business logic module dynamically loads the command processor based on a reflection mechanism, and realizes multi-condition event triggering through a rule engine. The method comprises the processes of system initialization, message priority scheduling, composite alarm processing and exception recovery, and the equipment integration efficiency and the communication reliability are remarkably improved. The method solves the problems of rigid parameter mapping, single event processing and poor equipment compatibility of a traditional scheme, and can be widely applied to equipment automation control of scenes such as semiconductor wafer manufacturing and packaging testing.

Owner:GUANGDONG SOWOTECH CO LTD
Large model calculation acceleration chip architecture
ActiveCN120525012AArchitecture with single central processing unitPhysical realisationMassively parallelComputer architecture
The invention discloses a large model calculation acceleration chip architecture, and relates to the field of large models. Comprising a normalized network-on-chip, an interconnection transmission system, a storage control system and a calculation acceleration core, the storage control system is connected with the Memory video memory group and the external SSD memory based on different built-in storage controllers; the normalized network-on-chip reads on-chip model parameters of a target position based on the storage control system, sends the on-chip model parameters to the calculation acceleration core for calculation, restores on-chip model data, carries out off-chip interaction with an external management server based on the interconnection transmission system, receives an instruction task, reads and restores external model parameters, and sends the external model parameters to the calculation acceleration core for calculation. And performing inter-chip interaction with other computing acceleration chips based on an interconnection transmission system, and reading and restoring inter-chip model parameters. According to the scheme, the hybrid video memory computing chip architecture supports multi-parallel SSD direct connection access, the capacity is expanded at low cost under the condition of keeping the bandwidth, and high cost performance is kept for both large-scale parallel tasks and small-sized low-cost all-in-one machines.

Owner:STORAGEX TECH INC
Ad hoc network dynamic slice architecture based on software defined radio and management and control method
The invention relates to the field of wireless communication and intelligent networks, in particular to a software defined radio-based ad hoc network dynamic slicing architecture and a management and control method, comprising a basic communication layer, an intelligent control layer and a service execution layer. The basic communication layer adopts a multi-distribution multi-center clustering architecture; the intelligent control layer is responsible for intelligent management and resource scheduling of the self-organizing network, and the intelligent control layer comprises a plurality of command and control nodes; and the service execution layer adopts a micro-service-based architecture, and encapsulates different network functions and service logics into independent micro-service modules. According to the method, the technical problems of high plane coupling, resource scheduling rigidness, insufficient survivability and high hardware dependency in the prior art are solved.

Owner:CHENGDU BIYUN TIANXI TECHNOLOGY CO LTD
Memory processing method based on intelligent agent, storage medium and electronic device
The embodiment of the invention provides a memory processing method based on an intelligent agent, a storage medium and an electronic device, a memory architecture of the intelligent agent comprises a first memory layer, a second memory layer and a third memory layer, the first memory layer is used for storing historical dialogue information of interactive dialogue between at least one interactive object and the intelligent agent, and the second memory layer is used for storing historical dialogue information of interactive dialogue between at least one interactive object and the intelligent agent. The second memory layer is used for storing structured events extracted from historical dialogue information, and the third memory layer is used for storing pattern induction memory obtained by performing pattern induction on the structured dialogue events; the method comprises the steps that in response to current round dialogue input information of a target interaction object, target storage information associated with the current round dialogue input information is retrieved from at least one memory layer in a memory architecture, and the current round dialogue input information and the target storage information are assembled into a current cue word; and submitting the current prompt word to a specified interaction model through the intelligent agent, and outputting a response result of the specified interaction model to the interaction object.

Owner:ZTE CORP
SoC performance verification method and device based on dynamic QoS regulation and control, medium and equipment
ActiveCN120805842ACAD circuit designSpecial data processing applicationsComputer architectureChip architecture
The invention belongs to the technical field of integrated circuit design verification, and particularly discloses an SoC performance verification method and device based on dynamic QoS regulation and control, a medium and equipment, and the method comprises the steps: analyzing a chip architecture, and obtaining a chip resource mapping table; constructing an automatic verification environment based on the chip resource mapping table and performing testing; scene parameter configuration is carried out according to a target application scene and based on the chip resource mapping table; and performing dynamic QoS regulation and control based on the configured scene parameters in a tested automatic verification environment so as to verify the performance of the SoC. According to the invention, the accuracy and efficiency of SoC performance verification and the consistency of the result and the actual application scene can be improved.

Owner:XIAMEN UNISOC TECH CO LTD
Image encryption system and method in smart power grid environment
ActiveCN120547282AMultiple keys/algorithms usageEncryption apparatus with shift registers/memoriesComputer architectureGraph neural networks
The invention discloses an image encryption system and method in an intelligent power grid environment, and aims to solve the problem that an encryption strategy is static and lacks self-adaptive capability in the prior art. The image encryption system comprises terminal equipment, edge equipment and central equipment, and a dynamic key generation unit on the terminal equipment generates a dynamic key by cooperatively utilizing a physical unclonable feature (PUF) of the equipment and a real-time load of a power grid; the hierarchical encryption unit performs encryption of different intensities based on image content complexity. A topology sensing transmission module of the system analyzes power grid topology by using a graph neural network (GNN) and dynamically optimizes transmission. In addition, the image encryption system further integrates low-density parity check code encoding and decoding and a self-adaptive decryption strategy so as to enhance the anti-interference capability. According to the invention, by constructing a sensing, decision-making and execution integrated adaptive security system, the security, high efficiency and robustness of smart grid image data transmission are significantly improved.

Owner:EASTERN GANSU UNIVERSITY