
Patents
Literature
8185results about "Electric digital data processing" patented technology
Efficacy Topic
Property
Owner
Technical Advancement
Application Domain
Technology Topic
Technology Field Word
Patent Country/Region
Patent Type
Patent Status
Application Year
Inventor
Image processing apparatus and method, and storage medium
InactiveUS7372594B1Quality improvementDegradation of image qualityDigitally marking record carriersDigital computer detailsImaging qualityComputer graphics (images)
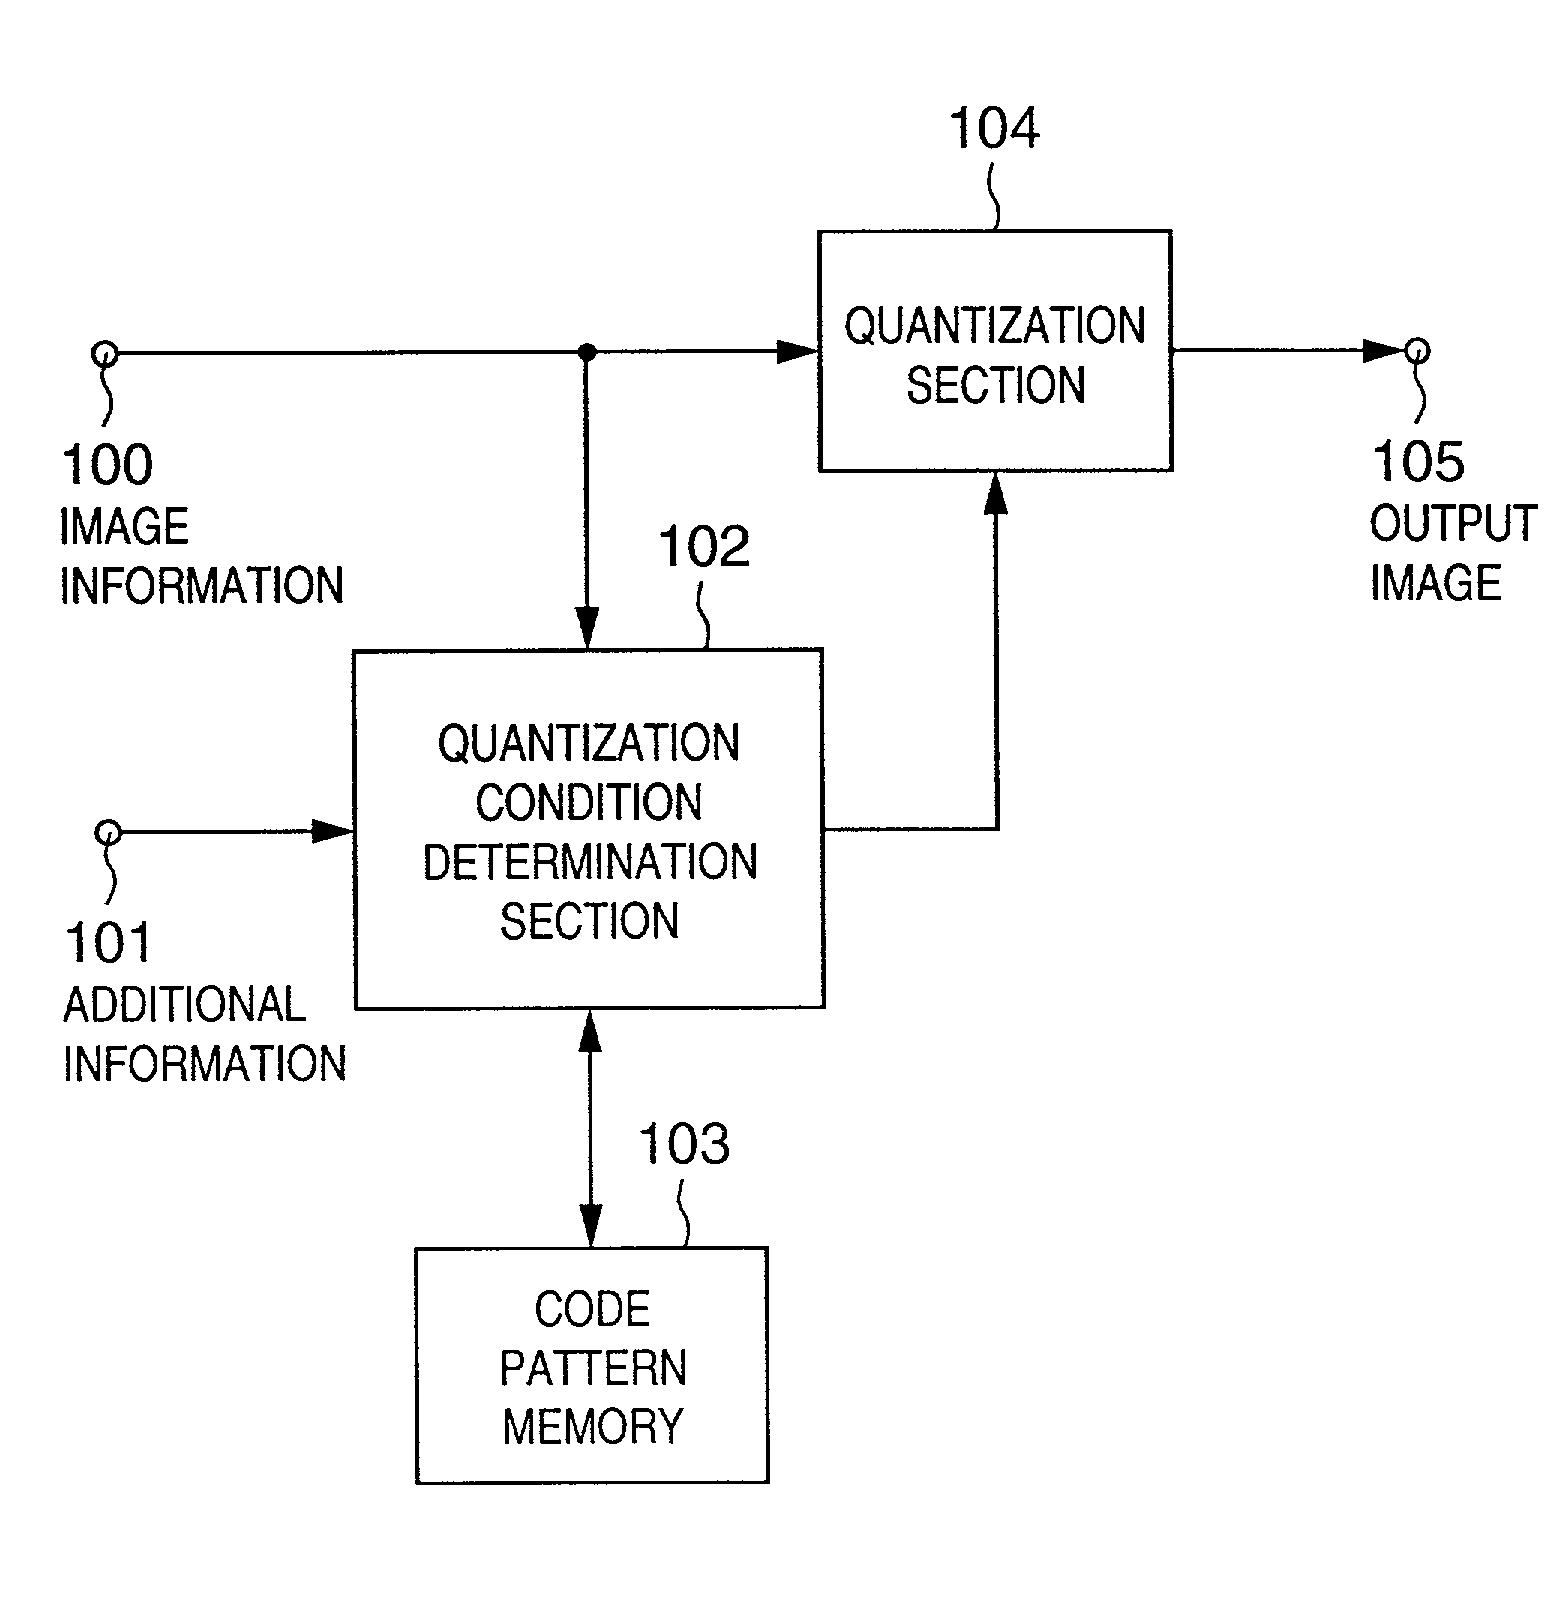
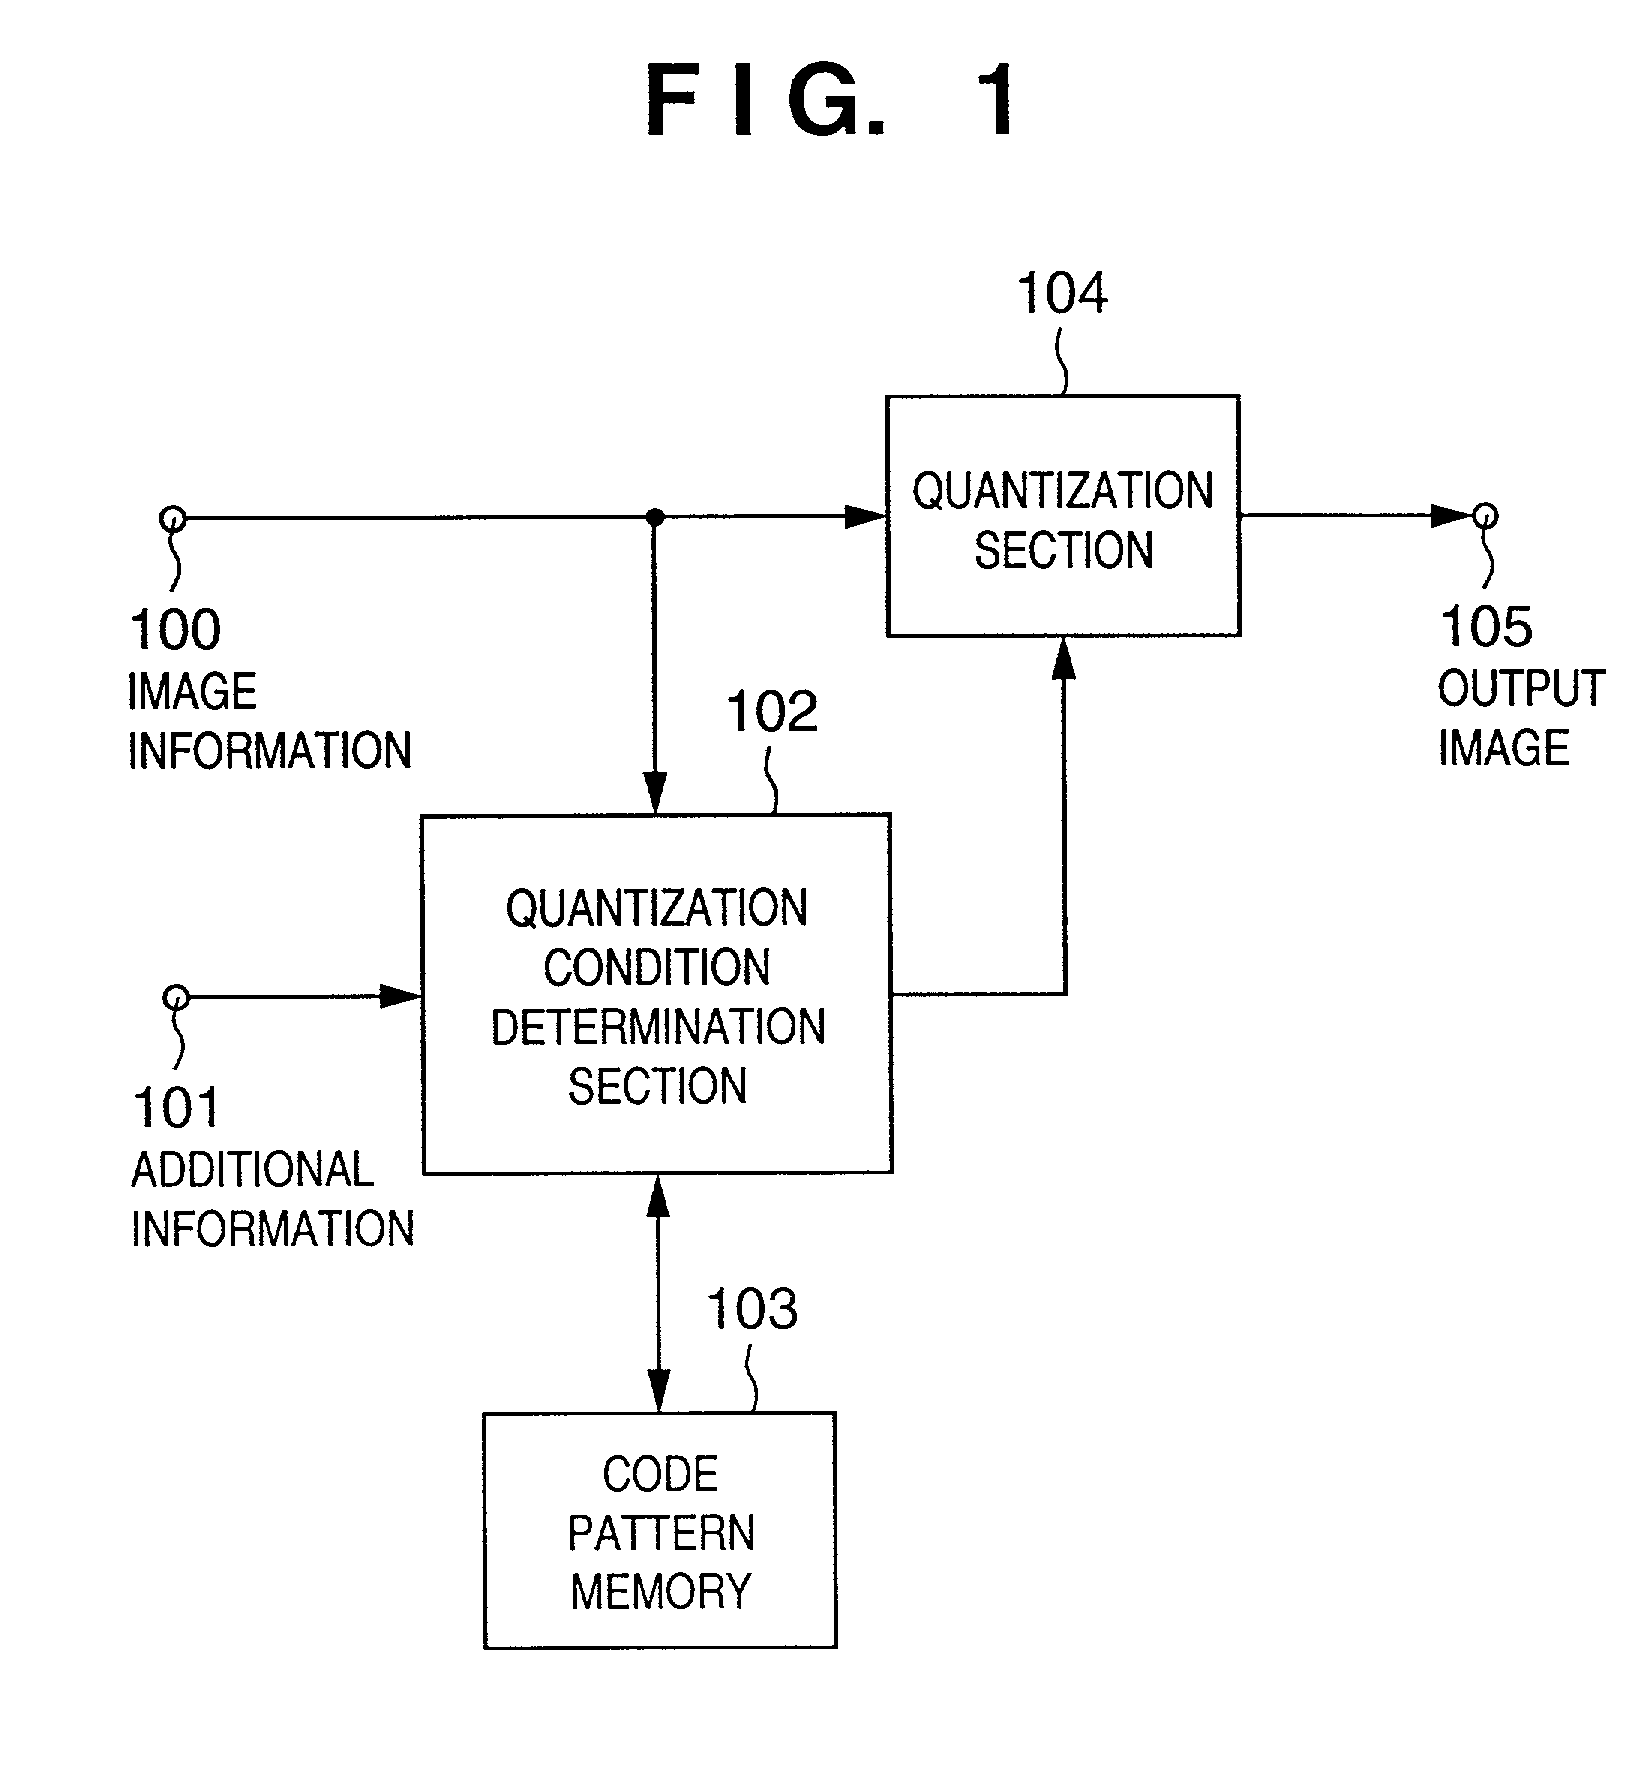
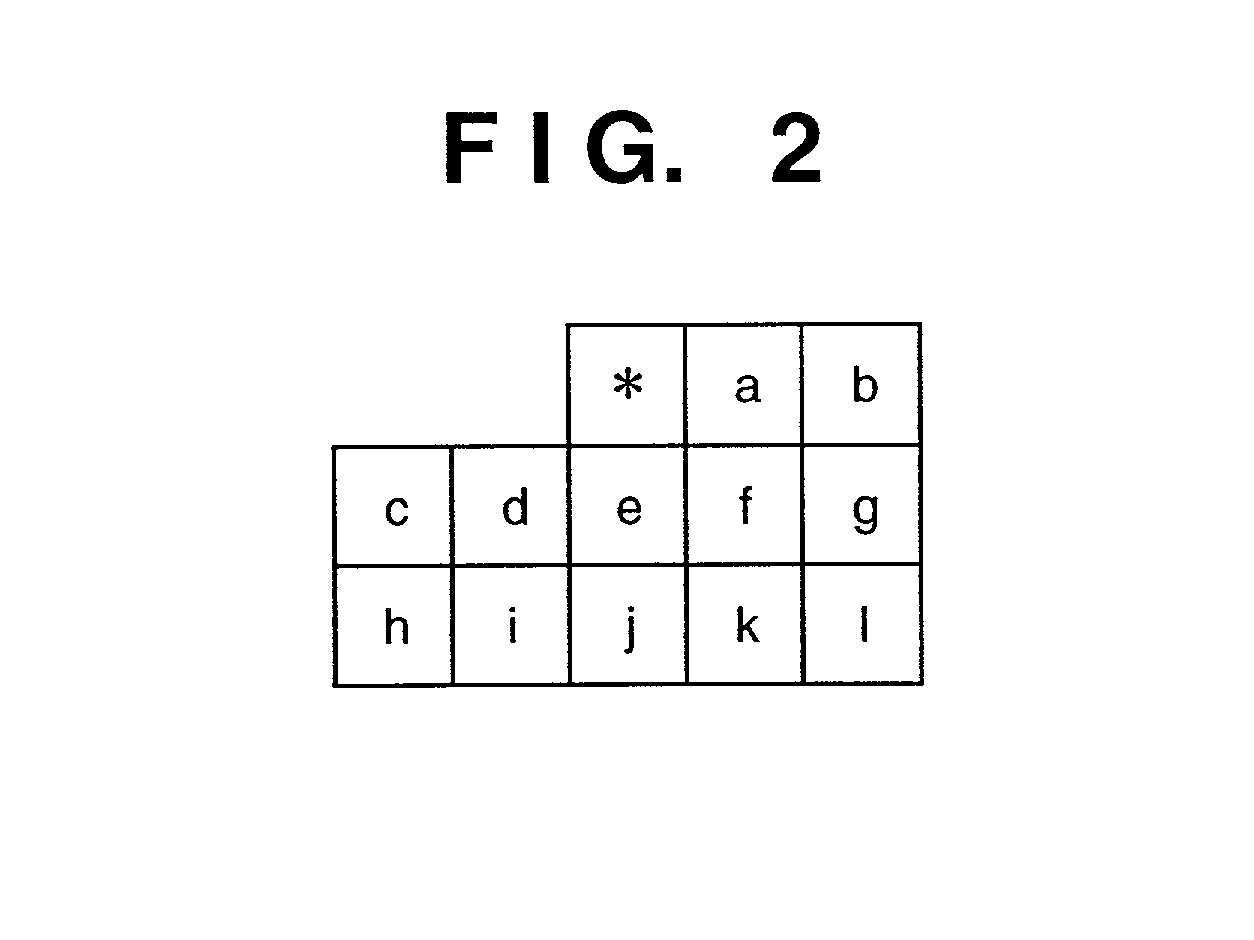
A pattern which does not appear at a flat portion in normal binarization processing is set as a code pattern, and a code formed from this pattern is attached. At this time, code attachment with little degradation in image quality is implemented by selecting an unnoticeable pattern.
Owner:CANON KK
Remote memory access systems and methods
PendingUS20250291760A1Digital computer detailsElectric digital data processingComputer architectureRemote memory access
The present disclosure relates to systems and methods remote memory access between systems. In particular, some implementations relate to remote memory access using data processing units that can reduce loads on central processing units or other system components. Some implementations utilize scheduling algorithms to optimize memory transfers. Some implementations relate to data processing unit hardware that includes programmable logic, which can be configured for scheduling, data processing, and the like.

Owner:THE ALIGNED CO
Data processing chip based on heterogeneous computing architecture
PendingCN120596409ADigital computer detailsElectric digital data processingComputer architectureRedundant code
The invention discloses a data processing chip based on a heterogeneous computing architecture, and relates to the technical field. The data processing chip based on the heterogeneous computing architecture comprises a data processing unit for receiving and preprocessing data to be transmitted; the clustering compression engine is used for carrying out clustering compression processing on the preprocessed data to be transmitted; the modulation and coding control unit is used for carrying out modulation and coding processing on the data to be transmitted after clustering compression processing; the redundant coding unit is used for carrying out redundant coding processing on the modulated and coded data to be transmitted; and outputting the to-be-transmitted data subjected to redundant coding processing to a protocol stack and interface unit of external equipment according to a set communication protocol. Through collaborative design of a clustering compression engine in a chip and a modulation coding control unit, clustering compression aiming at data structure characteristics and modulation strategy matching in a dynamic channel state are realized; the problems of fixed compression and modulation modes and lack of cooperation in the prior art are solved.

Owner:SHENZHEN JINCHAO CLOUD CONTROL TECH CO LTD
Clock domain crossing synchronization circuit and method based on multi-phase clock
The invention relates to the technical field of integrated circuits, and provides a clock domain crossing synchronization circuit and method based on a multiphase clock, and the circuit comprises a selector, an asynchronous clock synchronization module and a digital signal processor. Wherein serial data to be transmitted and a low-frequency clock are input into the selector, and the selector is used for outputting corresponding RX parallel data to the asynchronous clock synchronization module according to the serial data and the low-frequency clock; the asynchronous clock synchronization module is used for outputting corresponding alignment data to the digital signal processor according to the input RX parallel data, the clock of the digital signal processor and the low-frequency clock; the asynchronous clock synchronization module is used for performing phase alignment on the RX parallel data and a clock of the digital signal processor; and the digital signal processor is used for carrying out data processing on the alignment data. According to the invention, stable transmission of low-delay cross-clock domain data can be realized.

Owner:SHANGHAI SHENGLIANKE SEMICONDUCTOR CO LTD
Network card adapter plate and server system
The invention discloses a network card adapter plate and a server system, and relates to the technical field of computers, the network card adapter plate comprises a power supply connector, a plurality of node connectors, a power supply and time sequence signal processing module and a plurality of network card connectors, the power supply connector is connected to a power supply board, the plurality of node connectors are respectively connected with different server nodes, and the power supply and time sequence signal processing module is connected with the network card connectors. The plurality of network card connectors are respectively configured to be connected with different interfaces of a network card; the power supply and time sequence signal processing module comprises a power supply enabling control unit, an electronic fuse and a main power supply time sequence signal generating unit; the power supply enabling control unit enables the electronic fuse to supply power to the network card when the hot plug-in condition is met and no hot pull-out operation exists; the power supply normal signal output end of the electronic fuse outputs an auxiliary power supply time sequence signal to the network card; and the main power supply time sequence signal generation unit outputs a main power supply time sequence signal to the network card when receiving the network card power supply normal signal and having no hot pull-out operation. According to the invention, hot plugging of the network card is realized in a multi-node sharing environment.

Owner:LANGCHAO ELECTRONIC INFORMATION IND CO LTD
Real-time transmission system based on Zynq AXI4 bus and control method thereof
ActiveCN120872874AArchitecture with single central processing unitElectric digital data processingComputer architectureTransmission channel
The invention relates to the technical field of direct current motor servo drive control, and provides a Zynq AXI4 bus-based real-time transmission system and a control method thereof, and the system comprises a Zynq system on chip, a DDR3 common data area, an AXI4 bus interconnection architecture and a dynamic partition manager. By implementing the scheme, firstly, the multi-channel characteristic of the AXI4 bus is utilized, special transmission channels are distributed for different types of data, and parallel data interaction is realized; secondly, a dynamic partition manager is deployed at a PL end, a DDR3 public data area is dynamically divided into a plurality of partitions in real time according to needs, multi-task parallel is achieved, and the real-time performance of the system is improved; thirdly, the read-write operation on the DDR3 in each control period is split into a plurality of state machines through precise scheduling of the state machines, the state machines are combined into a state loop to be mounted to an AXI4 bus, it is ensured that key tasks are completed on time, and the certainty of the system is improved; fourthly, the size and the number of partitions in the DDR3 are dynamically adjusted through a dynamic partition manager, and the storage efficiency is improved.

Owner:RENOVATE OPTOELECTRONICS TECH(SHENZHEN) CO LTD
Network pipeline abstraction layer (NAPL) split interfaces
Technologies for creating an optimized and accelerated network pipeline using a network pipeline abstraction layer (NPAL) for split interfaces are described. A DPU includes a physical port configured to couple to a breakout cable that physically couples to a set of a plurality of devices, DPU hardware, and a memory operatively coupled to the DPU hardware. The NPAL supports a plurality of logical split ports, each logical split port corresponding to one of the plurality of devices, wherein the network pipeline comprises a set of tables and logic organized in a specific order to be accelerated by the acceleration hardware engine. The acceleration hardware engine is to process the network traffic data using the network pipeline.

Owner:MELLANOX TECHNOLOGIES LTD(IL)
Data transmission method based on remote direct memory access, computer equipment and medium
The invention relates to the technical field of computers and provides a data transmission method based on remote direct memory access, computer equipment and a medium. The method comprises the following steps: when a sending side sends a plurality of request messages associated with a remote direct memory access transmission request, respectively writing a queue index value of a first queue at a receiving side into respective extension heads of the request messages; on the receiving side, based on the queue index value of the first queue in the extension header of the received request message, the message content is written into the position corresponding to the queue index value in the first queue, and the effective identifier of the corresponding position is set to be effective; and on the receiving side, when the effective identifier of the first position in the first queue is effective, reading contents in the positions with the effective identifiers being effective in the first queue one by one according to the sequence of the first queue, so as to generate a plurality of response messages. Therefore, the problem of out-of-order receiving is solved, and resources are saved.

Owner:ZHUHAI XINGYUN ZHILIAN TECH CO LTD
GPU BOX, server, interconnection system and high-speed interconnection and data interaction method
PendingCN120705096ADigital computer detailsElectric digital data processingComputer architectureData transport
The embodiment of the invention discloses a GPU BOX, a server, an interconnection system and a high-speed interconnection and data interaction method. The GPU BOX high-speed interconnection method is characterized in that the GPU BOX comprises a GPU and a control mainboard, an internal PCIe switch, an internal storage device, a first DMA controller and a system controller are integrated in the control mainboard, and a second DMA controller is integrated in the GPU; the system controller receives the reading instruction and performs data read-write initialization on the first DMA controller and the second DMA controller based on the reading instruction; the first DMA controller after data read-write initialization reads cache data from the internal storage device, and transmits the cache data to the GPU via the internal PCIe switch through the established GDS connection; wherein the GDS connection between the GPU and the internal storage device is established through the system controller, the second DMA controller, the internal PCIe switch and the first DMA controller. According to the method, high-speed direct data transmission of the GPU BOX can be achieved, CPU data transfer is not needed, and the data transmission efficiency is greatly improved.

Owner:BEIJING RONGXIN ZHIYUAN TECHNOLOGY CO LTD
High-speed I / O virtualization server based on FPGA and remote forwarding method
The invention relates to the technical field of computer hardware and network communication, in particular to a high-speed I / O (input / output) virtualization server based on an FPGA (field programmable gate array) and a remote forwarding method.The high-speed I / O virtualization server comprises an FPGA chip, a network processing unit, an I / O protocol processing unit, a protocol conversion and scheduling unit, a time sequence and transaction management unit and a data buffering and flow control unit are integrated in the FPGA chip; the optical fiber Ethernet interface module comprises a physical layer interface and an MAC layer processing and network configuration interface; the local I / O interface module comprises a USB interface circuit, a serial port interface circuit, a PCIe interface circuit and an interface expansion connector; the power supply and monitoring module comprises a multi-path power supply management system, a state monitoring and diagnosis system and an LED indication system; according to the self-adaptive Baud rate detection circuit, the Baud rate can be accurately locked under the condition that data with less than two characters is received, the number of data bits, the type of a check bit and the length of a stop bit are automatically identified, and compared with a traditional microcontroller scheme, the self-adaptive Baud rate detection circuit has higher precision and higher detection speed.

Owner:梁琦
Triple-modular redundancy data synchronization method and device based on FPGA
The invention relates to the technical field of data processing, in particular to a triple modular redundancy data synchronization method and device based on an FPGA. The method comprises the following steps: performing three-mode synchronization based on a periodic synchronization signal generated by an FPGA (Field Programmable Gate Array); when data interaction needs to be carried out among the three modes, non-periodic data handshake is carried out among the three modes by adopting an FPGA (Field Programmable Gate Array); and after the data handshake succeeds, performing data interaction among the three modes by adopting the FPGA. According to the invention, on the basis of triple-modular redundancy periodic synchronization, a data handshake function is added before data interaction among the three moduli at any moment is executed, synchronization errors caused by hardware of a triple-modular redundancy system or other reasons are reduced, and triple-modular redundancy synchronization is realized more accurately. Meanwhile, periodic synchronization, data handshake and data interaction are realized by adopting an FPGA (Field Programmable Gate Array), and the time delay is further reduced on the basis of triple modular redundancy architecture synchronization, so that the synchronization precision of the synchronization method reaches + / -20ns.

Owner:BEIJING DAHANG YUEQIAN TECHNOLOGY CO LTD
Modern global navigation satellite system receiver
The invention relates to a modernized global navigation satellite system receiver. GNSS receivers and systems within such receivers use improvements to reduce memory usage while providing sufficient processing resources to directly receive, capture and track E5 band GNSS signals (in one embodiment, not attempting to receive L1 GNSS signals). Other aspects are also described.

Owner:YIHANG CO LTD
Data transmission method based on UCIe, artificial intelligence chip, medium and electronic device
The invention provides a UCIe-based data transmission method, an artificial intelligence chip, a medium and an electronic device. The UCIe-based data transmission method comprises the following steps of: communicating with a module partner end of a second core grain through a module end of a first core grain; when the module partner end receives the retraining trigger signal, resetting a circuit of the module partner end, and sending a retraining request signal to the module partner end through the module end; when the module partner end receives the retraining request signal, replying a retraining response signal to the module end through the module partner end; and when the module end receives the retraining response signal, enabling the module end to enter a retraining state. According to the UCIe-based data transmission method, the artificial intelligence chip, the medium and the electronic device, good data transmission quality can be provided.

Owner:SHANGHAI BIREN TECH CO LTD
USB-A interface and serial port dynamic switching and protection system based on analog switch
ActiveCN120803998AEnergy efficient computingElectric digital data processingHandoff controlData transmission
The invention relates to the technical field of communication, in particular to a USB-A interface and serial port dynamic switching and protection system based on an analog switch. Comprising a main control unit, the main control unit is used for planning dynamic switching and conflict coordination of a USB-A interface and a serial port as a whole, generating a conflict-free channel switching control instruction by integrating a dynamic priority scheduling algorithm and combining a USB data transmission real-time load, a serial port communication request emergency degree and a device historical interaction record fed back by a state detection unit, and sending the conflict-free channel switching control instruction to the state detection unit; the analog switch unit is driven to complete channel gating; an analog switch unit; a grading protection unit; a protocol adaptation unit; and a state detection unit. Priority scheduling is carried out by means of the main control unit in combination with multi-dimensional parameters such as the transmission load of the USB-A interface and the communication emergency degree of the serial port UART, communication channels of the USB-A interface and the serial port can be flexibly switched, the flexibility and adaptability of interface switching are enhanced, and the problem of switching limitation caused by a single triggering condition is solved.

Owner:BEIJING SATECOMM SCI & TECH CO LTD
Satellite solid storage and data transmission integrated system
PendingCN120763092ARadio transmissionArchitecture with single central processing unitComputer hardwareRemote control
The invention relates to the technical field of spacecrafts, and discloses a satellite solid storage and data transmission integrated system which comprises a data transmission solid storage master control FPGA, an FPGA loading and refreshing system and an ARM system, the FPGA loading and refreshing system and the ARM system are connected with the data transmission solid storage master control FPGA, the ARM system is connected with the FPGA loading and refreshing system, and meanwhile the ARM system is connected with satellite service through a CAN bus; the FPGA loads and refreshes a system, and periodically refreshes rewrite configuration or system reset rewrite configuration to ensure normal operation of the configuration; and the ARM system forwards the satellite remote control instruction received from the CAN bus to the data transmission solid memory master control FPGA and the loading FPGA through the SPI bus. According to the technical scheme, storage and transmission are efficiently integrated, the data storage rate, the data transmission rate and the data transmission capacity are improved, the system architecture is simplified, flexible selection of a data transmission modulation mode and the data transmission rate is achieved, the system reliability is improved, data access and transmission can be more accurately regulated and controlled through control and management of the FPGA, and the system reliability is improved. And the system instability caused by hardware faults or interface problems is effectively reduced.

Owner:SHANGHAI JINGJI COMM TECH CO LTD
DMA (Direct Memory Access) communication device for computing network integration computing architecture and working method of DMA communication device
ActiveCN120705097AArchitecture with single central processing unitEnergy efficient computingComputer architecturePerformance computing
The invention discloses a direct memory access (DMA) communication device for a computing network convergence computing architecture and a working method of the DMA communication device. The DMA communication device comprises a DMA transaction processing module and a protocol conversion module; the DMA transaction processing module is used for analyzing related DMA read-write requests, realizing processing of the DMA read-write requests and receiving of response data of the DMA read requests and completing processing of interrupt requests at the same time, and the protocol conversion module is used for completing conversion of read-write requests between a DMA interface and an AXI interface and mapping of response states. The invention aims to realize efficient protocol conversion between AXI and DMA interfaces, avoid the problem of DMA read request starvation caused by resource competition and ensure the consistency of DMA data access so as to improve the performance of an accelerator in high-performance calculation and artificial intelligence application, reduce transmission delay and improve data transmission bandwidth and energy efficiency.

Owner:NAT UNIV OF DEFENSE TECH
GPU cluster connection method and device, switch and storage medium
The invention provides a GPU cluster connection method and device, a switch and a storage medium, relates to the technical field of communication, and is used for solving the problems that a GPU cluster of a single-layer fat tree architecture is relatively small in scale and a GPU cluster of a two-layer fat tree architecture is relatively low in efficiency in related technologies. The GPU cluster connection method comprises the steps that Leaf switches with the same serial number of different server clusters are interconnected, and each server cluster comprises a plurality of Leaf switches and a plurality of servers; each server comprises a plurality of graphic processing units (GPUs); and each switch is in communication connection with the GPU in the server cluster. According to the method, a GPU cluster with a larger scale and higher efficiency can be constructed in a transverse expansion mode.


Owner:CHINA UNITED NETWORK COMM GRP CO LTD +1
Semiconductor device for changing link speed and link width of pcie link and operating method thereof
Provided are a semiconductor device for changing a link speed and a link width of a peripheral component interconnect express (PCIe) link and an operating method thereof. The semiconductor device includes the PCIe link including a plurality of lanes, and a controller configured to transceive a data link layer packet (DLLP) including a number of times of transition and a maximum number of times of transition from an L0 state to an L0p state through the PCIe link, based on a first bit error rate (BER) of a data packet received through the PCIe link and a first criterion value in the L0 state, and determine whether to perform at least one of a link speed changing operation performed in a recovery state, or a link width changing operation performed in the L0p state, based on the number of times of transition and the maximum number of times of transition.

Owner:SAMSUNG ELECTRONICS CO LTD
Read transmission bridging device and method for AXI main equipment and CHI request node
According to the read transmission bridging device and method for the AXI master device and the CHI request node, the master device which does not support cache consistency can be interconnected with a CHI bus to perform read transmission and maintain the cache consistency and address allocation of the whole system under the condition that the design is not modified, and the device has good compatibility, conforms to a standard AXI4 protocol and a standard CHI protocol, and is convenient to use. And the device maintains the cache consistency in the system, ensures the data consistency when the master device accesses the shared data, and avoids errors caused by non-updating of the cache or conflicts. According to the read transmission bridging device of the AXI master device and the CHI request node, the AXI master device is connected to the request node of a CHI bus, a central processing unit (CPU) is connected to the request node of the CHI bus, and an external device and a memory are connected to a completion node of the CHI bus.

Owner:EHIWAY MICROELECTRONIC SCI & TECH (SUZHOU) CO LTD
Low-bit-width high-energy-efficiency floating point storage and calculation integrated circuit based on partial pre-alignment architecture
PendingCN121597629AArchitecture with single central processing unitEnergy efficient computingMultiplexerParallel computing
The invention belongs to the technical field of storage and calculation integration, and particularly relates to a low-bit-width and high-energy-efficiency floating point storage and calculation integrated circuit based on a partial pre-alignment framework. The circuit comprises a memory array, a pre-calculation unit, an adder tree, a configurable arithmetic unit and a normalization unit, and supports mixed precision operation of FP8MACFP4 and FP8MACFP8. The method is characterized in that a partial pre-alignment strategy dominated by an activation value is adopted, the maximum index of the activation value is dynamically counted, the mantissa of the maximum index is aligned, and multiple partial pre-alignment intermediate results are pre-calculated and latched for reuse; in combination with a customized lookup table and a multiplexer, a pre-calculation result is directly selected to replace real-time multiplication and displacement; and through the reconfigurable hardware, the FP8MACFP8 high-precision operation is realized by utilizing the FP8MACFP4 unit combination. According to the method, complete online floating point multiplication and addition operation is realized, and excellent energy efficiency ratio and operation speed are obtained while high precision is kept.

Owner:FUDAN UNIVERSITY
Storage and calculation integrated chip architecture, chip stacking and packaging structure and terminal equipment
PendingCN121009055AArchitecture with single central processing unitEnergy efficient computingComputer architectureTerminal equipment
According to the storage and calculation integrated chip architecture, the chip stacking packaging structure and the terminal equipment, physical tight coupling of storage and calculation is realized through the 3D stacking design of the first storage unit and the logic calculation unit, the problem of physical separation of traditional storage and calculation is solved, the data carrying distance and the cross-chip communication overhead are remarkably reduced, and the communication efficiency is improved. And the chip area and the packaging process complexity are reduced, and the application scenarios of end-side artificial intelligence reasoning and mass data reading and writing are supported. According to the storage and calculation integrated chip architecture, the first storage unit and the logic calculation unit are directly interconnected through the vertical interconnection technology, the data access delay is reduced, the requirement of end side equipment for low delay is met, and the energy efficiency ratio of the storage and calculation integrated chip architecture is remarkably reduced.

Owner:SHANGHAI GUANGYU XINCHEN TECHNOLOGY CO LTD
Adaptive dynamic routing method and system for NoC (Network on Chip)
The invention discloses a self-adaptive dynamic routing method and system for an NoC (Network on Chip), and relates to the technical field of routing management. Comprising the steps that the local congestion degree of each routing node is collected through a communication link, the global congestion degree is generated through a weighted average mechanism, each routing node integrates delay counters in the east direction, the west direction, the south direction and the north direction according to a local router, the delay counters are used for monitoring the time interval when adjacent data packets leave a buffer area in real time, and the global congestion degree is generated; taking a time interval of leaving a buffer area of adjacent data packets as output delay, spreading the output delay to neighbor routing nodes, calculating local congestion degree and global congestion degree of the routing nodes, generating all possible shortest paths and a candidate direction set corresponding to output directions according to addresses of a source routing node and a destination routing node, and sending the candidate direction set to the destination routing node; screening an optimal path through the local congestion degree and the global congestion degree in sequence; and when a plurality of equivalent paths exist, the routing direction is randomly selected to balance the network load.

Owner:SHANDONG INSPUR SCI RES INST CO LTD
Sixty gigahertz multiple input multiple output transceiver
An example system-on-chip (SoC) device for a communication system includes a peripheral component interconnect express (PCIe) interface configured to receive data from a backhaul field programmable gate array (FPGA) of the communication system, and a producer port linked with a consumer port through direct memory access (DMA). Data received by the PCIe interface is assigned to the producer port. The device includes dual hardware media access controls (MACs) configured to consume the data assigned to the producer port, and at least one processor configured to supply the data to a wireless interface for transmission to another wireless communication device of the communication system at a frequency of at least sixty Gigahertz.

Owner:TENSORCOM INC +1
GPUBox hardware decoupling system based on Retimer card and PCIeSwitch chip
PendingCN121144242AImage memory managementMultiple digital computer combinationsVideo memoryComputer architecture
The invention discloses a GPU Box hardware decoupling system based on a Retimer card and a PCIe Switch chip, and belongs to the technical field of computer hardware architecture and high-speed interconnection. According to the system, a Retimer card and a PCIe Switch chip are integrated in an independent GPU Box, and a decoupling link of a CPU server and a GPU acceleration card is constructed; the Retimer card realizes 30-meter long-distance PCIe signal transmission and breaks through physical distance limitation; the PCIe Switch chip pools GPU resources through a dynamic routing and MRIOV technology, supports flexible allocation of computing power by multiple servers, and realizes Peer-to-Peer direct connection communication between GPUs. Aiming at a large model reasoning scene, the system optimizes KV cache bandwidth allocation and video memory and memory cooperative scheduling, so that the 100B parameter model reasoning throughput is greatly improved; and meanwhile, the usability of the system is greatly improved through fault isolation and hot plug design. According to the method, the problems of physical binding of the CPU and the GPU, limited transmission distance, rigid resource allocation and the like in a traditional architecture are solved, and the method is suitable for large-scale AI calculation and distributed GPU cluster deployment.

Owner:HEFEI FENGZHIYI SEMICON CO LTD
IO pin multiplexing circuit, control method, chip and electronic equipment
PendingCN120934501ALogic circuits coupling/interface using field-effect transistorsElectric digital data processingComputer hardwareMultiplexing
The invention discloses an IO pin multiplexing circuit, a control method, a chip and electronic equipment, and the circuit comprises a gating module which is connected with a chip core and is used for transmitting a first enabling signal and / or a second enabling signal according to an on-chip control signal; the control word coding module is respectively connected with the gating module and the off-chip, and is used for enabling an IO pin to work in a control word coding mode according to the first enable signal; the digital signal input module is respectively connected with the gating module and is used for enabling an IO pin to work in a digital signal input mode according to a second enable signal; and the ESD module is connected with the digital signal input module and the control word coding module and is used for providing electrostatic protection. According to the invention, a pin function multiplexing technology is adopted, a control word writing function can be realized when the chip is just started through an enable signal switching function, a digital signal transmission function can be realized when the chip normally runs, the hardware cost is reduced, and the consumption of pin resources is reduced.

Owner:GUANGZHOU RUNXIN INFORMATION TECH CO LTD
Coordinating processing tasks between one-dimensional processing engines and two-dimensional processing engines
PendingUS20260038079A1Digital computer detailsCharacter and pattern recognitionComputer architectureProcessing element
In various examples, systems and methods are disclosed relating to coordinating and synchronizing the actions of different types of processors with low latency. Different types of processors may perform better at different types of tasks. By coordinating the processing of a one-dimensional processor such as a vector processing unit (VPU) and the processing of a two-dimensional processor such as a pixel processing engine (PPE), an overall speed of task completion can be improved.

Owner:NVIDIA CORP
High-speed data communication method and system based on synchronous triggering and parallel transmission
The invention relates to the technical field of embedded systems, and provides a high-speed data communication method and system based on synchronous triggering and parallel transmission. The method comprises the following steps: configuring a master timer, a plurality of slave timers and a corresponding number of DMA (Direct Memory Access) channels in an MCU (Microprogrammed Control Unit), and setting a data buffer area corresponding to each DMA channel; configuring a main timer to generate a synchronous trigger signal with a target sampling rate, and driving all slave timers to generate synchronous update events with sequentially delayed phases as parallel DMA trigger signals; the signals are utilized to control each DMA channel to alternately transmit external equipment data to a corresponding area of the buffer area in parallel; and finally, performing time sequence recombination on the multi-region data according to the phase sequence of the update event, and restoring a complete sampling sequence. The rate bottleneck of a single DMA channel is broken through, the aggregation bandwidth of multiple DMA channels is utilized, high-sampling-rate data collection far exceeding the single DMA limit is achieved under limited hardware resources, and the system data throughput rate is effectively improved.

Owner:SHENZHEN PHOENIX TECH CO LTD
Zynq UltraScale + MPSoCs-based high-speed data processing and exchanging method and system
The invention discloses a high-speed data processing and exchanging method and system based on Zynq UltraScale + MPSoCs, and belongs to the technical field of data processing.The method comprises the steps that nanosecond-level synchronous pulses are generated through a PL end of Zynq, initial multi-modal data are collected, the transmission rate and integrity are analyzed through a double-SERDES controller of the PL end, and a dynamic data processing matrix is constructed; pL and PS end data flow distribution is simulated and optimized through a preset multi-data granularity scale, and an exchange instruction set is generated; in combination with an on-chip bus topology, a first data exchange path is formed through DMA-OCM interaction and hardware accelerator adaptation, and a second data exchange path is obtained by adjusting sub-channel allocation and bus priority; and the operation state parameters of the second data exchange path are written back to the data frame state attribute bar corresponding to the dynamic data processing matrix in real time, so that efficient processing and dynamic optimization of the multi-modal data are realized, and the system stability and the transmission efficiency are improved.

Owner:SHANGHAI HENGZE FUHUI INTELLIGENT TECHNOLOGY CO LTD
System and Method for Energy-Aware Distributed Edge-Cloud Homomorphic Compression Using Adaptive Neural Networks
A distributed system and method for compressing and restoring data across edge computing devices and cloud infrastructure is disclosed. The system dynamically adjusts compression based on available computing resources, network conditions, and now energy constraints. Edge devices monitor power consumption and battery levels, optimizing compression parameters to extend battery life while maintaining data quality. A workload scheduler prioritizes tasks based on energy availability, offloading intensive processing to cloud infrastructure when necessary. The system utilizes an energy-aware coordination layer to balance workloads across multiple devices, ensuring efficient data flow and long-term operational stability. Homomorphic operations allow secure distributed processing on compressed data, while an adaptive neural upsampler enhances reconstructed outputs. By integrating energy optimization, the system improves performance and longevity of edge devices in power-limited environments.

Owner:ATOMBEAM TECH INC
Method and apparatus for cache tiering
A method for use in a storage processor, comprising: receiving an I / O request that is associated with a logical block address; allocating a cache slot that corresponds to the logical block address, wherein allocating the cache slot includes: identifying a type of memory that is required to host the cache slot by using one or more configuration settings that are associated with the cache slot, identifying a cache slot that is both available and hosted in the identified type of memory, and assigning the identified cache slot to the logical block address; and executing the I / O request by using the allocated cache slot, wherein using the allocated cache slot includes identifying a memory address that is associated with the cache slot and executing at least one direct memory access (DMA) command that is associated with the allocated cache slot.

Owner:DELL PROD LP