
Patents
Literature
11431results about "Memory systems" patented technology
Efficacy Topic
Property
Owner
Technical Advancement
Application Domain
Technology Topic
Technology Field Word
Patent Country/Region
Patent Type
Patent Status
Application Year
Inventor
Advanced model management platform for optimizing and securing ai systems including large language models
PendingUS20250259075A1Memory architecture accessing/allocationBiological modelsModel managementRobustification
An advanced model management platform for optimizing and securing generative artificial intelligence systems such as large language models (LLMs) and diffusion models. The platform incorporates various techniques to address the limitations of current generative AI systems, such as hallucination, lack of validation, security vulnerabilities, and inadequate model management. The system employs reinforcement learning algorithms for model optimization, retrieval augmented generation (RAG) for hallucination mitigation, domain-specific validation against expert knowledge, model distillation and similarity scoring for security, adversarial training for robustness, and attention mechanism search and model blending for advanced management and neuro symbolic AI routine combinations. By integrating these techniques, the platform significantly improves the performance, reliability, and security of generative AI across a wide range of tasks and domains leveraging the best elements of symbolic and connectionist techniques alongside automated planning and modeling simulation.

Owner:QOMPLX INC
Method and System for Optimizing Use of Retrieval Augmented Generation Pipelines in Generative Artificial Intelligence Applications
ActiveUS20250190460A1Memory architecture accessing/allocationDigital data information retrievalMultiple contextGenerative process
A method of generating outputs in LLMs including receiving including textual content, defining a context for the documents including identifying a topic or a category, segmenting the textual content into content chunks associated with the topic or category, assigning a tag to each content chunk, identifying selected chunks, adding metadata to the selected chunks indexing the selected chunks, receiving a query, and performing a response generation process including determining if a cache includes information for the query and either retrieving the information from the cache or performing a search of the index to retrieve the information, generating an augmented query by augmenting the query with retrieved information, generating a response from the augmented query, evaluating the response for compliance with criteria, and one of generating a final response and transmitting the final response to the user or performing a fine-tuning process comprising redefining the of the one or more contexts.

Owner:MADISETTI VIJAY
System and Method for Utilizing Available Best Effort Hardware Mechanisms for Supporting Transactional Memory
ActiveUS20090282386A1Reduce difficultyReduce overheadSpecific program execution arrangementsMemory systemsTransactional memoryApplication software
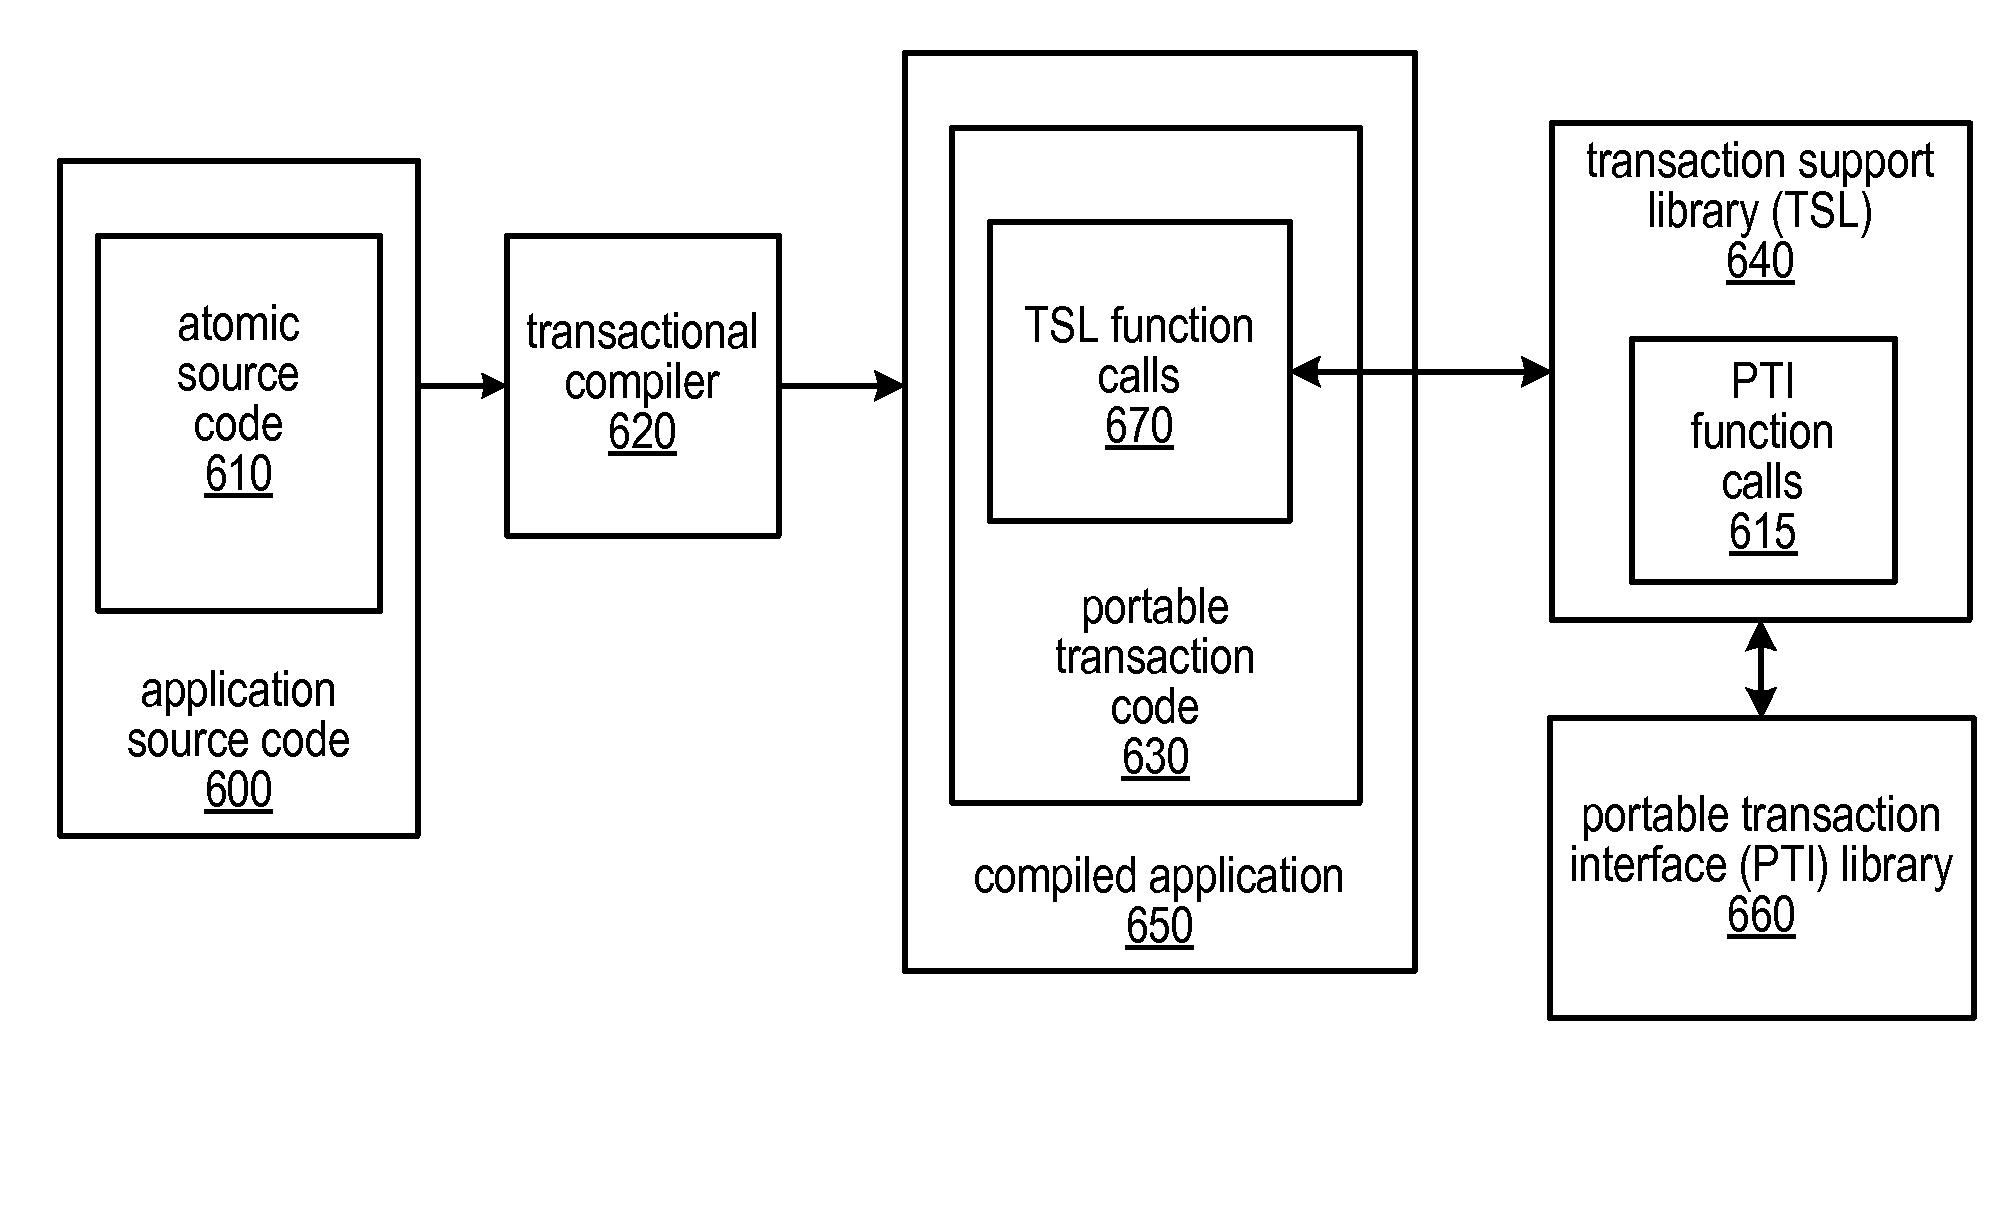
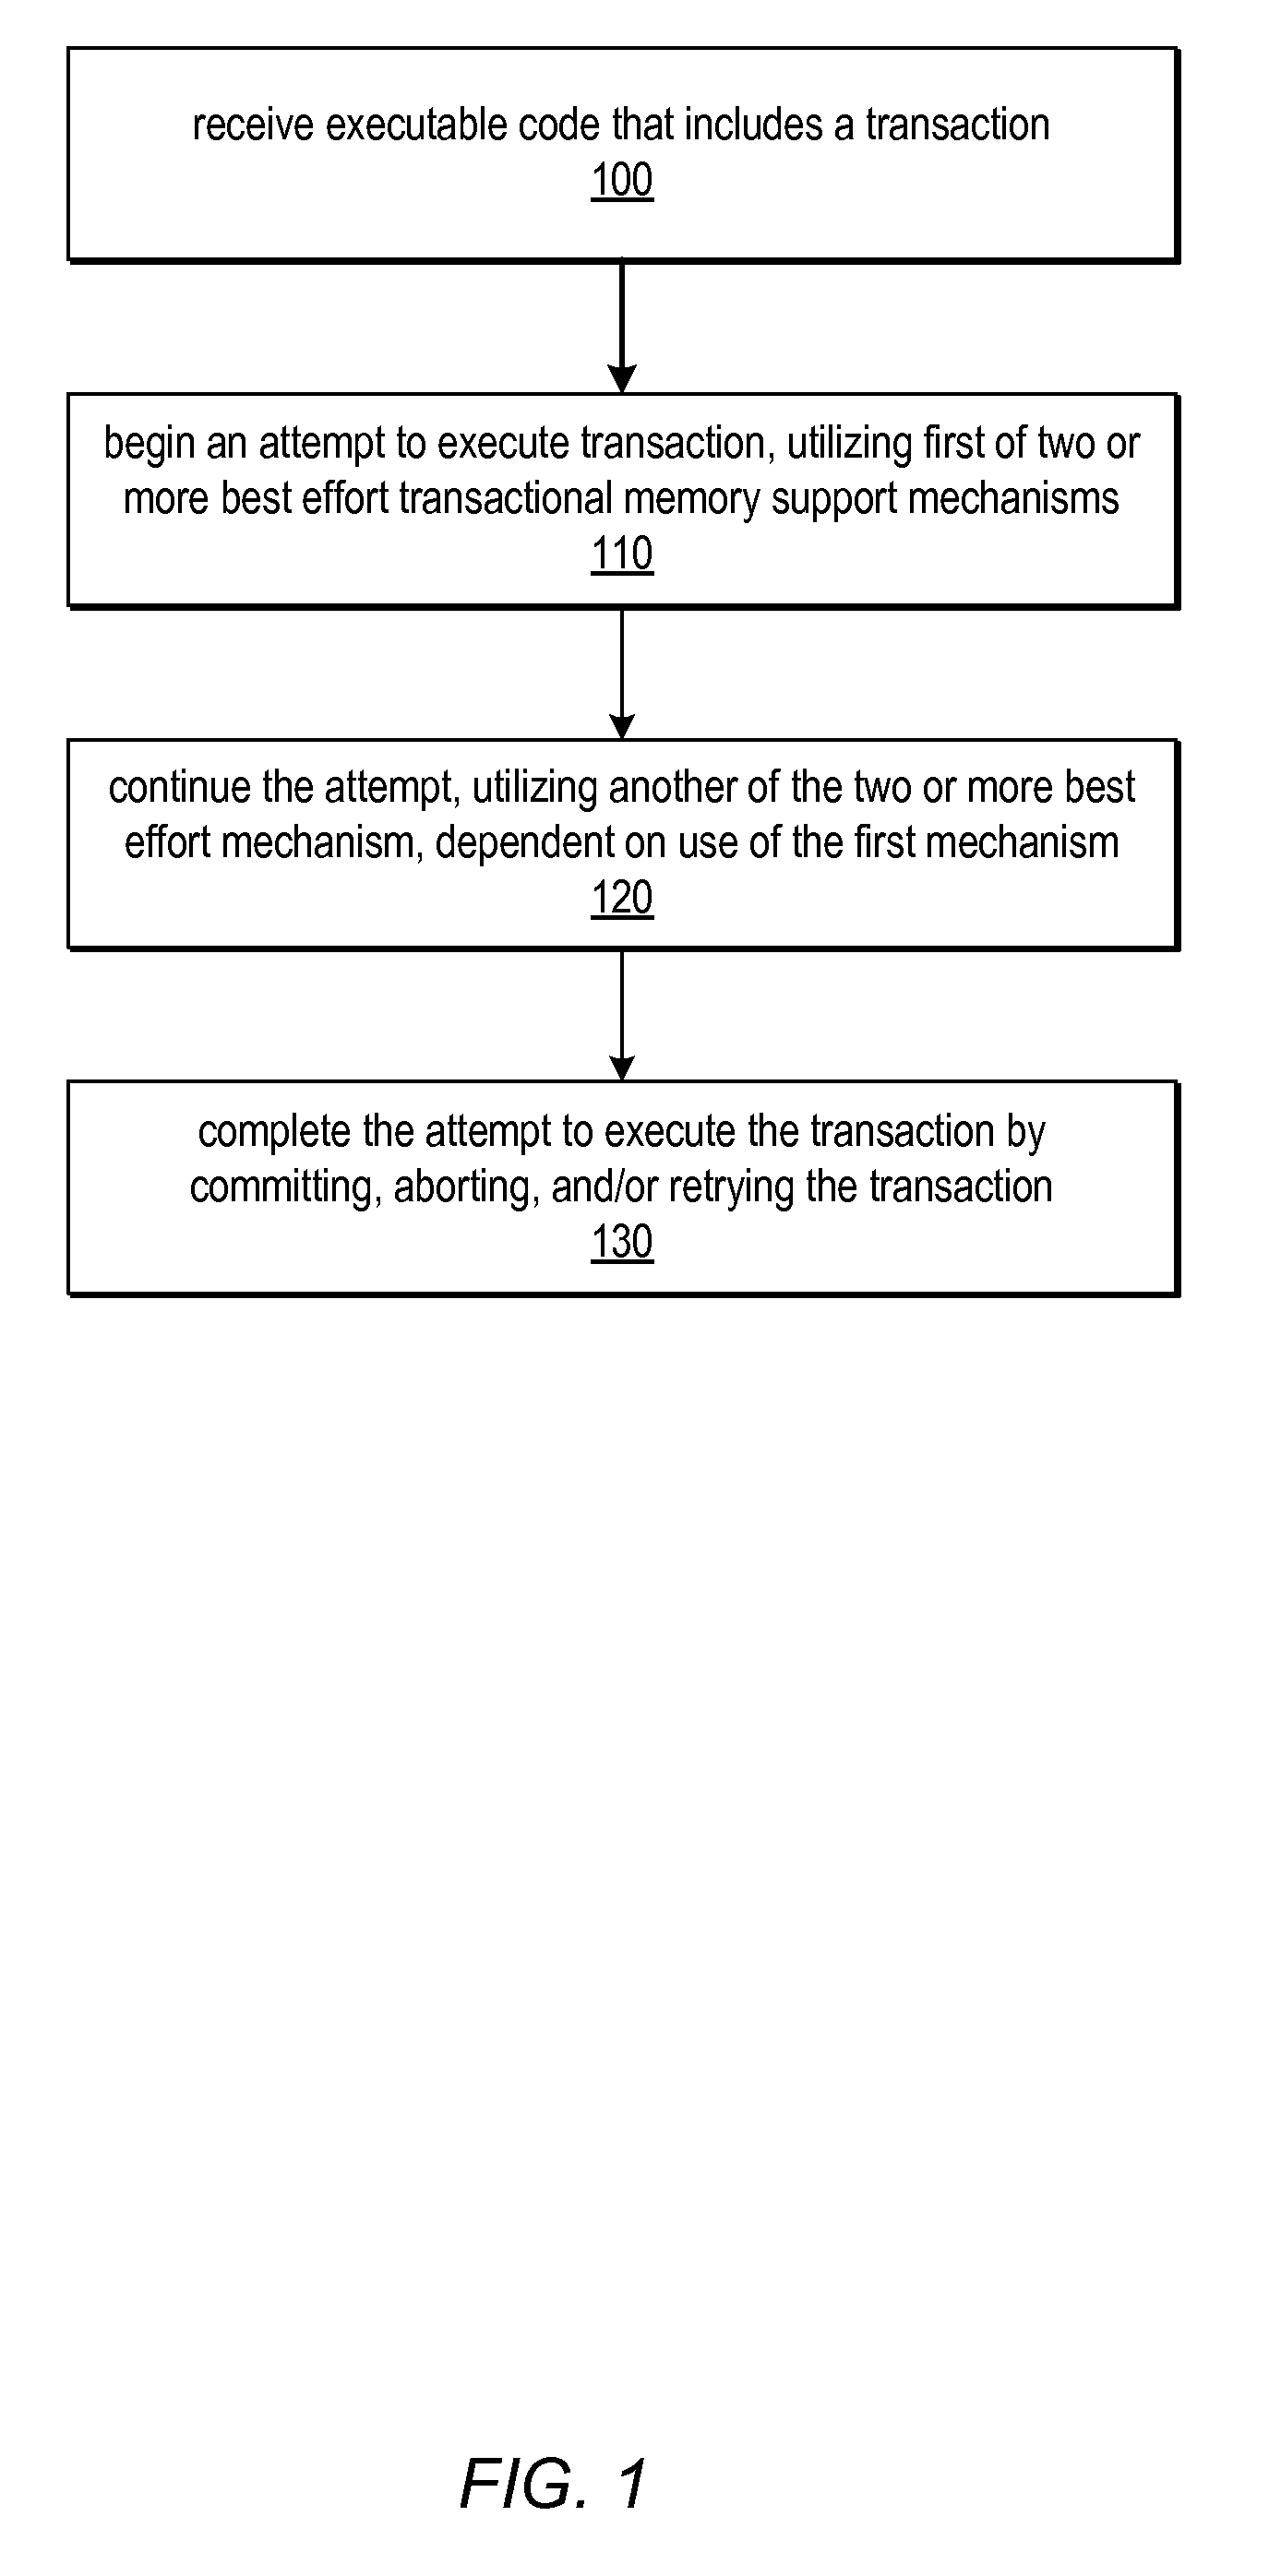
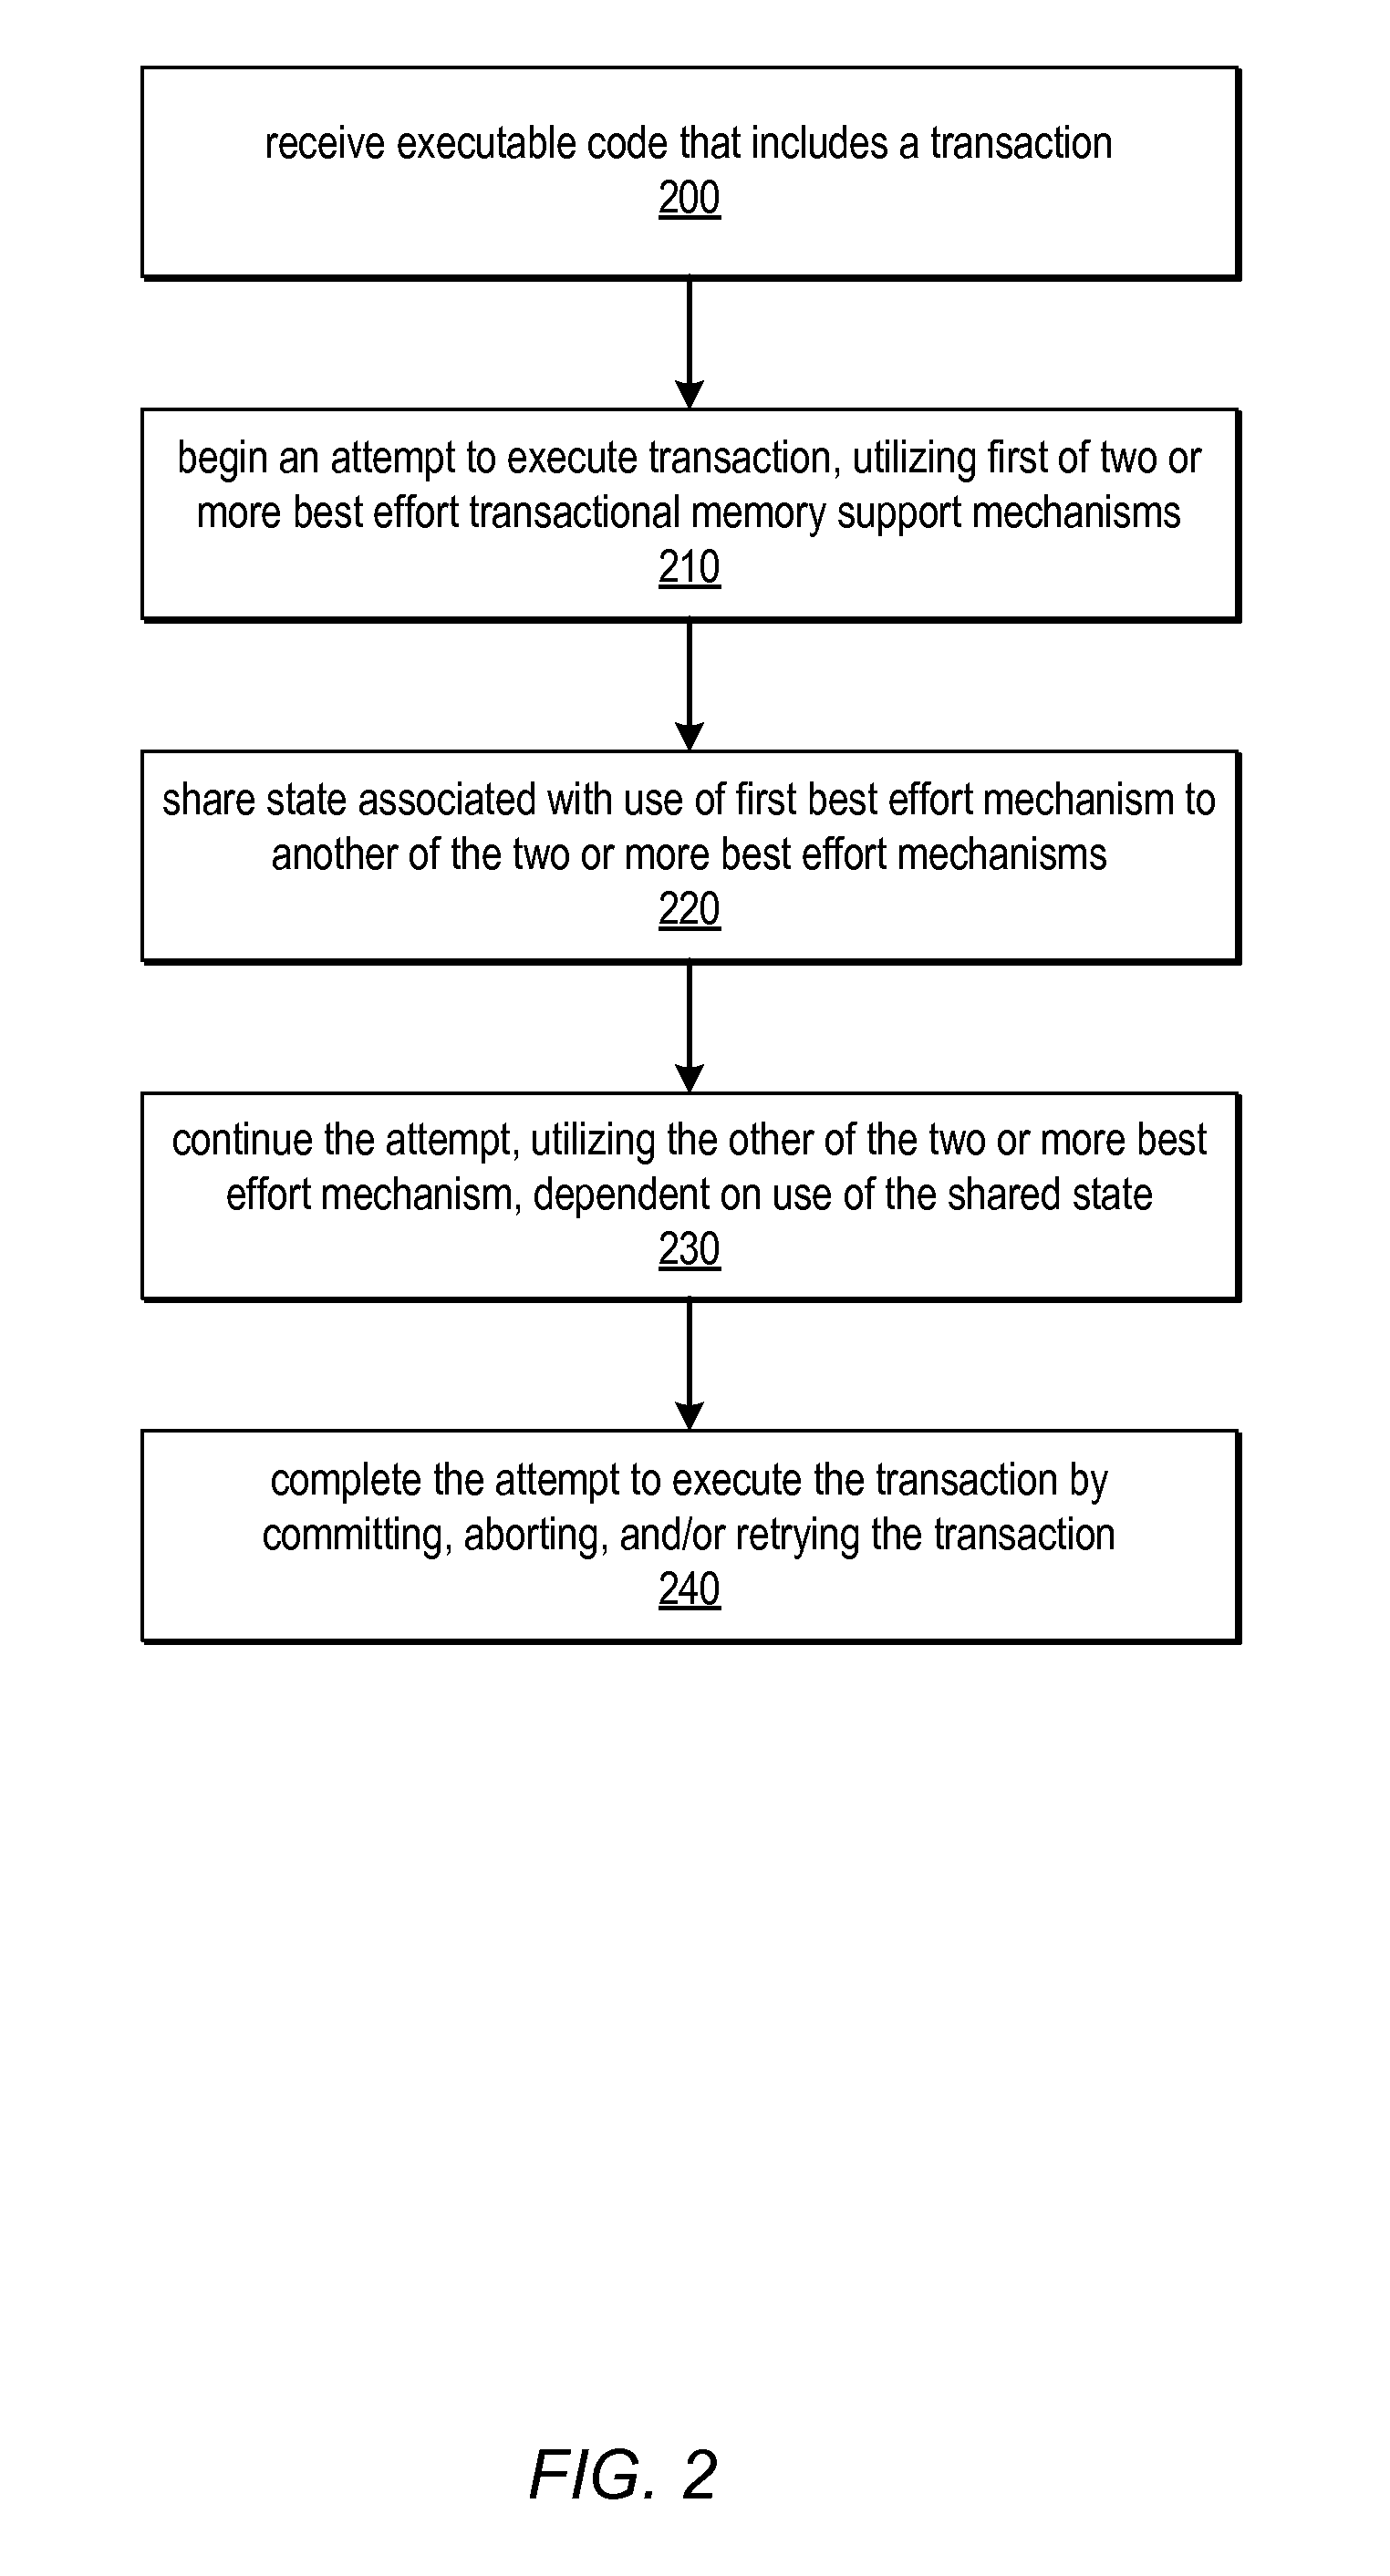
Systems and methods for managing divergence of best effort transactional support mechanisms in various transactional memory implementations using a portable transaction interface are described. This interface may be implemented by various combinations of best effort hardware features, including none at all. Because the features offered by this interface may be best effort, a default (e.g., software) implementation may always be possible without the need for special hardware support. Software may be written to the interface, and may be executable on a variety of platforms, taking advantage of best effort hardware features included on each one, while not depending on any particular mechanism. Multiple implementations of each operation defined by the interface may be included in one or more portable transaction interface libraries. Systems and / or application software may be written as platform-independent and / or portable, and may call functions of these libraries to implement the operations for a targeted execution environment.
Owner:ORACLE INT CORP
Web application internationalization
InactiveUS7784026B1Eliminate needEasy constructionExecution for user interfacesMemory systemsMeta levelWeb page
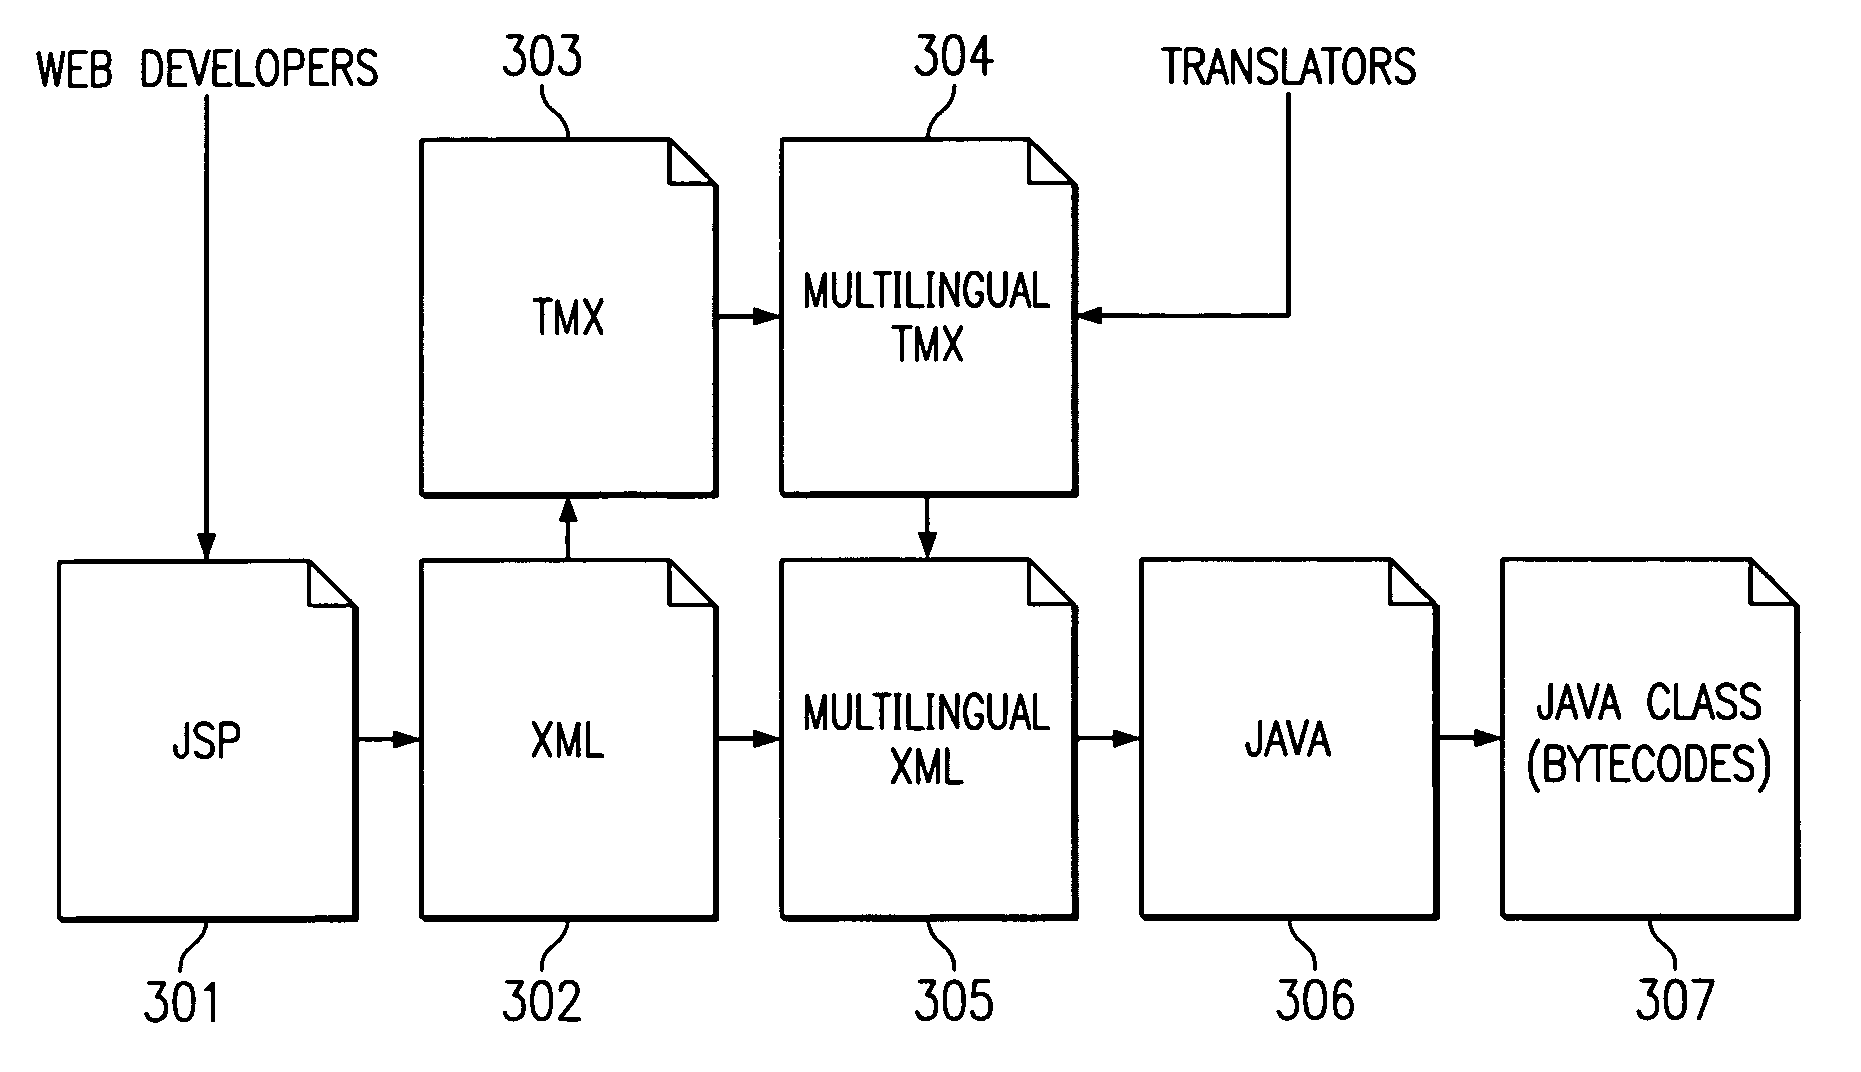
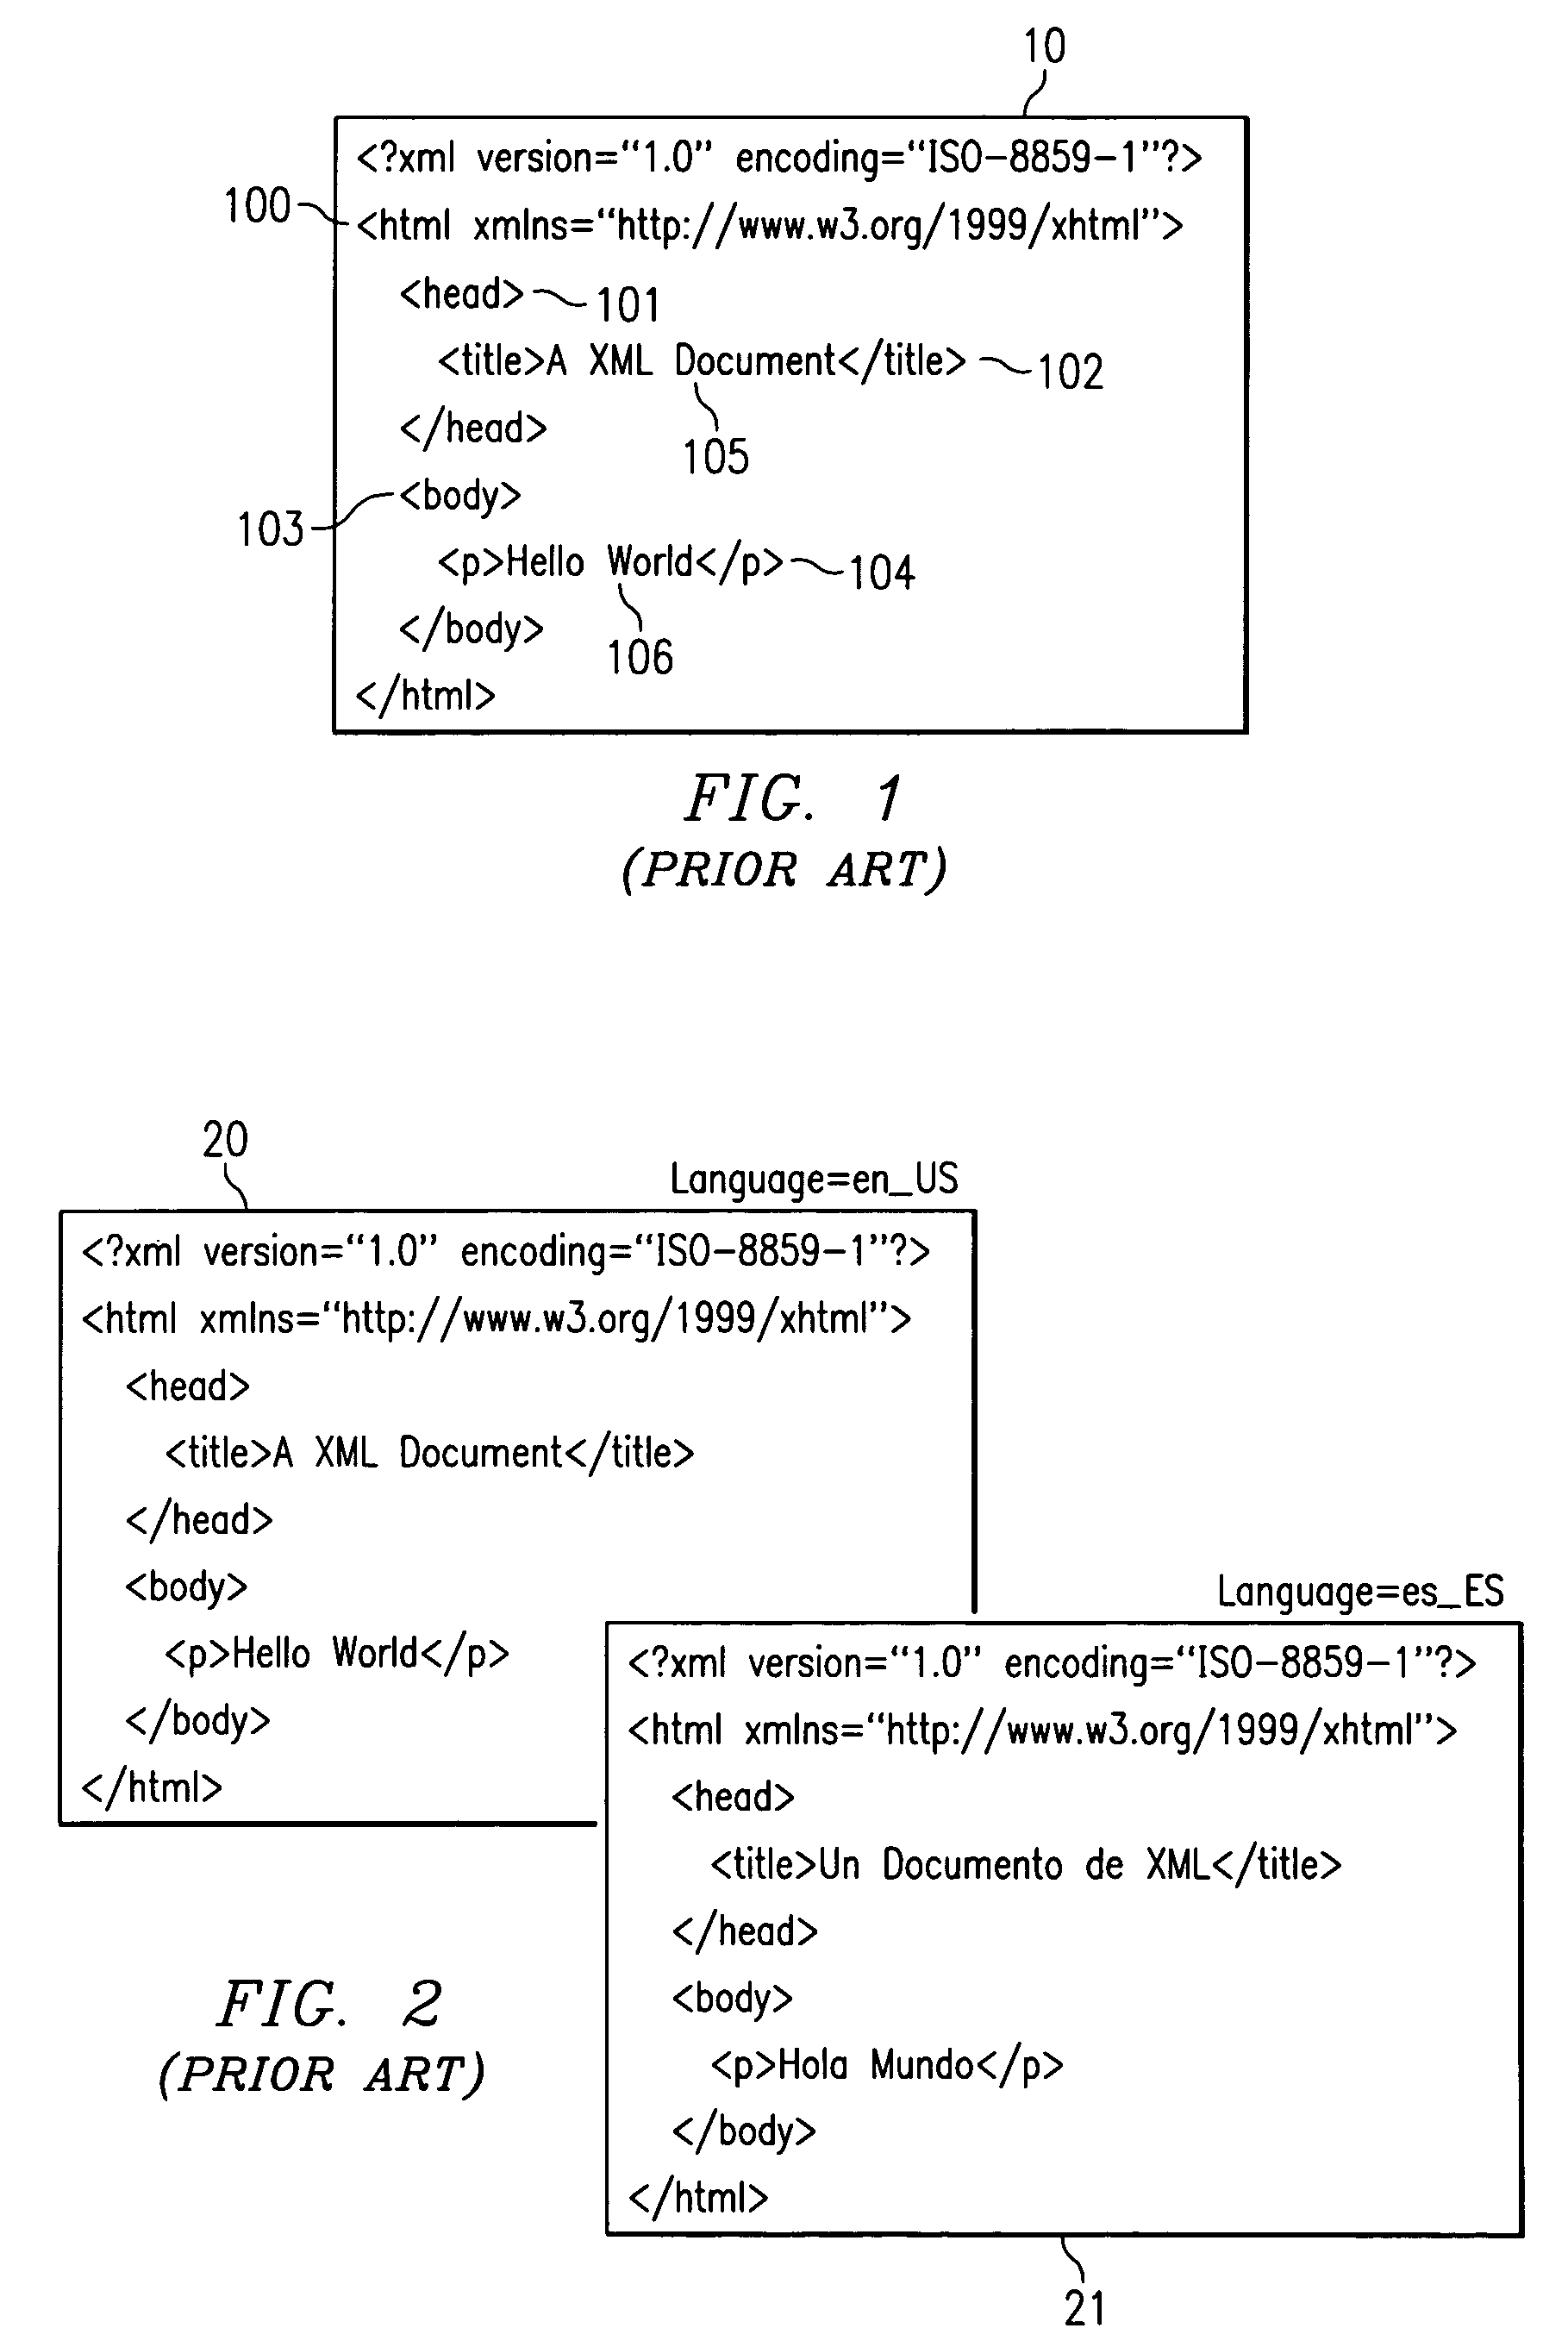
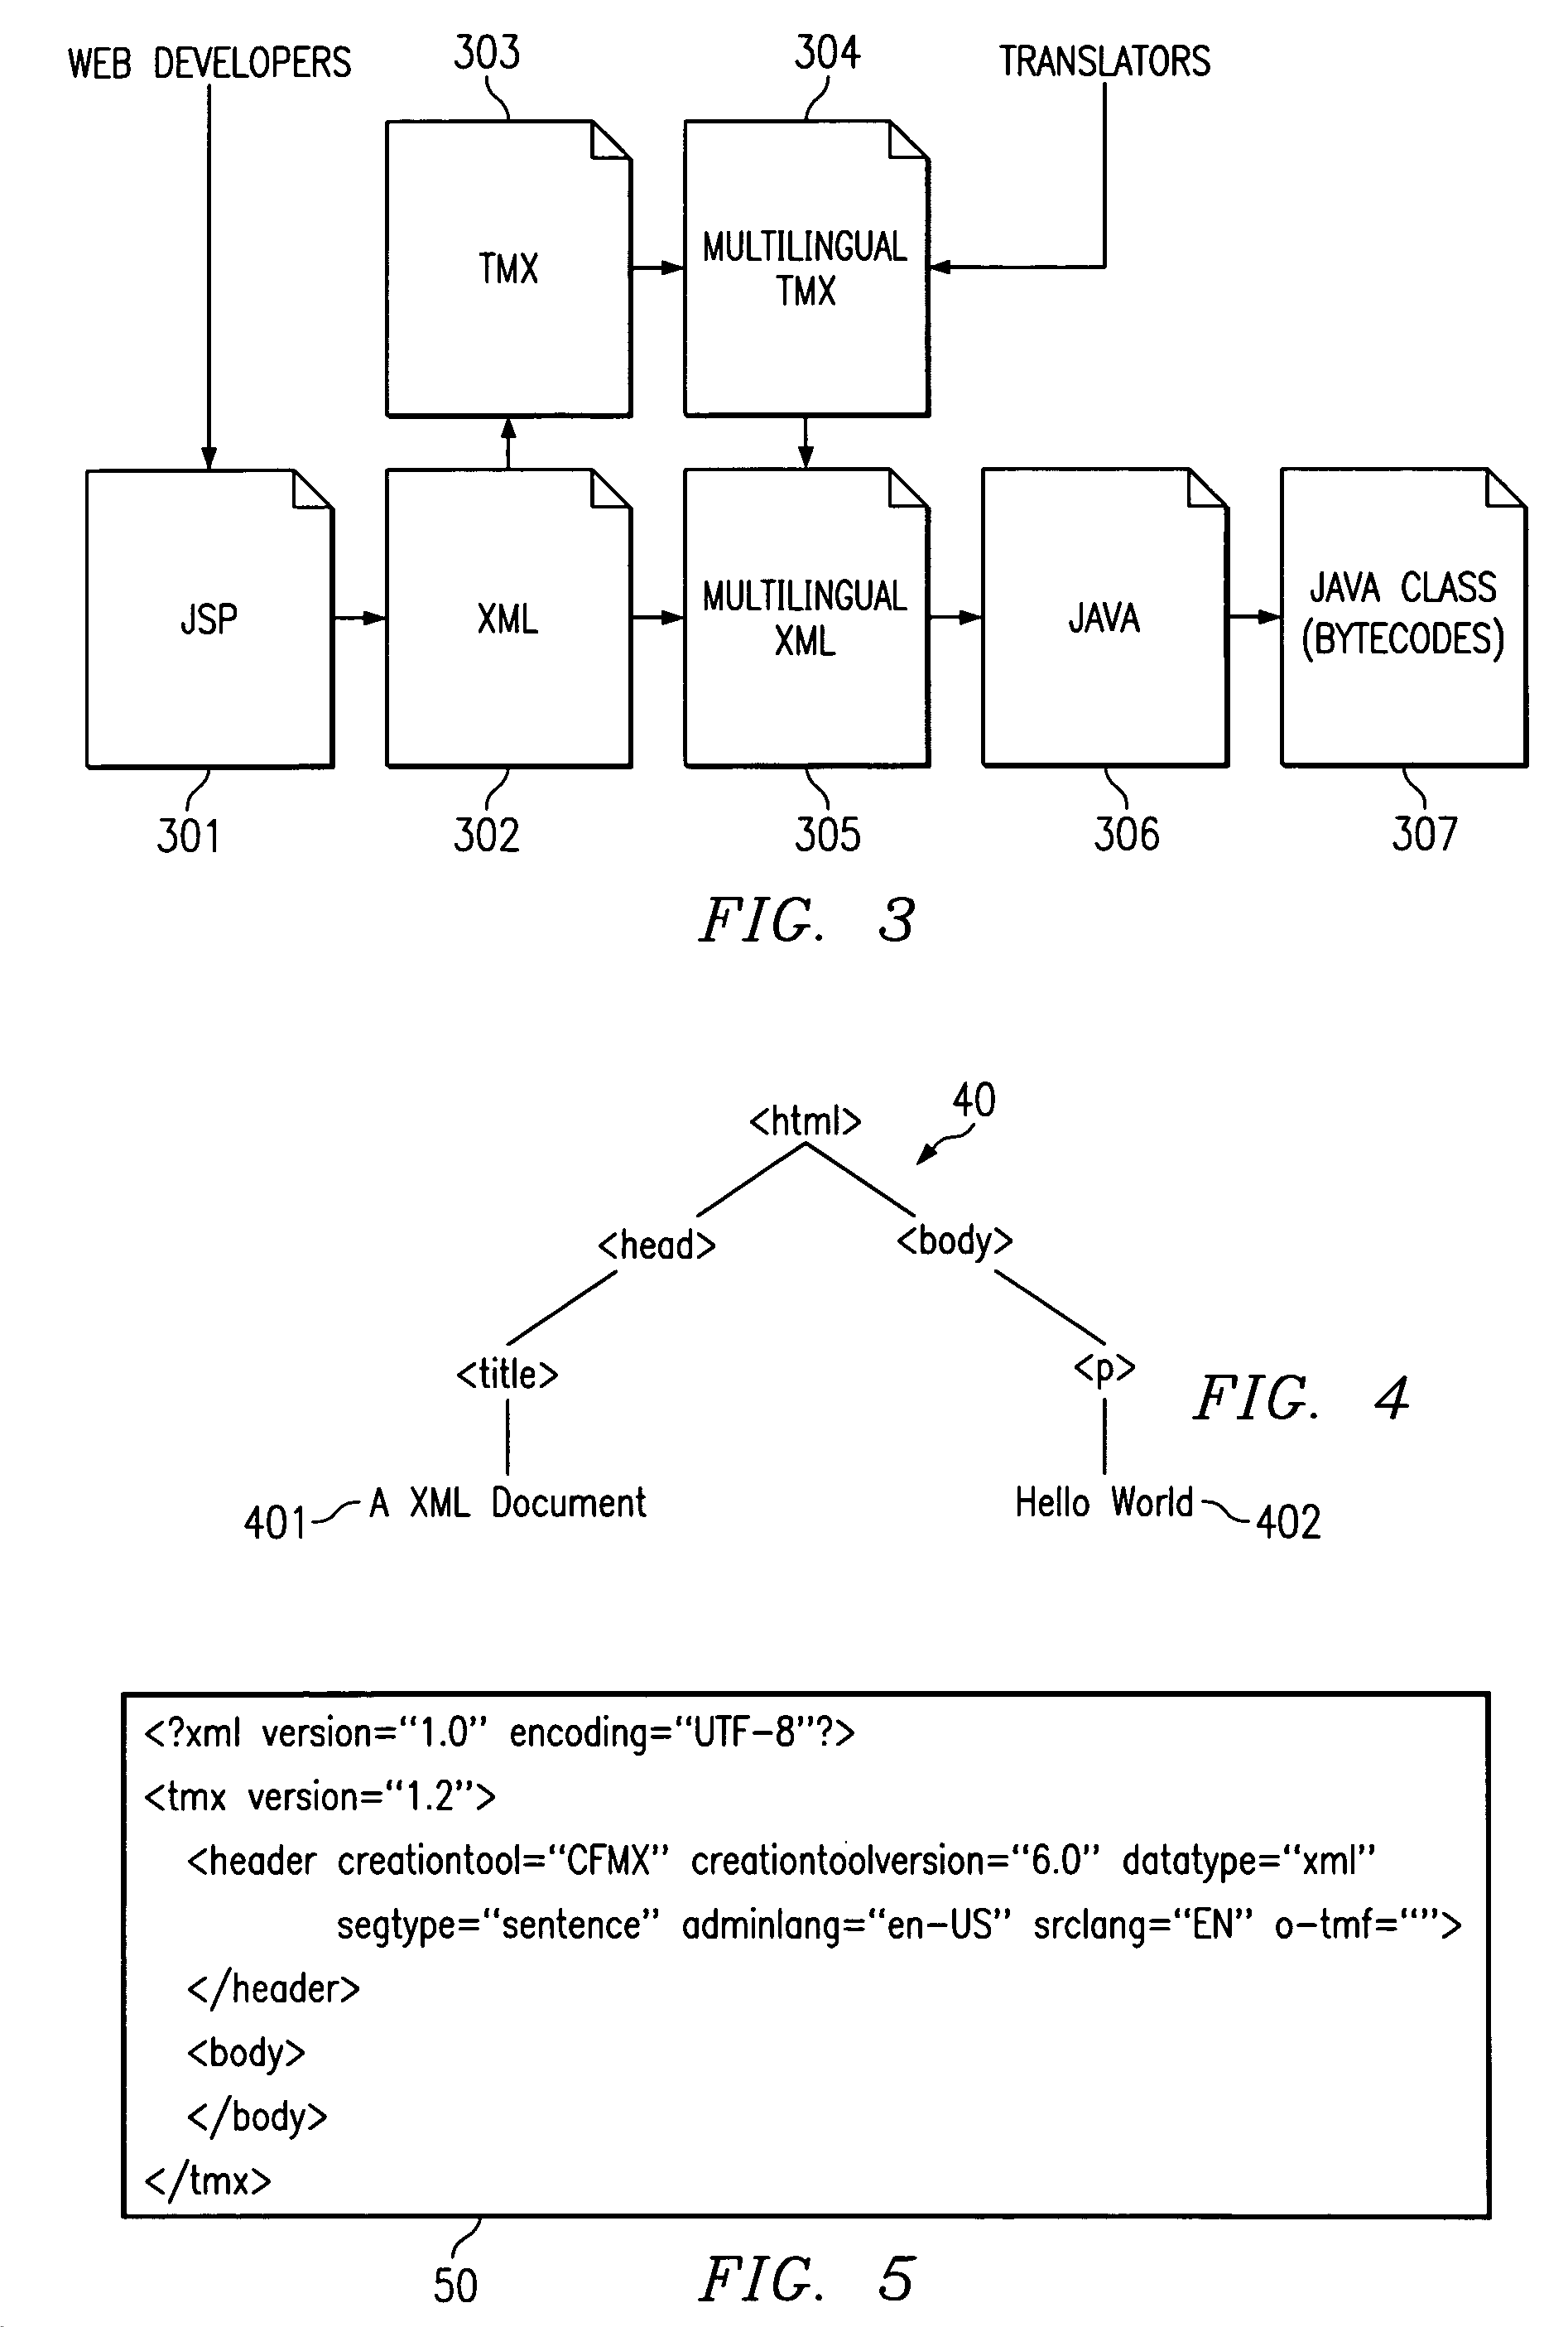
A system and method is described for internationalization of web pages by extracting translatable content from extensible mark-up language (XML), or similar data-centric meta-language representations of web pages or data used to build web pages. The extracted translatable content is stored in a translation task repository (TTR) accessible by the web developer and the translator. The XML representation is then modified to include selection control logic to select the appropriate translations for insertion into the final web page. The translator accesses the TTR to translate the appropriate content and saves the translations back to the TTR associated with the original translatable data. The translations are obtained from the TTR as selection cases for the selection control logic of the XML representation. As the XML is converted into the web source code, the selection logic and translations are embedded therein facilitating building the web site in multiple different languages.
Owner:ADOBE INC
AI Serving Hardware and Software Frontier Enhancements
PendingUS20250390352A1Memory architecture accessing/allocationResource allocationComputer hardwareComputer architecture
A computer system implements a unified framework integrating an adaptive elastic funnel (AEF) with a convergent intelligence fabric (CIF) for multi-agent AI collaboration. The system provides a universal multi-modal key-value subsystem for sharing partial computations, implements hybrid placement strategies for dynamic memory management, and incorporates quantum-resistant secure enclaves. The architecture integrates hardware acceleration through GPU-FPGA hybrid caching and neuromorphic processors, applies adaptive energy and thermal management across hardware generations, and implements autonomous flash resource orchestration with multi-dimensional wear management. The system orchestrates tensor workflows using hierarchical scheduling, enables cross-agent collaboration with privacy preservation, and supports continuous learning without catastrophic forgetting. This integration delivers unprecedented computational efficiency and security in high-dimensional decision-making environments while supporting incremental adoption through modular interfaces.

Owner:QOMPLX INC
Nonvolatile memory
ActiveUS20250138940A1Memory architecture accessing/allocationRead-only memoriesEngineeringAddress control
A nonvolatile memory device includes a plurality of latch groups, an address controller, an encoder, and a buffer. The address controller controls an input address and an output address to indicate one of the plurality of latch groups. The encoder receives sector data from a latch group corresponding to the output address among the plurality of latch groups and also compresses the received sector data. The buffer stores the compressed sector data. Among the plurality of latch groups, the compressed sector data stored in the buffer is overwritten in a latch group corresponding to the input address.

Owner:SAMSUNG ELECTRONICS CO LTD
Efficient remote pointer sharing for enhanced access to key-value stores
A method to share remote DMA (RDMA) pointers to a key-value store among a plurality of clients. The method allocates a shared memory and accesses the key-value store with a key from a client and receives an information from the key-value store. The method further generates a RDMA pointer from the information, maps the key to a location in the shared memory, and generates a RDMA pointer record at the location. The method further stores the RDMA pointer and the key in the RDMA pointer record and shares the RDMA pointer record among the plurality of clients.


Owner:IBM CORP
Initialization of parameters for machine-learned transformer neural network architectures
An online system trains a transformer architecture by an initialization method which allows the transformer architecture to be trained without normalization layers of learning rate warmup, resulting in significant improvements in computational efficiency for transformer architectures. Specifically, an attention block included in an encoder or a decoder of the transformer architecture generates the set of attention representations by applying a key matrix to the input key, a query matrix to the input query, a value matrix to the input value to generate an output, and applying an output matrix to the output to generate the set of attention representations. The initialization method may be performed by scaling the parameters of the value matrix and the output matrix with a factor that is inverse to a number of the set of encoders or a number of the set of decoders.

Owner:THE TORONTO DOMINION BANK
Dynamic stalling of software waiting period
An example operation may include one or more of executing a waiting period of time within a software application being accessed by a user, executing an animation via the software application during the waiting period, determining a result of the software application being accessed by the user, determining additional time to add to the waiting period of time based on the result, via the software application, executing the waiting period with the additional time, augmenting the animation based on the additional time to add to the waiting period, via the software application, and executing the augmented animation via the software application during the additional time. At least one portion of the example operation: integrates with an artificial intelligence (AI) chatbot, interacts with the AI chatbot, is performed by the AI chatbot, and / or is associated with an AI model.

Owner:THE TORONTO DOMINION BANK
Memory access optimization method based on intelligent cache management
The invention discloses a memory access optimization method based on intelligent cache management, and relates to the technical field of computer storage. According to the method, spatial-temporal characteristics and semantic association data of memory access requests are collected in real time, a dynamic heat matrix is constructed, and a multi-dimensional access rule is fused to improve modeling precision. And inputting the dynamic popularity matrix into a hybrid prediction model, predicting a future access probability by using a time convolutional network, analyzing a competition relationship between data blocks through a graph attention network, generating a conflict pre-judgment weight and a corrected popularity ranking, and effectively reducing the cache jitter risk. On the basis of popularity ranking and conflict weight, a fragmented reinforcement learning algorithm is adopted to divide logic sub-regions, a differential reward function is designed to dynamically decide cache operation, and performance and energy efficiency requirements are balanced; and finally, through an online learning mechanism, combining real-time feedback to dynamically adjust a prediction model weight and strategy parameters, forming a closed-loop optimization link, and realizing adaptive stability under long-term load fluctuation.

Owner:SHENZHEN FIRST STORAGE TECH LTD
Method and System for Optimizing Use of Retrieval Augmented Generation Pipelines in Generative Artificial Intelligence Applications
ActiveUS20250190461A1Memory architecture accessing/allocationDigital data information retrievalAlgorithmTheoretical computer science
A system and method of improving performance of LLMs including receiving a query, retrieving relevant documents for the query to form a combined context, partitioning the combined context in context partitions, generating intermediate results from the context partitions using a mapper prompt, and generating a final result from the intermediate results using a reducer prompt. The final result is transmitted to a user.

Owner:MADISETTI VIJAY
Efficient token pruning in transformer-based neural networks
PendingUS20250124105A1Memory architecture accessing/allocationMemory systemsLinguistic modelAlgorithm
Key-value (KV) caching accelerates inference in large language models (LLMs) by allowing the attention operation to scale linearly rather than quadratically with the total sequence length. Due to large context lengths in modern LLMs, KV cache size can exceed the model size, which can negatively impact throughput. To address this issue, KVCrush, which stands for KEY-VALUE CACHE SIZE REDUCTION USING SIMILARITY IN HEAD-BEHAVIOR, is implemented. KVCrush involves using binary vectors to represent tokens, where the vector indicates which attention heads attend to the token and which attention heads disregard the token. The binary vectors are used in a hardware-efficient, low-overhead process to produce representatives for unimportant tokens to be pruned, without having to implement k-means clustering techniques.

Owner:INTEL CORP
Cache management optimization method and system
The invention provides a cache management optimization method and system. The method comprises the steps that a cache access request initiated by an application program is received, and the cache access request comprises identification information of to-be-accessed data; based on the identification information, the access popularity of the to-be-accessed data is evaluated, and the position of the to-be-accessed data in the cache hierarchical structure is dynamically adjusted in combination with the current cache state and a preset cache strategy; when it is detected that the cache space is insufficient, the access requirement in a future period of time is predicted according to the access mode of the to-be-accessed data, the high-value to-be-accessed data is reserved preferentially, and the low-value to-be-accessed data is selectively migrated to a low-level cache or storage device through an intelligent algorithm; according to historical access records and real-time access conditions, a cache strategy is continuously optimized, efficient utilization of cache resources is ensured, and access delay to a rear-end storage system is reduced. According to the technical scheme provided by the invention, the performance and efficiency of the cache management system are improved.

Owner:QUAN SPACE (JILIN) INFORMATION TECHNOLOGY CO LTD
System and method for adaptive protocol caching in event-driven data communication networks
ActiveUS20250181432A1Interprogram communicationCode conversionCommunications systemParallel computing
A system for adaptively caching network communication protocols provides improved efficiency and performance through a multi-level cache architecture. The system monitors performance metrics and synchronizes cache contents across distributed nodes using a hierarchical structure. Protocol cache requirements are predicted based on usage patterns, enabling proactive cache management. The system compresses cached protocols using existing codebooks to optimize storage and transmission efficiency. Integration with event-driven data communication systems enables seamless protocol selection and translation. The caching system works in conjunction with transaction managers and protocol predictors to enhance network communication performance. The system maintains cache coherency across local, regional, and global cache levels while minimizing network overhead and optimizing protocol availability. By predicting and pre-caching likely needed protocols, the system reduces protocol negotiation latency and improves overall network communication efficiency.

Owner:ATOMBEAM TECH INC
Memory fault repairing method and device, equipment, medium and computer program product
The invention discloses a memory fault repairing method and device, equipment, a medium and a computer program product, and relates to the technical field of computers.The memory fault repairing method includes the steps that memory error information sent by a memory controller is obtained, a fault target memory page can be positioned, and a standby memory page is obtained from a standby memory pool; the memory address mapping table is updated, the physical address of the target memory page with the fault is mapped to the physical address of the standby memory page, the repairing process does not depend on triggering of a system management interrupt mechanism, memory repairing in the system running stage is achieved, the system downtime caused by memory fault repairing is shortened, and therefore the memory repairing efficiency is improved. The problem of high delay in memory fault processing can be solved, and the technical effect of improving the memory fault repairing efficiency is achieved.

Owner:INSPUR SUZHOU INTELLIGENT TECH CO LTD
System and Method for Endpoint-Aware Adaptive Protocol Caching with Semantic Deduplication in Heterogeneous Networks
PendingUS20260010476A1Memory architecture accessing/allocationCode conversionStructure analysisNetwork Communication Protocols
A system for adaptively caching network communication protocols enhances efficiency across heterogeneous device environments through a multi-level cache architecture with device-capability-based tiers. The system collects endpoint telemetry data including device capabilities and operational constraints to classify endpoints and generate context-aware protocol variants optimized for specific device types. Protocol optimization opportunities are determined through structural analysis of message patterns and state transitions. The system performs protocol deduplication by identifying functionally equivalent variants and maintaining canonical representations to reduce cache redundancy. Cache synchronization across distributed nodes uses enhanced Merkle tree structures with protocol normalization processing. The system predicts communication needs based on historical patterns, network context, and endpoint constraints, enabling proactive cache management tailored to device capabilities. Integration with event-driven data communication systems enables seamless protocol selection and translation while maintaining compatibility between diverse endpoint types, from high-performance servers to resource-constrained IoT devices.

Owner:ATOMBEAM TECH INC
Programmable metadata
Methods, systems, and devices for programmable metadata and related operations are described. A method may include receiving signaling that indicates a set of rules for transitions of states of metadata at a memory device storing the metadata. The memory device may receive a command from a host device associated with a set of data after receiving the set of rules. The memory device may transition metadata associated with the set of data stored at the memory device from a first state to a second state based in part on the set of rules and the command. The memory device may execute the command received from the host device.

Owner:MICRON TECHNOLOGY INC
Hybrid expert model reasoning method based on cooperation of CPU and GPU
The invention discloses a hybrid expert model reasoning method based on cooperation of a CPU (Central Processing Unit) and a GPU (Graphics Processing Unit), and belongs to the field of deep learning. According to the method, a CPU-GPU computing framework of a hybrid expert model is constructed, heterogeneous computing resource loads are effectively balanced, and the hardware utilization rate is remarkably increased; an intelligent cache management mechanism based on dynamic priority scores is provided, high-demand experts are reserved preferentially, and the transmission overhead caused by cache missing is reduced; through pipeline parallel design for separating calculation and transmission tasks, CPU calculation and PCIe transmission are overlapped in the GPU execution period, and delay is effectively hidden. In addition, in combination with a multi-layer expert activation prediction prospective prefetching mechanism, the expert cache hit rate is improved. The method is compatible with hybrid expert models of different scales and structures, and stable and efficient reasoning acceleration is realized on a resource-limited heterogeneous platform.

Owner:PEKING UNIV
Programmable metadata
PendingUS20250165160A1Input/output to record carriersError detection/correctionData storingData store
Methods, systems, and devices for programmable metadata and related operations are described. A method may include receiving signaling that indicates a set of rules for transitions of states of metadata at a memory device storing the metadata. The memory device may receive a command from a host device associated with a set of data after receiving the set of rules. The memory device may transition metadata associated with the set of data stored at the memory device from a first state to a second state based in part on the set of rules and the command. The memory device may execute the command received from the host device.

Owner:MICRON TECHNOLOGY INC
Workflow condition node management method based on dynamic rule engine
The invention provides a workflow condition node management method based on a dynamic rule engine, and the method comprises the steps: obtaining a business circulation demand, configuring a task node attribute, and carrying out the adaptation of the business circulation demand according to the task node attribute, and obtaining a process template model; setting rule conditions, binding the rule conditions with the task nodes, and processing the flow template model; generating a process instance according to the updated process template model, analyzing rule conditions, initializing task allocation logic, and pushing a to-do task to a user; the user executes a to-do task, triggers the rule engine to carry out condition judgment, and updates a process instance state to obtain an updated process instance state; and according to the updated process instance state, generating a visual interface to display the process progress, and carrying out real-time early warning on an overtime or abnormal task to obtain a monitoring report and the process instance state after abnormal processing. Tasks can be decomposed, so that complex tasks are easier to manage, and the execution difficulty is reduced.

Owner:JIANGXI TONGRUI INFORMATION TECH CO LTD
Large model reasoning method for user request and server
The invention discloses a large model reasoning method for a user request and a server, and relates to the technical field of large model application, and the method comprises the steps: inputting an obtained request text and a target statement into a preset language model for reasoning processing, if it is judged that the request text can be matched with the historical prefix key-value cache in the host memory, determining the historical prefix key-value cache as a preliminary pre-filling reasoning result; performing pre-filling reasoning processing according to the request text, the preliminary pre-filling reasoning result and the target statement to obtain a pre-filling reasoning result; performing recursive reasoning processing according to the pre-filling reasoning result to obtain a recursive reasoning result; the recursive reasoning result is output to the user side, the historical prefix key-value cache is stored through the host memory, and the corresponding historical prefix key-value cache does not need to be reasoned repeatedly, so that the reasoning efficiency of the request text is improved, and the user experience is improved.

Owner:INSPUR SUZHOU INTELLIGENT TECH CO LTD
Method and System for Optimizing Use of Retrieval Augmented Generation Pipelines in Generative Artificial Intelligence Applications
ActiveUS20250390520A1Memory architecture accessing/allocationDigital data information retrievalTime informationService Interface for Real Time Information
Systems and methods for dynamic knowledge integration in LLM systems including receiving multimodal input data comprising text, image, audio, video, and / or code data, extracting information by processing the multimodal input data through a document processor, storing the extracted information in a dynamic knowledge base, receiving a user query at a query processor, identifying knowledge domains related to the user query using domain-specific agents, retrieving real-time information from the dynamic knowledge base responsive to the identified knowledge domains, integrating the real-time information into the processing of an LLM by a dynamic knowledge integrator, and generating a response using the LLM with the real-time information.

Owner:MADISETTI VIJAY
Multi-modal big language model reasoning optimization method and device, equipment and medium
The invention relates to the technical field of artificial intelligence, can be applied to the fields of financial science and technology and medical health, and discloses a reasoning optimization method, device, equipment and medium for a multi-modal large language model.The method comprises the steps that an input long context sequence is obtained, and key value projection is conducted on the long context sequence to generate an initial key value cache; for each attention layer of the multi-modal large language model, calculating an attention matrix of the attention layer according to the vector dimension of the long context sequence and the initial key value cache; calculating a cross-modal attention entropy according to the attention matrix, and determining a cache size of an attention layer according to the cross-modal attention entropy; optimizing the initial key value cache based on a cumulative attention scoring mechanism and a window strategy to obtain a target key value cache; and reasoning the long context sequence according to the cache size and the target key value cache to generate a long context reasoning result. And the reasoning efficiency and the reasoning accuracy are improved.

Owner:PING AN TECH (SHENZHEN) CO LTD
Many-core cache consistency system and method, electronic equipment, storage medium and product
ActiveCN119669109Aimprove consistencyImprove access efficiencyArchitecture with single central processing unitMemory systemsMemory addressComputer architecture
The invention provides a many-core cache consistency system, a many-core cache consistency method, electronic equipment, a storage medium and a product, and the system is based on a network-on-chip architecture, and a plurality of nodes, corresponding routers and distributed directories deployed in the routers are introduced. Each node comprises one or more processor cores and a distributed last-stage cache, and a memory address is divided into a plurality of address blocks and is associated with the distributed last-stage cache through a dynamic address mapping rule. The distributed directories and the distributed last-stage caches are in one-to-one correspondence and used for recording the states of cache lines, the router is responsible for receiving and responding to requests from local or remote nodes, querying the distributed directories and updating the states of the cache lines, and efficient management of cache consistency is achieved. The technical scheme belongs to the technical field of communication, effectively solves the problems of high load and communication delay of a main node in a traditional cache consistency protocol, and improves data consistency and access efficiency in a multiprocessor system and a large-scale parallel computing environment.

Owner:SHANDONG YUNHAI GUOCHUANG CLOUD COMPUTING EQUIP IND INNOVATION CENT CO LTD
Address mapping method in DPU local storage virtualization
ActiveCN119806749AMemory systemsSoftware simulation/interpretation/emulationDirect memory accessPhysical address
The invention discloses an address mapping method in DPU local storage virtualization, which comprises the following steps: a virtual machine calls a system call interface provided by an address mapping configuration management module on a host side to perform mapping configuration of a virtual machine physical address and a host physical address, and issues the virtual machine physical address and length to a virtual address mapping module of a DPU; the virtual address mapping module manages global direct memory access address resources, firstly allocates a global direct memory access address on a host side, then maps a virtual machine physical address to the allocated global direct memory access address in a mapping page table of the DPU, and returns the virtual machine physical address to the address mapping configuration management module; and the address mapping configuration management module obtains the distributed global direct memory access address, and maps the distributed global direct memory access address to a host physical address in the IOMMU. According to the method, by optimizing address mapping, the efficient and flexible local storage virtualization service can be realized while the data reliability is ensured.

Owner:ZHEJIANG UNIV
Memory access method and graphics processor
PendingCN120541006AMemory architecture accessing/allocationMemory systemsComputer hardwareMemory address
The embodiment of the invention provides a memory access method and device, electronic equipment and a readable storage medium. The method comprises the following steps: receiving a cache line access request; extracting label information from a target memory address corresponding to the cache line access request, wherein the label information comprises a shared label, a private label, a group index, inter-block offset and intra-block offset; querying whether the cache line access request hits the L1 cache or not based on the label information; the group index is used for determining a target group, the shared tag and the private tag are used for determining a target cache line in the target group, and the inter-block offset is used for determining a target cache block in the target cache line; and if the cache line access request hits the L1 cache, determining a target data position in a hit target cache block based on the in-block offset, and executing a corresponding memory access request based on the target data position. According to the embodiment of the invention, on the basis of ensuring the data access efficiency, the storage space of the cache line is fully utilized, and the waste of the cache space is reduced.

Owner:LOONGSON TECH CORP
Request management method and device, electronic equipment and storage medium
The invention relates to the technical field of computers, and provides a request management method and device, electronic equipment and a storage medium, and the method comprises the steps: when it is detected that a data access request is subjected to a cache miss, based on a first address carried by the data access request, executing the cache miss on the data access request; checking whether an uncompleted request entry corresponding to the first address exists in a preset request management structure or not, wherein the preset request management structure is a pre-constructed multi-path group associative cache structure used for performing grouping management on a cache miss request; and adding the data access request into a waiting queue of the uncompleted request entry under the condition that the uncompleted request entry exists in the preset request management structure. According to the method and the device, the cache miss requests are subjected to grouping management by adopting a multi-path group associative cache structure, so that the parallel search of the cache miss requests can be realized, and the processing efficiency of the cache miss requests is greatly improved.

Owner:SHANGHAI BIREN TECH CO LTD
Object-based storage with garbage collection and data consolidation
PCT designated stage expiredWO2025101465A1Memory architecture accessing/allocationFile system administrationRefuse collectionFile system
Embodiments are directed to a file system that include object stores. An object store for write requests may be provided. Write ahead log (WAL) entries that include data blocks may be generated. A WAL object may be generated based on the WAL entries and stored in the object store. An in-memory overlay may be updated to associate the data blocks with the WAL object. A checkpoint operation may be executed to: generate an index object that includes index entries that associate other data blocks with data objects stored in the object store; update the index object to include index entries that associate the data blocks with the WAL object; store the updated index object in the object store; update the in-memory overlay to remove the association of the data blocks and the WAL object and update the in memory WAL to remove records of successfully checkpointed WAL objects.

Owner:QUMULO INC
Solid state disk pre-reading method and device based on host I / O software and medium
PendingCN120010775AInput/output to record carriersMachine learningSoftware engineeringCache management
The invention discloses a solid state disk pre-reading method and device based on host I / O software and a medium. According to the method, through deep collaboration between the host I / O software and the solid state disk, multi-dimensional context information such as application program running, user operation and system resources is accurately perceived, and then the pre-reading strategy of the solid state disk is dynamically optimized. Various kinds of context information are collected through host I / O software and then transmitted to the solid state disk, the solid state disk analyzes and processes the context information by means of a machine learning technology so as to predict subsequent pre-access related parameters, so that a pre-reading strategy is correspondingly and dynamically adjusted, a cache management mechanism is matched, pre-read data better meet actual requirements, and the pre-read data are more accurate. The hit rate of pre-reading is improved, the overall data reading efficiency is improved, and the data reading speed is remarkably increased.

Owner:成都芯忆联信息技术有限公司
Multi-source heterogeneous distributed system, memory access method, and storage medium
PCT designated stage expiredWO2025139858A1Input/output to record carriersProgram controlMemory cellAccess method
The present application relates to the technical field of data storage. Disclosed are a multi-source heterogeneous distributed system, a memory access method and a nonvolatile readable storage medium. The method comprises: a first unified interconnection bus unit receiving, by means of a protocol adaptation interface module, a read request sent by a first device, and setting the cache state of a first memory unit to be an invalid state; sending to a second unified interconnection bus unit of a second device a request message obtained by packaging the read request, the second unified interconnection bus unit reading data from a second memory unit; setting the cache state of the second memory unit to be a shared state, and sending to the first unified interconnection bus unit a response message, the first unified interconnection bus unit storing in the first memory unit data carried by the response message; and setting the cache state of the first memory unit to be a shared state. Thus, deploying a unified interconnection bus unit on each device can achieve a consistent memory communication between the devices, thereby achieving memory sharing, and further improving the performance of the multi-source heterogeneous distributed system.

Owner:INSPUR (BEIJING) ELECTRONICS INFORMATION IND CO LTD