
Patents
Literature
130 results about "Technical documentation" patented technology
Efficacy Topic
Property
Owner
Technical Advancement
Application Domain
Technology Topic
Technology Field Word
Patent Country/Region
Patent Type
Patent Status
Application Year
Inventor
In engineering, technical documentation refers to any type of documentation that describes handling, functionality and architecture of a technical product or a product under development or use. The intended recipient for product technical documentation is both the (proficient) end user as well as the administrator / service or maintenance technician. In contrast to a mere "cookbook" manual, technical documentation aims at providing enough information for a user to understand inner and outer dependencies of the product at hand.
Method for analyzing matching degree between demand and output result based on text semantics
PendingCN111309871AReduce difficultyReduce time and resource investmentNeural architecturesText database queryingEnterprise project managementData science
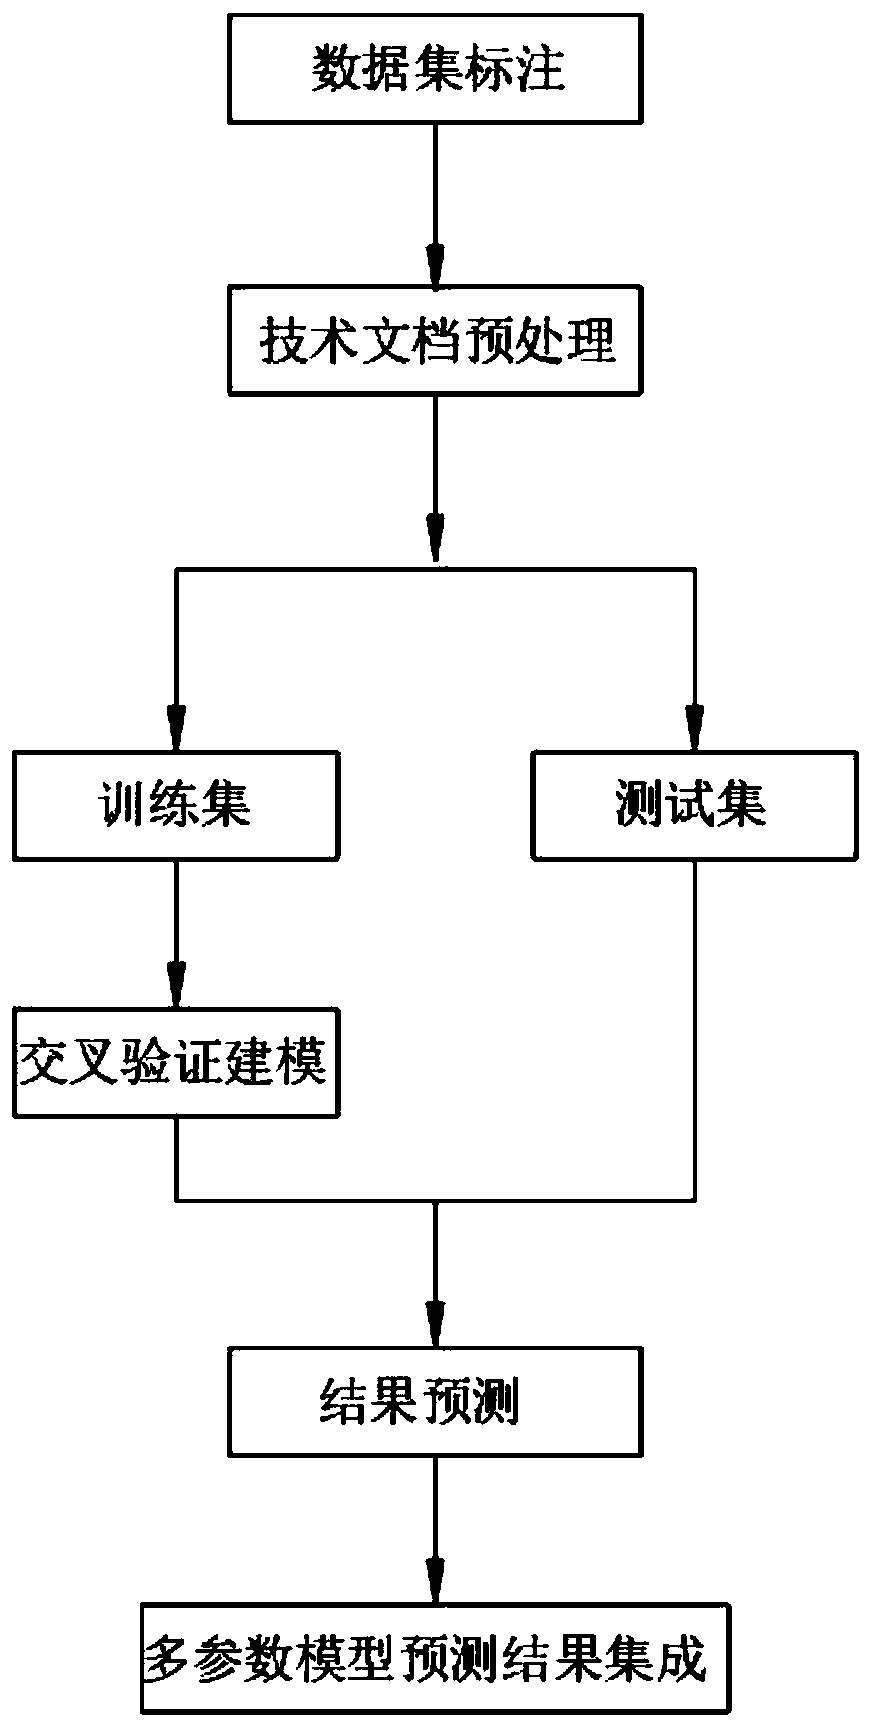
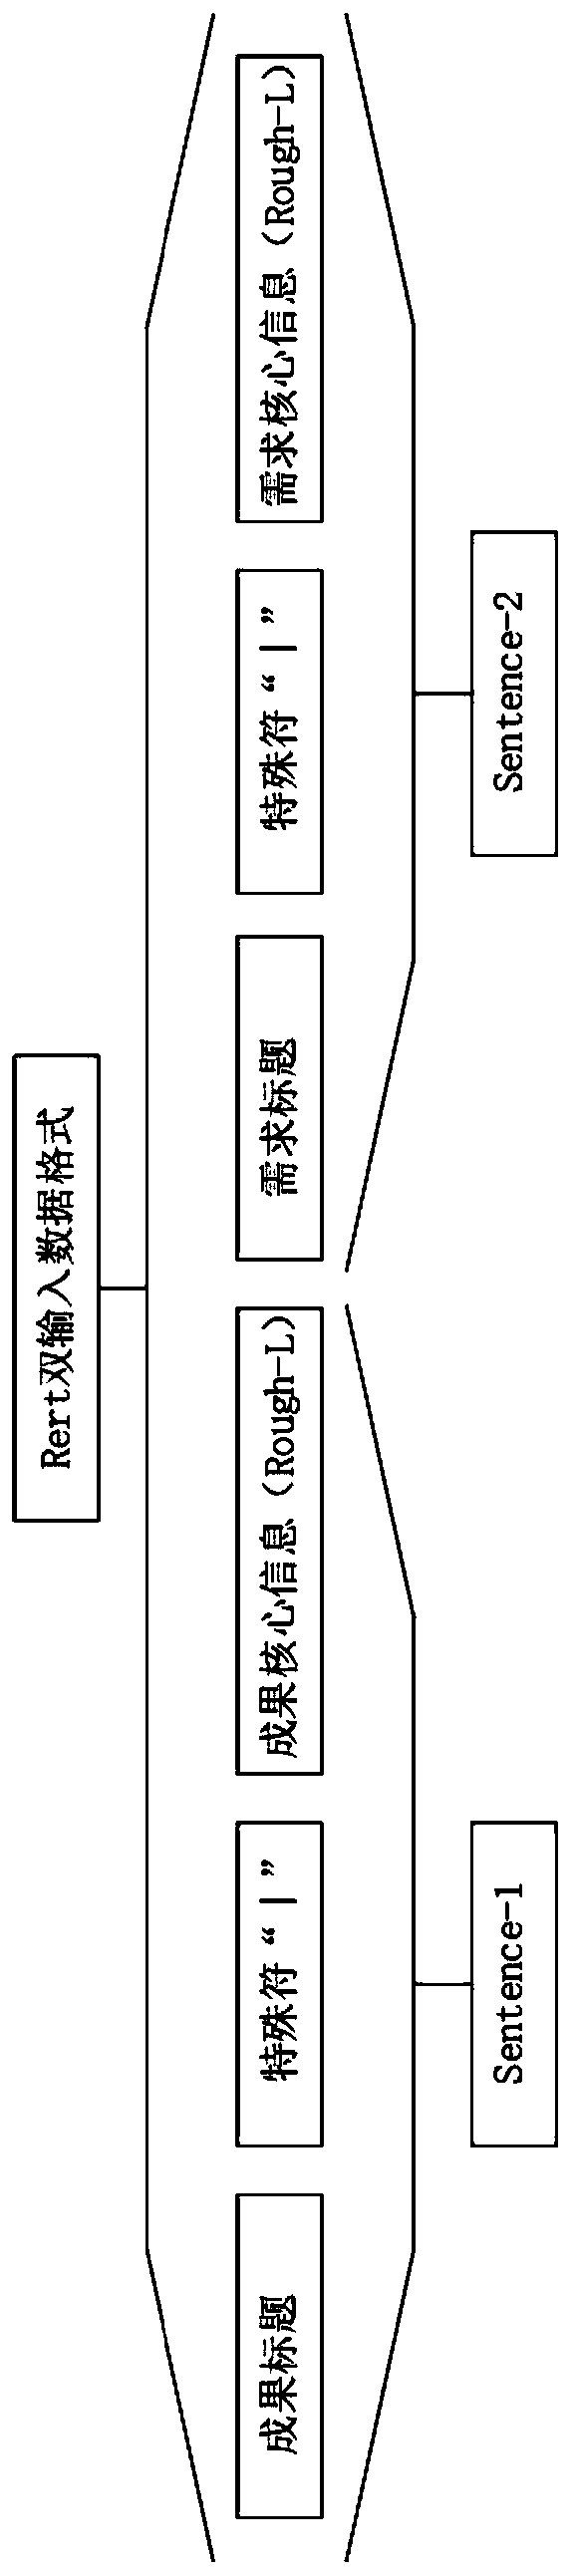
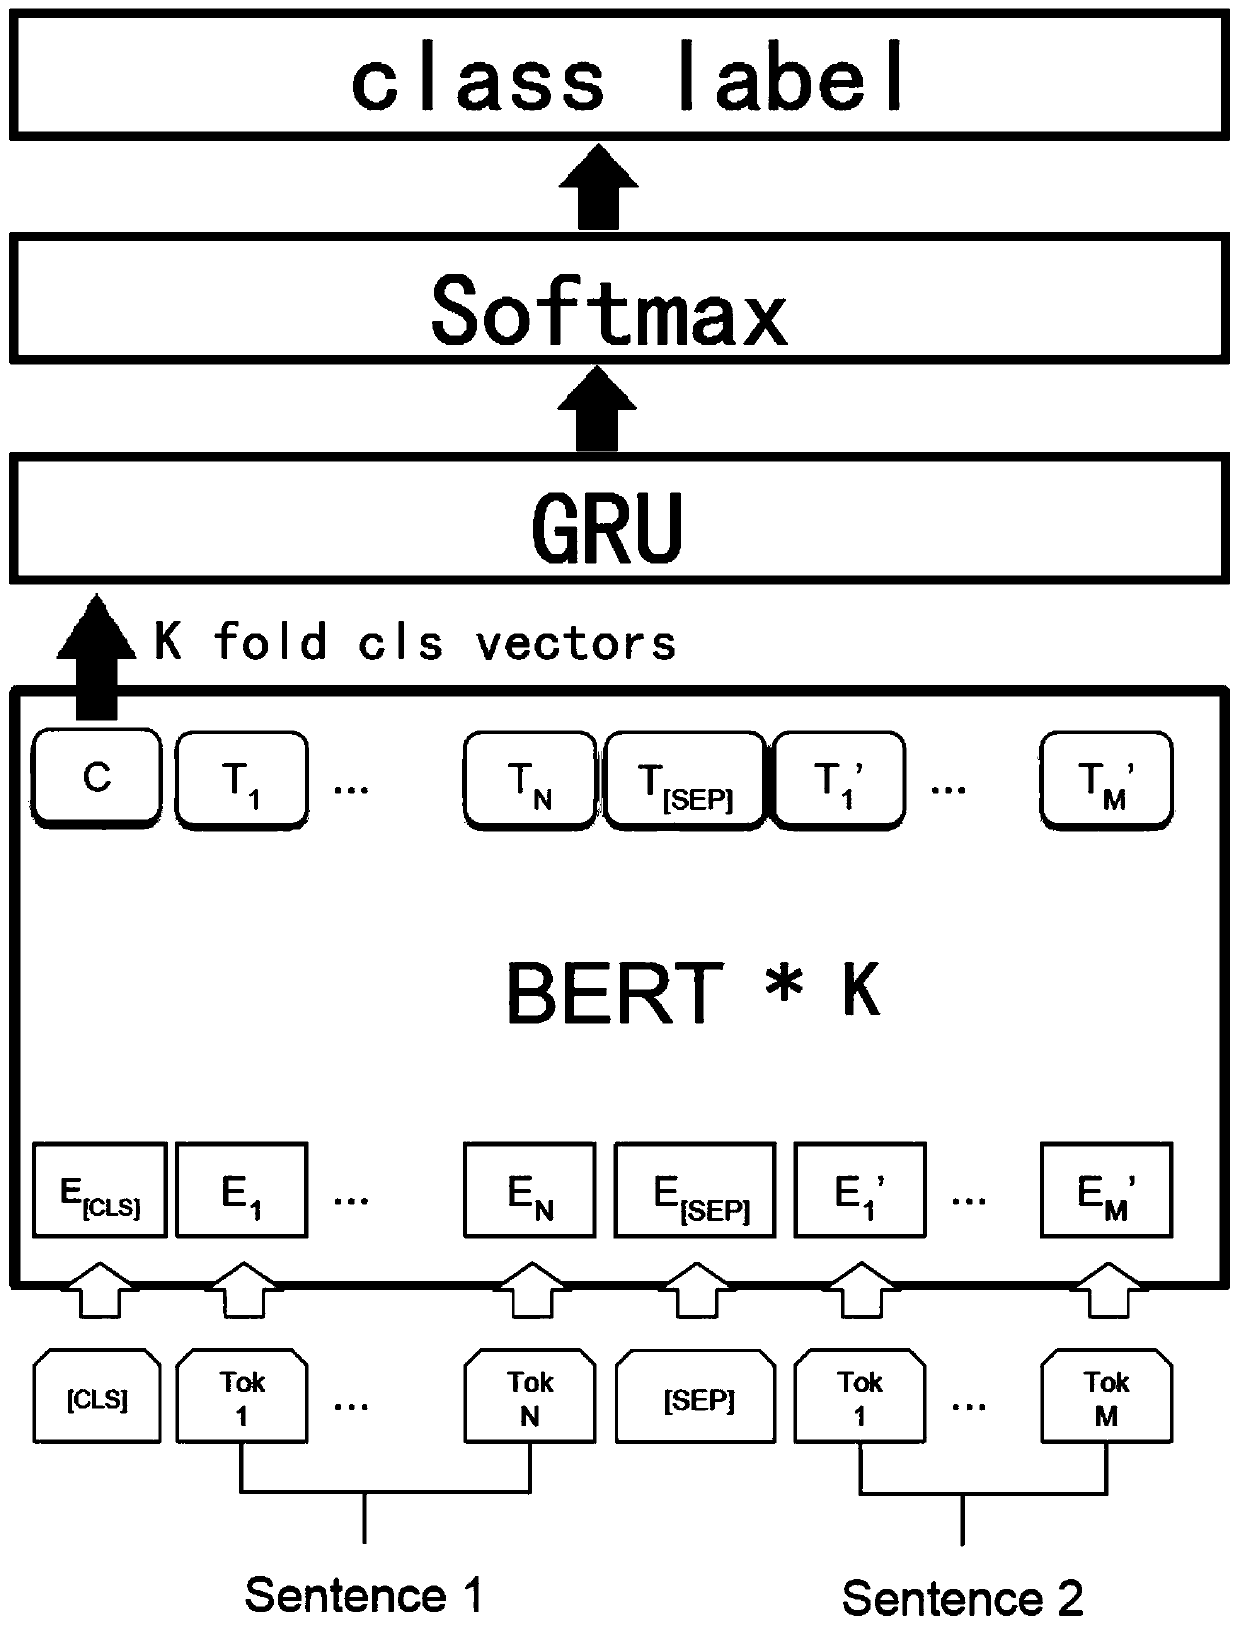
The invention discloses a method for analyzing a matching degree between a demand and an output result based on text semantics. The method comprises the following steps: step 1, labeling a data set; step 2, technical document preprocessing; 3, training and predicting a single-parameter model; 4, integrating prediction results of the multi-parameter model; the method has the beneficial effects thatthe method is simple; deep learning and the NLP technology are applied to the field of project association degree calculation of enterprise project management for the first time. Calculating an association matching degree between the two projects according to project requirements and result description; the associated project positioning difficulty is effectively reduced; meanwhile, the demand side can be helped to quickly and efficiently locate high-quality projects adapting to the demand of the demand side; time and resource investment for achievement screening and matching are greatly reduced, the association matching degree between projects is calculated by means of text data of existing project achievement technical documents and project declaration guidelines, and then large enterprises are assisted in screening high-quality projects with the high matching degree in the project bidding and tendering link.
Owner:普华讯光(北京)科技有限公司
Retrieval augmented generative question and answer boosting
ActiveUS20250328565A1Natural language translationSpecial data processing applicationsTheoretical computer scienceScientific instrument
Systems or techniques are provided for facilitating retrieval augmented generative question and answer boosting. In various embodiments, a system can access a plain text question regarding a scientific instrument. In various aspects, the system can generate, via a large language model that references a document-graph repository, a structured or unstructured answer for the plain text question. In various instances, the document-graph repository can comprise a plurality of document-graphs that respectively correspond to a plurality of technical documents. In various cases, for a first document-graph that corresponds to a first technical document, leaf nodes of the first document-graph can represent respective text blocks written in the first technical document, and non-leaf nodes of the first document-graph can respectively represent a document title, one or more section headings, and one or more scientific instrument identifiers written in the first technical document and beneath which the respective text blocks are nested.

Owner:PPD DEVELOPMENT LP +2
Method and system for RAG type data item extraction and consistency checking oriented to engineering technology document
The invention relates to the technical field of intelligent processing of document information, discloses a method and a system for extracting RAG type data items and checking consistency for engineering technology documents, and solves the problem that an existing scheme is difficult to consider high-accuracy extraction, cross-document consistency, strong traceability and structured landing in engineering technology document data processing. The scheme comprises the following steps of: performing layout analysis and necessary OCR (Optical Character Recognition) processing on a received document, and dividing the document into multiple levels of text blocks; carrying out vectorization processing on the multi-level text blocks by adopting an embedding model subjected to two-stage fine adjustment, establishing a vector index and recalling candidate fragments to form a candidate fragment set; a cross encoder with efficient fine tuning of parameters is adopted to screen out high-correlation fragments; performing standardization processing by extracting a target variable to form a structured record; consistency checking is conducted on the target variables, and finally structured records and checking results are bound with minimum evidence fragments and corresponding position information to be exported through a format list.

Owner:CHINA HYDROELECTRIC ENGINEERING CONSULTING GROUP CHENGDU RESEARCH HYDROELECTRIC INVESTIGATION DESIGN AND INSTITUTE
Network anomaly mitigation based on a large language model
A computer-implemented method for managing a telecommunications network based on a large language model is disclosed, the large language model being fine-tuned with technical documentation for the telecommunications network and historical data originating from the telecommunications network. The method comprises receiving one or more key-performance indicators and determining whether the one or more key-performance indicators indicate an anomaly. The method further comprises, in response to detecting an anomaly, determining contextual data associated with the real-time data and feeding a prompt to identify a root cause to the large language model, the prompt containing the contextual data and a task description for root cause analysis for the anomaly. The method also comprises performing one or more responses to address the root cause.

Owner:SAMSUNG ZHILABS SLU
Intelligent Document Drafting
A computer-implemented system for automated document generation receives user input and processes it through artificial intelligence models to create professional documents. The system combines user-provided information with specialized knowledge databases containing domain-specific requirements and formatting standards to generate enhanced processing instructions. Trained machine learning models process these instructions to produce contextually appropriate content that addresses specific technical and legal requirements. The generated content is formatted using configurable templates to create completed documents that meet professional standards. The system provides adaptive user interfaces that adjust functionality based on user expertise levels, supports multiple operational modes including guided and automated generation, learns from example documents to improve output quality, and enables comprehensive workflow management through network-accessible services. Applications include patent applications, legal responses, technical documentation, and other specialized professional documents requiring domain expertise and regulatory compliance.

Owner:BAIRD CAMILLE
Automatic testing and document generating method and system based on AI drive
The invention discloses an AI-driven automatic testing and document generation method and system, and the method comprises the steps: obtaining document data of test software, carrying out the preprocessing and information extraction, and forming structured data; identifying key test points from the structured data by using an agent, and generating a test case; executing the test case by utilizing a preset automatic test framework to obtain a test result; retrieving data information associated with the structured data in the knowledge base by utilizing RAG to form a retrieval result set; fusing the retrieval result set with the structured data and the test result according to a preset weight strategy to construct a complete context; and taking the context as input, calling the large language model by utilizing an agent, and generating a technical document. By means of the technical scheme, accurate and real-time technical document generation is achieved, the document generation quality can be continuously improved, and the real-time updating capacity and the data driving decision support capacity of the document are improved.

Owner:BEIJING KUAFU TECHNOLOGY CO LTD
Augmented test execution based on ai-driven test script generation
Methods, systems, and apparatus, including medium-encoded computer program products for executing a test strategy, include: receiving a request to generate a test script for a new test strategy defined for a software solution, wherein the received request includes a specification of the new test strategy; generating the test script based on executing a large language model that receives as input the specification of the new test strategy, wherein the large language model is trained to automatically generate test scripts based on technical documentation for a testing framework defined for the software solution and integration tests generated for the software solution; and executing the test script for the new test strategy to obtain output data, the output data including performance data for the software solution.

Owner:SAP SE
Directory perception-based long document knowledge base construction method and program product
The invention discloses a long document knowledge base construction method based on directory perception and a program product, and belongs to the field of artificial intelligence and natural language processing. According to the scheme, an original long document is sequentially subjected to preprocessing, directory structure analysis, mixed blocking, double-tag generation, tag intelligent optimization, vectorization and meta-information mounting, and finally automatic construction and high-quality retrieval enhancement generation of a knowledge base are achieved. According to the method, the semantic integrity is guaranteed by fully utilizing the perceptual ability of the directory structure, the label quality and the retrieval efficiency are improved by combining a double-label system and intelligent optimization circulation, and the construction efficiency, the retrieval accuracy and the result traceability of the knowledge base are remarkably improved; the method is suitable for intelligent processing and application of long complex structure documents such as academic specialities, technical documents, policies and regulations and the like.

Owner:SOUTHEAST UNIV
Research and development platform language intelligent analysis method based on multi-system fusion
The invention discloses a research and development platform language intelligent analysis method based on multi-system fusion, and relates to the technical field of language intelligent analysis. According to the method, various language data in a multi-system fusion research and development platform are efficiently processed, cleaned and coded to generate a standardized data set by customizing a data adaptation interface, deep lexical and syntactic analysis and semantic role labeling are performed on the standardized data set, related features are extracted, a semantic mapping network is constructed, and semantic feature vectors are generated; cross-modal feature fusion is realized, deep meanings of language data are comprehensively captured, rich feature input is provided for intelligent analysis, a constructed intelligent analysis model can perform accurate intelligent analysis and intention recognition on natural language instructions and technical documents, and the intelligent analysis model can be used for performing intelligent analysis and intention recognition on the technical documents by means of compiling environment simulation, debugging information semantic optimization and the like. The model training effect is improved, and the analysis accuracy and the hardware compatibility are improved through hardware behavior simulation, real-time data flow analysis, user feedback and other modes.

Owner:SOUTHERN POWER GRID DIGITAL GRID RESEARCH INSTITUTE CO LTD
Biochemical experiment automation script training generation method based on RAG and DPO
The invention discloses a biochemical experiment automation script training generation method based on RAG and DPO. The method comprises the steps that biochemical experiment technical documents are collected to serve as an external knowledge base; the BM25 and the Fiss are fused to construct a hybrid retriever; generating experimental process description by using a large language model, determining equipment, protocols and materials, and retrieving related documents from a knowledge base on the basis of the experimental process description, the protocols and the materials; generating an experiment script based on a retrieval result, and performing platform simulation verification, and performing iterative optimization on the script which fails in verification; marking successful and failed scripts as preference data pairs, and constructing a training set; carrying out LoRA fine tuning on a local large language model by adopting direct preference optimization; and according to a target and appliance prompt input by a user, generating a verified experiment script by using the large language model after direct preference optimization training. According to the method, the script generation automation level and the passing rate are remarkably improved, the manual intervention cost is reduced, and an efficient solution is provided for automation of biochemical experiments.

Owner:SOUTH CHINA UNIV OF TECH
Big language model dynamic dialogue history compression method and system based on double verification
ActiveCN121144461ADigital data information retrievalNatural language data processingLinguistic modelAlgorithm
The invention relates to the technical field of big language model dialogue system optimization, in particular to a big language model dynamic dialogue history compression method and system.The method comprises the steps that the maximum length of a context window matched with a target big language model, the maximum number of newly-generated lexical elements and the size of a safety buffer area are set, and then dialogue history is loaded; initial compression and verification are carried out through a keyword and TF-IDF mixed scoring system, multiple times of dynamic compression are carried out according to gradients if the conditions are not met, and finally, parameters are adjusted to adapt to the residual space when a model is called to generate response. The system comprises a dialogue history loading module, a parameter configuration module, a dynamic compression engine module and a large language model integration module. Through a multi-stage compression verification mechanism and a progressive multi-stage dynamic compression strategy, super-long texts such as engineering technology documents can be processed, service interruption is reduced, the compression efficiency is improved on the premise that key semantics are reserved, and multi-language dynamic compression is supported. The problems of system token overrun and service instability in the prior art are solved.

Owner:POWERCHINA BEIJING ENG CORP
Network anomaly mitigation based on a large language model
A computer-implemented method for managing a telecommunications network based on a large language model is disclosed, the large language model being fine-tuned with technical documentation for the telecommunications network and historical data originating from the telecommunications network. The method comprises receiving one or more key-performance indicators and determining whether the one or more key-performance indicators indicate an anomaly. The method further comprises, in response to detecting an anomaly, determining contextual data associated with the real-time data and feeding a prompt to identify a root cause to the large language model, the prompt containing the contextual data and a task description for root cause analysis for the anomaly. The method also comprises performing one or more responses to address the root cause.


Owner:SAMSUNG ZHILABS SLU
Artificially intelligent assistant for work protocols
To provide systems and methods for aggregating disparate documentation and metadata from multiple programs and sources into centralized large language models.SOLUTION: A computing system 100 comprises a storage device 102 for storing at least technical documents 104. The technical documents include at least work protocols 112 and technical data files tagged with metadata. One or more large language models 134 are trained on at least the work protocols, and text and metadata 122, 124 extracted from the technical documents. An AI assistant 142 is commissioned for the large language models, and at least retrieves text and metadata in response to receiving a prompt. In a digital work environment 140 including an interface for the AI assistant, the AI assistant provides a contextual response via the digital work environment based on the received prompt.SELECTED DRAWING: Figure 1


Owner:THE BOEING CO
Multimodal context selection for large language model based resolutions addressing technical issues
ActiveUS20250321986A1Special data processing applicationsDocument management systemsLinguistic modelImage conversion
A method for technical issue resolution. The method includes: receiving, from a user, a text query concerning a technical issue; obtaining query-related context relevant to the text query; and processing, through a large language model (LLM), the text query and the query-related context to produce a multimodal query response used by the user to address the technical issue. More specifically, embodiments described herein utilize text topic and zero shot classification models to translate multimodal technical documentation (e.g., including text and images) into topic relevant metadata; and process queries, pertaining to technical issues, using a multimodal LLM provided with query-related text and image context derived from said topic relevant metadata.

Owner:DELL PROD LP
Artificially intelligent assistant for work protocols
A computer-implemented method comprises storing technical documents in a storage device. The technical documents include at least work protocols and technical data files tagged with metadata. One or more large language models are trained on at least the work protocols, and text and metadata are extracted from the technical documents. An artificially intelligent assistant is commissioned for the large language models, the artificially intelligent assistant configured to at least retrieve text and metadata in response to receiving a prompt. A digital work environment including an interface for the artificially intelligent assistant is provided. At the artificially intelligent assistant, a prompt related to a first work protocol is received. Text and metadata related to the first work protocol are retrieved via the large language model based on the received prompt. A contextual response is provided via the digital work environment based on the retrieved text and metadata.

Owner:THE BOEING CO
Construction technology knowledge management method and system based on knowledge base and large language model
The invention relates to the technical field of knowledge management, in particular to a construction technology knowledge management method and system based on a knowledge base and a large language model.The method comprises the steps that original construction technology documents are collected and preprocessed to obtain construction technology documents, then the construction technology documents are stored, and a knowledge base of the construction technology field is constructed; based on a natural language processing technology, identifying entities and semantic relationships among the entities from the construction technology document, and constructing a knowledge graph of the construction technology field; generating a construction technology question and answer model based on a pre-trained language model, a knowledge base and a knowledge graph; on the basis of a search engine, querying a construction technology document most related to query content input by a user from a knowledge base; and receiving query content input by a user through the interactive operation page, and displaying a query result or displaying a construction technology question and answer result. According to the invention, intelligent integration, dynamic updating and accurate service of knowledge can be realized.

Owner:CHINA RAILWAY TENTH GRP FOURTH ENG CO LTD +1
Building management system with generative AI-based automated flexible customer report generation and standardization
ActiveUS12406232B2Natural language translationData processing applicationsSoftware engineeringUnstructured data
A method includes receiving, by one or more processors, an unstructured service report corresponding to a service request handled by one or more technicians for servicing building equipment. The unstructured service report may include unstructured data not conforming to a predetermined format or conforming to a plurality of different predetermined formats. The method may include extracting, by the one or more processors, a set of standards from one or more technical documents associated with the building equipment. The method may include automatically generating, by the one or more processors using a generative AI model, a structured service report in the predetermined format for delivery to a customer associated with the building equipment. Generating the structured service report may include standardizing the structured service report to comply with the set of standards extracted from the one or more technical documents associated with the building equipment.

Owner:TYCO FIRE & SECURITY GMBH
System and method for requirements recognition for system-on-a-chip verification
A system for analyzing documents to be used for verifying a system-on-a-chip (SoC). The system includes: a parser configured to analyze a technical document associated with the SoC to generate multiple text fragments; a data preparator configured to convert the multiple text fragments into a dataset for a machine learning model; and a machine learning model block configured to perform a training mode including multiple training epochs or an inference mode. In each training epoch, the machine learning model block trains the machine learning model based on the dataset such that a label is appended to each text fragment. In the inference mode, the machine learning model block makes a prediction for each text fragment based on the training result to generate the dataset with prediction values.

Owner:SK HYNIX INC
Server hardware configuration method and device, equipment, storage medium and product
ActiveCN120196360ADetecting faulty hardware by configuration testDatabase management systemsComputer hardwareRework
The invention discloses a server hardware configuration method and device, equipment, a storage medium and a product, and relates to the technical field of server hardware configuration and intelligent supply chain management.The server hardware configuration method comprises the steps that after a target server host is selected on a graphical interface, a database is established based on a hardware manufacturer compatibility rule, a compatible extension cabinet list is automatically loaded, and the target server host is configured; manual matching is avoided, the dependence on technical documents and artificial experience is reduced, the configuration efficiency is remarkably improved, and the error rate is reduced. Meanwhile, interface, resource and topological connection verification is carried out in the configuration process, global resource verification can be carried out on the multi-level extension architecture, and the defect of traditional single-level verification is overcome. If verification fails, error information is automatically determined, a predefined solution strategy is matched, and the configuration problem is quickly positioned and processed, so that hardware return, reworking and system downtime are effectively reduced, and the after-sales cost is reduced.

Owner:INSPUR SUZHOU INTELLIGENT TECH CO LTD
Systems and methods for multi-system networking and content delivery using taxonomy schemes
Taxonomy driven multi-system networking and content delivery systems and methods are provided herein. An example systems includes a website authoring platform generating a taxonomy structure for a webpage, the taxonomy structure indicating assets to be included in the webpage a layout for the assets, a technical documentation authoring system for creating technical documents related to the assets, and a metadata binder providing the technical documentation authoring system with access to the taxonomy structure of the website authoring platform so that technical document authors are provided with the taxonomy structure to guide creation and structuring of the technical documents so that the technical documents comprise data that corresponds to the assets.

Owner:SDL NETHERLANDS BV
Industrial robot operation teaching programming method and system based on knowledge graph
PendingCN121070368AData processing applicationsNatural language data processingCode generationTheoretical computer science
The invention discloses a programming method and system for industrial robot operation teaching based on a knowledge graph, and relates to the technical field of industrial automation and intelligent control. The method comprises the following steps: analyzing an industrial robot PDF technical document, extracting an instruction and an instruction parameter, and constructing a tree structure based on an identified title hierarchy; constructing a hierarchical knowledge graph based on the tree structure; generating an abstract syntax tree based on the instruction, the instruction parameter and the knowledge graph; filling node attributes of the abstract syntax tree into a preset control template, generating a reference RAPID code, importing the reference RAPID code into a robot controller, loading teaching environment parameters, and executing; and comparing execution results of the student self-compiled code and the reference code for students to observe difference comparison learning. The invention aims to break through a PDF technical document understanding threshold and accurately position errors in self-compiled codes of students through knowledge graph construction and reference code generation, so that the learning efficiency of the students is improved, and the teaching burden of teachers is relieved.

Owner:NANJING INST OF MECHATRONIC TECH +1
Apparatus, method and program for generating technical documentation for software
A method for generating technical documentation corresponding to source code is provided. In response to a repository selection received from a user terminal 110, the device 100 receives repository information related to the repository from a code management system 130 (S201 to S203). The device 100 then extracts multiple API code candidates and one or more root file candidates from the repository information (S204). The device 100 then requests a generative AI model (k) to determine paths for the multiple API codes and one or more root files using the extracted file candidates (S205) and receives the determined paths (S206). For each API code, the device 100 requests a generative AI model (l) to generate API documentation corresponding to the API code, and receives and stores the generated technical documentation (S207 to S209).


Owner:JITERA PTE LTD
Proactively identifying errors in technical documentation code
An embodiment for a method of using machine learning algorithms to proactively identify potential errors in code instance data for creating technical documentation. The embodiment may receive code instance data. The embodiment may generate error classifications for the received code instance data using a convolutional neural network and natural language processing techniques. The embodiment may perform a correlation analysis to derive correlations between the generated error classifications for the received code instance data and similarly occurring classifications in one or more historical code instances. The embodiment may calculate a score for each of the derived correlations, the calculated score corresponding to a likelihood that the similarly occurring classifications in the one or more other code instances represents a potential error. The embodiment may output notifications to a user for each of the derived correlations for which the calculated score exceeds a threshold value.

Owner:INTERNATIONAL BUSINESS MACHINE CORPORATION
Industrial product parameter extraction method based on domain knowledge learning
The invention provides an industrial product parameter extraction method based on domain knowledge learning, and the method comprises the steps: 1, collecting a plurality of technical documents of a preset industrial product field as knowledge sources, and constructing a structured domain knowledge model through a man-machine cooperation mode; 2, based on the domain knowledge model, generating a training data set with entity type labels, and training one or more deep learning extraction models by using the data set to enable the extraction models to learn parameter knowledge of the industrial product field; 3, receiving a new to-be-processed digital technology document, and processing the document by adopting the trained deep learning extraction model so as to identify and extract structured data corresponding to parameter entities in the domain knowledge model; and 4, storing the extracted structured data into a database, and selectively utilizing the data to carry out iterative updating and enhancement on the domain knowledge model.

Owner:欧冶工业品股份有限公司
A file processing method and apparatus
The present invention relates to the technical field of information processing, and discloses a file processing method and apparatus. The method includes: obtaining a target file; the target file includes a plurality of content units; the types of content units include structured data and unstructured data; respectively performing semantic extraction on the plurality of content units, and correspondingly generating association features between multiple content units; classifying the target file based on the association features to generate at least one classification label; extracting domain information from the association features according to the classification label; generating an abstract of the target file based on the domain information, the classification label, and the association features between multiple content units. The problems of fuzzy file classification, scattered information extraction, and insufficient flexibility of the abstract in the traditional method are solved. For example, it can be applied to the processing of bidding documents, accurately identify the relevance between technical parameters and business terms, generate a structured abstract, and is also applicable to scenarios such as contract review and technical document analysis.

Owner:ZHONGKE NANJING SOFTWARE TECH RES INST
3C product export compliance automatic detection method based on AI
The invention relates to an AI-based 3C product export compliance automatic detection method, which comprises the following steps: monitoring laws and regulations issuing platforms of 37 national supervision organizations at a frequency of not less than 30 minutes per time through a distributed crawler cluster deployed at a plurality of geographic nodes, and obtaining technical laws and regulations updating data of a target export country; a dynamic compliance mapping knowledge domain with a version tracing function is constructed, nodes comprise a standard term entity, a test method entity and an exemption condition entity, and edges comprise a logic dependence edge, a conflict edge and a reference edge. According to the AI-based 3C product export compliance automatic detection method, through collaborative optimization of a distributed crawler cluster and a hybrid neural network, single product detection is shortened to 3.4 minutes, vision-text-signal three-mode coupling analysis is constructed, the bottleneck of single-mode processing is broken through, the technical document analysis speed is increased by 18 times, real-time frame processing is achieved through video stream analysis, and the detection efficiency is improved. The 60fps video stream delay is less than 0.1 s, and the detection efficiency is remarkably improved.

Owner:BEIJING ZHONGTAI XINYUAN TRADING CO LTD
Providing enhanced functionality in an interactive electronic technical manual
Embodiments of the present disclosure provide methods, apparatus, systems, computing devices, and computing entities for displaying content found in technical documentation for an item via an IETM viewer. In accordance with one embodiment, a method is provided comprising: providing a window for display via the IETM viewer, the window displaying the content found in the technical documentation; receiving a focus of a first portion of the content received based at least in part on the user performing a first action; and in response, causing the first portion to be conveyed using a first enhancing format; and thereafter: receiving a focus of a second portion of the content received based at least in part on the user performing a second action; and in response: causing the first portion to no longer be conveyed using the first enhancing format; and causing the second portion to be conveyed using a second enhancing format.

Owner:MBTE HLDG SWEDEN
Document synchronization method and apparatus for code change, and electronic device
The application relates to the technical field of distributed applications, and discloses a document synchronization method for code change, which comprises the following steps: in response to a code deployment request, monitoring code change through a change capturing engine and obtaining a unified change set; performing document paragraph positioning on an interface definition file according to the unified change set, constructing a change-paragraph mapping list and a document synchronization task; performing acceptance review on the document synchronization task based on acceptance rules to obtain a review result; and making a decision based on a blocking condition and the unified change set, the change-paragraph mapping list and the review result to determine whether to block code deployment and complete document synchronization. The method can realize accurate positioning of abstract code change to technical document paragraphs, form a unified and feasible evidence chain to jointly drive a document synchronization process and decision-making. The application further discloses a document synchronization device for code change and electronic equipment.

Owner:QINGDAO JUSHANGHUI NETWORK TECH CO LTD
Textual encoding and analysis with a large graphical language model
The techniques discussed herein enhance the operation of content generation and analysis systems. Namely, textual content applications such as technical documentation, creative writing, and content moderation. This is accomplished through generating a graphical representation of a body of text (e.g., a document). The graphical representation can comprise a plurality of nodes representing the words of the document and a plurality of lines that join the nodes representing a level of association between individual words. As such, the graphical representation can capture the semantic and syntactical structure of the associated document while omitting the original textual content. The graphical representation can be subsequently evaluated for complexity based on the density of nodes and lines. Accordingly, the disclosed system can assign a score to a document based on the evaluation of the graphical representation. In addition, various documents can be ranked based on such scores.

Owner:MICROSOFT TECHNOLOGY LICENSING LLC
Technical document automatic generation method, system, device and storage medium
PendingCN122152276ANatural language data processingRequirement analysisInteractive contentSoftware engineering
The application provides a technical document automatic generation method, system, device and storage medium, the method comprises the following steps: analyzing a demand document through a feishu intelligent slice, and extracting complete content; an intelligent agent actively inquires a user to obtain an interface name, an application ID and an interactive picture link, triggers corresponding MCP to obtain interface data and interactive documents, and performs integrity check; in combination with demand, interface and interactive content, the intelligent agent inquires technical stack information, and generates a standardized technical document by using a prompt word engineering. Then, a double check mechanism is started: the intelligent agent can automatically correct the error, and the user is asked to confirm the ambiguous demand until the document is correct; finally, the feishu document generation MCP is triggered, the demand, interface, interaction and final document are integrated into a Markdown format, and a link is pushed to an AI programming tool for generating code. The application can realize full-process automatic conversion from a demand document to a technical document in a Web webpage development scene, and provide a standardized technical basis for an AI programming tool.

Owner:CTRIP TRAVEL NETWORK TECH SHANGHAI0