
Patents
Literature
949results about "Text database querying" patented technology
Efficacy Topic
Property
Owner
Technical Advancement
Application Domain
Technology Topic
Technology Field Word
Patent Country/Region
Patent Type
Patent Status
Application Year
Inventor
Method for analyzing matching degree between demand and output result based on text semantics
PendingCN111309871AReduce difficultyReduce time and resource investmentNeural architecturesText database queryingEnterprise project managementData science
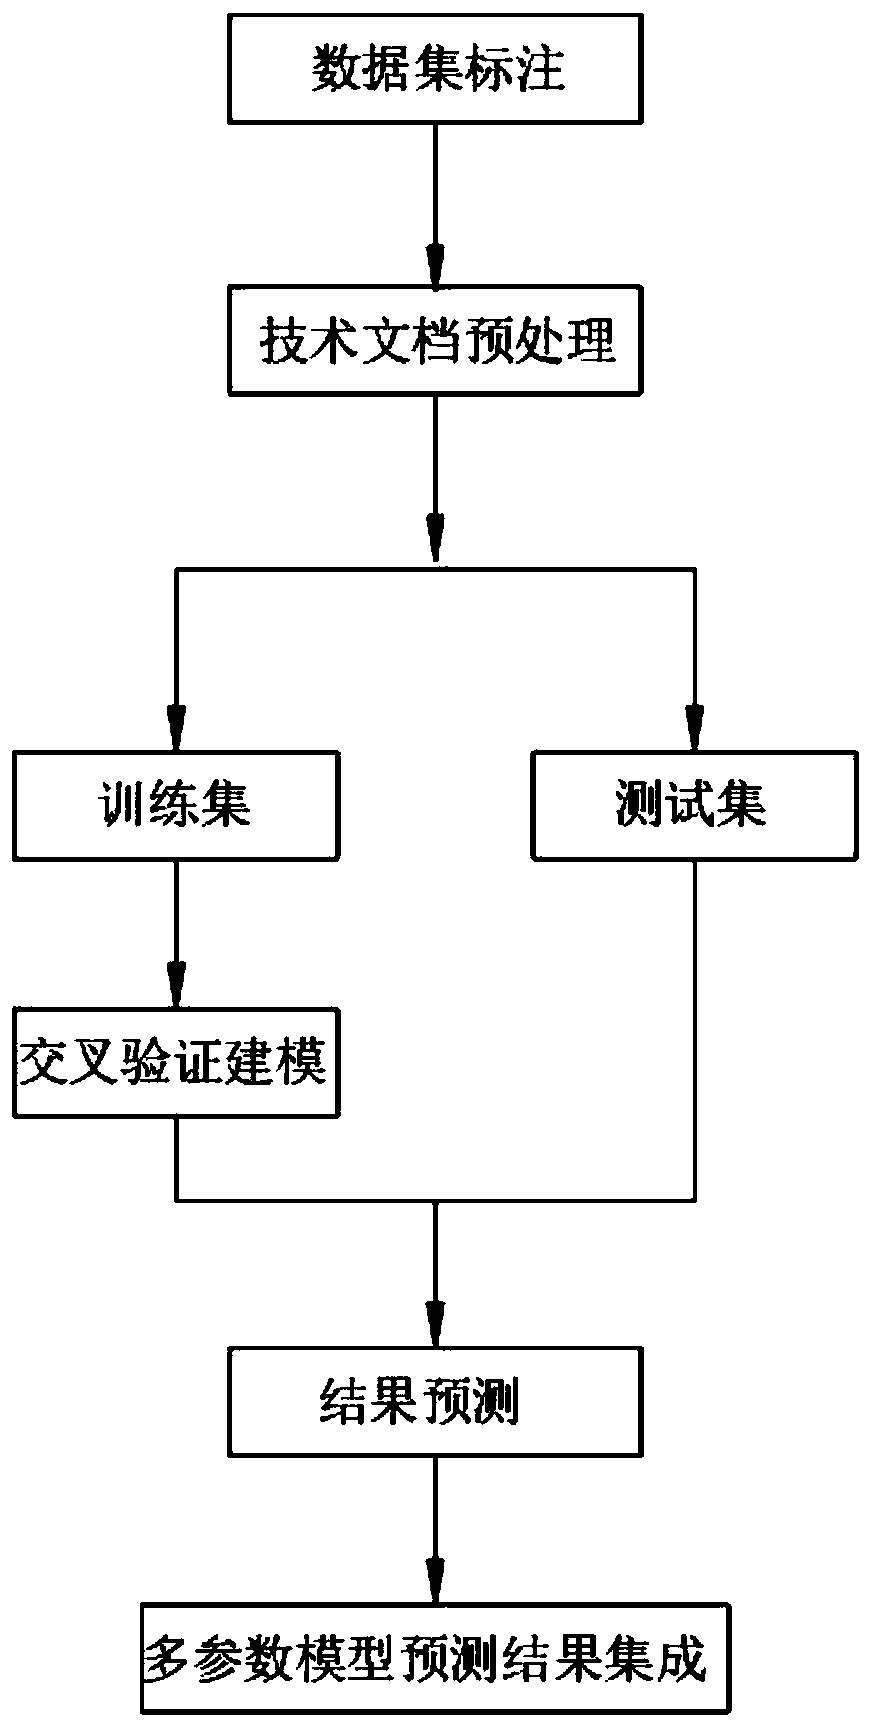
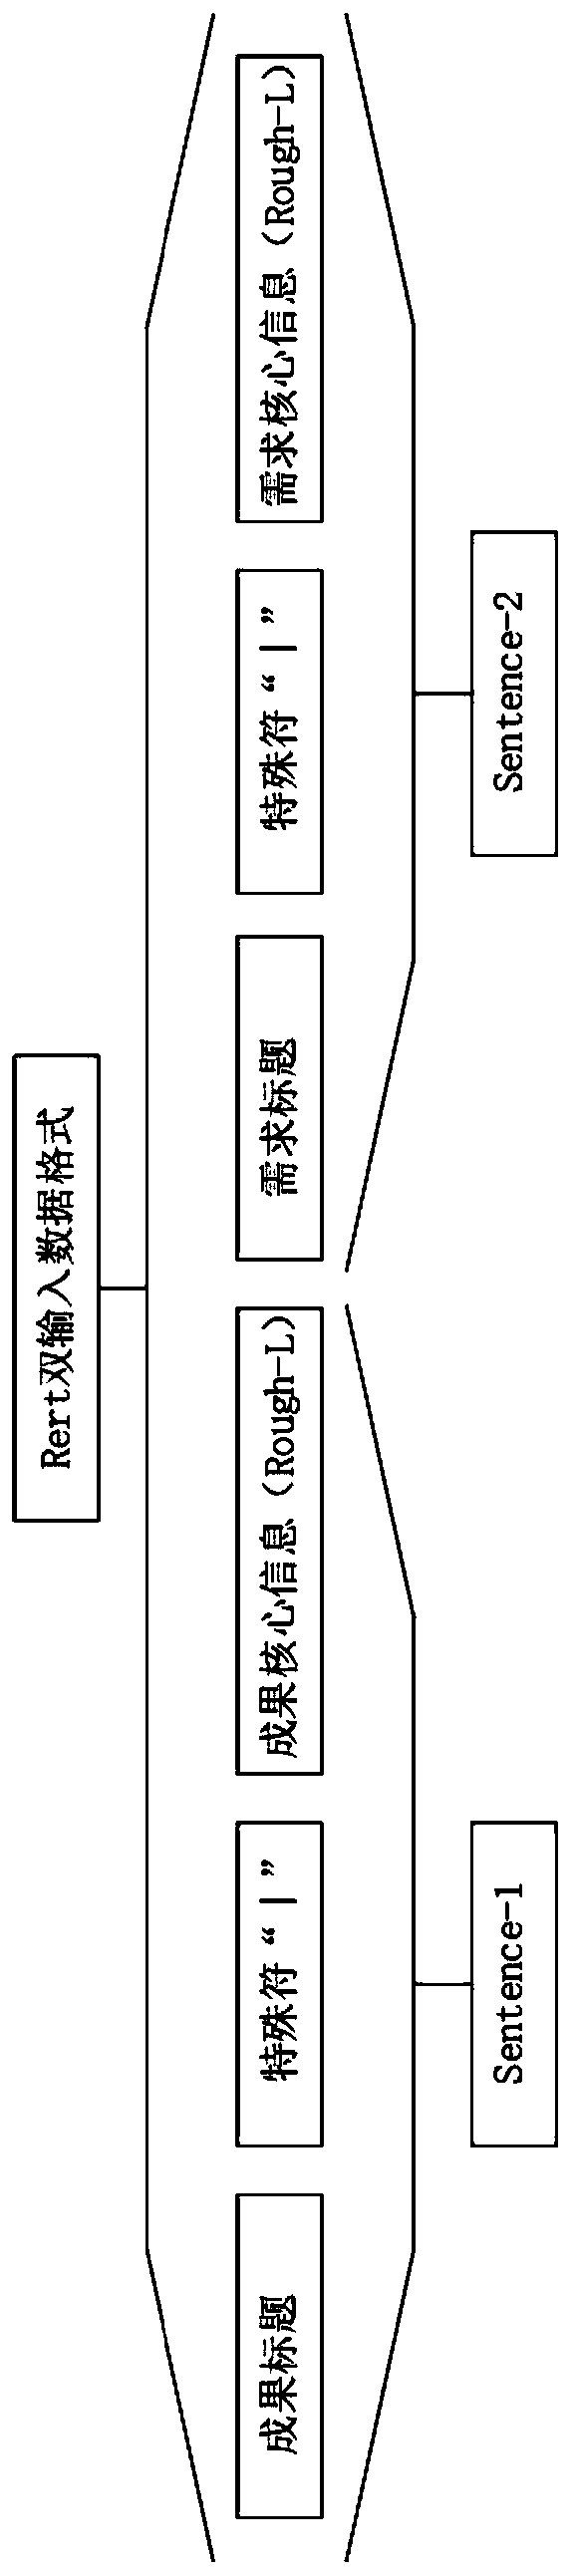
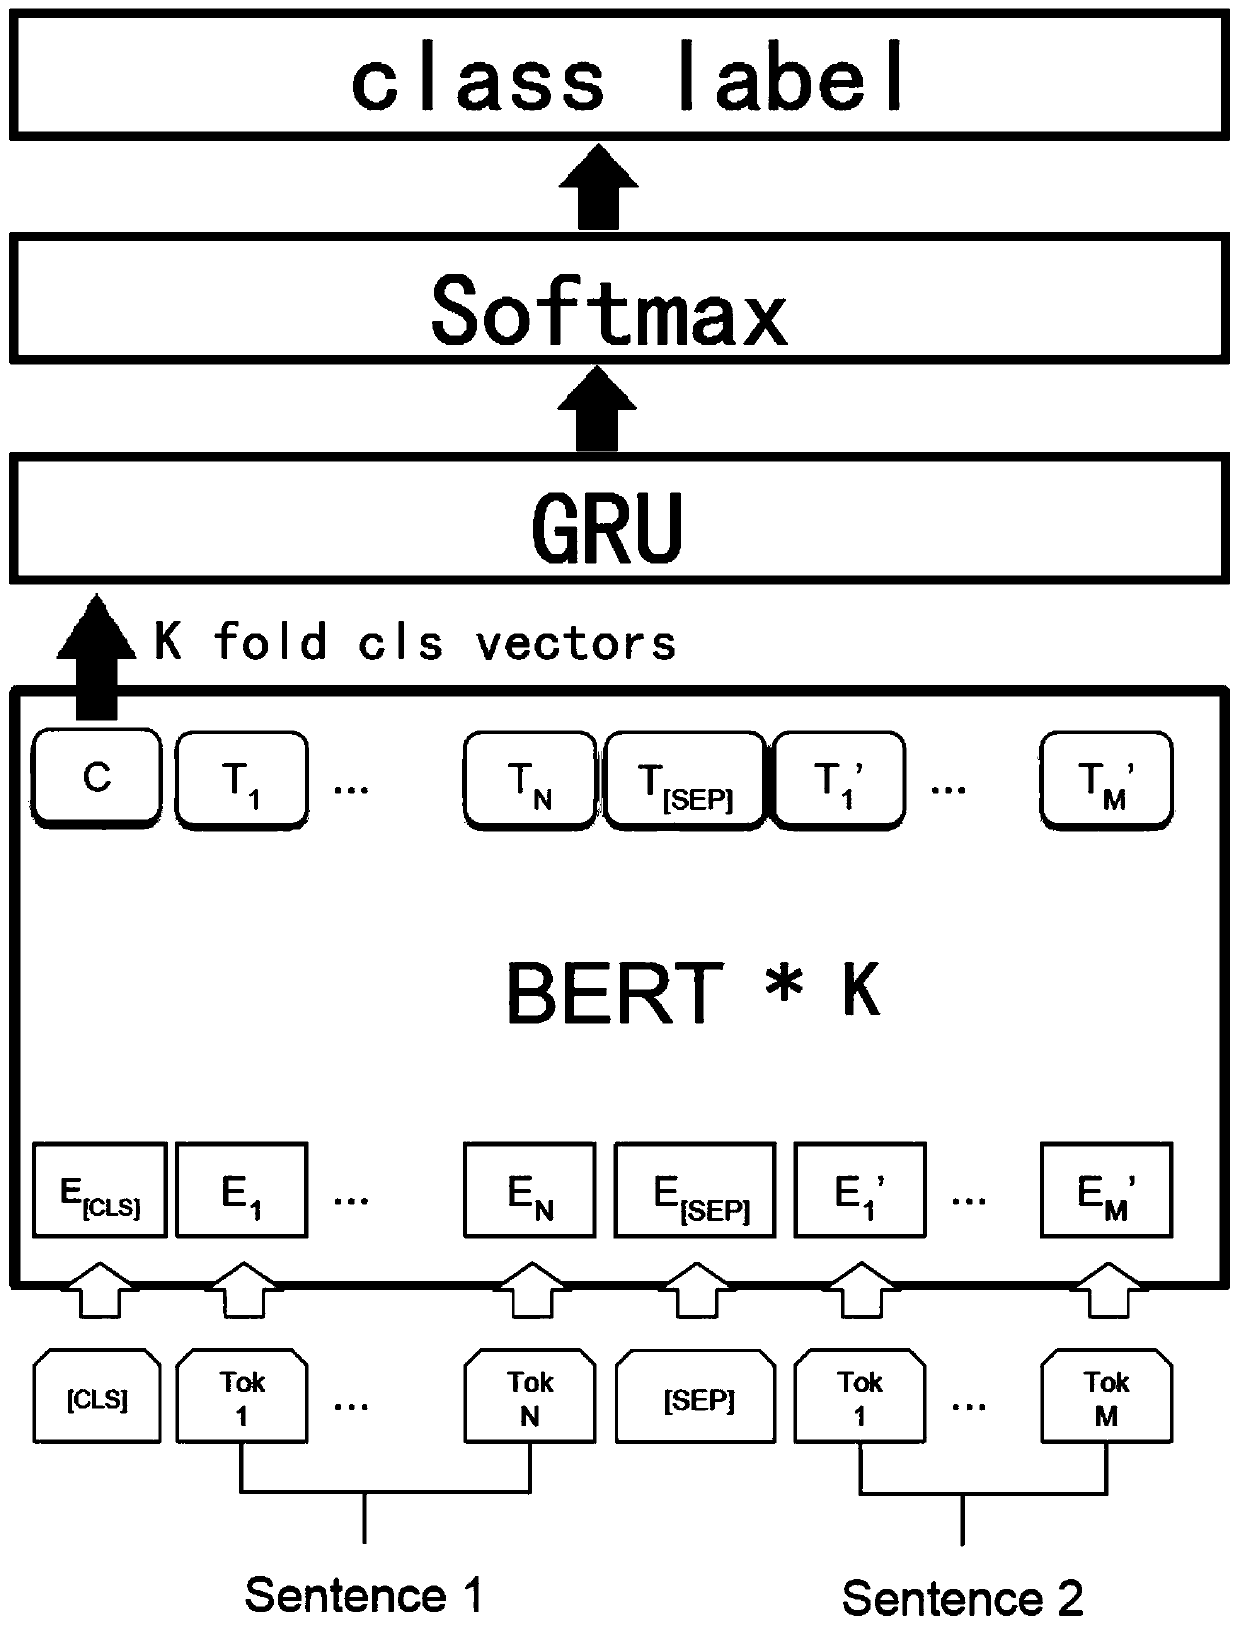
The invention discloses a method for analyzing a matching degree between a demand and an output result based on text semantics. The method comprises the following steps: step 1, labeling a data set; step 2, technical document preprocessing; 3, training and predicting a single-parameter model; 4, integrating prediction results of the multi-parameter model; the method has the beneficial effects thatthe method is simple; deep learning and the NLP technology are applied to the field of project association degree calculation of enterprise project management for the first time. Calculating an association matching degree between the two projects according to project requirements and result description; the associated project positioning difficulty is effectively reduced; meanwhile, the demand side can be helped to quickly and efficiently locate high-quality projects adapting to the demand of the demand side; time and resource investment for achievement screening and matching are greatly reduced, the association matching degree between projects is calculated by means of text data of existing project achievement technical documents and project declaration guidelines, and then large enterprises are assisted in screening high-quality projects with the high matching degree in the project bidding and tendering link.
Owner:普华讯光(北京)科技有限公司
Retrieval augmented generative question and answer boosting
ActiveUS20250328565A1Natural language translationSpecial data processing applicationsTheoretical computer scienceScientific instrument
Systems or techniques are provided for facilitating retrieval augmented generative question and answer boosting. In various embodiments, a system can access a plain text question regarding a scientific instrument. In various aspects, the system can generate, via a large language model that references a document-graph repository, a structured or unstructured answer for the plain text question. In various instances, the document-graph repository can comprise a plurality of document-graphs that respectively correspond to a plurality of technical documents. In various cases, for a first document-graph that corresponds to a first technical document, leaf nodes of the first document-graph can represent respective text blocks written in the first technical document, and non-leaf nodes of the first document-graph can respectively represent a document title, one or more section headings, and one or more scientific instrument identifiers written in the first technical document and beneath which the respective text blocks are nested.

Owner:PPD DEVELOPMENT LP +2
Generating a response for a communication session based on previous conversation content using a large language model
ActiveUS20250307290A1Special data processing applicationsText database queryingHuman–computer interactionData science
An example operation may include one or more of receiving interaction content from a communication session between a source device and a service provider device of a service provider, identifying a search criteria from the interaction content, retrieving a subset of vectors from a plurality of vectors stored in a vector database based on the search criteria of the interaction content, wherein the subset of vectors includes previous interaction content with the service provider, generating a response for the communication session based on execution of a large language model (LLM) on the subset of vectors, and outputting the response to at least one of the source device and the service provider device during the communication session.

Owner:THE TORONTO DOMINION BANK
Chunk synthesis for retrieval augmented generation assistants
A query answering system may access a collection of data sources to populate an index. A query answering system derives content from a collection of data sources to create synthetic chunks that are each representative of a portion of content from one or more of the data sources. A query answering system populates the index with the synthetic chunks. A query answering system identifies a subset of the synthetic chunks as relevant to a user query, generates a large language model (LLM) prompt that includes the subset of the synthetic chunks from the index and the user query, provides the LLM prompt to an LLM., and generates a response to the user query based on output of the LLM.

Owner:MICROSOFT TECHNOLOGY LICENSING LLC
System and method for dynamic optimization of artificial intelligence conversational prompts
A system and method for optimizing automated textual prompts in artificial intelligence (AI) conversational systems is disclosed. The system comprises a network interface, processors, and memory-storing instructions for performing operations to optimize prompts. These operations include receiving and preprocessing input data, tokenizing the data, verifying data authenticity, performing temporal analysis, calculating prompt complexity scores, and selectively expanding or refining prompts based on complexity thresholds. The system further incorporates context-aware optimization, multi-faceted prompt refinement, variation generation, and evaluation using machine learning models. Additional features include a technological hub with advanced processing capabilities, sensor-augmented input apparatus, device-specific prompt optimization, AI model selection, multimodal context integration, and an AI-driven creativity booster. The system provides interactive prompt visualization, certification, and uniqueness verification modules. This comprehensive approach ensures the generation of optimized, contextually relevant, and creative prompts for various AI applications while maintaining data integrity and user engagement.

Owner:VIERI RICCARDO
Open environment-oriented missing modal gamma collaborative retrieval diffusion method
PendingCN120724376ASpecial data processing applicationsNeural learning methodsMultimodal learningBiology
The invention discloses a missing mode gamma collaborative retrieval diffusion method for an open environment, and belongs to the field of multi-mode learning and missing mode processing. According to the method, a human brain multi-source context completion mechanism is simulated, and robust multi-modal learning is realized through three innovative modules: a context retrieval enhancement module: a multi-modal memory library is constructed, related instances are retrieved through similarity calculation under a gating mechanism, and context representation of a missing mode is enhanced; the prompt drive diffusion generation module is used for constructing a semantic prompt based on a retrieval result, fusing a de-noising diffusion probability model through an attention mechanism, and realizing context-aware knowledge migration and missing modal generation; and the inverse gamma noise optimization module is used for establishing a mixed normal-inverse gamma distribution model, dynamically sensing noise, realizing uncertainty estimation in multi-modal fusion and ensuring robustness and reliability of a regression result. According to the method, the dependence of the model on the available modal quality is effectively reduced, and the cross-modal knowledge migration effect and the multi-modal learning task performance are improved.

Owner:UNIV OF ELECTRONICS SCI & TECH OF CHINA
Pre-prompt and prompt engineering for language generation
PendingUS20250371283A1Natural language translationSpecial data processing applicationsUser deviceEngineering
A method of automatic pre-prompt generation includes receiving at least one user preference from a user device, modifying a system prompt for a machine-learning language model based on the received at least one user preference to generate a modified system prompt, providing the modified system prompt as an initial input to the machine-learning language model, receiving a natural-language text prompt provided by the user to a chat application on the user device, receiving a user identifier from the user device, querying a first database with the user identifier to retrieve first information, generating a representation of the first information and the natural-language prompt, querying a second database using the representation to retrieve second information, and generating a modified text prompt based on the natural-language prompt, the first information, and the second information.

Owner:INSIGHT DIRECT USA INC
Large language model federated fine-tuning method and apparatus based on gradient compression
PCT designated stageWO2025260391A1Biological modelsComputer security arrangementsData privacy protectionData set
Disclosed in the present invention are a large language model federated fine-tuning method and apparatus based on gradient compression. The method comprises the following steps: constructing, on the basis of a gradient tensor generated during fine tuning of a large language model, a raw data set having a time series relationship, performing inference by means of an autoencoder to obtain a reconstructed gradient data set, and constructing a reconstruction loss function to optimize the autoencoder; and initializing a base model of the large language model as a global model at a server end, the server end updating the global model to a client, using a pre-trained encoder to obtain a compressed gradient at the client, and at the server end, using a pre-trained decoder to decode and aggregate the compressed gradient, and then updating the global model. The present invention can improve the fine-tuning efficiency of the large language model and reduce computing resource requirements while ensuring data privacy protection, and is suitable for application scenarios such as communication optimization improvement and privacy protection enhancement in the process of scientific computing-oriented large model fine-tuning and training.

Owner:ZHEJIANG LAB
Machine learning-based management of feedback data
PendingUS20250307302A1Special data processing applicationsText database queryingGeneration processGenerative process
An apparatus includes at least one processing device including a processor coupled to a memory, wherein the at least one processing device is configured to modify first data obtained from one or more sources, wherein the modifying includes adding user context data to the first data to generate second data, the second data representing the first data supplemented with a per-user context and, in response to receipt of a query, generate a response to the query using at least one generative language model supplemented by a retrieval augmented generation process based on at least a portion of the second data.

Owner:DELL PROD LP
Systems and methods for querying graph databases using natural language queries
A method for querying a graph database using natural language queries comprises: receiving a natural language user query; identifying one or more node types from a type graph in the natural language user query, wherein the one or more node types correspond to one or more words or phrases in the natural language user query; generating, using a large language model, a graph database query based on the one or more node types identified in the natural language user query; querying a graph database using the graph database query generated by the large language model; receiving results of the graph database query; and generating, using the large language model, a natural language response to the natural language user query based on the results of the graph database query.

Owner:THE MITRE CORPORATION
Digital content generation with in-prompt hallucination management for conversational agent
ActiveUS12505137B1Special data processing applicationsText database queryingDigital contentConversational search
A device may provide a prompt to a first machine learning model. The prompt may include at least one instruction to cause the first machine learning model to use at least first natural language input associated with a use of a conversational search system to rank data sources, generate a first search query and reasoning, and use the first search query and the reasoning to generate a second search query. The first search query may include data obtained from at least one of the ranked data sources. The reasoning may include an explanation of how the first machine learning model generated the first search query. A second machine learning model may synthesize a response determined via execution of the second search query. The synthesized response may be provided for presentation via the conversational search system.

Owner:MICROSOFT TECHNOLOGY LICENSING LLC
Systems and method for enhanced conversational performance of large language models using adaptive retrieval-augmented generation
PendingUS20250378092A1Special data processing applicationsText database queryingResponse generationEngineering
Systems and methods for enhanced conversational performance of large language models using adaptive retrieval-augmented generation are disclosed. A method may include: (1) receiving a query from a user; (2) retrieving a plurality of summaries of historical conversations from a database of historical conversation summaries similar to the query; (3) generating a first prompt comprising the query and the plurality of summaries; (4) submitting the first prompt to a first large language model (LLM); (5) receiving, from the first LLM, a first response; (6) presenting the first response to the user; (7) generating a second prompt for a summary of the query and the first response; (8) submitting the second prompt to a second LLM; and (9) saving a second response to the second prompt from the second LLM to the database of historical conversation summaries, wherein the second response comprises the summary.

Owner:JPMORGAN CHASE BANK NA +1
System and method of semantic search scoring for hierarchically related artificial intelligence productivity tool-enablable application capabilities for a user query input at an information handling system
A system and method for executing computer readable code instructions for an on-the-box (OTB) artificial intelligence (AI) productivity tool comprising a hardware processor accessing capabilities associated with each of a plurality of AI productivity tool-enablable software applications, a natural language capabilities database memory to store natural language descriptions of the capabilities and capability intent values generated from the natural language descriptions in a capabilities decision tree with each capability node grouped under a branch of the capabilities decision tree according to logical topics in hierarchical parent-child relationships, the hardware processor generating a query input intent value from a user query input and performing a cosine semantic similarity search comparing the capability intent values of the capability nodes along the branch of the capabilities decision tree for identifying a best match capability node having a highest cosine semantic similarity search score, and the hardware processor executing the best match capability.

Owner:DELL PROD LP
Data preparation method, system, and device for AIGC-based interaction analysis, and medium
PCT designated stageWO2025227532A1Natural language data processingEnergy efficient computingDigital dataAlgorithm
The present application relates to the technical field of electric digital data processing, and provides a data preparation method, system, and device for AIGC-based interaction analysis, and a medium. The method comprises: by means of a pre-trained text label recognition model, determining a label sequence corresponding to an interaction statement having experienced first word segmentation processing; on the basis of a preset expression construction rule, determining a label combination sequence corresponding to the label sequence and a conditional expression corresponding to the label combination sequence; by means of a preconfigured database candidate text dictionary and a preset matching rule, determining a strictly matched keyword and a fuzzily matched keyword corresponding to the interaction statement having experienced second word segmentation processing; on the basis of the strictly matched keyword and a similar candidate text corresponding to the fuzzily matched keyword, determining a word segmentation result corresponding to the second word segmentation processing; on the basis of a plurality of preset SQL statement rule matching templates, generating an interaction SQL query statement, so as to determine, on the basis of the interaction SQL query statement, interaction response information corresponding to the interaction statement.

Owner:INSPUR GENERSOFT CO LTD
Enterprise knowledge base retrieval and intelligent answering method and system based on large language model
The invention discloses an enterprise knowledge base retrieval and intelligent answering method and system based on a large language model. The method comprises the following steps: performing clause-level segmentation on an enterprise knowledge base document, associating document metadata to form structured knowledge entries, and establishing a keyword reverse index and a semantic vector index for the structured knowledge entries; analyzing the natural language query of the user, and performing multi-strategy expansion to generate an enhanced query expression and a query semantic vector; performing dual-channel mixed retrieval, performing duplicate removal, version filtering and weighted fusion sorting on a result, and generating a final candidate knowledge item list; and based on the candidate list and a predefined instruction, calling a large language model to generate a structured answer with complete traceability information. The method is compatible with an existing retrieval framework, precise understanding, knowledge point-level positioning, cross-document content integration and version consistency control of natural language problems are achieved, and the retrieval accuracy, answer availability and service intelligence level of an enterprise knowledge base are remarkably improved.

Owner:XIAMEN YUANTING INFORMATION TECH CO LTD
Artificial intelligence medical diagnosis system based on multi-dimensional information fusion
The invention belongs to the technical field of artificial intelligence, and particularly relates to an artificial intelligence medical diagnosis system based on multi-dimensional information fusion. Comprising the steps that a self-adaptive diagnosis path planning module judges whether a user request belongs to a preset non-diagnosis and treatment category or not, if yes, a quick response path is activated, and a standardized answer is retrieved and returned to a user; the preliminary diagnosis module generates a candidate disease hypothesis list, verifies the candidate disease hypothesis list and outputs a verified disease hypothesis list; the dynamic knowledge enhancement module generates missing knowledge according to the disease knowledge graph and the query verification disease hypothesis list and supplements the missing knowledge into the medical knowledge graph; a composite confidence evaluation module performs confidence evaluation on each hypothesis disease in the verification disease hypothesis list, and outputs a final disease confidence; the result integration module sorts the final disease confidence in a descending order and integrates the multi-dimensional information of each hypothetical disease to generate a structured differential diagnosis report; the system and the method can assist doctors in realizing high-accuracy, high-reliability and explainable intelligent medical diagnosis.

Owner:SHANGHAI-CHONGQING ARTIFICIAL INTELLIGENCE RES INST
Large language model (LLM)-based knowledge resource retriever and ranker
Disclosed herein are a system, method, and computer program product embodiments for retrieving and ranking knowledge resources relevant to a query from knowledge base(s). For example, a query for resources from knowledge base(s) may be received. Based on the query, a first set of candidate resources are obtained from the knowledge base(s) having a lexical similarity to the query search terms, and a second set of candidate resources are obtained from the knowledge base(s) having a semantical similarity to the search terms. For each of the first and second sets of candidate resources, a confidence level indicating the relevance of the candidate resource to the query is determined. The sets of candidate resources are ranked based on at least the confidence levels to generate a ranked list of candidate resources. A query response comprising at least a subset of the ranked list candidate resources is provided to a GUI.

Owner:SAP SE
Directory perception-based long document knowledge base construction method and program product
The invention discloses a long document knowledge base construction method based on directory perception and a program product, and belongs to the field of artificial intelligence and natural language processing. According to the scheme, an original long document is sequentially subjected to preprocessing, directory structure analysis, mixed blocking, double-tag generation, tag intelligent optimization, vectorization and meta-information mounting, and finally automatic construction and high-quality retrieval enhancement generation of a knowledge base are achieved. According to the method, the semantic integrity is guaranteed by fully utilizing the perceptual ability of the directory structure, the label quality and the retrieval efficiency are improved by combining a double-label system and intelligent optimization circulation, and the construction efficiency, the retrieval accuracy and the result traceability of the knowledge base are remarkably improved; the method is suitable for intelligent processing and application of long complex structure documents such as academic specialities, technical documents, policies and regulations and the like.

Owner:SOUTHEAST UNIV
Digital content generation with in-prompt hallucination management for conversational agent
ActiveUS20250390525A1Special data processing applicationsText database queryingDigital contentConversational search
A device may provide a prompt to a first machine learning model. The prompt may include at least one instruction to cause the first machine learning model to use at least first natural language input associated with a use of a conversational search system to rank data sources, generate a first search query and reasoning, and use the first search query and the reasoning to generate a second search query. The first search query may include data obtained from at least one of the ranked data sources. The reasoning may include an explanation of how the first machine learning model generated the first search query. A second machine learning model may synthesize a response determined via execution of the second search query. The synthesized response may be provided for presentation via the conversational search system.

Owner:MICROSOFT TECHNOLOGY LICENSING LLC
Section-based chunking technique for Retrieval-Augmented Generation (RAG) with Large Language Models (LLMs)
PendingUS20250335483A1Text database indexingSpecial data processing applicationsEngineeringDocumentation
Systems, methods, and non-transitory computer-readable media are provided for conducting user query searches. According to one implementation, a process includes a step of, in response to receiving a user query directed to subject information retrievable from documentation stored in a private database, using a section-based chunking procedure to obtain, from the private database, a relevant section of the documentation as context. The process further includes a step of feeding the user query and the relevant section as context to a Large Language Model (LLM).

Owner:CIENA CORP
User- and operator-specific system prompts for language generation
PendingUS20250371054A1Relational databasesSpecial data processing applicationsUser deviceLinguistic model
A method of automatic pre-prompt generation includes receiving, by a user device, an indication of at least one user preference, where the at least one user preference indicative of at least one first characteristic preferred by a user of natural-language outputs generated by a machine-learning language model. The method further includes, by a server, receiving a natural-language text prompt provided by the user, receiving the at least one user preference from the user device, modifying a system prompt based on the received at least one user preference and the at least one first operator preference, providing the modified system prompt as an initial input to the machine-learning language model, providing the natural-language text prompt as an input to the machine-learning language model to generate a natural-language text output after providing the modified system prompt, and transmitting the natural-language text output to the user device.

Owner:INSIGHT DIRECT USA INC
Analytics assistant using a large language model
PendingUS20260111466A1Special data processing applicationsText database queryingTable (database)Data science
Provided are system, apparatus, device, method and / or computer-program product embodiments, combinations and / or sub-combinations thereof for using an AI model to facilitate natural language interactions with databases. An example method can include receiving a natural language prompt associated with a user and identifying tables in a database based on the natural language prompt. The method can further include determining a table schema(s) of each of the tables identified, generating, using a large language model, a query to the tables in the database based on the natural language prompt and the table schema(s), and obtaining, using the query, data from at least one table of the tables in the database. The method can include generating, using the large language model or another large language model, a response to the natural language prompt based on the data obtained from the at least one table of the tables in the database.

Owner:ROKU INC
Evaluating retrieval system for language model processing
ActiveUS12579174B1Natural language translationSpecial data processing applicationsLinguistic modelData mining
Techniques for determining whether retrieved content is sufficient for a language model to generate a response to an input are described. In some embodiments, a system may determine a retrieval complexity (RC) metric based on a question, a reference answer and document results retrieved from a retrieval component (e.g., a search engine, a knowledge search, etc.). The RC metric may be based on whether one of the document results corresponds to the reference answer and whether the reference answer can be determined from the set of the document results (e.g., using two or more document results). The RC metric can be used to determine when retrieved content is to be used by a language model for responding to an input corresponding to the question.

Owner:AMAZON TECH INC
Data processing method based on large language model, and large language model and electronic device
PCT designated stageWO2025209055A1Physical realisationSpecial data processing applicationsLinguistic modelAlgorithm
Disclosed in the present application are a data processing method based on a large language model, and a large language model, an electronic device, a computer-readable storage medium and a computer program product. The method is applied to a user terminal, wherein a large language model is deployed on the user terminal, and weight parameters of linear calculation layers of the large language model are pre-quantized into format data of an integer data type. The method comprises: acquiring input data; performing vector conversion on the input data by means of an embedding layer of a large language model, so as to obtain a floating-point query vector of a floating-point data type corresponding to the input data; converting the floating-point query vector into an integer query vector of an integer data type; and performing an operation by means of weight parameters of linear calculation layers and the integer query vector, so as to obtain a query result corresponding to the input data. By means of the solution provided in the present application, a large language model can be smoothly run on a user terminal, such that the user terminal can provide services for users without needing network connectivity, and can better ensure the privacy of the users.

Owner:TAOBAO CHINA SOFTWARE
Methods and systems for updating a retrieval-augmented generation framework
PendingUS20260017302A1Special data processing applicationsText database queryingResponse generationTheoretical computer science
There is provided a computer method, system and device comprising detecting an updated iteration of a document for query response generation; comparing the updated iteration to a prior iteration to identify chunks of the updated iteration of the document that differ from corresponding chunks of the prior iteration, the prior iteration for generating a set of synthetic questions and answers using an LLM. Responsive to identifying that a given chunk of the updated iteration differs from a corresponding chunk of the prior iteration, the method triggers generation, using the LLM, of a new set of synthetic questions associated with corresponding text in the given chunk defining a new set of synthetic responses, and wherein the new set of synthetic questions and responses replaces at least a subset of the set of synthetic questions and answers associated together by a mapping with the corresponding chunk of the prior iteration.

Owner:SHOPIFY INC
Question answering method and apparatus, computing device, storage medium, and computer program product
PCT designated stageWO2025253185A1Semantic analysisMachine learningTheoretical computer scienceQuestion answer
Embodiments of the present disclosure provide a question answering method and apparatus, a computing device, a storage medium, and a computer program product. The question answering method comprises: determining a target question, a question answering field to which the target question belongs, a vector library corresponding to the question answering field, and a text library corresponding to the vector library; determining a target vector corresponding to the target question, determining, from the vector library, a template vector corresponding to the target vector, performing word segmentation on the target question, and determining, from the text library, a template text corresponding to a word segmentation result; on the basis of the template vector, the template text, the target vector and the target question, determining an initial answer corresponding to the target vector; when it is determined that a similarity result between the target vector and the initial answer satisfies a preset similarity condition, determining a first prompt text corresponding to the target vector on the basis of the initial answer; and using a language model and the prompt text to determine a target answer corresponding to the target question. The method improves the accuracy of determined target answers corresponding to target questions.

Owner:CLOUD INTELLIGENCE ASSETS HOLDING (SINGAPORE) PTE LTD
Context management in a hierarchical agent model
ActiveUS20250322000A1Special data processing applicationsText database queryingContext managementData class
In some embodiments, a method may include determining hierarchical agents including a first agent and a second agent based on a document defining a UI, the hierarchical agents having access to initial context data. The method may include delegating a task related to a UI element to the first agent based on information associated with the UI element and restricting portions of the initial context data available to the first agent to a propagated subset based on input data types mapped to the first agent and portions of the initial context data available to the second agent. The method may include generating interaction data by providing a machine learning model with the propagated subset and updating the document (e.g., by populating or interacting with the UI element based on the interaction data).

Owner:INVISIBLE PLATFORMS INC
Ranking-augmented generation for long documents
PendingUS20250342181A1Special data processing applicationsText database queryingLinguistic modelData mining
A computer-implemented method comprising: receiving, as input, a query and a source document intended for a content-grounded question-answering or multi-turn conversation task by a specified large language model (LLM) which has a context window size limit, wherein the source document has a size which exceeds the context window size limit; dividing the source document into a plurality of segments; applying a language model to each of the segments, to assign to each of the segments a relevance score; selecting the k-top segments having the highest the relevance scores; combining the selected k-top segments into a virtual document having a size which complies with the context window size limit; and feeding the virtual document as input to the specified LLM, to generate a response that is grounded in the content of the virtual document.

Owner:INTERNATIONAL BUSINESS MACHINE CORPORATION
Recursive multi-metric expansion for queries
PendingUS20250355905A1Machine learningSpecial data processing applicationsLinguistic modelProcessing
Methods, systems, apparatuses, devices, and computer program products are described. A processing device may receive a natural language query asking a question about a data metric. The processing device may use a large language model (LLM) to generate a summary of the natural language query for vector embedding. The processing device may determine one or more query response portions indicating possible answers to the query based on the summary and a vector database including vector representations of data summaries. To expand the scope of the answers, the processing device may recursively expand a set of data metrics for analysis. For example, the processing device may determine additional data metrics adjacent to the data metric of the query and may search the vector database for additional query response portions based on the additional data metrics. The processing device may use the query response portions to answer the natural language query.

Owner:SALESFORCE INC
Multi-level resource-utilization for service request generation with generative artificial intelligence
Service request generation using generative artificial intelligence is disclosed. For instance, a user query comprising character strings is received; the character strings are converted to initial vector values associated with a first continuous vector space. Groups of data representing knowledge base articles that are identified. The knowledge base articles are retrieved from first database equipment. The text content of the knowledge base articles is converted to further vector values associated with a second continuous vector space. A listing of support agent identities is determined based on the further vector values being proximate to additional vector values associated with the listing of support agent identities. The additional vector values are used to retrieve the listing of support agent identities from second database equipment and generate and transmit a service ticket to resolve the user query.

Owner:DELL PROD LP