
Patents
Literature
50 results about "Auto-text" patented technology
Efficacy Topic
Property
Owner
Technical Advancement
Application Domain
Technology Topic
Technology Field Word
Patent Country/Region
Patent Type
Patent Status
Application Year
Inventor
Auto-text is a portion of a text preexisting in the computer memory, available as a supplement to newly composed documents, and suggested to the document author by software. A block of Auto-text can contain a few letters, words, sentences or paragraphs. It can be chosen by the document author via menu or be offered automatically after typing specific words or letters (word prediction or text prediction), or be added to the document automatically after typing specific words or letters (word / text completion).
Category based, extensible and interactive system for document retrieval
InactiveUS20050108200A1High precisionReduction in relevant document recall rateWireless commuication servicesData switching networksDocument analysisPaper document
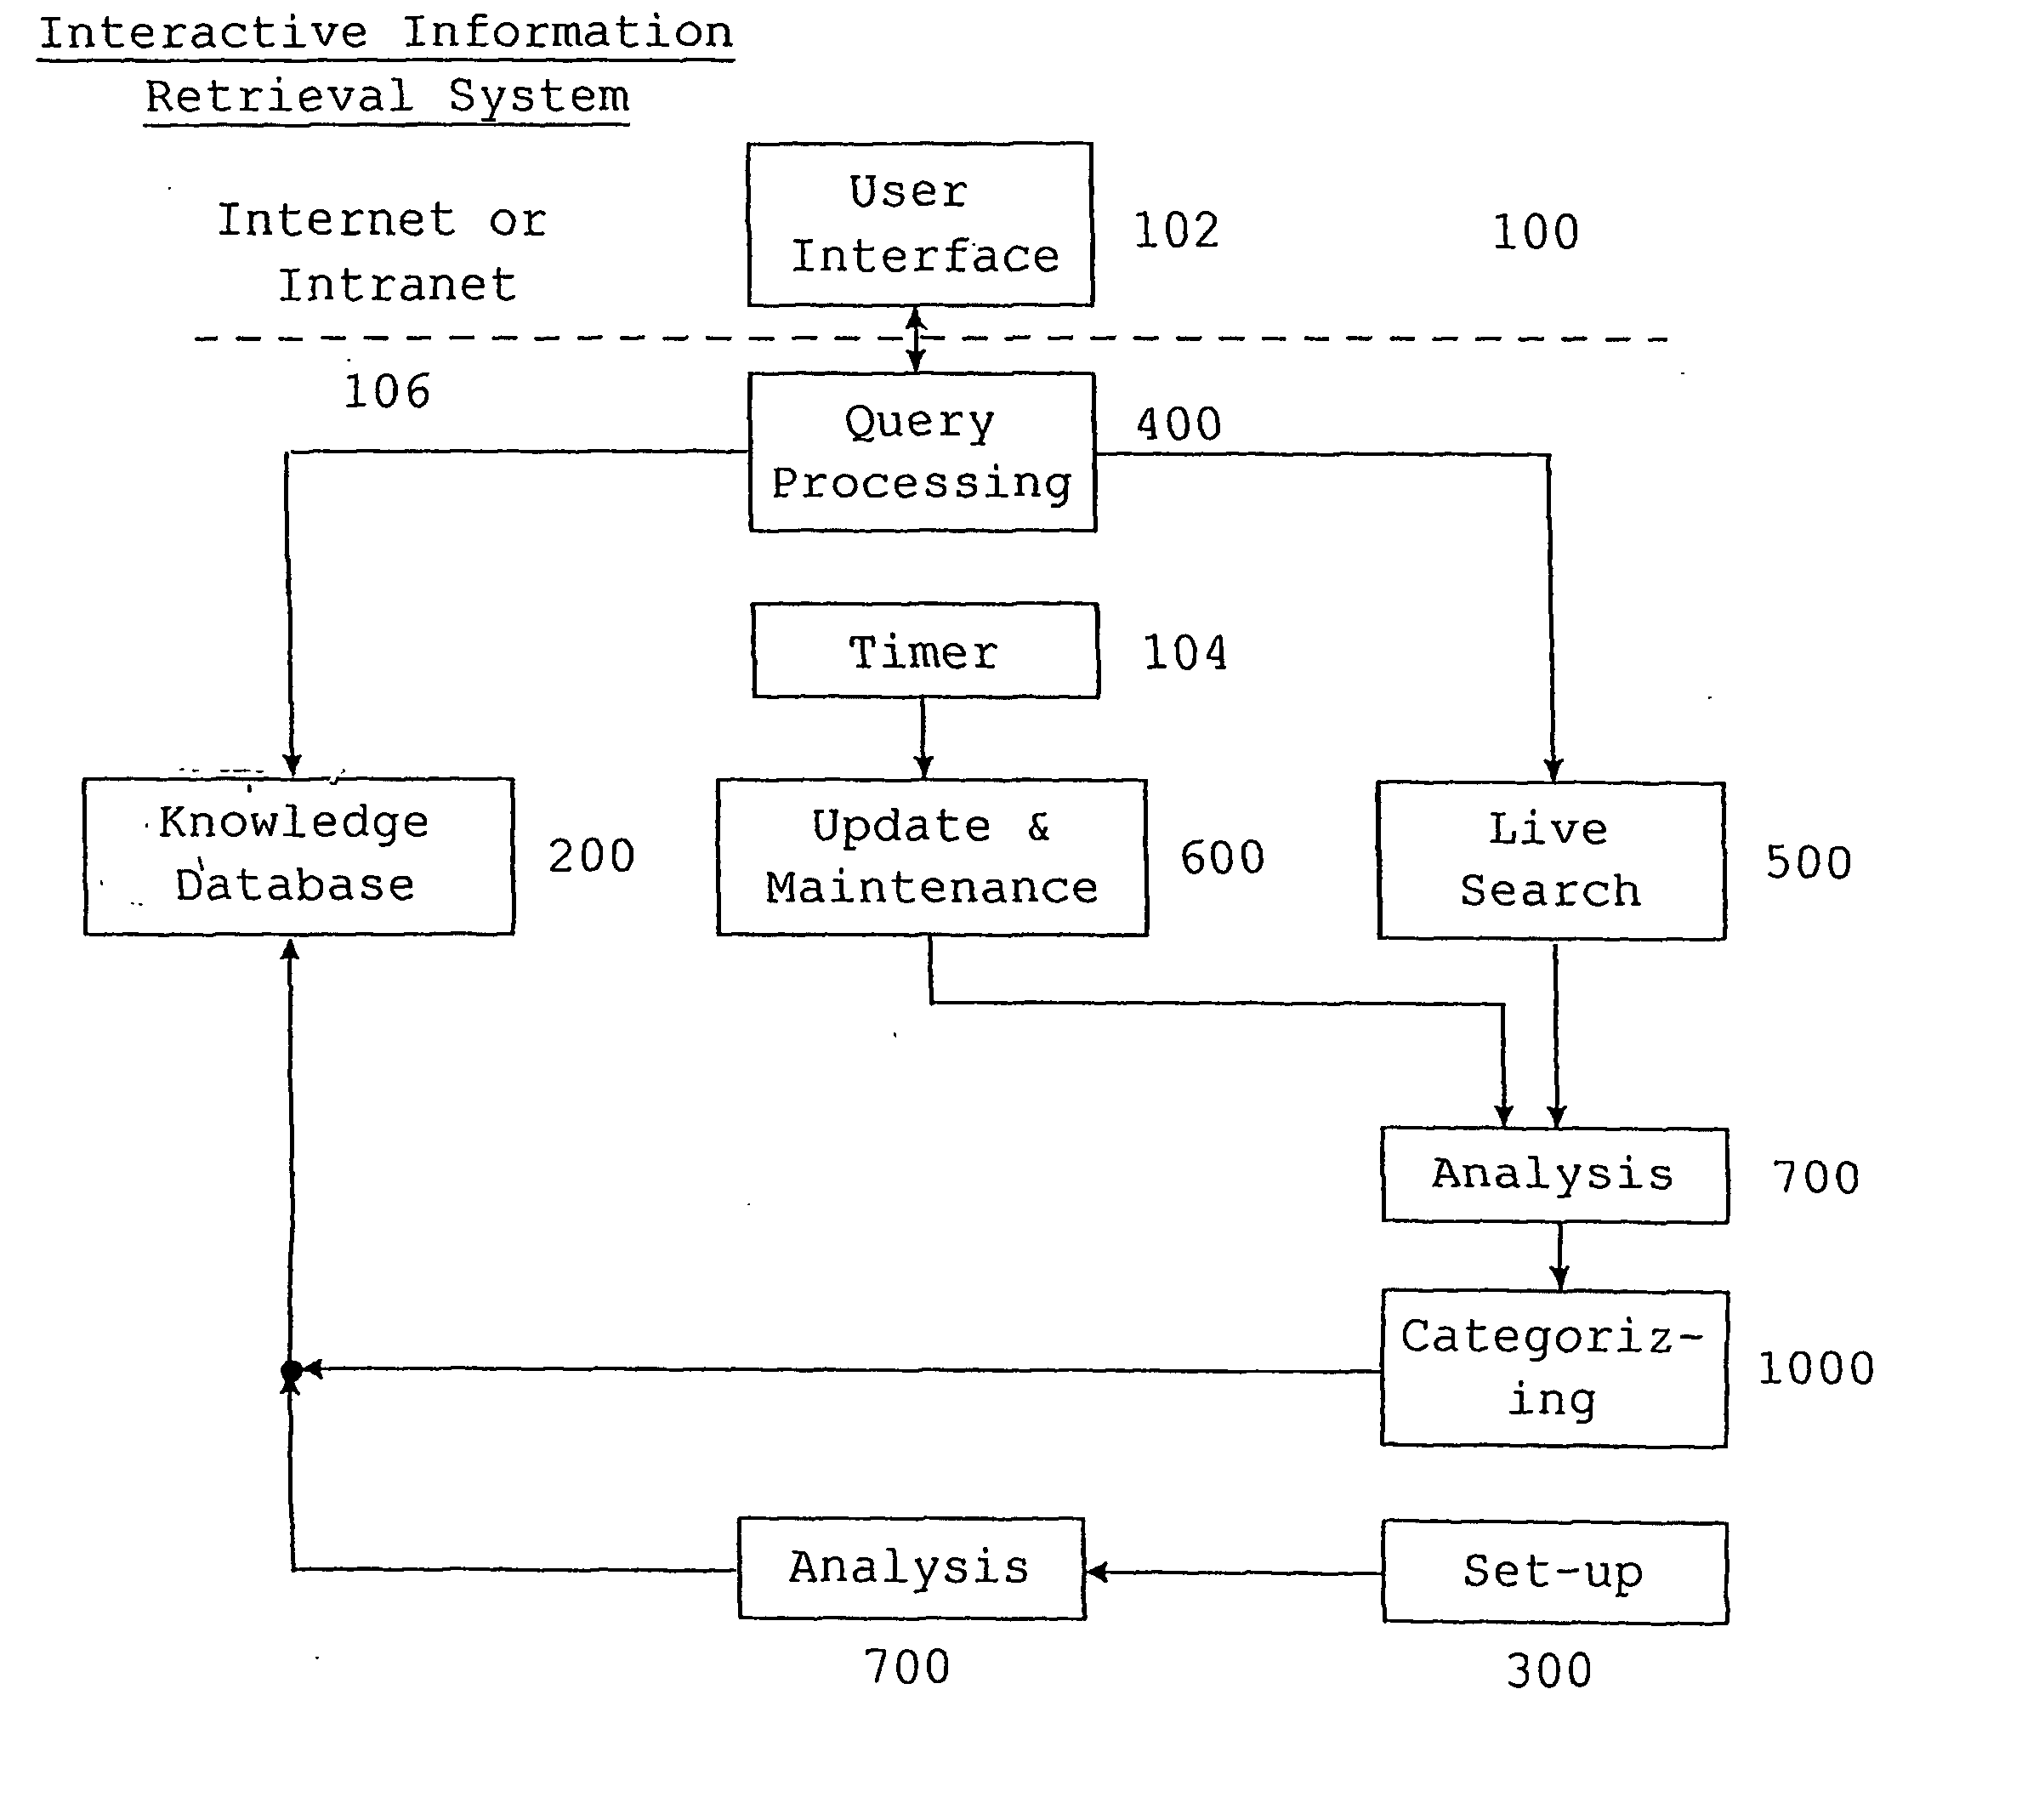
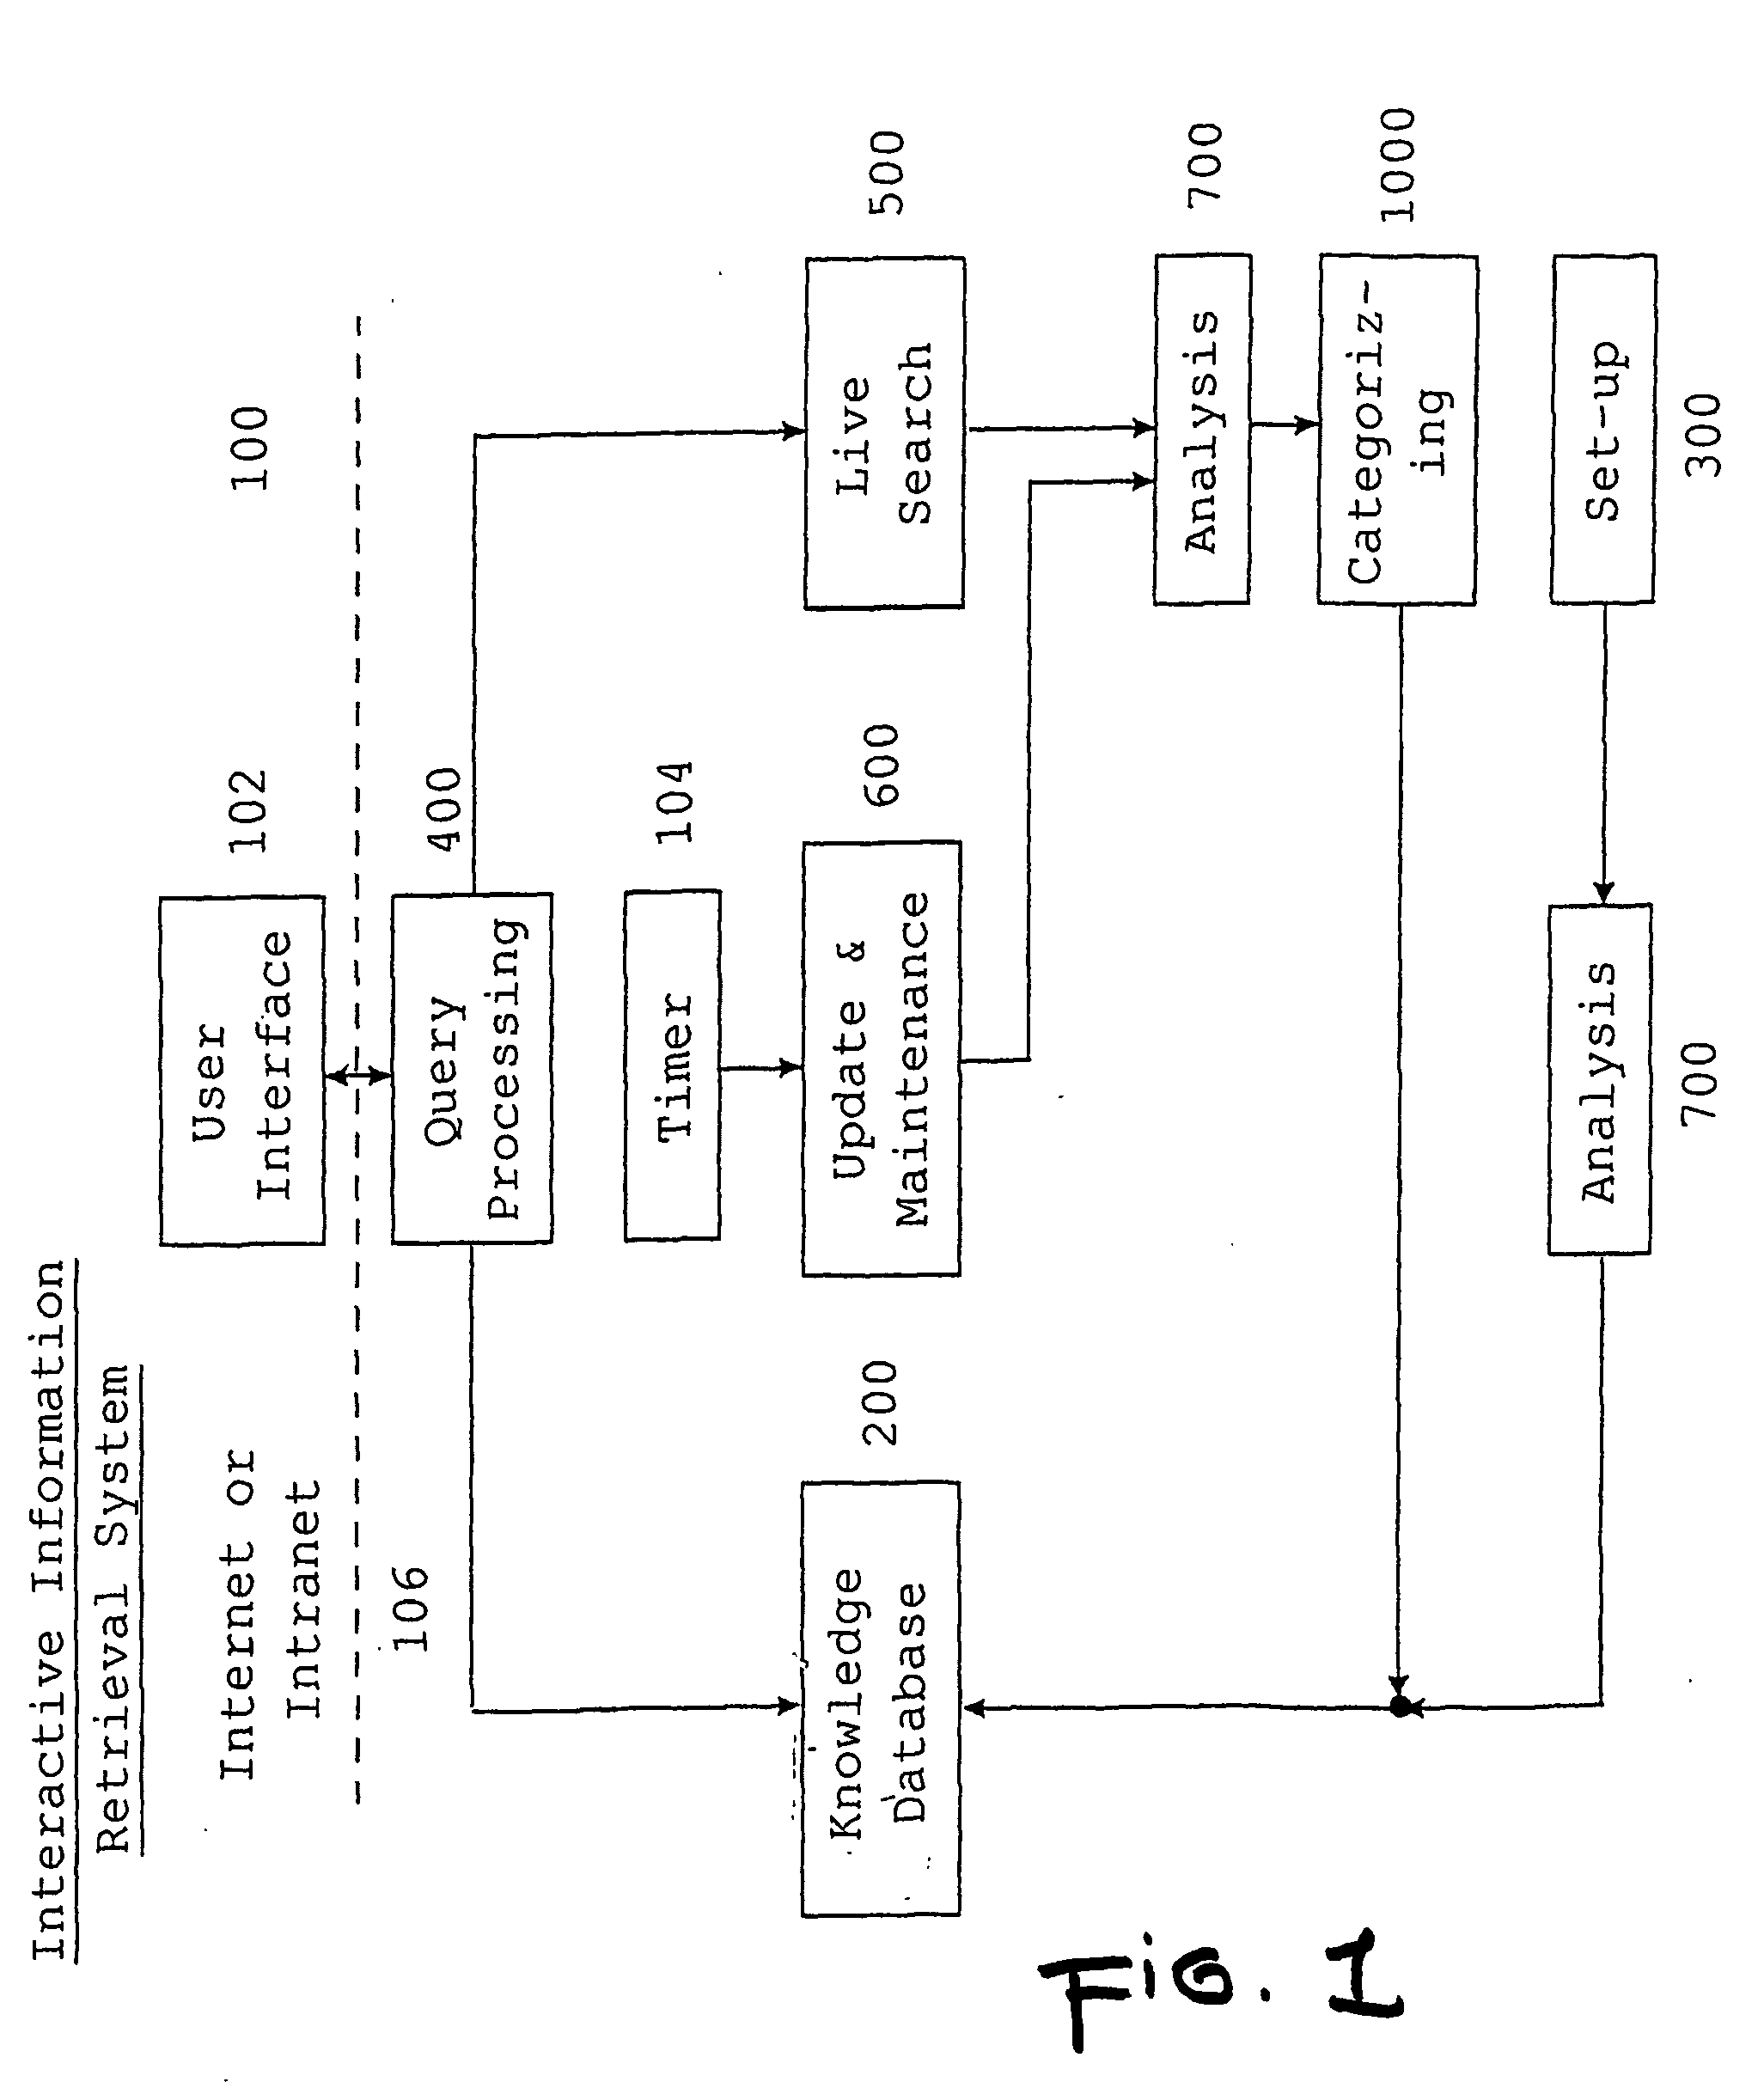
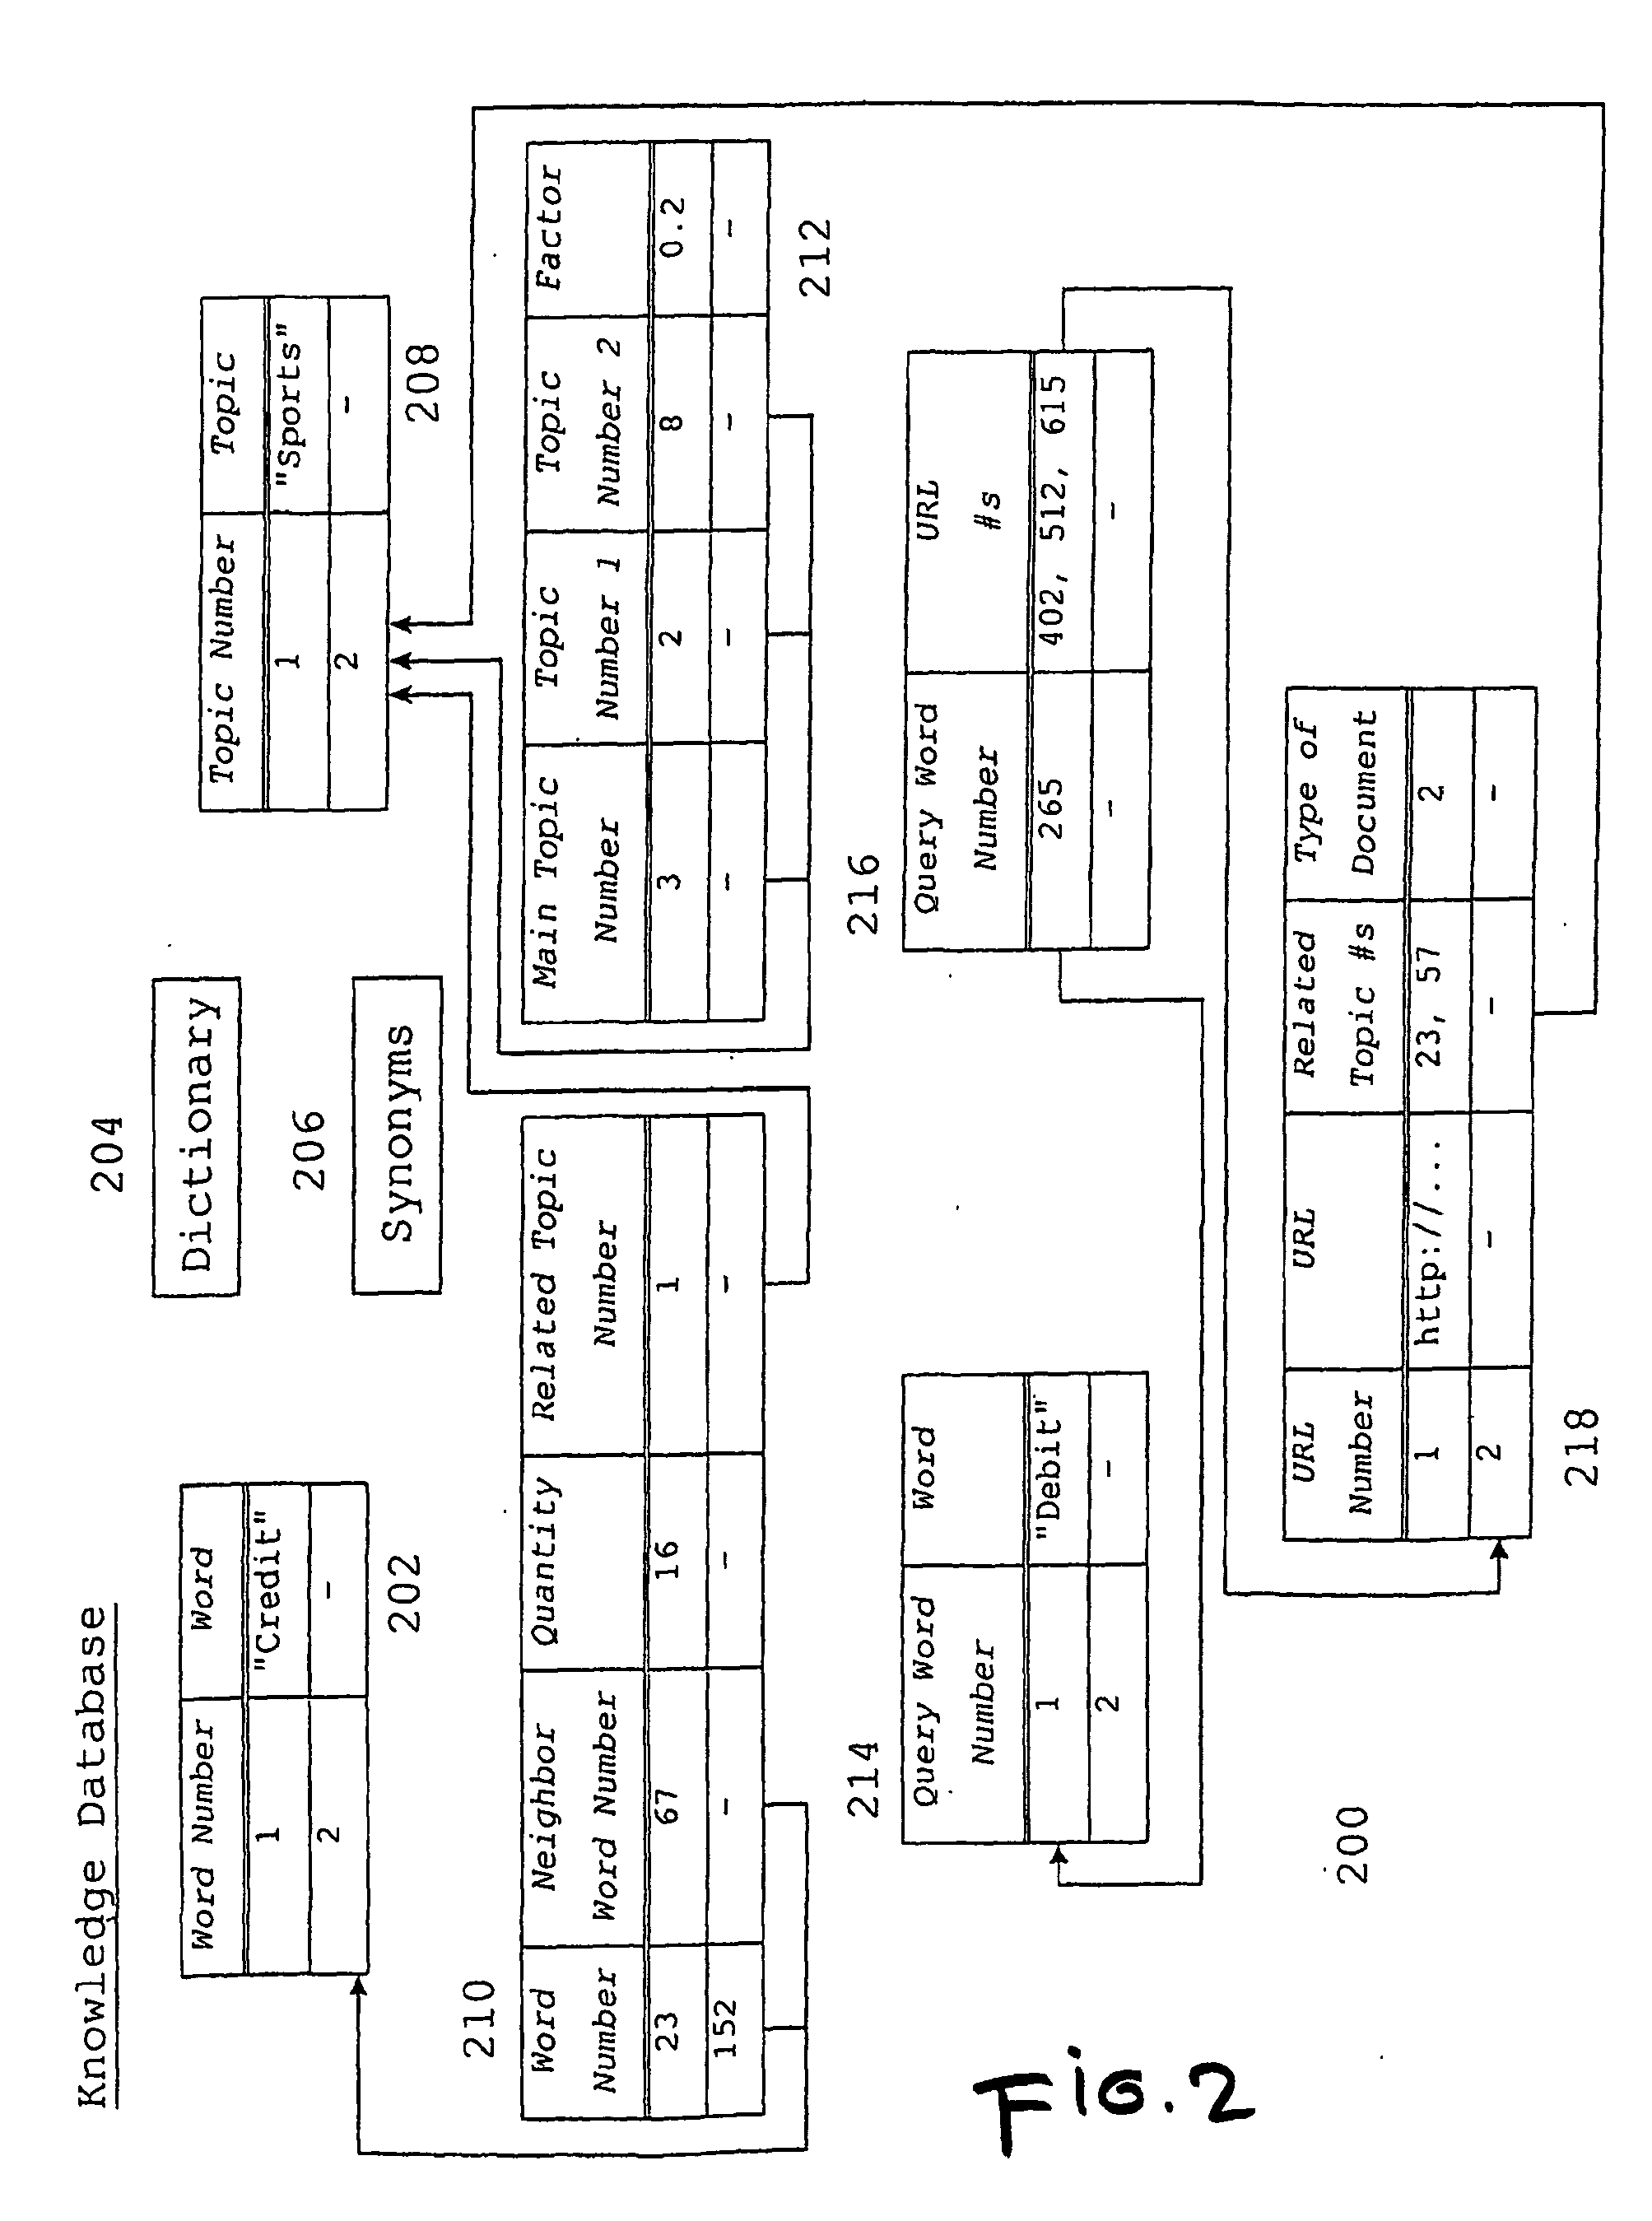
In information retrieval (IR) systems with high-speed access, especially to search engines applied to the Internet and / or corporate intranet domains for retrieving accessible documents automatic text categorization techniques are used to support the presentation of search query results within high-speed network environments. An integrated, automatic and open information retrieval system (100) comprises an hybrid method based on linguistic and mathematical approaches for an automatic text categorization. It solves the problems of conventional systems by combining an automatic content recognition technique with a self-learning hierarchical scheme of indexed categories. In response to a word submitted by a requester, said system (100) retrieves documents containing that word, analyzes the documents to determine their word-pair patterns, matches the document patterns to database patterns that are related to topics, and thereby assigns topics to each document. If the retrieved documents are assigned to more than one topic, a list of the document topics is presented to the requester, and the requester designates the relevant topics. The requester is then granted access only to documents assigned to relevant topics. A knowledge database (1408) linking search terms to documents and documents to topics is established and maintained to speed future searches. Additionally, new strategies are presented to deal with different update frequencies of changed Web sites.
Owner:COGISUM INTERMEDIA
Category based, extensible and interactive system for document retrieval
InactiveCN1535433AFulfil requirementsFast deliveryWireless commuication servicesData switching networksWeb siteDocument analysis
An integrated, automatic and open information retrieval system comprises an hybrid method based on linguistic and mathematical approaches for an automatic text categorization. It solves the problems of conventional systems by combining an automatic content recognition technique with a self-learning hierarchical scheme of indexed categories. In response to a word submitted by a requestor, said system retrieves documents containing that word, analyzes the documents to determine their word-pair patterns, matches the document patterns to database patterns that are related to topics, and thereby assigns topics to each document. If the retrieved documents are assigned to more than one topic, a list of the document topics is presented to the requestor, and the requestor designates the relevant topics. The requestor is then granted access only to documents assigned to relevant topics. A knowledge database linking search terms to documents and documents to topics is established and maintained to speed future searches. Additionally, new strategies are presented to deal with different update frequencies of changed Web sites.


Owner:COGISUM INTERMEDIA
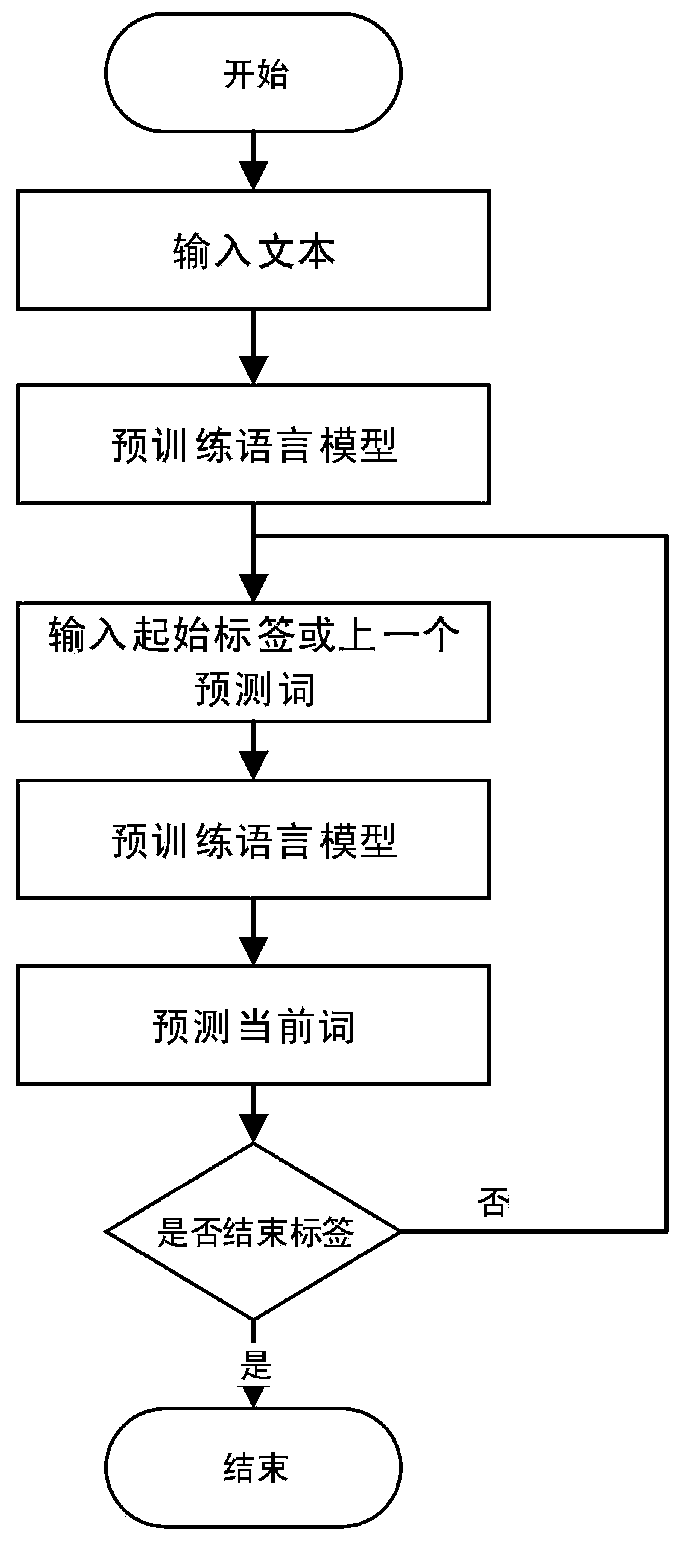
An automatic text abstraction method based on a pre-training language model
InactiveCN109885673ARich in featuresRich semantic informationSpecial data processing applicationsText database browsing/visualisationGenerative processHuman language
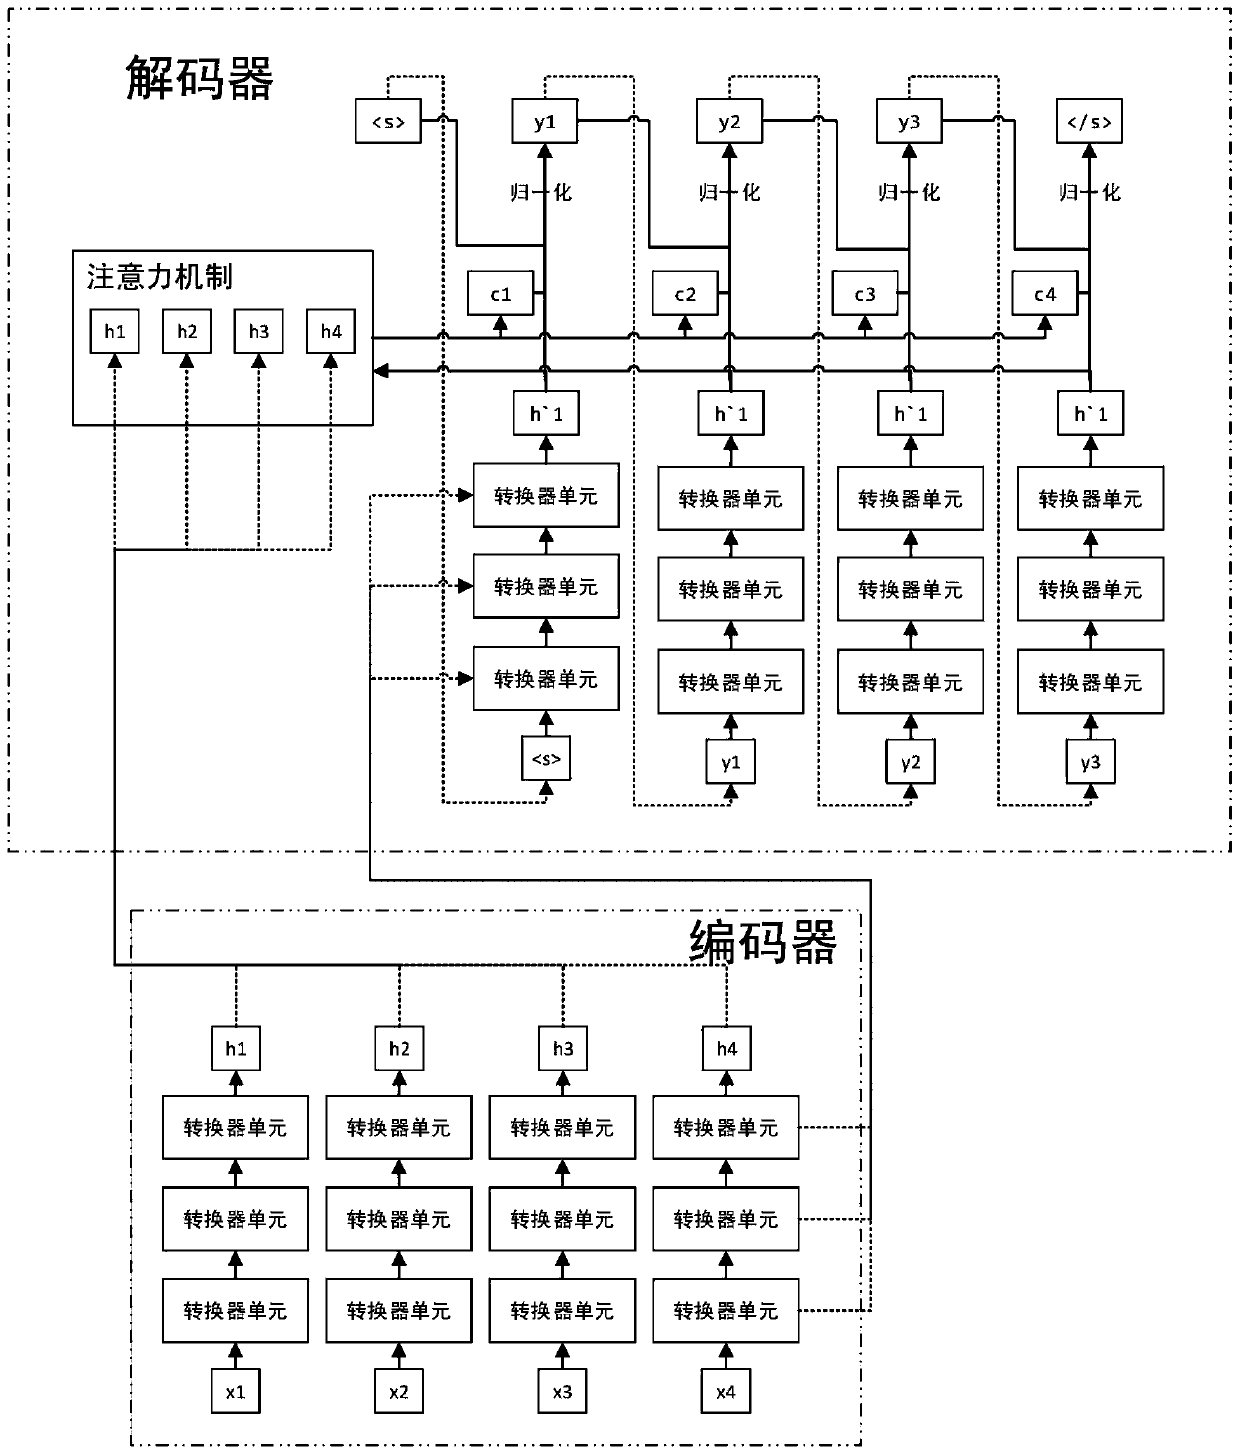
The invention provides an automatic text abstraction method based on a pre-training language model. According to the method, an ultra-large-scale unsupervised Chinese corpus is used for training a complex deep language model; the low-layer network structure of the model can extract and retain the grammar and structure information of a text, and the high-layer network structure can extract and retain the semantics and context information of the text, so that the richer text features and semantic information are provided for an automatic text summary task; a pre-training language model and an Encoder are combined to realize, the text features and the semantic information in the pre-training language model are fully utilized, so that a better semantic compression effect is provided, and the performance of an automatic text abstract is improved; a pre-training language model and a decoder are combined, not only the semantics in an original text are considered in the text generation process, but also the semantic information of vocabularies is also considered, so that the readability of the generated text and relevance with the original text are improved, and the performance of an automatic text abstract is improved.
Owner:BEIHANG UNIV
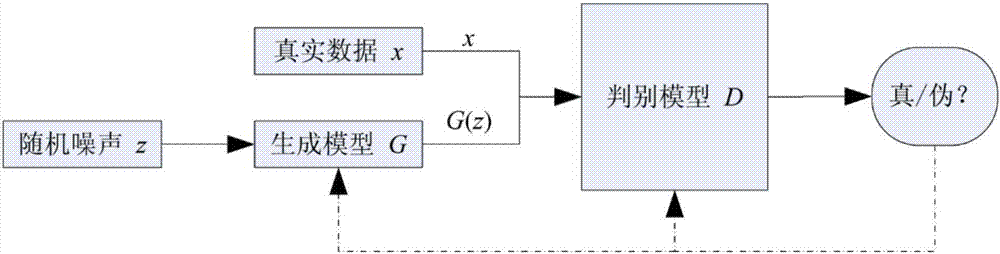
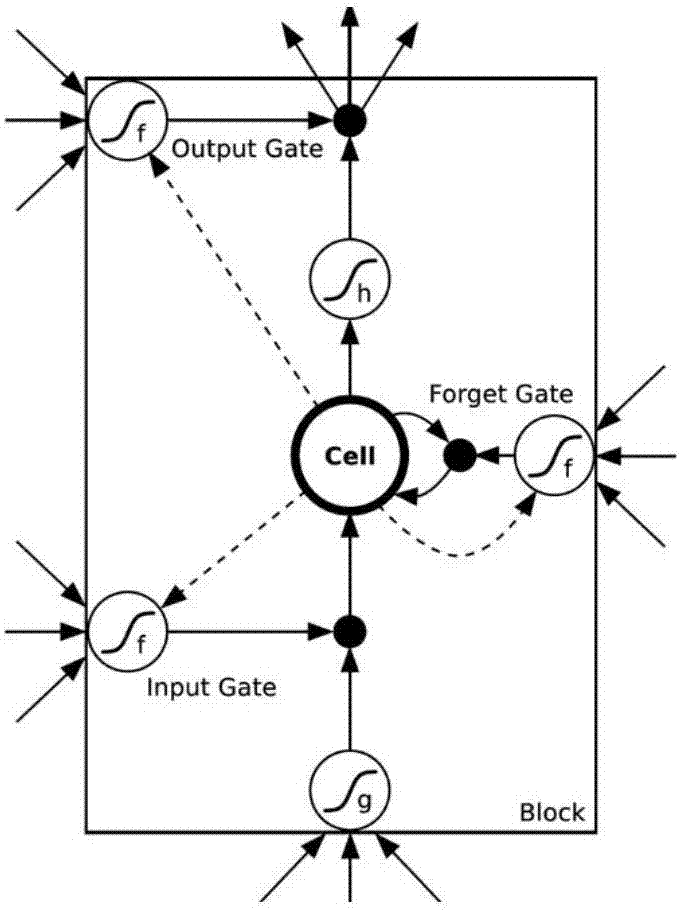
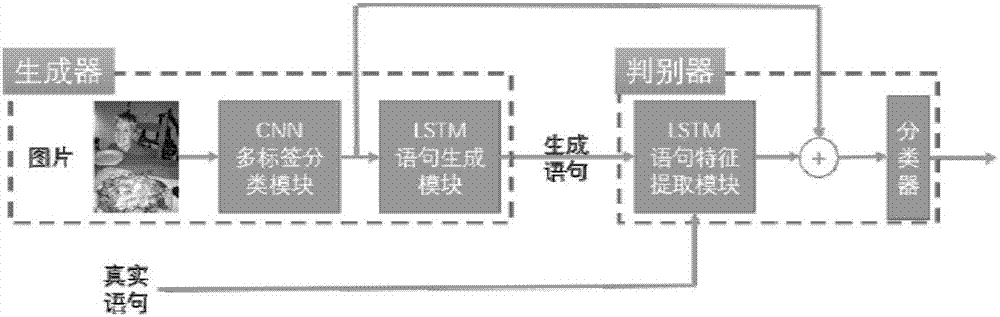
Method for image automatic text annotation based on generative adversarial networks
InactiveCN107330444AValid descriptionEasy retrievalCharacter and pattern recognitionSpecial data processing applicationsDiscriminatorPattern recognition
The invention discloses a method for image automatic text annotation based on generative adversarial networks, which comprises the steps of generating false statements by a generator, rebuilding a discriminator at the same time, and inputting the generated statements and real statements into the discriminator to train until the discriminator cannot discriminate the real statements and the generated statements. The method disclosed by the invention changes a problem that sentences are rigid and inflexible in CNN-RNN image automatic statement annotation, and enables the generated sentences to be more accurate, more natural and more diversified. The generated statements can face more complex scenes in reality and more conform to language expression means annotation images of the human, thereby having more extensive applications in practice.
Owner:SUZHOU UNIV OF SCI & TECH
Automatic text summarization method based on enhanced semantics
InactiveCN108804495APrevent deviationQuality improvementNatural language data processingSpecial data processing applicationsSemantic vectorWord list
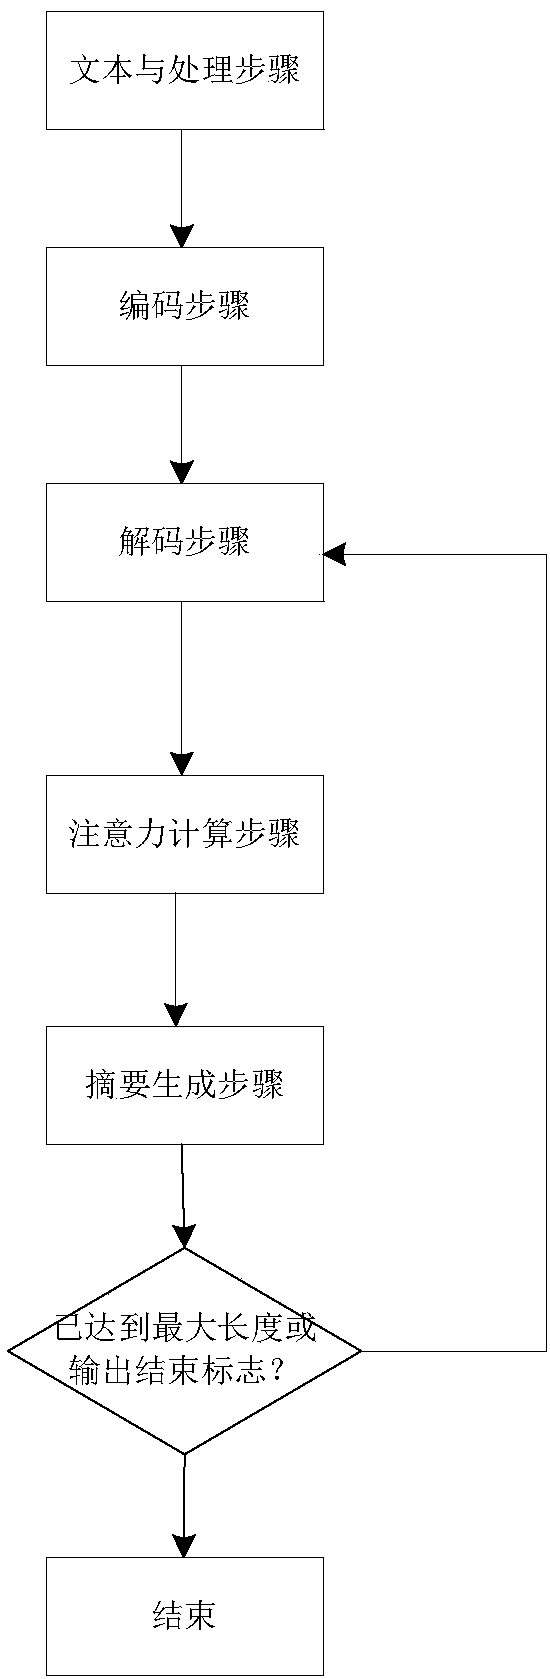
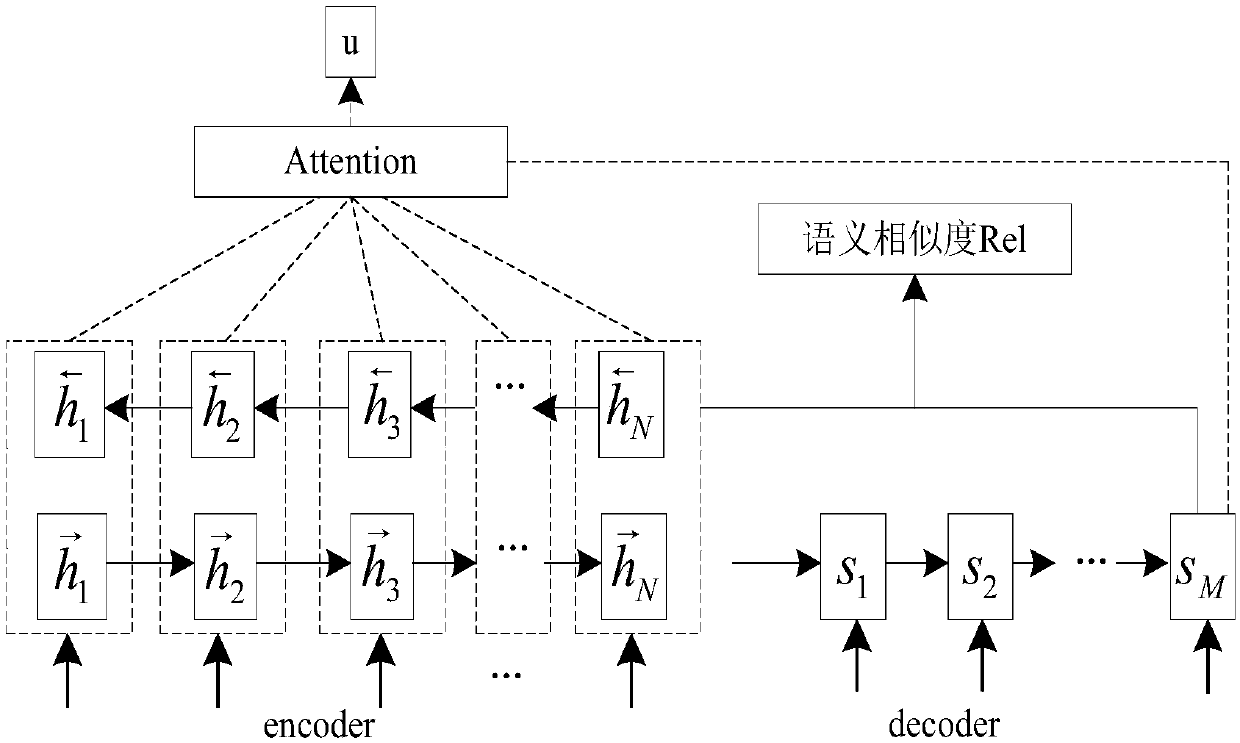
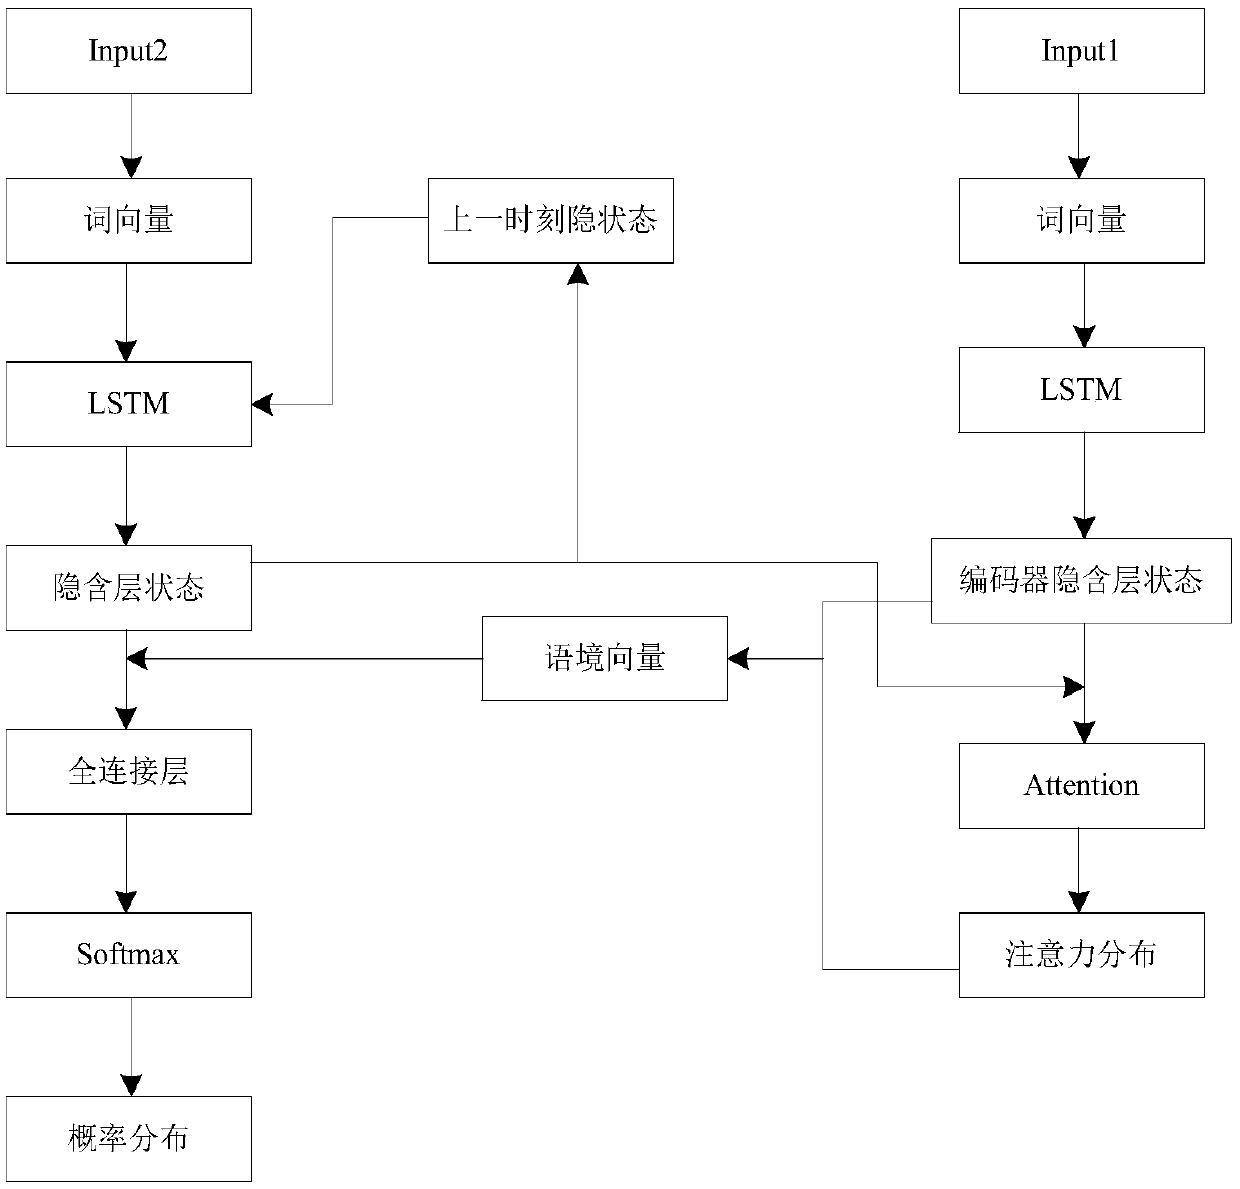
The invention discloses an automatic text summarization method based on enhanced semantics. The method comprises the following steps of: preprocessing a text, arranging words from high to low according to the word frequency information, and converting the words to id; using a single-layer bi-directional LSTM to encode the input sequence and extracting text information features; using a single-layer unidirectional LSTM to decode the encoded text semantic vector to obtain the hidden layer state; calculating a context vector to extract the information, most useful the current output, from the input sequence; after decoding, obtaining the probability distribution of the size of a word list, and adopting a strategy to select summarization words; in the training phase, fusing the semantic similarity between the generated summarization and the source text to calculate the loss, so as to improve the semantic similarity between the summarization and the source text. The invention utilizes the LSTM depth learning model to characterize the text, integrates the semantic relation of the context, enhances the semantic relation between the summarization and the source text, and generates the summarization which is more suitable for the subject idea of the text, and has a wide application prospect.
Owner:SOUTH CHINA UNIV OF TECH
Text clustering multi-document automatic abstracting method and system for improving word vector model
PendingCN110413986AGet efficientlyExpress semantic coherenceCharacter and pattern recognitionNeural architecturesScale modelProblem of time
The invention discloses a text clustering multi-document automatic abstracting method and a system for improving a word vector model. The CBOW of the Hierachic Softmax belongs to the field of large-scale model training, and the CBOW of the Hierachic Softmax belongs to the field of large-scale model training. Based on the method, a TesorFlow deep learning framework is introduced into word vector model training; the problem of time efficiency of a large-scale training set is solved through streaming processing calculation, TF-IDF is introduced firstly during sentence vector representation, thenthe semantic similarity of a semantic unit to be extracted is calculated, weighting parameters are set for comprehensive consideration, and a semantic weighted sentence vector is generated; beneficialeffects are as follows. The advantages and disadvantages of semantics, deep learning and machine learning are comprehensively considered; density clustering and convolutional neural network algorithms are applied. Intelligent degree is high, according to the method, the statement with high relevancy with the central content can be quickly extracted to serve as the abstract of the text, various machine learning algorithms are applied to the automatic text abstract to achieve a better abstract effect, the method is possibly the main research direction in future in the field, and in addition, the system according to the invention supplies a tool for automatic extraction of a document abstract based on the method.


Owner:上海晏鼠计算机技术股份有限公司
Run-time image display on a device
An embodiment for a computing device is described herein. The computing device may include a word database enhancer, a recommendation engine, a keyboard monitor, a ranking and display manager, and a keyboard. The keyboard may be a configurable physical keyboard device that includes an embedded display, where the embedded display is a runtime configurable display. The keyboard may display configurable images in the form of auto-text completion text or a decrypted password. The keyboard may also include a microcontroller, a touch sensor, and a keyboard filter driver.


Owner:INTEL CORP
Methods and Systems for Automated Text Correction
InactiveUS20140163963A2Minimize loss functionNatural language data processingSpecial data processing applicationsTheoretical computer scienceData science
Owner:NAT UNIV OF SINGAPORE
Automatic rhythm extracting method, system and application thereof in natural language processing
The invention relates to an automatic rhythm extracting method, a system and an application thereof in natural language processing; the method includes steps of applying an automatic text-voice alignment technology to generate a large-scale rhythm data set, and applying a circular neural network to perform modeling on the rhythm of a sentence, adding a bidirectional expanding mechanism; applying the automatically structured text rhythm data to a natural language processing task based on the circular neural network. The method fully uses the isomorphism properties of common sequence data in the text rhythm sequence and the natural language processing task; through an alternative training method under the multi-task study, the natural language processing task is promoted without the assistance of artificially explicit marked semantic information. The practice of the method can overcome shortcomings of low efficiency, different standards, incapability of large-scale application of the artificial rhythm marking; meanwhile, the method can transfer semantics and pragmatics in massive voice data to the other tasks.


Owner:SHENZHEN IPIN INFORMATION TECH CO LTD
Automatic text summarization method, apparatus, computer device, and storage medium
InactiveUS20200265192A1Improve accuracySemantic analysisNeural architecturesAlgorithmTheoretical computer science
Disclosed are an automatic text summarization method, apparatus, computer device and storage medium. The method includes: obtaining a character of a target text sequentially and decoding the character according to a first-layer LSTM structure sequentially inputted into a LSTM model to obtain a sequence composed of hidden states; inputting the sequence composed of hidden states into a second-layer LSTM structure of the LSTM model and decoding such sequence to obtain a word sequence of a summary; inputting the word sequence into the first-layer LSTM structure and encoding the word sequence to obtain an updated sequence composed of hidden states; obtaining a context vector according to a contribution value of a decoder hidden state in the updated sequence composed of hidden states and obtaining a probability distribution of the corresponding words, and using the most probable word as the summary of the target text.


Owner:PING AN TECH (SHENZHEN) CO LTD
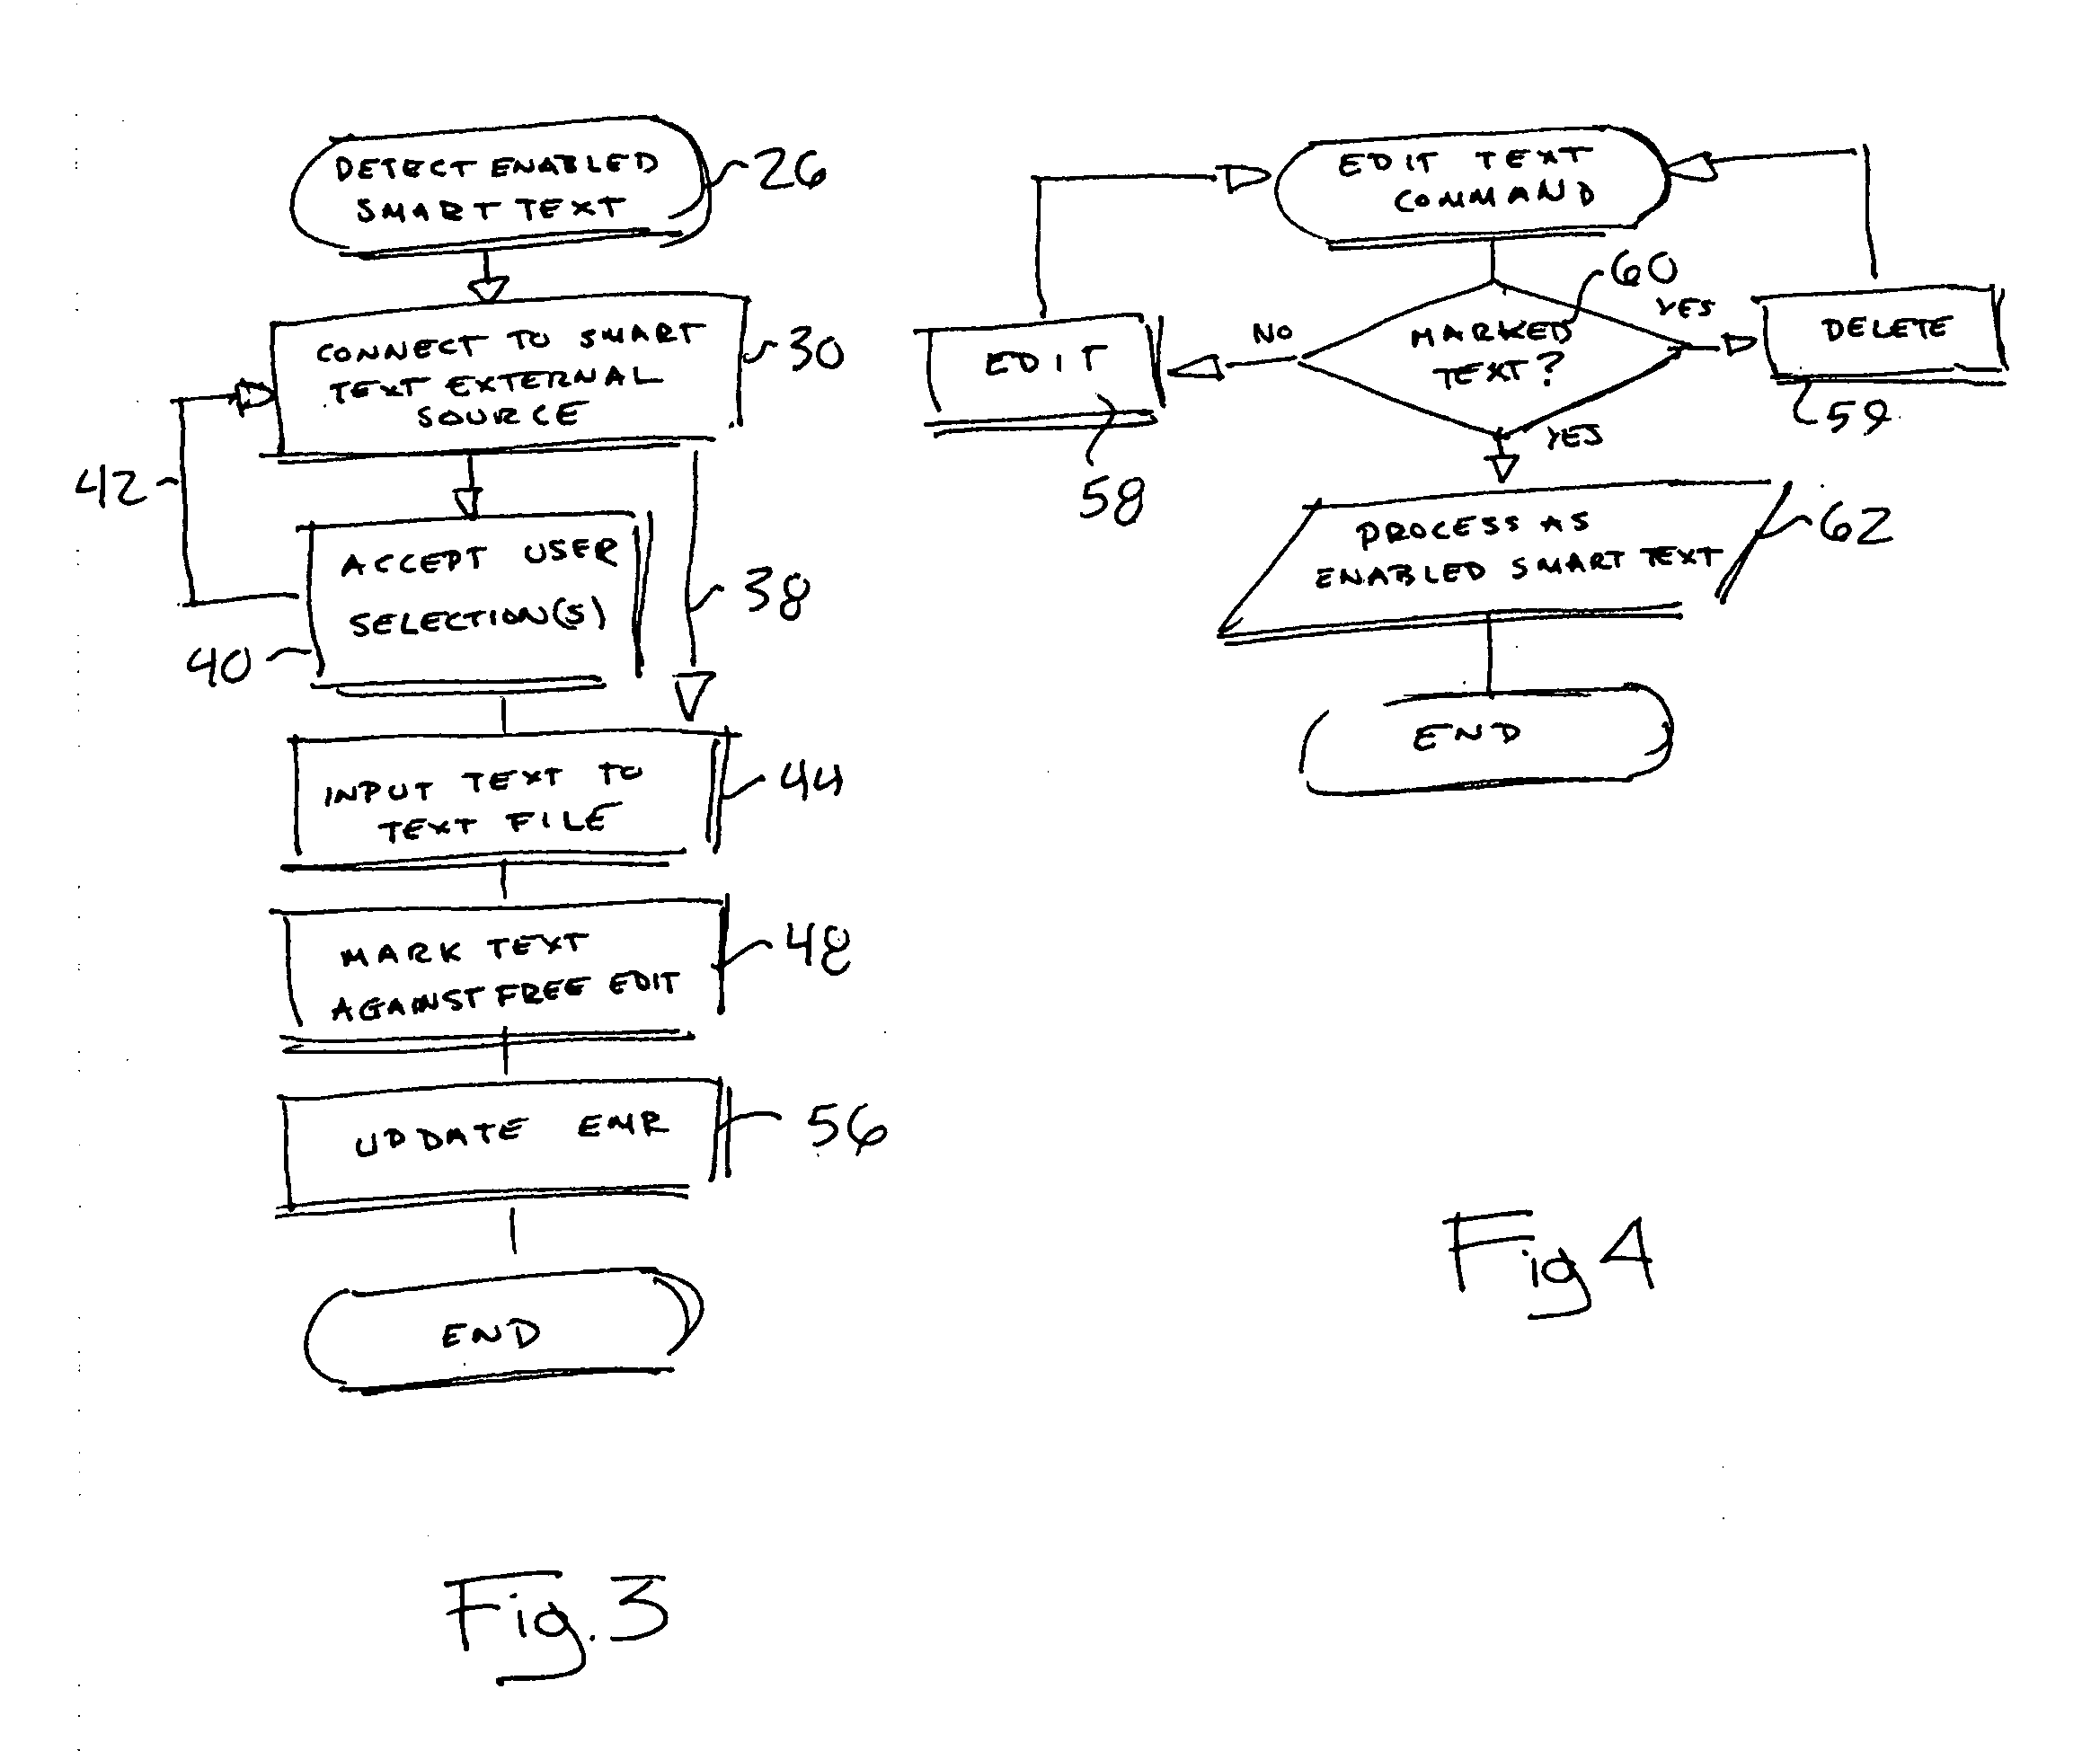
Clinical documentation tool with protected and revisable text expansion
InactiveUS20060031096A1Alteration can be preventedData generationNatural language data processingOffice automationDocumentation procedureClinical document
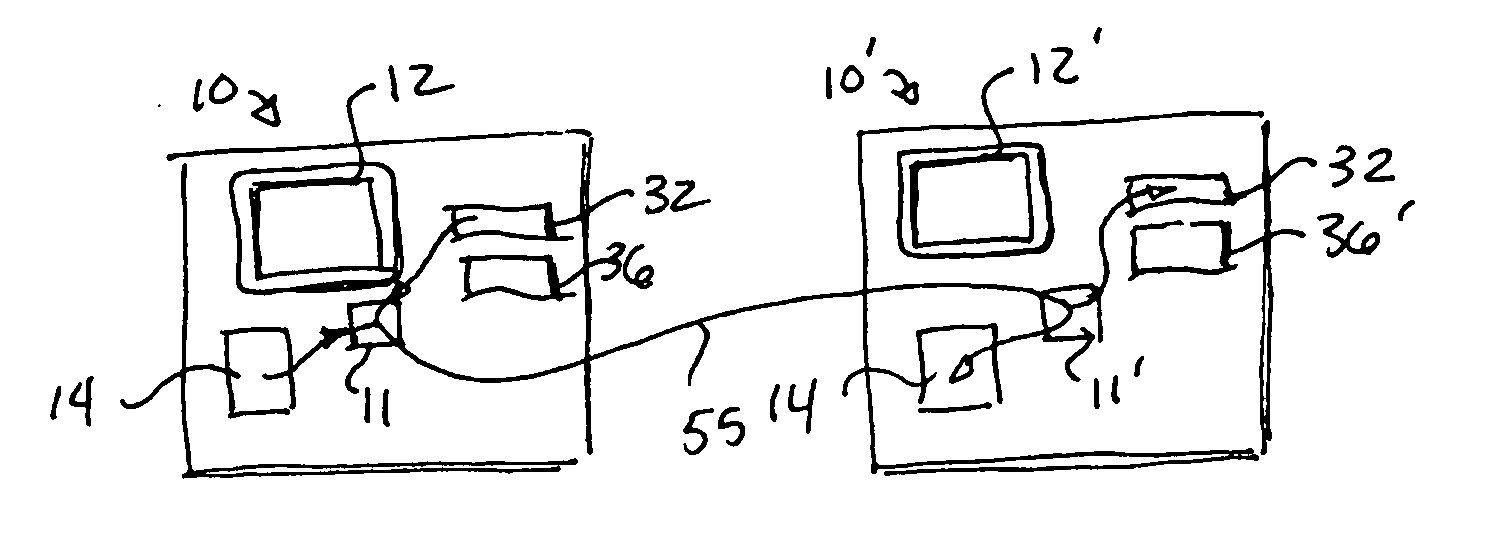
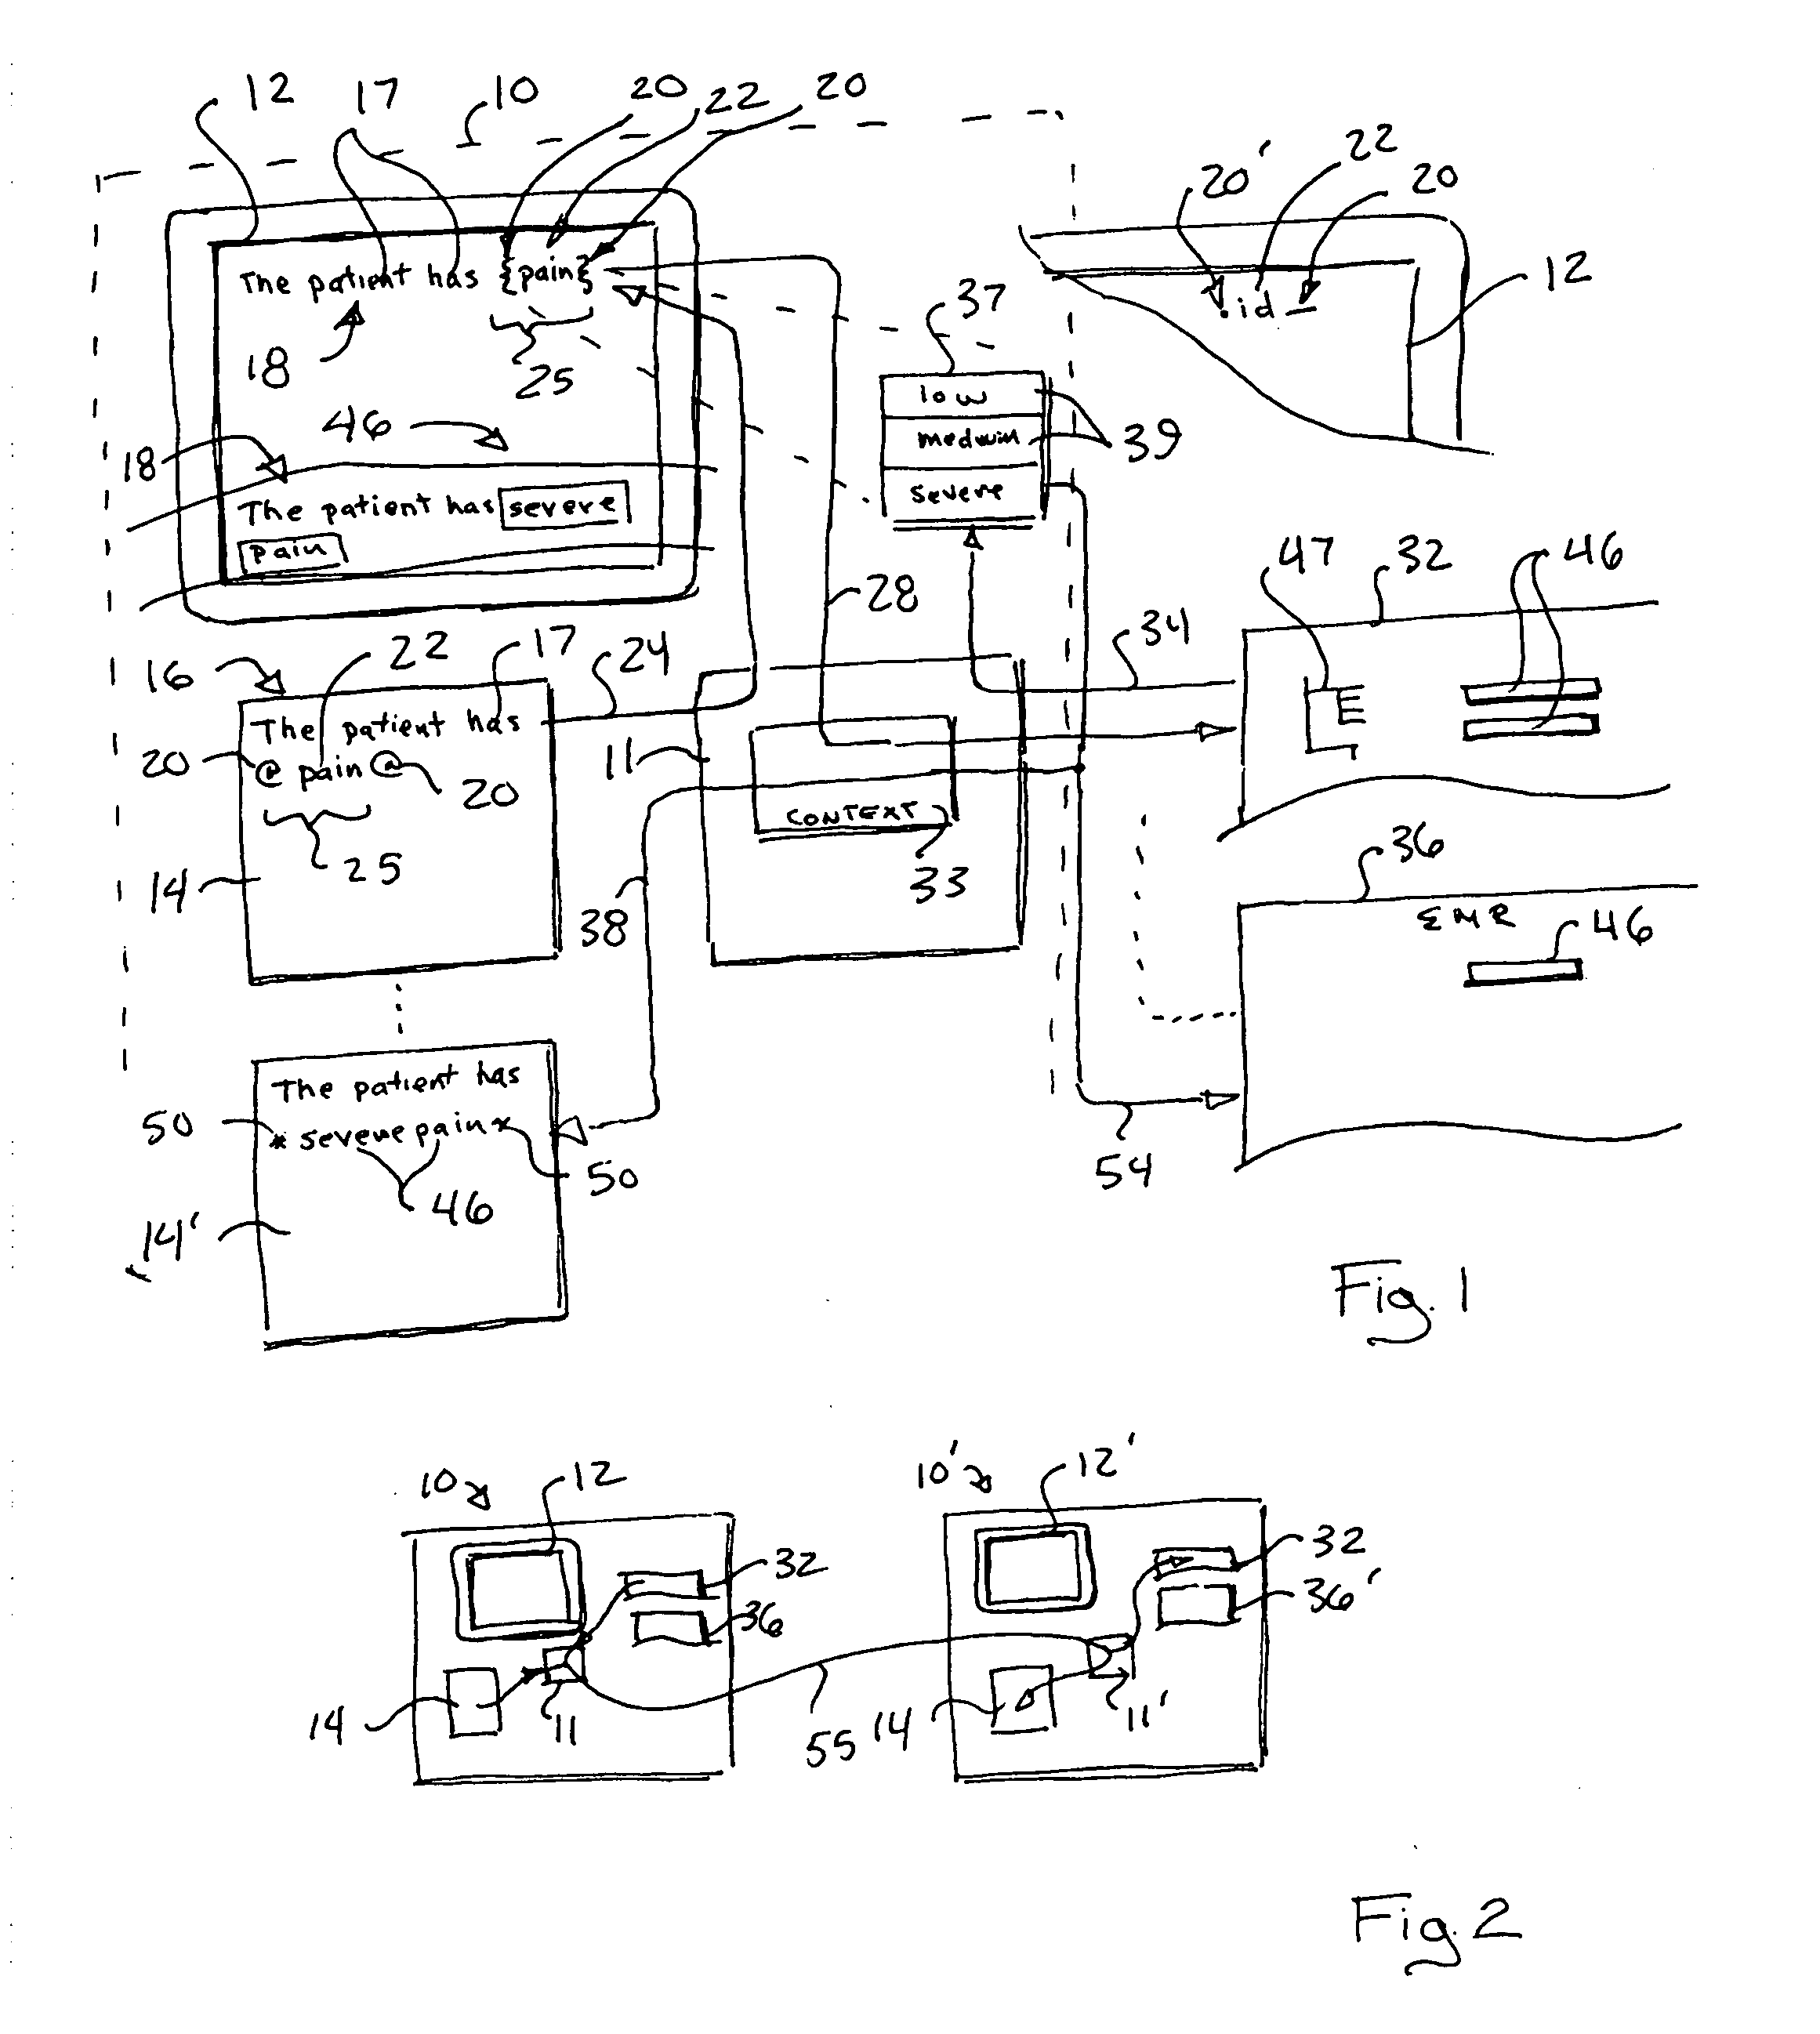
Automatic text generation is marked in a text document to allow later re-invocation of automatic text generation to revise the expanded text and to ensure integrity in capture of machine interpretable data generated during automatic text generation.
Owner:BUTTNER MARK DUANE +3
Methods and system for improving the relevance, usefulness, and efficiency of search engine technology
InactiveUS20180121545A1Improve relevanceImprove the usefulnessWeb data indexingSemantic analysisSemantic searchFull scale
The disclosed methods, systems, and apparatus use Natural Language Processing (NLP) in conjunction with a world model and cognitive frames to semantically analyze, understand, rank, store, and retrieve digital text. The goal is to improve the relevance, usefulness and efficiency of information search. The world model represents things existing in the real world whereas cognitive frames specify possible user interaction with such a world. Using NLP in conjunction with a world model and cognitive frames to understand text is an advancement in automated text analysis. It addresses three serious shortcomings of the existing search technology: the inadequate measure of the meaningful content in web pages; a poor understanding of users' goals and tasks in their search and, the irrelevant search results. The disclosed methods have led to the successful implementation of a full-scale semantic search engine in medicine, and they are applicable and adaptable to other disciplines.


Owner:COGILEX R&D INC
Genetic people's health: the biocultural microcomputers and microprocessor toys for grown-ups and kids and for all the world, and the science and technological art of the computerized global humanitarian biocultural genetic 'public health' (health without the medical 'health service')
InactiveUS20050055222A1Data processing applicationsSpecial data processing applicationsPrivate lifeSkin color
What do we, the people, have?—We have only the life. Our proposed BIOcultural microcomputers and microprocessor toys are to remind, what does shorten and depreciate our life. These microprocessor devices, as it turns out, have no analogs in the world are assigned for simple, easy-to-understand self-enlightening of an individual in fundamentals of BIOlogy concerning Life as such, as BIO, as natural phenomenon on the Globe and in organism of everybody. The BIOcultural microcomputers and microprocessor toys—these BIOenlightening microprocessor tools, autonomic and build-in, for instance, into cellular phones and personal computers, by auto-text or other audiovisual means, in playing or serious form, are to remind several times a day, on our private life as a constituent of the global Life, single and exclusive on the Globe and in our organism, non-submittable to us, existing beyond and independently of our consciousness—that is, on its turn, to remind on the existence of the Creator of Life and of us upon it. The databases in the said devises do contain a biological knowledge for an illustration to the user, that the “BIOcultural Way of Thinking” is a method, or an intellectual tool, or a mental technique, helping those who possesses it to come to correct conclusions in an analysis of four the most important and urgent methods for everyone on the Globe independently of sex, age, occupation, race, color of skin and place of residence: firstly, WHAT is correct to eat; secondly, HOW is correct to eat; thirdly, HOW is correct to live; and at last HOW is correct to support and restore the own health,—that is, from the point of biology, physiology and genetics. The algorithms in these devices enable the user to cognize this biological knowledge in an easy playing manner and then, gradually, to induce the user to live more comfortably by the further self-enlightening in the educational subject “BIOculture of the Individual” and by gradual turn to the own “BIOcultural Way of Thinking”.
Owner:LEONOV VALERY +1
Text category prediction method and device, equipment, storage medium and program product
ActiveCN114706987AImprove consistencyAccurate representationSemantic analysisNeural architecturesSemantic vectorAlgorithm
The invention relates to a text category prediction method and device, computer equipment, a storage medium and a computer program product. The method relates to an automatic text classification technology of artificial intelligence, and comprises the following steps: performing semantic coding according to a semantic vector of each word in a short text through a coding layer of a trained text category prediction model to obtain a semantic coding vector of the short text; through a decoding layer of the text category prediction model, performing first decoding according to the semantic coding vector to obtain a first decoding hidden vector, and after obtaining a first category corresponding to the short text based on the first decoding hidden vector, continuing to perform current decoding according to a decoding hidden vector obtained by previous decoding and the category; obtaining a decoding hidden vector and a category of the current decoding until the decoding is finished; and combining the plurality of categories obtained by decoding according to the hierarchy to obtain the category path corresponding to the short text, so that the problem of consistency of father and child nodes of the multi-hierarchy category path can be improved, and the category path of the text can be accurately predicted.


Owner:TENCENT TECH (SHENZHEN) CO LTD
Text abstract generation method and device
ActiveCN111159394AImprove readabilityFast Automatic Text SummarizationNatural language data processingSpecial data processing applicationsAlgorithmWord list
The embodiment of the invention provides a text abstract generation method and device to achieve rapid and automatic text abstract, and abstract text is high in readability and consistent with an original text main text in meaning. The method comprises the steps of providing and training an abstract generation model comprising an encoder and a decoder; receiving an input text and an original textcode output by the encoder through the decoder; wherein the input text comprises a start character and an abstract text output last time; respectively determining a generation mode probability matrix,an extraction mode probability matrix and a weight matrix through the decoder; based on the generation mode probability matrix, the extraction mode probability matrix and the weight matrix, generating a reference probability matri, wherein the reference probability matrix represents the reference probability of each word in a word list; and determining a current abstract text based on the reference probability of the reference probability matrix.


Owner:重庆觉晓科技有限公司
Chinese abstract automatic generation method and system based on NLP technology
PendingCN114547289ASemantic fluentGenerate accuratelyNeural architecturesText database queryingSemanticsEngineering
The invention relates to the field of abstract automatic generation, and particularly provides a Chinese abstract automatic generation method and system based on an NLP technology, and the method comprises the following steps: S1, carrying out the target training of a text which needs to generate an abstract, and maximizing the probability of generating each target word; s2, automatically generating evaluation indexes; s3, evaluating the text in which the abstract needs to be generated by adopting an automatic generation evaluation index; and S4, performing statement extraction on the text by adopting an abstract generation model to generate an abstract. According to the method, the abstract is automatically generated through a natural language processing technology, namely, according to one or more documents, a section of abstract which keeps key information in an input text and is smooth, concise and accurate in semantics is automatically generated. According to the automatic text abstract, the abstract can be quickly and accurately generated in real time, and the defects of manual abstract are overcome.


Owner:山西巨擘天浩科技有限公司
Automatic text abstracting method
ActiveCN111008277AIncrease the speed of learningImprove accuracyCharacter and pattern recognitionSpecial data processing applicationsAlgorithmNetwork generation
The invention discloses an automatic text abstracting method which comprises the following steps: preprocessing a text, establishing mapping from a text character to a number, and converting the textcharacter into a vector code for calculation; pre-training a codec, and training a codec initialization network capable of encoding and decoding a long text into a short text; optimizing the generative adversarial network, and optimizing encoder parameters in the encoding and decoding network; and decoder optimization: after the encoder is optimized, repeatedly training the encoding and decoding network for multiple times to optimize the decoder, and improving the BLEU value of the generated text. The method can adapt to text abstract tasks in various language scenes and the generated abstracthas good readability.


Owner:TROY INFORMATION TECHNOLOGY CO LTD
User-focused, ontological, automatic text summarization using a bi-directional neural network for selecting answers based on their uncommon words to user queries
The present disclosure is directed to systems and methods of providing systems and methods of autonomously generating summary documents based, at least in part, on a plurality of queries provided by a system user. The systems and methods disclosed herein include processor circuitry to identify a plurality of information sources for a specific topic guided by an ontology with specific concepts and relations. The systems and methods disclosed herein also include processor circuitry to generate user-focused extractive text summarization from each of at least some of the plurality of identified information sources using a plurality of queries supplied by the user / researcher.

Owner:BATTELLE MEMORIAL INST
A Knowledge-Based Adaptive Event Index Cognitive Model Extraction Method for Document Summarization
ActiveCN110188189BImprove accuracyIncrease or decrease chances of retrieving informationNatural language data processingSpecial data processing applicationsImaging processingImage manipulation
The invention proposes a method for extracting document abstracts based on a knowledge-based self-adaptive event index cognitive model, which belongs to the fields of natural language processing and automatic text abstract generation. This method redefines the concept of five types of indicators in the event index cognitive model, and uses two dimensions of emotional attributes and core influences to extract document summaries based on the standard human memory model; this method closely reflects the human understanding of text process, which has unique advantages in dealing with unstructured, incomplete and ambiguous text content; therefore, it is suitable for various scenarios and applications involving data uncertainty, including machine learning, intelligent applications, image processing and medical diagnosis application etc.


Owner:ZHEJIANG GONGSHANG UNIVERSITY
Method for classifying a text parse
PCT designated stageWO2026054681A1Metadata text retrievalNatural language data processingMedicineAuto-text
The invention relates to the field of computing, and more particularly to methods for automated text processing. A method for classifying a text parse includes inputting into a classification model a text parse containing a main entity and, associated with said main entity, an associated end entity. A text processing method consists in performing the following steps of: identifying a text including three segments, and subsequently identifying said segments; selecting one of the segments for subsequent marking, and marking in this first segment only one part to be parsed; parsing marked parts by semantic-syntactic parsing; extracting from the semantically-syntactically parsed part of the first segment a main entity of said first segment and an associated entity related to the main entity of the first segment, wherein one associated entity is an associated end entity, and extracting from each semantically-syntactically parsed part of a selected second segment and / or a selected third segment one assertion; associating said assertion with the main entity of the first segment. The invention provides for more precise automated generation of a text corpus.


Owner:KRAVCHENKO ARTEM ALEKSANDROVICH
Method and system for automatically generating Wiki-style article
The invention belongs to the technical field of natural language processing and artificial intelligence, and particularly relates to a method and system for automatically generating a Wiki-style article. The invention aims to solve the problems of logic fragmentation, insufficient fact accuracy, limited content coverage, poor format normalization and the like in the existing automatic text generation. An outline with a strict structure is constructed by combining internal knowledge and external references obtained through multi-view retrieval; generating a preliminary article according to the outline, and performing segment-by-segment refinement and fact calibration on the preliminary article by using references; and finally, carrying out comprehensive evaluation and iterative optimization on the article by adopting a multi-dimensional review mechanism to ensure that the article is logically coherent and accurate in content and completely meets the specification requirements of Wikipedia. According to the method, through multi-source knowledge fusion and multi-stage quality control, irrelevant information interference is effectively reduced, the efficiency, reliability and accuracy of automatically generating the Wiki-style article are remarkably improved, and meanwhile the highest publishing standard of the Wiki-style article can be met.

Owner:BEIJING INST OF TECH
Intelligent question type conversion system and method based on choice question editor
PendingCN112216168AReduce manual editing operationsReduce workloadNatural language data processingElectrical appliancesType conversionEngineering
The invention discloses an intelligent question type conversion system and method based on a choice question editor; and the system comprises an input module which is used for obtaining a needed question in an automatic mode, a textualization module used for textualizing the questions, an analysis module used for analyzing the textualized questions to obtain question surfaces and correct answers,a wrong answer recommendation module used for generating a plurality of wrong answers for the user to select according to text characteristics of the question surface and the correct answers, an integrated editing module used for transmitting the analyzed content and correspondingly generated wrong answers to a choice question editor, and the choice question editor used for automatically generating choice questions according to the input content and further editing the choice questions by the user. The intelligent question type conversion system and method have the beneficial effects that themanual editing operation of the user in the question type conversion process is reduced and the conversion efficiency is improved by automatically obtaining the questions, carrying out automatic textualizing, carrying out intelligent analyzing, automatically generating the wrong answers and finally converting the selection questions.


Owner:李帮军
Computing device for automated processing of natural language text
The proposed technical solution relates to methods for automated text processing and can be used in the generation of text corpora. What is proposed is a computing device for the automated processing of natural language text. The claimed invention solves the technical problem of creating a method and / or a computing device and / or a system and / or a machine-readable data carrier which overcome the disadvantages of the prior art and, in so doing, provide for the precise automated generation of a text corpus which can subsequently be used for pre-training, or training, or post-training classification models and / or clustering models.


Owner:KRAVCHENKO ARTEM ALEKSANDROVICH
A speech recognition text editing processing method
ActiveCN120373268BCharacter and pattern recognitionNatural language data processingText editingKeyboard shortcut
The present invention provides a speech recognition text editing processing method, which innovatively designs a user interface to clearly separate the manual editing area and the automatic text generation area. Users can freely modify the text in the manual editing area without affecting the cursor position in the automatic text generation area, ensuring that the two areas operate independently and improving work efficiency and accuracy. In order to solve the problem of cursor position confusion caused by automatic text generation during manual modification, the present invention introduces a cursor locking mechanism. When the user operates in the manual editing area, the lock is enabled by triggering a button or shortcut key to pause the automatic text generation in the editing area. After the modification is completed and confirmed, the lock is released and the automatic text generation in the editing area is resumed. This mechanism ensures that the cursor position is stable during manual modification and avoids operational errors caused by interference from automatic generation.

Owner:CHINA SHIPBUILDING LINGJIU HIGH TECH (WUHAN) CO LTD +1
Method for automated natural-language text processing
The proposed technical solution relates to methods for automated text processing and can be used in the generation of text corpora. The claimed invention solves the technical problem of creating a method and / or a computing device and / or a system and / or a machine-readable data carrier which overcome the disadvantages of the prior art and thus provide for the precise automated generation of a text corpus which can subsequently be used for pre-training, or training, or post-training classification models and / or clustering models.


Owner:KRAVCHENKO ARTEM ALEKSANDROVICH
Sequence-to-sequence text summarization generation method and system based on causality
The application provides a sequence-to-sequence text abstract generation method and system based on causality, and belongs to the field of natural language processing and automatic text abstract generation. The method is inspired by the causality theory, and studies the causality of various elements in the abstract task from the perspective of data generation. The method first introduces two unobservable variables to obtain a structural causal model of the abstract task; then, a corresponding sequence-to-sequence generation framework is obtained according to the structural causal model, which is used to model the generation process of the original text and the abstract. The framework includes three core modules: a double latent variable variational encoder, an original text reconstruction decoder and an abstract prediction decoder. The method not only has stronger explainability than existing end-to-end deep text abstract methods, but also has better abstract performance and stronger generalization ability. The method is a sequence-to-sequence framework with strong applicability, and therefore can be migrated to more model subjects, generation tasks and different data sets.

Owner:INST OF COMPUTING TECH CHINESE ACAD OF SCI
Automatic text collection method for specific field
PendingCN114817678AAchieve cleaningImplement extractionWeb data indexingSpecial data processing applicationsEngineeringSentence extraction
The invention provides an automatic text collection method oriented to a specific field. The method comprises the following steps: establishing a url scheduling link pool and a task manager according to a preset target site; the method comprises the following steps: mapping input keywords and words in a Chinese synonym library to a high-dimensional vector space through word2vec, and calculating to generate a subject word group; the task manager cleans the html unstructured data in the accessed url page to obtain a long text; extracting Chinese feature sentences of the long text, extracting feature words in the Chinese feature sentences of the long text, and generating a long text feature word group; mapping the subject word group and the long text feature word group to a high-dimensional vector space, and calculating a semantic similarity value of the subject word group and the long text feature word group; and if the semantic similarity value reaches a set threshold value, writing the structured data in the url page corresponding to the long text feature word group into a database. According to the method, domain focusing is realized by converting rule matching of Chinese words and long texts into semantic distance calculation.


Owner:WUHAN UNIV OF TECH
Automatic text recognition with layout preservation

Owner:APPLE INC
A Text Summarization Model and Automatic Text Summarization Method Based on Improved Selection Mechanism and LSTM Variation
ActiveCN110134782BImprove generalizationImprove readabilityNeural architecturesSpecial data processing applicationsEncoder decoderInformation gain
The invention discloses a text summarization model based on an improved selection mechanism and LSTM variant and an automatic text summarization method. On the basis of an encoder-decoder model based on an attention mechanism, the invention proposes a selection mechanism based on information gain and Copy-based LSTM variant. On the one hand, an improved selection mechanism is added between the encoder and the decoder to judge the key information in the original text and extract the summary information, which improves the generalization ability of automatic text summarization; on the other hand, the LSTM variant is used as the The recurrent unit of the decoder-side recurrent neural network can optimize the decoding process, improve the decoding efficiency, reduce the repetition problem in the generated summary and improve the readability of the generated summary.


Owner:NANJING UNIV
Linguistically-driven automated text formatting
Systems and techniques for linguistically-driven automated text formatting are described herein. Data representing the linguistic structure of input text may be received from Natural Language Processing (NLP) Services, including but not limited to constituents, dependencies, and coreference relationships. A text model of the input text may be built using the linguistic components and relationships. Cascade rules may be applied to the text model to generate a cascaded text data structure. Cascaded data may be displayed on a range of media, including a phone, tablet, laptop, monitor, VR / AR devices. Cascaded data may be presented in dual screen formats to promote more accurate and efficient reading comprehension, greater ease in teaching native and foreign language grammatical structures, and tools for remediation of reading-related disabilities.

Owner:CASCADE READING INC