

Patents
Literature
52 results about "Facial component" patented technology
Efficacy Topic
Property
Owner
Technical Advancement
Application Domain
Technology Topic
Technology Field Word
Patent Country/Region
Patent Type
Patent Status
Application Year
Inventor
System and method for automatically detecting neutral expressionless faces in digital images
ActiveUS6879709B2Improve facial expression analysisEasy to analyzeProgramme controlElectric signal transmission systemsFace detectionDigital image
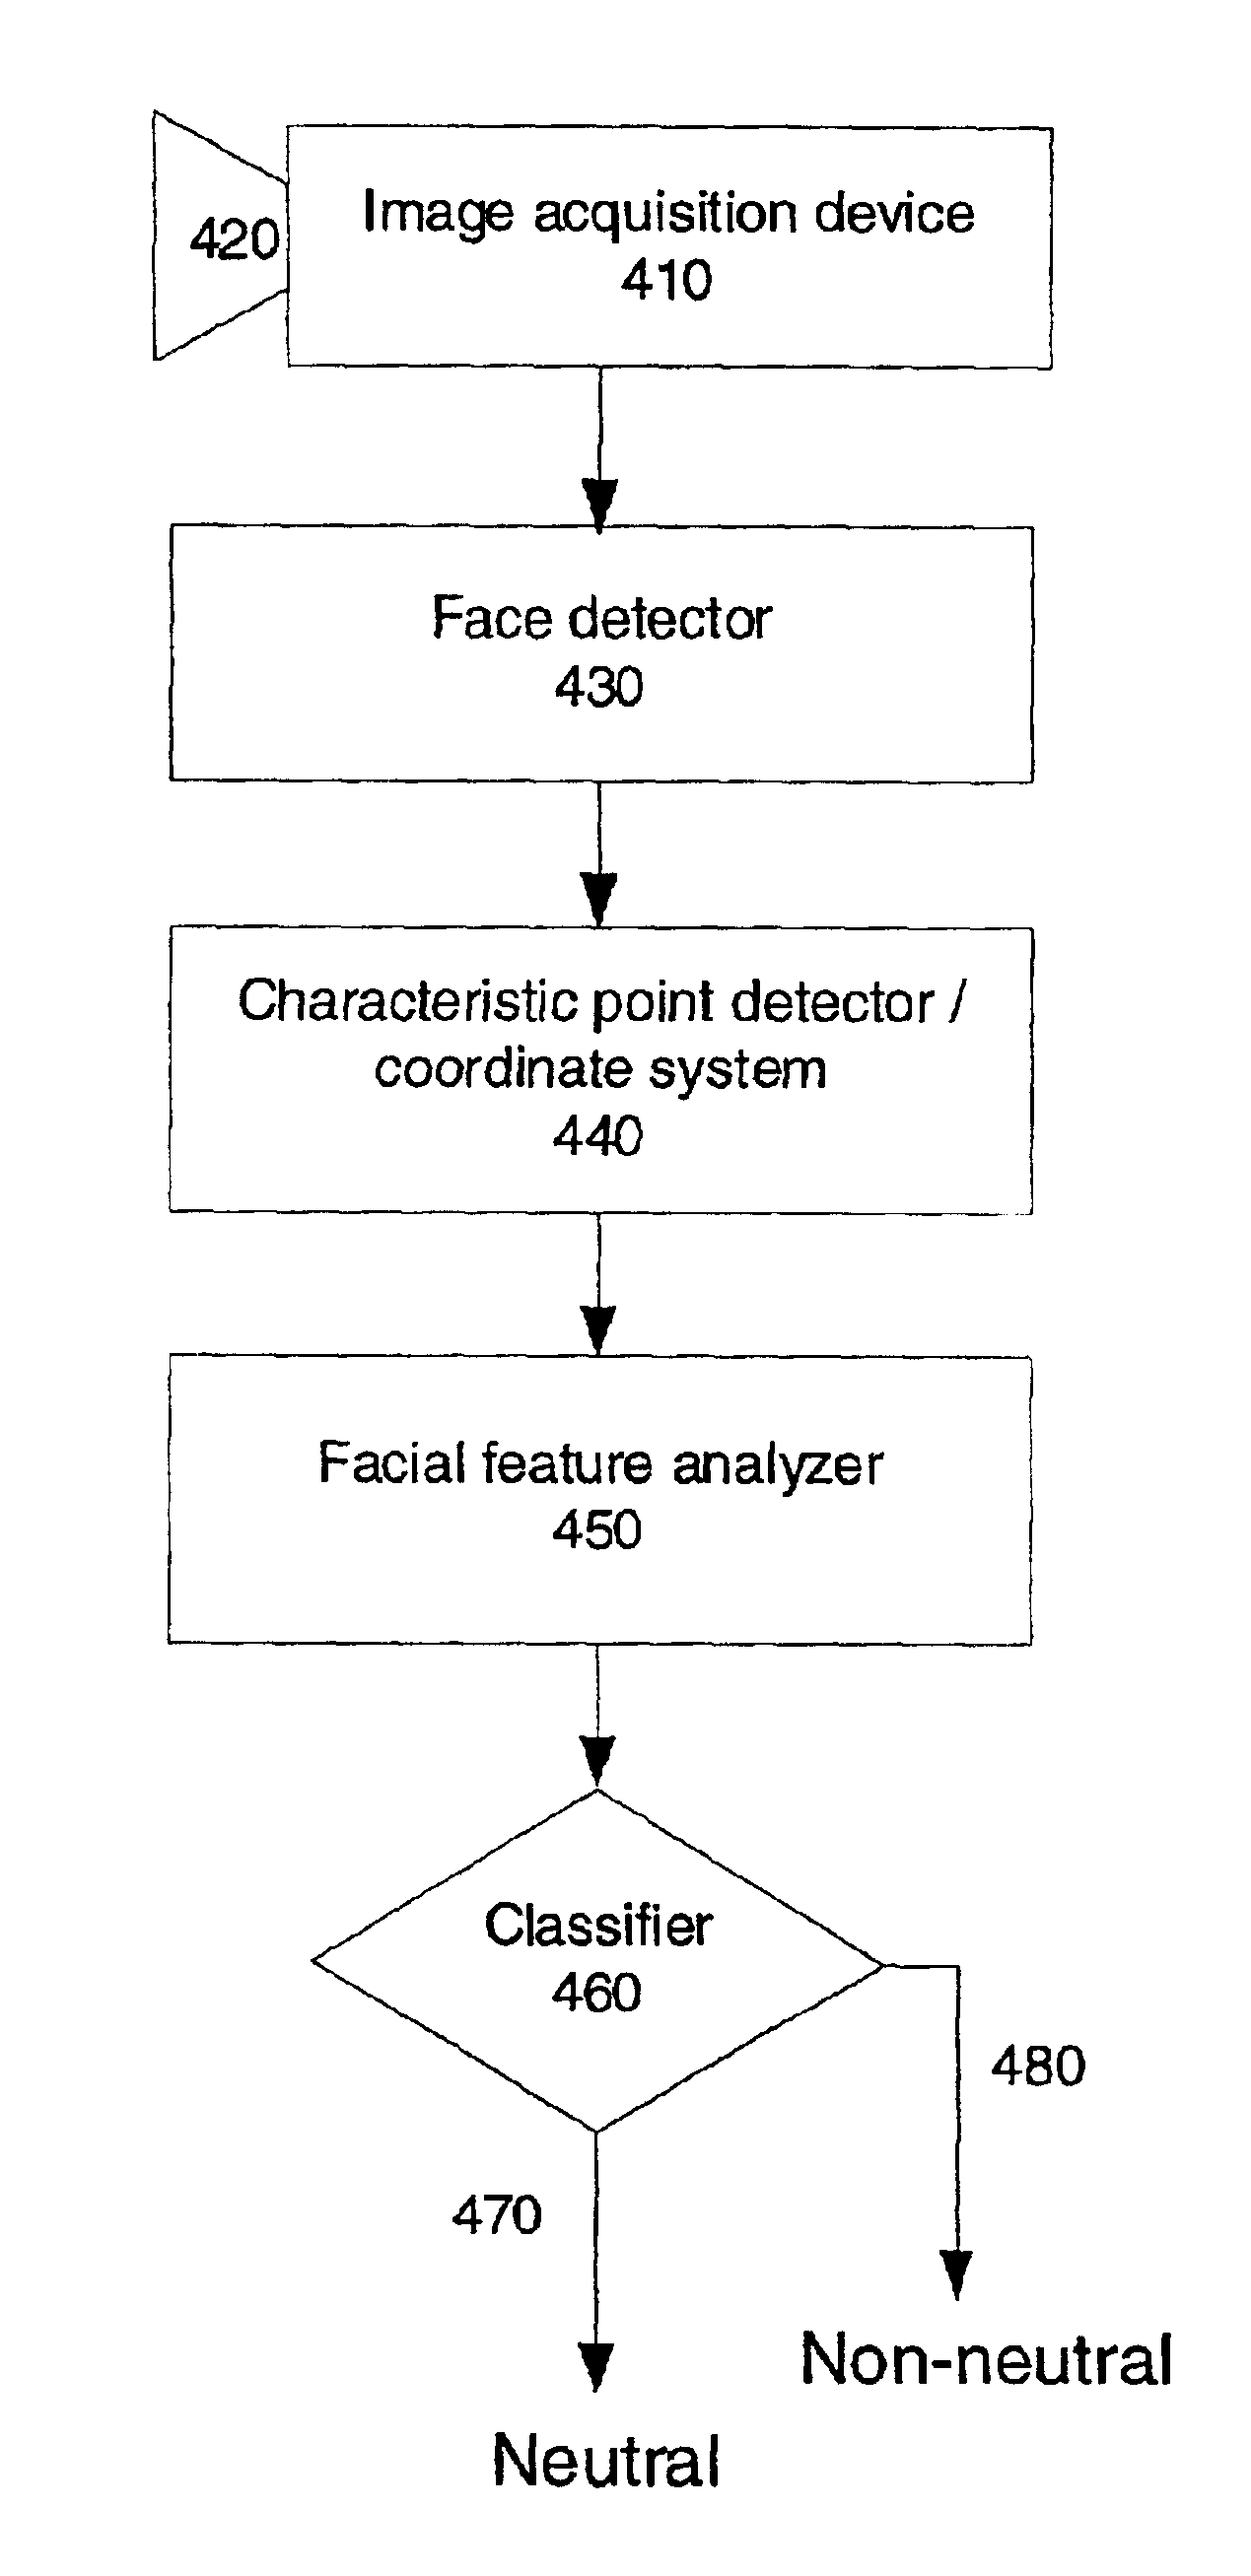
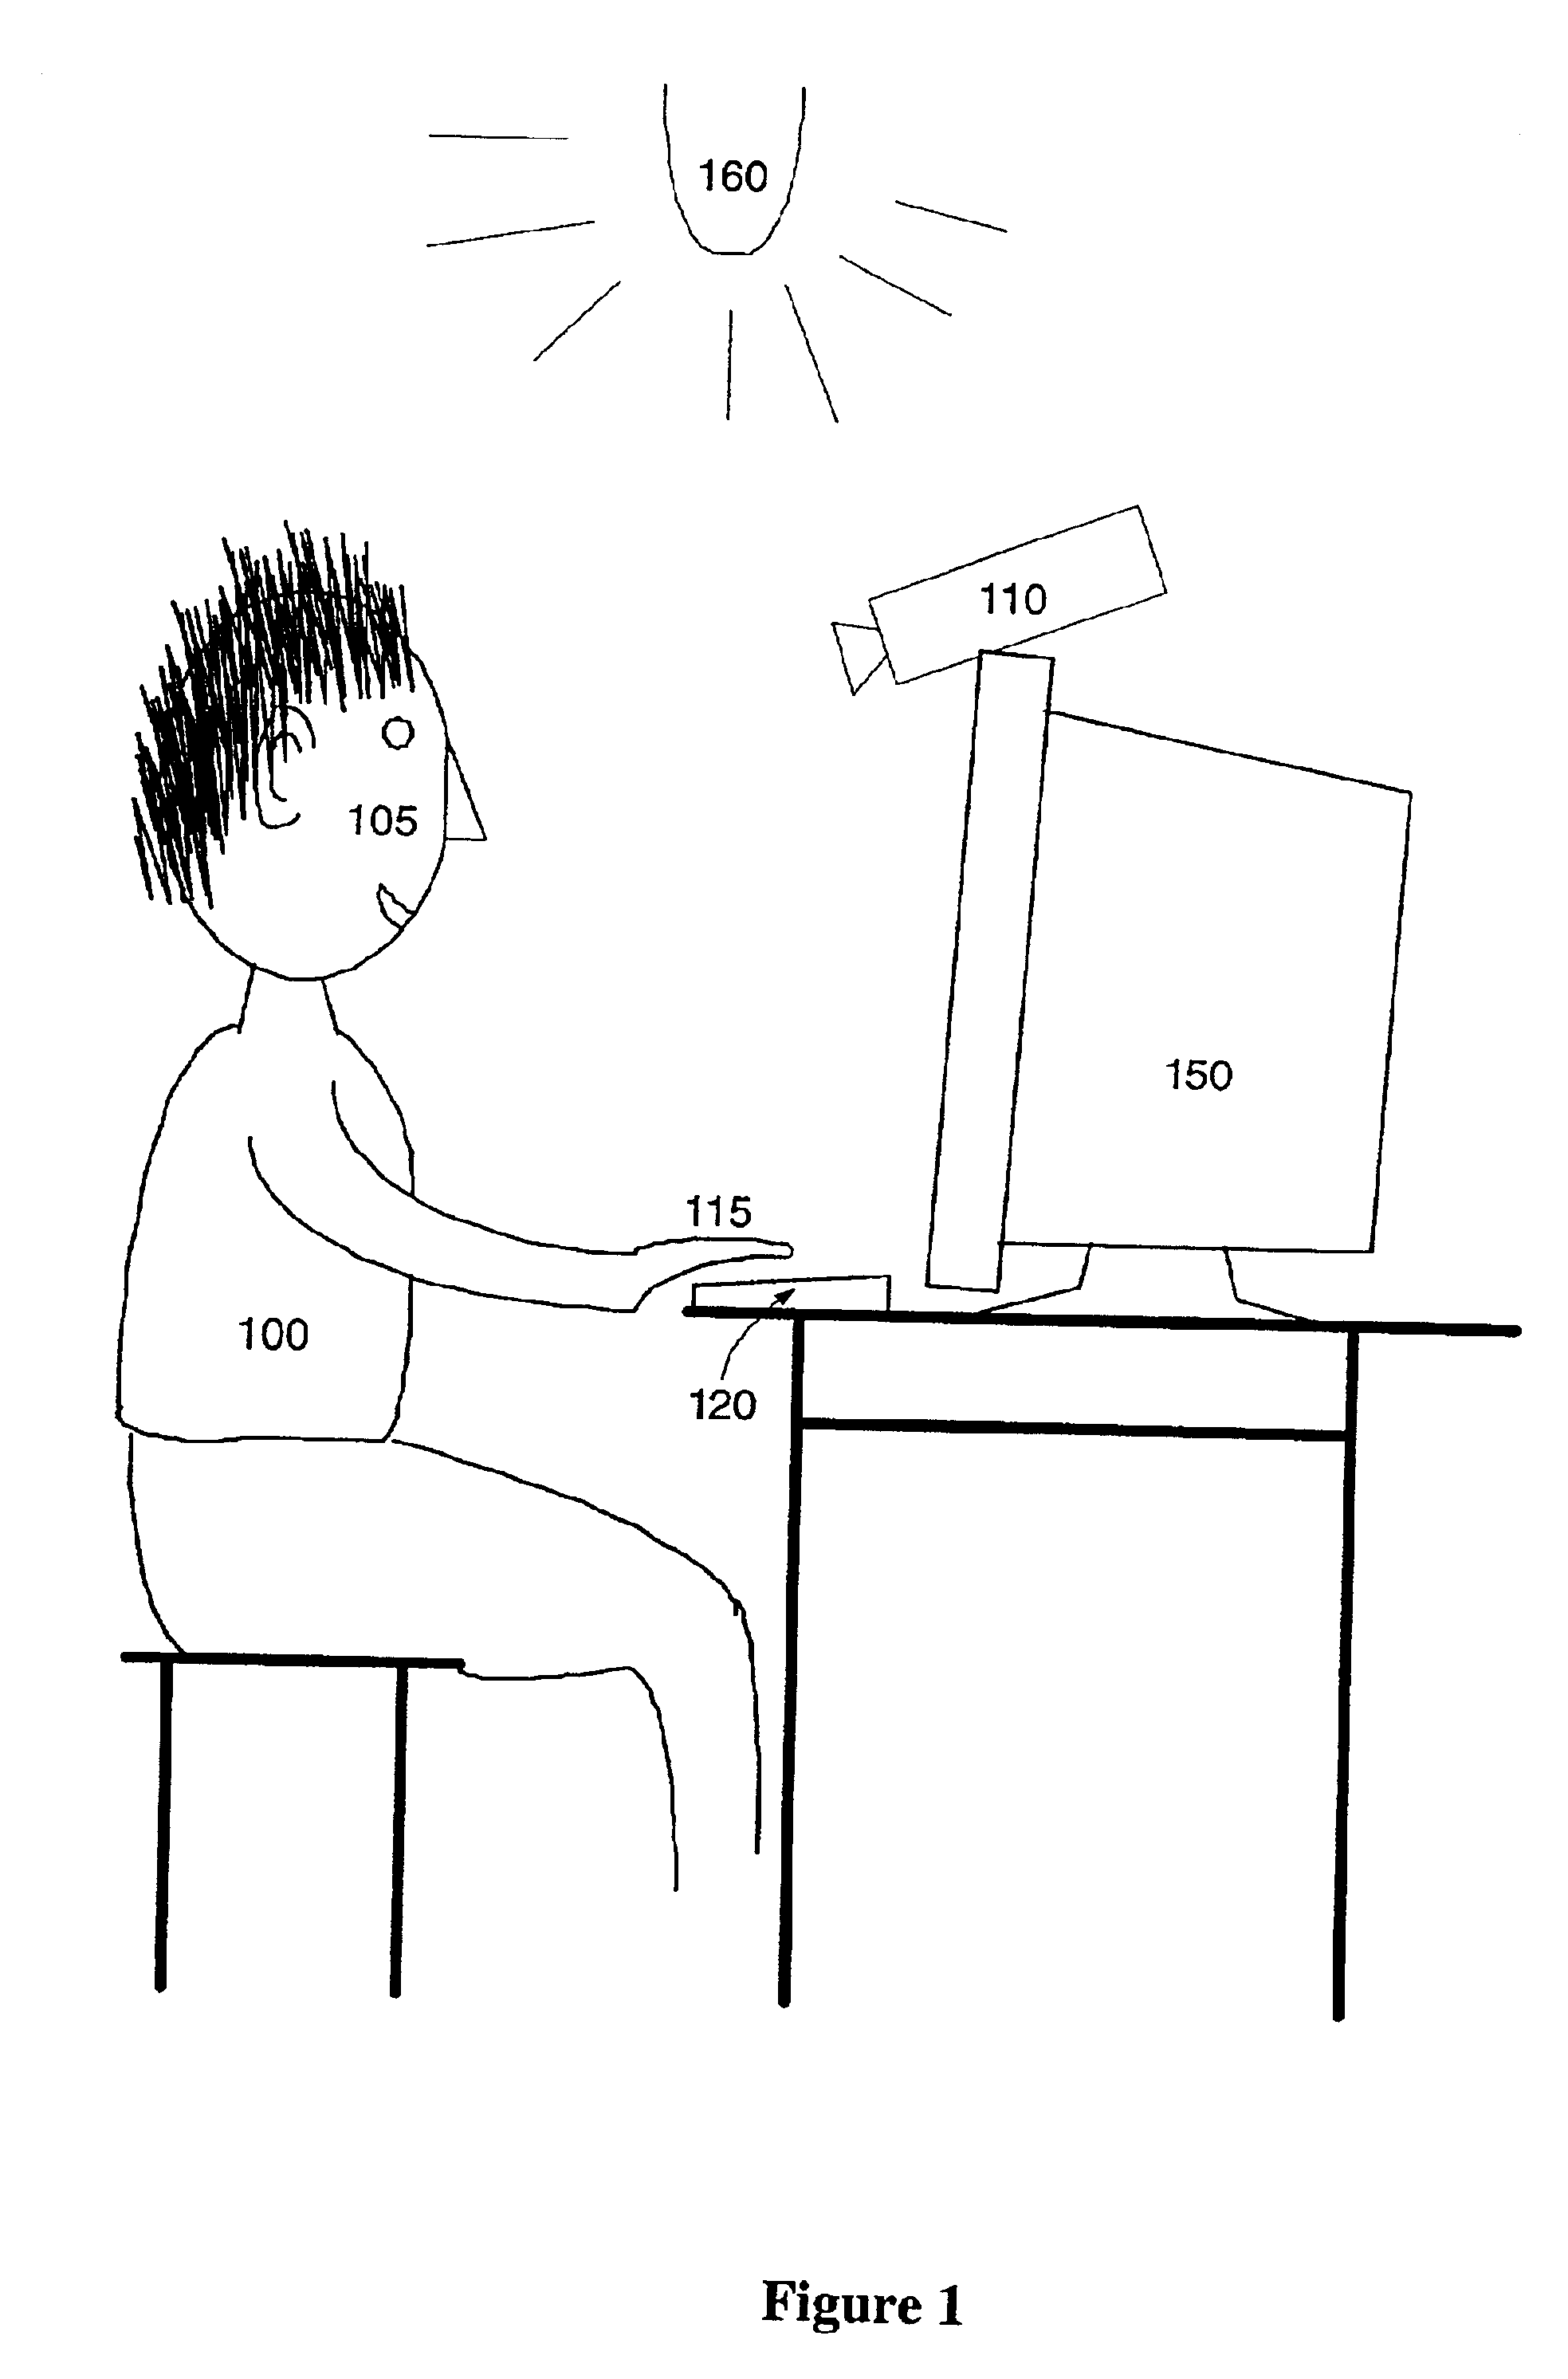
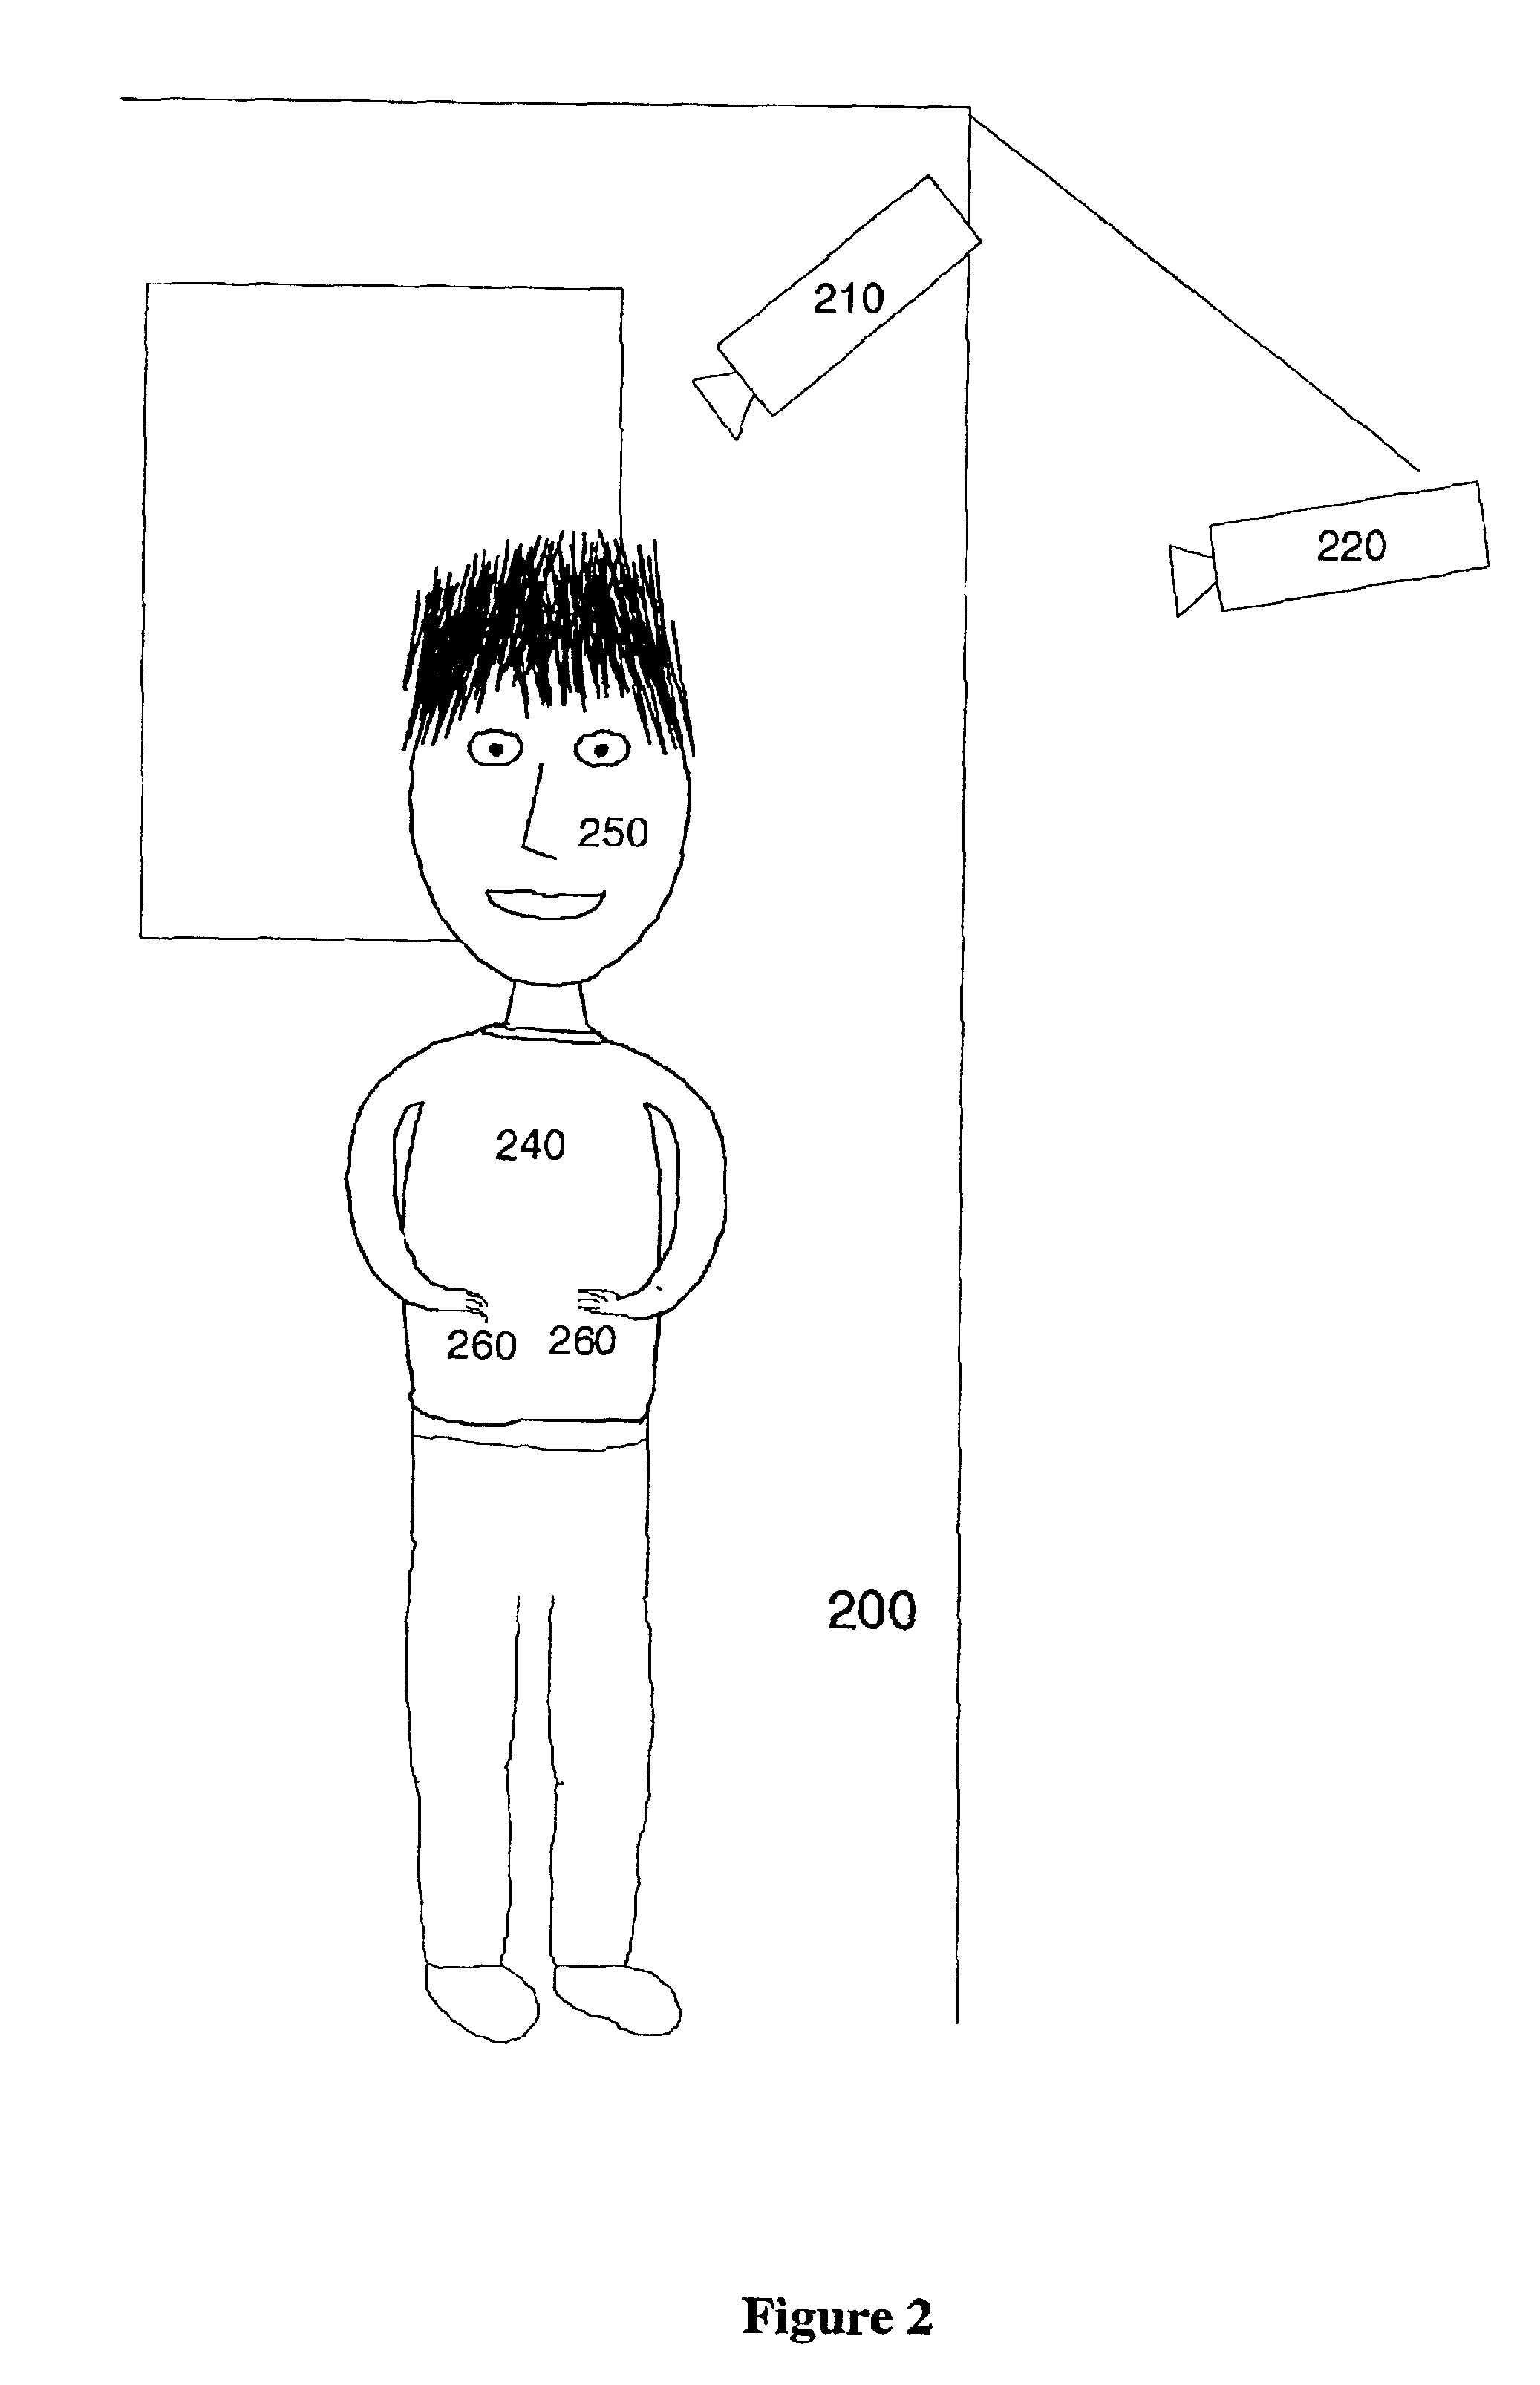
A system and method for automatic detecting neutral expressionless faces in digital images and video is described. First a face detector is used to detect the pose and position of a face and find the facial components. Second, the detected face is normalized to a standard size face. Then a set of geometrical facial features and three histograms in zones of mouth are extracted. Finally, by feeding these features to a classifier, the system detects if there is the neutral expressionless face or not.
Owner:SAMSUNG ELECTRONICS CO LTD
Method and apparatus for creating facial images
InactiveUS6731302B1Fast transferEasy to combineCathode-ray tube indicatorsModifying/creating image using manual inputContrast levelComputer graphics (images)


Owner:INTER QUEST +1
Methods and Apparatus for Automated Facial Feature Localization
ActiveUS20130044958A1Image enhancementCharacter and pattern recognitionPattern recognitionTransformation parameter


Owner:ADOBE INC
Specific expression face detection method, and imaging control method, apparatus and program
InactiveUS20070189584A1Reduce the differenceReduce disagreementAcquiring/recognising facial featuresFace detectionRadiology


Owner:FUJIFILM CORP
Facial expression recognition method based on depth 3D convolution neural network
InactiveCN107463919AEasy to identifyCharacter and pattern recognitionNeural architecturesNerve networkShort-term memory
The present invention provides a facial expression recognition method based on a depth 3D convolution neural network. The main content comprises a 3D initial residual network, a facial mark, a long-term and short-term memory network unit. The process is as follows: a convolution neural network extracts a spacial relationship in a facial image and a temporal relationship among different frames in a video; and because the facial mark is helpful for a network to focus on a more important facial component in a feature map, the facial mark is extracted as an input of the network, which improves the recognition ability of sequences for subtle changes of a facial expression for more accurate recognition. The present invention provides a method for extracting the temporal relationship among frames in a video sequence by using the 3D convolution neural network and the long-term and short-term memory network, wherein, the facial mark is extracted, so as to emphasize more expressive facial components, improve the ability of recognizing the subtle changes of the facial expression, and make more contributions to new designs in the field of lie detection and innovative solutions to the field of justice.


Owner:SHENZHEN WEITESHI TECH
Image-taking apparatus and output image generation method
ActiveUS20080024620A1Slow changeReduce size changeTelevision system detailsCharacter and pattern recognitionComputer graphics (images)Facial region
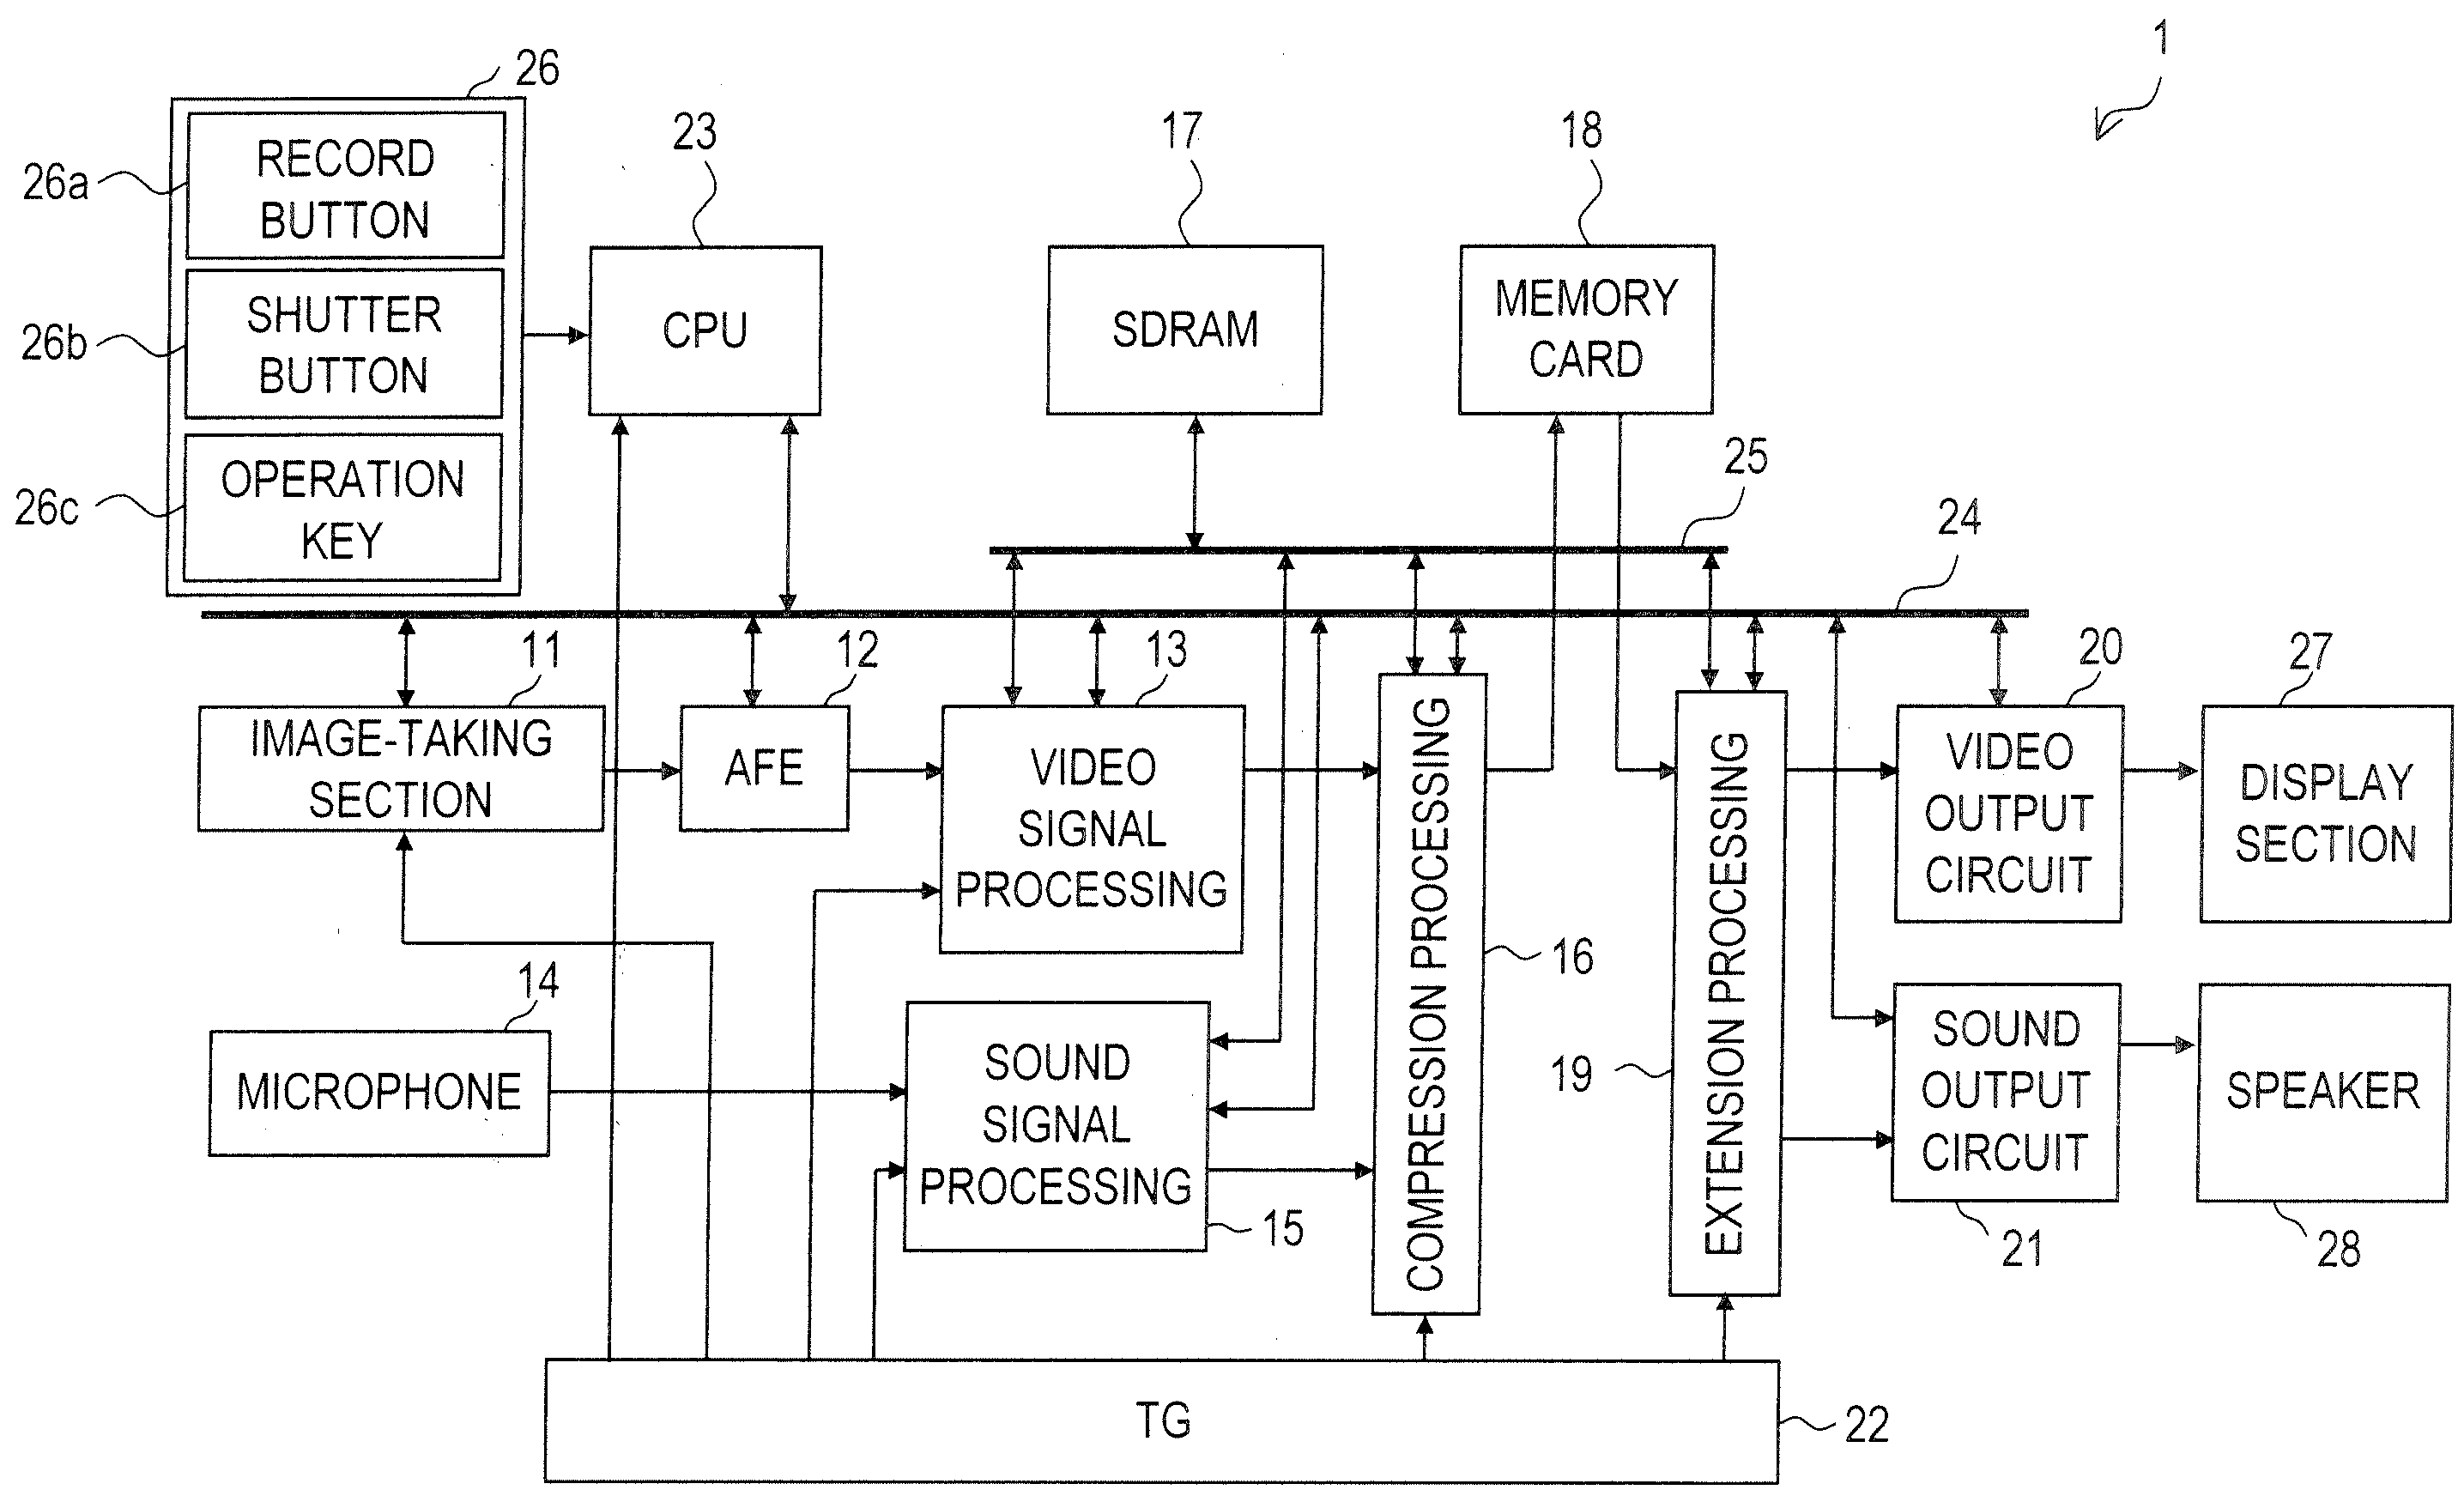
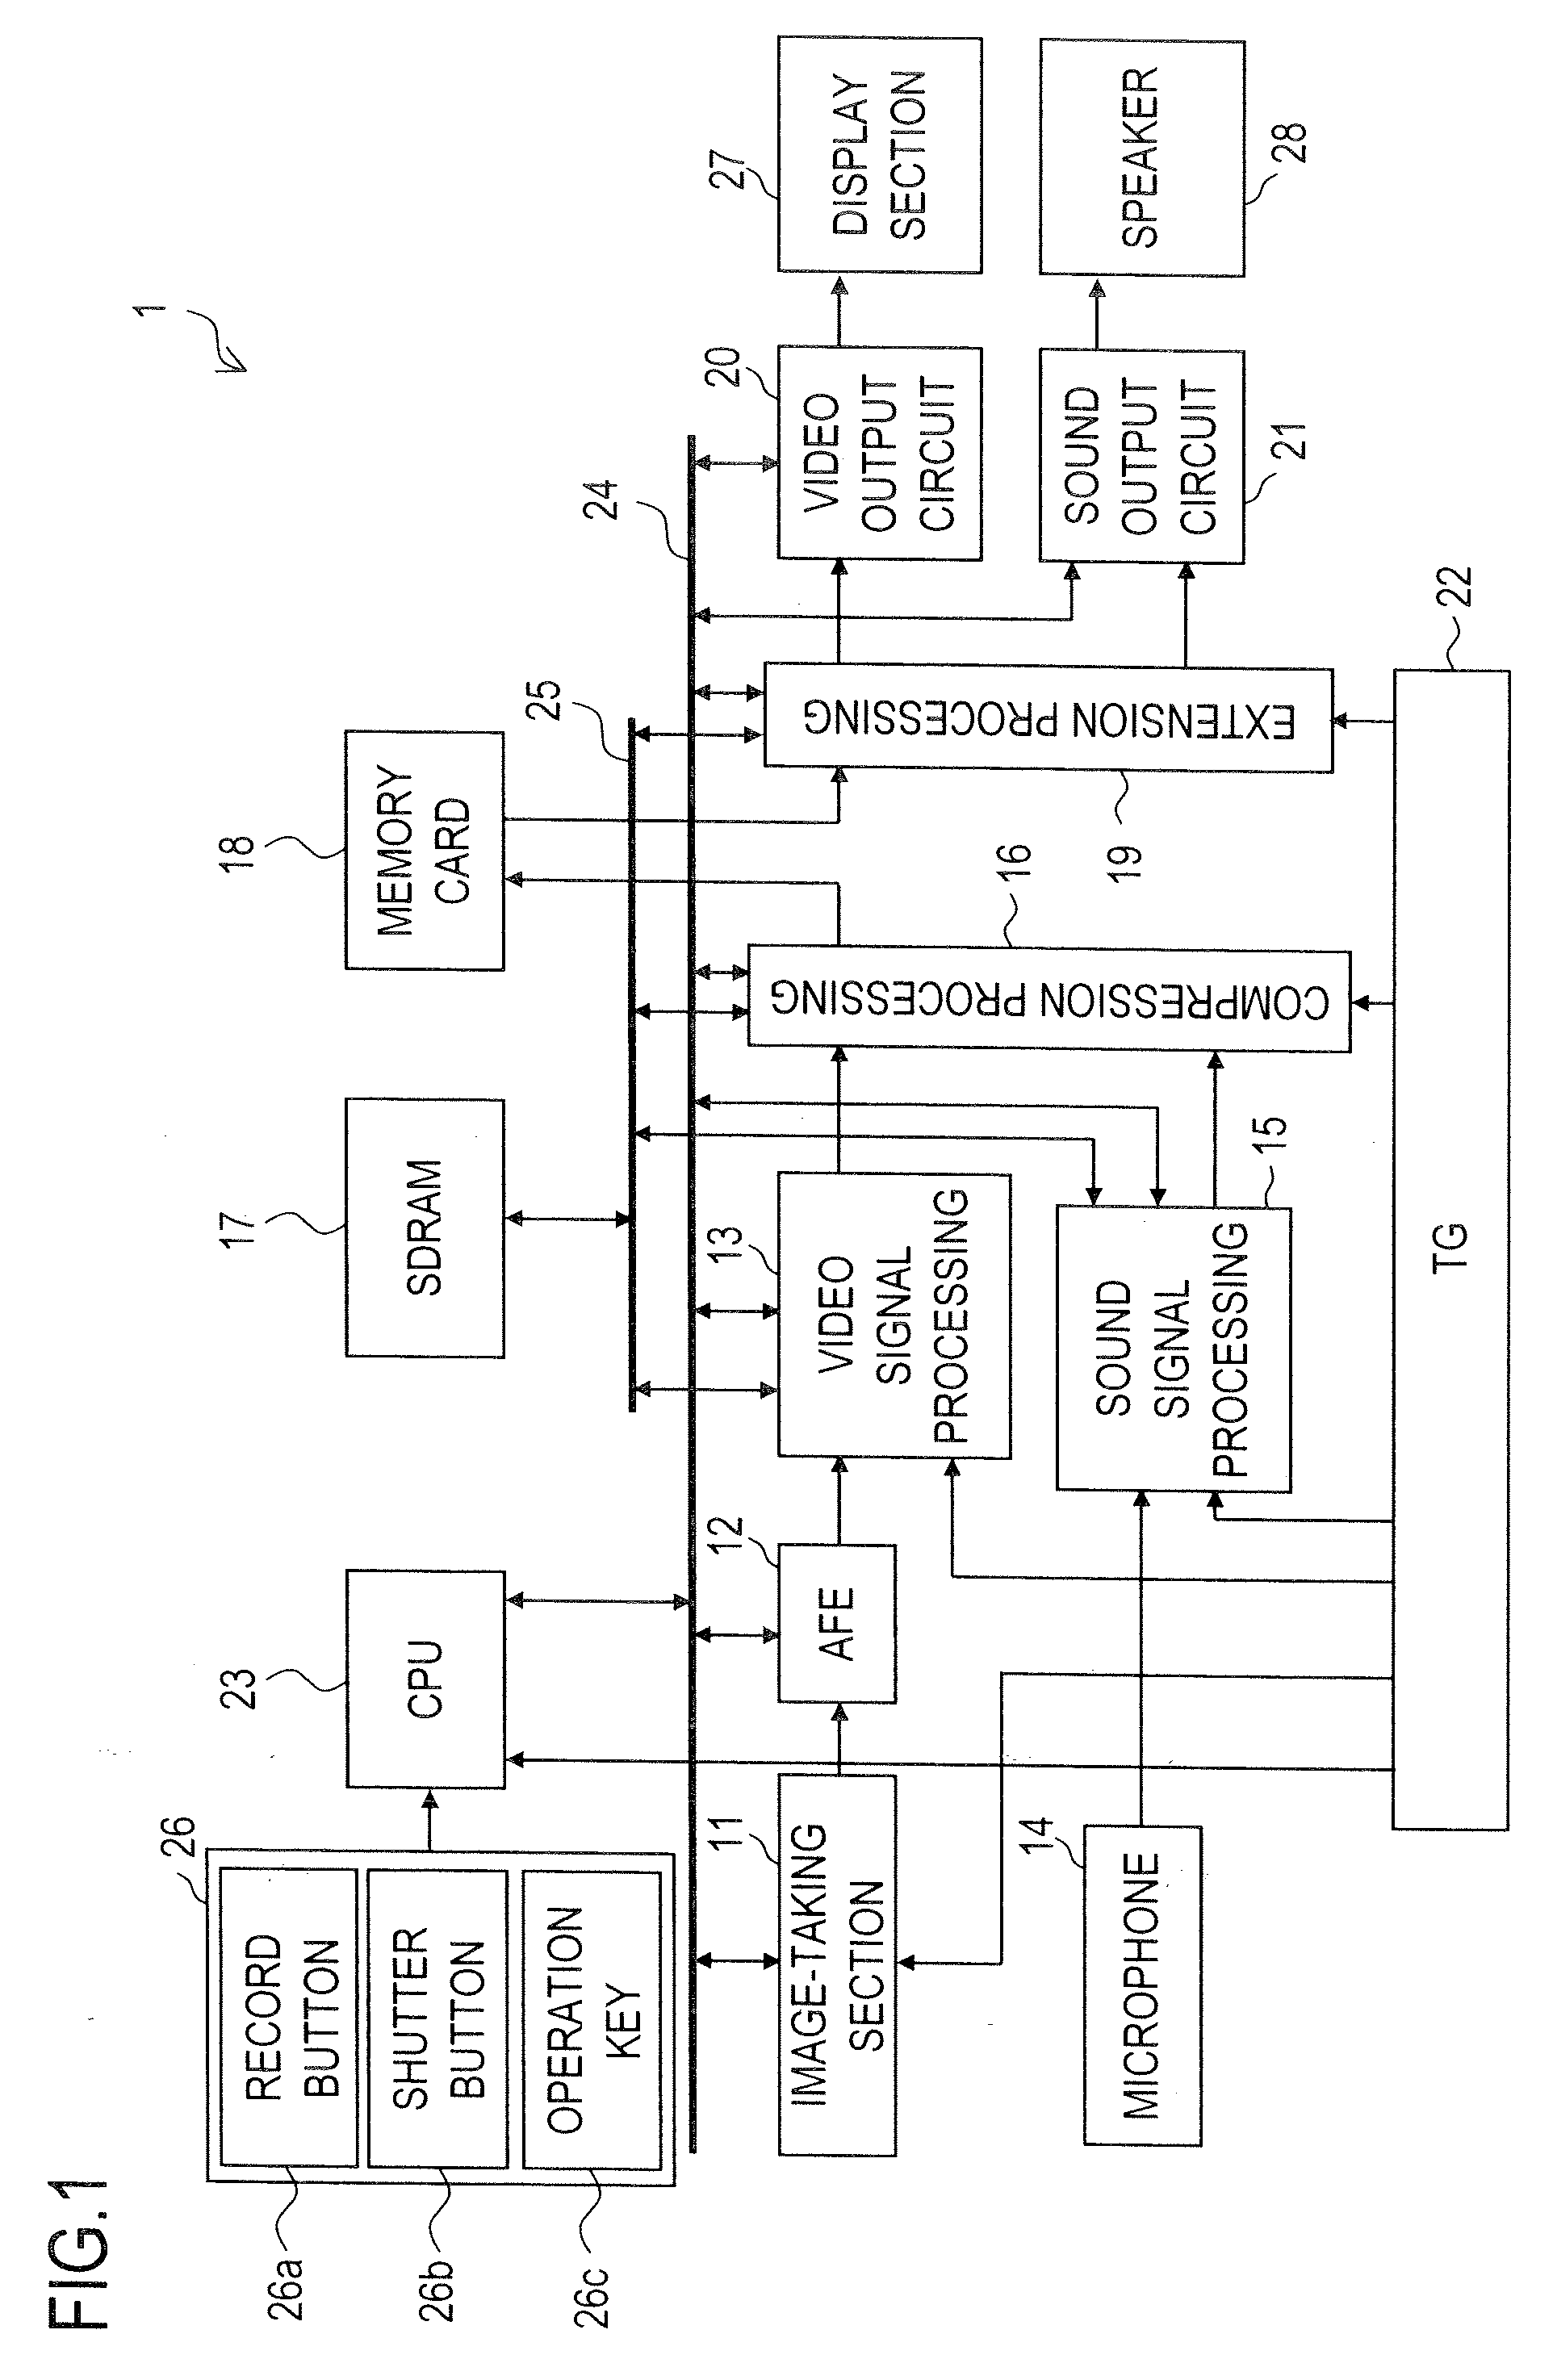
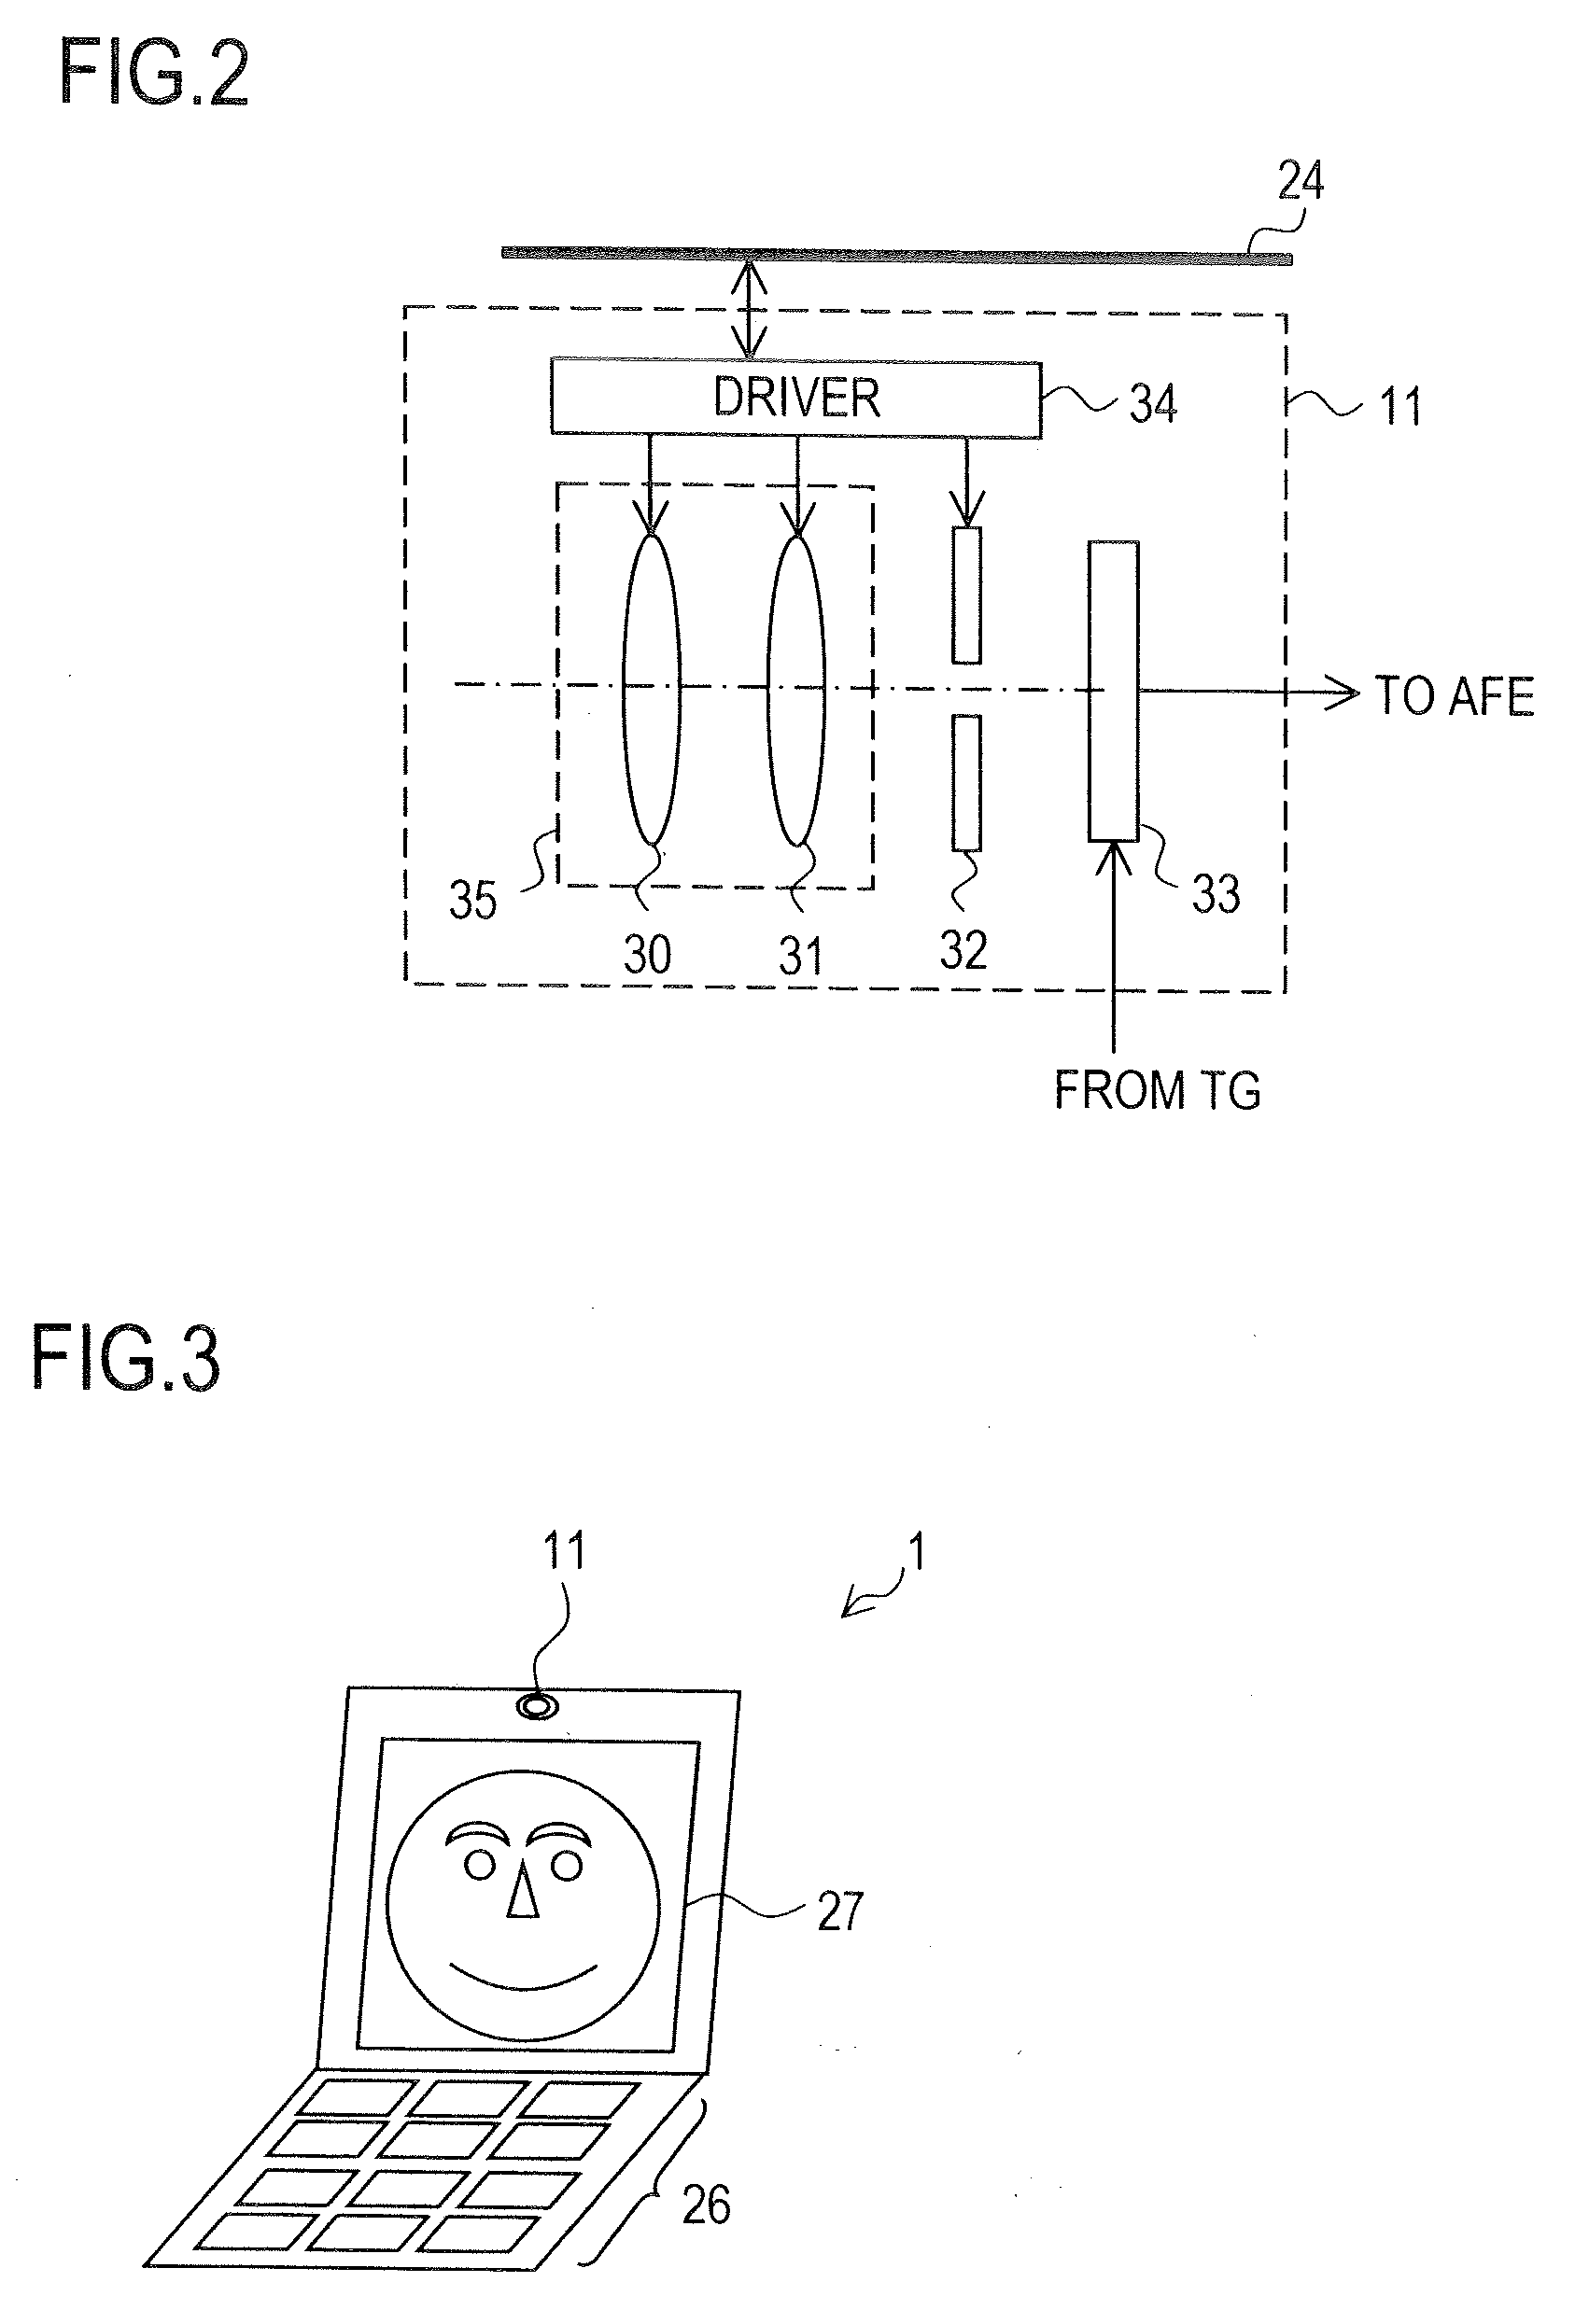
An image-taking apparatus generates an output image from a photographed image obtained by photographing and displays this output image on a display screen of a display section. The image-taking apparatus includes a recognition processing section for recognizing a specific subject (facial region of a person, or a facial component such as eyes) included in the photographed image. Referring to results of this recognition, the image-taking apparatus evaluates the dimension of the specific subject in each photographed image. If the dimension evaluated is relatively large, a relatively small magnification ratio to be employed upon the generation of the output image from the photographed image is provided. If the dimension evaluated is relatively small, a relatively large magnification ratio to be employed upon the generation of the output image from the photographed image is provided. As a result, the dimension of the specific subject in the output image is kept substantially constant.
Owner:XACTI CORP
Digital Image Enhancement
InactiveUS20090297029A1Television system detailsCharacter and pattern recognitionPattern recognitionDigital image
Methods and systems for enhancing a digital image include analyzing the digital image to determine if the digital image includes a facial component. Facial characteristics of the facial component are determined for each image that does include at least one facial component. The digital image is then modified based on the facial characteristics.


Owner:HEWLETT PACKARD DEV CO LP
Audio-driven facial animation using machine learning
Systems and methods of the present disclosure include animating virtual avatars or agents according to input audio and one or more selected or determined emotions and / or styles. For example, a deep neural network can be trained to output motion or deformation information for a character that is representative of the character uttering speech contained in audio input. The character can have different facial components or regions (e.g., head, skin, eyes, tongue) modeled separately, such that the network can output motion or deformation information for each of these different facial components. During training, the network can use a transformer-based audio encoder with locked parameters to train an associated decoder using a weighted feature vector. The network output can be provided to a renderer to generate audio-driven facial animation that is emotion-accurate.

Owner:NVIDIA CORP
Methods and apparatus for automated facial feature localization
ActiveUS8824808B2Image enhancementCharacter and pattern recognitionPattern recognitionTransformation parameter


Owner:ADOBE INC
Database constructing system
InactiveUS7010146B2Automatic collectionSpectales/gogglesCharacter and pattern recognitionWeb browserStatistical analysis
In order to provide a database constructing system in which information from a plurality of persons can be automatically collected without being limited to a customer visiting a store and personal goods to wear or carry which the person likes associated with the personal characteristics to construct database, the database constructing system comprises a web server 11 for showing information on eyeglass frame; a statistical analyzing means 24 for dividing a personal facial picture 22a into component to classify them into a type of every facial component 22c and statistically analyzing a relationship between the type of every component 22c and a selected eyeglass frame 14 in order to collect data for associating a personal facial type with the selected eyeglass frame 14 on the basis of the personal facial picture 22a and information on the eyeglass frame 14 selected by the person transmitted to the web server 11 by using a web browser; and a memory means 21 for associating and preserving the information on type of every facial component 22c and the selected eyeglass frame 14.


Owner:KK TOPCON
Side face recognition method based on kernel standard correlation analysis
ActiveCN107292299AImprove recognition rateQuick identificationCharacter and pattern recognitionKernel principal component analysisChin
The invention discloses a side face recognition method based on a kernel standard correlation analysis. The method includes: for the right side portion and the side face portion of a to-be-detected face image, manually noting the eyes, the nose, the mouth, and the chin; performing geometrical normalization processing with different degrees on the right side and side face attitudes, describing the face by employing a local binary pattern facial component, calculating 64 histograms for divided areas in a local binary pattern image, and connecting the histograms of 14 areas of the face to form a vector for description; and after extracting a local binary characteristic vector, performing dimension reduction operation through application of the standard correlation analysis, introducing non-linear generalization based on a kernel principal component analysis to consider the transformation non-linearity between a side face image and a right side face image, performing transformation of the right side or the side surface through mapping from an original input space to a high-dimensional characteristic space, calculating the Euclidean distance, and giving side face image identity information. According to the method, rapid recognition of the side face can be effectively realized in a non-restricted condition.


Owner:HENAN INST OF ENG
Image-taking apparatus and output image generation method
ActiveUS8363146B2Reduce size changeSlow changeTelevision system detailsCharacter and pattern recognitionComputer graphics (images)Facial region
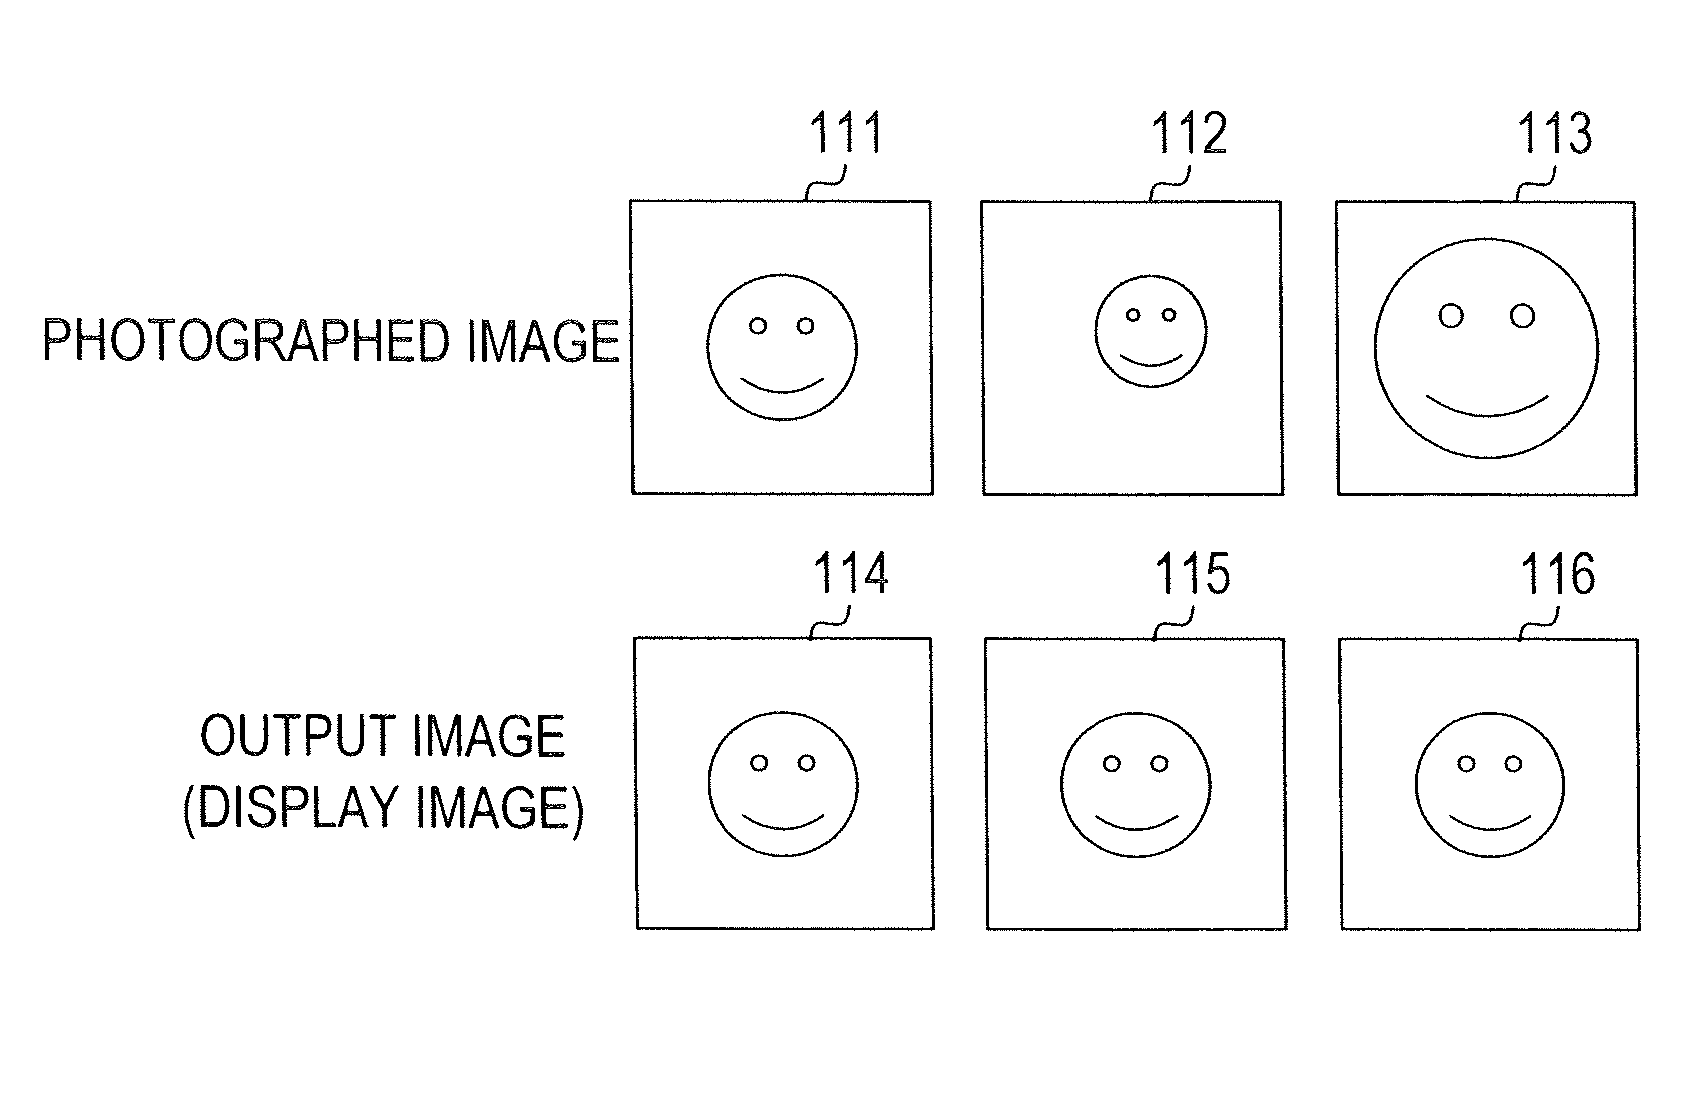
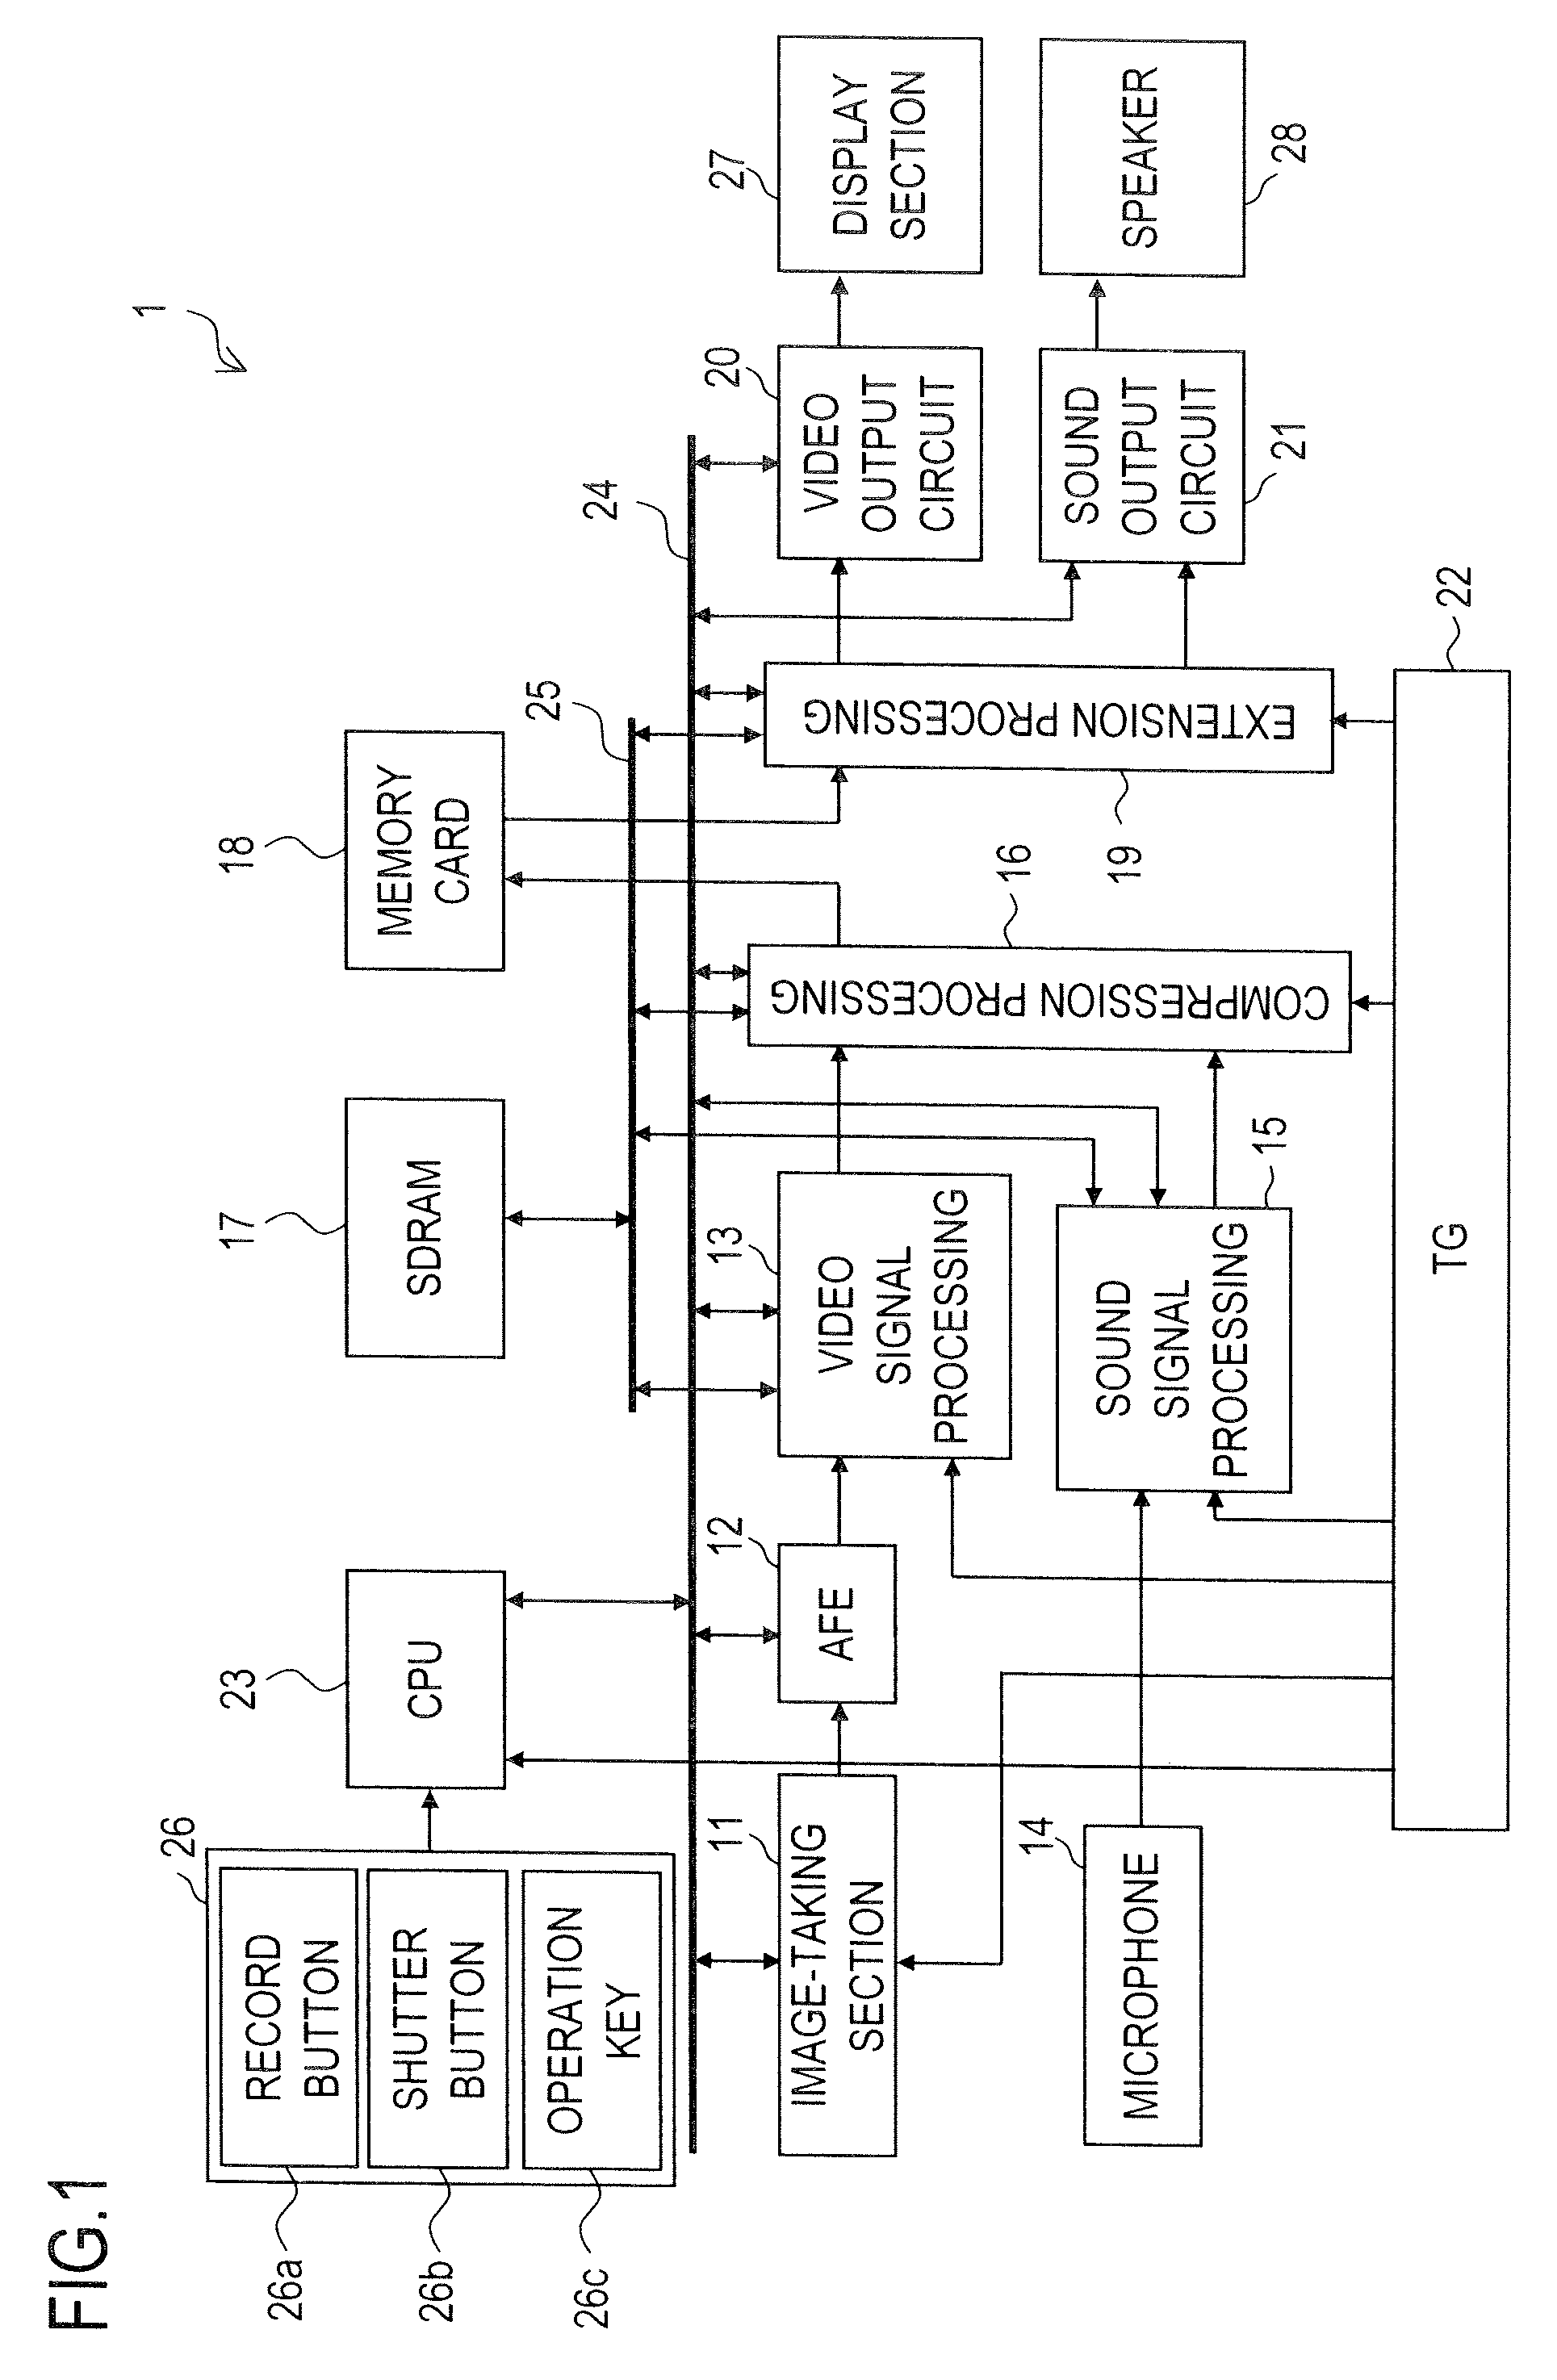
An image-taking apparatus generates an output image from a photographed image obtained by photographing and displays this output image on a display screen of a display section. The image-taking apparatus includes a recognition processing section for recognizing a specific subject (facial region of a person, or a facial component such as eyes) included in the photographed image. Referring to results of this recognition, the image-taking apparatus evaluates the dimension of the specific subject in each photographed image. If the dimension evaluated is relatively large, a relatively small magnification ratio to be employed upon the generation of the output image from the photographed image is provided. If the dimension evaluated is relatively small, a relatively large magnification ratio to be employed upon the generation of the output image from the photographed image is provided. As a result, the dimension of the specific subject in the output image is kept substantially constant.
Owner:XACTI CORP
Audio driven facial animation using machine learning
The invention discloses audio-driven facial animation using machine learning. Systems and methods of the present disclosure include animating an avatar or proxy according to input audio and one or more selected or determined emotions and / or styles. For example, a deep neural network may be trained to output motion or deformation information of a character representing that the character spokes an utterance contained in the audio input. The character may have different facial components or regions (e.g., head, skin, eyes, tongue) that are modeled individually, such that the network may output motion or deformation information for each of these different facial components. During training, the network may train associated decoders using weighted feature vectors using converter-based audio encoders with locked parameters. The network output may be provided to a renderer to generate a mood-accurate audio-driven facial animation.

Owner:NVIDIA CORP
Image creating device, image creating method and recording medium
ActiveUS9437026B2Easy to createCharacter and pattern recognitionEditing/combining figures or textComputer visionRecording media


Owner:CASIO COMPUTER CO LTD
Digital image enhancement
InactiveUS8184869B2Television system detailsCharacter and pattern recognitionPattern recognitionRadiographic Image Enhancement
Methods and systems for enhancing a digital image include analyzing the digital image to determine if the digital image includes a facial component. Facial characteristics of the facial component are determined for each image that does include at least one facial component. The digital image is then modified based on the facial characteristics.


Owner:HEWLETT PACKARD DEV CO LP
Method and device for processing audio data
The invention relates to an audio data processing method, a neural network training method, an audio data processing device, electronic equipment and a computer readable storage medium. The method comprises the following steps: determining facial prior information of a virtual object based on reference video data; determining a target audio feature based on the target audio data; determining target expression sequence information based on the face prior information and the target audio feature; and determining target video data corresponding to the target audio data based on the target expression sequence information and a reference frame in the reference video data. According to the method and the device, the synchronization precision between the audio content and the facial component (such as the mouth) action of the virtual object can be remarkably improved, the real texture of the mouth action is enhanced, the expression difference between individuals is more accurately captured and reproduced, and the operation efficiency and the stability of the whole system are also improved while the performance of the system is improved.

Owner:TENCENT TECHNOLOGY (SHENZHEN) CO LTD
Audio data processing method, neural network training method, and related apparatus
PCT designated stageWO2025180271A1Speech analysisSelective content distributionPattern recognitionTarget expression
The present disclosure relates to an audio data processing method, a neural network training method, an audio data processing apparatus, an electronic device, and a computer readable storage medium. The audio data processing method comprises: determining facial prior information of a virtual object on the basis of reference video data; determining a target audio feature on the basis of target audio data; determining target expression sequence information on the basis of the facial prior information and the target audio feature; and on the basis of the target expression sequence information and a reference frame in the reference video data, determining target video data corresponding to the target audio data. According to the present disclosure, the synchronization precision between audio content and a facial component (e.g., the mouth) action of a virtual object can be significantly improved, the sense of reality of the mouth action is enhanced, an expression difference between individuals is captured and reproduced more accurately, and the operation efficiency and stability of the whole system are improved while the system performance is improved.

Owner:TENCENT TECHNOLOGY (SHENZHEN) CO LTD
Profile Face Recognition Method Based on Kernel Canonical Correlation Analysis
ActiveCN107292299BImprove recognition rateQuick identificationCharacter and pattern recognitionKernel principal component analysisFeature vector
The invention discloses a side face recognition method based on kernel specification correlation analysis. For the front part and side face part of the face image to be detected, manually annotate the eyes, nose, mouth and chin, and make different postures of the front face and the side face. Degree of geometric normalization processing, use the local binary mode facial components to describe the face, calculate 64 histograms for the divided regions in the local binary mode image, and then connect the histograms of the 14 regions of the face into a vector for description , after extracting the local binary feature vector, the dimensionality reduction operation is performed by applying canonical correlation analysis, and the nonlinear generalization based on kernel principal component analysis is introduced to consider the transformation nonlinearity between the side face image and the front face image, by Mapping from the original input space to the high-dimensional feature space to perform front or side transformation, and calculate the Euclidean distance to give the identity information of the side face image; effectively realize the fast recognition of the side face under unrestricted conditions.


Owner:HENAN INST OF ENG
Expression editing method based on facial components, electronic device and readable storage medium
The present invention discloses an expression editing method based on facial components, an electronic device and a readable storage medium, aiming to achieve high-quality expression editing. The method comprises the following steps: first, using SemanticStyleGAN to semantically segment the input face image, extract local facial components, and extract local expression features through the visual and text encoders of the CLIP model in combination with the prior knowledge of facial action units; second, using MobileFaceNet to detect key points of the face and extract global features; through the attention mechanism, learning and fusing global features and local features to generate features related to expression; at the same time, using the gradient reversal technology to extract features unrelated to expression to ensure that the facial structure is not affected by expression editing; finally, combining with the diffusion model, based on the fusion results of expression-related and unrelated features, gradually denoising and reconstructing a high-fidelity edited image.

Owner:HANGZHOU INST FOR ADVANCED STUDY UCAS
Facial expression analysis method based on feature points and local features
PendingCN114022921AImprove generalization abilityReduce redundancyCharacter and pattern recognitionEnergy efficient computingData setSupport vector machine classification
The invention discloses a facial expression analysis method based on feature points and local features, belongs to the technical field of facial expression analysis, and aims to solve the technical problem of how to predict facial expressions through multi-feature combination and improve the prediction accuracy. The method comprises the following steps: extracting coordinate values of face key points, and performing reduction and clipping processing on a face image based on the coordinate values of the face key points to obtain feature points; for each preprocessed face image, face parts are extracted based on the coordinate values of the face key points; dividing each face part into a plurality of face sub-regions, extracting a local binary pattern from each face sub-region to obtain a row vector, and splicing each face image and each preprocessed face image with the corresponding row vector to obtain a row vector; forming a feature matrix as a local feature based on all row vectors corresponding to the face image data set; and carrying out support vector machine classification to train a support vector machine, and carrying out expression prediction through the trained support vector machine.


Owner:QILU UNIV OF TECH
AUDIO-DRIVEN FACIAL ANIMATION USING MACHINE LEARNING
Systems and methods of this disclosure involve animating virtual avatars or agents according to input audio and one or more selected or specific emotions and / or styles. For example, a deep neural network can be trained to output motion or deformation information for a character representing the character speaking speech contained in the audio input. The character may have various facial components or regions (e.g., head, skin, eyes, tongue) that are modeled separately, so that the network can output motion or deformation information for each of these different facial components. During training, the network may use a transformer-based audio encoder with locked parameters to train an associated decoder using a weighted feature vector.The network output can be provided to a renderer to generate audio-driven facial animation that is emotion-accurate.

Owner:NVIDIA CORP
A medical three-dimensional surface scanning system accuracy detection phantom device and evaluation method
The invention discloses a medical three-dimensional surface scanning system accuracy detection phantom device and a related evaluation method. The phantom can be used to evaluate the accuracy of reconstruction of human facial features. The phantom includes a phantom frame, multiple facial feature components and an angle controller. The present invention is used in the analysis and evaluation of the reconstruction accuracy of the medical three-dimensional surface scanning system, which has the characteristics of simple structure, strong practicability, and high flexibility. Quality assurance and quality control provide effective means.


Owner:AFFILIATED STOMATOLOGICAL HOSPITAL OF NANJING MEDICAL UNIV
Audio-driven facial animation with emotion support using machine learning
A deep neural network can be trained to output motion or deformation information for a character that is representative of the character uttering speech contained in audio input, which is accurate for an emotional state of the character. The character can have different facial components or regions (e.g., head, skin, eyes, tongue) modeled separately, such that the network can output motion or deformation information for each of these different facial components. During training, the network can be provided with emotion and / or style vectors that indicate information to be used in generating realistic animation for input speech, as may relate to one or more emotions to be exhibited by the character, a relative weighting of those emotions, and any style or adjustments to be made to how the character expresses that emotional state. The network output can be provided to a renderer to generate audio-driven facial animation that is emotion-accurate.

Owner:NVIDIA CORP
Method, apparatus, and system for processing facial images
ActiveCN114792356BDetails involving processing stepsCharacter and pattern recognitionRadiologyFacial component
The present application discloses a method, apparatus, and system for processing facial images. Among them, the method includes: obtaining a facial image of an entity object, where the facial image includes images of multiple facial components of the entity object; generating an initial virtual object based on the multiple facial components in the facial image; constructing a three-dimensional model of the facial image; and adjusting the initial virtual object based on the three-dimensional model to generate a target virtual object. The present application solves the technical problem in the related art that generating virtual objects manually results in high processing costs and poor effects.

Owner:ALIBABA DAMO (HANGZHOU) TECH CO LTD
Human character cartoon image generating method and apparatus
InactiveCN101477696BFeaturesAvoid positionImage analysis2D-image generationPattern recognitionFacial component


Owner:苏州华漫信息服务有限公司

A facial mask containing Cordyceps militaris and preparation method thereof
InactiveCN104352424BImprove wrinkle resistanceEfficient killingCosmetic preparationsToilet preparationsAdditive ingredientPurslane extract
The invention discloses a cordyceps militaris ingredient containing mask, which is prepared from five raw material components A, B, C, D and E in parts by weight, wherein the component A comprises pure water, hydrolyzed oat protein, xylitol, tranexamic acid, and dipotassium glycyrrhizinate; the component B comprises glycerin, and transparent xanthan gum; the component C comprises butanediol, nipagin, and scutellaria root extract; the component D comprises trinosin, cordyceps sinensis extract, hydrolyzed royal jelly, aloe fermentation broth, purslane extract, persimmon leaf extract, orange peel extract, phellinus igniarius extract, salicis extract, vanilla extract, roasted rosa rugosa extract, mung bean extract, green tea extract, lithospermum extract, chamomile extract, tree moss extract, and honeysuckle extract; and the component E comprises deionized water. The invention also provides a preparation method of the cordyceps militaris ingredient containing mask. The mask prepared by using the method has the characteristics of safety, no toxicity and wrinkle resistance, and is low in production cost.
Owner:沈阳园康天然生物科技有限公司
Sleeved simple detachable watchband
The utility model discloses a suite simple detachable watchband. The suite simple detachable watchband comprises at least one detachable structure forming the watchband, the detachable structure is composed of a surface layer component and a bottom layer component, the surface layer component and the bottom layer component are both in a groove shape, the two sides of the surface layer component and the bottom layer component are both of an open structure, one side of the surface layer component and one side of the bottom layer component are each provided with a penetrating channel allowing the surface layer component and the bottom layer component to be buckled, and the other side of the surface layer component and the other side of the bottom layer component are each provided with a hole channel matched with other detachable structures. The bottom layer component is provided with a limiting block capable of preventing the surface layer component from excessively penetrating. The surface layer component and the bottom layer component are assembled to form the integral disassembly piece, only the vacant site of the surface component of another disassembly piece needs to be embedded with the vacant site of the bottom component of the disassembly piece, and in order to stably fix after embedding, the bottom slingshot piece of the top bottom layer component deforms, so that the embedded components are fixed; when disassembly is needed, the face assembly of the other disassembly piece is pressed to enable the bottom slingshot piece to deform, so that the disassembly can be smoothly carried out.

Owner:TONG JIA SHI METAL MFR CO LTD
Image processing method and device, storage medium and electronic equipment
The invention discloses an image processing method and device, a storage medium and electronic equipment. The method comprises the steps that a source image and a reference image are acquired; performing semantic segmentation processing on the reference image to obtain a reference semantic segmentation map of a non-facial component containing the reference image; processing the source image, the reference image and the reference semantic segmentation image to obtain an undetermined image in which the features of the source image and the reference image are fused at the position corresponding to the face component of the reference image; and according to the key point information of the reference image, performing color processing on the part, corresponding to the face component of the reference image, of the to-be-determined image to obtain a composite image. According to the scheme, the feature of the source image can be represented in the fusion result, and the facial component feature of the source image in the synthesized image can be matched with the region where the internal feature of the reference image is located.


Owner:BEIJING PERFECT WORLD SOFTWARE TECH DEV CO LTD
Golf club head
InactiveCN1788815AIncrease flight distanceImprove hitting feelingGolf clubsRacket sportsEngineeringGolf Ball
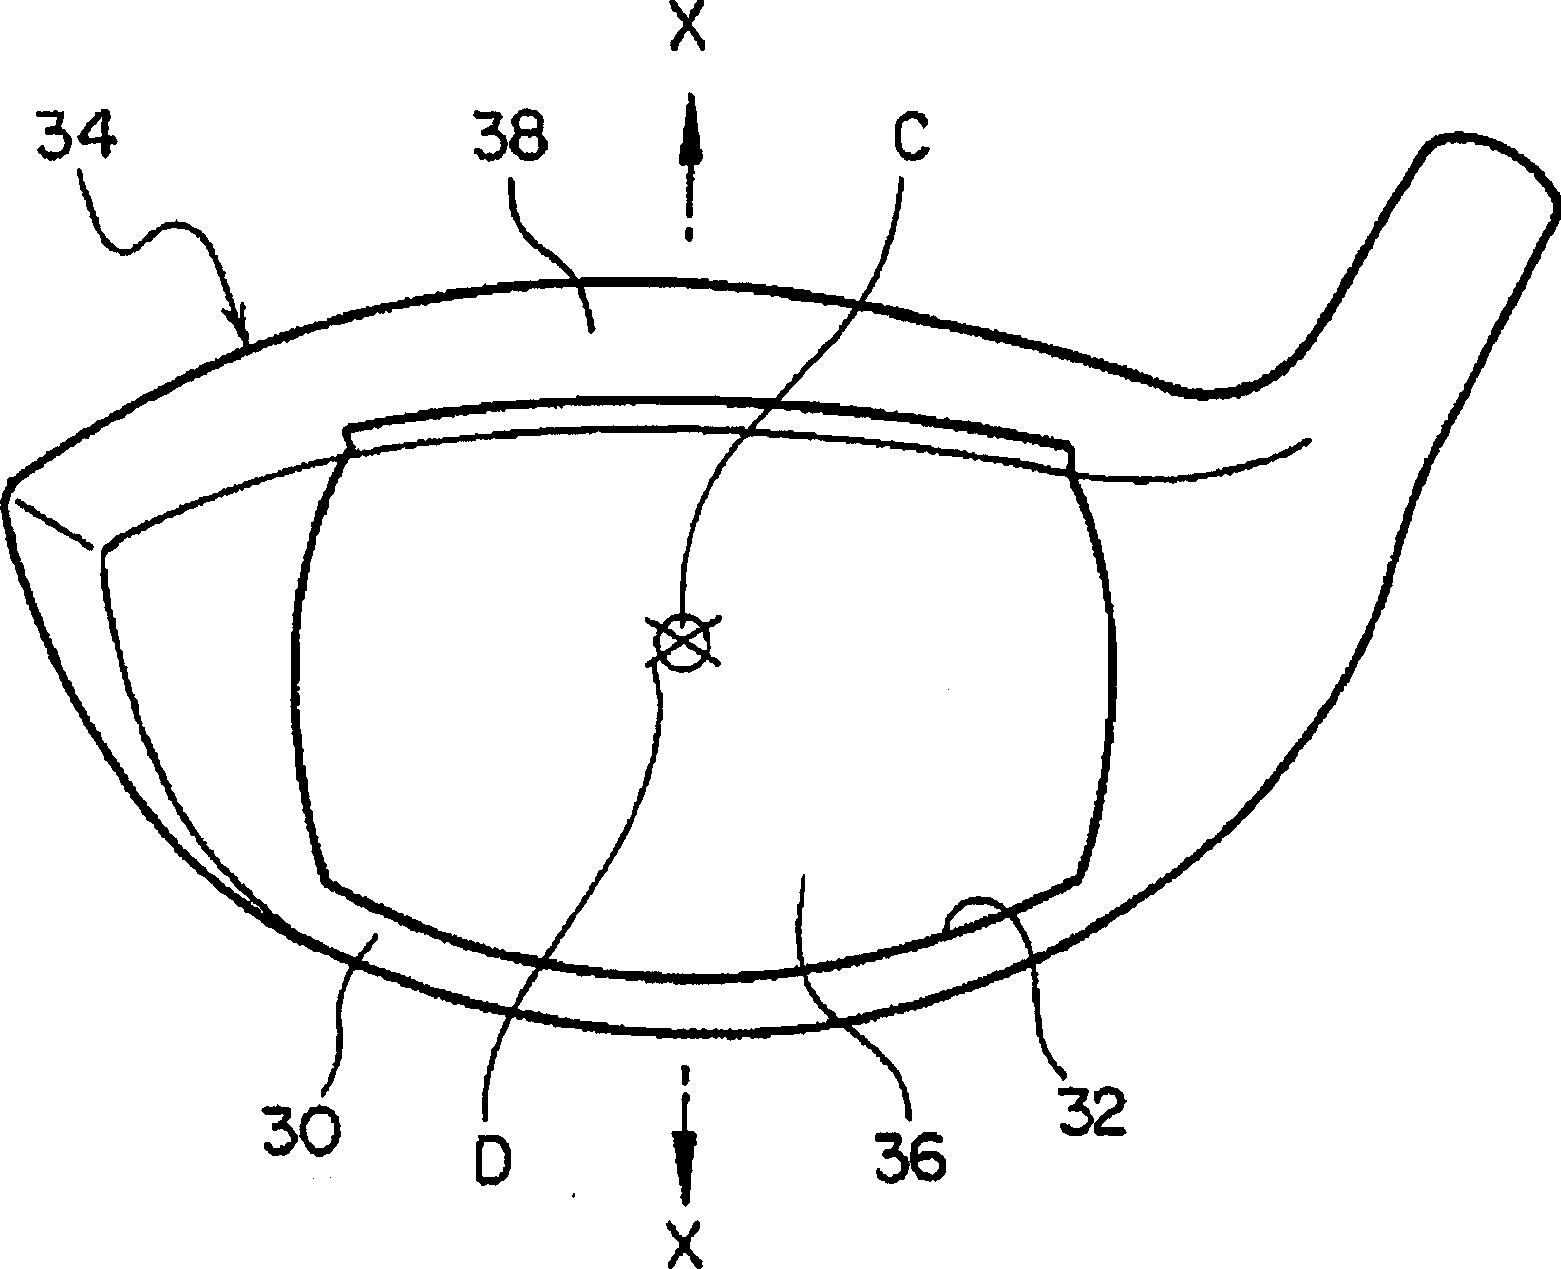
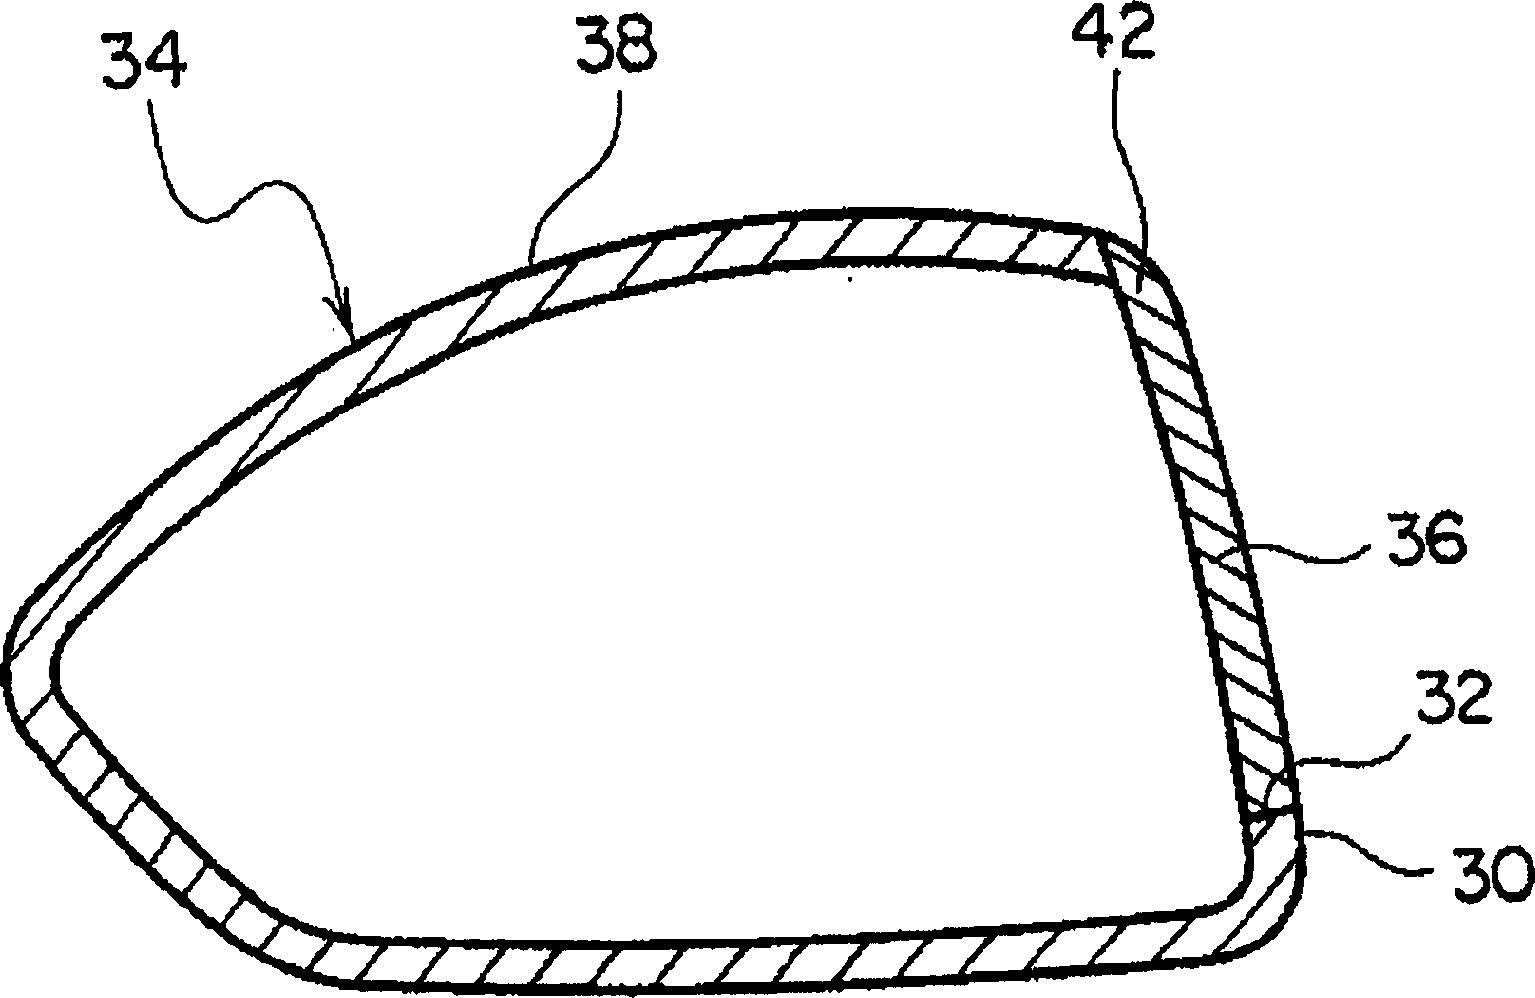
The present invention provides a golf club head in which the face part is sufficiently bent when hitting a golf ball with the face part, thereby improving the flight distance and the hitting feeling. The hollow golf club head of the present invention has a head body (34) and a face member (36), the head body (34) has a face opening (32) on the ball striking surface (30), and the face member (36) For filling the face opening, part or all of the upper edge of the face opening and the upper edge of the face member extends to the crown (38).
Owner:BRIDGESTONE SPORTS CO LTD