

Patents
Literature
50 results about "Pose prediction" patented technology
Efficacy Topic
Property
Owner
Technical Advancement
Application Domain
Technology Topic
Technology Field Word
Patent Country/Region
Patent Type
Patent Status
Application Year
Inventor
Predictive virtual reality display system with post rendering correction
ActiveUS20170018121A1Enhance the virtual reality experienceEffectively approximatesInput/output for user-computer interactionGeometric image transformationComputer graphics (images)Biomechanical model
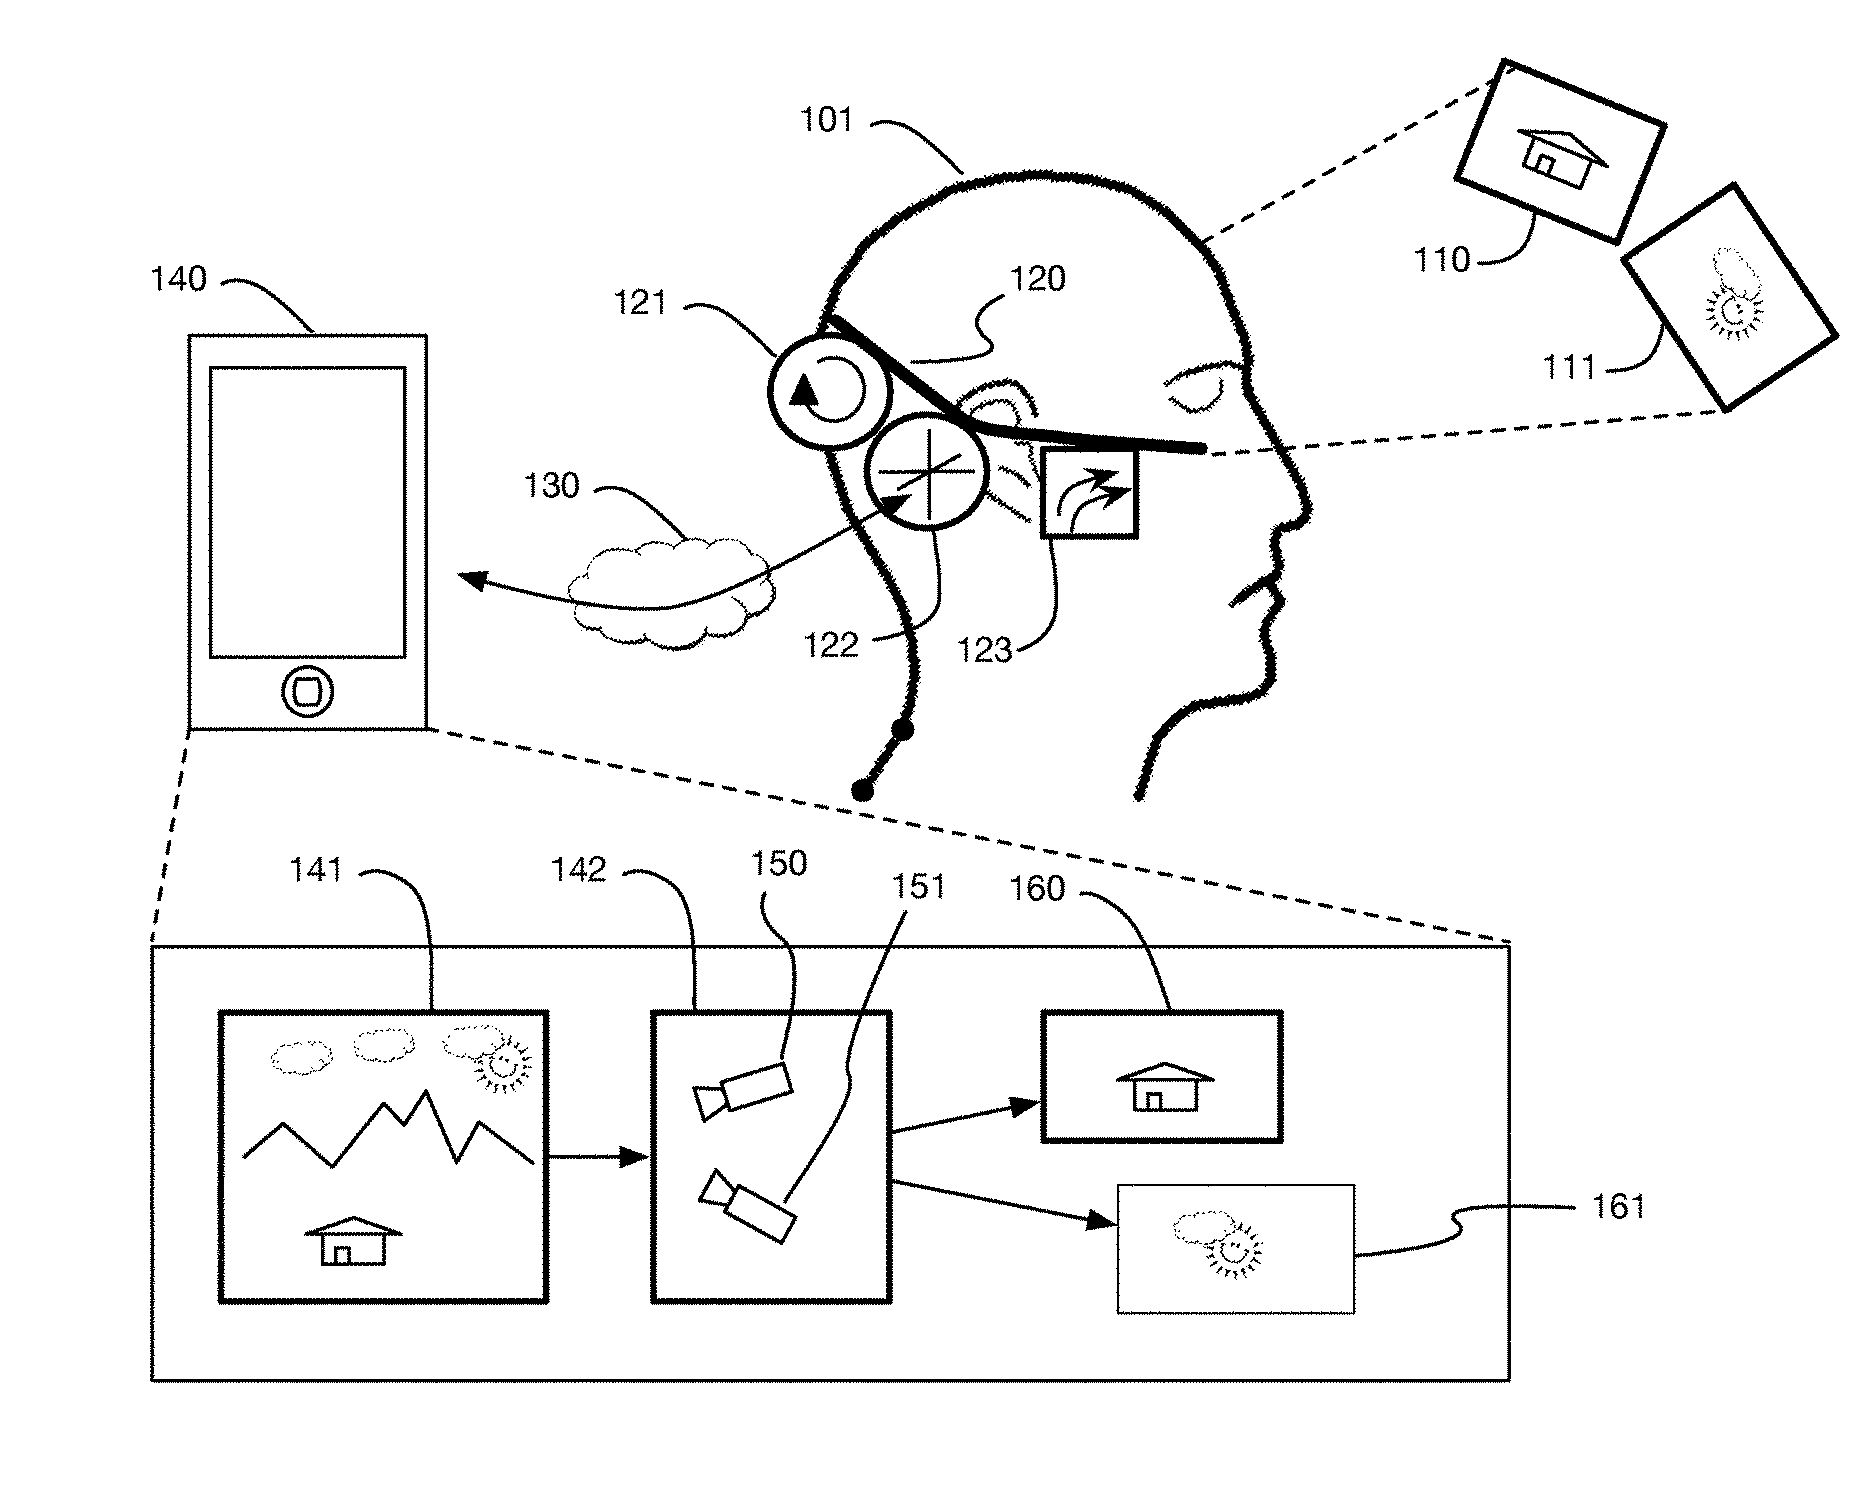
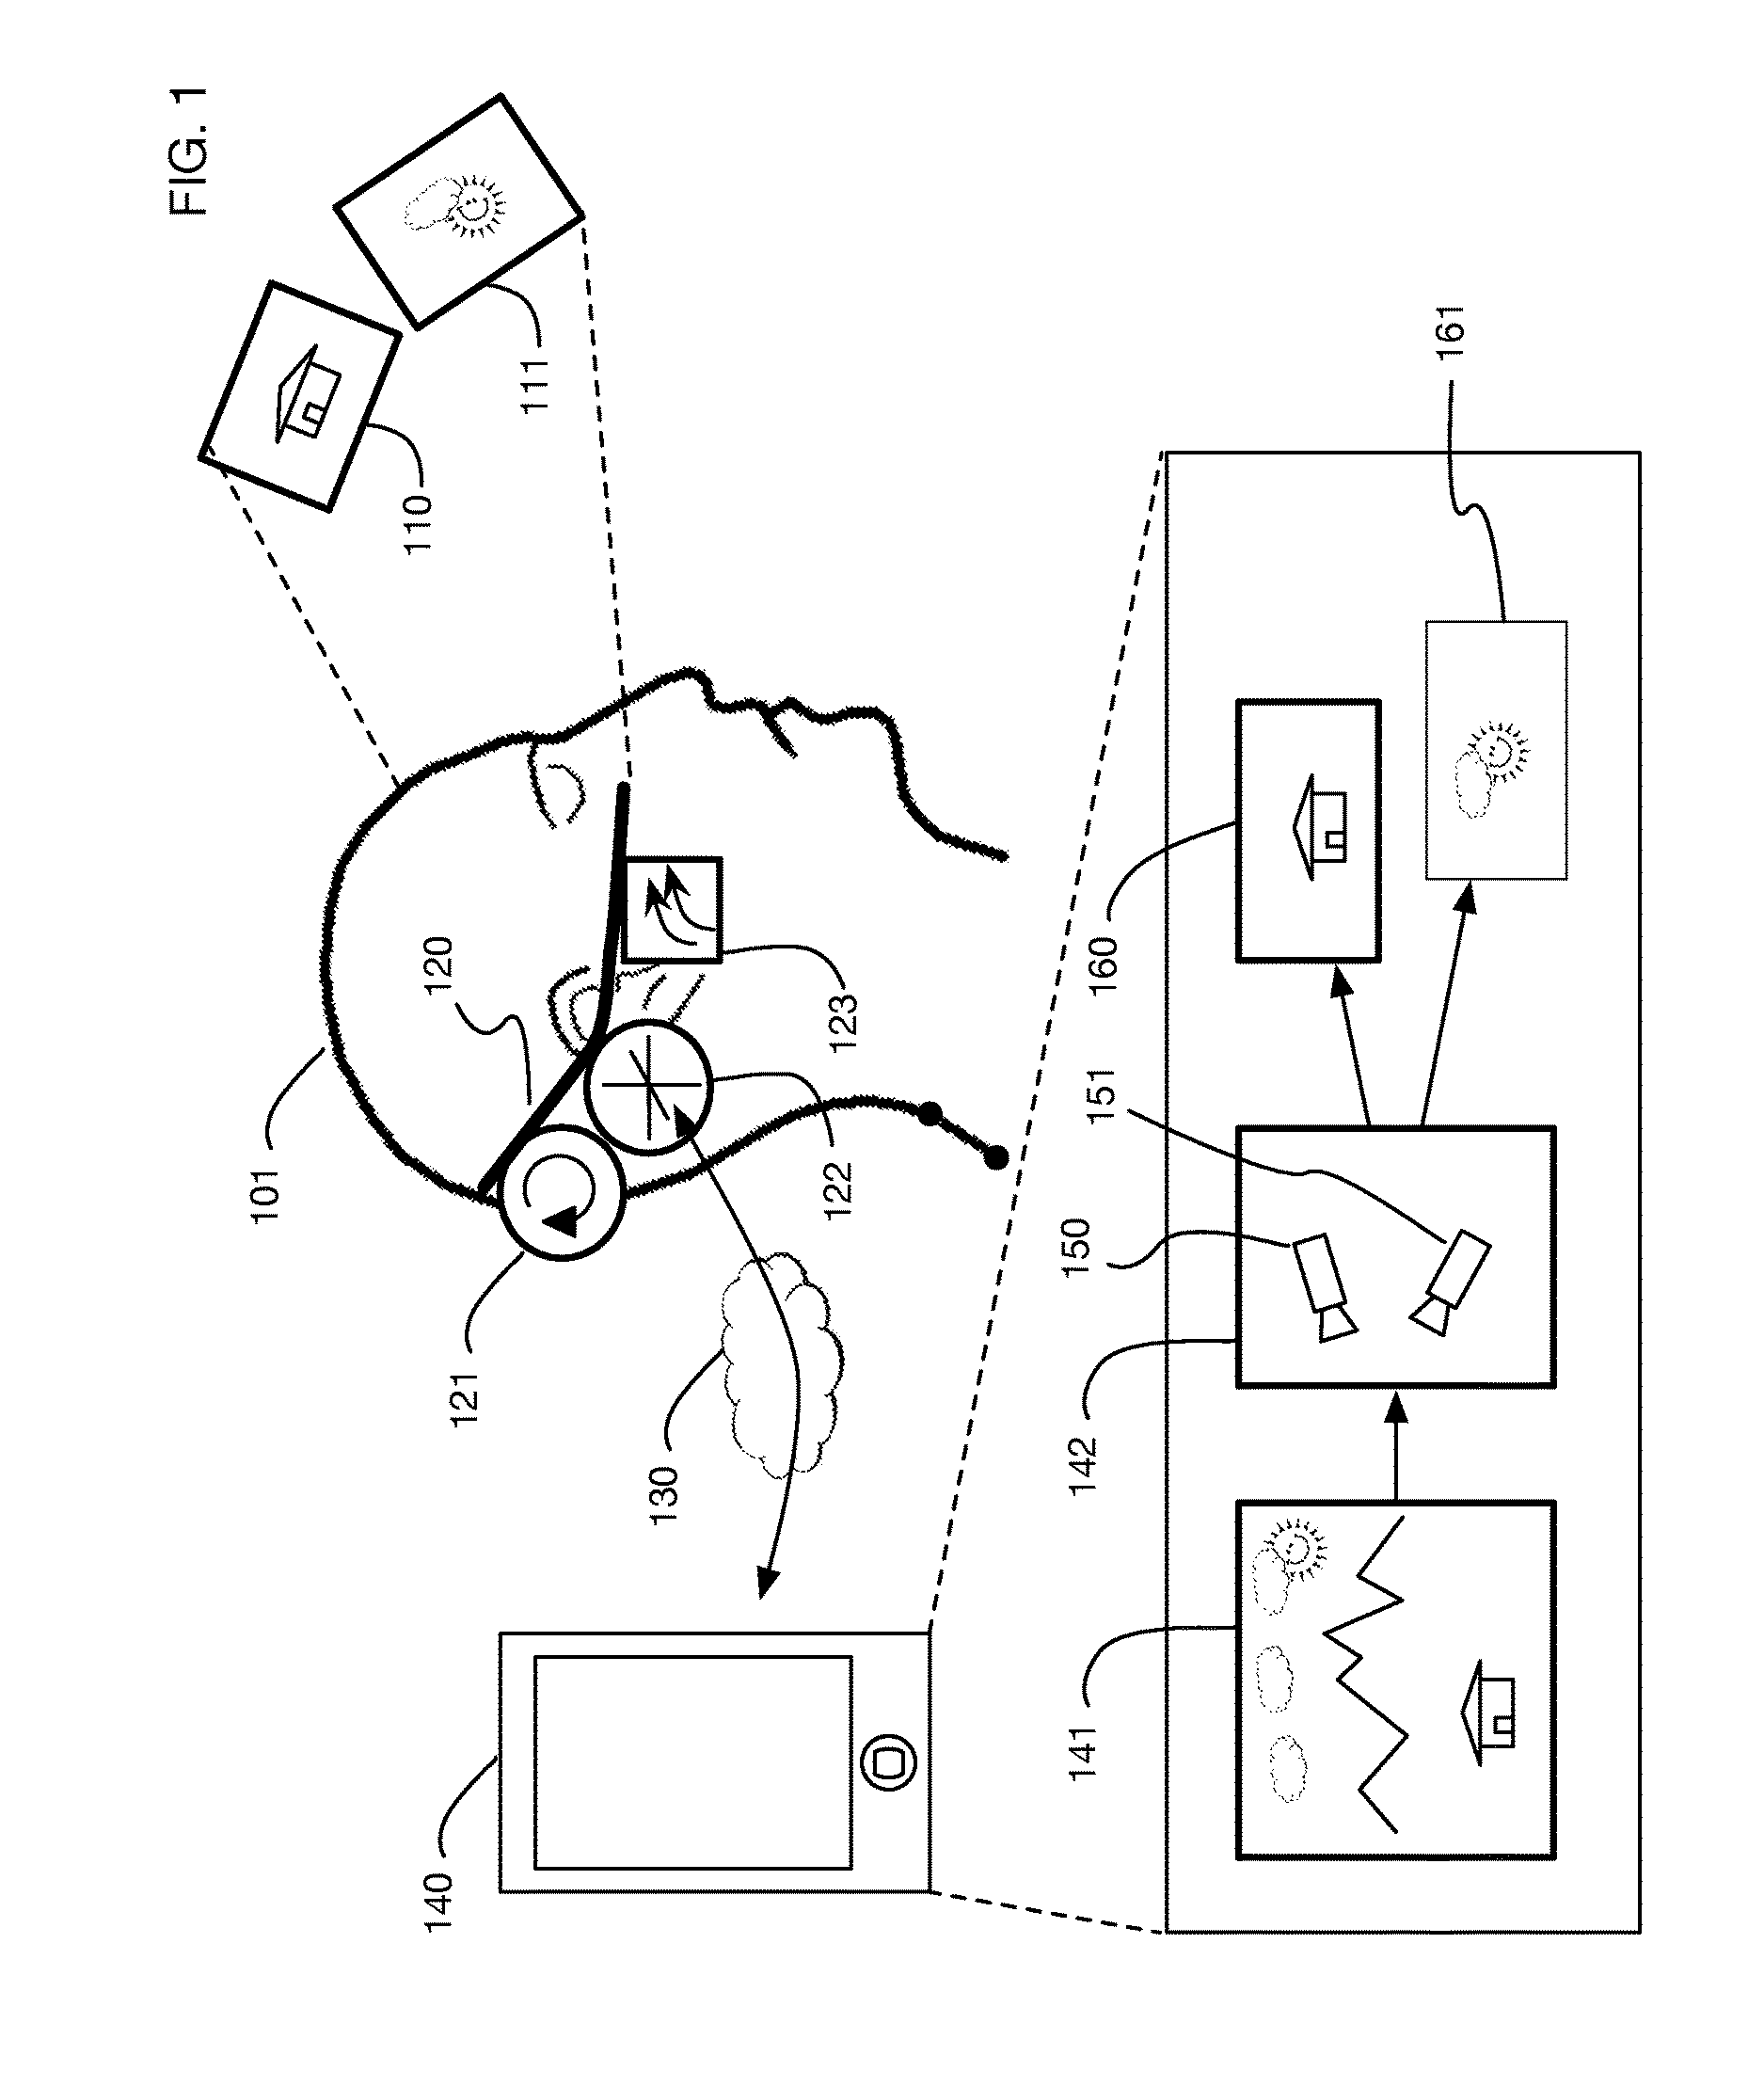
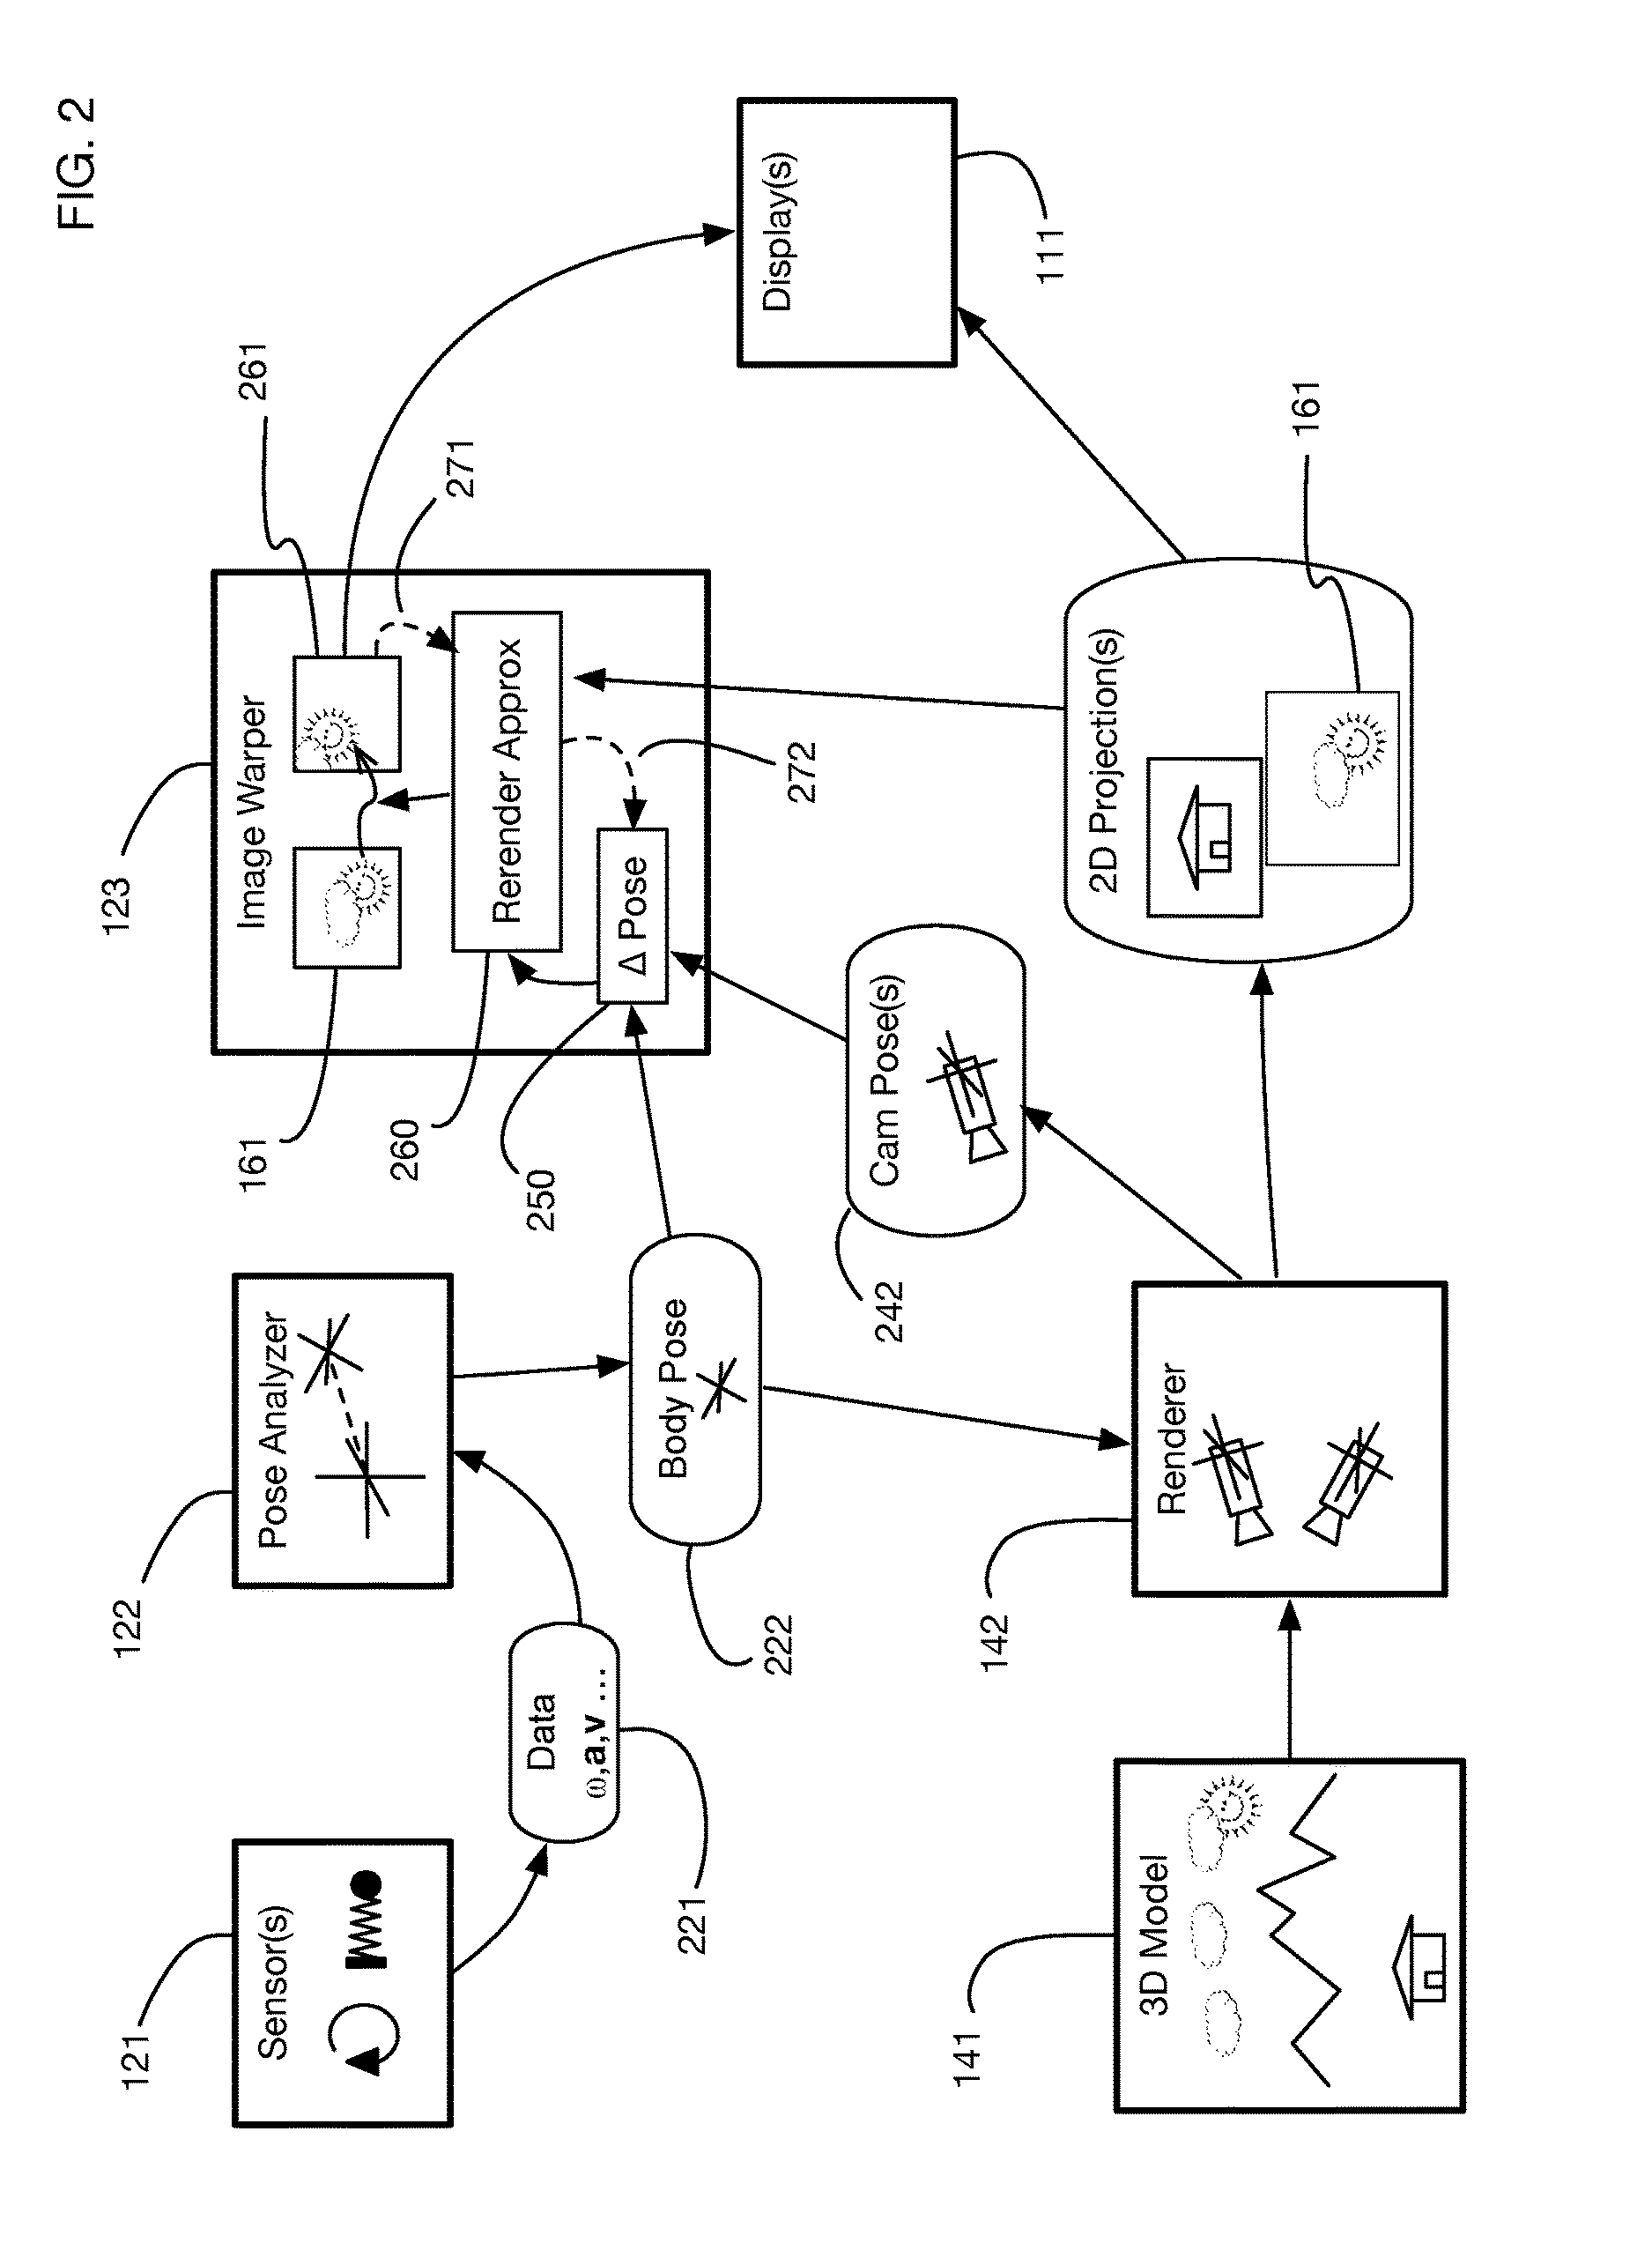
A virtual reality display system that generates display images in two phases: the first phase renders images based on a predicted pose at the time the display will be updated; the second phase re-predicts the pose using recent sensor data, and corrects the images based on changes since the initial prediction. The second phase may be delayed so that it occurs just in time for a display update cycle, to ensure that sensor data is as accurate as possible for the revised pose prediction. Pose prediction may extrapolate sensor data by integrating differential equations of motion. It may incorporate biomechanical models of the user, which may be learned by prompting the user to perform specific movements. Pose prediction may take into account a user's tendency to look towards regions of interest. Multiple parallel pose predictions may be made to reflect uncertainty in the user's movement.
Owner:LI ADAM
Stable motion tracking method and stable motion tracking device based on integration of simple camera and IMU (inertial measurement unit) of smart cellphone
InactiveCN105953796AFast and stable motion tracking methodStable motion tracking methodImage analysisNavigation by speed/acceleration measurementsThree-dimensional spaceAngular velocity
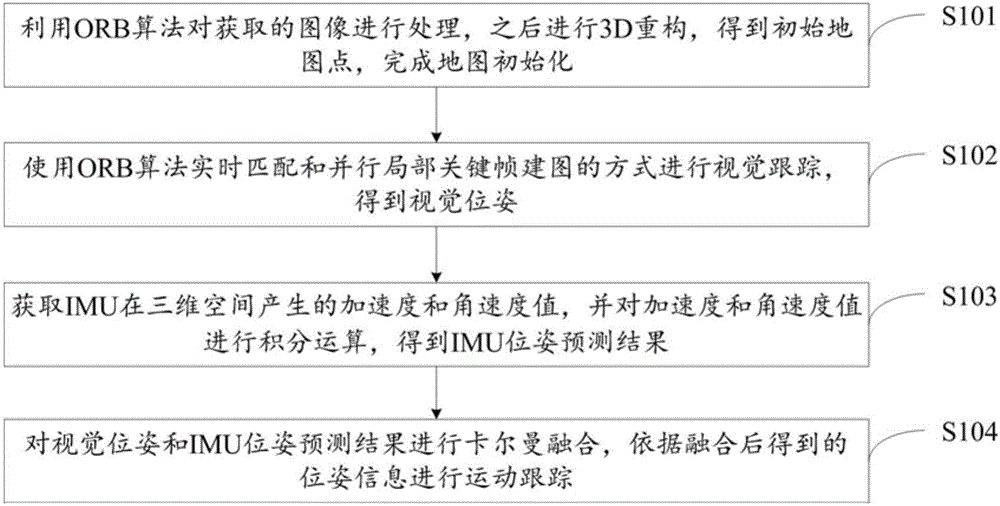
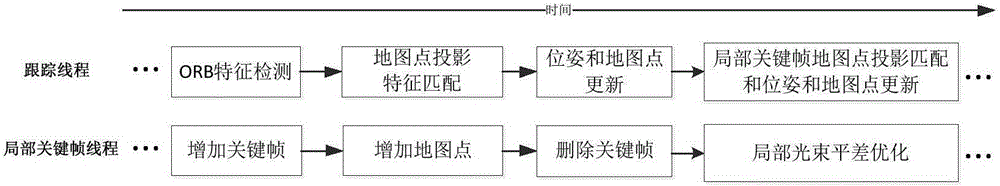
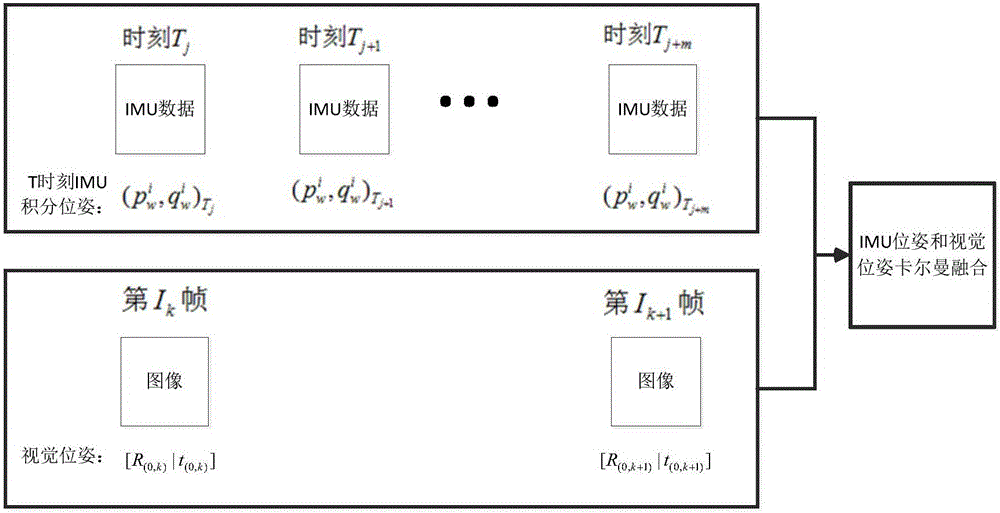
The invention discloses a stable motion tracking method and a stable motion tracking device based on integration of a simple camera and an IMU (inertial measurement unit) of a smart cellphone, and belongs to the technical field of AR (augmented reality) / VR (virtual reality) motion tracking. The method includes processing an acquired image according to an ORB (object request broker) algorithm, performing 3D (three-dimensional) reconstruction to obtain initial map points, and completing map initialization; performing visual tracking through ORB algorithm real-time matching and parallel partial keyframe mapping to obtain a visual pose; acquiring accelerated velocity and angular velocity, both generated in a three-dimensional space, of the IMU, and performing integral operation on the accelerated velocity and the angular velocity to obtain an IMU pose prediction result; performing Kalman fusion on the visual pose and the IMU pose prediction result, and performing motion tracking according to pose information acquired after fusion. Compared with the prior art, the stable motion tracking method and the stable motion tracking device have the advantages that a stable motion tracking mode can be acquired and real-time online dimension estimation can be achieved.
Owner:北京暴风魔镜科技有限公司
Method for instant positioning and map building based on fusion of laser and two-dimensional code
ActiveCN109211251AImprove robustnessHigh precisionInstruments for road network navigationSimultaneous localization and mappingInformation processing
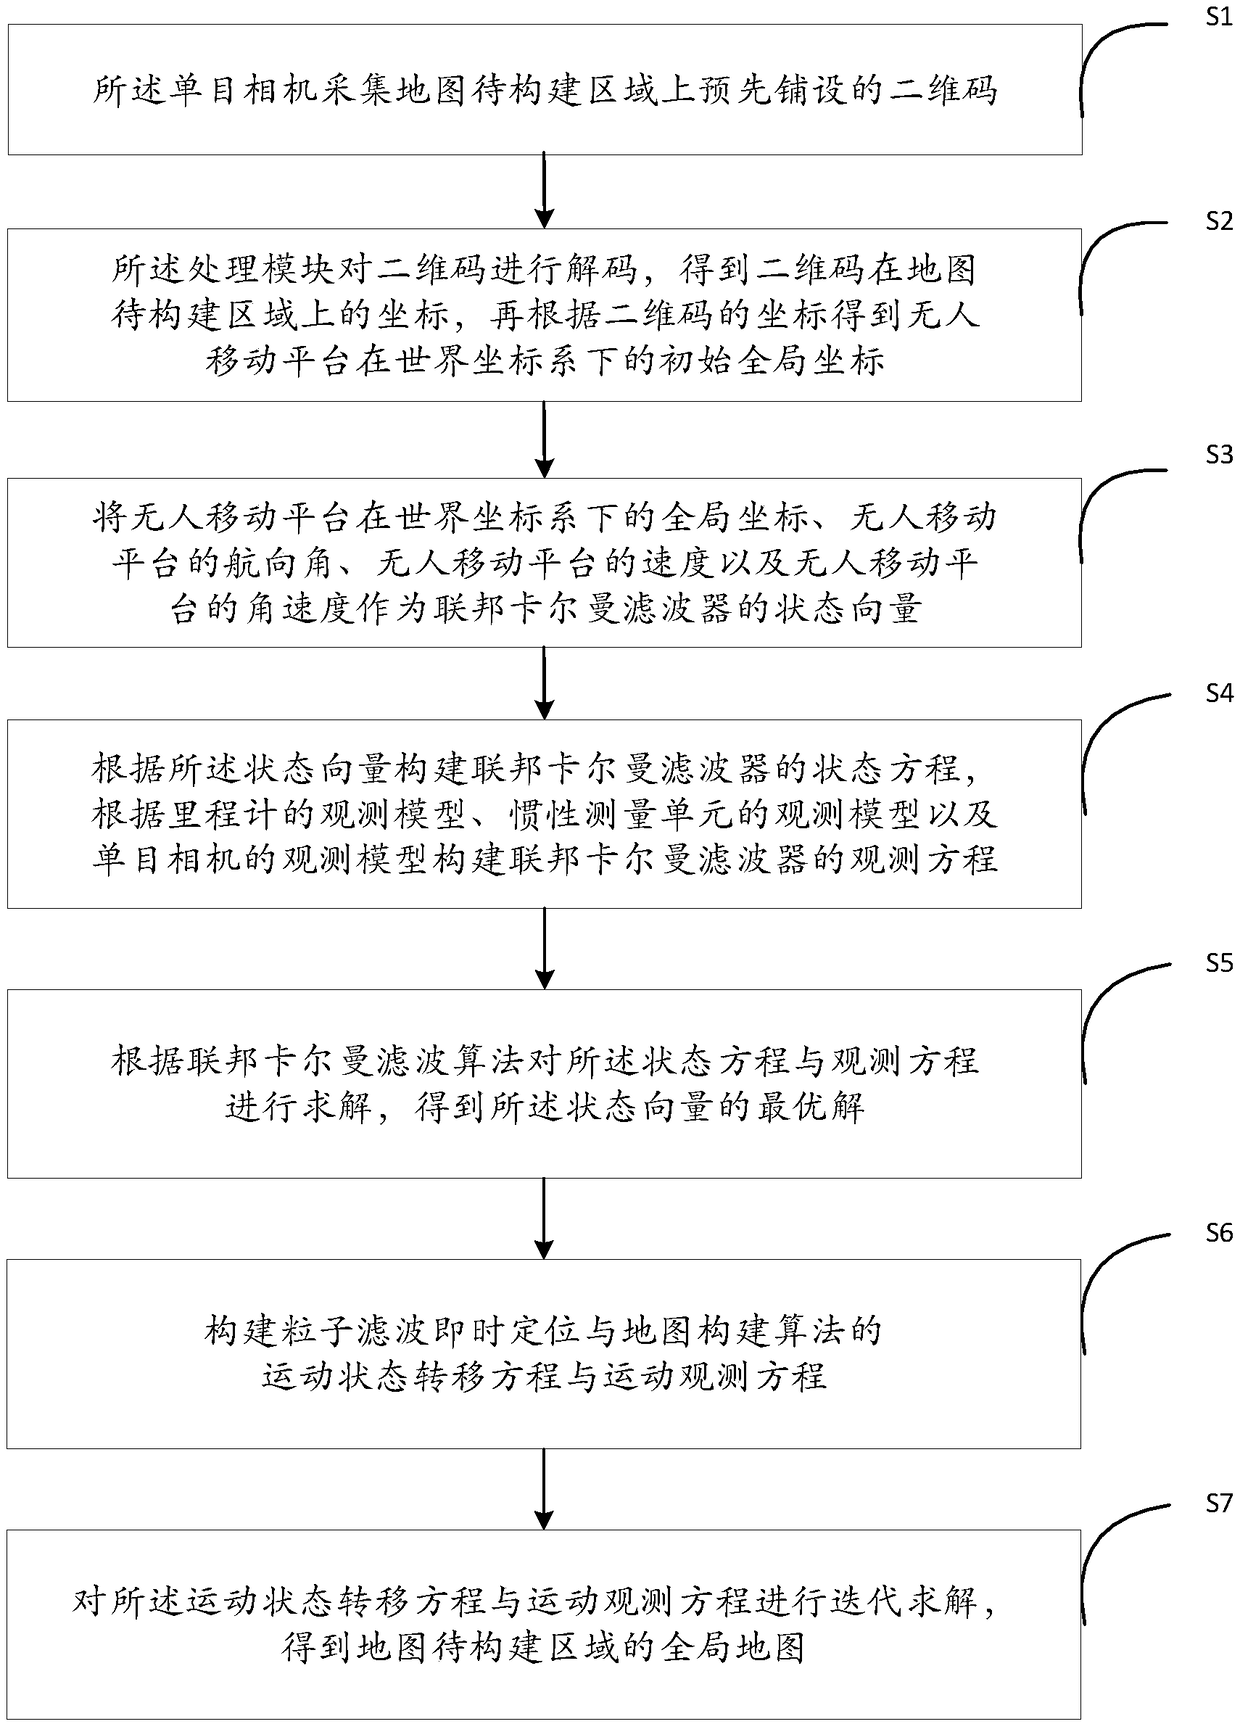
The invention provides a method for the instant positioning and the map building based on the fusion of a laser and a two-dimensional code. The driving distance and the speed information of an odometer, a two-dimensional code acquired by a monocular camera, and the information of an inertial measurement unit are integrated into a state vector. An observation equation of the federated Kalman filteris constructed according to an observation model of the odometer, an observation model of the inertial measurement unit, and an observation model of the monocular camera. The two-dimensional code positioning information is added on the basis of a traditional odometer and the inertial measurement unit, thereby obtaining the optimal solution of the state vector of an unmanned mobile platform; the pose prediction information with higher accuracy is formed by using the characteristics of the fastness and the accuracy of the two-dimensional code information processing, thereby reducing the numberof particles in the method for particle filter instant positioning and map building, and improving the low-power processor, such as the positioning accuracy of the unmanned mobile platform. The positioning effect of the unmanned mobile platform in the complex environment is ensured, map building is completed, and the application need in the complex environment is met.
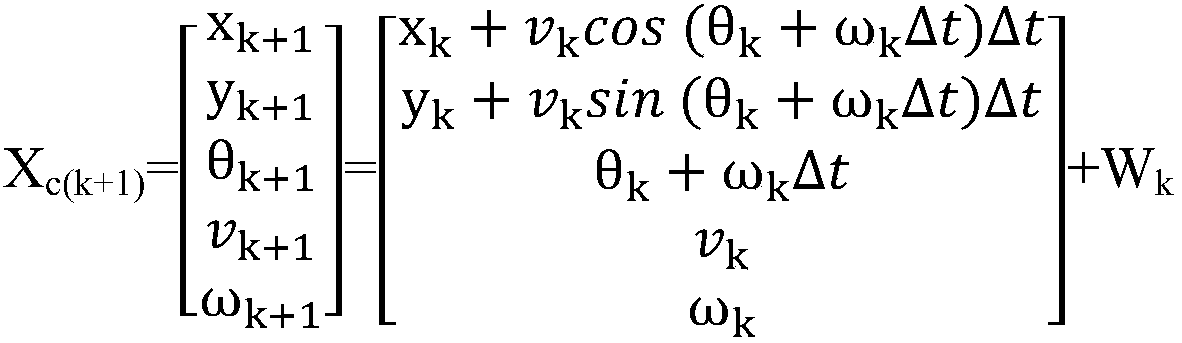
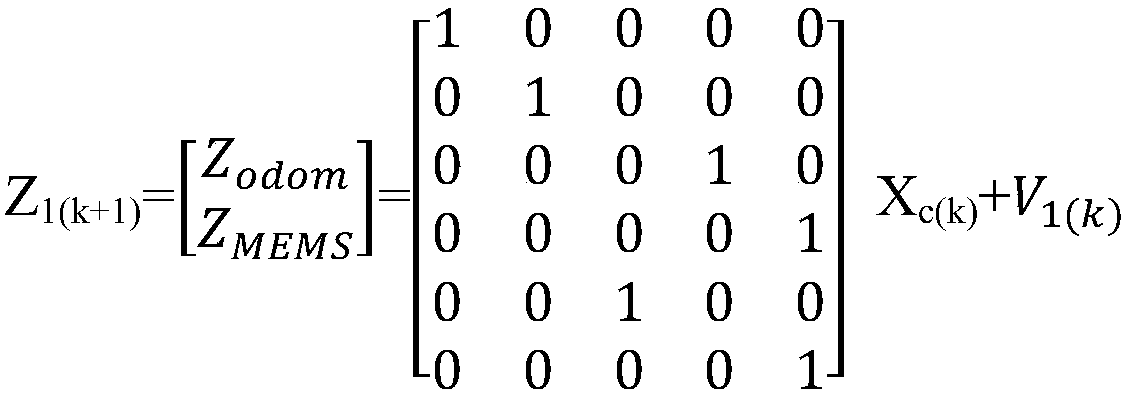
Owner:BEIJING INSTITUTE OF TECHNOLOGYGY
Positioning method and device
ActiveCN109887033AImprove robustnessImprove practicalityImage analysisCharacter and pattern recognitionFeature extractionPose prediction
The invention provides a positioning method. The positioning method comprises the steps of obtaining image information of a parking lot; acquiring attitude information measured by the IMU; processingthe image information to obtain lane line information and two-dimensional code information; determining path track information of the vehicle in a coordinate system of the vehicle; determining firstpose information according to the two-dimensional code information and a preset first map; Performing feature extraction on the image information, matching the extracted feature information with a second map, and determining second pose information; calculating third pose information according to the path track information under the vehicle coordinate system and the path track information under the vehicle coordinate system obtained based on global pose prediction; and fusing the first pose information, the second pose information, the third pose information and the pose information to obtaintarget pose information of the vehicle. Therefore, the robustness and practicability of positioning are greatly improved.


Owner:BEIJING ZHIXINGZHE TECH CO LTD
Posture determination method, tray loading method and device, medium and electronic equipment
ActiveCN109829947AImprove robustnessBroad universal applicabilityImage analysisPhotogrammetry/videogrammetryObject basedPose prediction
The invention relates to the technical field of computers, in particular to a pose determination method, a tray loading method, a pose determination device, a tray loading device, a computer readablestorage medium and electronic equipment. The pose determination method provided by the embodiment of the invention comprises the following steps: acquiring an image containing a target object throughimage acquisition equipment; determining a plurality of feature points of the target object based on the image, and obtaining pixel coordinates of each feature point in the image; inputting the pixelcoordinates into a pre-trained neural network to obtain depth information of each feature point and rotation angle information of the target object; and determining pose information of the target object relative to the image acquisition device according to the depth information and the rotation angle information. According to the pose determination method provided by the embodiment of the invention, the robustness and universality of pose prediction can be improved.


Owner:BEIJING KUANGSHI TECH
Localisation and mapping
ActiveUS20150187133A1Improved localisationImproved mappingDetails involving processing stepsImage enhancementPose predictionKey frame
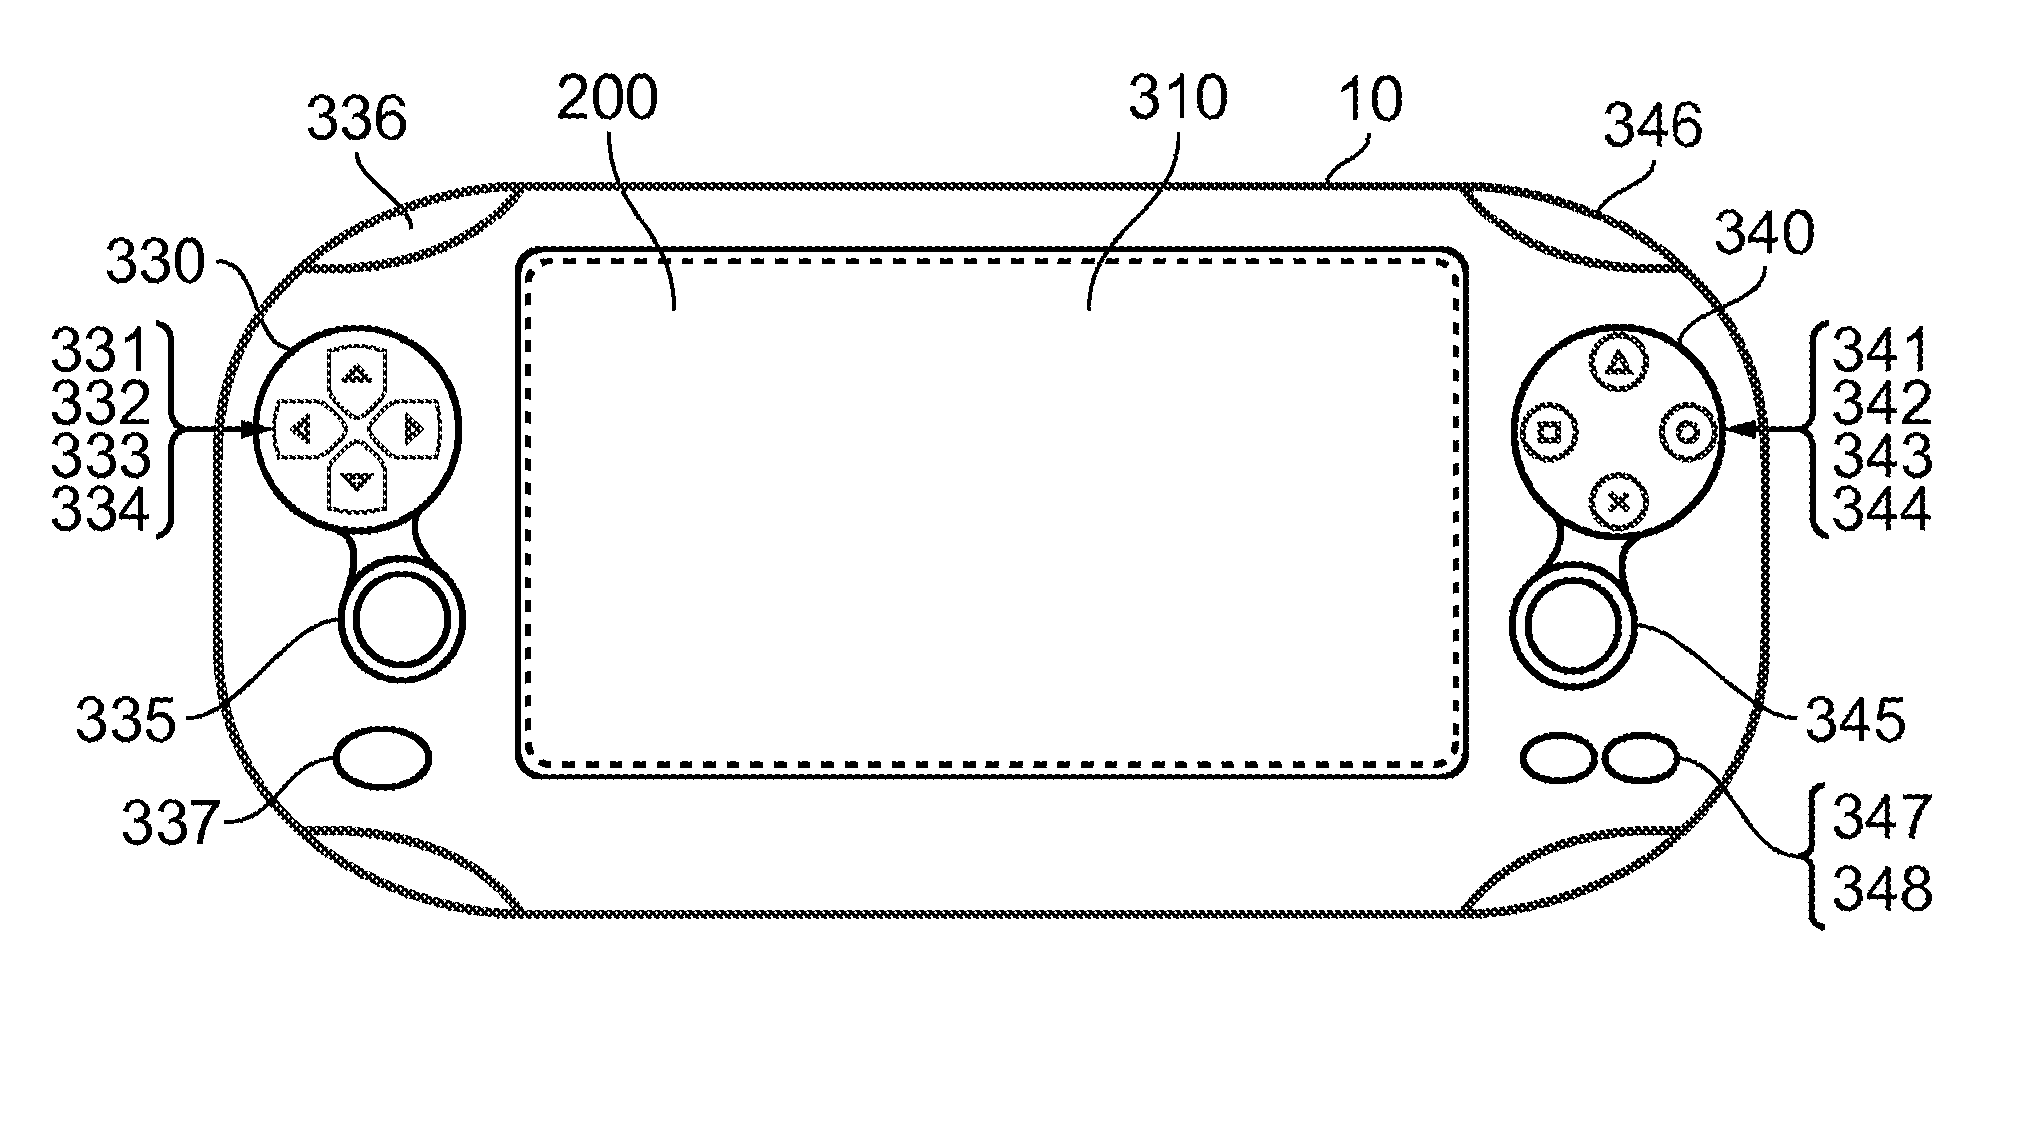
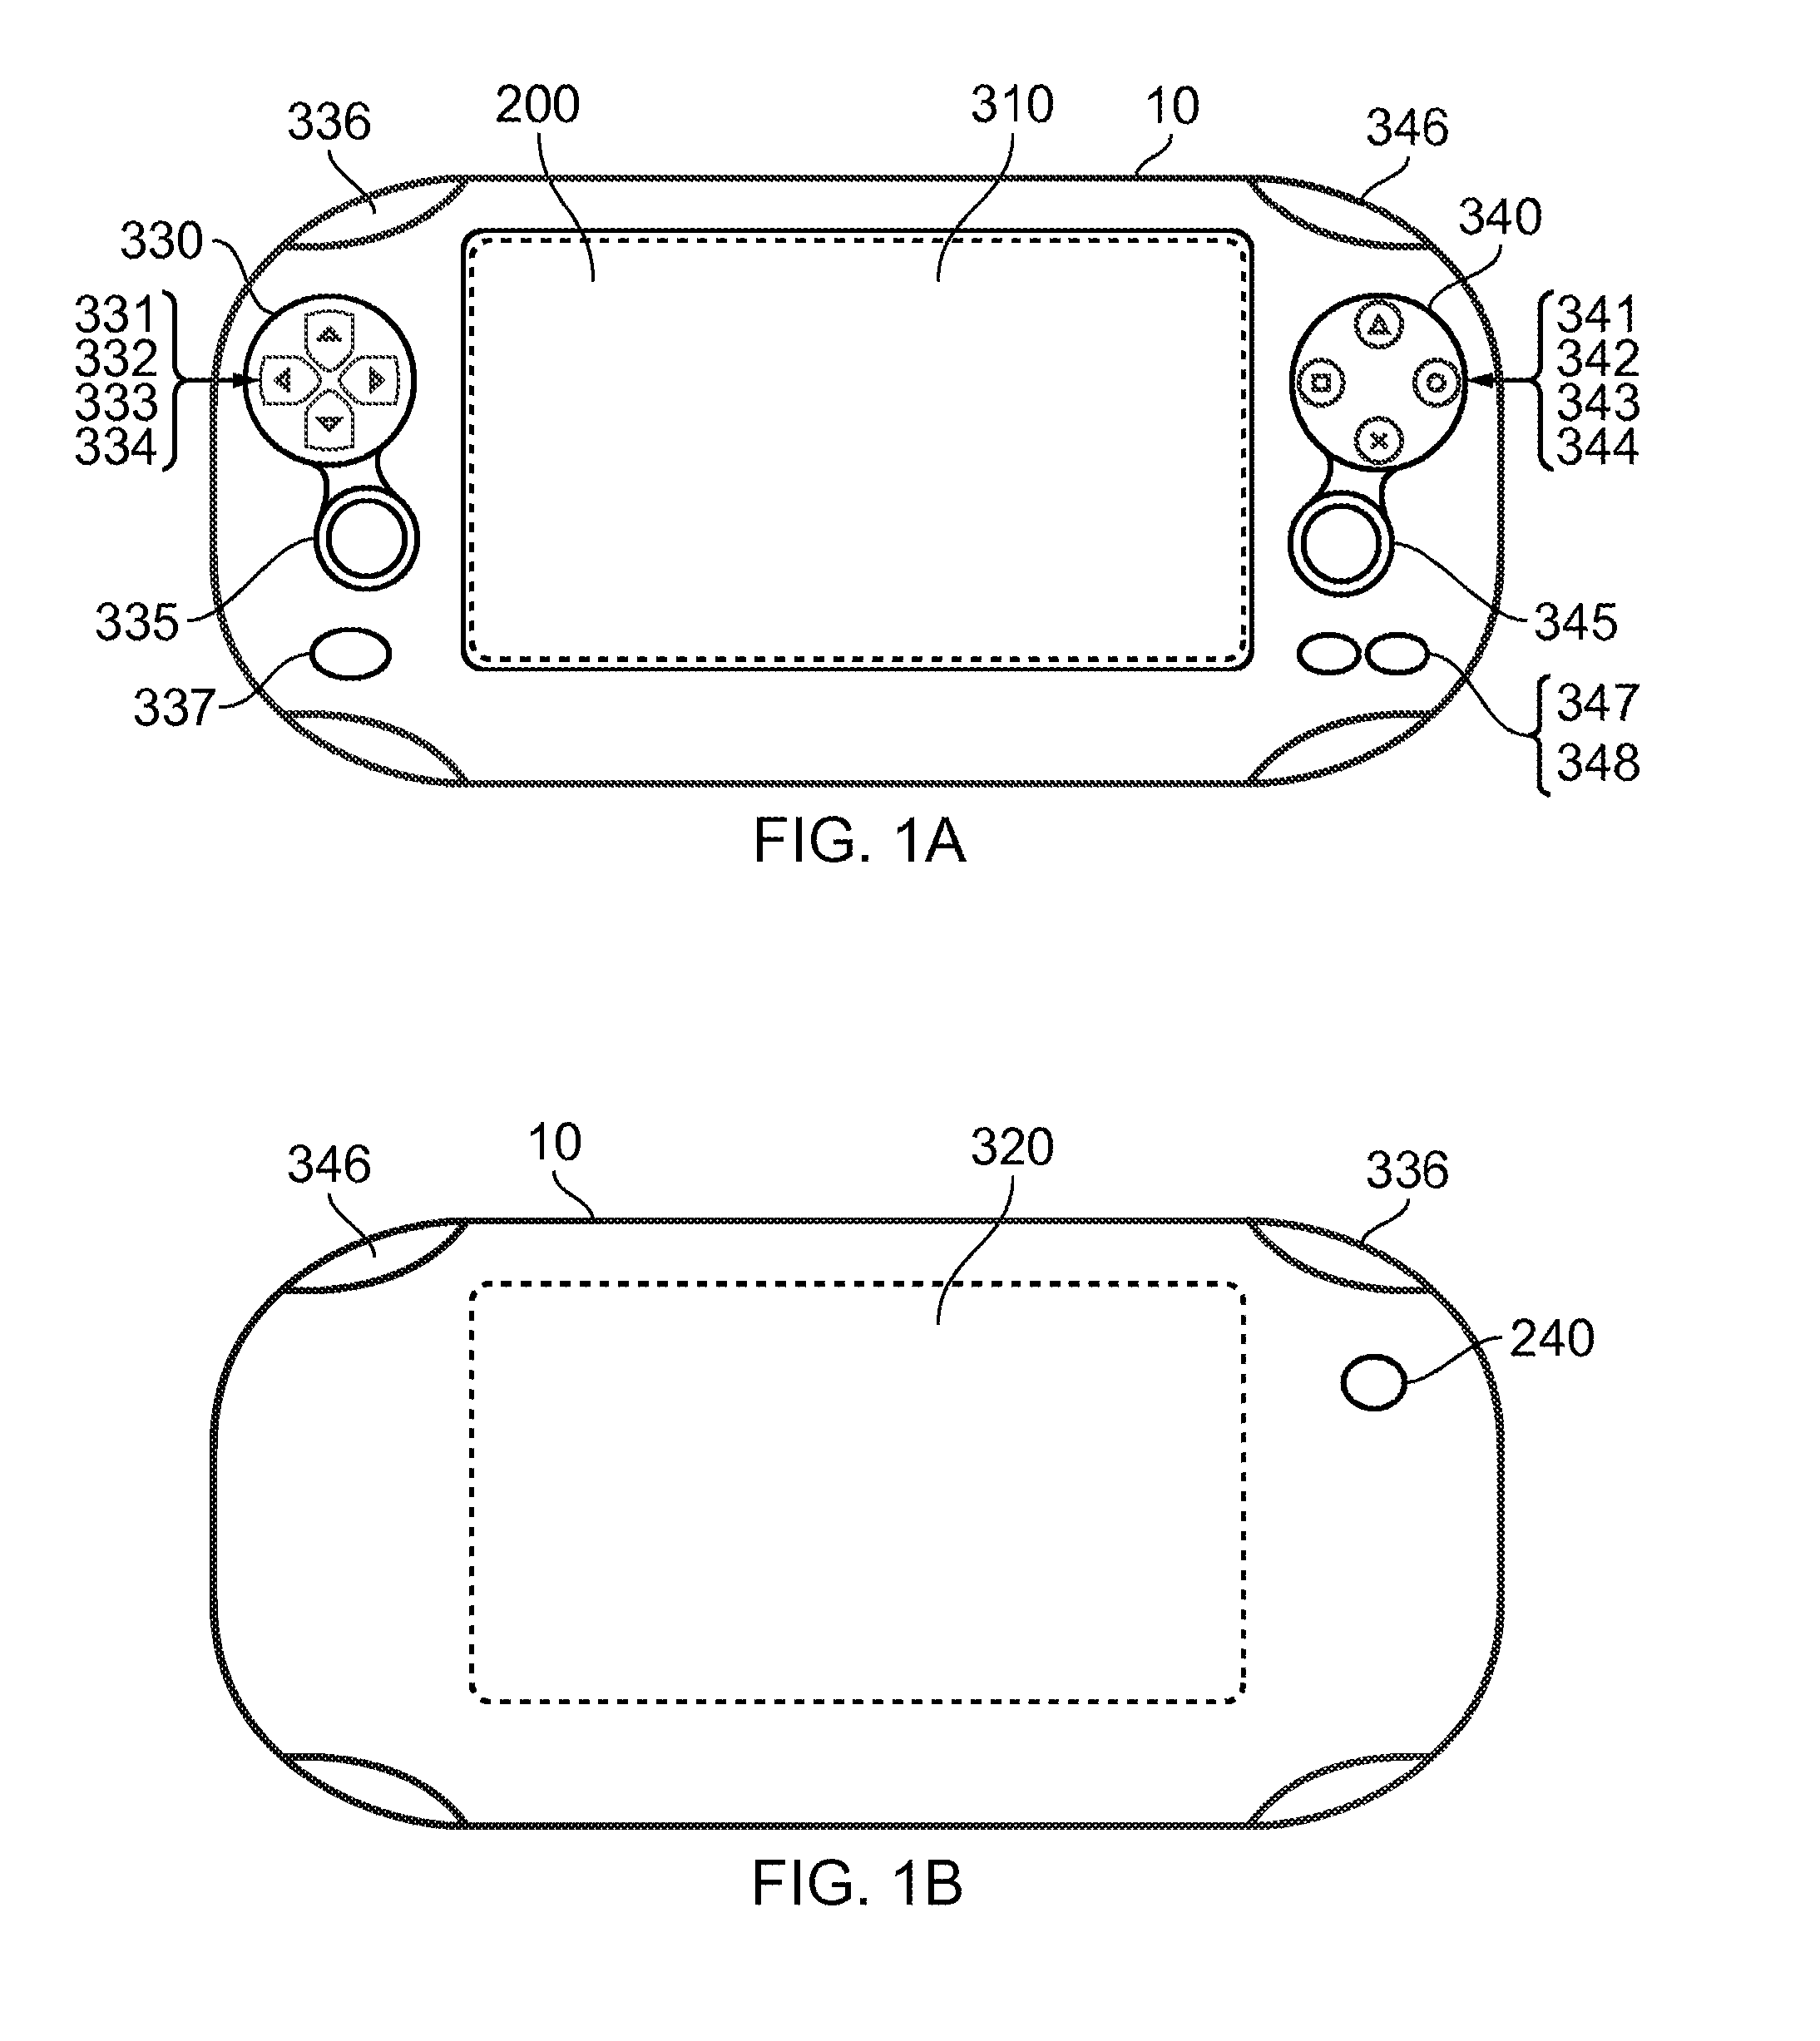
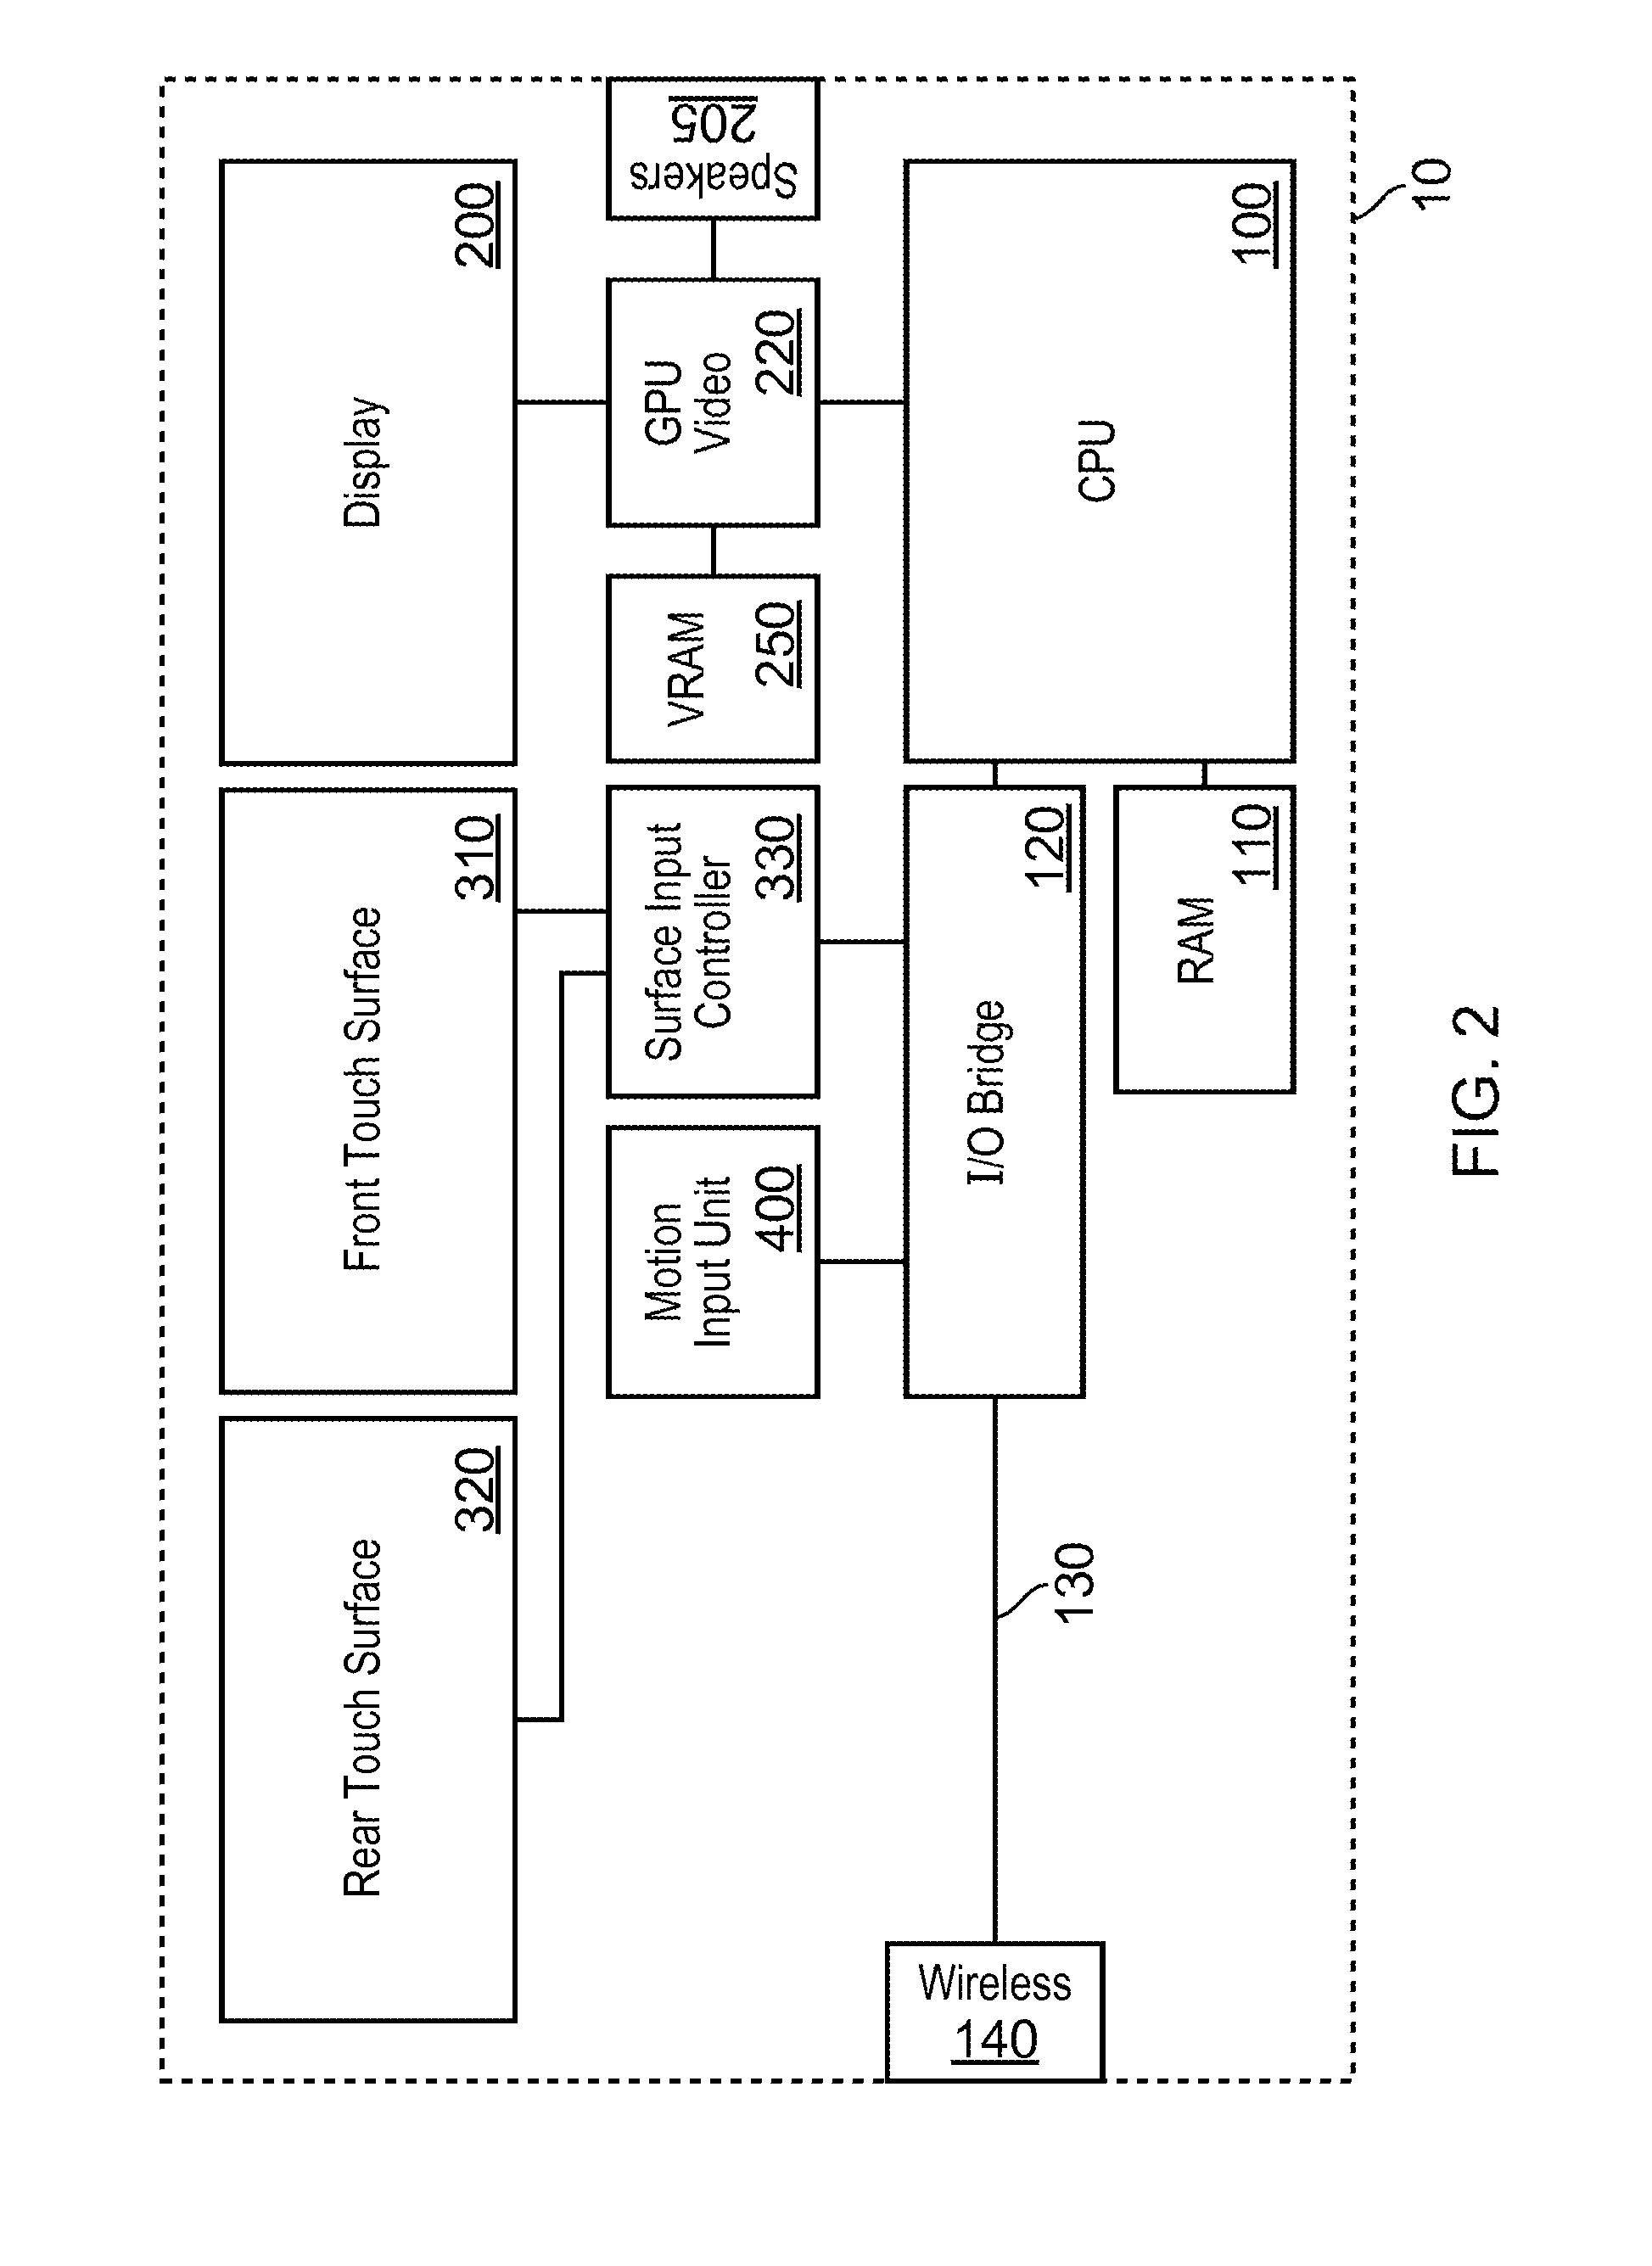
A method generates a three-dimensional map of a region from successive images captured from different camera poses. The method includes a camera capturing images of the region; designating a subset of captured images as a set of keyframes each having respective sets of image position data representing image positions of landmark points detected as feature points in that image; for a newly captured image, generating a camera pose prediction; selecting an ordering of the landmark points; detecting whether an image region of the new image approximately matches an expected image position of a landmark point based on the predicted camera pose by detecting whether the image region is substantially identical to the image information associated with that landmark point; and refining the pose prediction from the detecting step. The selecting includes performing a statistical test on the landmark points and selecting the ordering according to the statistical test results.
Owner:SONY COMP ENTERTAINMENT EURO
Predictive virtual reality display system with post rendering correction
ActiveUS10089790B2Enhance the virtual reality experienceEffectively approximatesInput/output for user-computer interactionGeometric image transformationComputer graphics (images)Biomechanical model
A virtual reality display system that generates display images in two phases: the first phase renders images based on a predicted pose at the time the display will be updated; the second phase re-predicts the pose using recent sensor data, and corrects the images based on changes since the initial prediction. The second phase may be delayed so that it occurs just in time for a display update cycle, to ensure that sensor data is as accurate as possible for the revised pose prediction. Pose prediction may extrapolate sensor data by integrating differential equations of motion. It may incorporate biomechanical models of the user, which may be learned by prompting the user to perform specific movements. Pose prediction may take into account a user's tendency to look towards regions of interest. Multiple parallel pose predictions may be made to reflect uncertainty in the user's movement.


Owner:LI ADAM
Mobile robot positioning method based on occupancy grid map and combined with imu
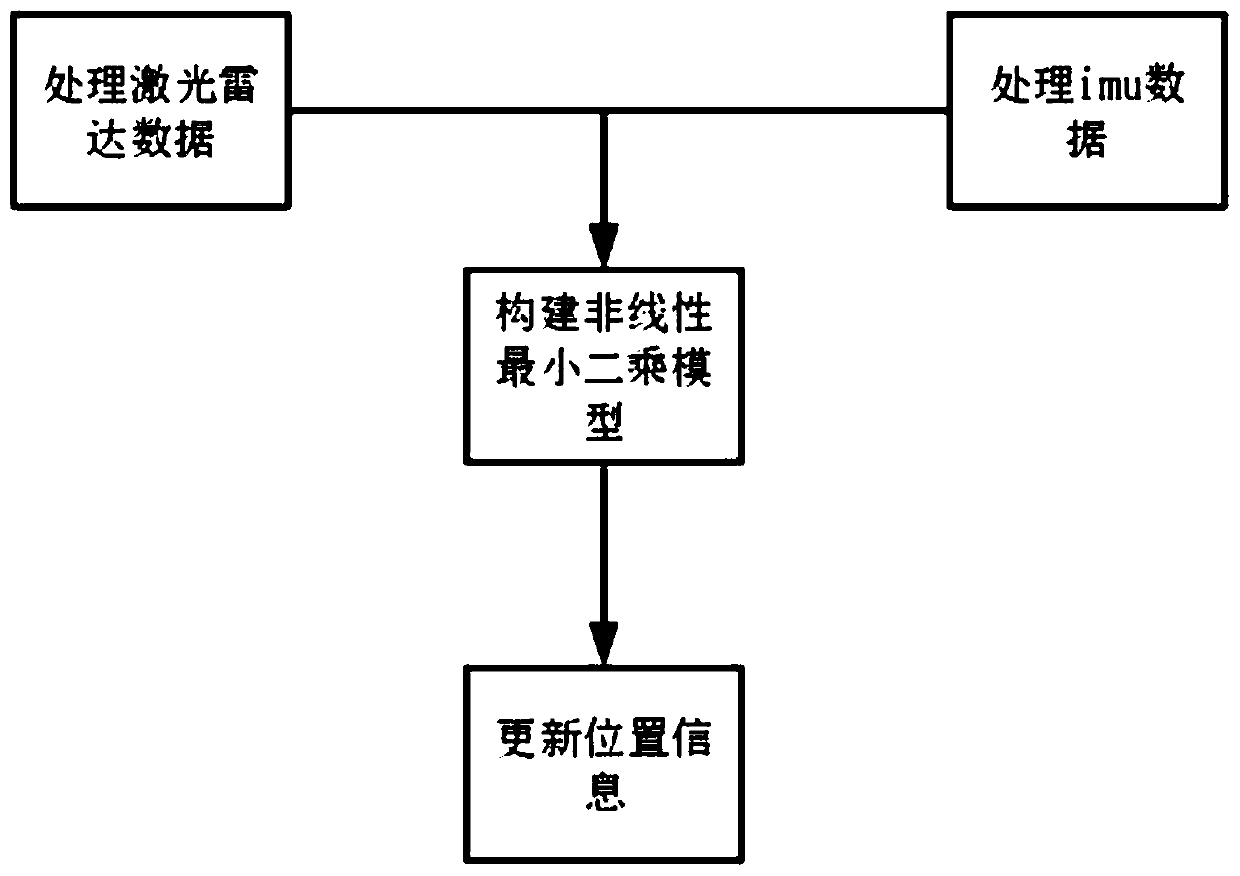
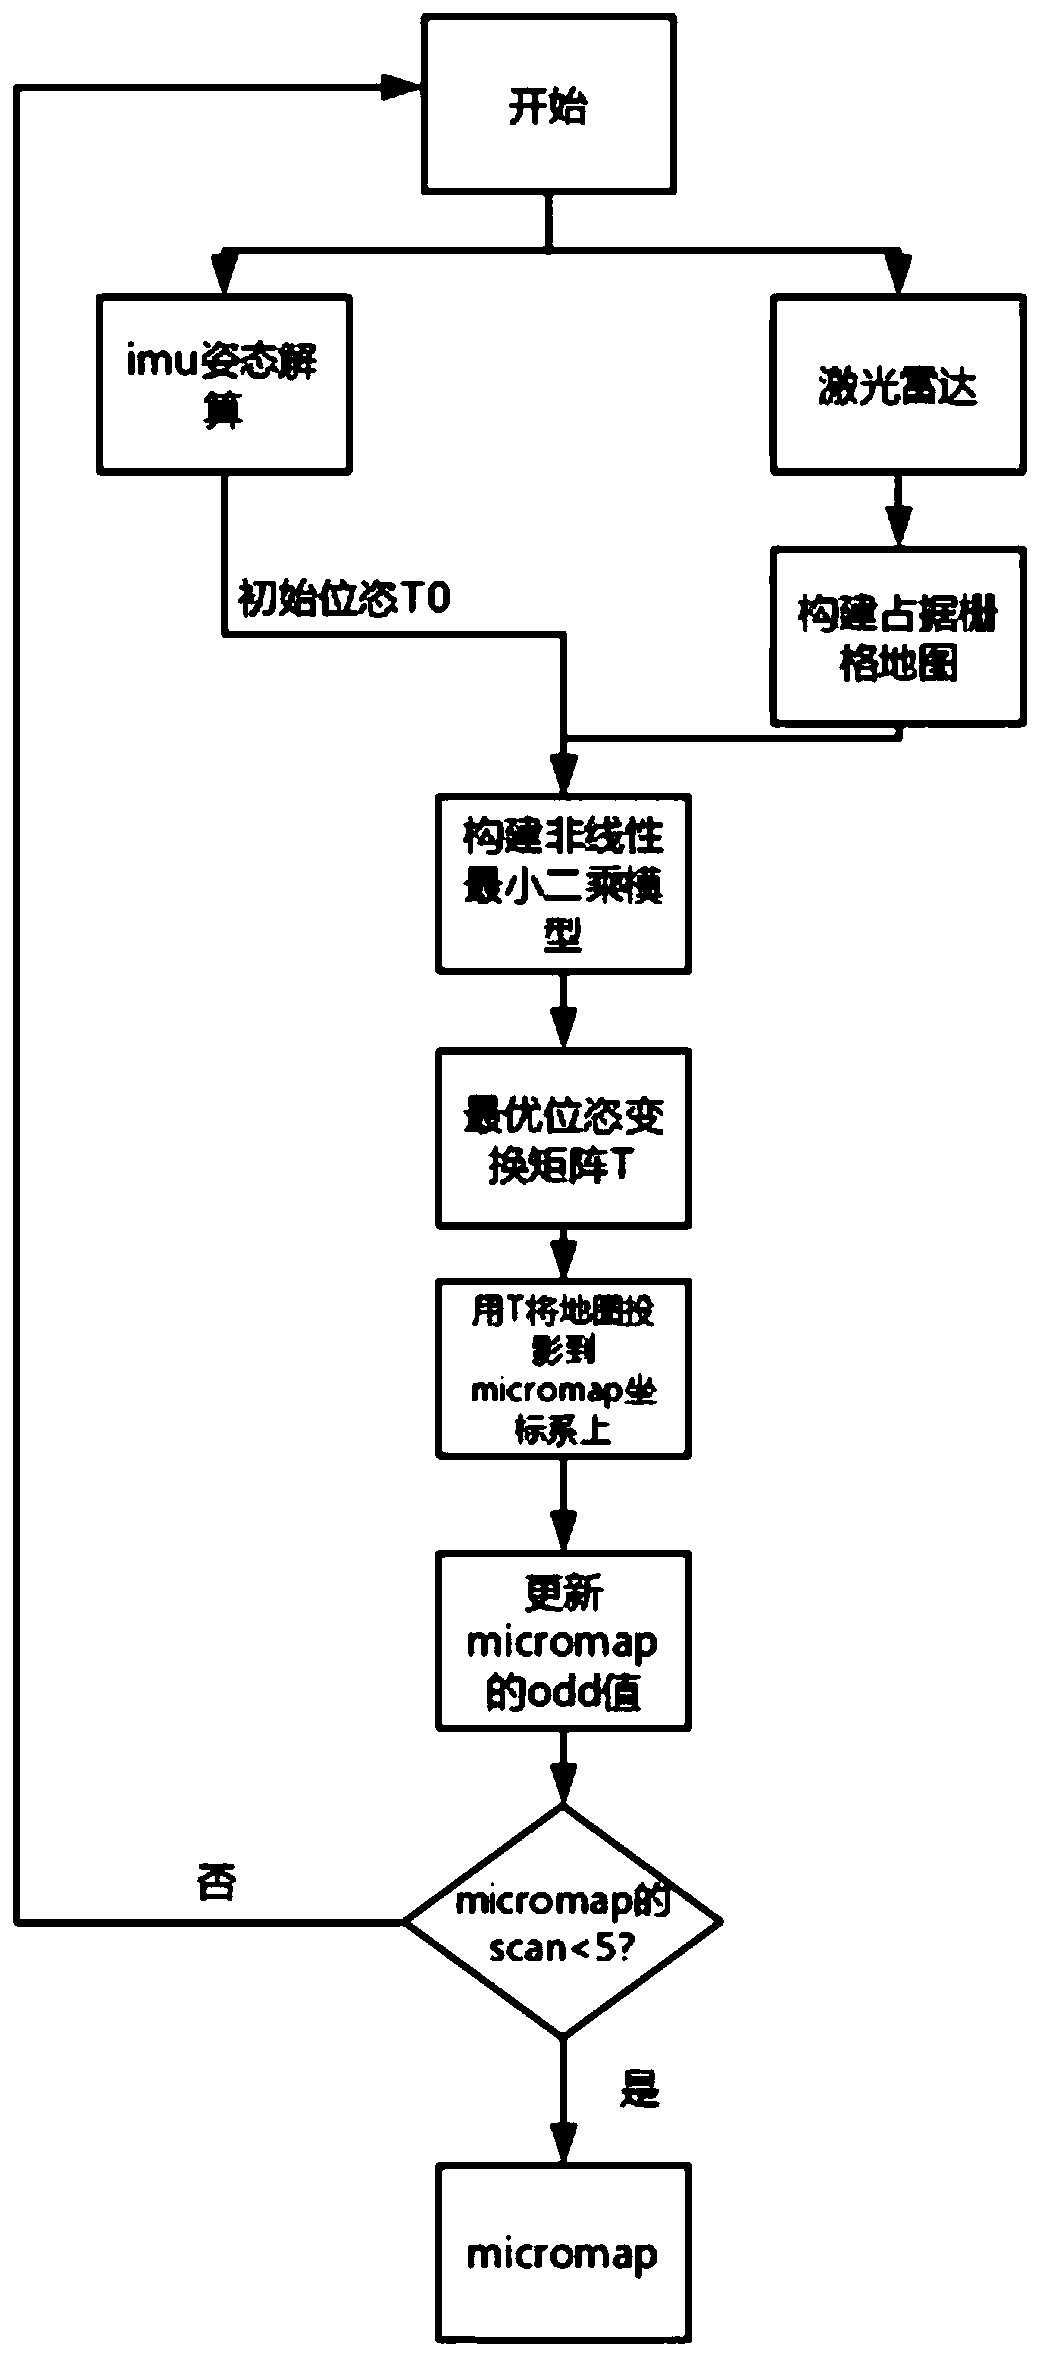
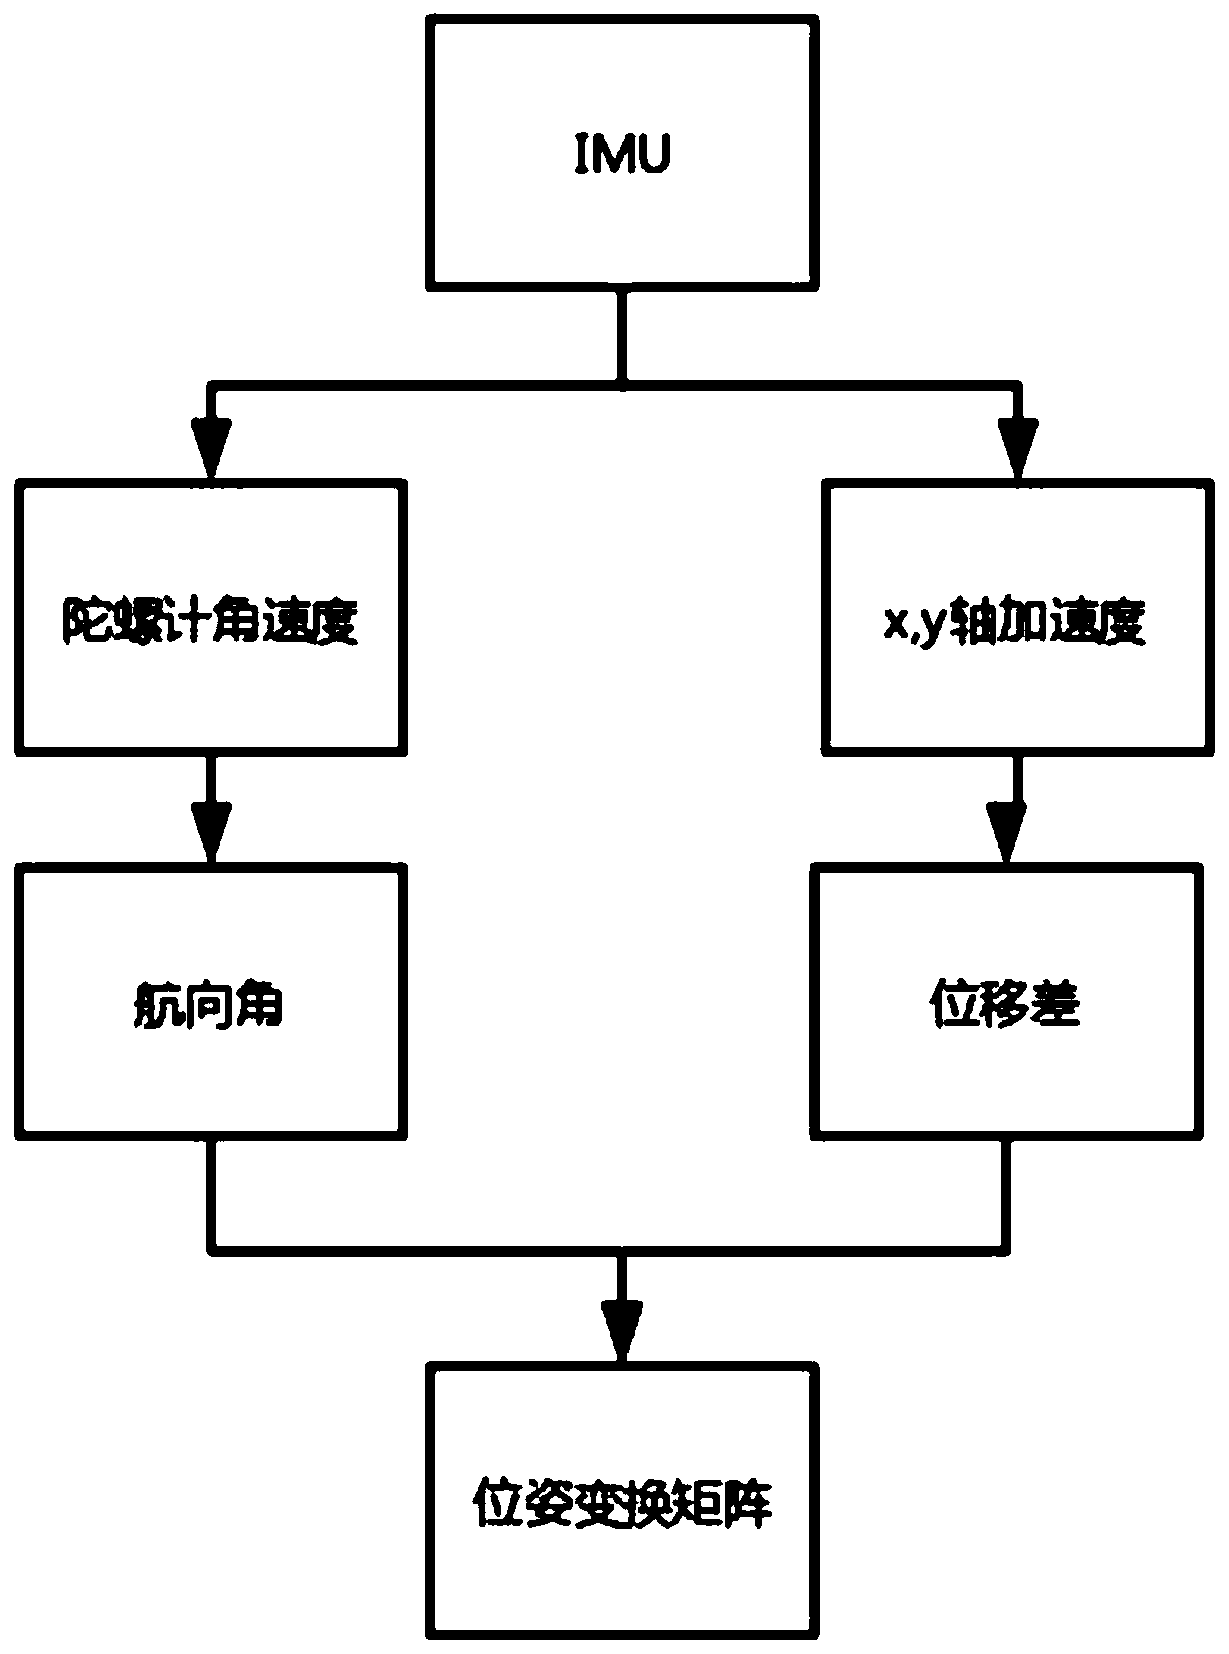
ActiveCN110361010AEliminate the effects ofImprove robustnessNavigational calculation instrumentsNavigation by speed/acceleration measurementsFeature extractionPose prediction
Owner:SUN YAT SEN UNIV
A monocular vision mileage prediction method based on semi-supervised learning and a mileage meter
InactiveCN108986166AImprove estimation accuracyImage analysisForecastingView synthesisPose prediction
The invention discloses a monocular vision mileage prediction method based on semi-supervised learning and a mileage meter. The prediction method comprises the following steps: the models of a deep estimation network and the pose estimation network are set in advance and the deep estimation network and the pose estimation network are set in parallel to construct a prediction network model; the parallel deep estimation network and pose estimation network are coupled by the view synthesis method, and the sparse deep map obtained from sparse sampling monocular image is used as the supervisory signal of deep estimation, so that the deep estimation network and pose estimation network are trained jointly; the monocular image of the current frame is input into the trained deep estimation network,and a deep prediction value corresponding to the monocular image of the current frame is output; inputting the current frame monocular image and its two adjacent frames monocular image to the trainedpose estimation network, and the camera pose prediction value corresponding to the current frame monocular image is output. The method can simultaneously estimate the scaled depth of monocular imageand camera pose.


Owner:SHANDONG UNIV
Indoor navigation method based on connection of multiple 3D (three dimensional)-structure optical cameras
InactiveCN107091643AAchieve positioningData error is smallNavigational calculation instrumentsPosition/course control in two dimensionsFeature extractionRadar
The invention discloses an indoor navigation method based on connection of multiple 3D (three dimensional)-structure optical cameras. The indoor navigation method comprises the following steps: expressing a map by using a grid map manner, setting an initial map as null, setting an initial pose of a robot as an origin of a global coordinate system, calculating robot pose prediction quantity according to odometer data through a robot motion model in a process of building the map, simultaneously extracting observation quantity from continuously-updated sensor data by using a feature extraction technology, and calculating the robot pose prediction quantity and a visual global map through a designed observation model to obtain the observation prediction quantity. According to the indoor navigation method based on the connection of the multiple 3D-structure optical cameras, a method for simulating a laser radar by connecting the multiple 3D-structure optical cameras is adopted; the pose estimation is carried out by multiple filtering algorithms based on probability; the robot is positioned and navigated; the data is collected by the 3D-structure optical cameras, so that the method is difficultly influenced by the environment; the method is low in data error, has the advantage of low cost and can make up the shortcomings of the laser radar.
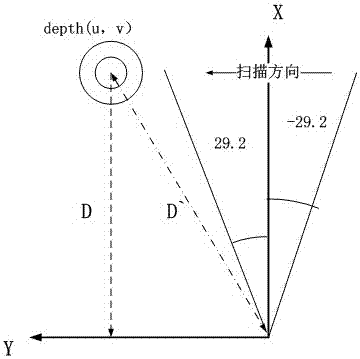
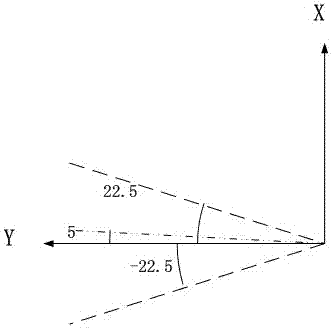
Owner:深圳市三宝创新机器人有限公司
Method for predicting real-time pose of target object based on two-dimensional image of target object
InactiveCN110335314AImprove adaptabilityIncrease flexibilityImage enhancementImage analysisObject basedData set
The invention belongs to the related technical field of pose prediction, and discloses a method for predicting a real-time pose of a target object based on a two-dimensional image of a target object.The method comprises the following steps: (1) respectively constructing a target segmentation network model and a target pose prediction network model, including: acquiring a plurality of two-dimensional images containing a plurality of target objects by using an RGB camera after internal reference calibration to obtain a target segmentation data set, determining a target segmentation network model, and training the target segmentation network model by using the target segmentation data set; (2) inputting a two-dimensional image of a target object obtained in real time into the target segmentation network model, and outputting a target mask by the target segmentation network model; and (3) inputting the processed target mask into a target pose prediction network model, wherein the target pose prediction network model performs pose prediction on a target object based on the received target mask. According to the invention, the applicability is improved, and the flexibility is better.


Owner:HUAZHONG UNIV OF SCI & TECH
Trailer system pose prediction method and device and storage medium
ActiveCN108871338AAchieve forecastReduce complexityNavigational calculation instrumentsPose predictionEngineering
The application relates to a trailer system pose prediction method and device and a storage medium. A trailer system comprises multiple trailers. The method comprises the following steps: acquiring atarget path of the trailer system, and acquiring the speed and pose of a current trailer in a current period; predicting the speed and pose of the next trailer in the current period; and updating thepose of the next trailer based on the predicted pose. When used for predicting the position of the trailers in the trailer system, the method can be used to predict the pose and speed of the next trailer based on information of the previous trailer, so that the entire trailer system can be predicted with a detection sensor only arranged on the first trailer and the other trailers not separately provided with a sensor, the complexity is low, the prediction efficiency is greatly improved and the real-time requirements can be met.


Owner:UISEE TECH BEIJING LTD
Elastic algorithm for calculating rotor assembly pose based on end jump measurement
ActiveCN110083906AAccurate predictionImprove coaxialityGeometric CADDesign optimisation/simulationAviationPrediction algorithms
The invention discloses an elastic algorithm for calculating a rotor assembly pose based on end jump measurement. A rotor matching surface is equivalent to a plurality of micro-convex body contact pairs; the contact elastic deformation is calculated by using a Hertz contact rule, contact pairs which actually contact with each other are separated; the final contact state is judged through the energy and torque balance equation, the normal vector of the contact plane is finally solved to represent the contact pose, the rotor assembly pose prediction accuracy is improved, the assembly coaxialitycan be well reflected, and rotor assembly phase prediction and optimization are better achieved. The method is based on actually measured end hop data in actual production; elastic deformation generated in the assembly process is considered; the method has the advantages that the defects of a rigid prediction algorithm are overcome, the accurate prediction of the assembly pose before assembly is realized, the rotor coaxiality after assembly is improved, meanwhile, the one-time assembly qualification rate is greatly improved, and the method has important practical guiding significance for axisprediction and assembly phase adjustment and optimization in the assembly process of the aero-engine rotor piece.
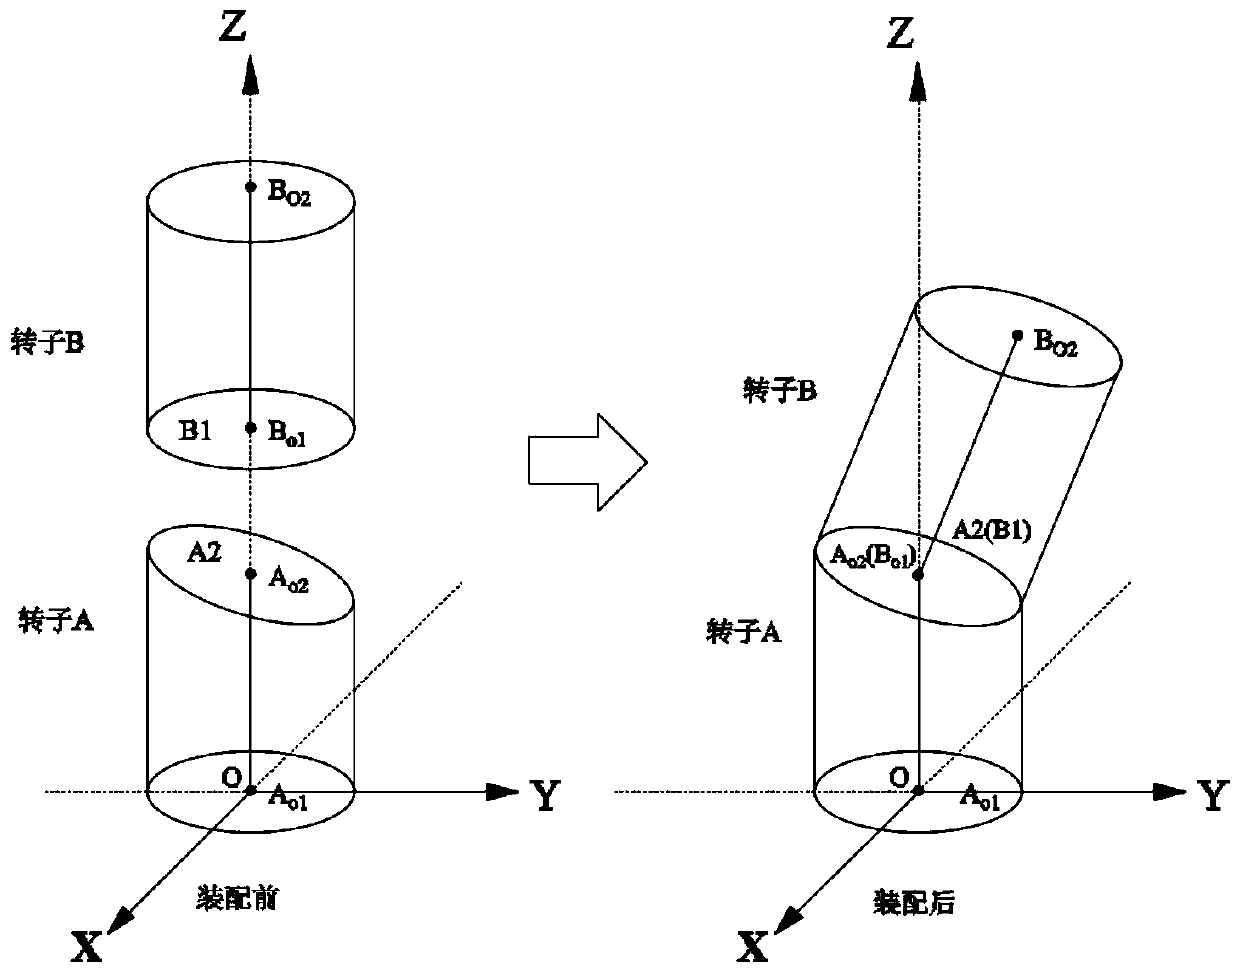
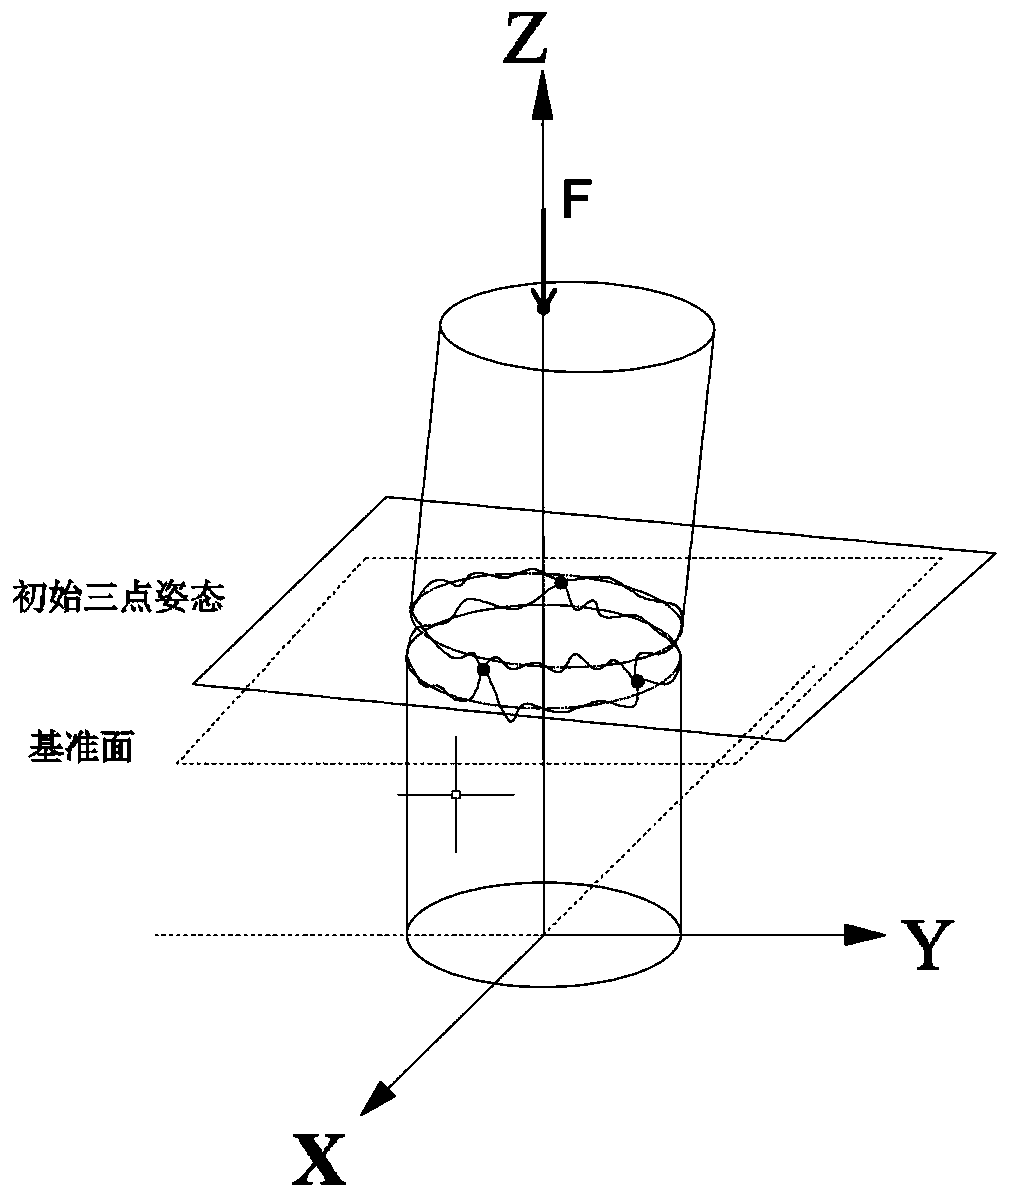
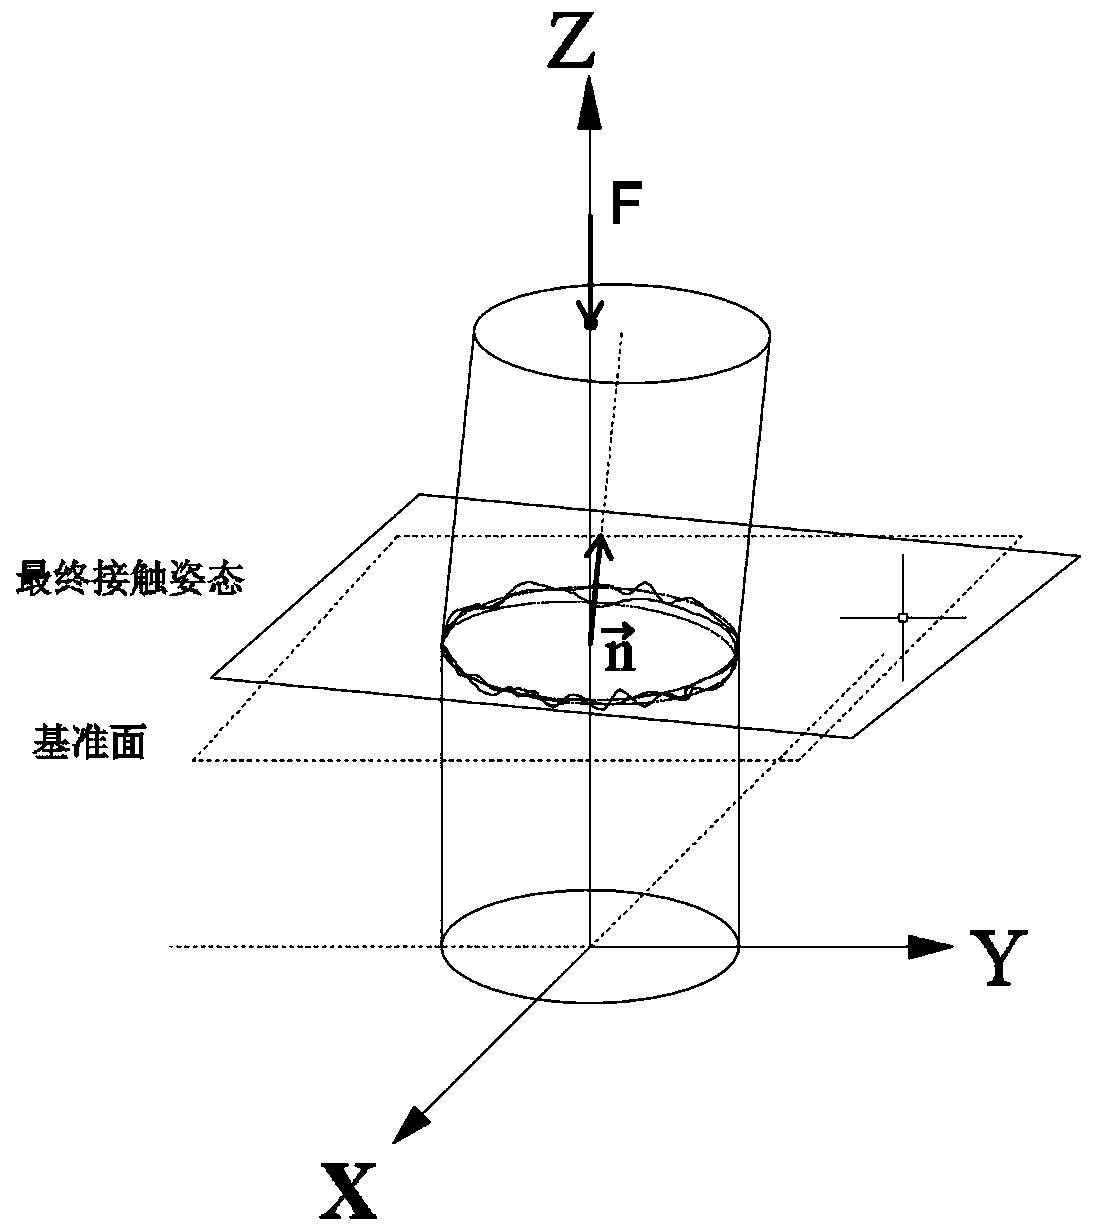
Owner:DALIAN UNIV OF TECH
An assembly pose high-precision linear solving method considering geometric errors
ActiveCN109766597ACalculation speedReduce assembly errorsSpecial data processing applicationsGeometric errorStress conditions
The invention discloses an assembly pose high-precision linear solving method considering geometric errors, which comprises the following steps of step 1, measuring the morphology of a to-be-assembledsurface on a part, and carrying out parameterization processing to obtain the mathematical description of the surface shape of each to-be-assembled surface; 2, obtaining an optimal expression of theassembling pose of the to-be-assembled surface according to the spatial plane relation, the shape error and the stress condition of the to-be-assembled surface; and step 3, solving the optimal expression to obtain the optimal assembly pose of the to-be-assembled surface, so that the contact pose relationship between the parts can be solved quickly, accurately and quantitatively in the assembly andmeasurement process to improve the precision and the efficiency of part pose prediction and control.


Owner:BEIJING INSTITUTE OF TECHNOLOGYGY
End-to-end unconstrained human face key point detection method
ActiveCN107491767AImprove time and efficiencyCharacter and pattern recognitionPattern recognitionVisibility
The invention discloses an end-to-end unconstrained human face key point detection method, which belongs to the technical field of human face recognition. The method provided by the invention comprises the steps that a number of key points of a face are pre-determined; the visibility information of the key points is determined; multitasking training is carried out to predict the coordinate and visibility of the key points. An end-to-end training scheme is realized without additional information such as a 3D human face. Multi-human-face pose prediction of a multi-angle key point detection scheme is prevented. According to the invention, the time efficiency is improved; a human face with change of any angle can be processed; and a human face with any degree of occlusion can be processed.


Owner:GUANGZHOU YUNCONG INFORMATION TECH CO LTD
Three-dimensional human body posture prediction method and device, medium and product
The invention discloses a three-dimensional human body posture prediction method and device, a medium and a product, and relates to the field of posture prediction, and the method comprises the steps: obtaining to-be-predicted three-dimensional human body skeleton data; constructing a three-dimensional human body posture prediction model based on the LSTM network and the generative adversarial network; the three-dimensional human body posture prediction model comprises a generator and a discriminator; the generator comprises an LSTM encoder, a mixed time sequence interaction module, a time sequence enhancement maximum information pooling module, a skeleton graph network module and an LSTM decoder. And performing three-dimensional human body posture prediction by adopting the trained three-dimensional human body posture prediction model according to three-dimensional human body skeleton data to be predicted. According to the invention, high-precision prediction of the human body motion track can be realized, and the safety and efficiency of a man-machine cooperation system are improved.

Owner:TAIZHOU UNIV
Three-dimensional attitude estimation method and device, storage medium and electronic equipment
The invention discloses a three-dimensional attitude estimation method and device, a storage medium and electronic equipment, and relates to the technical field of three-dimensional attitude estimation, and the method comprises the steps: carrying out the joint estimation of a multi-view image of a target object, and obtaining a joint feature map and a joint heat map of each view; performing cross-view-angle alignment analysis on the multi-view-angle joint heat map to obtain an initial three-dimensional joint coordinate of each joint point; carrying out deformable cross-attention feature aggregation on the multi-view joint feature map to obtain multi-view fusion features of the joints; and performing three-dimensional attitude prediction based on the initial three-dimensional joint coordinates of the joints and the multi-view fusion features to obtain target three-dimensional joint coordinates of the joints. According to the invention, the estimation accuracy of the three-dimensional coordinates of the joint points during three-dimensional attitude estimation can be effectively improved.

Owner:SHENZHEN TCL NEW-TECH CO LTD
Pose prediction method and device, equipment and medium
PendingCN120233874AInput/output for user-computer interactionBiological modelsPattern recognitionPose prediction
The invention discloses a pose prediction method and device, equipment and a medium, and relates to the technical field of data processing. The method comprises the steps that a historical pose sequence and a historical IMU sequence corresponding to the historical pose sequence are obtained, the historical pose sequence comprises multiple pieces of historical pose data arranged according to a time sequence, and the historical IMU data comprise multiple pieces of historical IMU data arranged according to the time sequence; generating a predicted pose sequence according to the historical pose sequence, the historical IMU sequence and a pose prediction model; the predicted pose sequence comprises a plurality of future pose data arranged according to a time sequence, the pose prediction model comprises a pose prediction sub-model, a pose compensation sub-model and a fusion sub-model, the pose prediction sub-model is used for receiving a historical pose sequence, the pose compensation sub-model is used for receiving a historical IMU sequence, and the fusion sub-model is used for fusing the historical IMU sequence. The outputs of the pose prediction sub-model and the pose compensation sub-model are the input of the fusion sub-model, and the fusion sub-model is used for outputting a predicted pose sequence.

Owner:GOERTEK INC
Map-Relative Pose Regression for Visual Relocalization
This disclosure pertains to a scene-agnostic, map-relative pose regression method. The pose regressor is conditioned on a scene-specific map representation such that its pose predictions are relative to the scene map. This allows training of the pose regressor across multiple scenes to learn the generic relation between a scene-specific map representation and the camera pose. The map-relative pose regressor can then be applied to new map representations.

Owner:NIANTIC SPATIAL INC
3D human body posture estimation optimization method and system based on diffusion model
The invention discloses a 3D human body posture estimation optimization method and system based on a diffusion model, and relates to the technical field of 3D human body posture estimation. The method comprises the following steps that an optimization framework based on a diffusion model is constructed, the optimization framework based on the diffusion model comprises a forward diffusion framework and a reverse denoising framework, the reverse denoising framework adopts a denoising neural network, and the denoising neural network comprises a time-guided graph convolution Transform module and a 3D attitude fusion optimization module; performing different training on the optimization framework based on the diffusion model based on three genres of single frame-single frame, sequence-sequence and sequence-single frame, and correspondingly designing a loss function; and reasoning the 3D attitude predicted by the existing model by adopting a denoising neural network in the trained optimization framework based on the diffusion model to obtain a final 3D attitude. According to the method, the optimization framework continuously learns uncertainty existing in initial prediction in the denoising process, so that more accurate 3D attitude prediction is realized.

Owner:CHONGQING UNIV OF TECH
Pose prediction method, device and equipment
PendingCN120233876AInput/output for user-computer interactionArtificial lifePattern recognitionPredictive methods
The invention discloses a pose prediction method, device and equipment, and relates to the technical field of data processing. The method comprises the following steps: acquiring a historical pose sequence, wherein the historical pose sequence comprises a plurality of historical pose data arranged according to a time sequence; decomposing the historical pose sequence according to a data decomposition algorithm to obtain k'sub-modal components corresponding to the historical pose sequence; for any sub-mode component, generating a pose prediction subsequence according to the pose prediction model corresponding to the sub-mode component; and fusing the pose prediction subsequences corresponding to the k'sub-modal components according to a fusion model to obtain a pose prediction sequence. The method is a novel pose prediction method capable of predicting a more accurate pose prediction sequence.

Owner:GOERTEK INC
Data processing, posture prediction method, device and storage medium
ActiveCN113807150Bimprove performanceImprove forecast accuracyCharacter and pattern recognitionNeural learning methodsSample graphPose prediction
The embodiments of the present application provide a data processing, posture prediction method, device and storage medium. In the data processing method, in the process of training a posture prediction model based on an automatically labeled sample image, the labeling error of the posture marked on the sample image can be predicted according to the posture prediction result output by the posture prediction model. Based on the posture marked on the sample image and the calculated labeling error, the posture prediction model can continue to be trained until the loss caused by the labeling error converges to a specified value. Based on this implementation method, the error of the supervisory signal can be compensated to reduce the impact of the labeling error on the sample image on the training process of the posture prediction model, and then the posture prediction model with higher performance obtained by training can be trained to improve the prediction accuracy of the posture prediction model.

Owner:ALIBABA GROUP HOLDING LTD
Human pose prediction method, device, equipment and readable storage medium
ActiveCN116363750BGeometric image transformationBiometric pattern recognitionTime informationHeat map
The application provides a human posture prediction method, device and equipment and a readable storage medium. The method comprises the following steps: extracting a feature map of an input picture; obtaining an offset of a human key point, a heat map and a center heat map based on the feature map; obtaining a predicted human key point according to the offset and the center heat map; generating a local key point expansion window with the predicted human key point as the center, and then converting the local key point expansion window into a key point attraction field; generating a global key point expansion window by using the predicted human key point and the heat map; performing a convolution operation on the global key point expansion window by using the key point attraction field as a convolution kernel to obtain a corrected key point heat map; obtaining two-dimensional coordinates of a predicted human joint point from the corrected key point heat map; and respectively using spatial and timing information of the two-dimensional coordinates of the predicted human joint point to encode and decode to obtain three-dimensional information of the predicted human joint point. Through the application, the human posture prediction accuracy is improved.

Owner:WUHAN UNIV
Pose prediction method and device and medium
PendingCN120233878AInput/output for user-computer interactionArtificial lifePattern recognitionRadiology
The invention discloses a pose prediction method and device and a medium, and relates to the technical field of data processing. The method comprises the following steps: acquiring a historical pose sequence; decomposing the historical pose sequence according to a data decomposition algorithm to obtain k'sub-modal components corresponding to the historical pose sequence; determining high-frequency sub-mode components and low-frequency sub-mode components in the k'sub-mode components; determining a pose prediction sequence according to the high-frequency sub-mode component, the low-frequency sub-mode component and a pose prediction model; the pose prediction sequence comprises a plurality of future pose data arranged according to a time sequence, the pose prediction model at least comprises a first pose prediction sub-model, a second pose prediction sub-model and a fusion sub-model, the first pose prediction sub-model is used for receiving a high-frequency sub-mode component, the second pose prediction sub-model is used for receiving a low-frequency sub-mode component, and the fusion sub-model is used for fusing the high-frequency sub-mode component and the low-frequency sub-mode component. The outputs of the first pose prediction sub-model and the second pose prediction sub-model are the input of a fusion sub-model, and the fusion sub-model is used for outputting a pose prediction sequence.

Owner:GOERTEK INC
Computer-implemented method for training pose prediction model for synthesizing and displaying perspective video
PendingCN121420332AGeometric image transformationBiological modelsPattern recognitionDriver/operator
A computer-implemented method is provided for training an untrained pose prediction model using a training dataset of optimal poses collected from a plurality of drivers in order to obtain a pose prediction model for synthesizing and displaying perspective video for the drivers. The method may include initializing a driver representation; receiving context information and a current attitude; determining features and predicting an optimal attitude; adjusting the pose prediction model based on a loss function that enhances consistency between the predicted optimal pose and the optimal pose of the training data set; and repeating the above steps until the method terminates, where the current pose is the predicted optimal pose of the previous iteration, and where determining the feature and predicting the optimal pose is also based on the feature determined in one or more previous iterations. A method for synthesizing and displaying perspective video is also provided.

Owner:OMOWE GMBH
General sketch three-dimensional human body posture prediction method for stylized input
The invention provides a stylized input-oriented general sketch three-dimensional human body posture prediction method, which comprises the following steps of: 1, sampling SMPL (skin multi-person linear model) posture parameters through a variational posture encoder, and injecting text description and the posture parameters as conditions into a training controllable generation network; 2, training a target detection model network and a visual converter attitude estimation model network; step 3, enabling the sketch human body two-dimensional joint point position to pass through a multi-layer perceptron network to obtain a human body two-dimensional joint point position high-dimensional vector; 4, combining the cross attention map and the feature map in the output layer of the sketch human body posture prediction network to generate a posture feature vector of the sketch; and step 5, outputting three-dimensional human body shape parameters and camera parameters. The method can be widely applied to the fields of game creation, animation film production and the like, and has relatively high practical value and development prospect.

Owner:NANJING UNIV
Reinforcement learning-based label-free six-dimensional object pose prediction method and apparatus
Provided are a reinforcement learning-based label-free six-dimensional object pose prediction method and apparatus. The method includes: obtaining a target image to be predicted, the target image being a two-dimensional image including a target object; performing pose prediction based on the target image by using a pre-trained pose prediction model to obtain a prediction result, the pose prediction model being obtained by performing reinforcement learning based on a sample image; and determining a three-dimensional position and a three-dimensional direction of the target object based on the prediction result. The pose prediction model is trained by introducing reinforcement learning, the pose prediction is performed based on the target image by using the pre-trained pose prediction model, and thus the problem of six-dimensional object pose estimation based on two-dimensional images can be solved in the absence of real pose annotation, which ensures the prediction effect of label-free six-dimensional object pose prediction.

Owner:TSINGHUA UNIVERSITY
A 6D pose estimation method and system for objects based on attention mechanism
The present invention relates to the field of computer vision technology, and specifically to a method and system for estimating the 6D pose of an object based on an attention mechanism; the object 6D pose estimation method utilizes a 6D pose estimation network, and the 6D pose estimation network includes a target detection module, a backbone network module, and a pose prediction module. In the target detection module, the RGB image is magnified according to the location of the target. The backbone network module adopts a new ResNet variant, integrating the pixel-level wavelet multi-branch attention mechanism and the dual-channel upsampling attention mechanism to achieve efficient capture and fusion of multi-scale features of the target in the spatial domain and the wavelet domain. The pose prediction module uses a neural network to directly predict the 6D pose. The present invention not only provides an innovative idea for improving occlusion robustness, but also constructs a new paradigm for end-to-end object 6D pose estimation based on spatial-frequency domain feature fusion.

Owner:HUNAN UNIV
Gesture prediction for articulated objects
PendingCN118922800AImage enhancementInput/output for user-computer interactionPattern recognitionPose prediction
A method for predicting a pose of an articulated object includes receiving spatial information for n joints of the articulated object. Passing the spatial information for the n joints to a machine learning model, the machine learning model being previously trained to receive, as input, spatial information for n + m joints, where mgt; 1. A pose prediction for the articulated object is received as an output from the machine learning model, the pose prediction based at least on spatial information for the n joints without spatial information for the m joints.

Owner:MICROSOFT TECHNOLOGY LICENSING LLC


