

Patents
Literature
63 results about "General purpose graphic processing unit" patented technology
Efficacy Topic
Property
Owner
Technical Advancement
Application Domain
Technology Topic
Technology Field Word
Patent Country/Region
Patent Type
Patent Status
Application Year
Inventor
GPGPU (general purpose graphics processing unit) Share this item with your network: A general-purpose GPU (GPGPU) is a graphics processing unit (GPU) that performs non-specialized calculations that would typically be conducted by the CPU (central processing unit). Ordinarily, the GPU is dedicated to graphics rendering.
C/c++ language extensions for general-purpose graphics processing unit
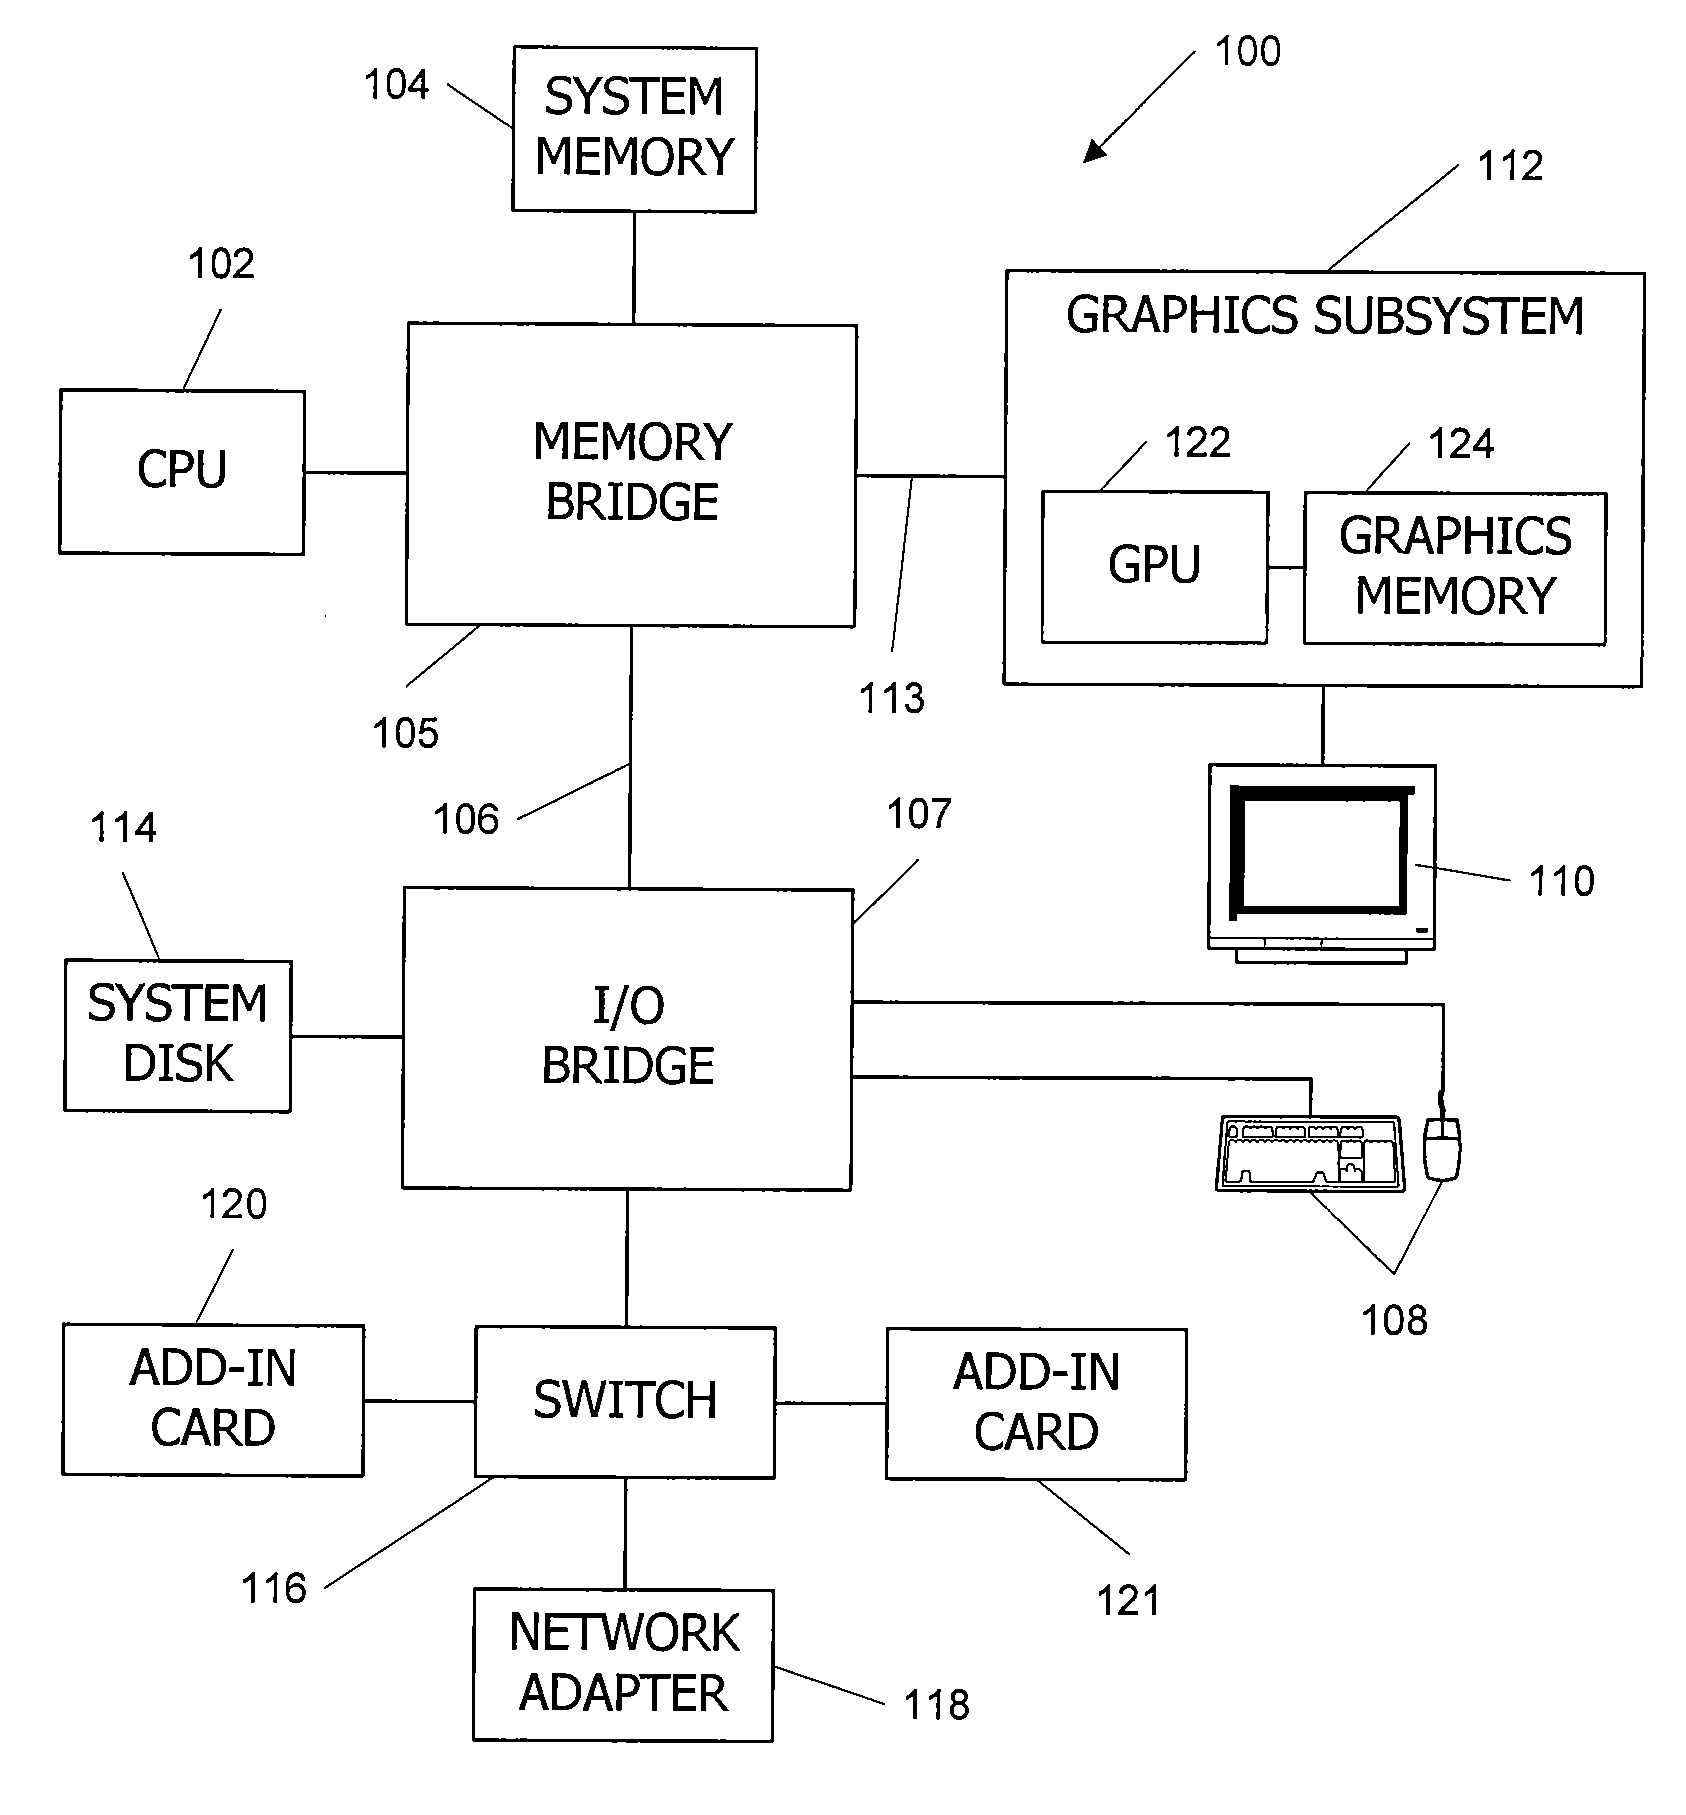
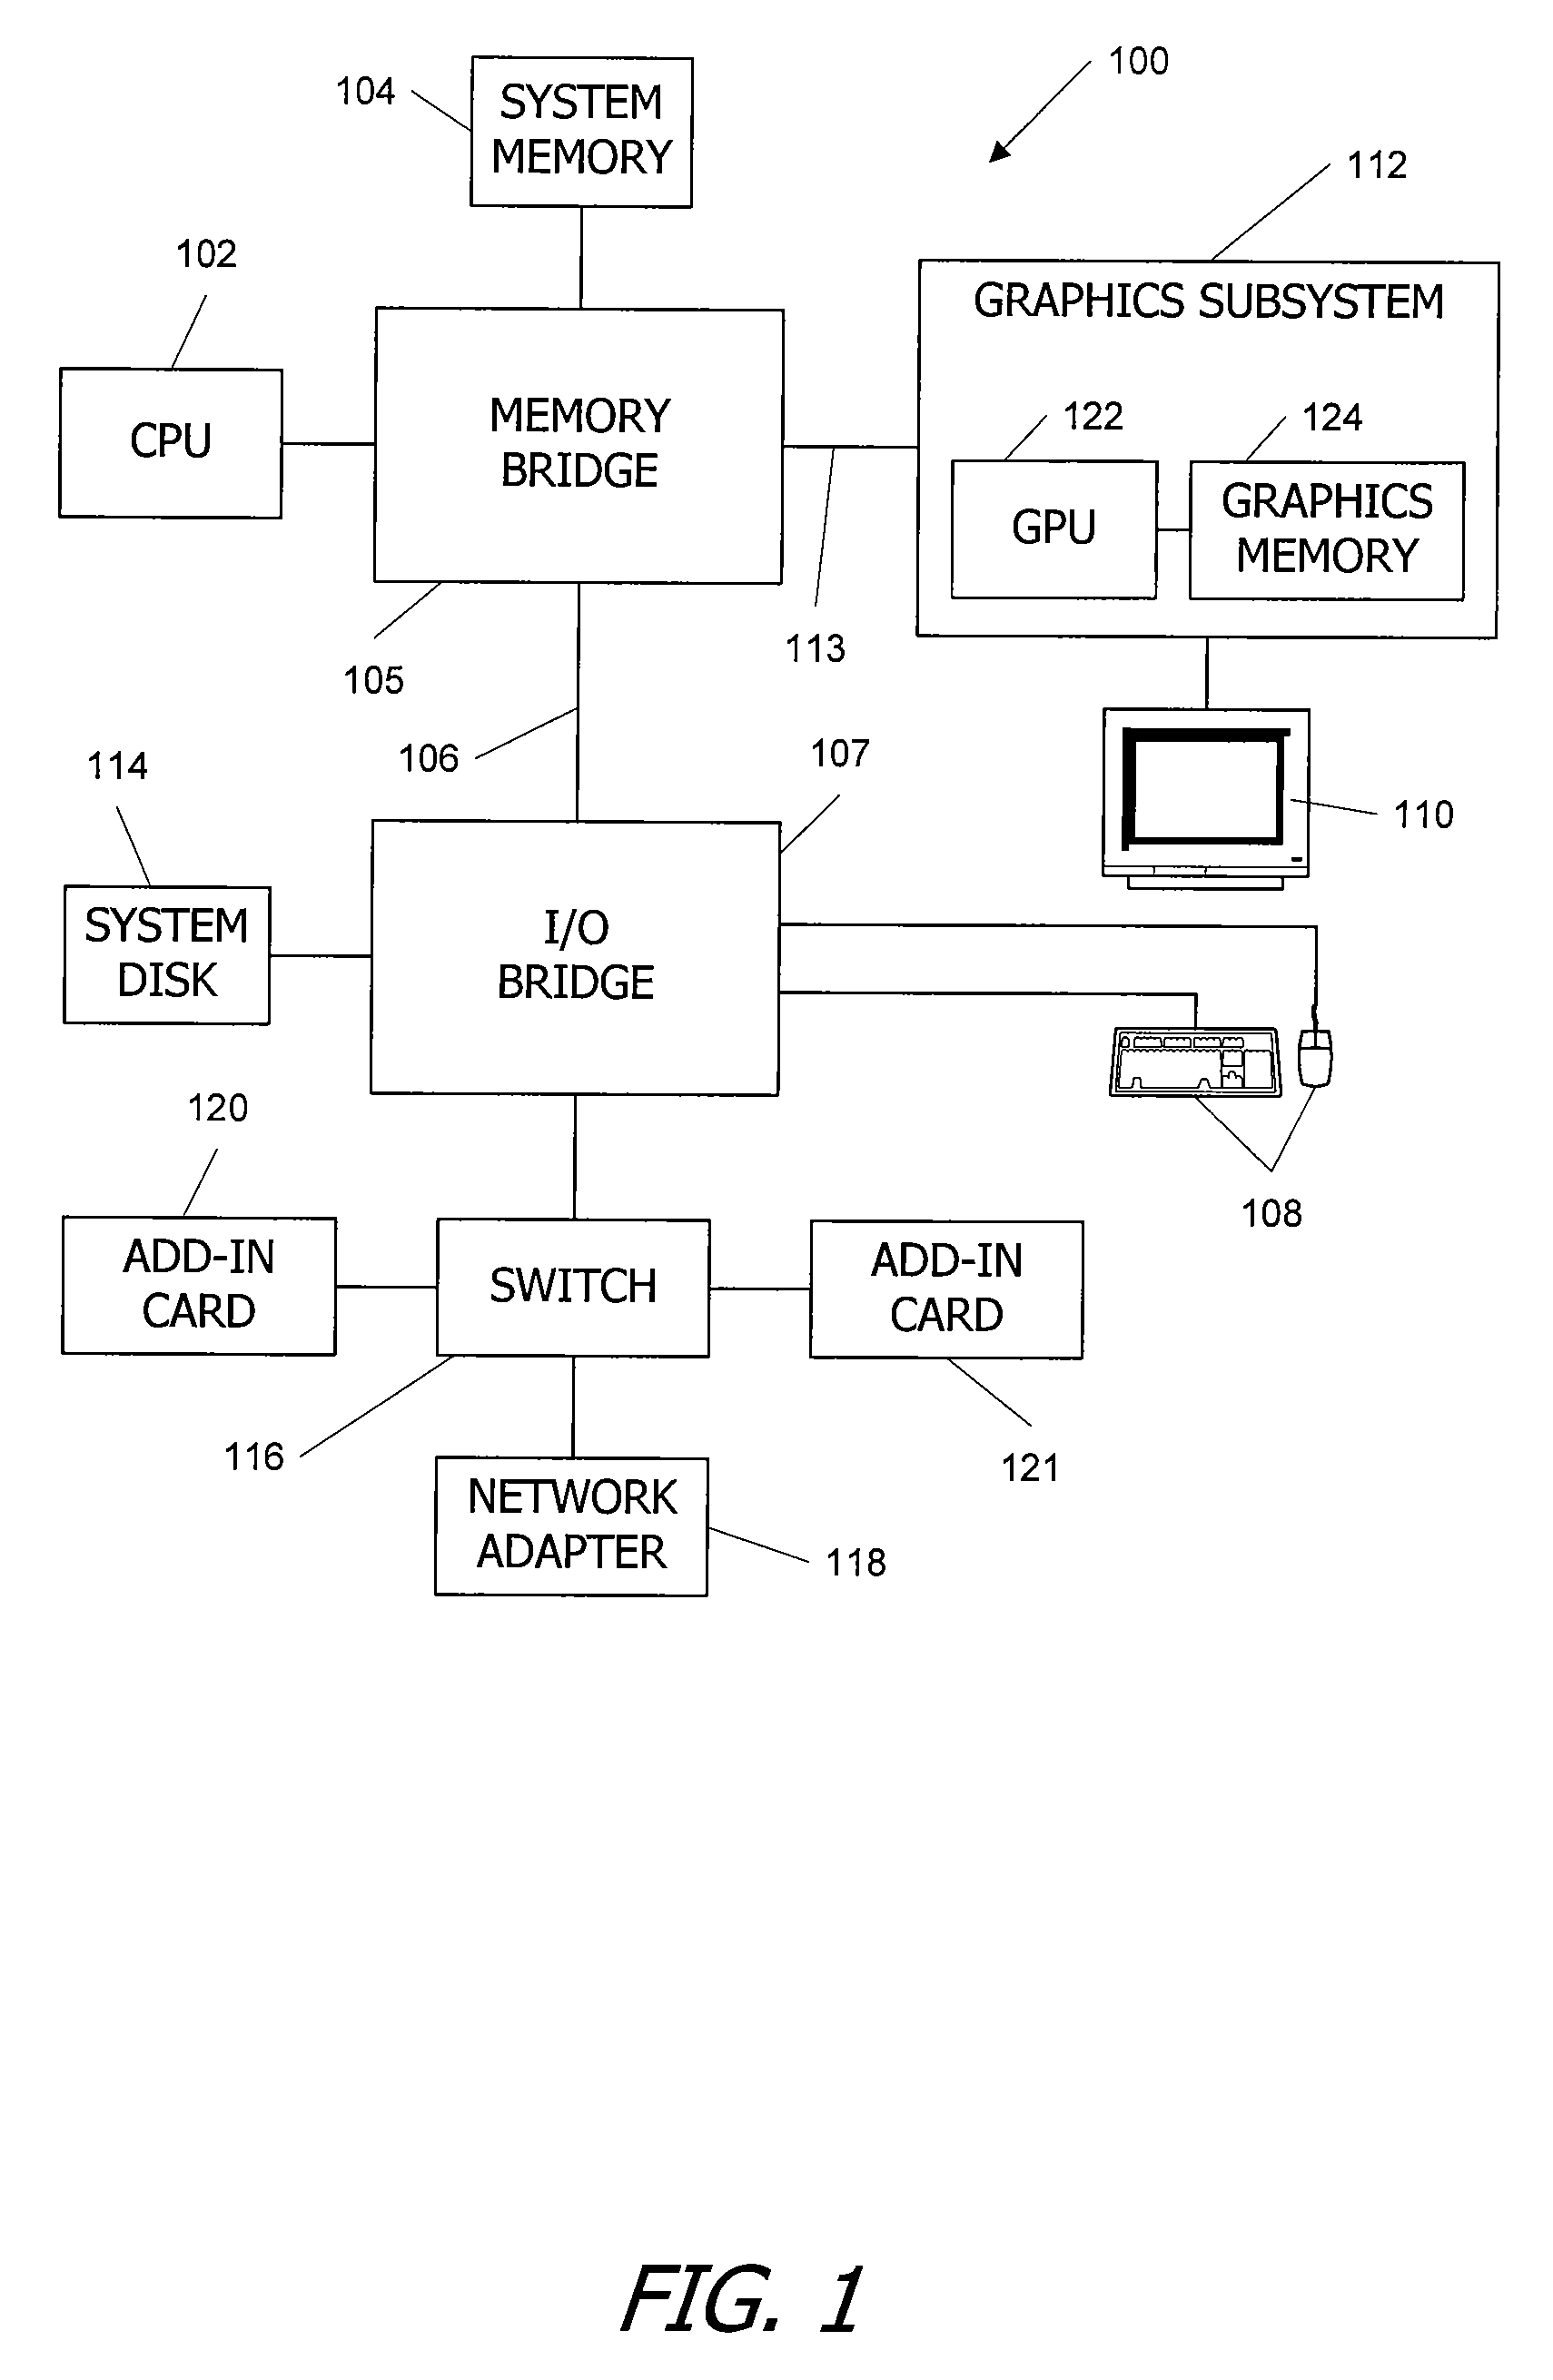
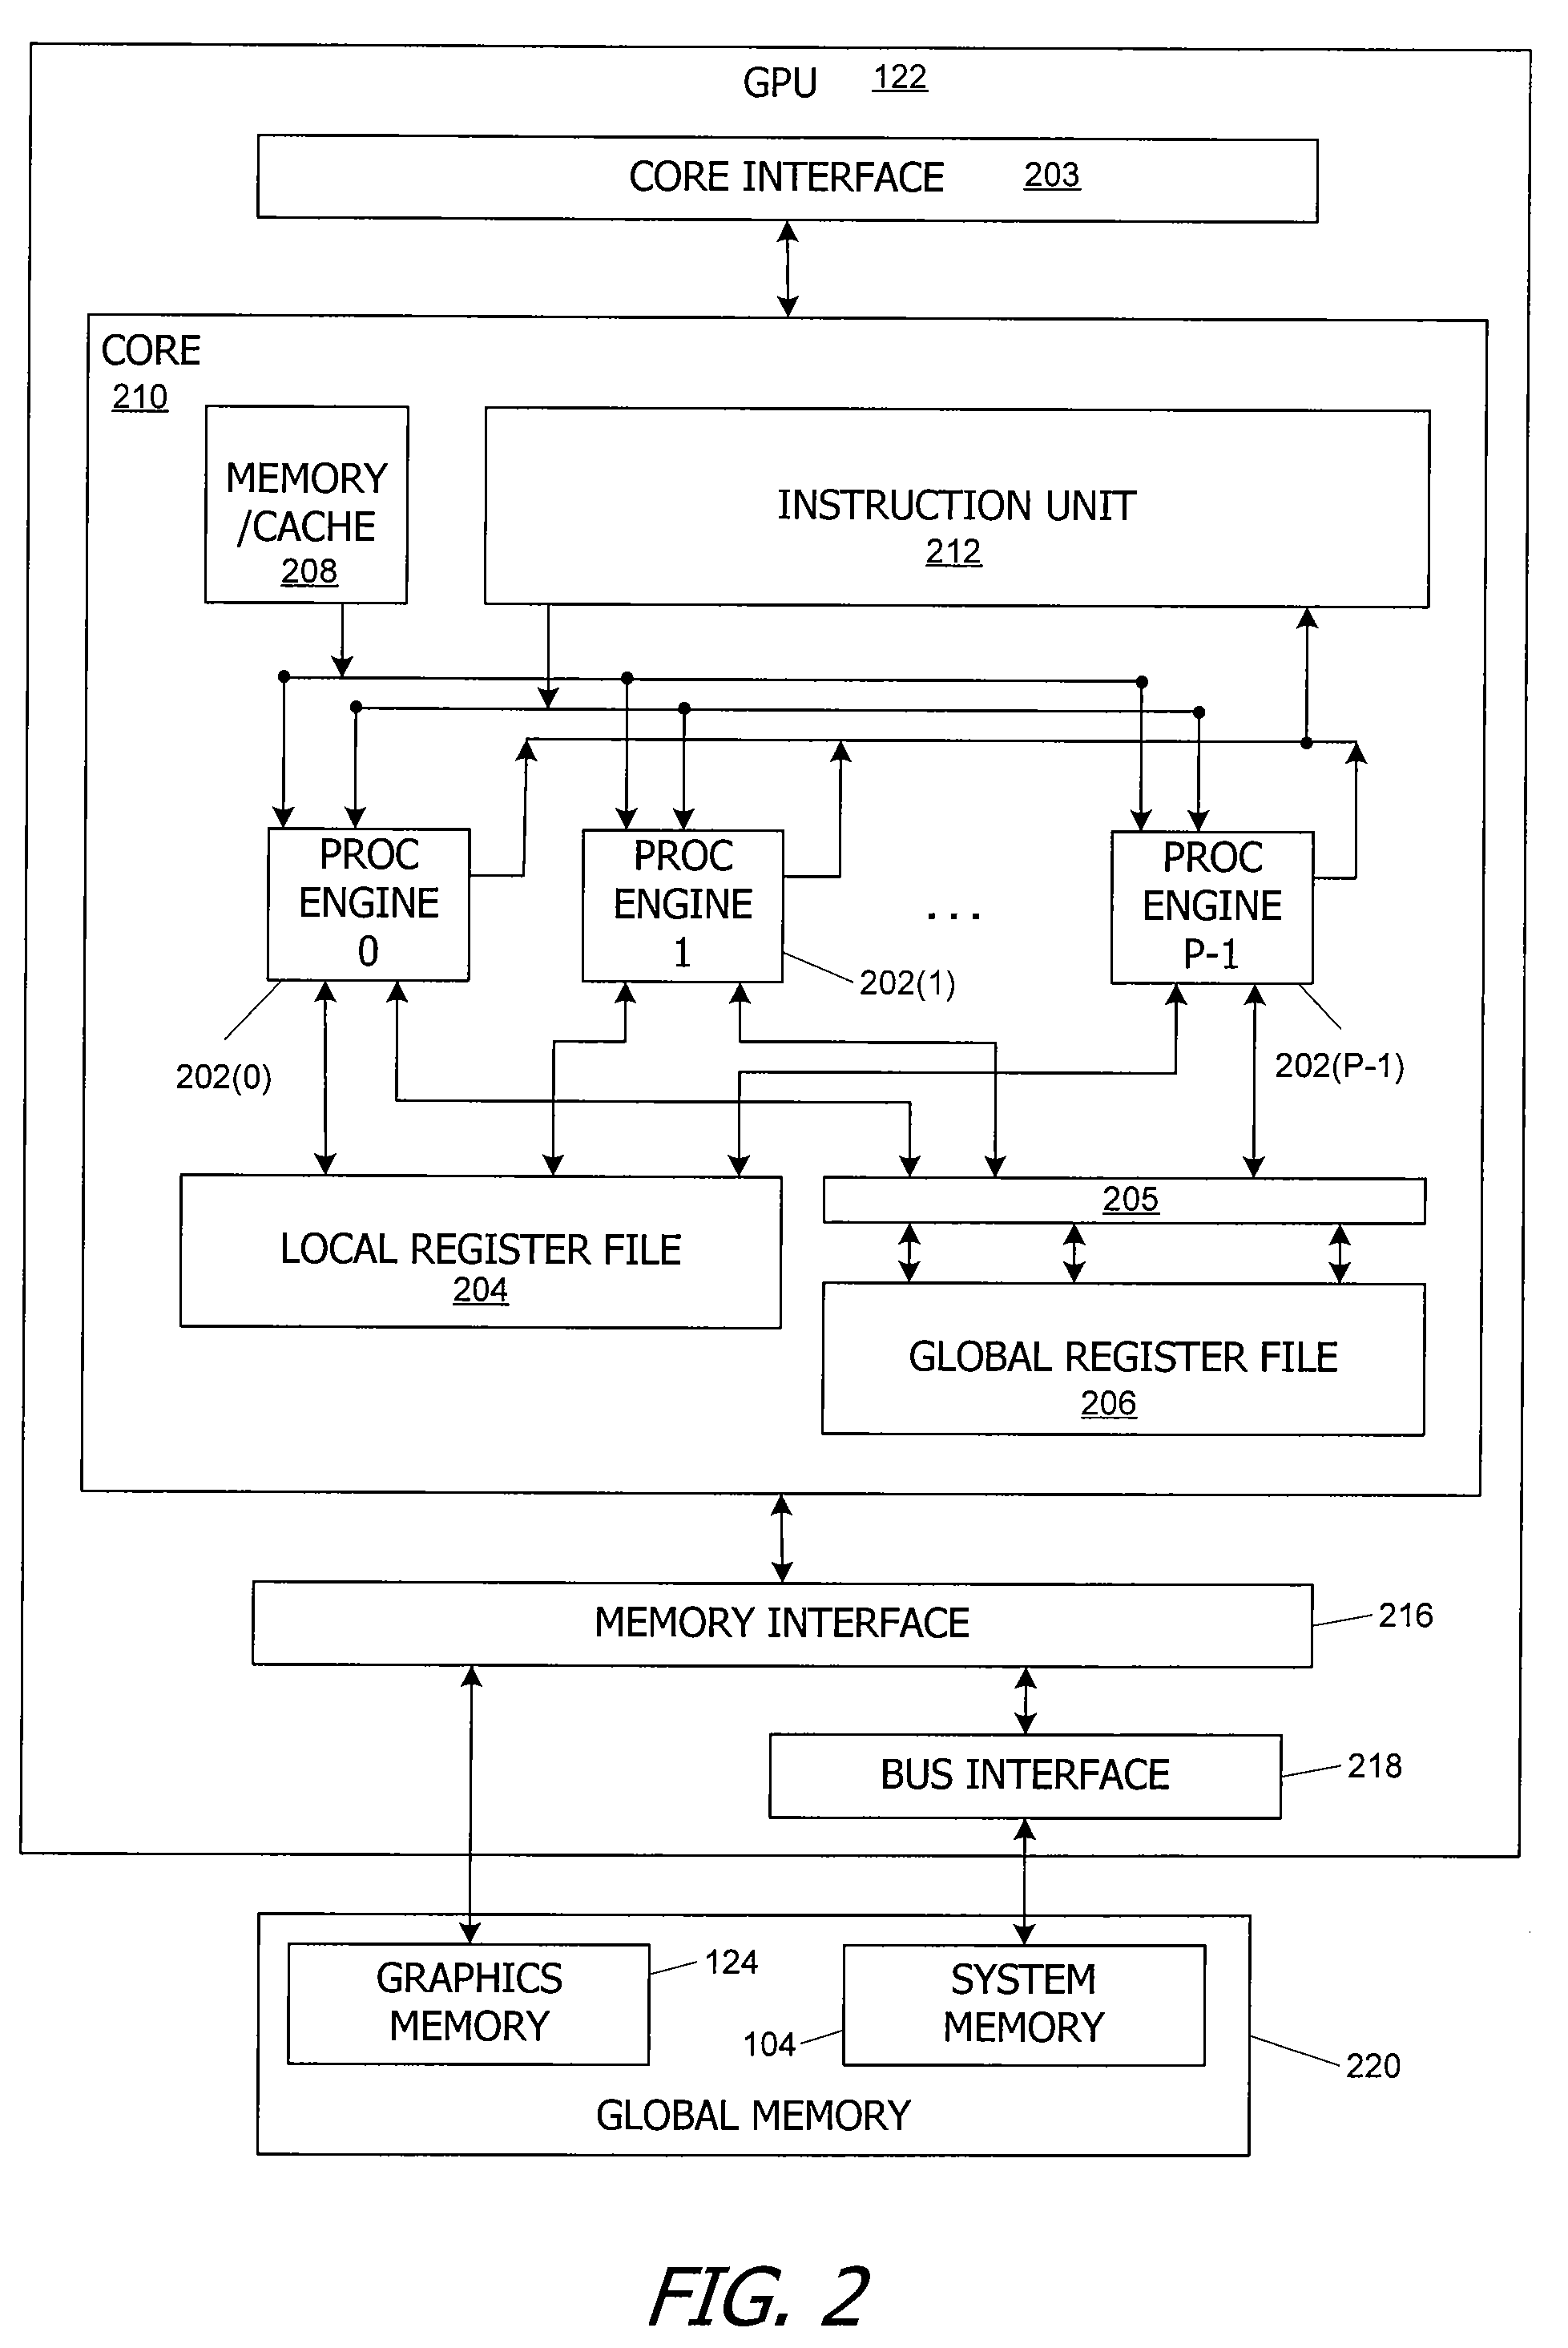
A general-purpose programming environment allows users to program a GPU as a general-purpose computation engine using familiar C / C++ programming constructs. Users may use declaration specifiers to identify which portions of a program are to be compiled for a CPU or a GPU. Specifically, functions, objects and variables may be specified for GPU binary compilation using declaration specifiers. A compiler separates the GPU binary code and the CPU binary code in a source file using the declaration specifiers. The location of objects and variables in different memory locations in the system may be identified using the declaration specifiers. CTA threading information is also provided for the GPU to support parallel processing.
Owner:NVIDIA CORP
Graphical processing system, graphical pipeline and method for implementing subpixel shifting to anti-alias texture
ActiveUS7456846B1Reduce aliasingReduce textureDetails involving antialiasingCathode-ray tube indicatorsGeneral purposeGraphics
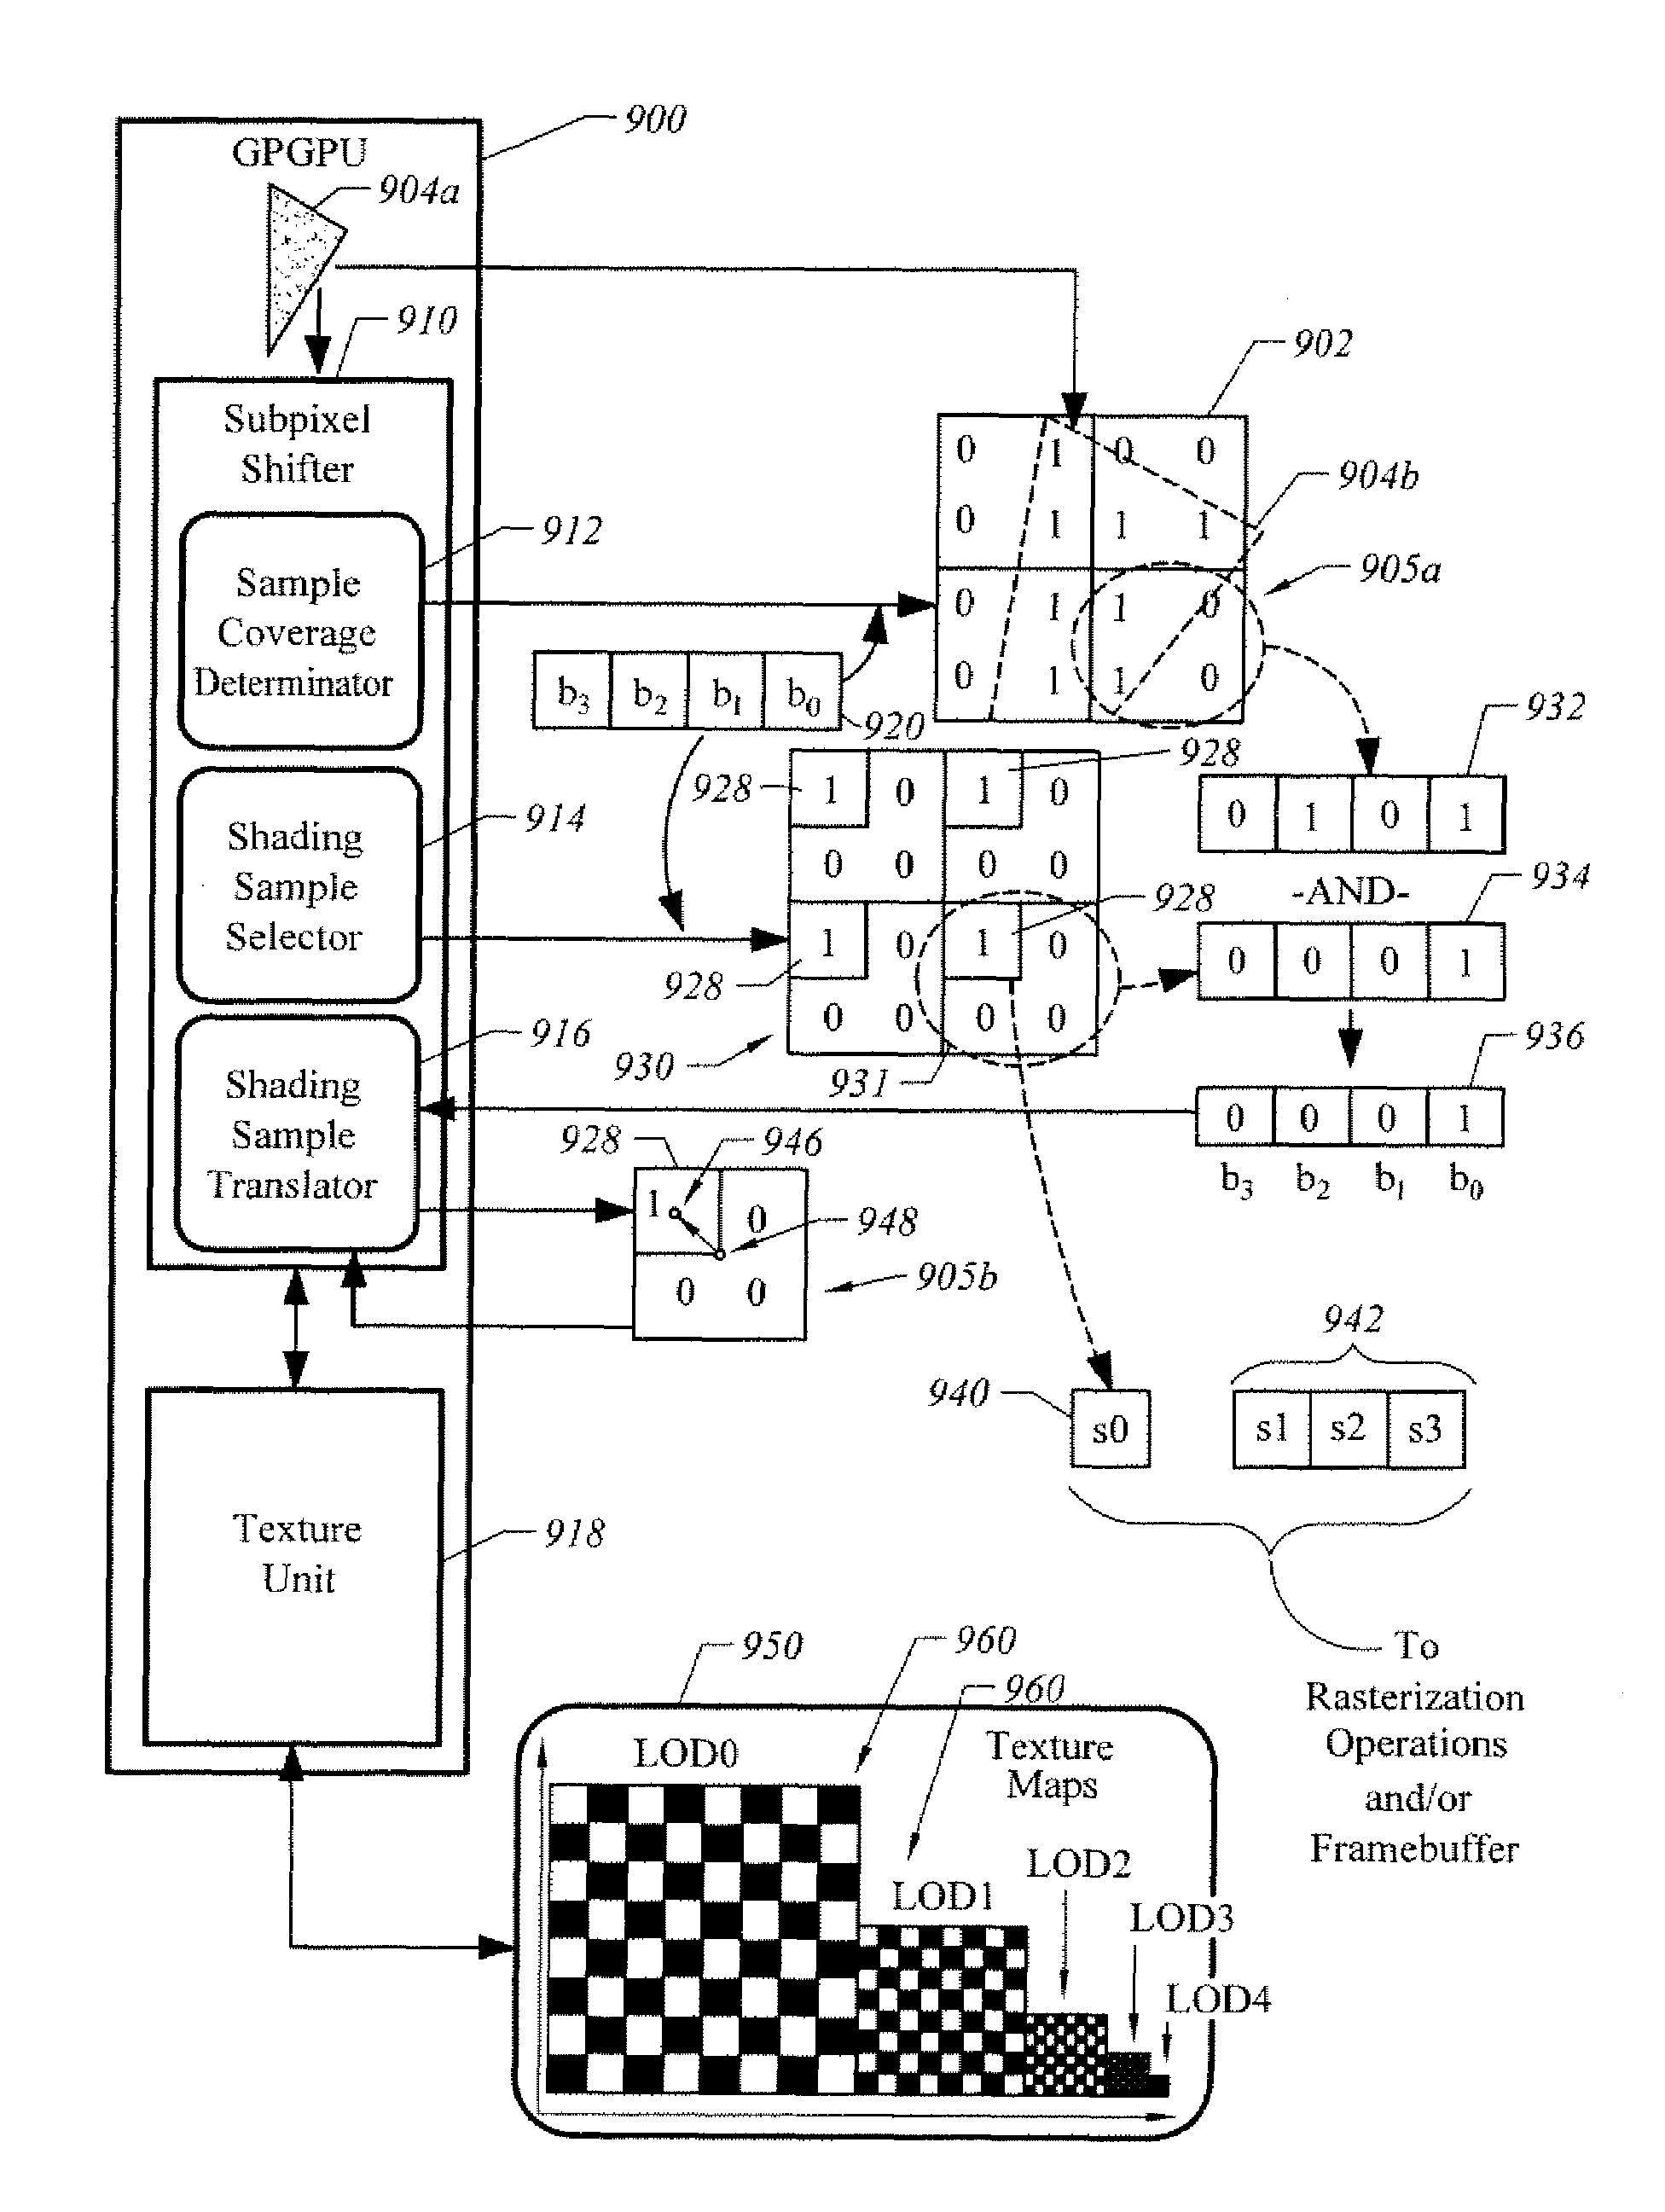
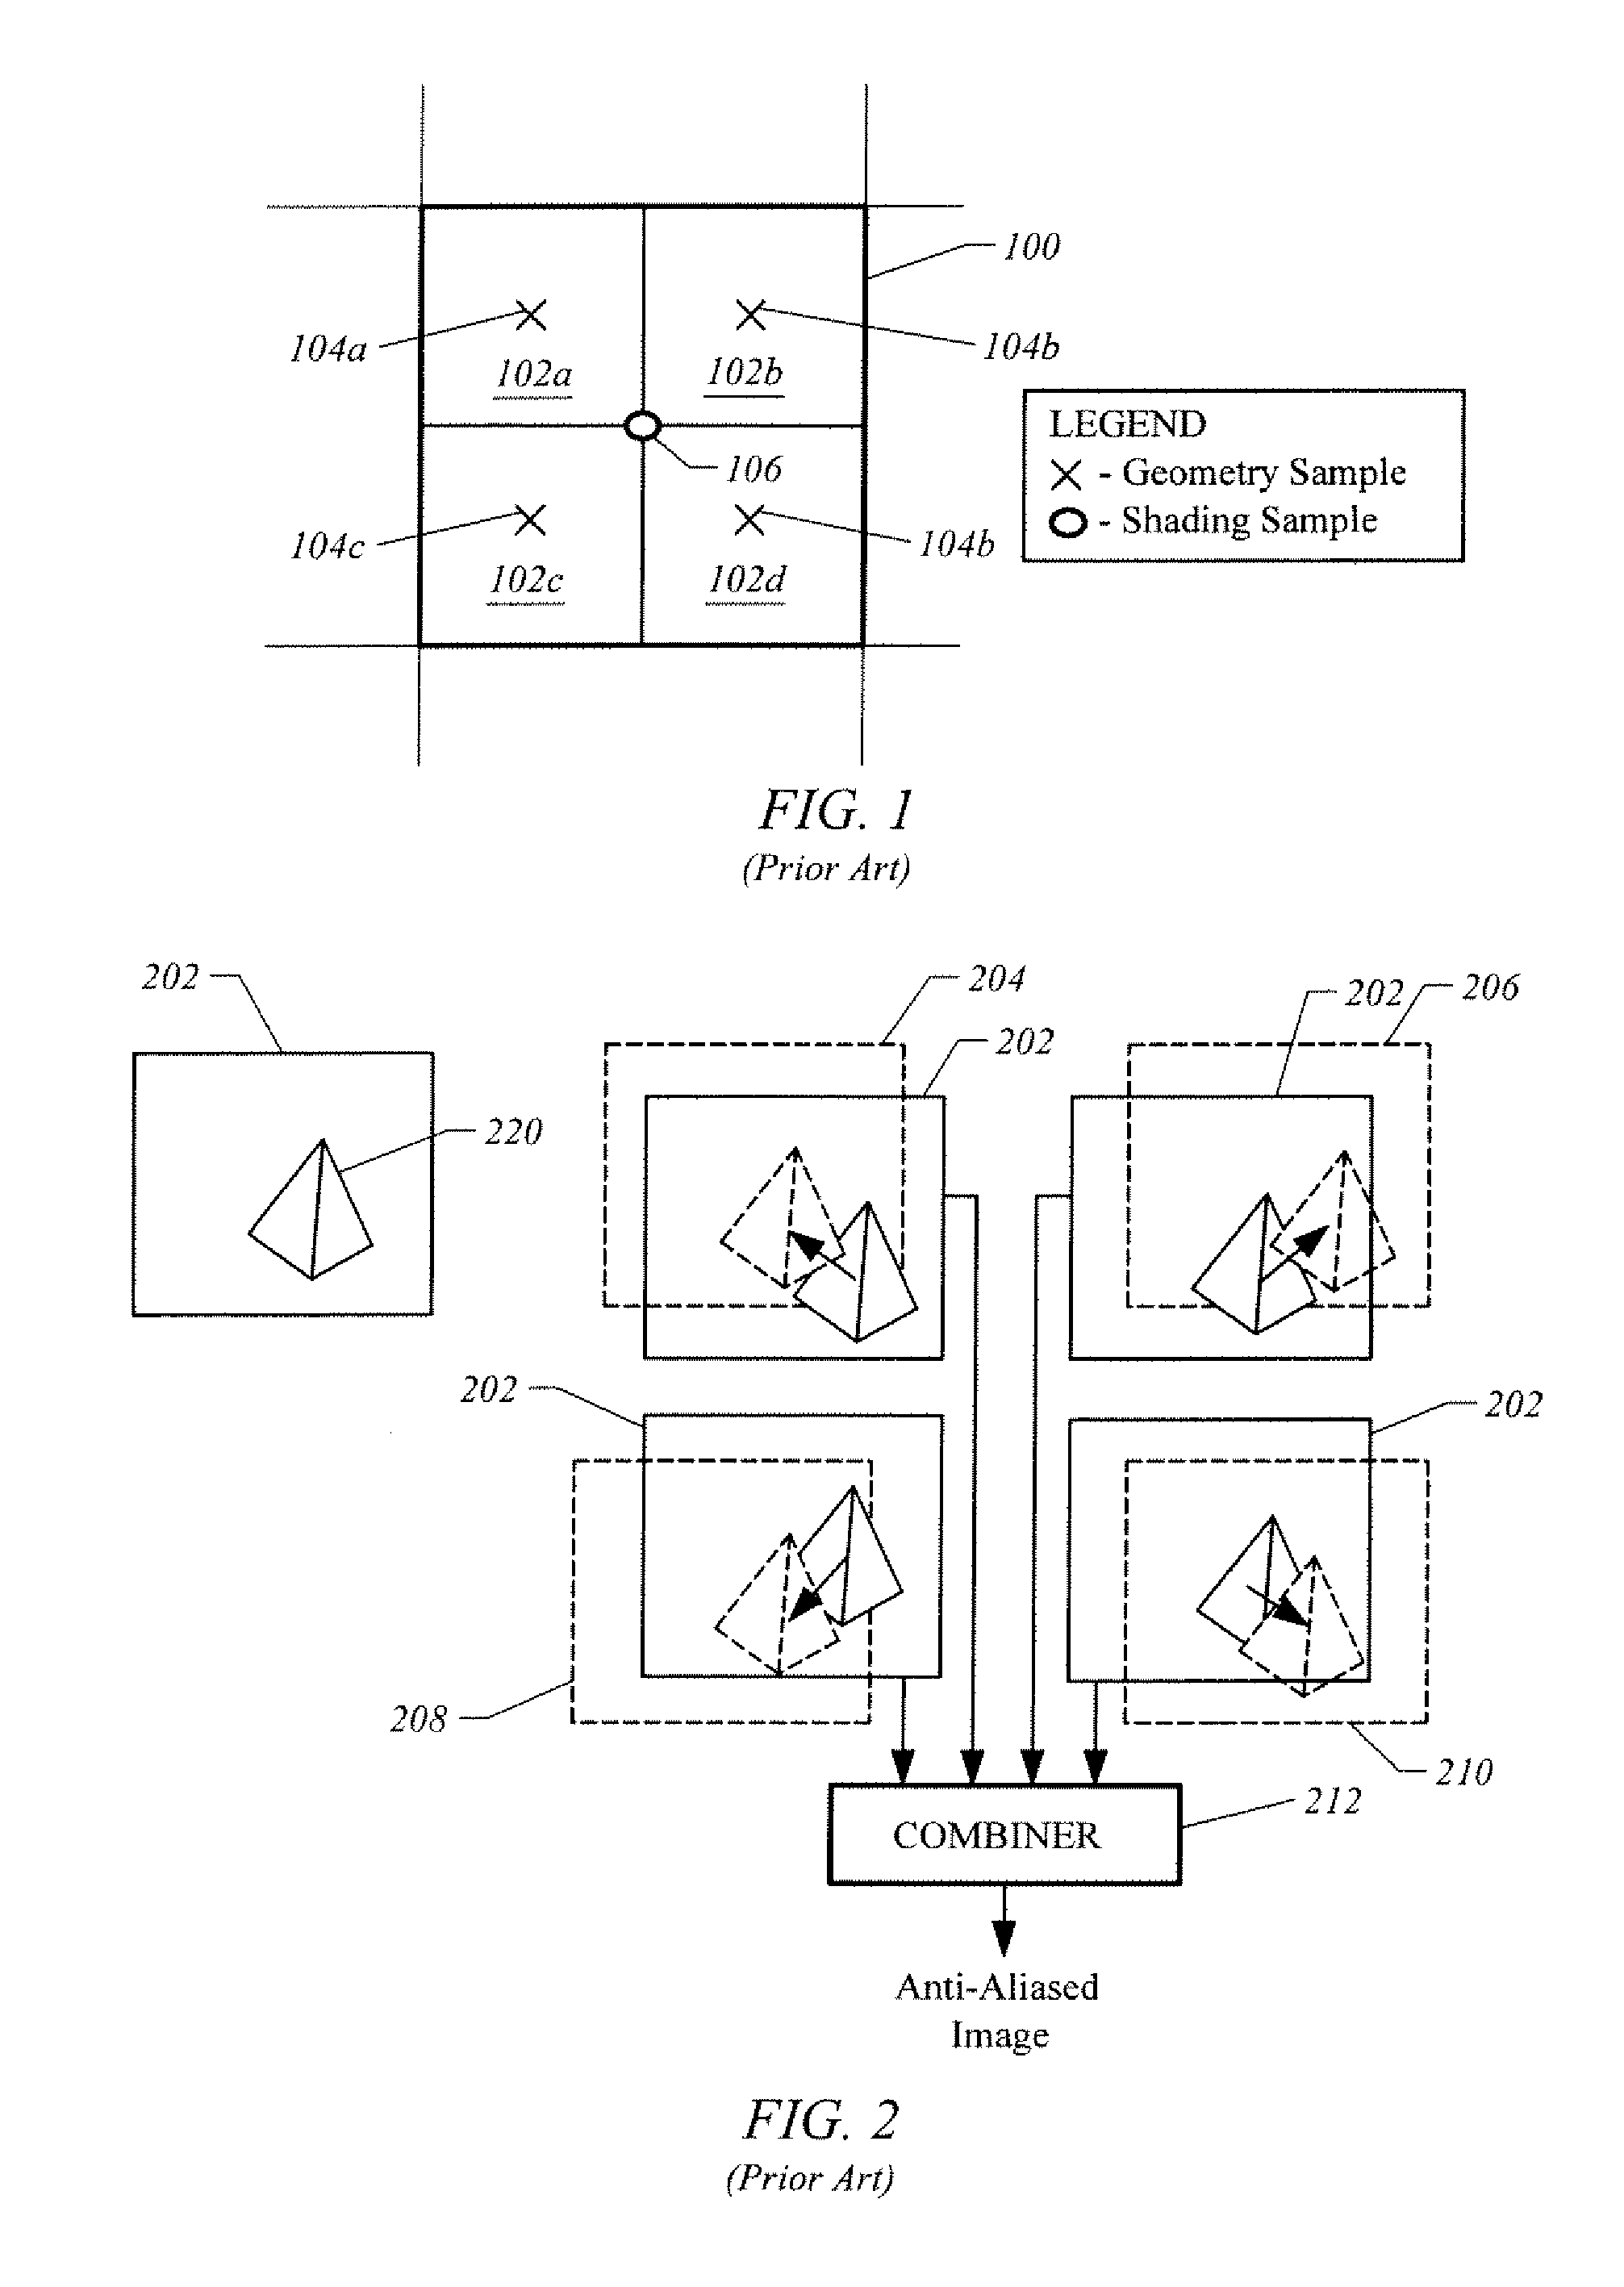
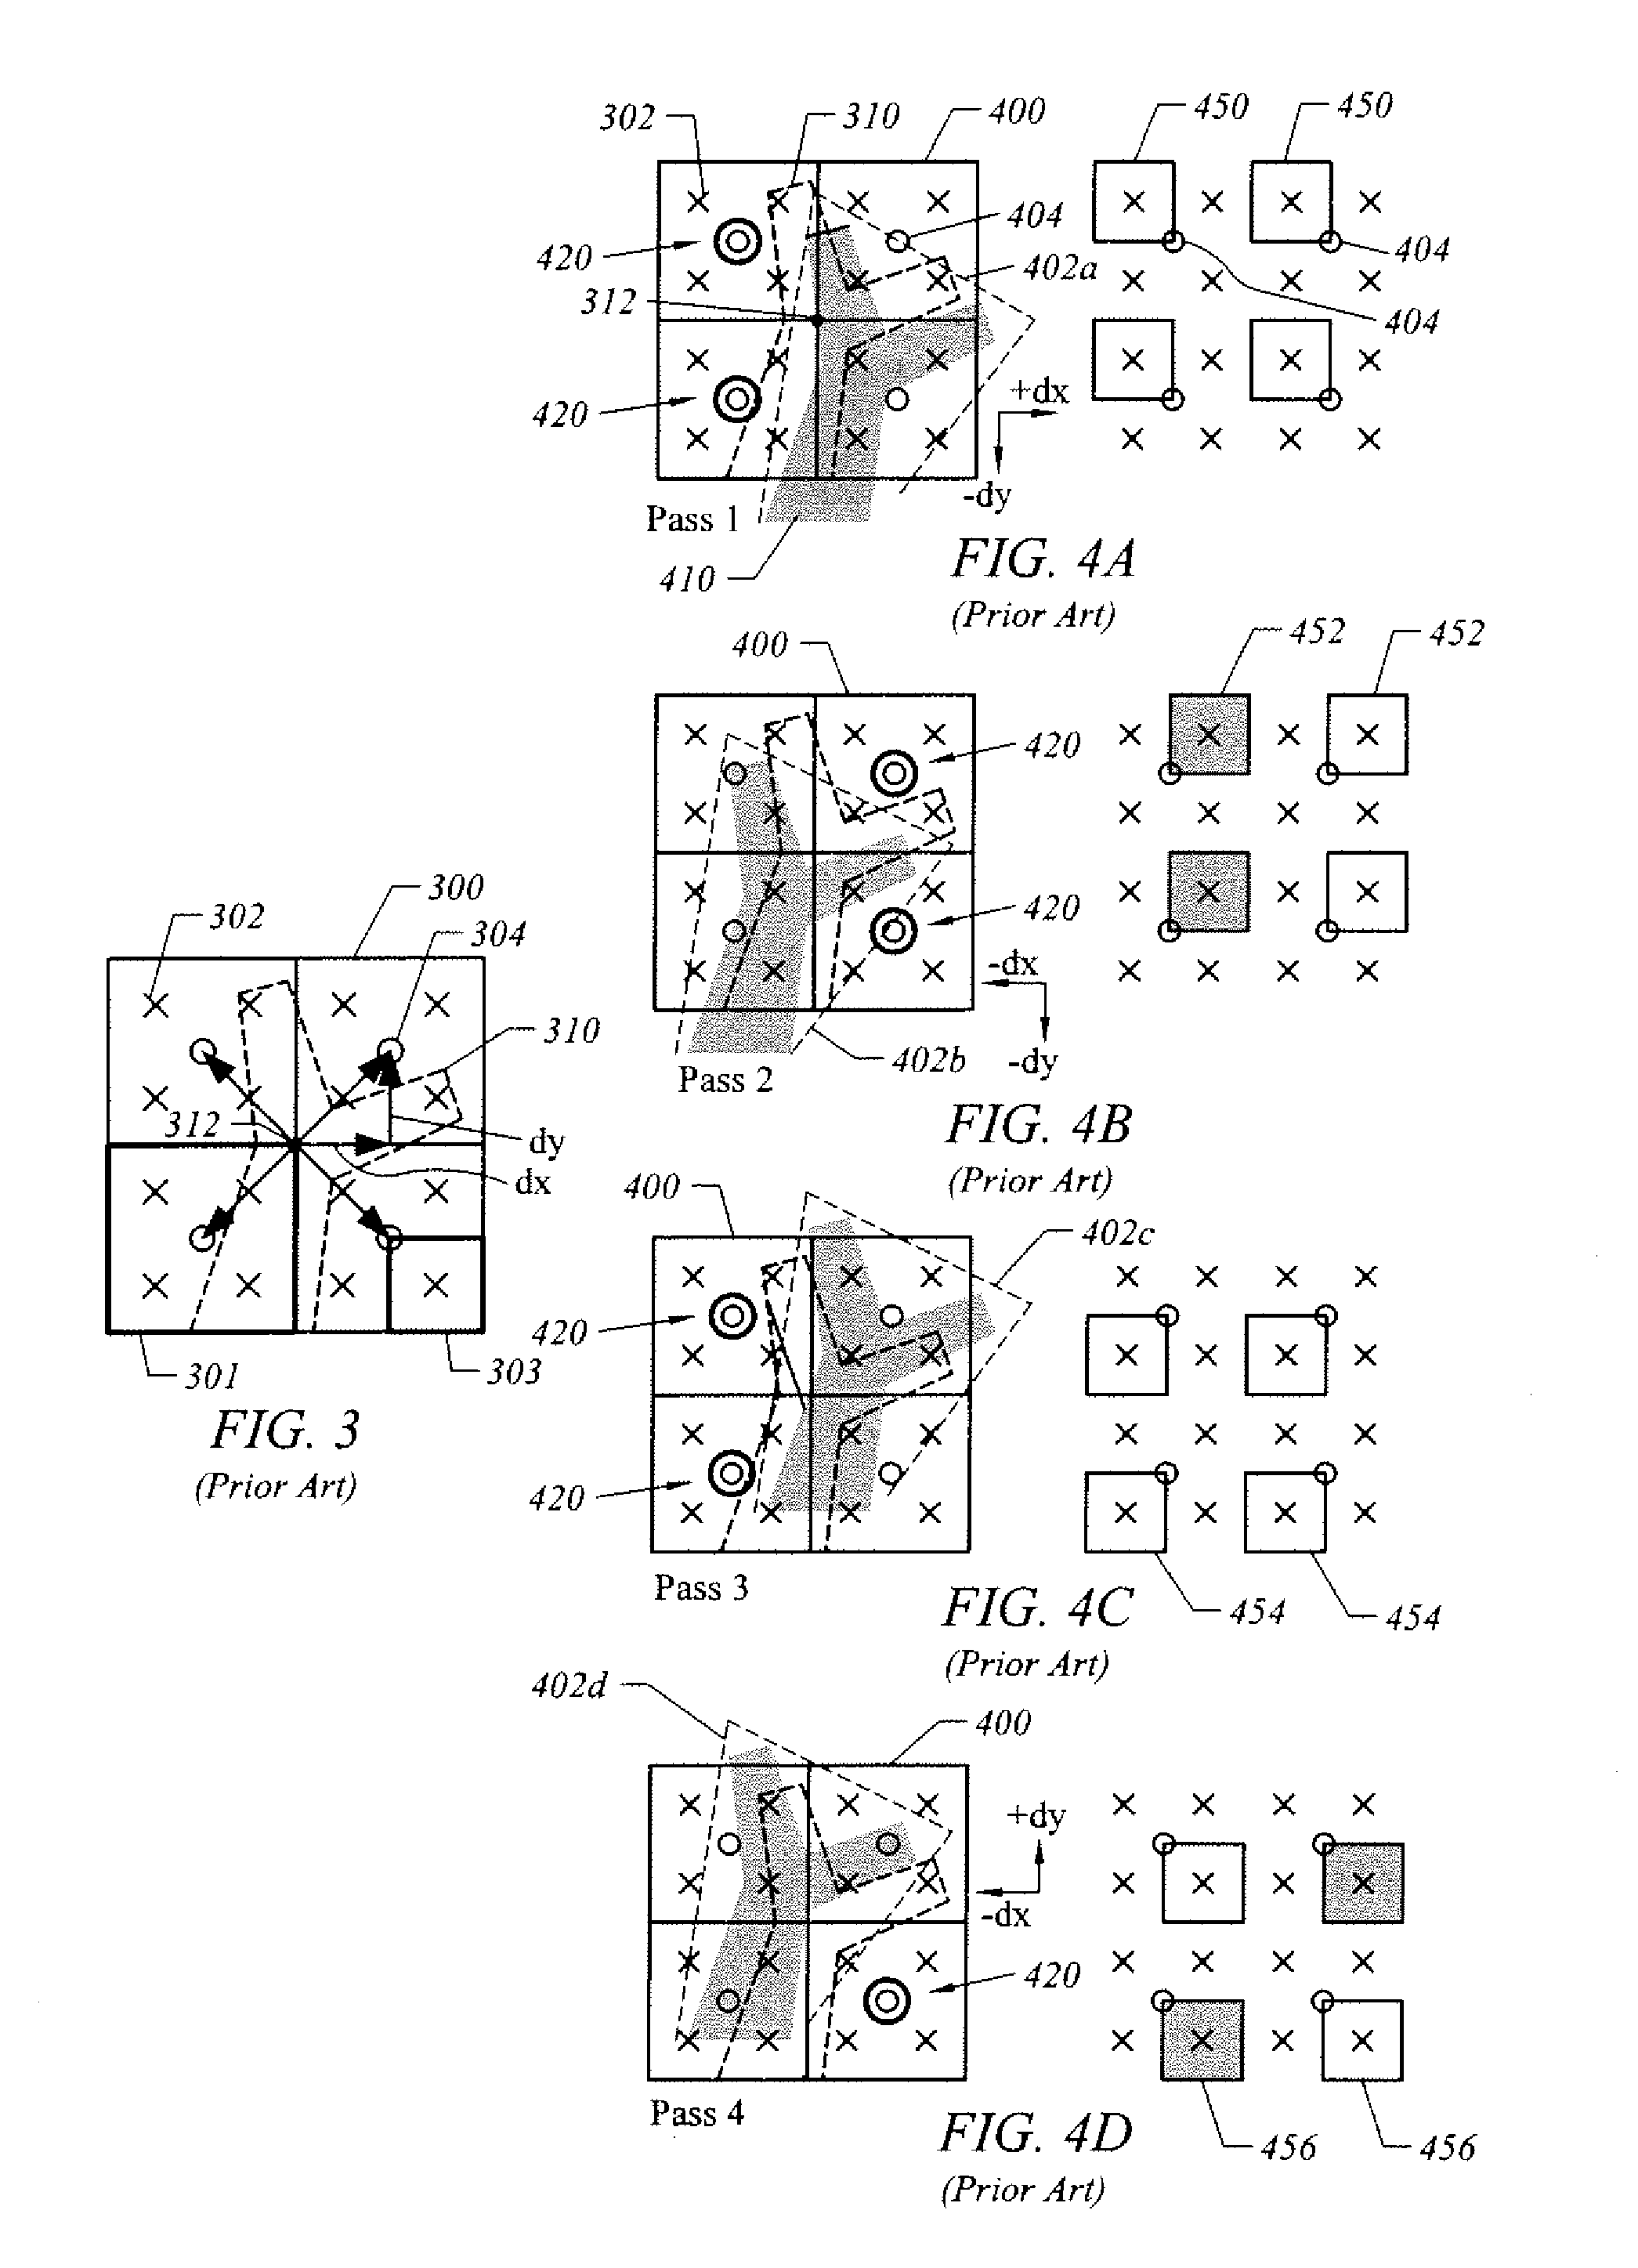
A system, apparatus, and method are disclosed for modifying positions of sample positions for selectably oversampling pixels to anti-alias non-geometric portions of computer-generated images, such as texture, at least in part, by shifting shading sample positions relative to a frame of reference. There is generally no relative motion between the geometries and the coverage sample positions. In one embodiment, an apparatus, such as a graphics pipeline and / or a general purpose graphics processing unit, anti-aliases geometries of a computer-generated object. The apparatus includes at least a texture unit and a pipeline front end unit to determine geometry coverage and a subpixel shifter to shift shading sample positions relative to the frame of reference. The apparatus can receive subpixel shifting masks to select subsets of shading sample positions. Each of the shading sample positions is shifted to a coverage sample position to reduce level of detail (“LOD”) artifacts.
Owner:NVIDIA CORP
Cryptographic computations on general purpose graphics processing units
ActiveUS7746350B1Release resourcesFaster and efficient performanceUnauthorized memory use protectionHardware monitoringGeneral purposeGeneral purpose graphic processing unit
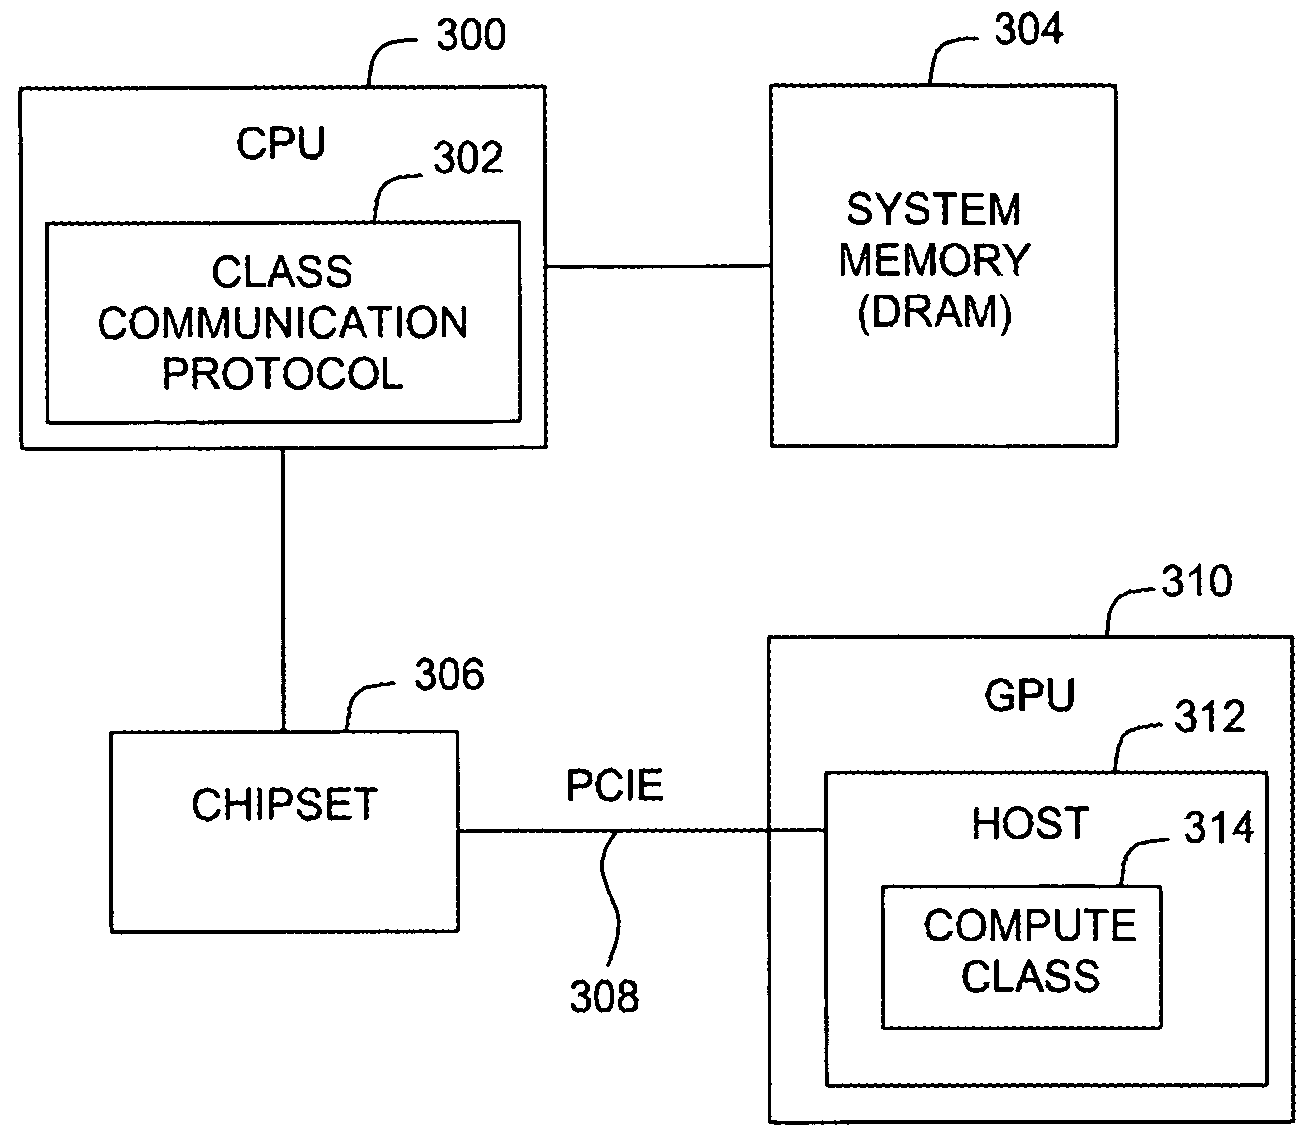
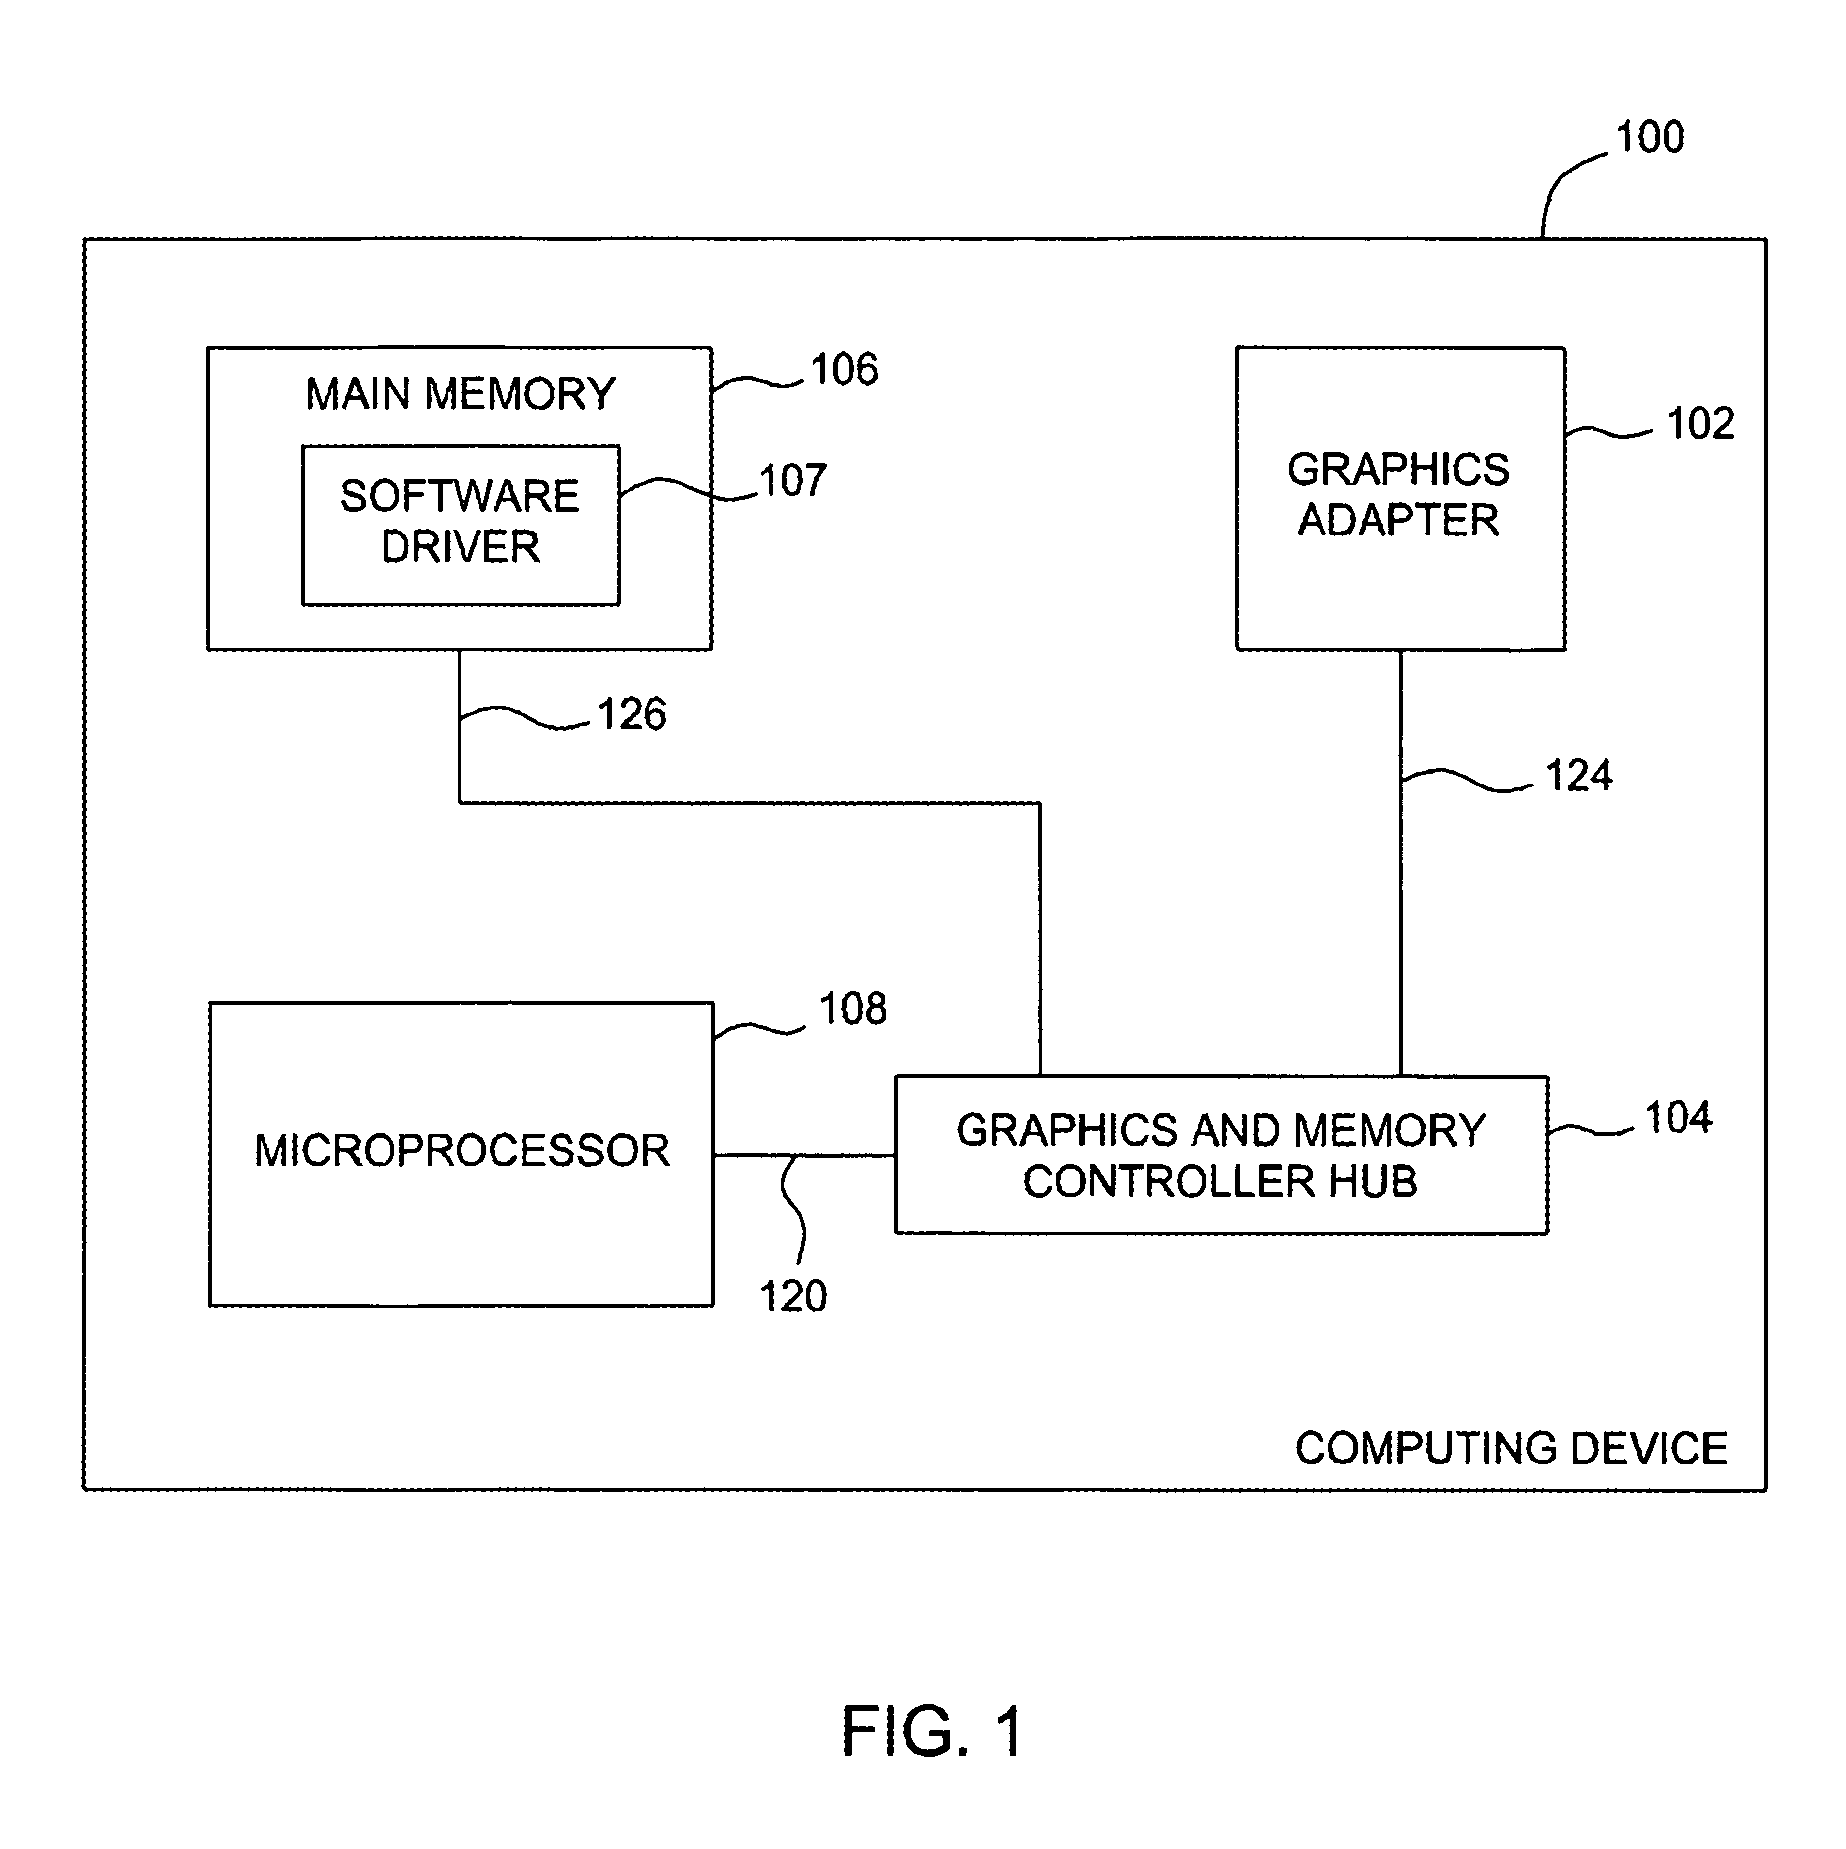
One embodiment of the invention sets forth a computing system for performing cryptographic computations. The computing system comprises a central processing unit, a graphics processing unit, and a driver. The central processing requests a cryptographic computation. In response, the driver downloads microcode to perform the cryptographic computation to the graphics processing unit and the graphics processing unit executes microcode. This offloads cryptographic computations from the CPU. As a result, cryptographic computations are performed faster and more efficiently on the GPU, freeing resources on the CPU for other tasks.
Owner:NVIDIA CORP
Implementation method, system and device for virtualization of universal graphic processor
ActiveCN102541618AImplement virtualizationProcessor architectures/configurationSoftware simulation/interpretation/emulationGeneral purposeGraphics
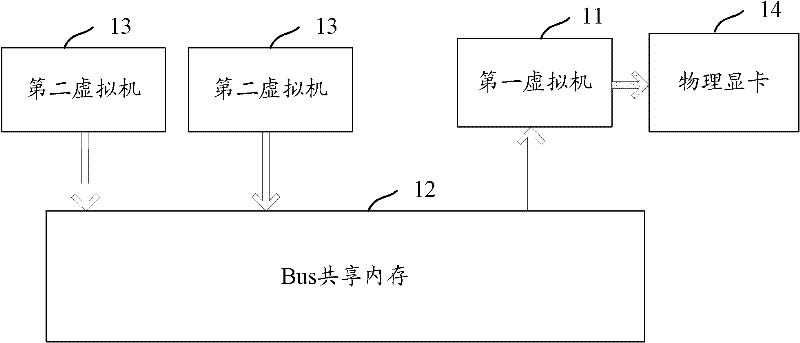
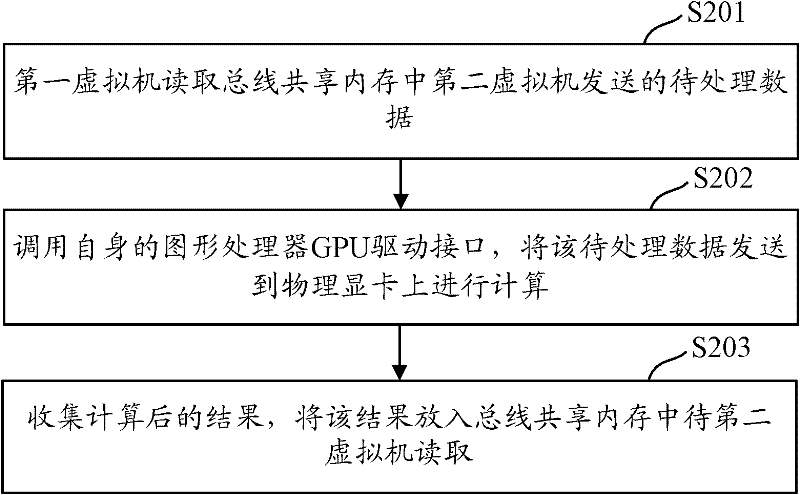
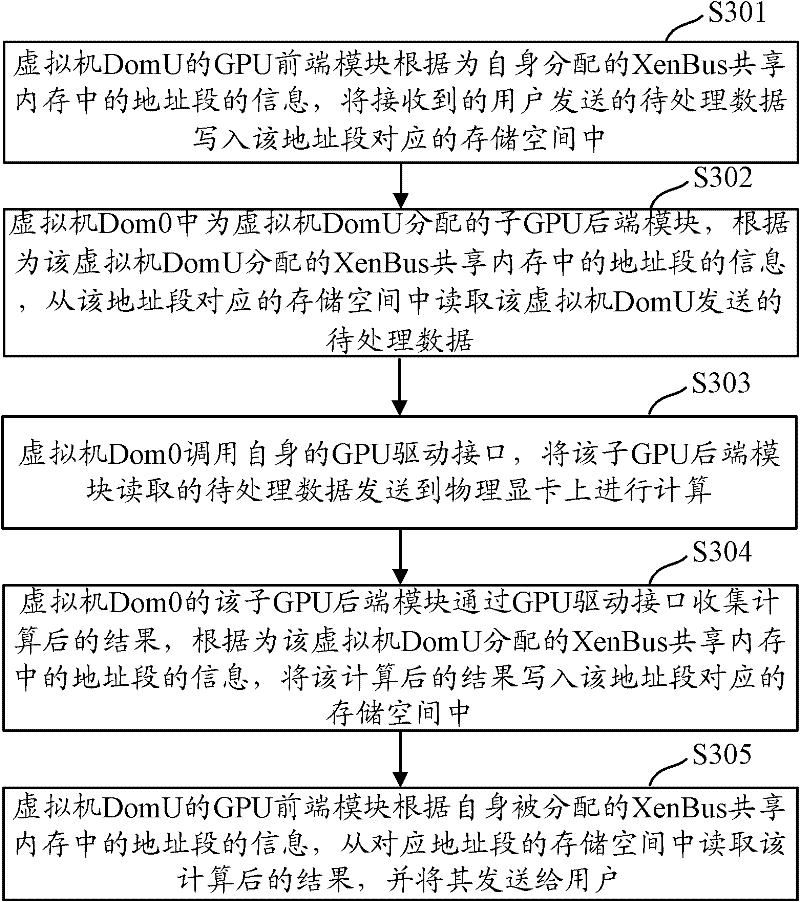
The invention discloses an implementation method, system and device for the virtualization of a GPGPU (General Purpose Graphics Processing Unit) to solve the problem that the virtualization of the GPGPU cannot be solved in the prior art. The implementation method comprises the following steps: a first virtual machine reads data to be processed in a shared memory of a bus, wherein the data to be processed is written by a second virtual machine; and the first virtual machine invokes a CPU (Central Processing Unit) driver interface, sends the data to be processed to a physical display card for calculation, collects calculated results, and inputs the results in the shared memory of the bus to be read by the second virtual machine. As the first virtual machine can visit the physical display card, and can realize information interaction with the second virtual machine, the virtualization of the GPGPU is realized.
Owner:CHINA MOBILE COMM GRP CO LTD
Method and device for achieving multi-application parallel processing on single processors
ActiveCN103064657AResource allocationConcurrent instruction executionHardware threadComputer architecture
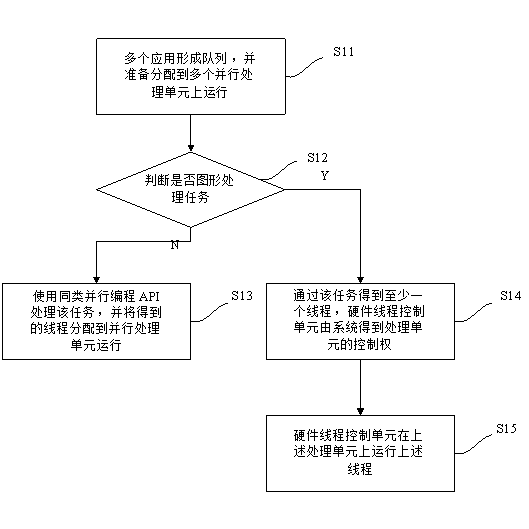
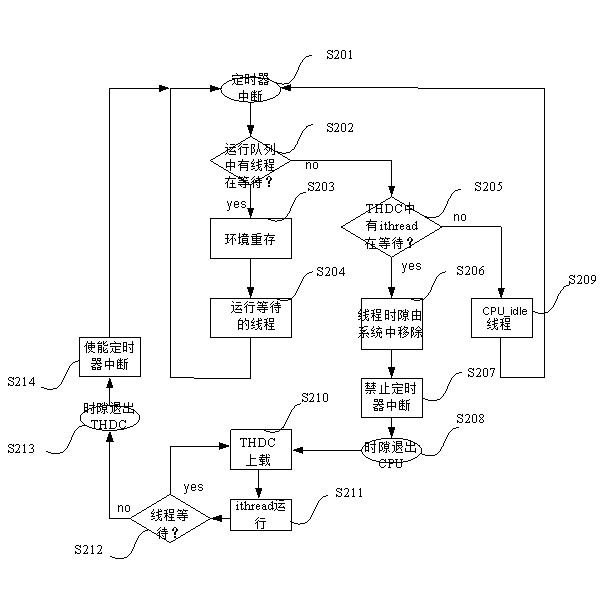
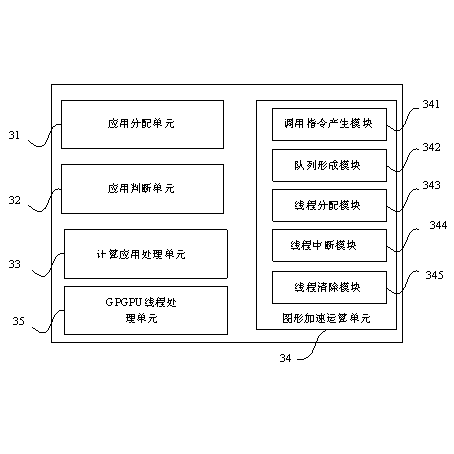
The invention relates to a method for achieving multi-application parallel processing on single processors such as a graphics processing unit (GPU) and a general purpose graphics processing units (GPGPU). The method comprises the steps of respectively enabling a plurality of applications to form queues and be prepared to be distributed to a plurality of parallel processing units to perform parallel running; respectively judging whether the plurality of applications are image rendering applications, and if the plurality of applications are the image rendering applications, generating at least one coloring thread to a hardware thread control unit through the applications, and starting rendering on the processing units controlled by a hardware manager by GPU driving; or else, using a homogeneous parallel programming application programming interface (API) to process at least one thread generated by the applications, and configuring the processed thread to the processing units serving as symmetrical multi processing (SMP) cores so as to run. The invention further relates to a device for achieving the method. The method and device for achieving multi-application parallel processing on the single processors have the advantage that two or more different kinds of applications can be processed simultaneously on one processor.
Owner:SHENZHEN ZHONGWEIDIAN TECH
Method and system for processing OCT (Optical Coherence Tomography) signal by using general purpose graphic processing unit
InactiveCN104794740AEvenly distributedIncreased maximum imaging depthBalloon catheter2D-image generationDigital signal processingOriginal data
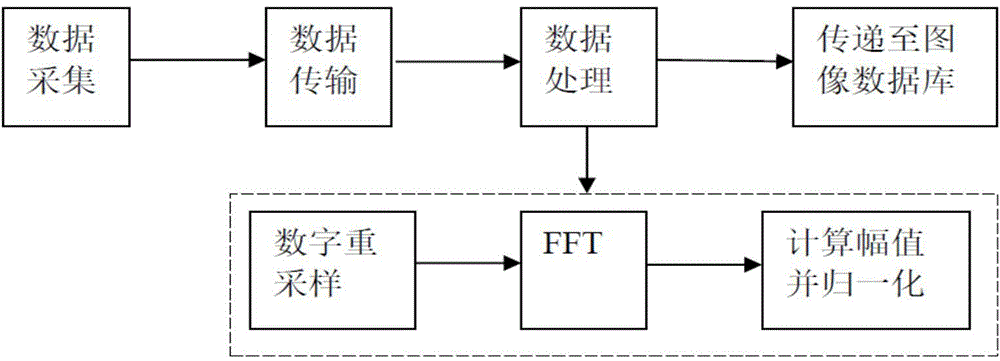
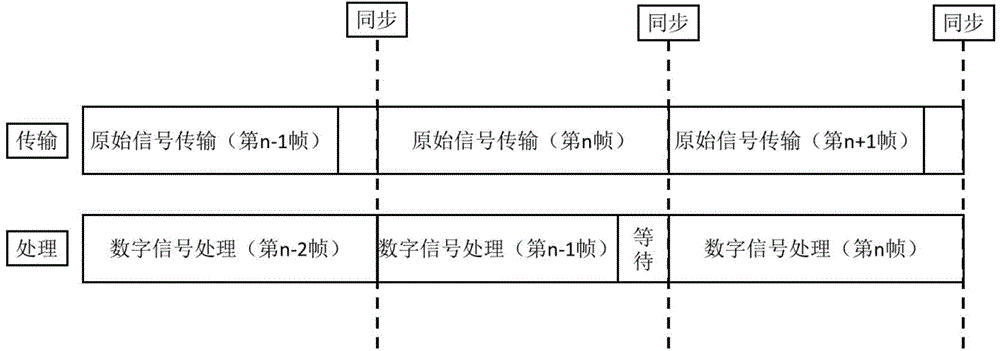
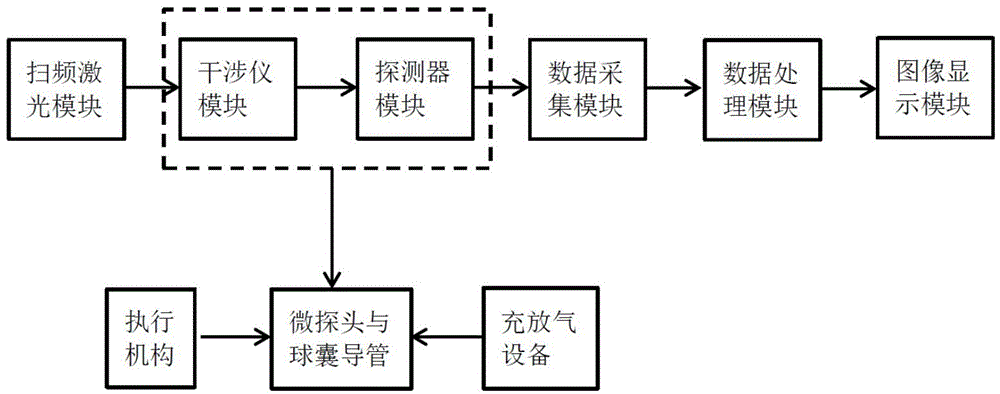
The invention provides a method or processing an OCT (Optical Coherence Tomography) signal in an OCT system by using a general purpose graphic processing unit (GPGPU). The method comprises the following four steps: (1) acquiring data; (2) transmitting the data; (3) processing the data; and (4) transmitting the data to a graphic display library. When the data are transmitted, OCT original data which are transmitted to an equipment memory at the last time by the general purpose graphic processing unit are subjected to parallel processing; and the processed data are stored into the memory of the graphic display library. By virtue of the method, FD-OCT digital signal processing efficiency can be improved, and real-time processing and displaying of a graphic can be realized; the requirements and cost of digital signal processing equipment are reduced, the transportability of software is improved and the software development cost is reduced; and meanwhile, the method is in seamless combination with a current modern graphic display library so that the flexibility of software display is improved.
Owner:MICRO TECH (NANJING) CO LTD
Method and system to dynamically bind and unbind applications on a general purpose graphics processing unit
InactiveUS20120188263A1Memory adressing/allocation/relocationImage memory managementComputational scienceGeneral purpose
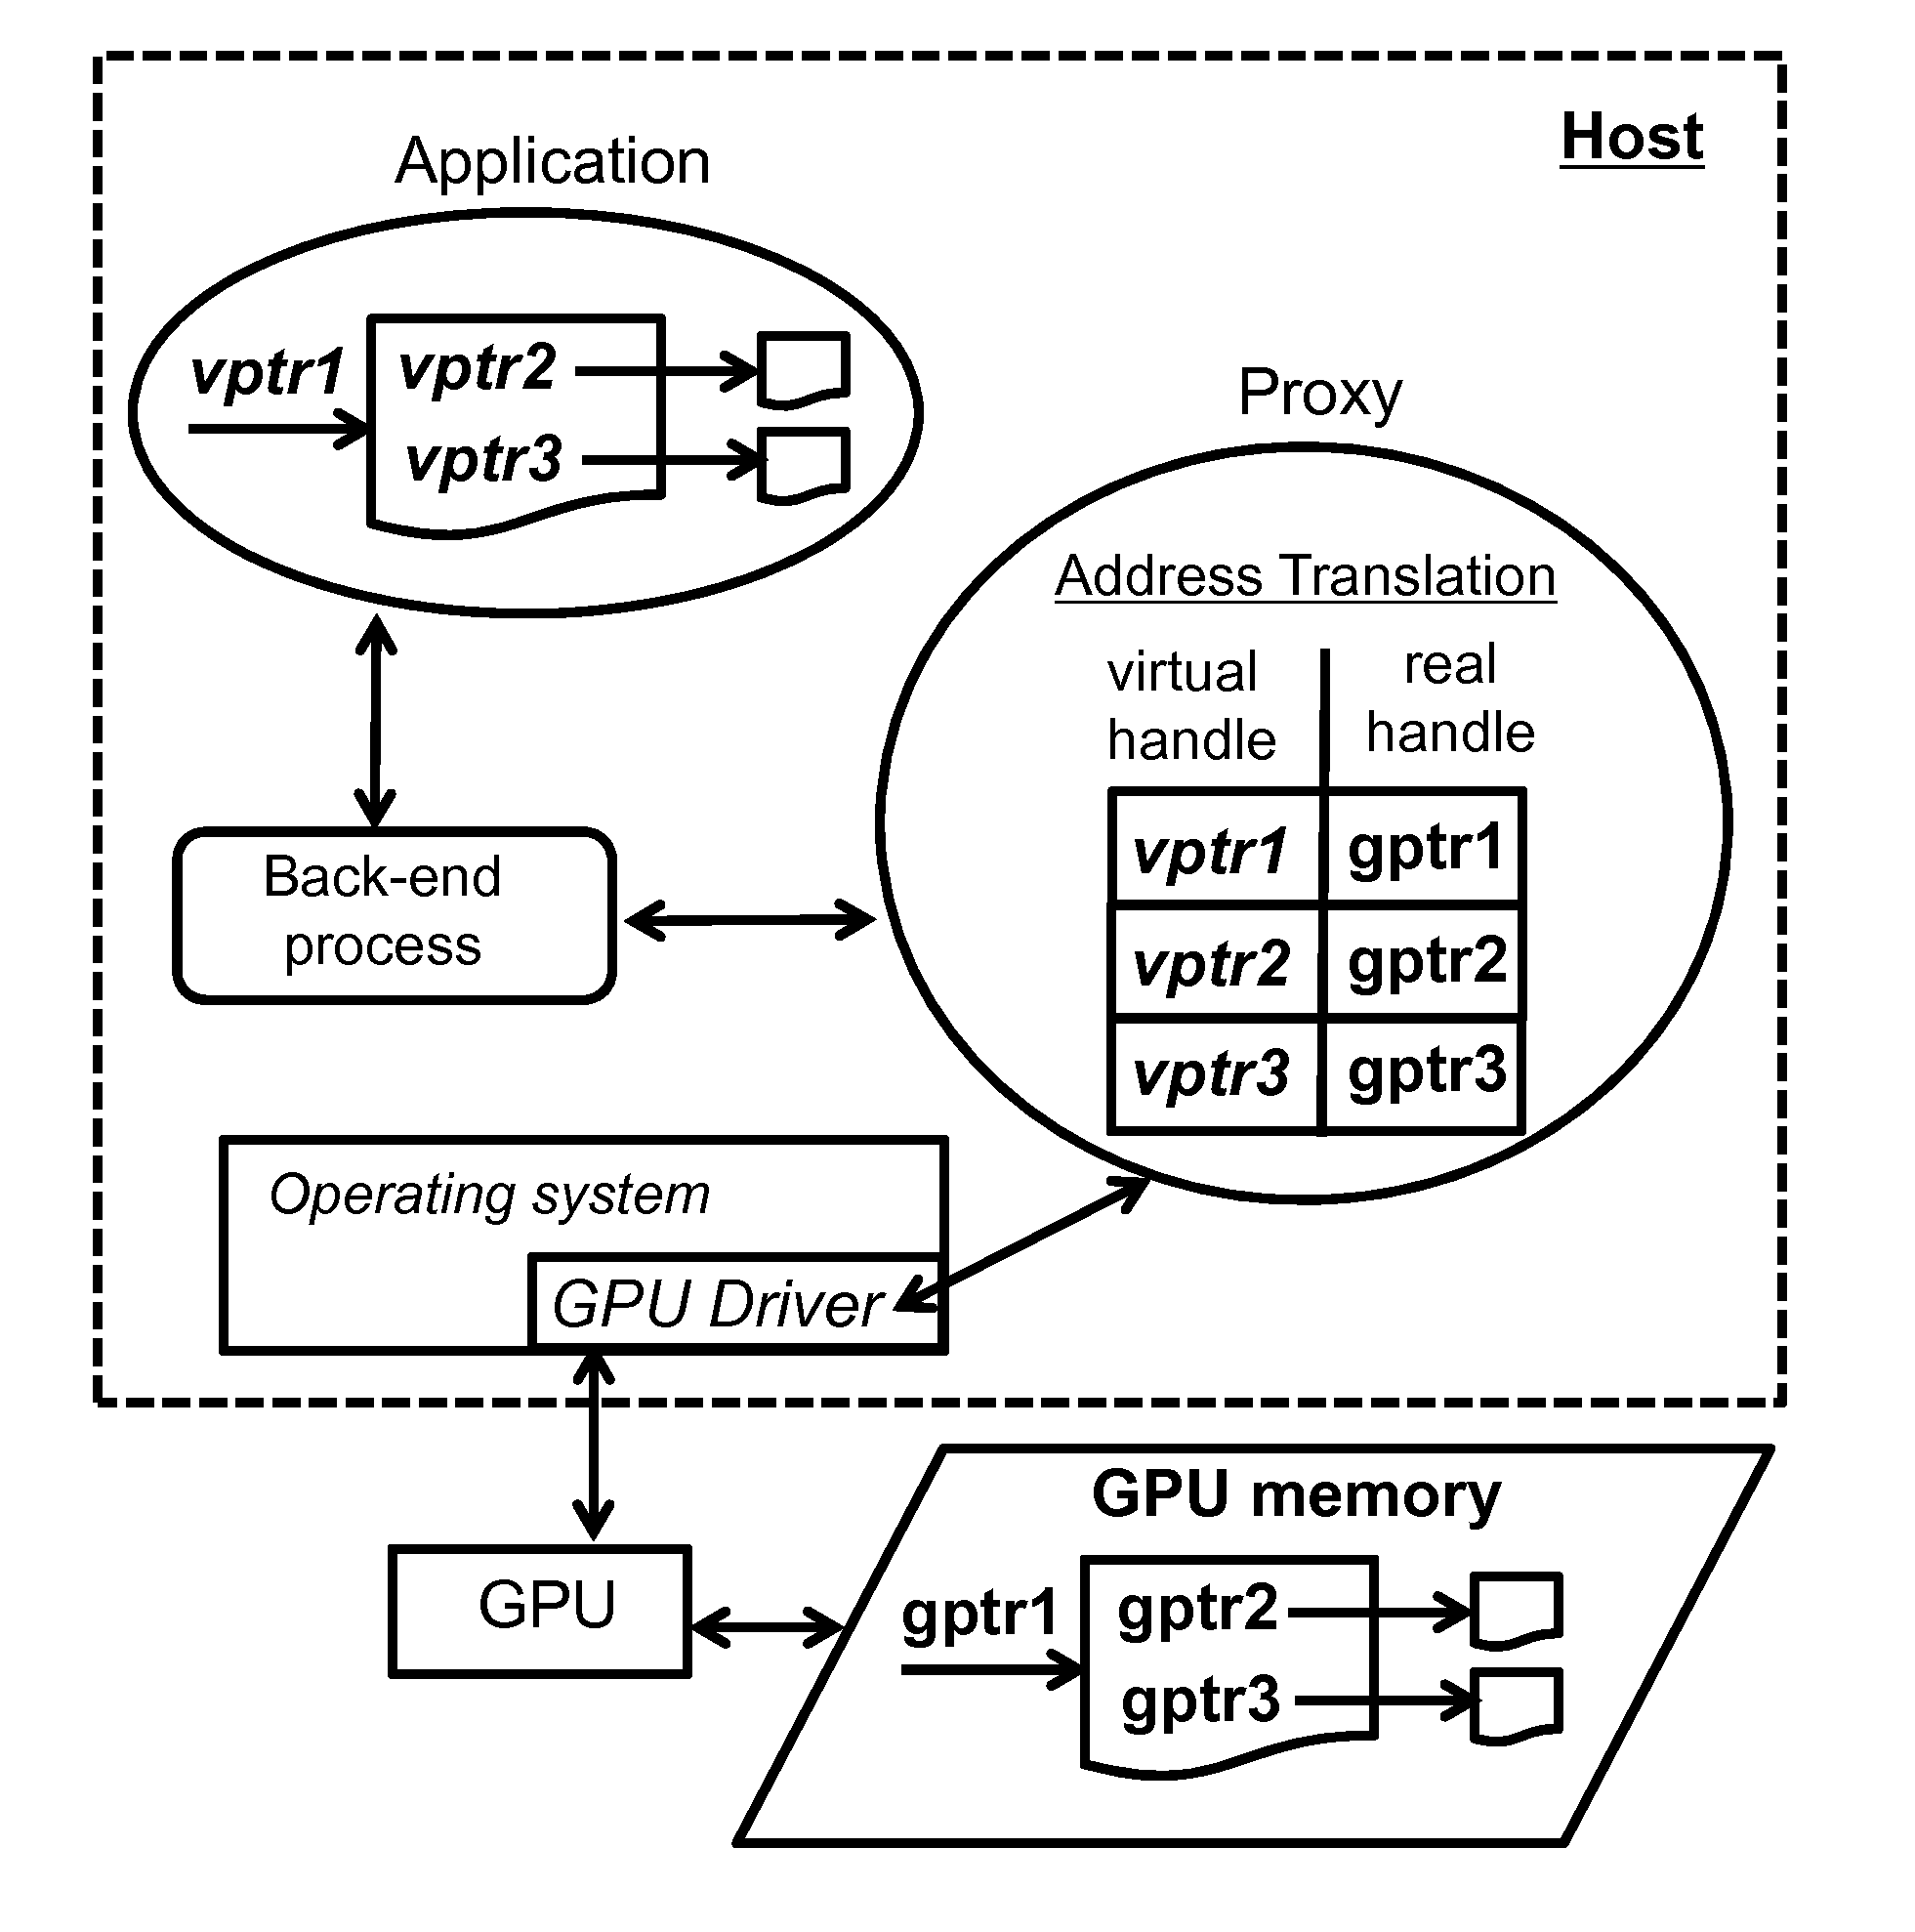
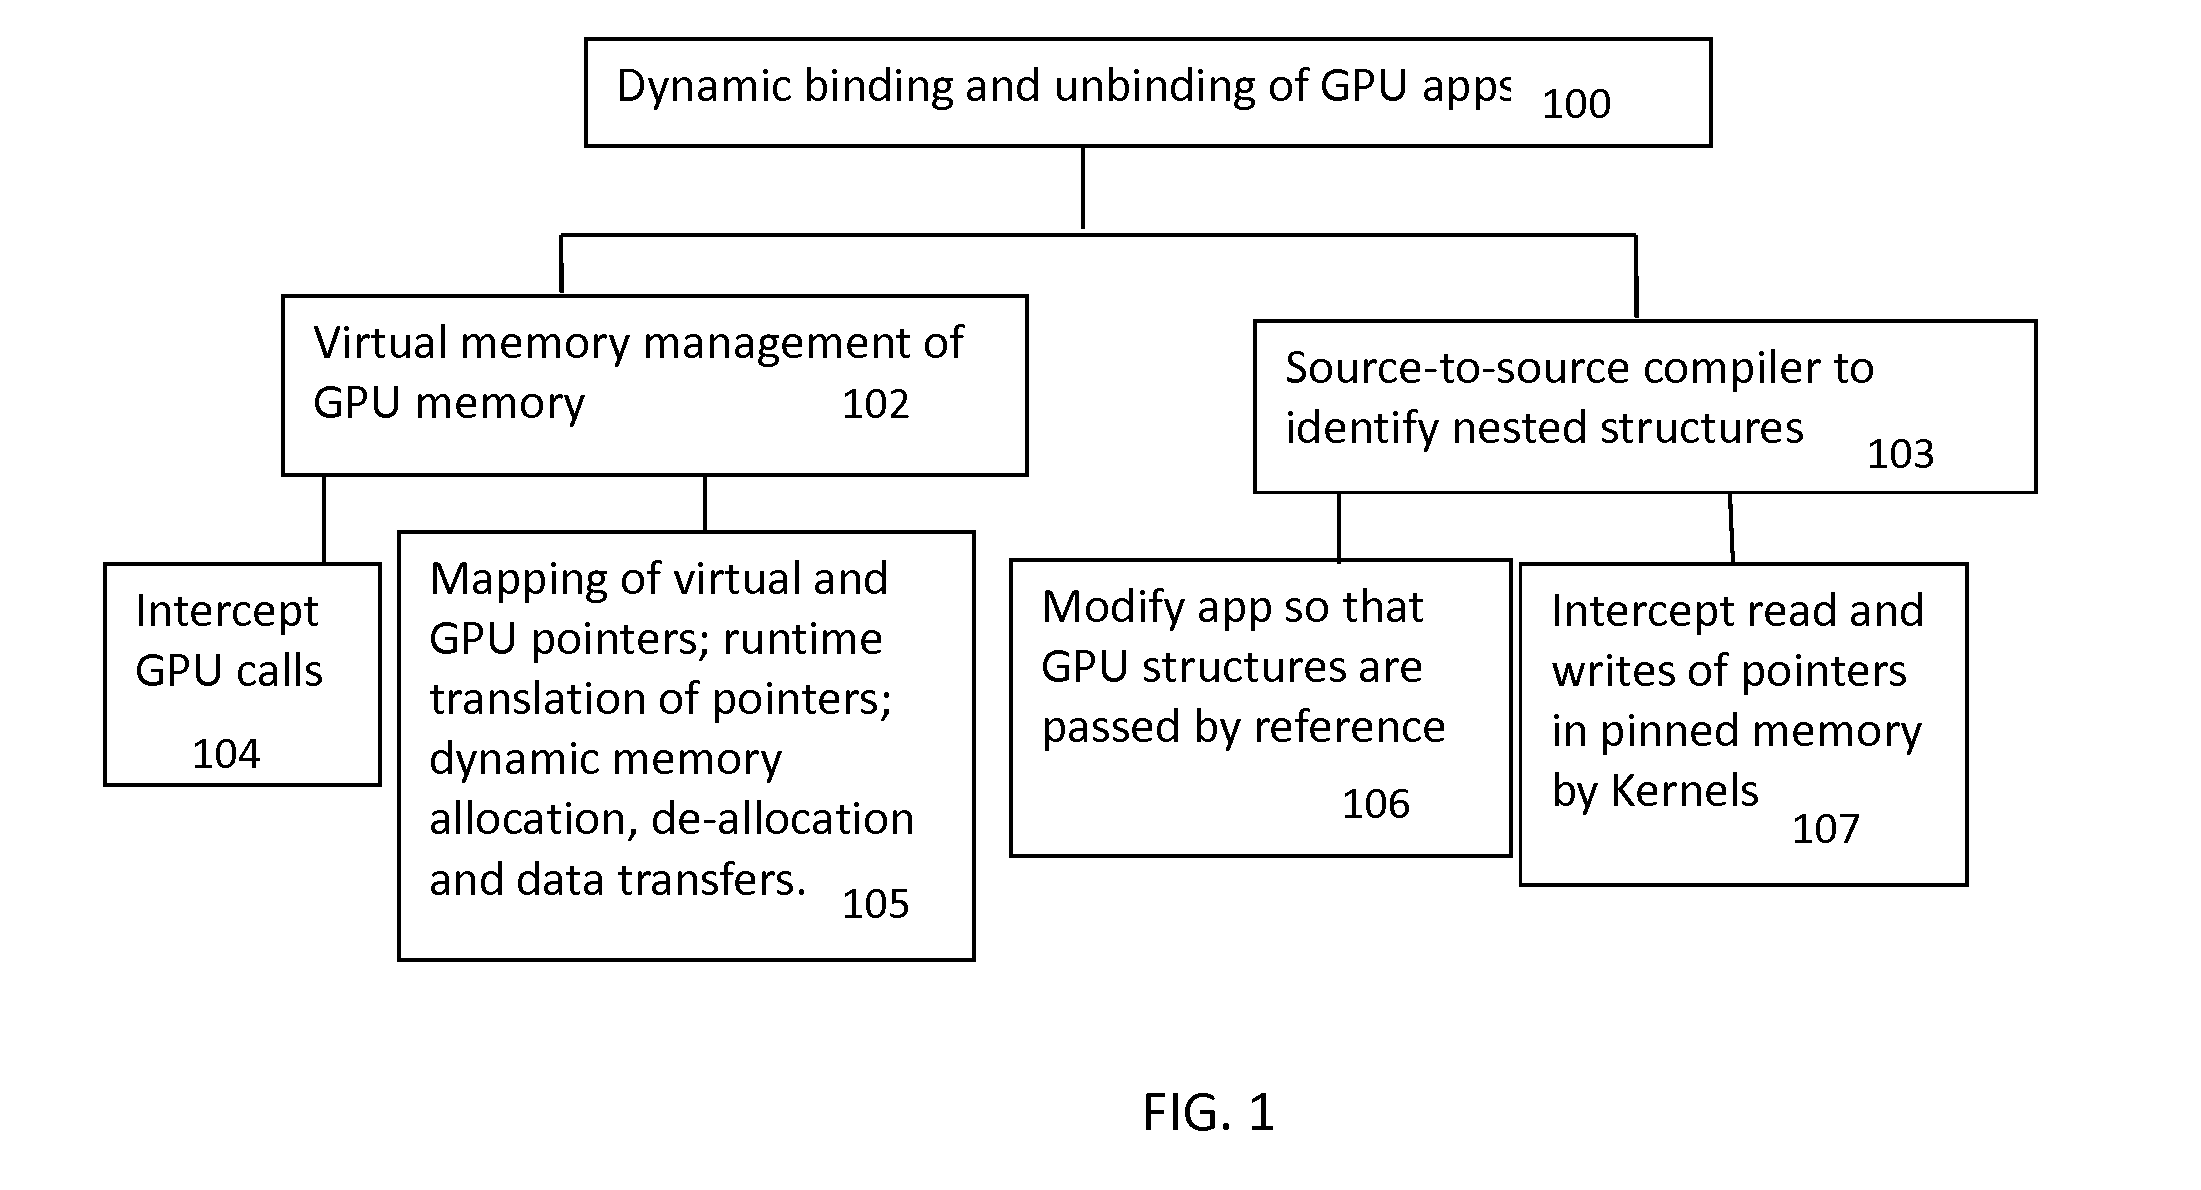
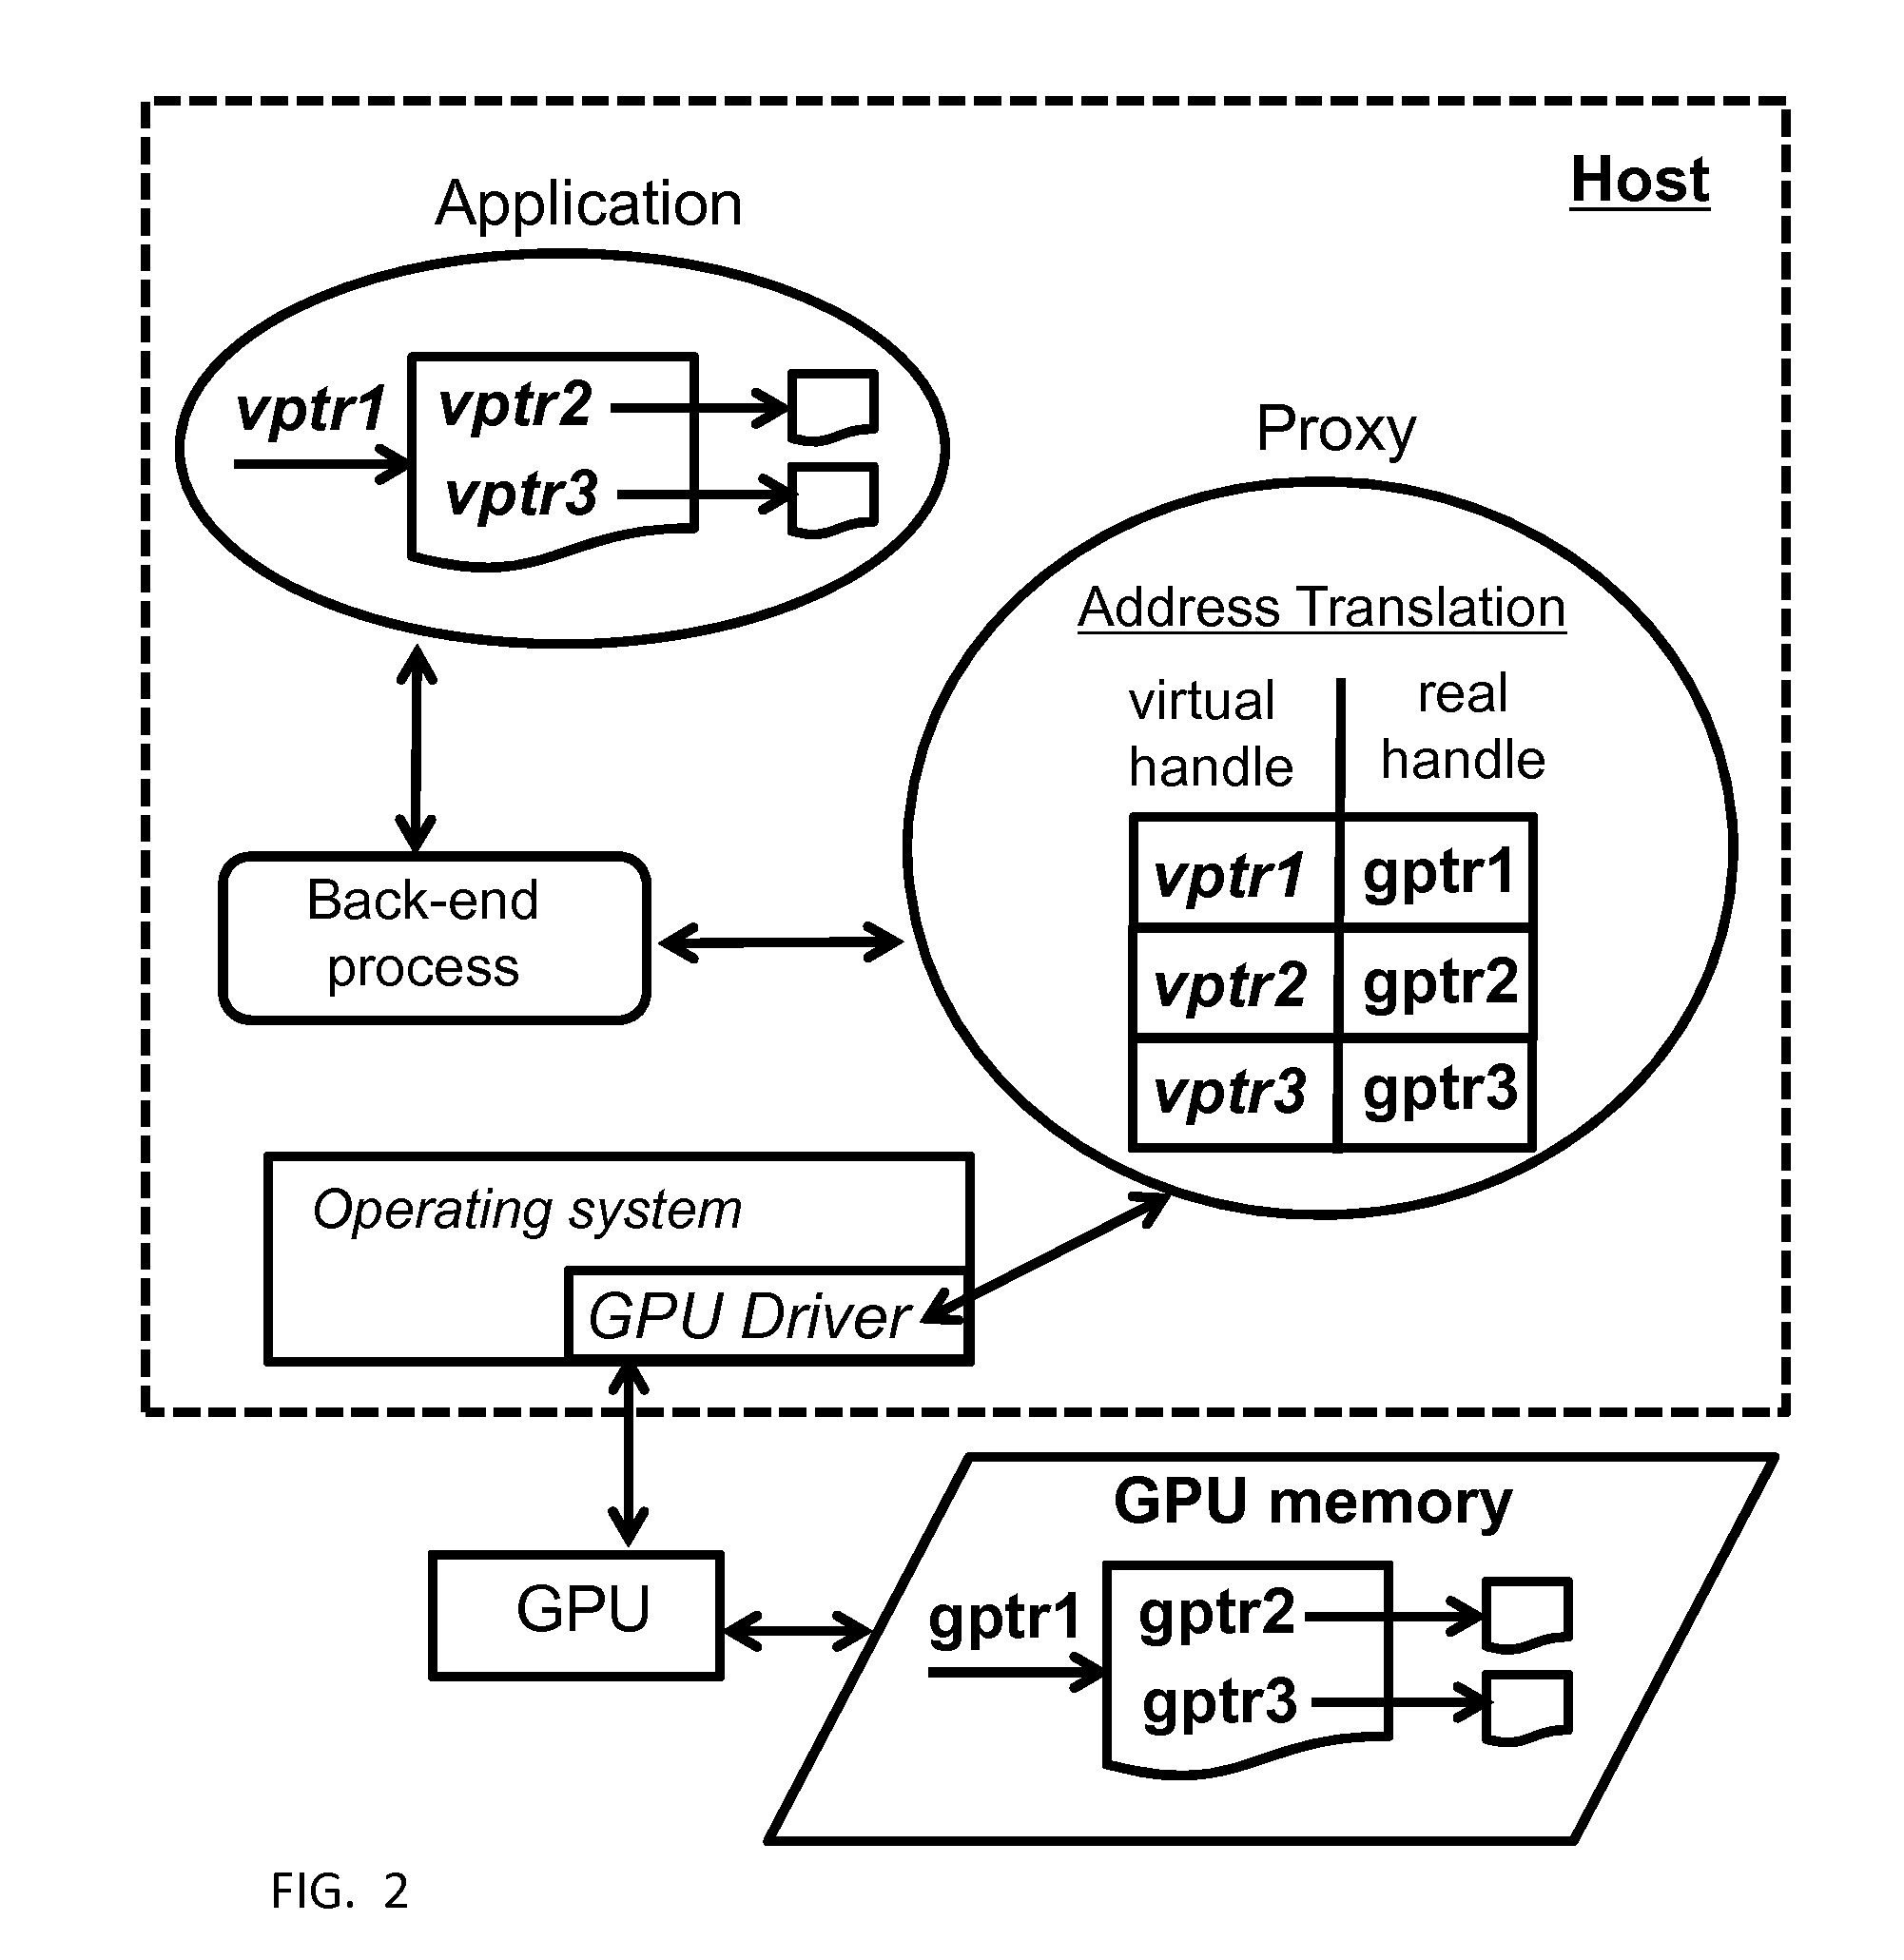
A system for dynamically binding and unbinding of graphics processing unit GPU applications, the system includes a memory management for tracking memory of a GPU used by an application, and a source-to-source compiler for identifying nested structures allocated on the GPU so that the virtual memory management can track these nested structures, and identifying all instances where nested structures on the GPU are modified inside kernels.
Owner:NEC CORP
C/c++ language extensions for general-purpose graphics processing unit
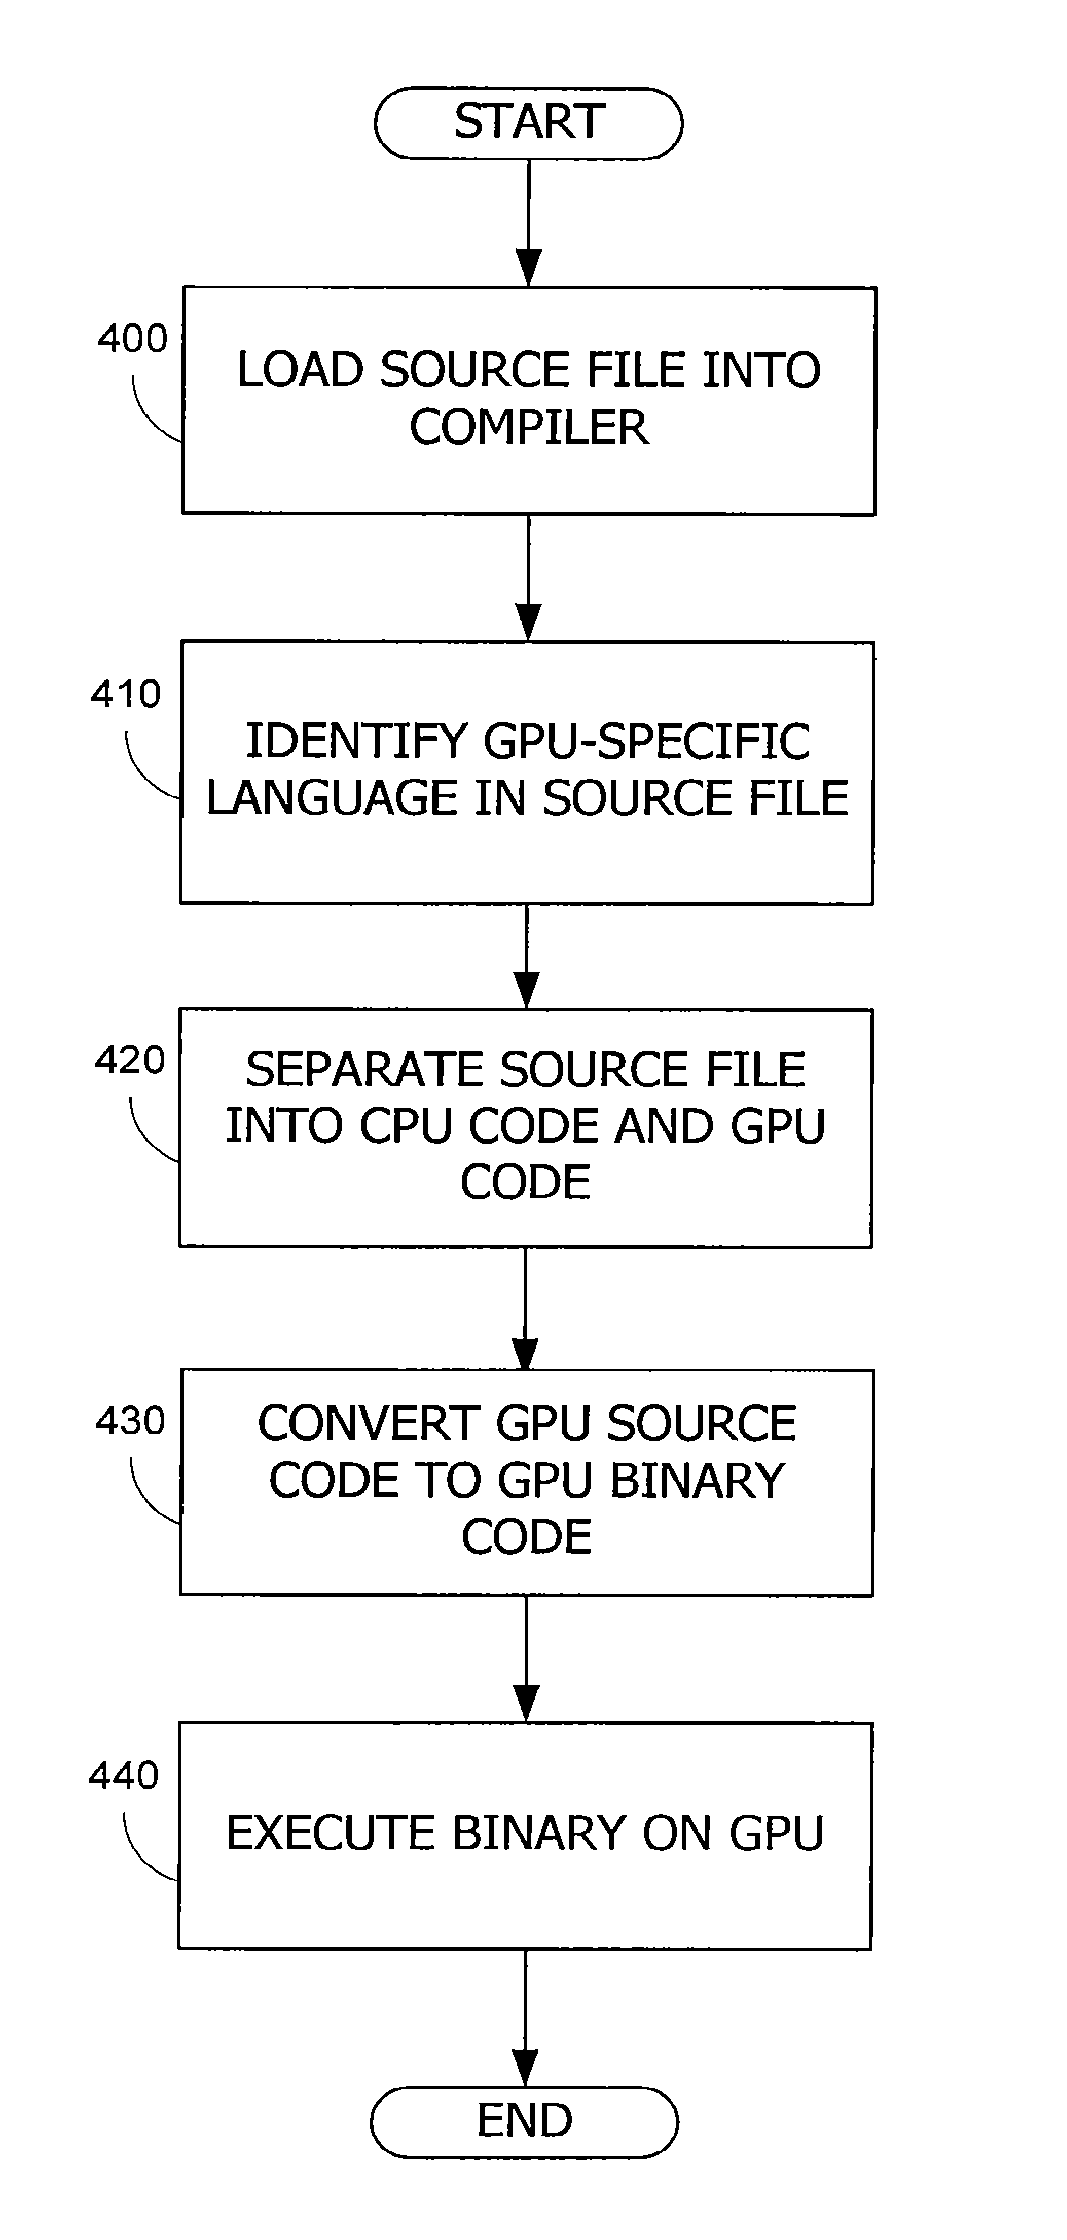
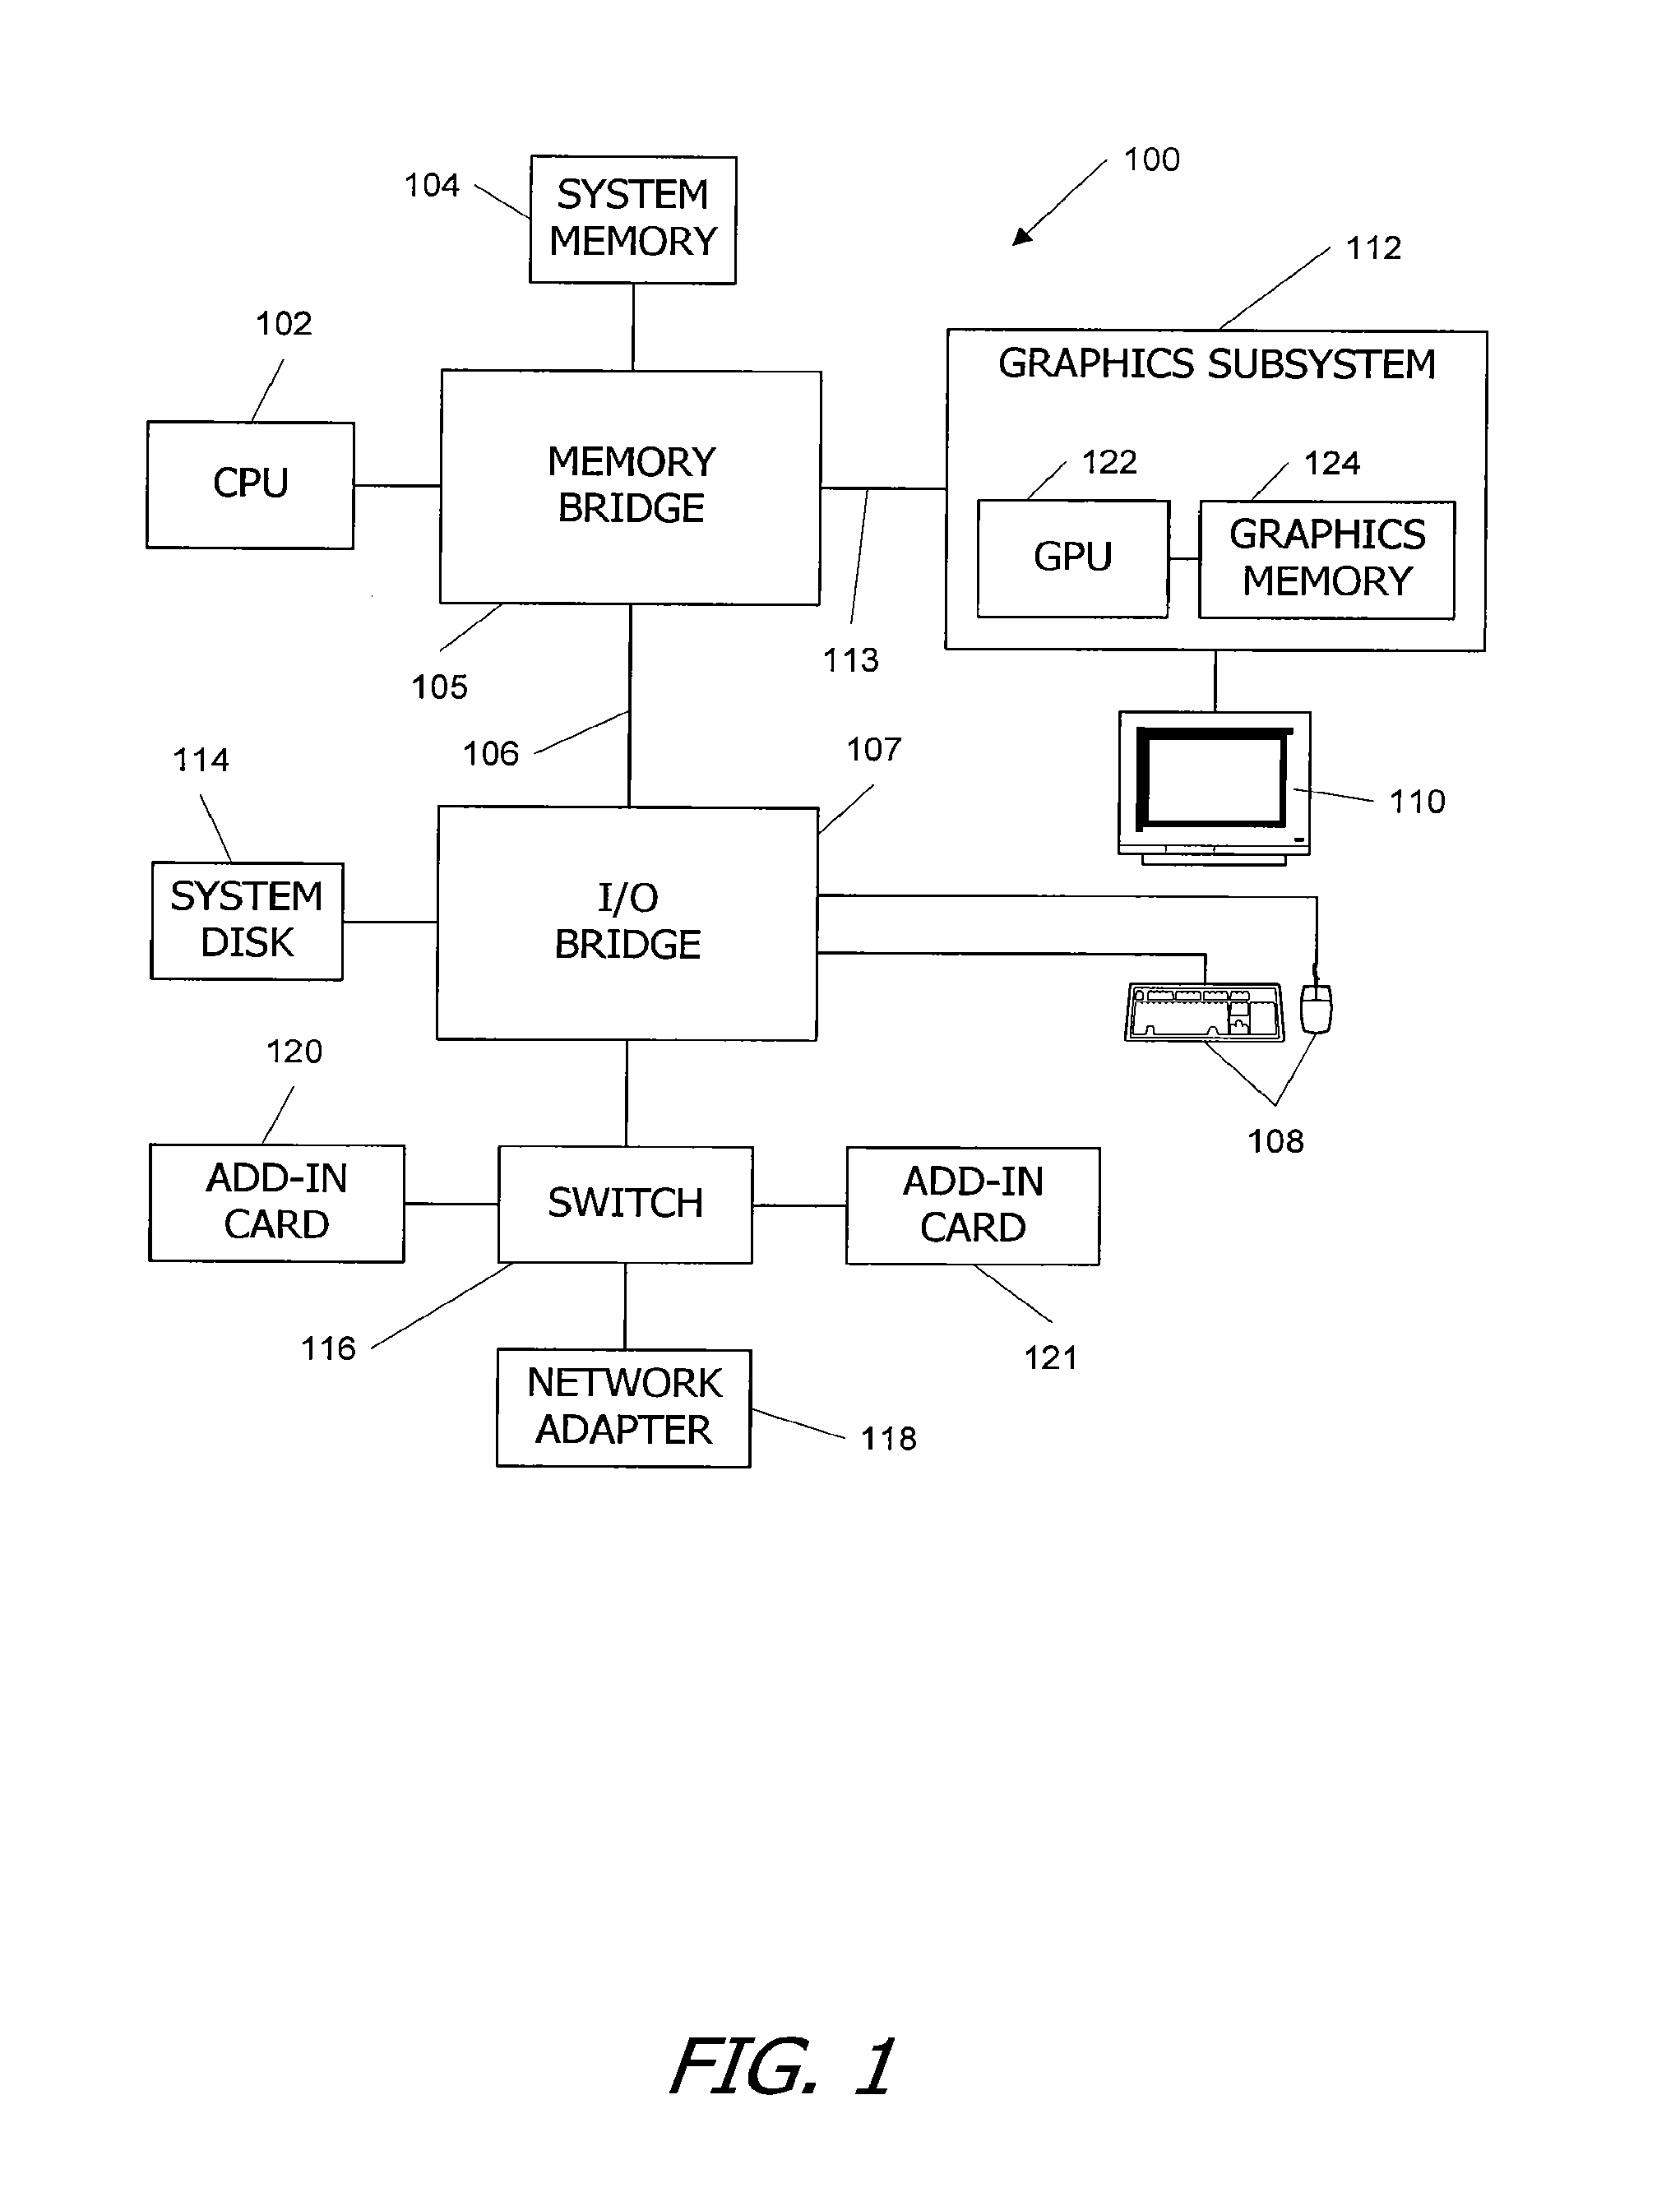
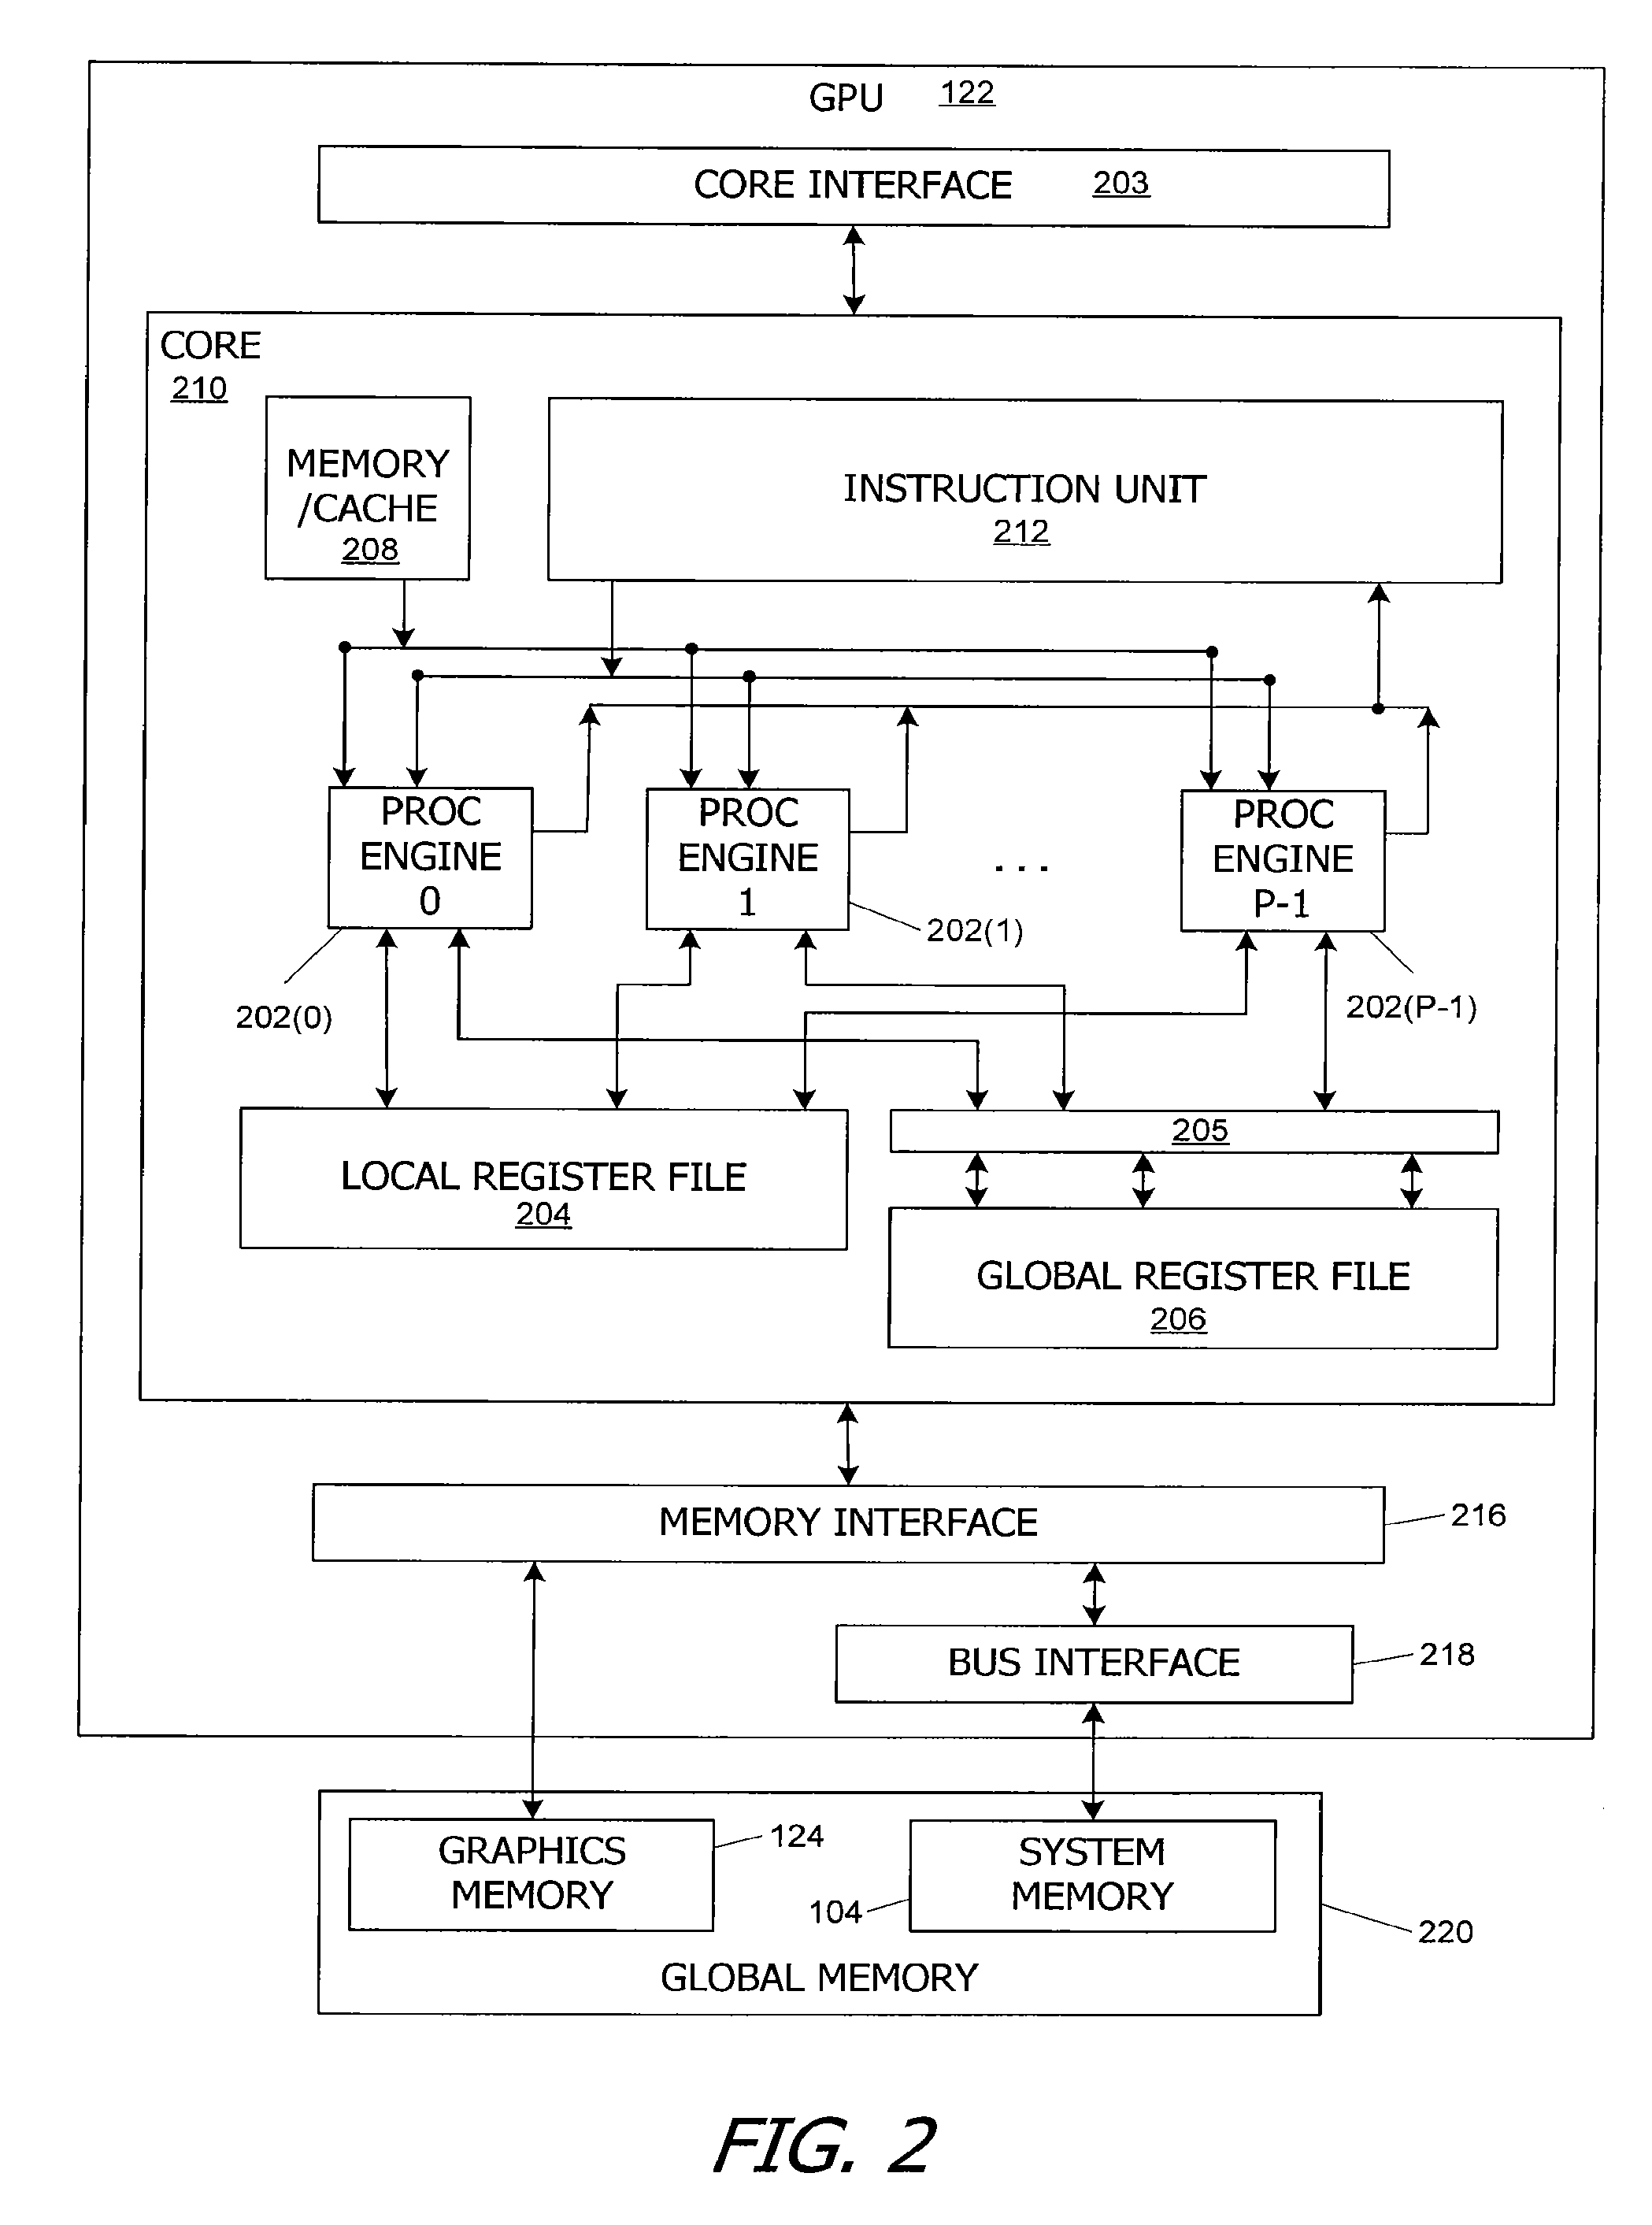
A general-purpose programming environment allows users to program a GPU as a general-purpose computation engine using familiar C / C++ programming constructs. Users may use declaration specifiers to identify which portions of a program are to be compiled for a CPU or a GPU. Specifically, functions, objects and variables may be specified for GPU binary compilation using declaration specifiers. A compiler separates the GPU binary code and the CPU binary code in a source file using the declaration specifiers. The location of objects and variables in different memory locations in the system may be identified using the declaration specifiers. CTA threading information is also provided for the GPU to support parallel processing.
Owner:NVIDIA CORP
Method for distributing tasks by general purpose graphic processing unit in multi-task concurrent execution manner
ActiveCN105653243ARelieve pressureOvercome low resource utilizationConcurrent instruction executionImage data processing detailsDynamic methodBusiness efficiency
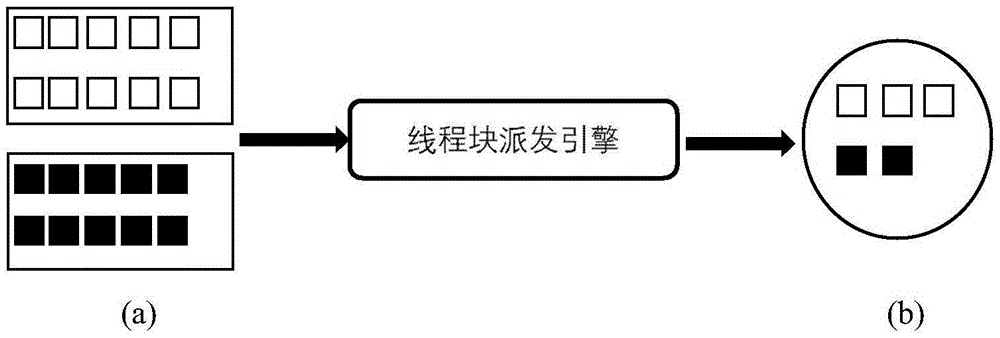
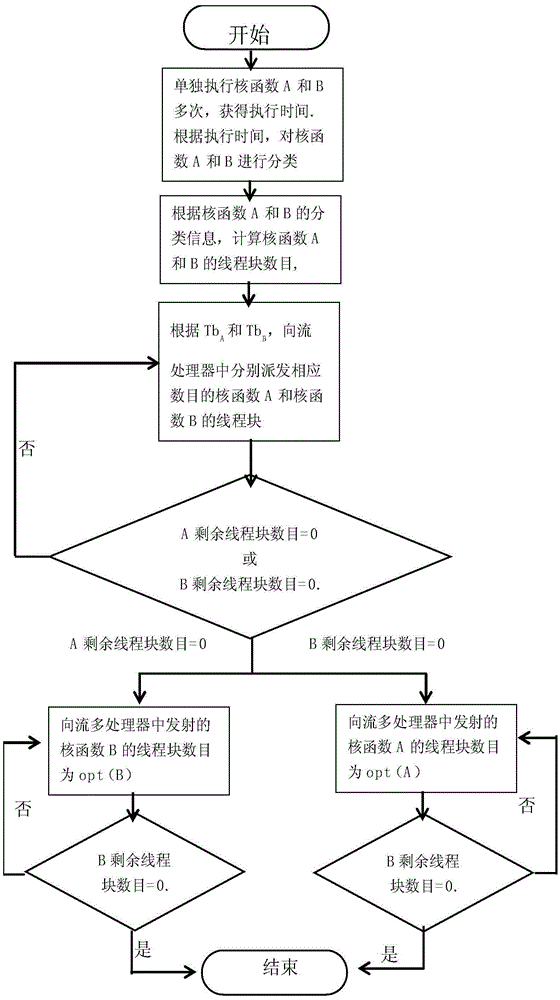
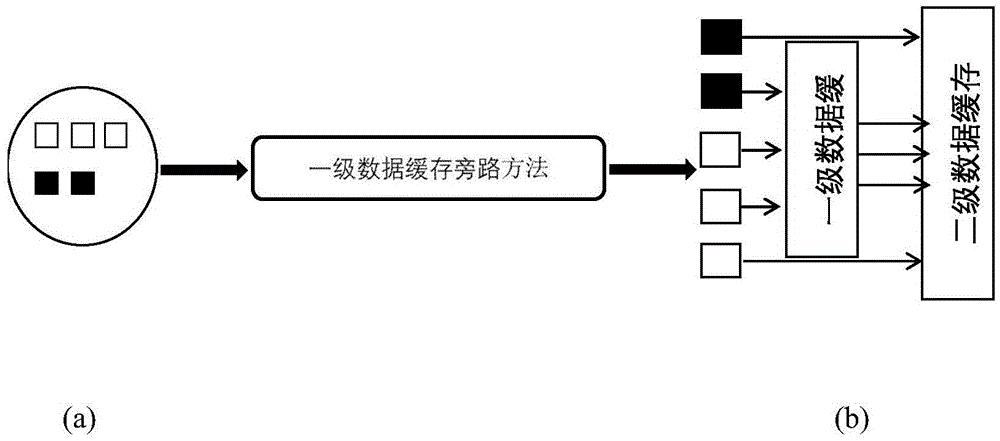
The invention discloses a method for distributing tasks by a general purpose graphic processing unit in a multi-task concurrent execution manner. The method comprises the following steps: firstly classifying kernel functions through a thread block distribution engine method; carrying out classified counting on the kernel functions to obtain the number of thread blocks of the kernel functions which are respectively distributed to a streaming processor; and distributing the thread blocks with different kernel function corresponding numbers into a same streaming multiprocessor so as to achieve the aims of improving the resource utilization rate of each streaming multiprocessor in the general purpose graphic processing unit and enhancing the system performance and the energy efficiency ratio. A level-1 data cache bypass method can be further utilized; and according to the method, a dynamic method is used for determining the thread block of which kernel function is bypassed, and then bypassing is carried out according to the number of the bypassed thread blocks of the kernel functions, so as to achieve the aims of lightening the pressure of the level-1 data cache and further improving the performance.
Owner:PEKING UNIV
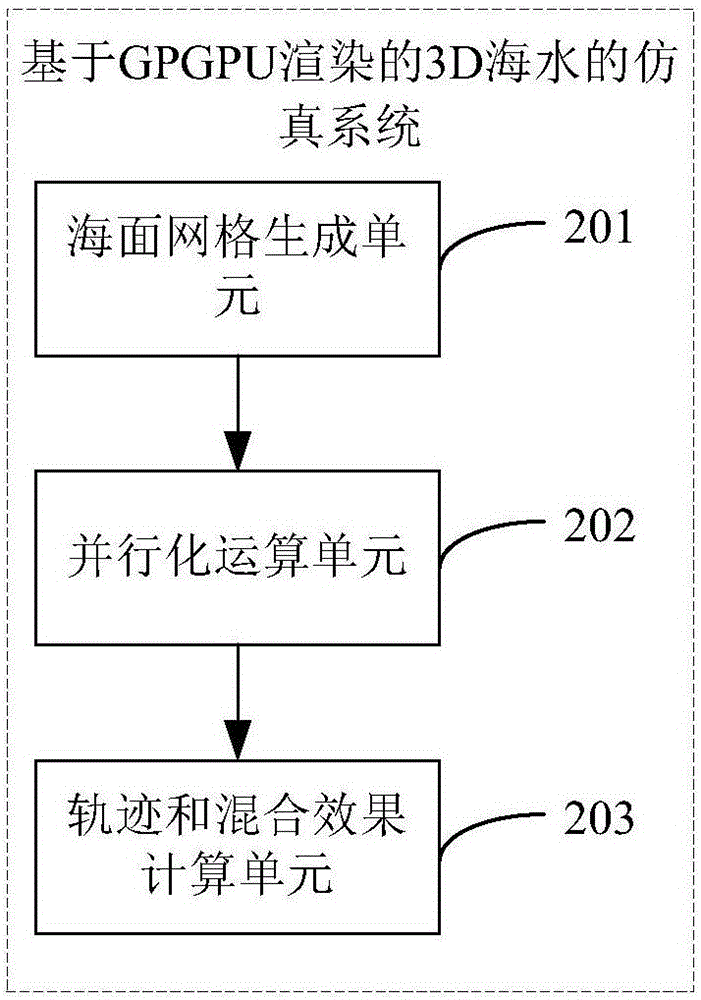
GPGPU-rendering-based simulation method and simulation system for 3D sea water
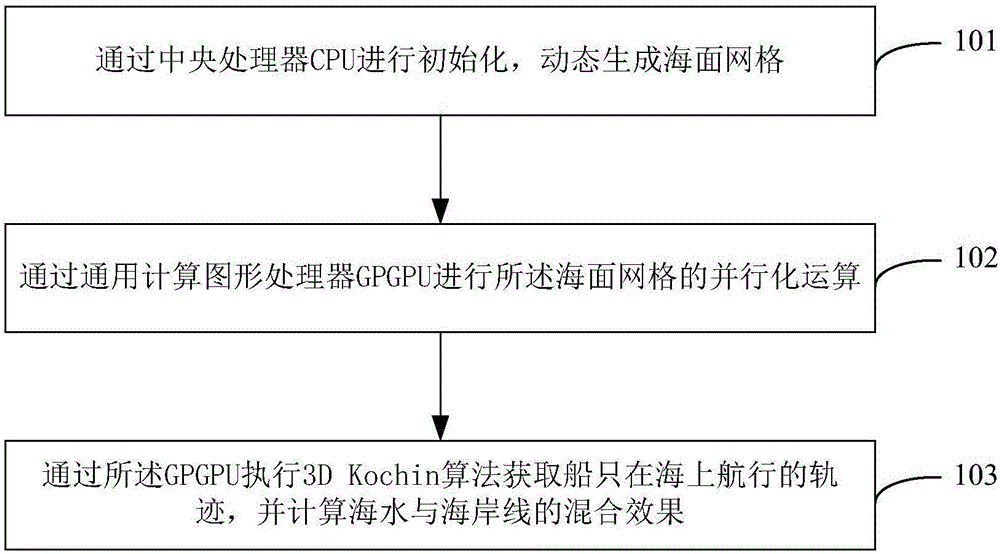
The application provides a general-purpose-graphics-processing-unit (GPGPU)-rendering-based simulation method and simulation system for 3D sea water. The simulation method comprises: a CPU is used for initialization and an ocean-surface grid is generated dynamically; parallel computing is carried out on the ocean-surface grid by using the GPGPU; and the GPGPU executes a 3D Kochin algorithm to obtain a marine navigation track of a ship and calculates a mixing effect of sea water and a coastline. According to the method provided by the application, all computing and rendering are arranged in the GPGPU and sea water module computing and rendering form an integrated flow in the GPGPU, thereby reducing communication between an internal memory and a video memory and thus realizing the GPGPU performances fully and improving the simulation efficiency. On the basis of the method, rendering, reflecting, and refraction of sea water and waves as well as good coordination of the visual effect reality sense of the ship track and simulation real-time performance are realized.
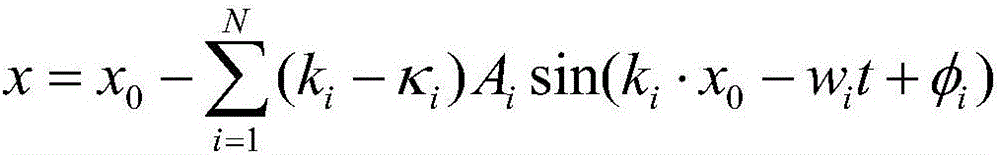
Owner:姜雪伟
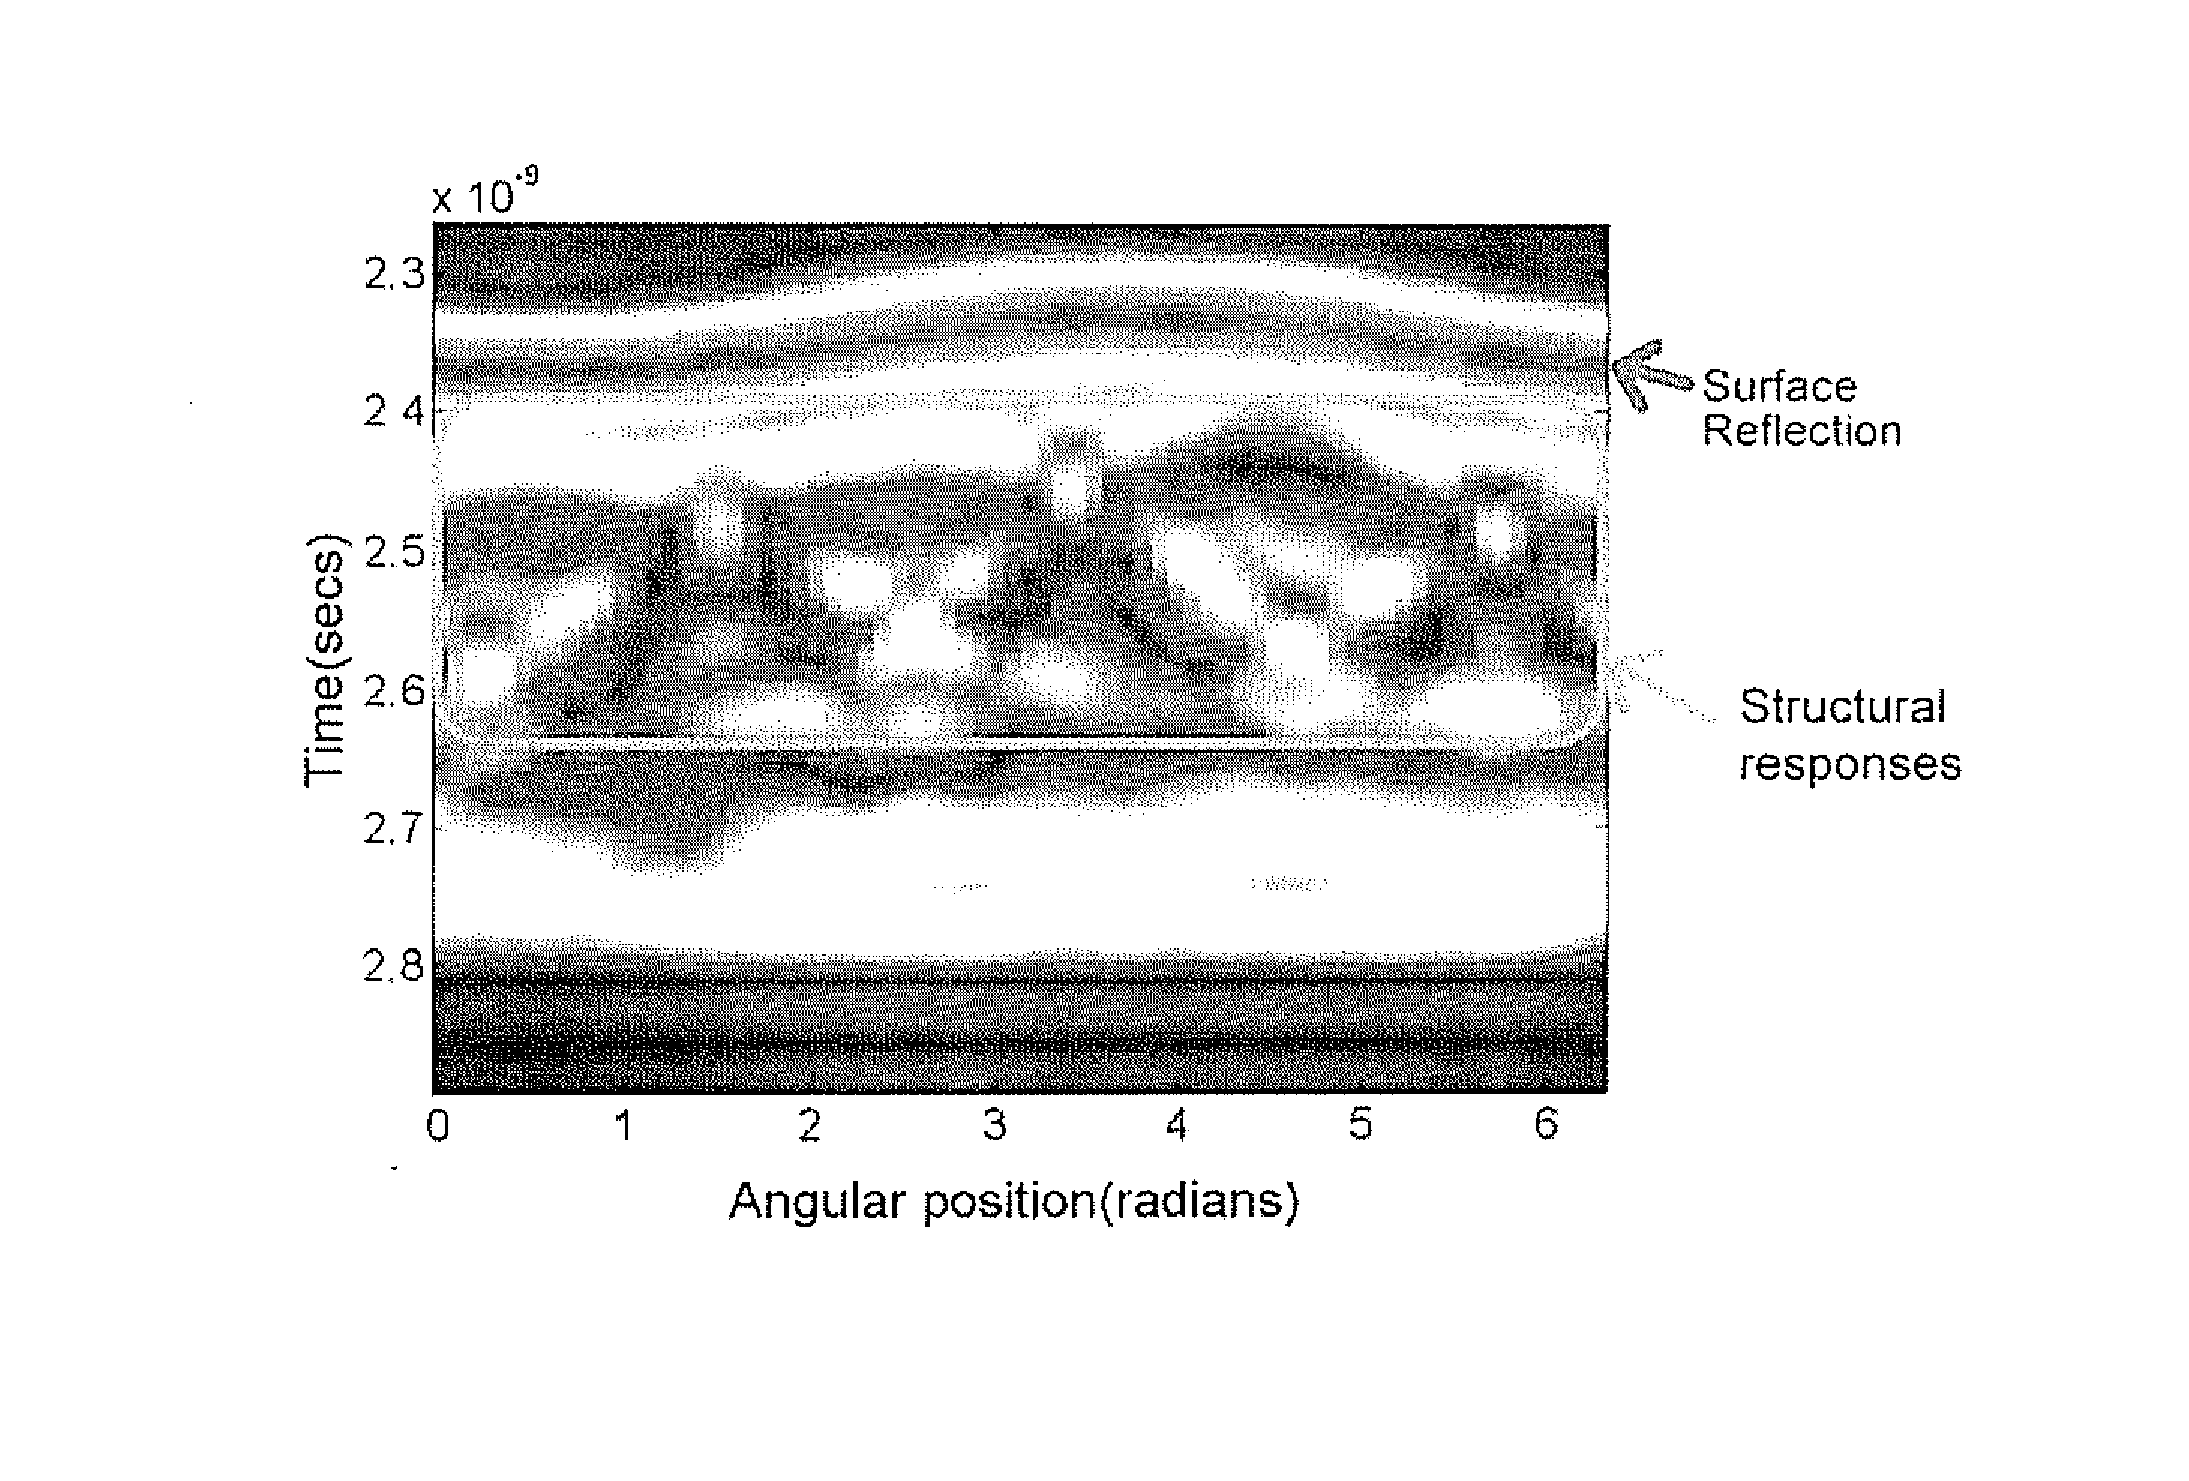
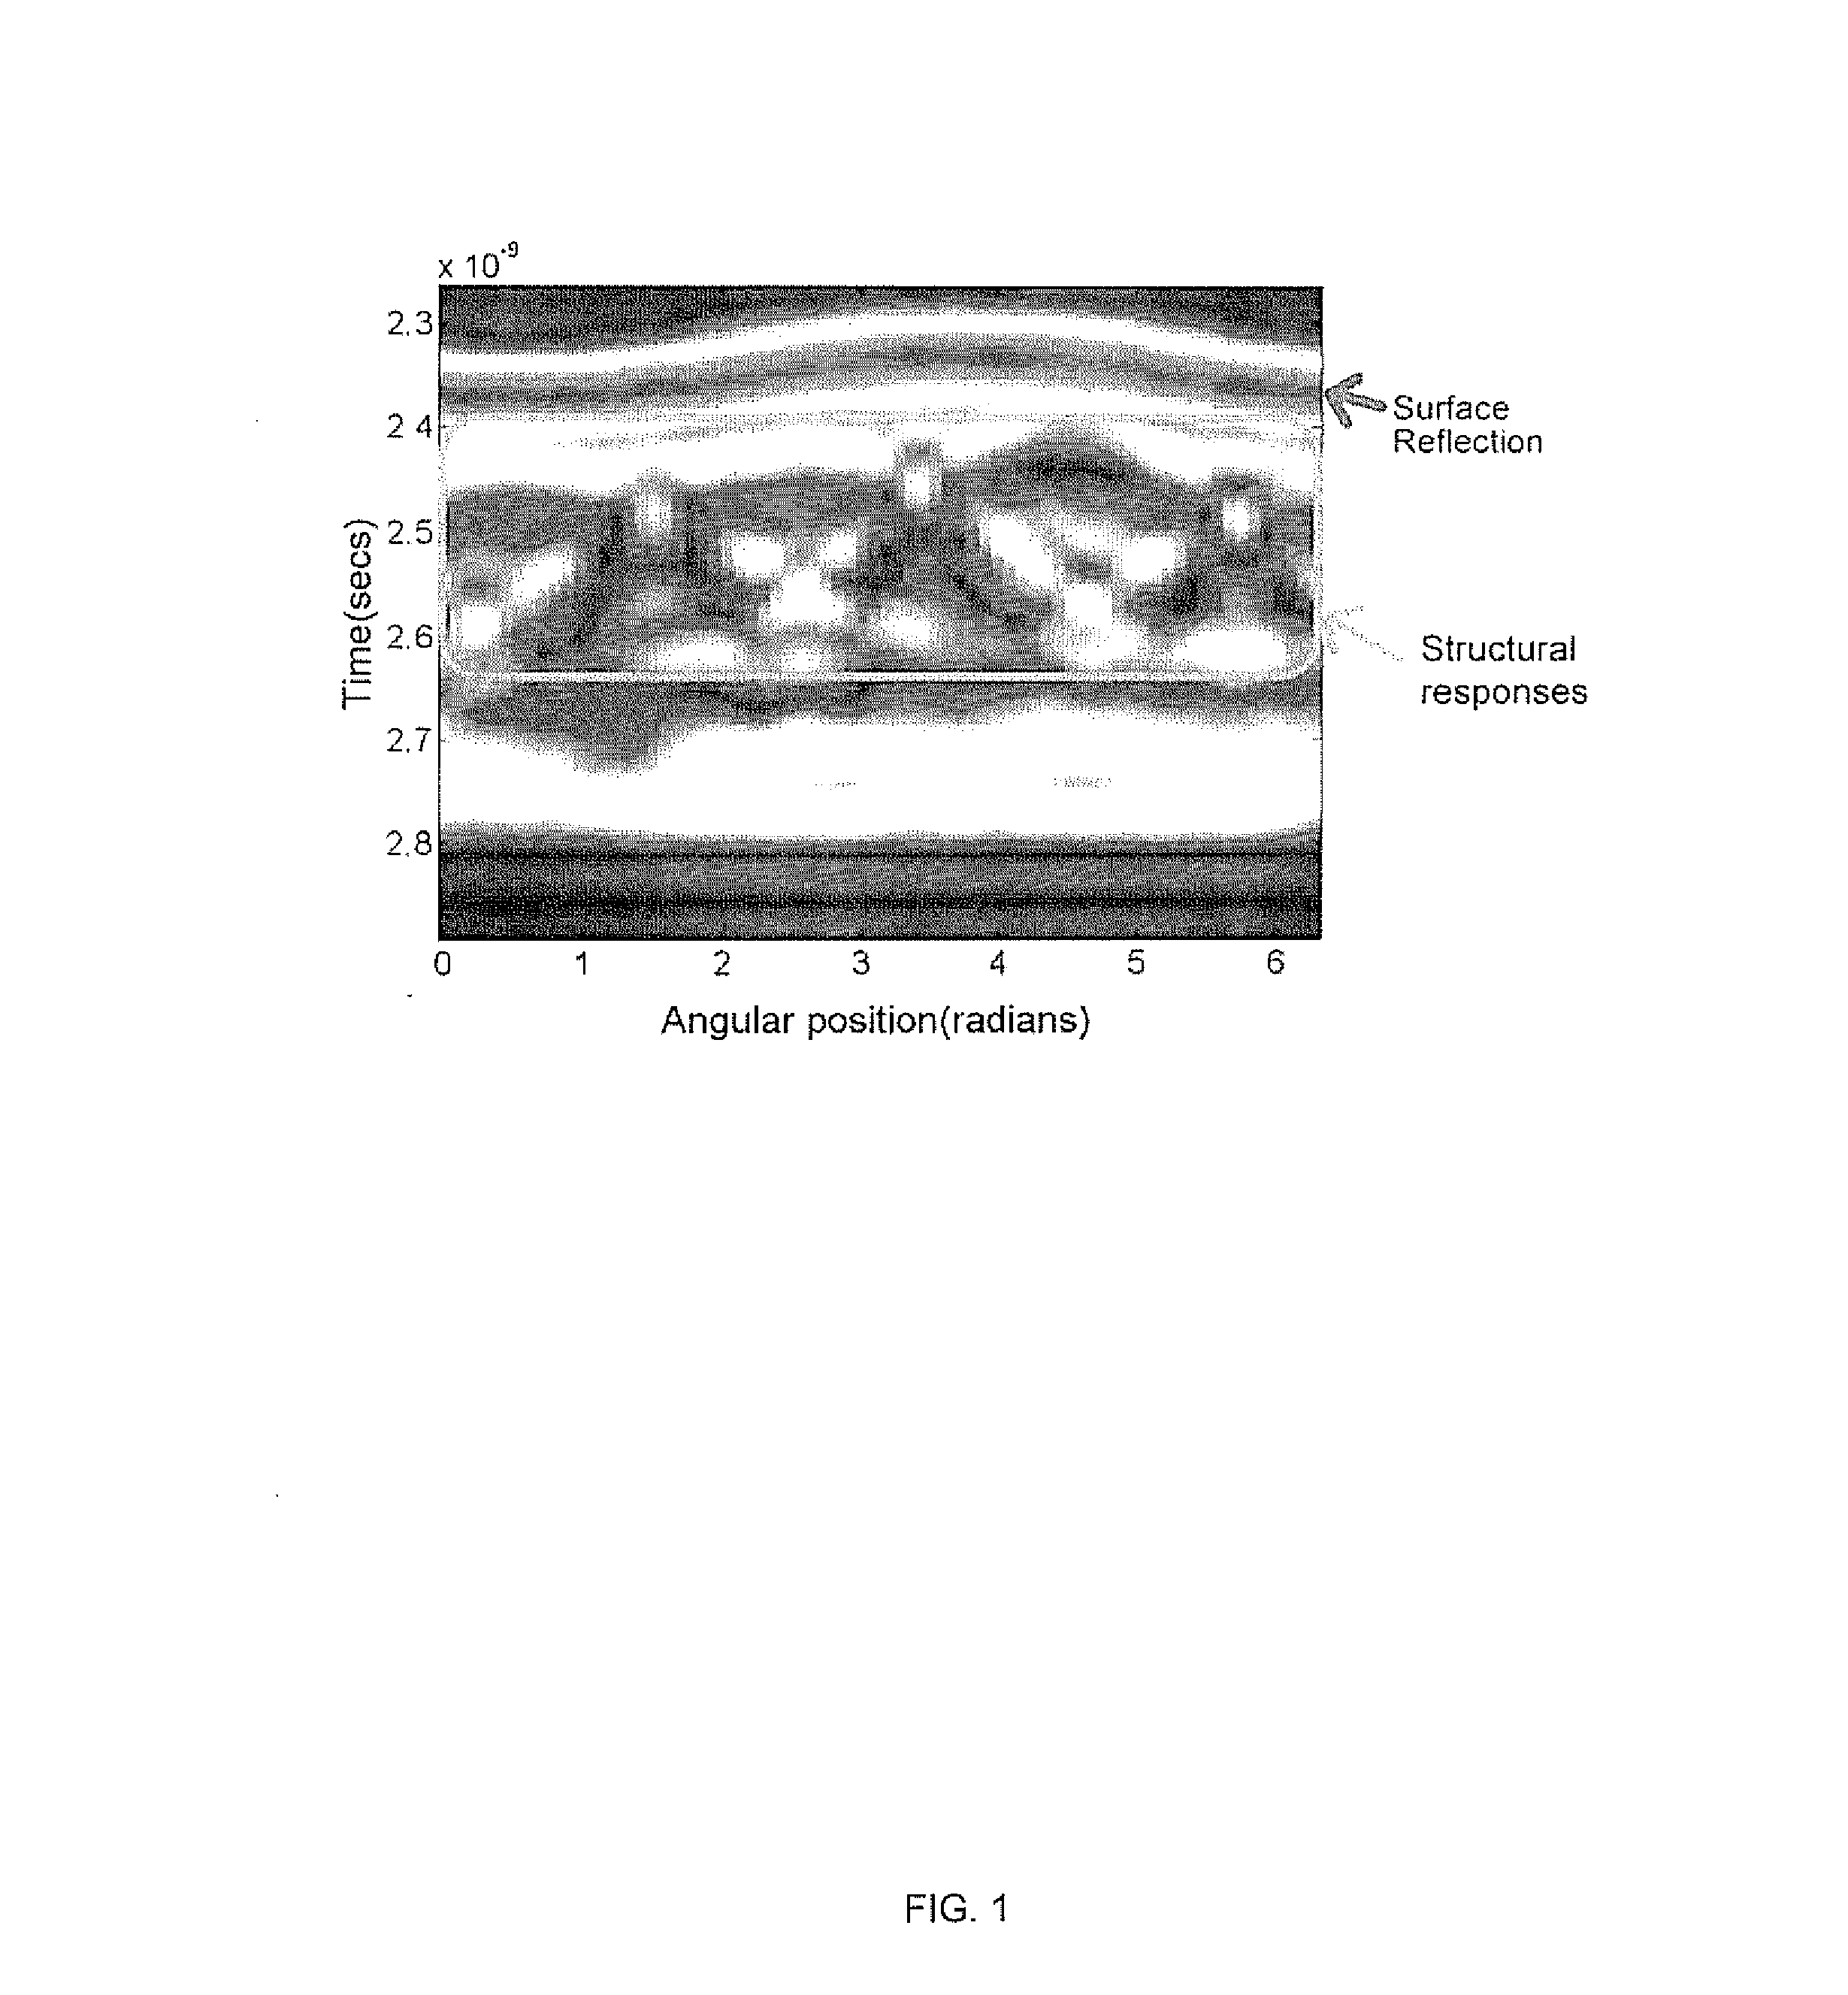
Real Time Reconstruction of 3D Cylindrical Near Field Radar Images Using a Single Instruction Multiple Data Interpolation Approach
InactiveUS20130044022A1Low costHigh bandwidthRadio wave reradiation/reflectionPerformance computingProblem space
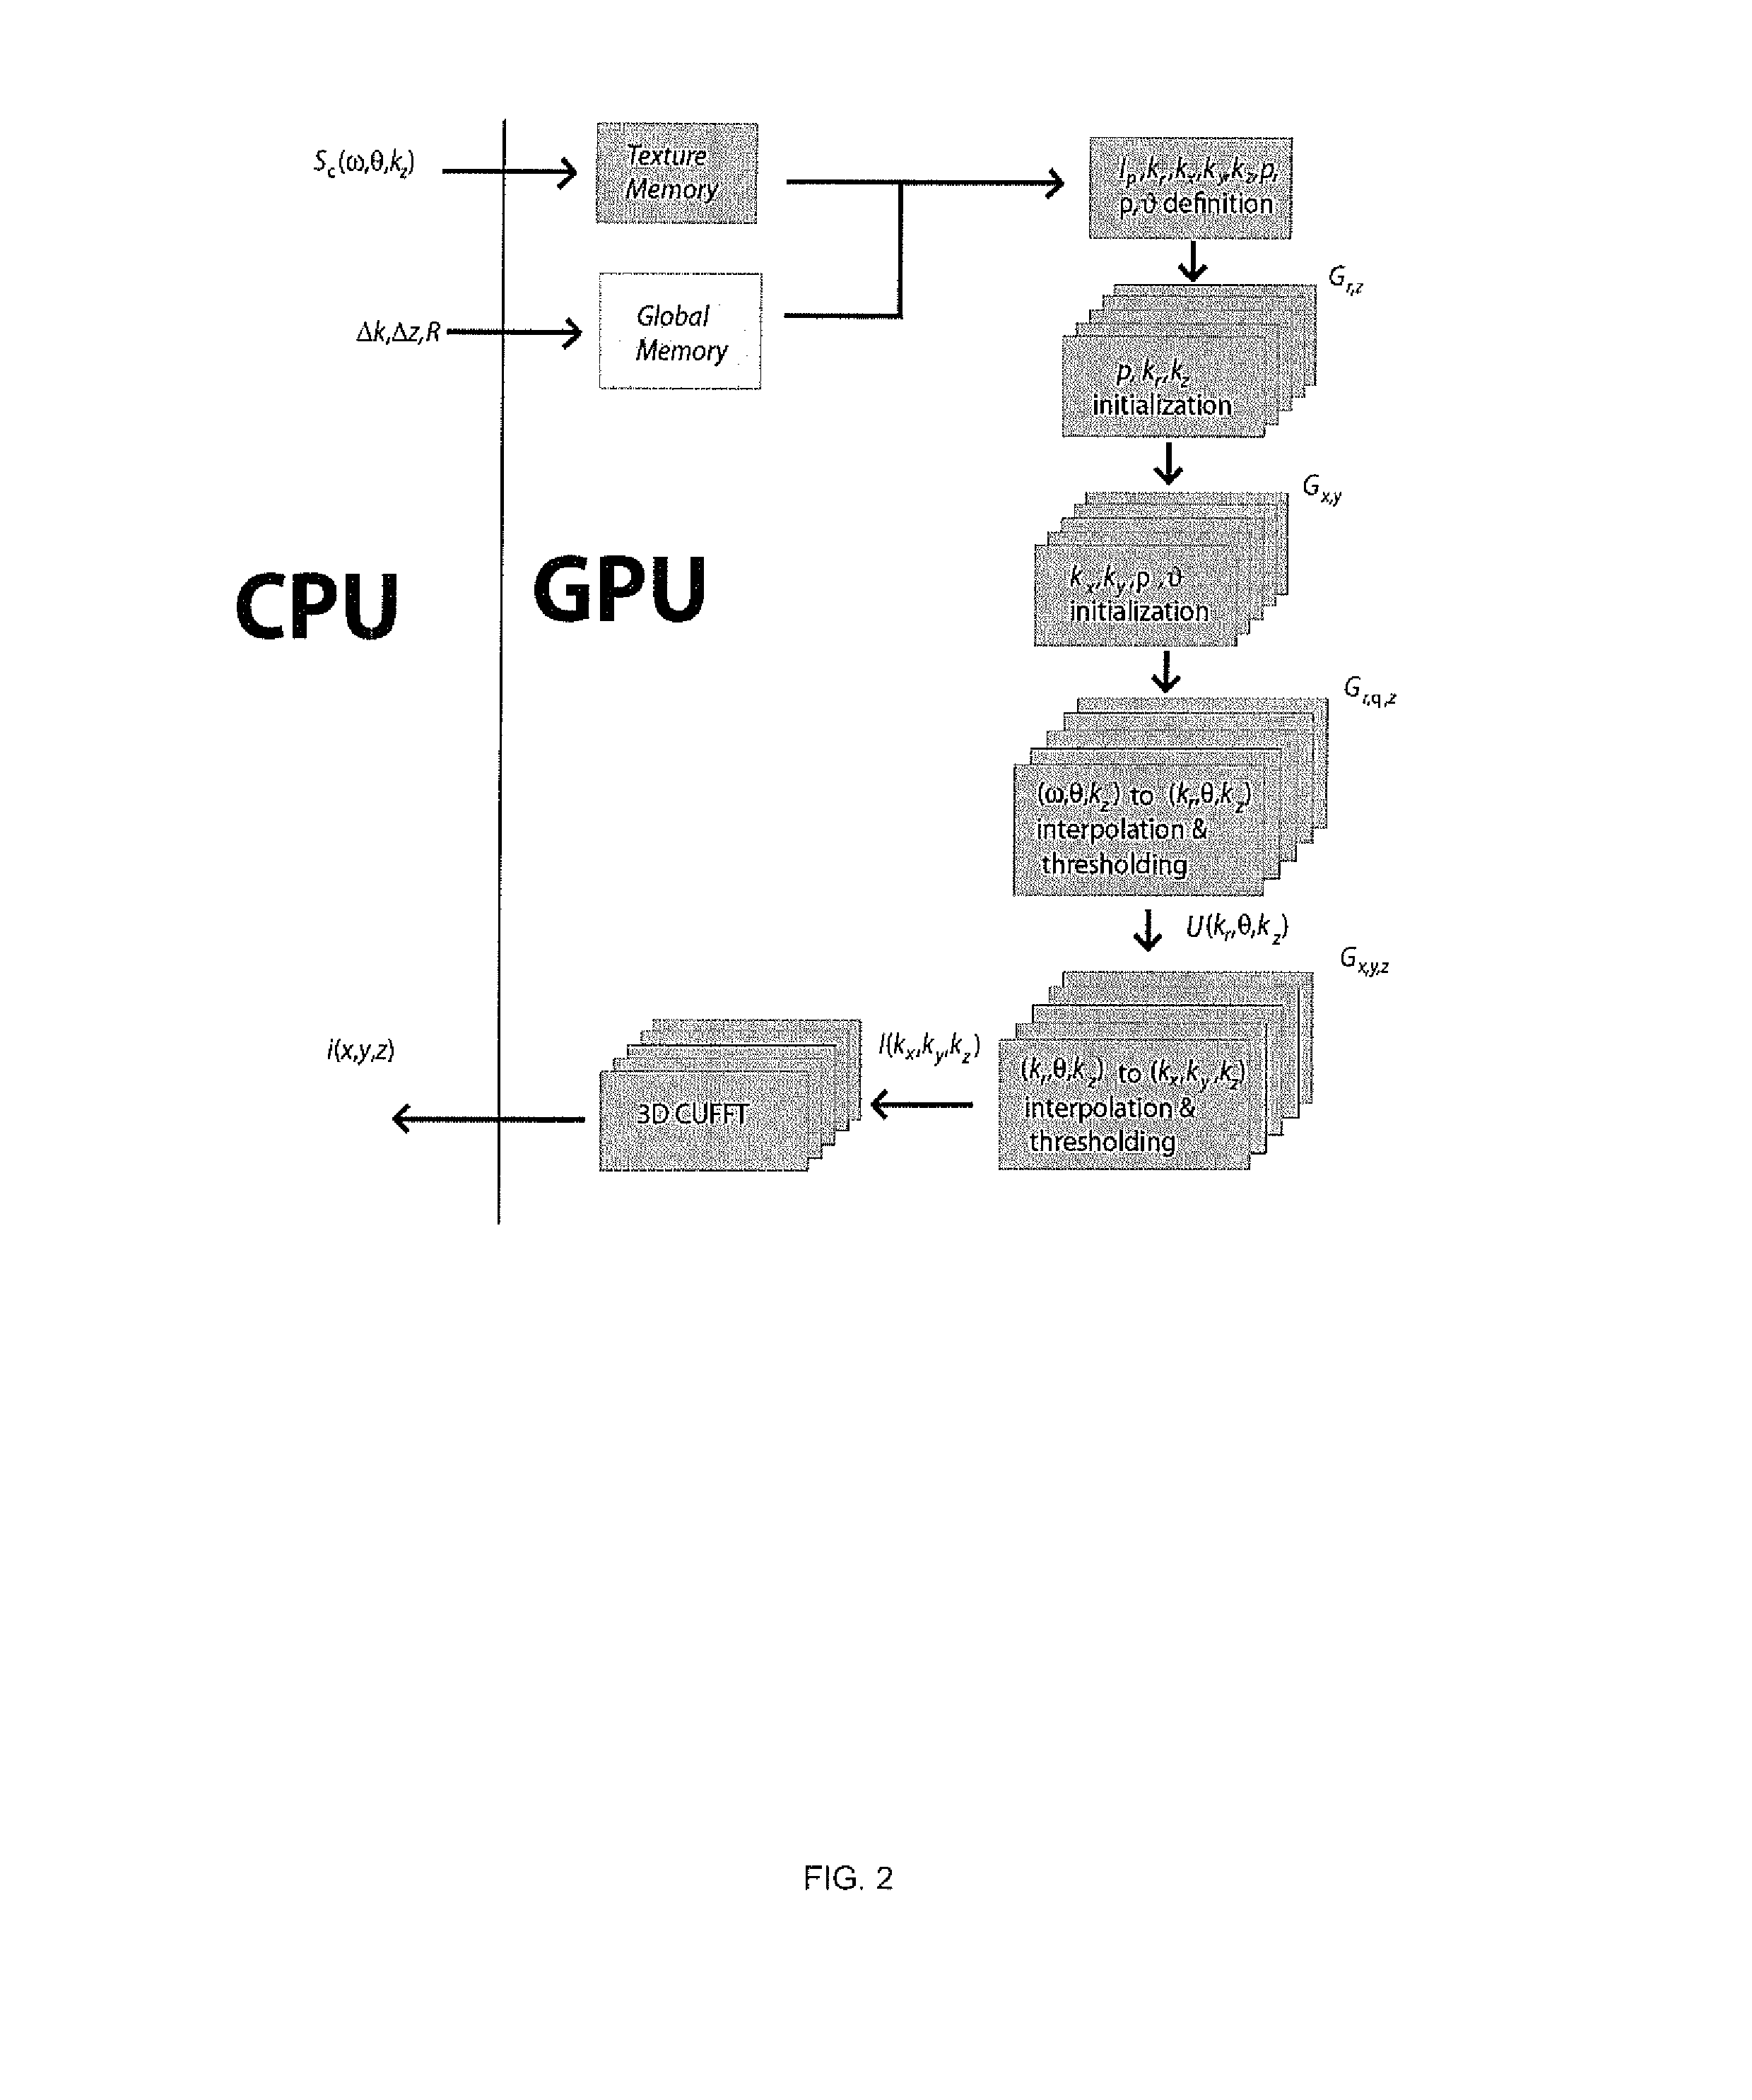
The present invention uses a Single Instruction Multiple Data (SIMD) architecture to form real time 3D radar images recorded in cylindrical near field scenarios using a wavefront reconstruction approach. A novel interpolation approach is executed in parallel, significantly reducing the reconstruction time without compromising the spatial accuracy and signal to noise ratios of the resulting images. Since each point in the problem space can be processed independently, the proposed technique was implemented using an approach on a General Purpose Graphics Processing Unit (GPGPU) to take advantage of the high performance computing capabilities of this platform.
Owner:TAPIA DANIEL FLORES +1
Real time automated nerve identification system
PendingUS20250069387A1Medical data miningMechanical/radiation/invasive therapiesAnatomical structuresImage manipulation
Precise nerve detection during surgery is crucial for safe operational outcomes, which largely depend on the surgeon's skills. Therefore, automatic real-time identification of anatomical structures is of great importance. However, image processing times must be kept as low as possible to be a viable solution for real-time visual identification. By using a general purpose graphics processing unit (GPGPU) implementation for birefringence mapping, the process can achieve rates of 43 frames per second (FPS); a 118×gain from a CPU implementation. Furthermore, by including a deep learning network, the complete framework can automatically detect nerves close to 12 FPS. By leveraging GPU for the processing task, the framework can run on compact devices with NVIDIA modules, such as Jetson Xavier AGX, while still achieving reasonably fast nerve identification and visualization.

Owner:GEORGE WASHINGTON UNIVERSITY
System and method for utilizing general-purpose graphics processing units (GPGPU) architecture for medical image processing
InactiveUS20200265578A1Enhance the imageEasy to resolveUltrasonic/sonic/infrasonic diagnosticsImage enhancementMedical imaging dataData set
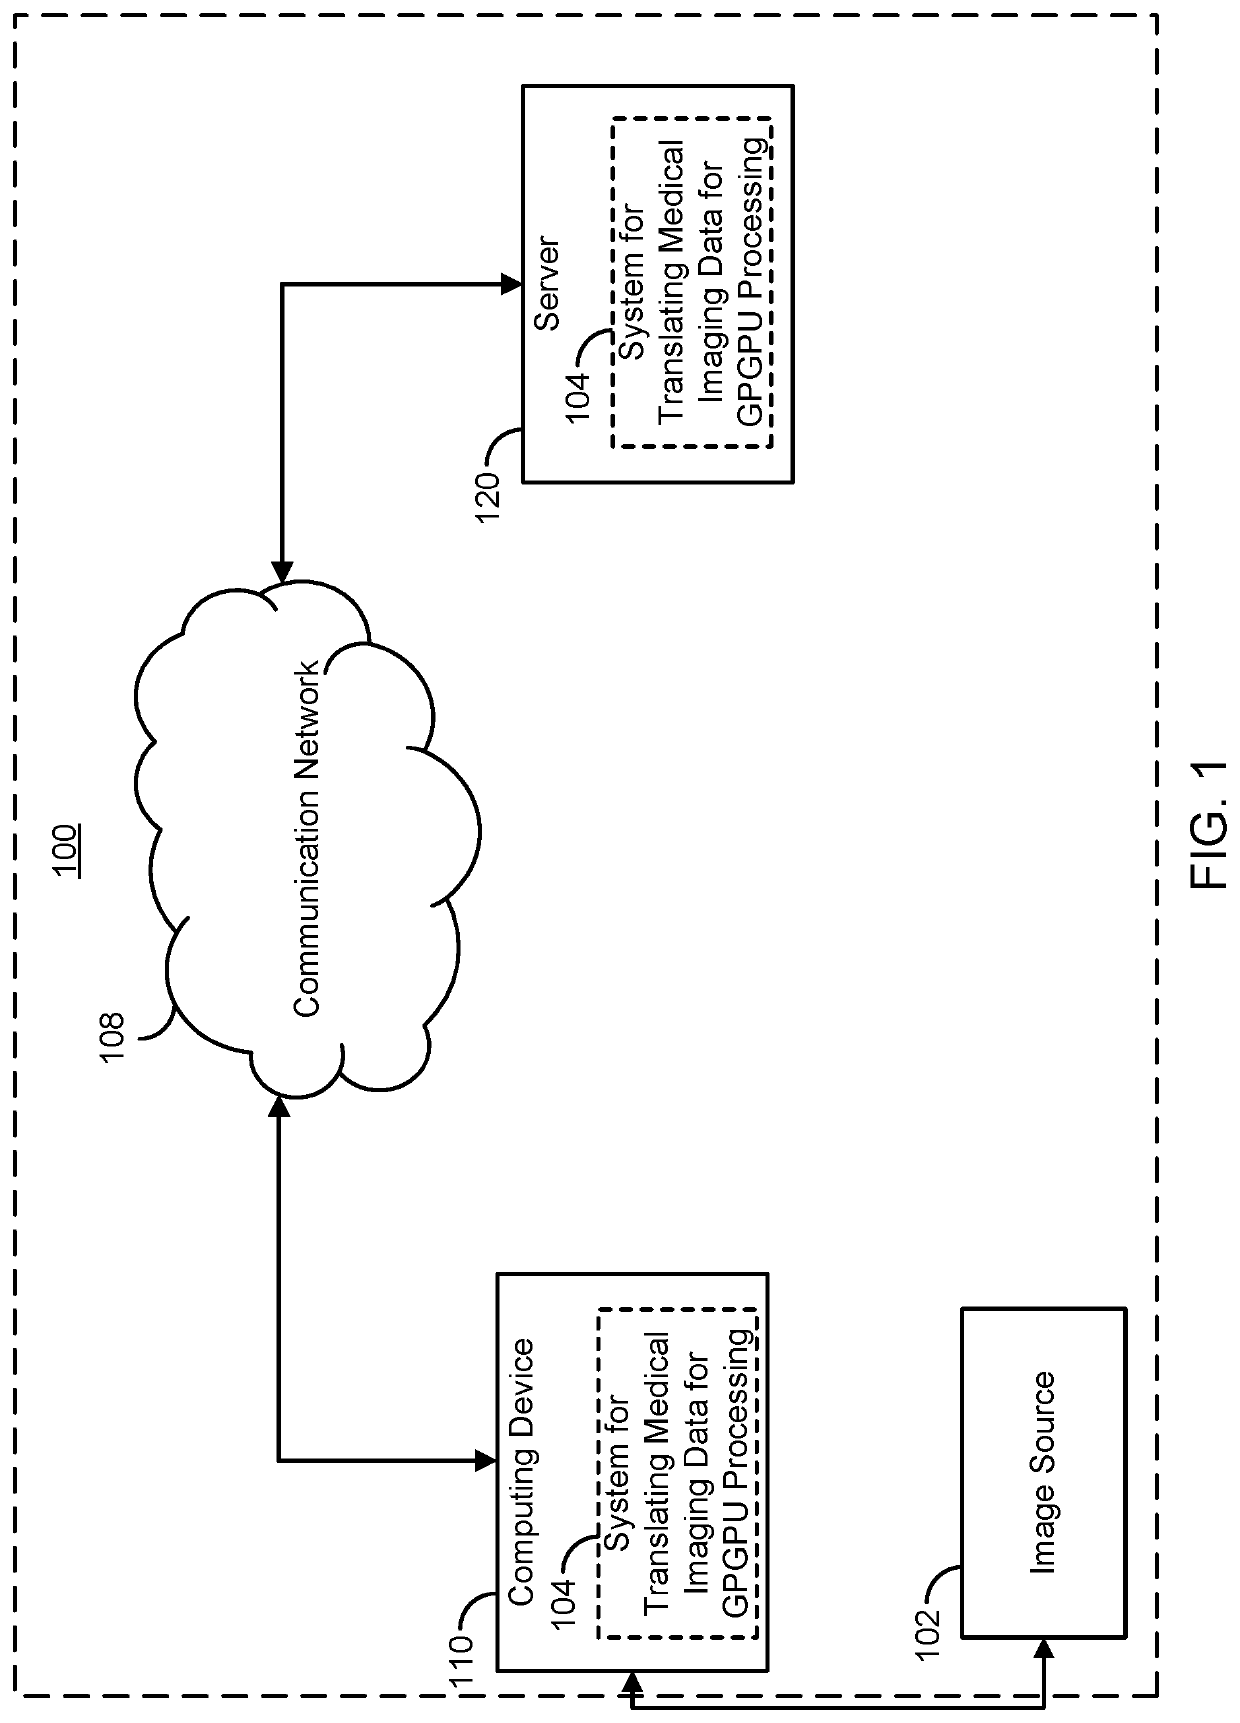
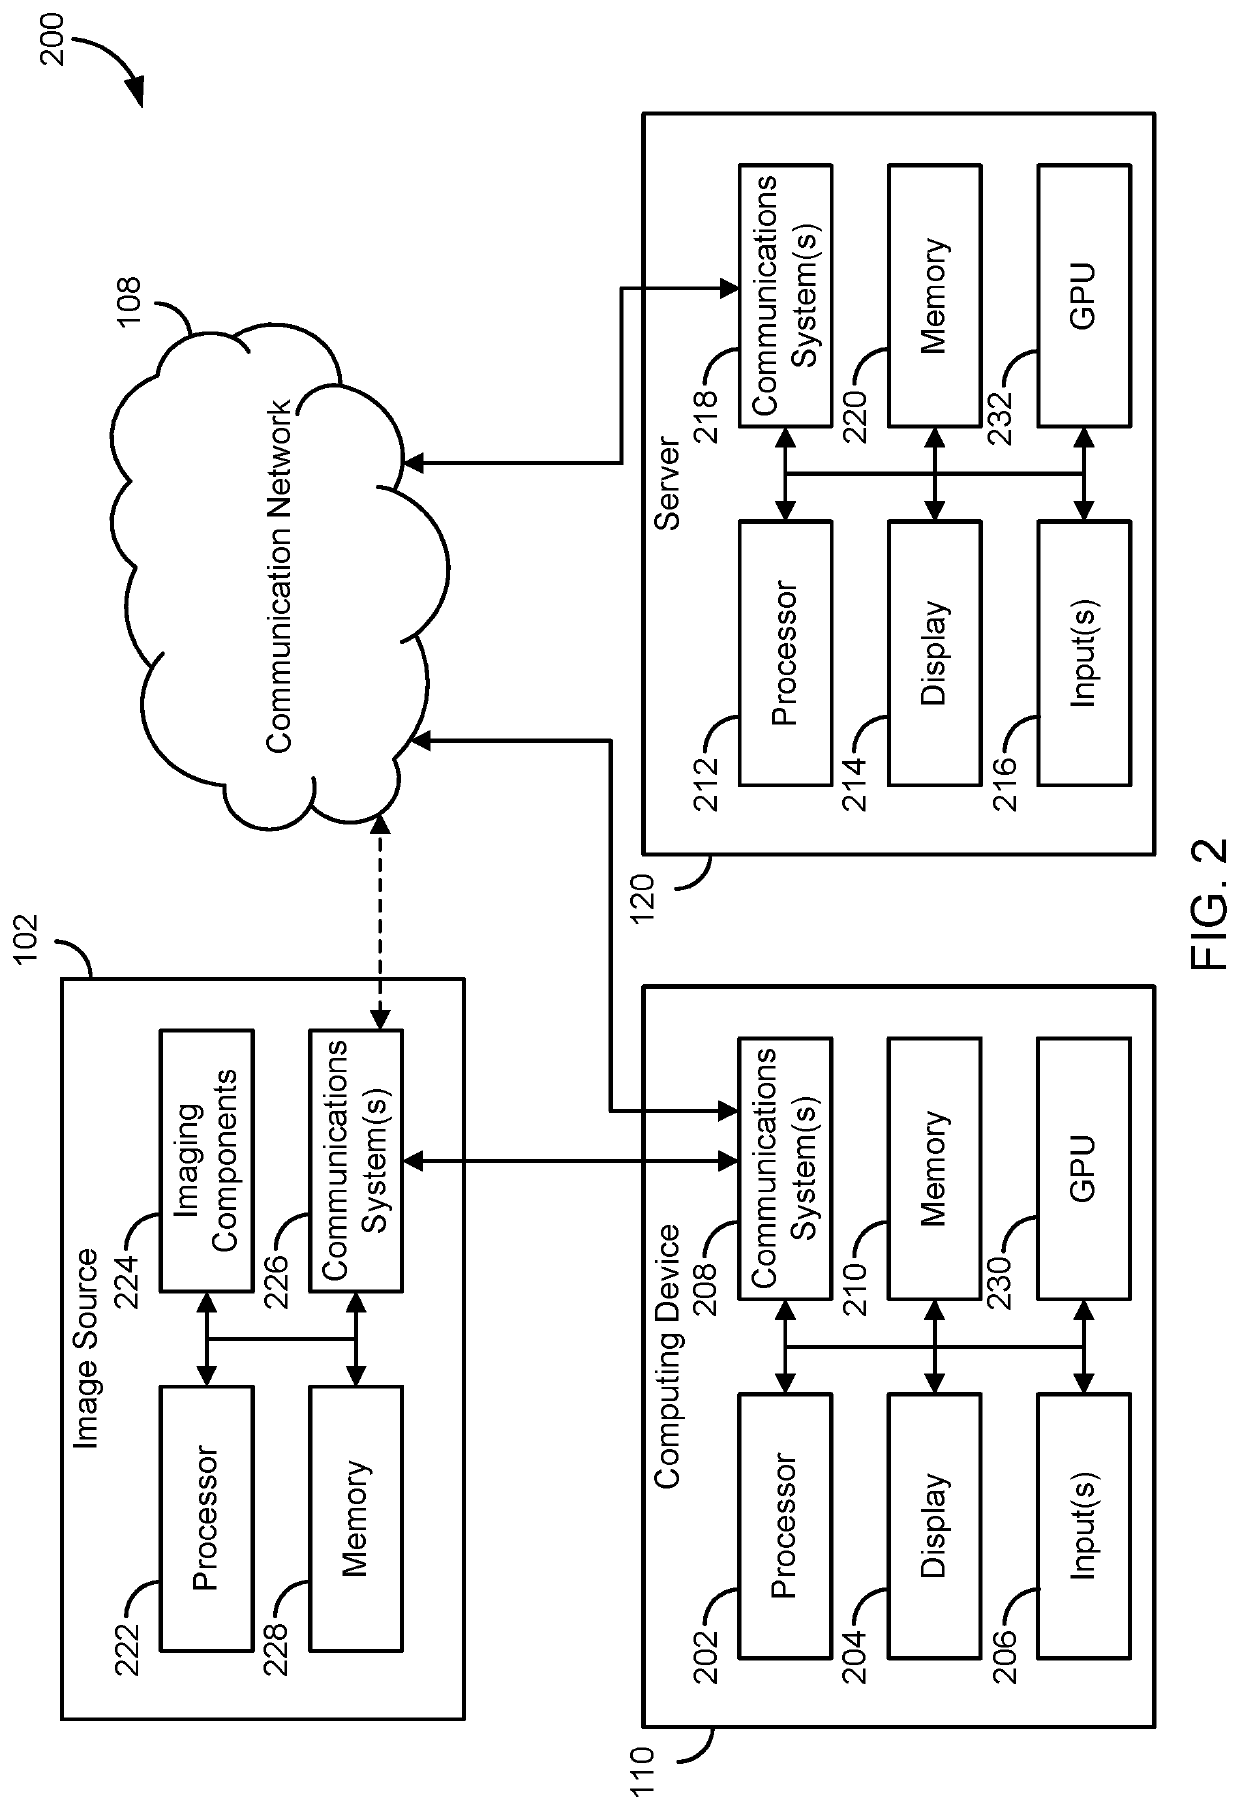
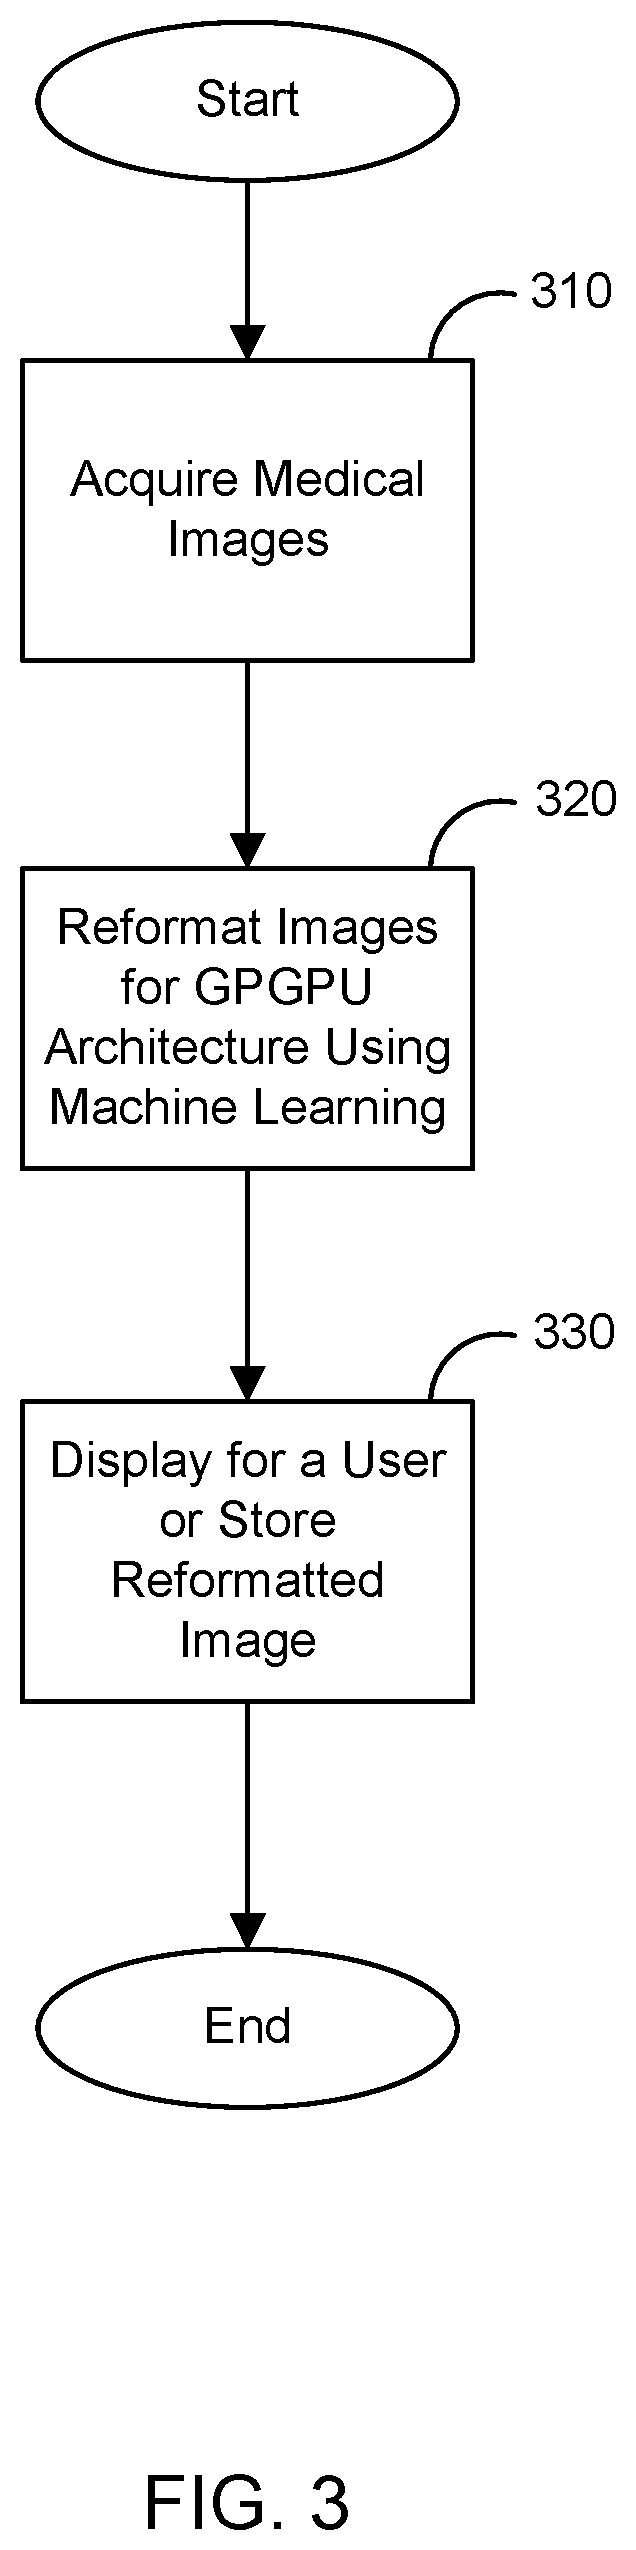
Systems and methods for translating medical imaging data for processing using a general processing graphic processing unit (GPGPU) architecture are provided. Medical imaging data acquired from a patient and having data characteristics incompatible with processing on the GPGPU architecture, including at least one of bit-resolution, memory capacity requirements for processing, or bandwidth requirements for processing is translated for processing by the GPGPU architecture. The translation process is performed by determining a plurality of window level settings using a machine learning network to increase conspicuity of an object in an image generated from the medical imaging data or generate at least two channel image datasets from the medical imaging data. Translated medical image data is crated using at least one of the window level settings or at least two channel image datasets and then processed using the GPGPU architecture to generate medical images of the patient.
Owner:THE GENERAL HOSPITAL CORP
Nonlinear unsteady-state complex signal self-adapting decomposition method based on GPGPU
ActiveCN105279376AEasy to handleTo achieve the purpose of parallelizationSpecial data processing applicationsGeneral purposeGraphics
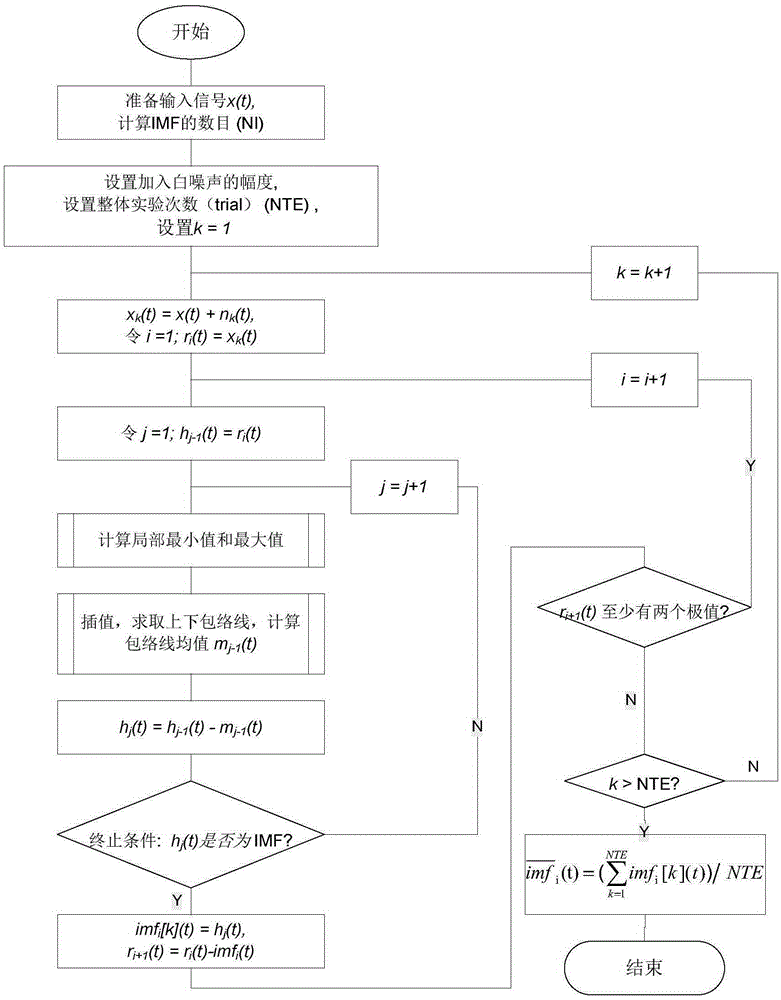
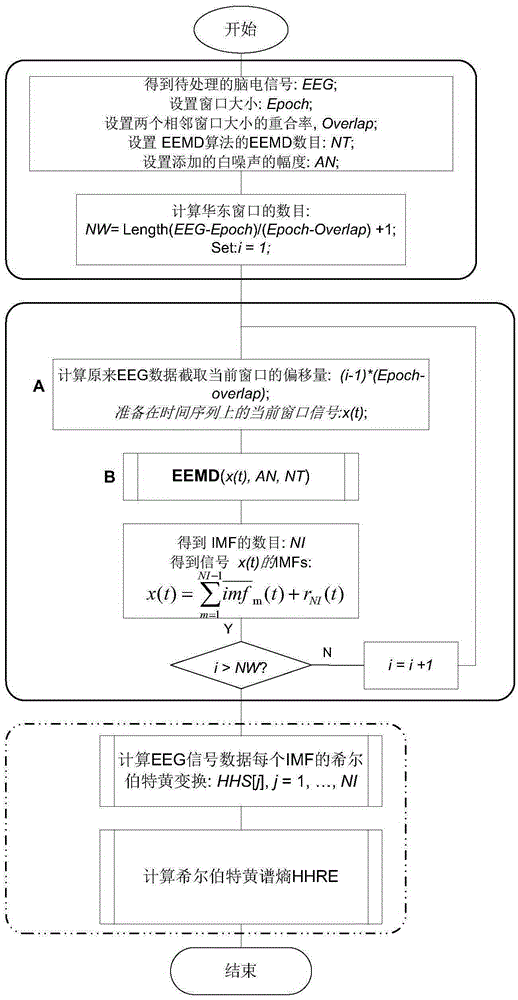
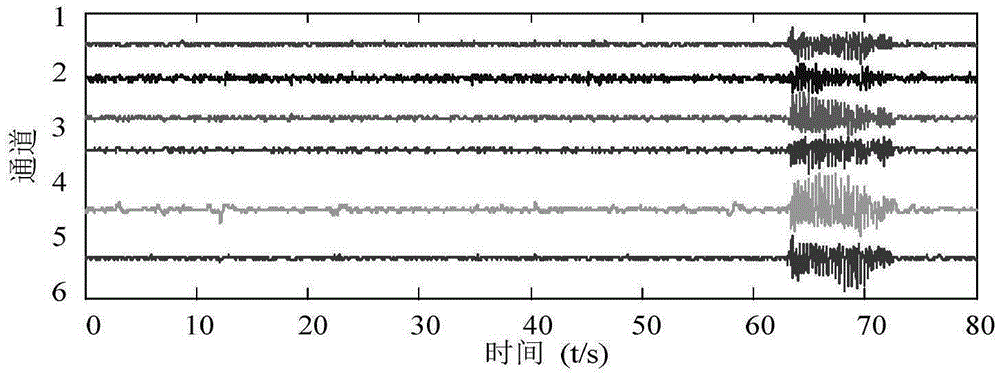
The invention discloses a nonlinear unsteady-state complex signal self-adapting decomposition method based on GPGPU (General Purpose Graphics Processing Units), and belongs to the field of signal analysis. During large-scale signal data processing by a conventional EEMD (Ensemble Empirieal Mode Decomposition) algorithm, the processing is limited by the denseness computation of the algorithm per se, so that the conventional algorithm cannot meet the real-time performance demand in practical application. A plurality of high parallel computation steps included by the EEMD algorithm are analyzed; a GPGPU method based on a CUDA (Compute Unified Device Architecture) is used for performing parallel design on the EEMD algorithm, so that the algorithm reaches an optimal state in the aspects of data precision and time consumption; Hilbert-huang transform is combined; Hilbert transform and Shannon entropy concepts are used for obtaining Hilbert-huang spectral entropy to further studying decomposition signals. Experiments prove that the method has high efficiency and availability in the practical signal decomposition analysis.
Owner:WUHAN UNIV
Thread-local memory reference promotion for translating CUDA code for execution by a general purpose processor
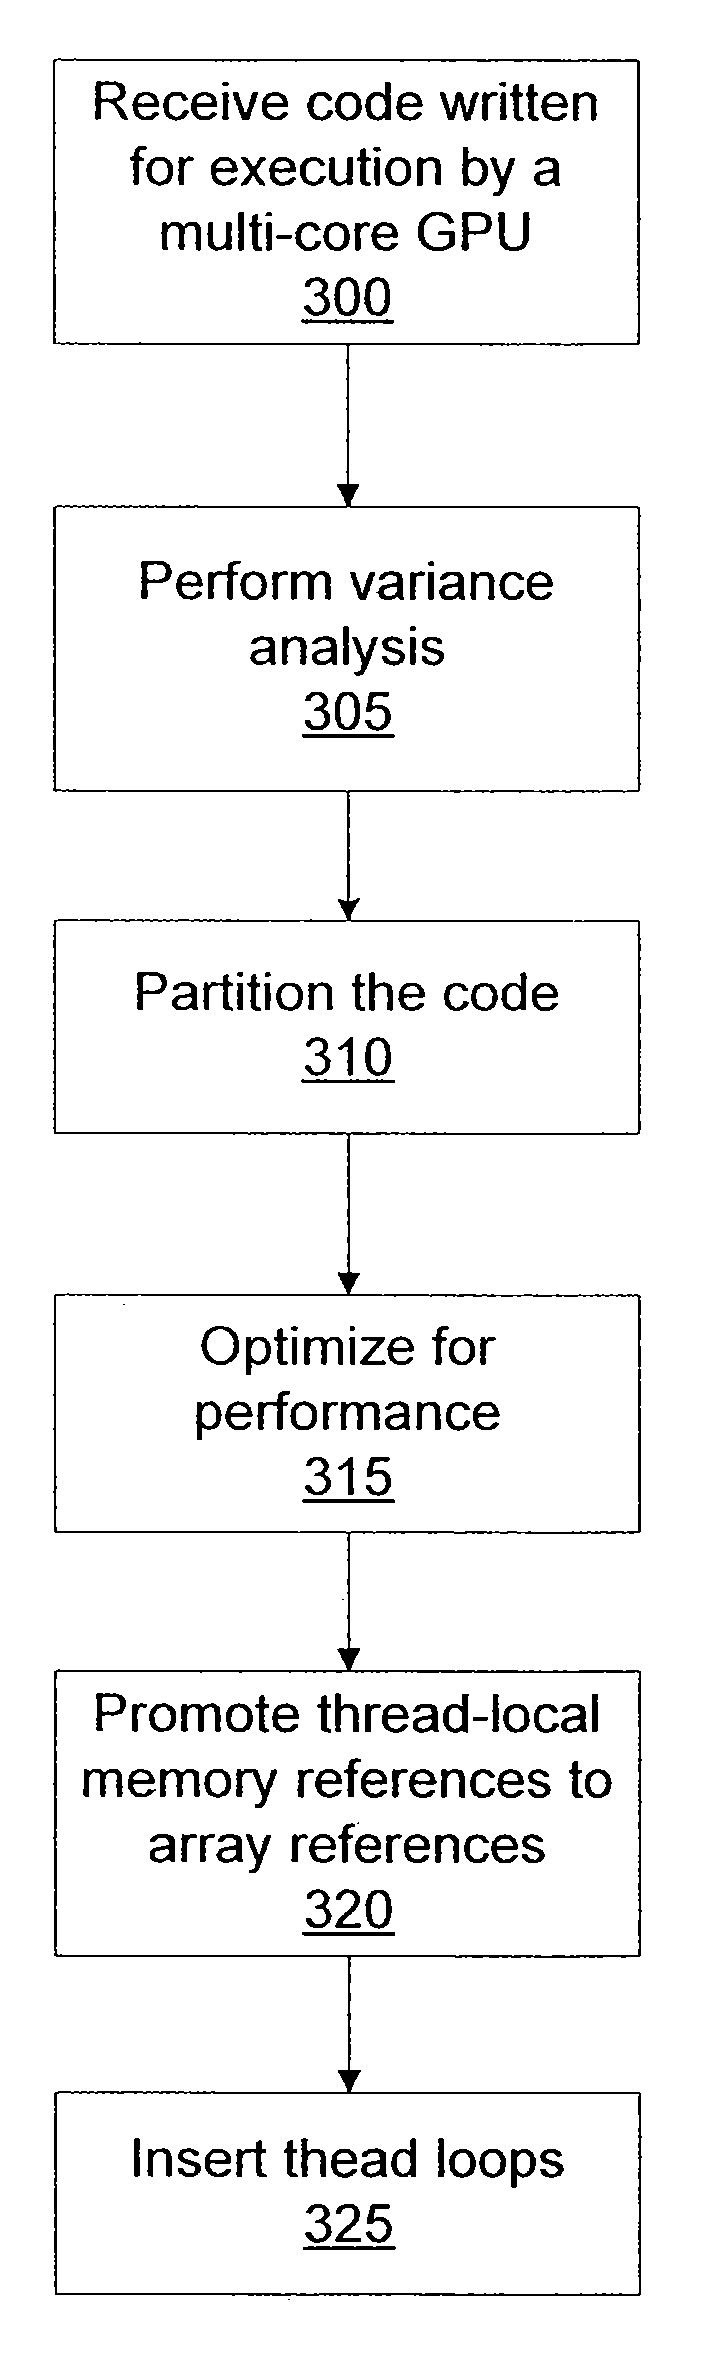
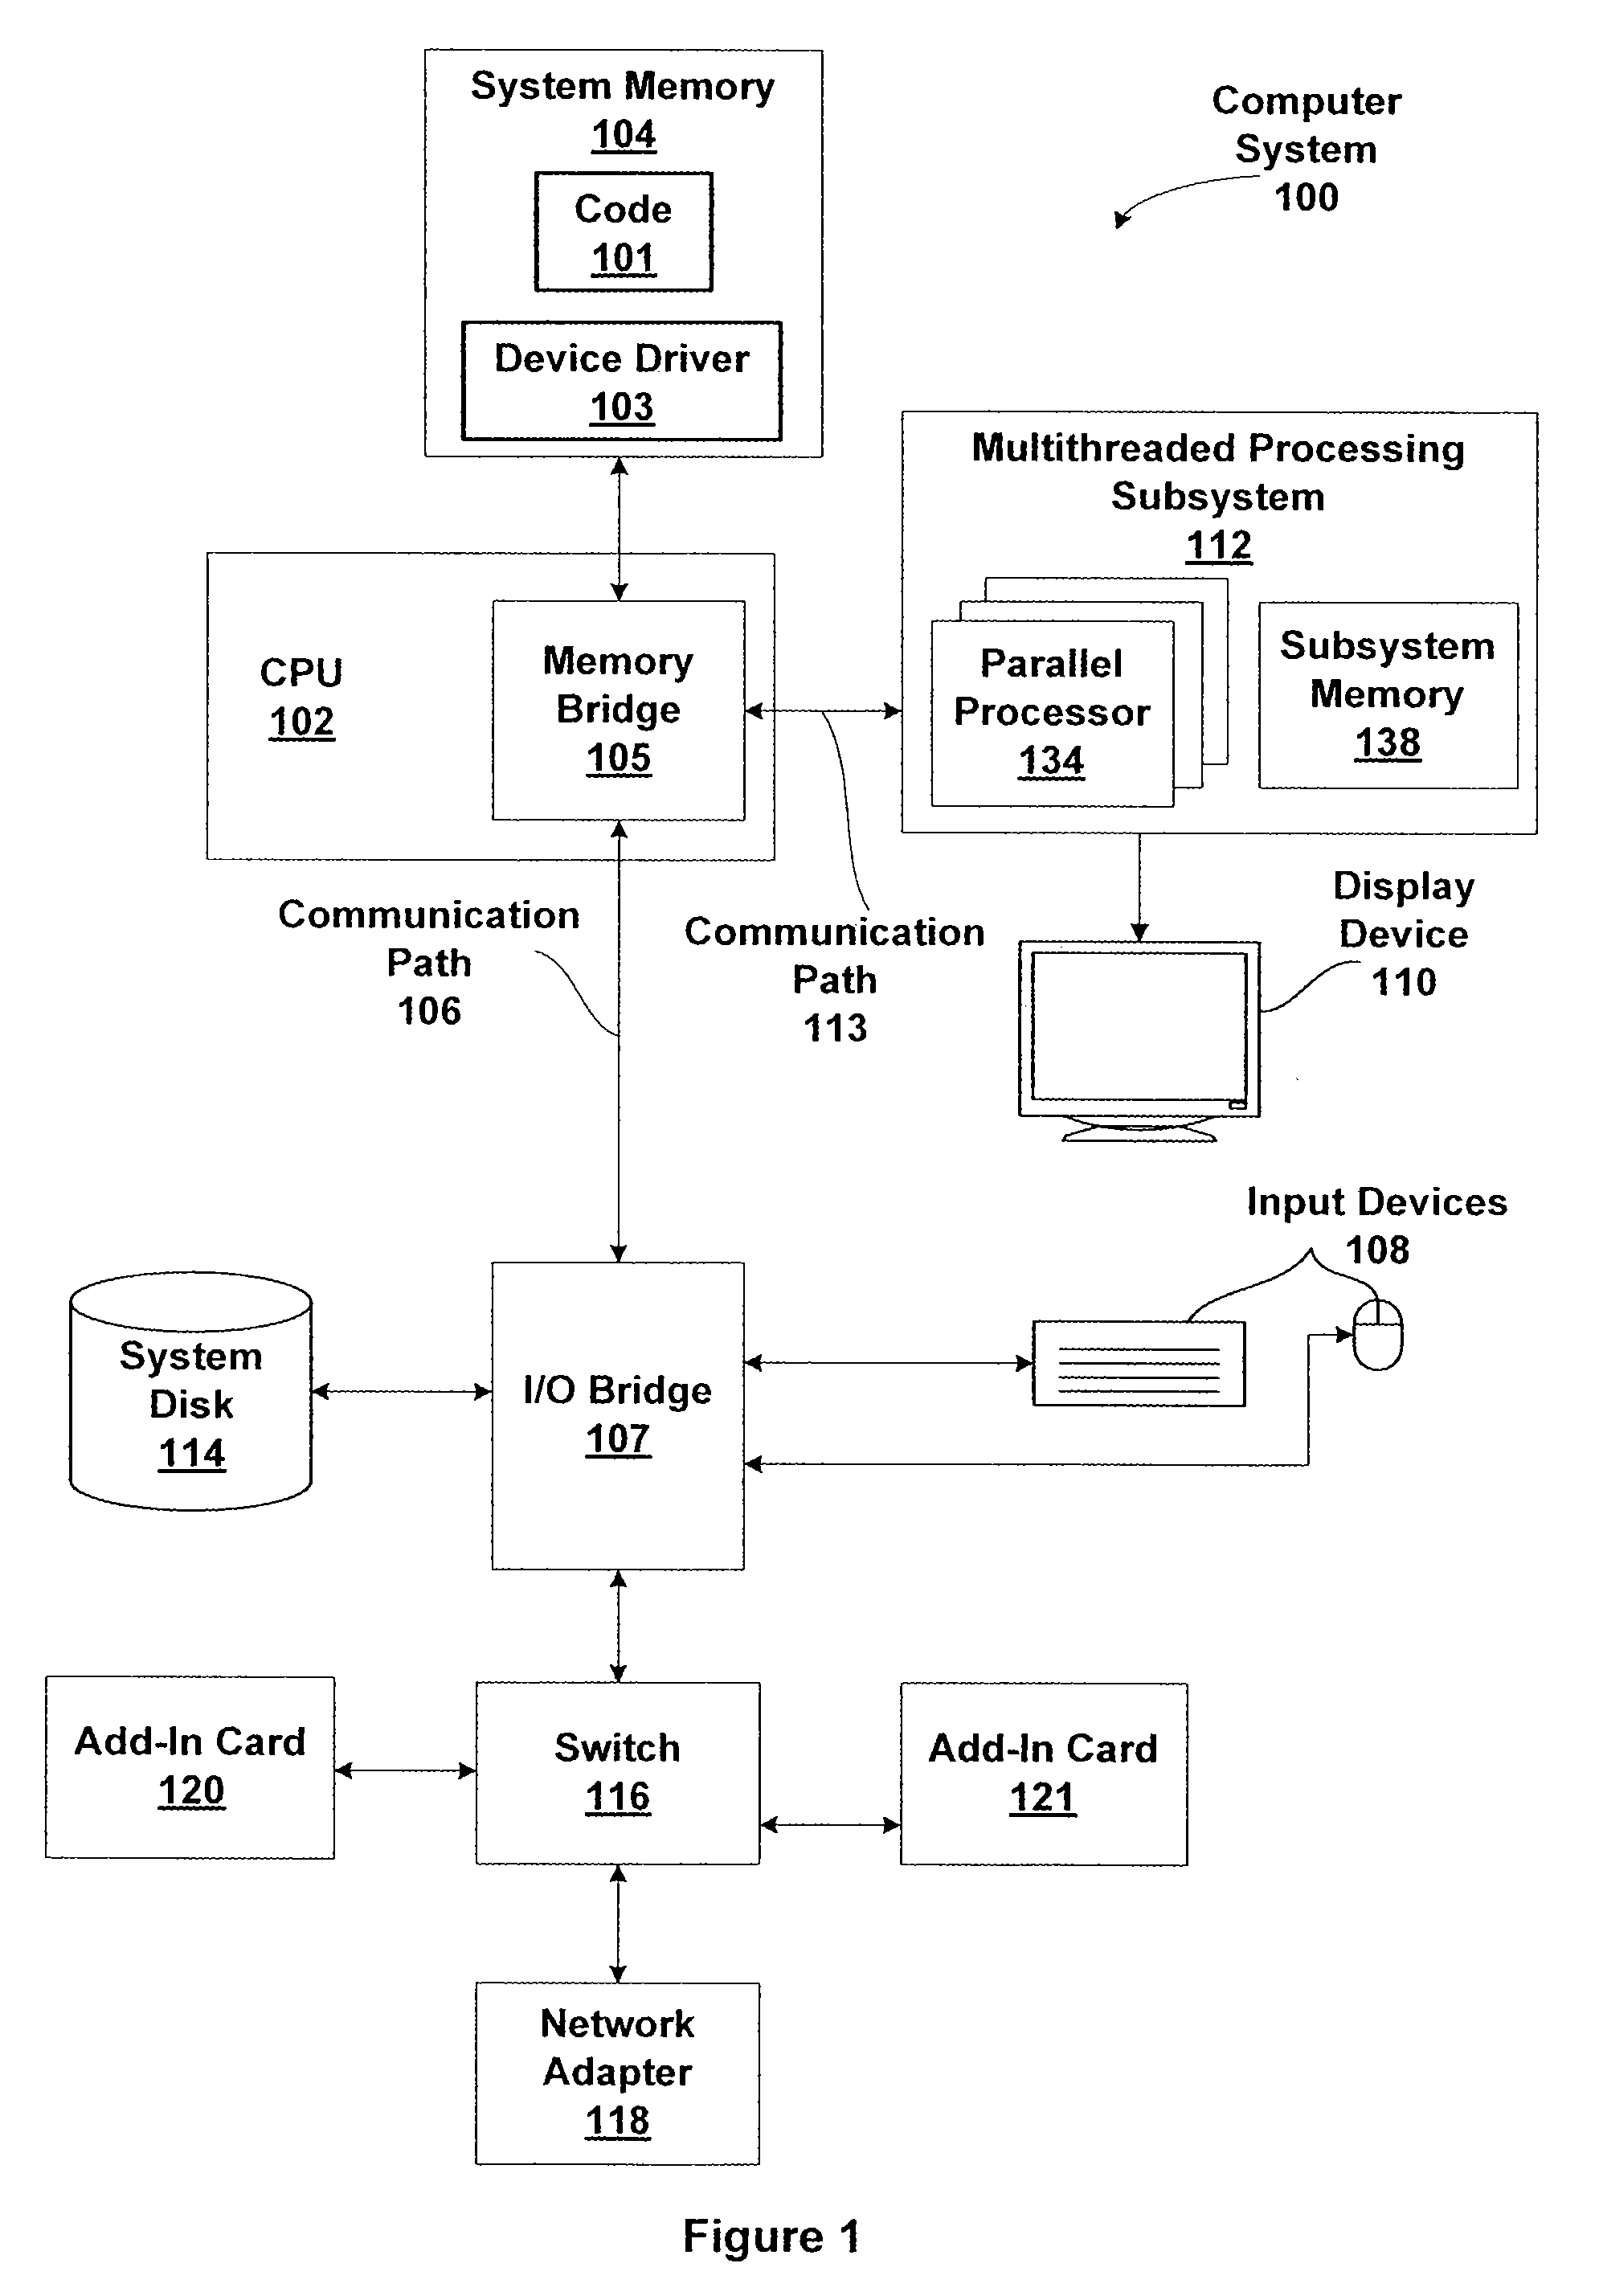
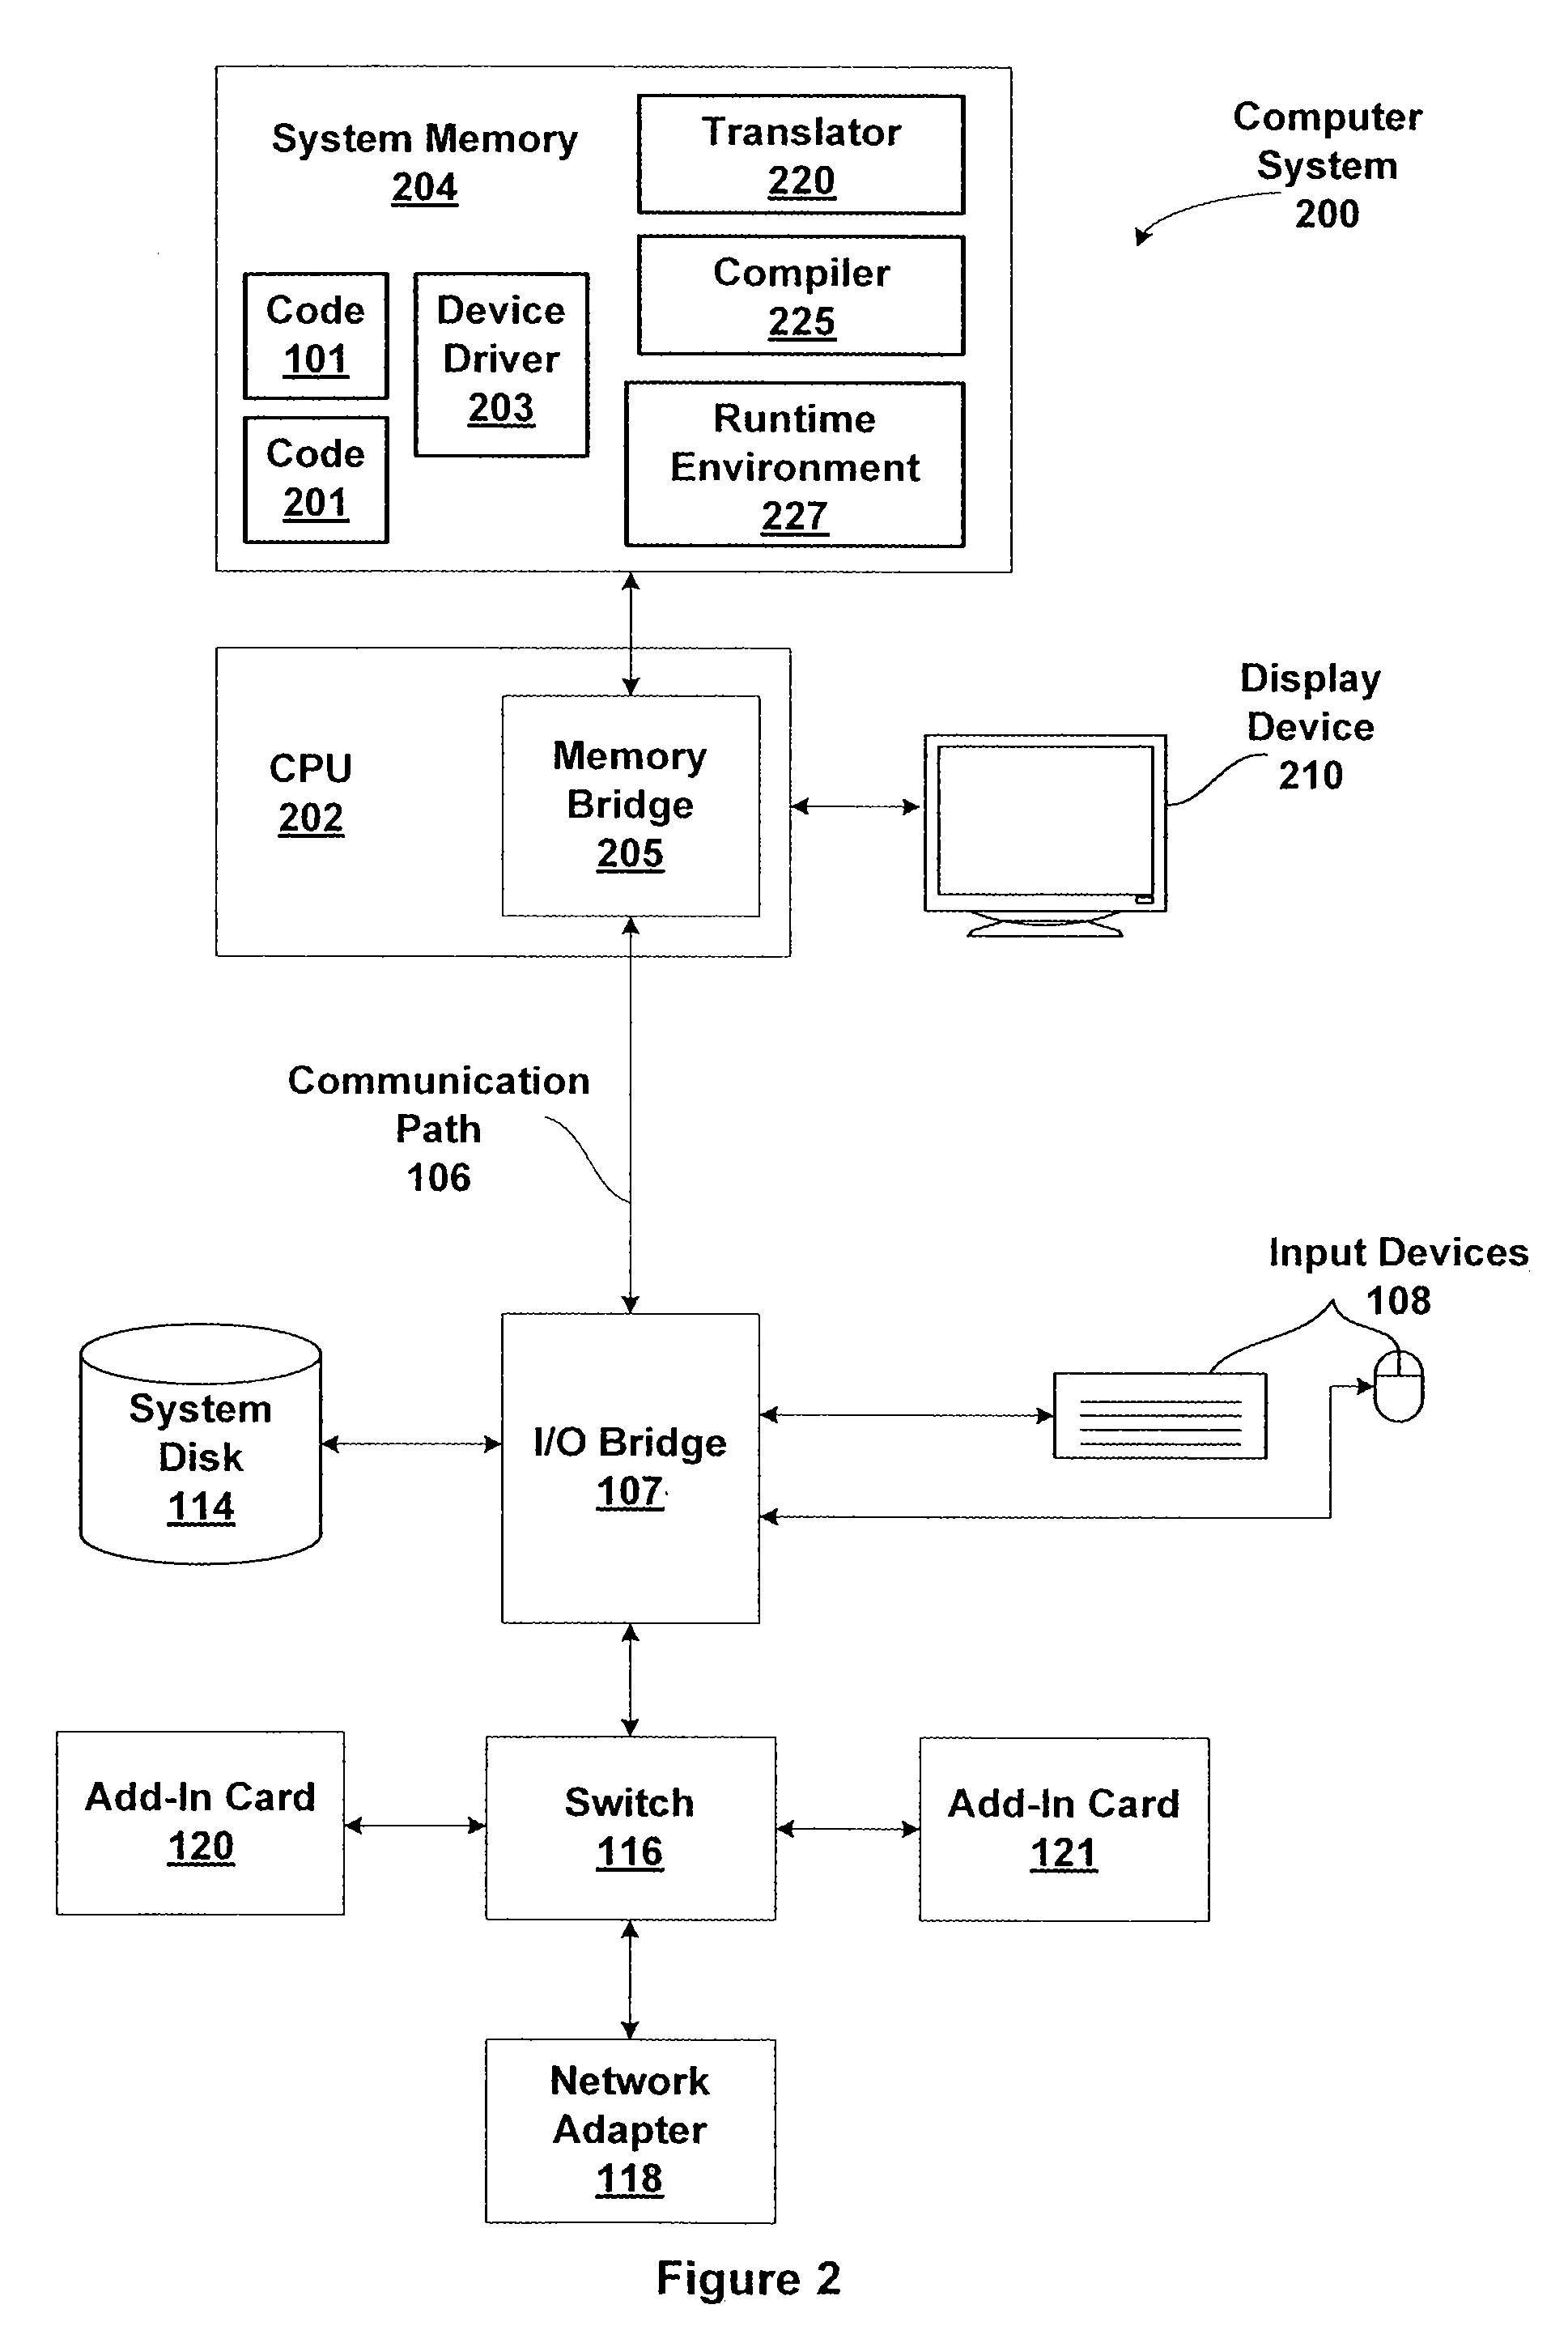
One embodiment of the present invention sets forth a technique for translating application programs written using a parallel programming model for execution on multi-core graphics processing unit (GPU) for execution by general purpose central processing unit (CPU). Portions of the application program that rely on specific features of the multi-core GPU are converted by a translator for execution by a general purpose CPU. The application program is partitioned into regions of synchronization independent instructions. The instructions are classified as convergent or divergent and divergent memory references that are shared between regions are replicated. Thread loops are inserted to ensure correct sharing of memory between various threads during execution by the general purpose CPU.
Owner:NVIDIA CORP
High-performance metagenomic data analysis system on basis of GPGPU (General Purpose Graphics Processing Units) and multi-core CPU (Central Processing Unit) hardware
InactiveCN103310125ASolve Computational BottlenecksSpeed upSpecial data processing applicationsData analysis systemGenomic data
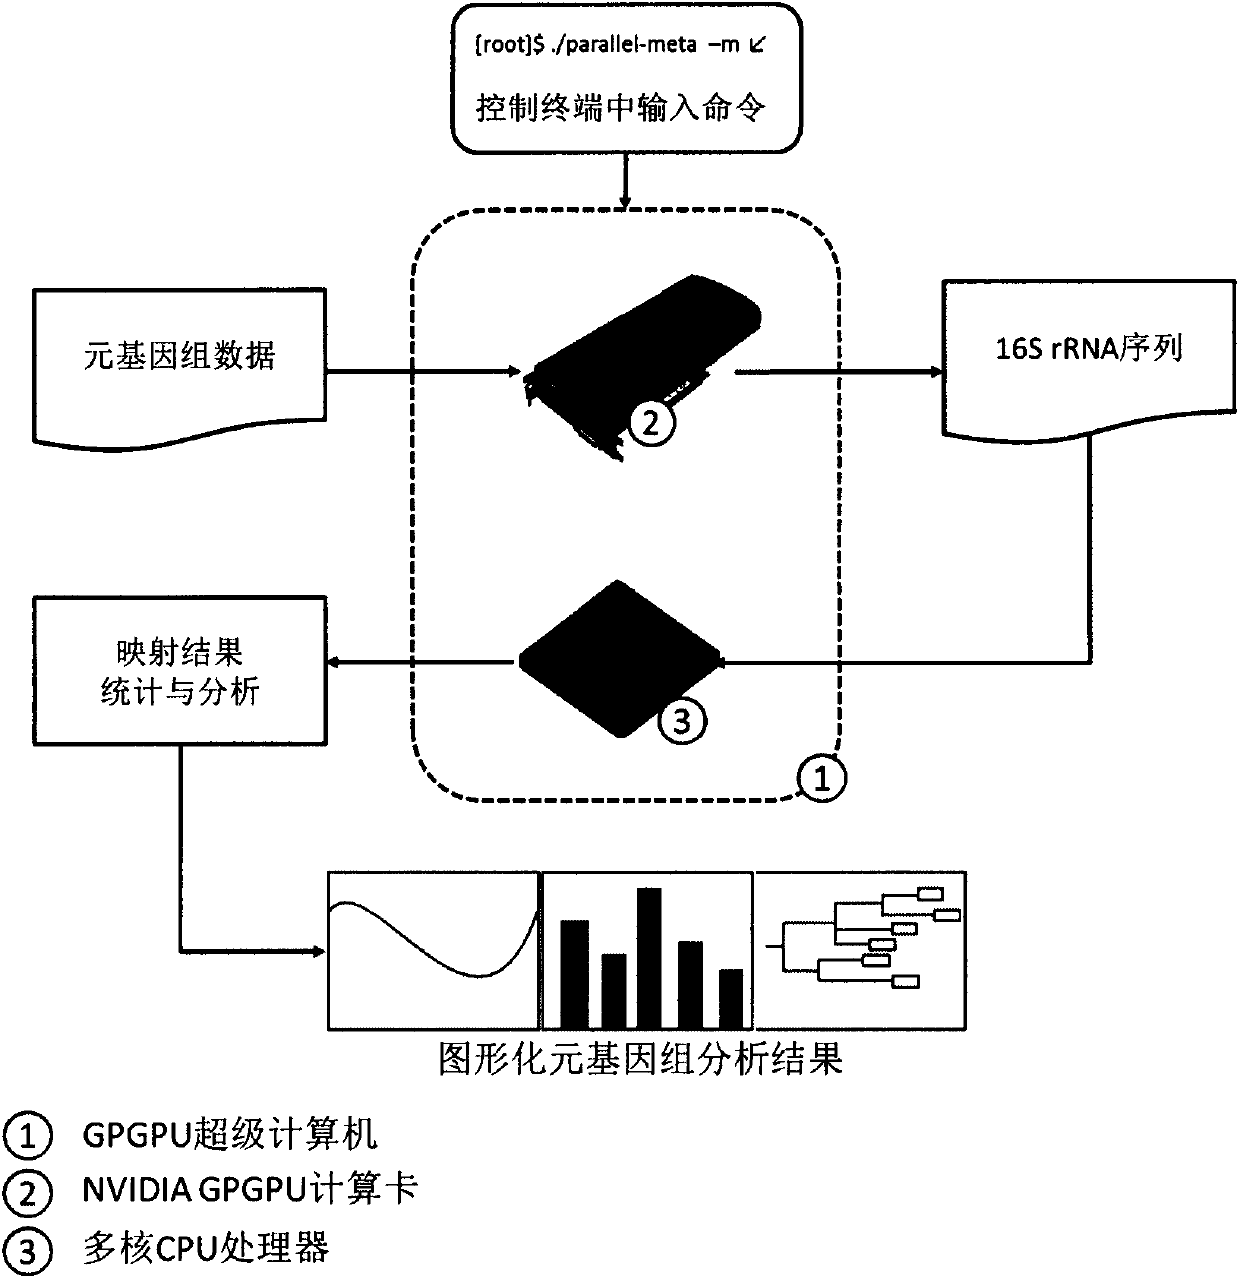
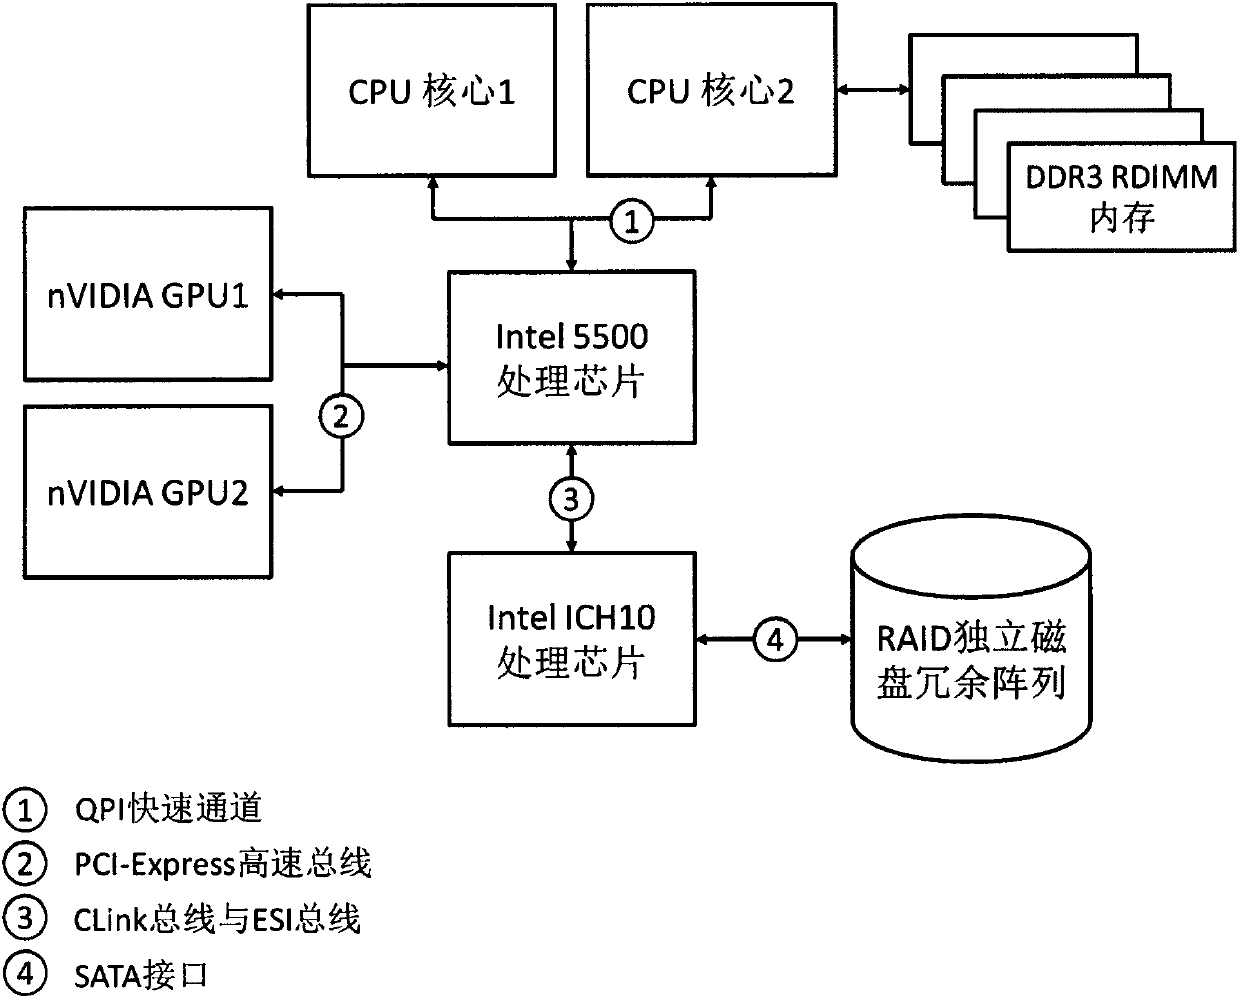
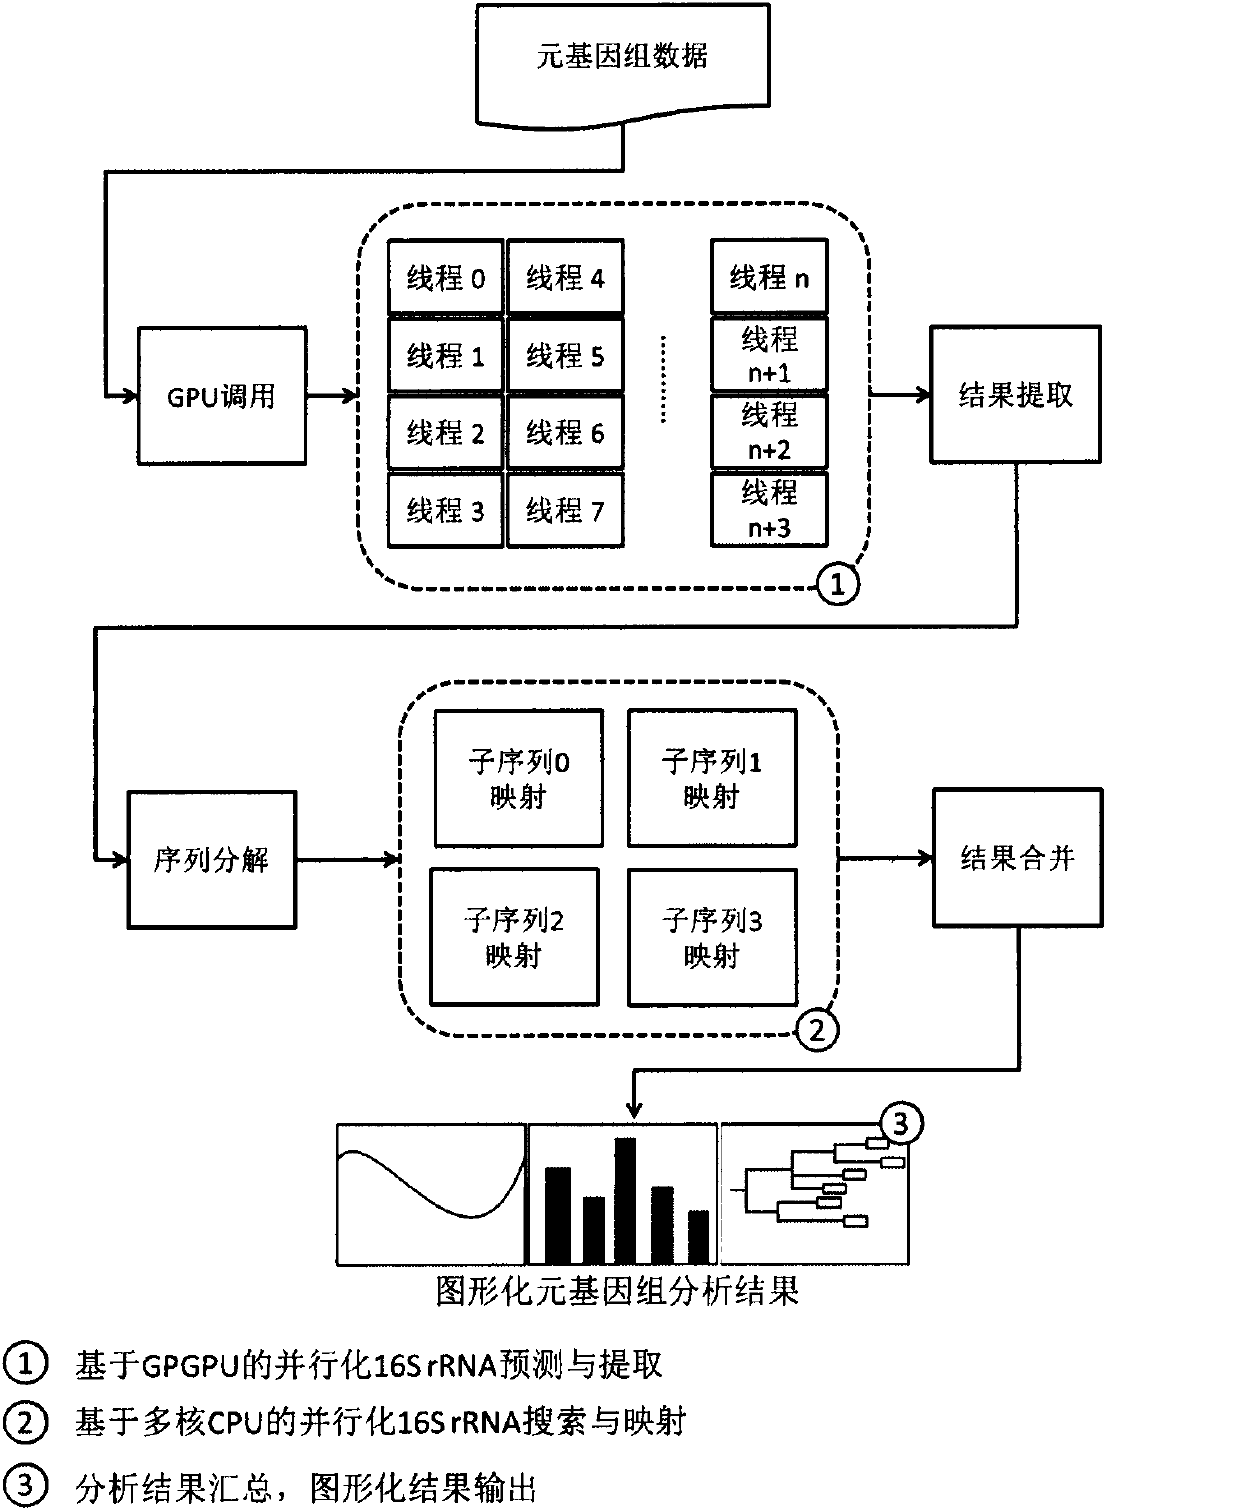
The invention relates to a high-performance metagenomic data analysis system on the basis of GPGPU (General Purpose Graphics Processing Units) and multi-core CPU (Central Processing Unit) hardware. Aiming at the condition that a conventional computer cannot meet the requirement on analysis of mass metagenomic data and according to the characteristic that the mass data in metagenomic data processing can be processed in parallel, the invention discloses a calculation analysis system which is on the basis of the GPGPU and the multi-core CPU hardware and combines software and hardware methods. A main module of the metagenomic calculation and analysis system on the basis of a GPGPU super computer comprises a GPGPU and multi-core CPU computer and a uniform software platform. The high-performance metagenomic data analysis system on the basis of the GPGPU and multi-core CPU hardware has the characteristics of (1) a high-performance parallel calculation and storage hardware system and (2) the high-performance uniform configurable software platform. Metagenomic sequence processing on the basis of the GPGPU hardware can obviously improve analysis efficiency of the metagenomic data.
Owner:QINGDAO INST OF BIOENERGY & BIOPROCESS TECH CHINESE ACADEMY OF SCI
SIMT stack and thread scheduling optimization method and device for GPGPU branch instruction, medium and GPGPU architecture
ActiveCN119902873AProgram initiation/switchingConcurrent instruction executionGeneral purposeGraphics
The invention relates to the technical field of GPGPU (General Purpose Graphics Processing Unit), and relates to an SIMT stack and thread scheduling optimization method and device for GPGPU (General Purpose Graphics Processing Unit) branch instructions, a medium and a GPGPU architecture. The method comprises the steps that in a GPGPU, an SIMT stack is optimized, an SM unit is expanded to be a double-instruction assembly line, and a main thread beam scheduler and an auxiliary thread beam scheduler are arranged. And in a non-branch state, half threads of each tube of the scheduler are executed in parallel by the assembly line. When a branch instruction is encountered, instruction addresses, thread masks and branch reunion points of the two branch paths are pressed into the SIMT stack. Judging conflicts according to the thread masks; if conflicts exist, performing serial execution; and if no conflict exists, executing on double pipelines in parallel. And when the branch is completed to a reunion point, the SIMT stack pops up an entry, and the execution is continued. The method has remarkable effects in the aspects of improving the thread resource utilization rate, improving the calculation efficiency, simplifying the branch control complexity, enhancing the GPGPU flexibility and the like.

Owner:SHANDONG INSPUR SCI RES INST CO LTD
Key thread bundle scheduling method and device
PendingCN119127447Arun fastAvoid extended runtime issuesProgram initiation/switchingResource allocationGeneral purposeGraphics
The invention discloses a key thread bundle scheduling method and device, and relates to the technical field of GPGPU (General Purpose Graphics Processing Unit), a thread bundle which is executed in sequence and a thread bundle which is branched are scheduled at different frequencies, different scheduling schemes are appointed for the two types of thread bundles in the mode, the parallel performance of the sequence thread bundle is ensured not to be influenced to the greatest extent, and the scheduling efficiency is improved. And meanwhile, the operation of the branch thread bundles is accelerated, the problem that the operation time of the thread bundles is prolonged due to excessive thread branches is avoided, and the combining performance of the universal graphics processor is improved to a certain extent.

Owner:SHANDONG INSPUR SCI RES INST CO LTD
Parallel optimization method and system for GPGPU (General Purpose Graphics Processing Unit) instruction execution stage
The invention provides a parallel optimization method and system for a GPGPU (General Purpose Graphics Processing Unit) instruction execution stage, and the method comprises the steps: splitting an input instruction into a plurality of sub-instructions which can be independently scheduled based on an instruction type, operand dependency analysis and a hardware resource real-time state, and generating a dependency table to record the input and output association of the sub-instructions; acquiring real-time load data of the calculation unit, the storage unit and the communication unit, and distributing the sub-instructions to the calculation unit, the storage unit or the communication unit by adopting a priority dynamic adjustment algorithm and combining instruction key path analysis; according to the dependency relationship of the sub-instructions and the availability of hardware resources, the execution sequence of the sub-instructions is adjusted to maximize the degree of parallelism; and analyzing the dependency relationship among the sub-instructions in real time to maximize the degree of parallelism to dynamically adjust a parallel execution strategy so as to realize serial execution of dependent instructions and parallel execution of non-dependent instructions. According to the method, the complexity of instruction compiling is reduced, the efficiency of instruction compiling is improved, and meanwhile extra consumed time is reduced.

Owner:HEFEI SUMICROELECTRONICS TECH CO LTD
General purpose processing unit with low power digital signal processing (DSP) mode
InactiveUS9274591B2Reduce power consumptionEnergy efficient ICTPower supply for data processingDigital signal processingGeneral purpose
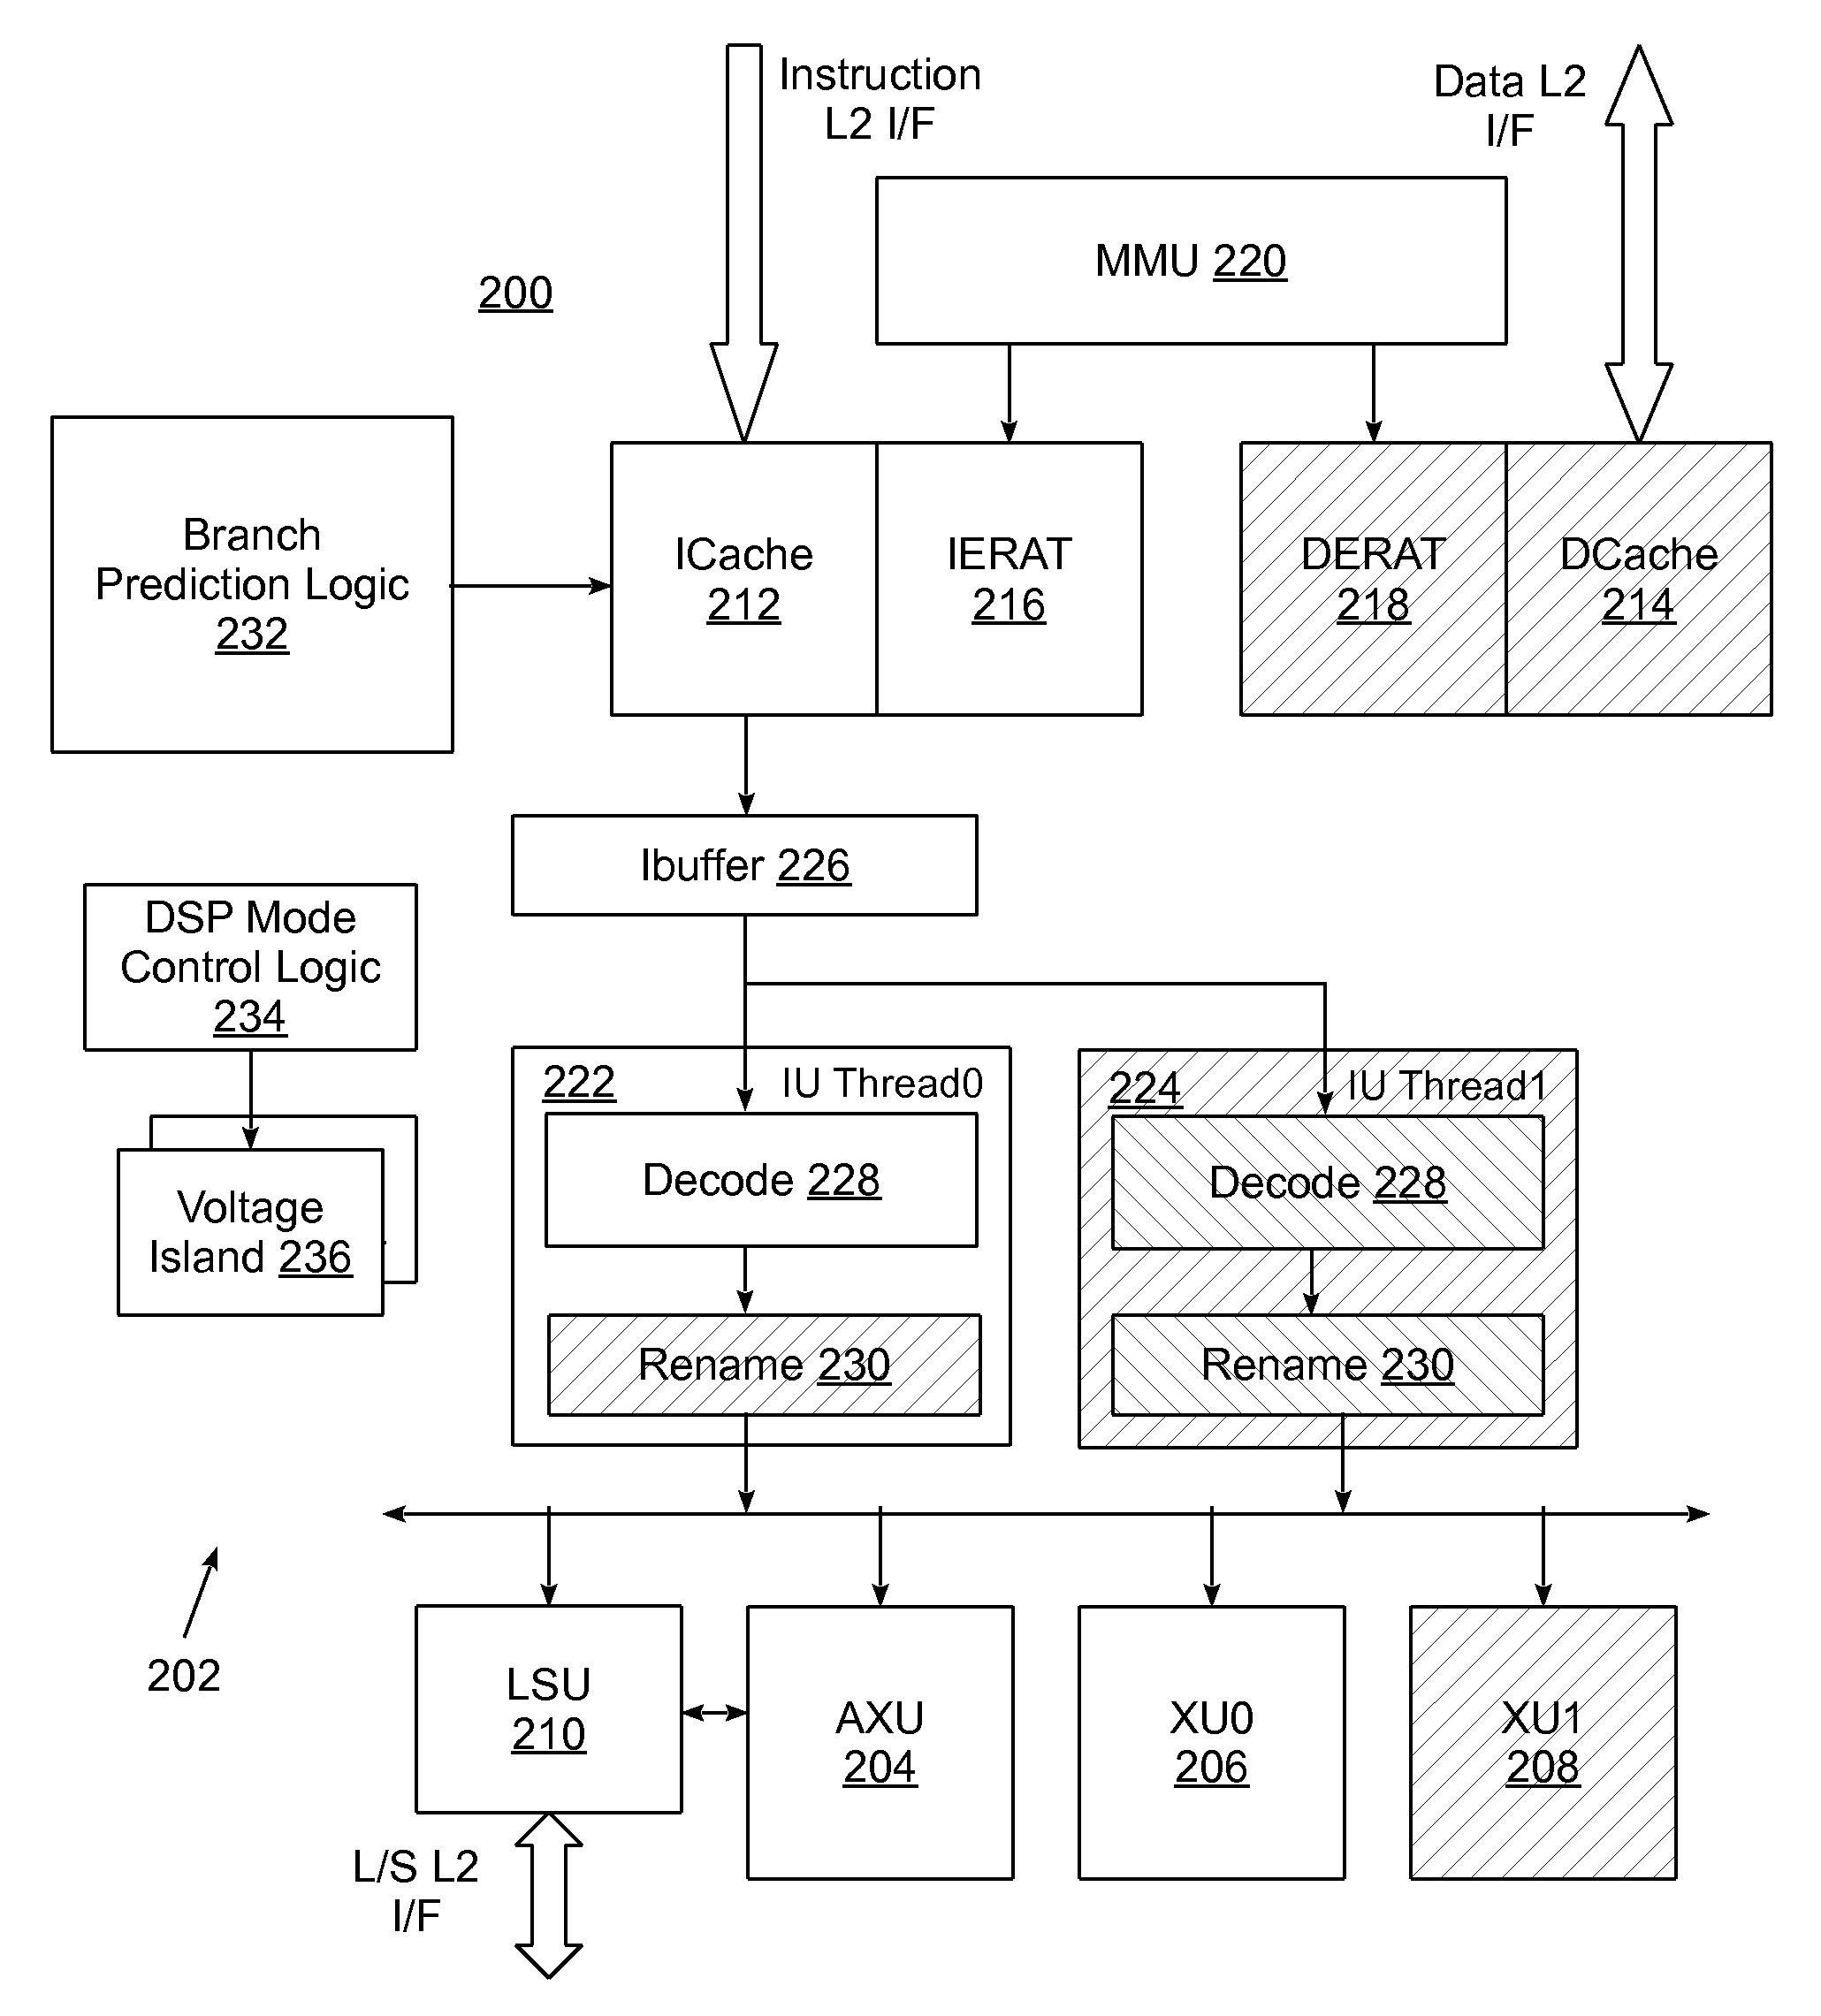
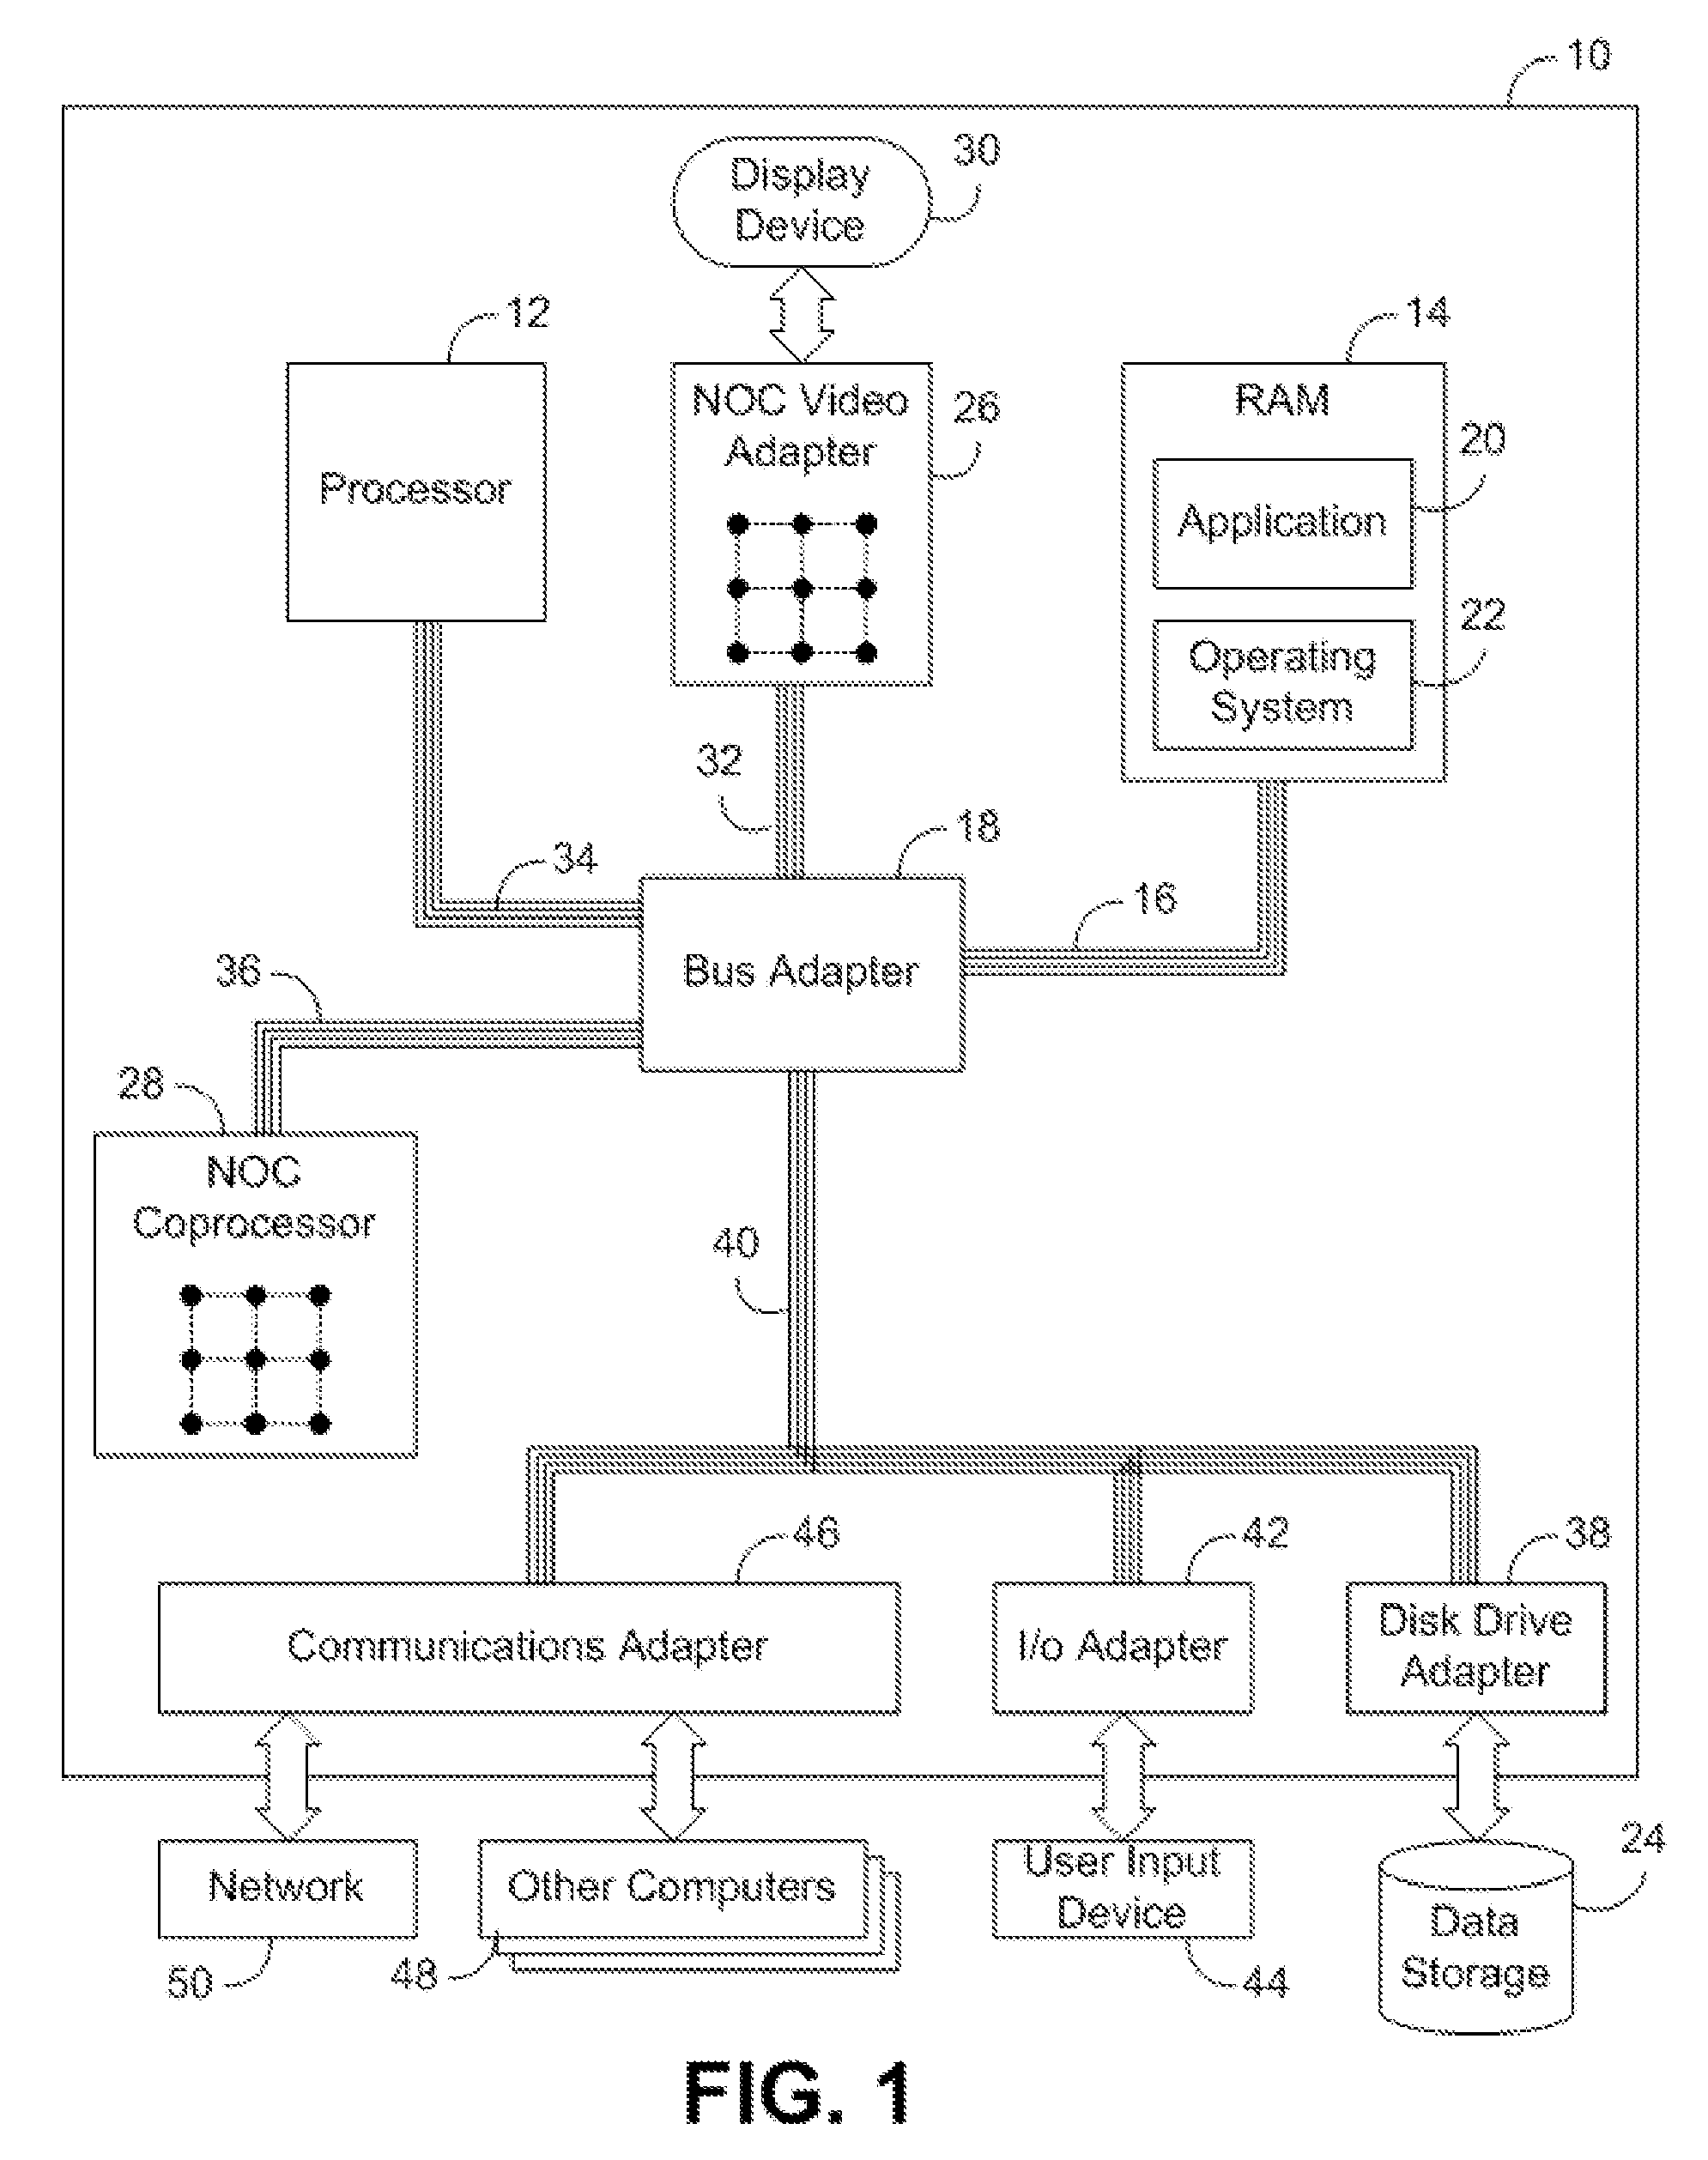
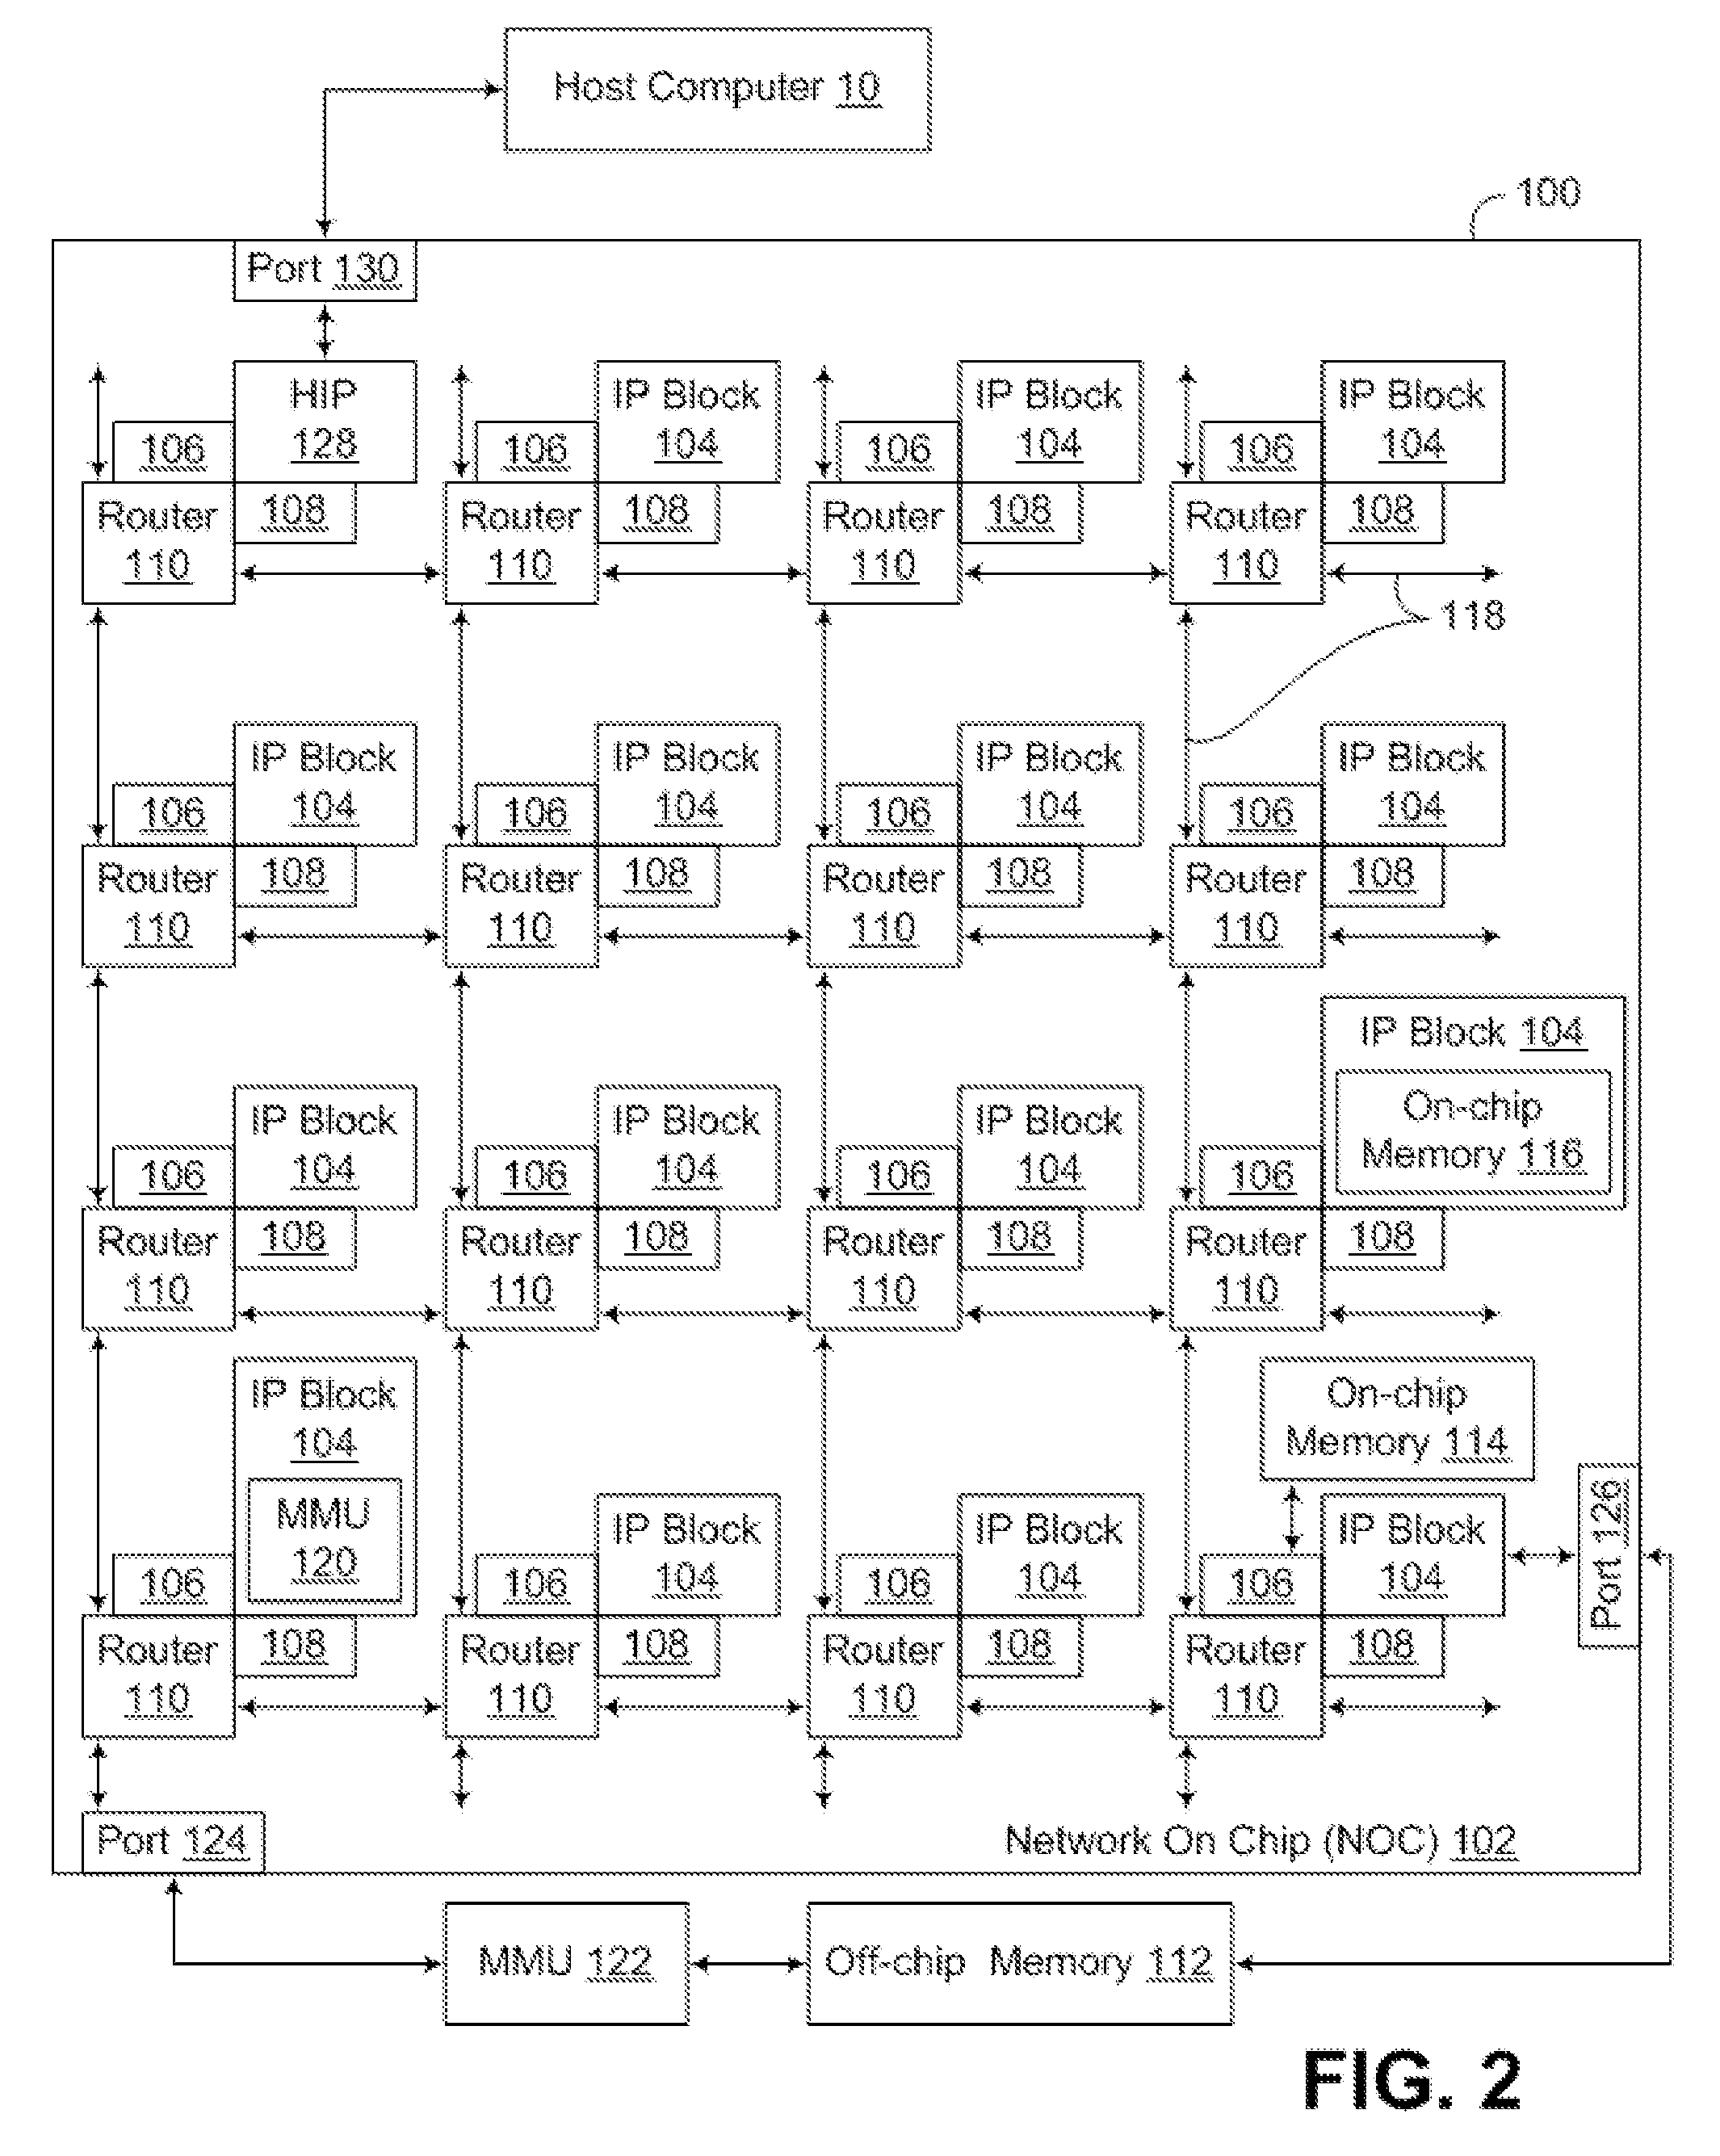
A method and circuit arrangement utilize a general purpose processing unit having a low power DSP mode for reconfiguring the general purpose processing unit to efficiently execute DSP workloads with reduced power consumption. When in a DSP mode, one or more of a data cache, an execution unit, and simultaneous multithreading may be disabled to reduce power consumption and improve performance for DSP workloads. Furthermore, partitioning of a register file to support multithreading, and register renaming functionality, may be disabled to provide an expanded set of registers for use with DSP workloads. As a result, a general purpose processing unit may be provided with enhanced performance for DSP workloads with reduced power consumption, while also not sacrificing performance for other non-DSP / general purpose workloads.
Owner:GLOBALFOUNDRIES INC
Computational resource pipelining in general purpose graphics processing unit
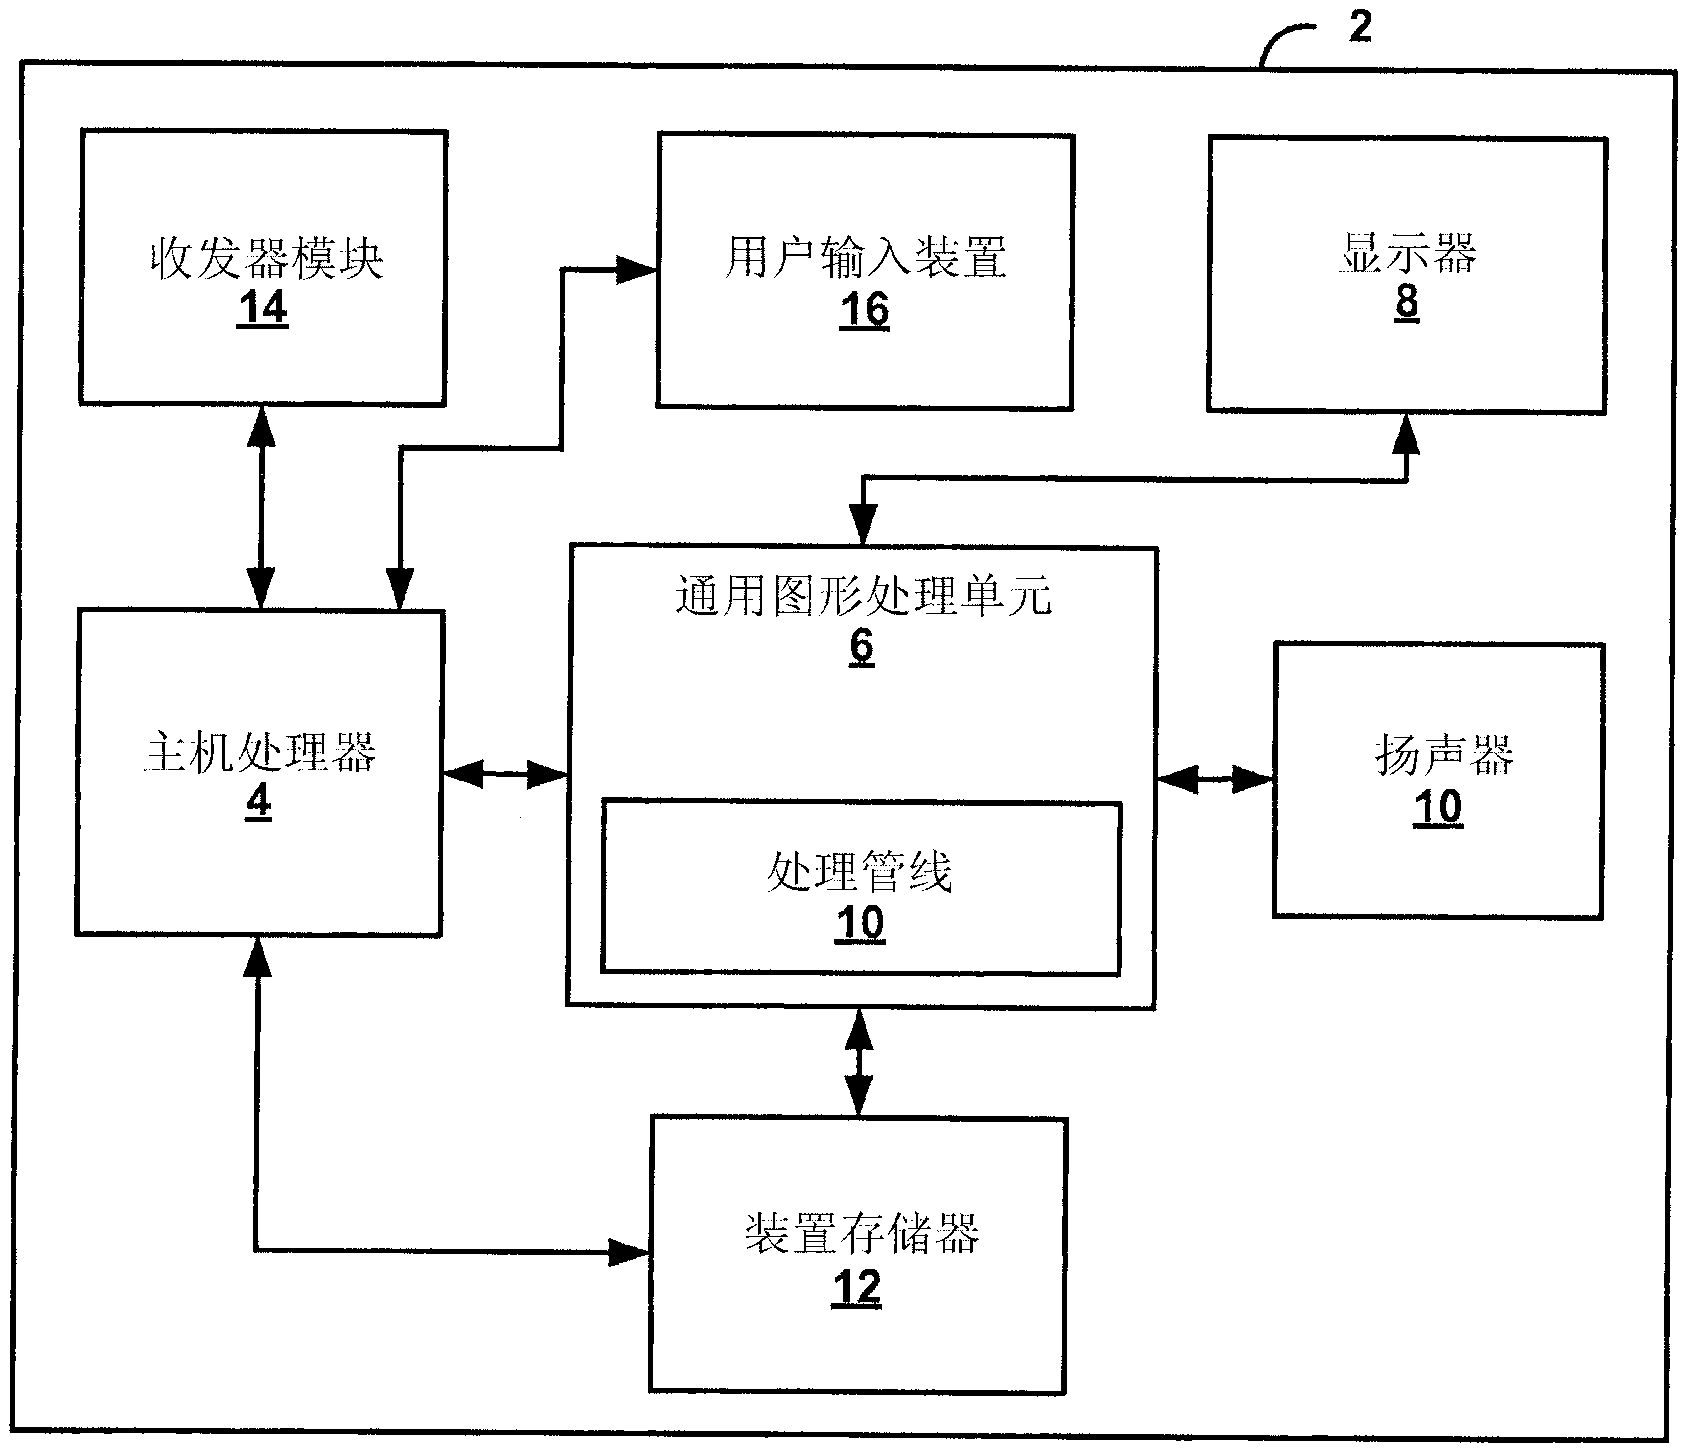
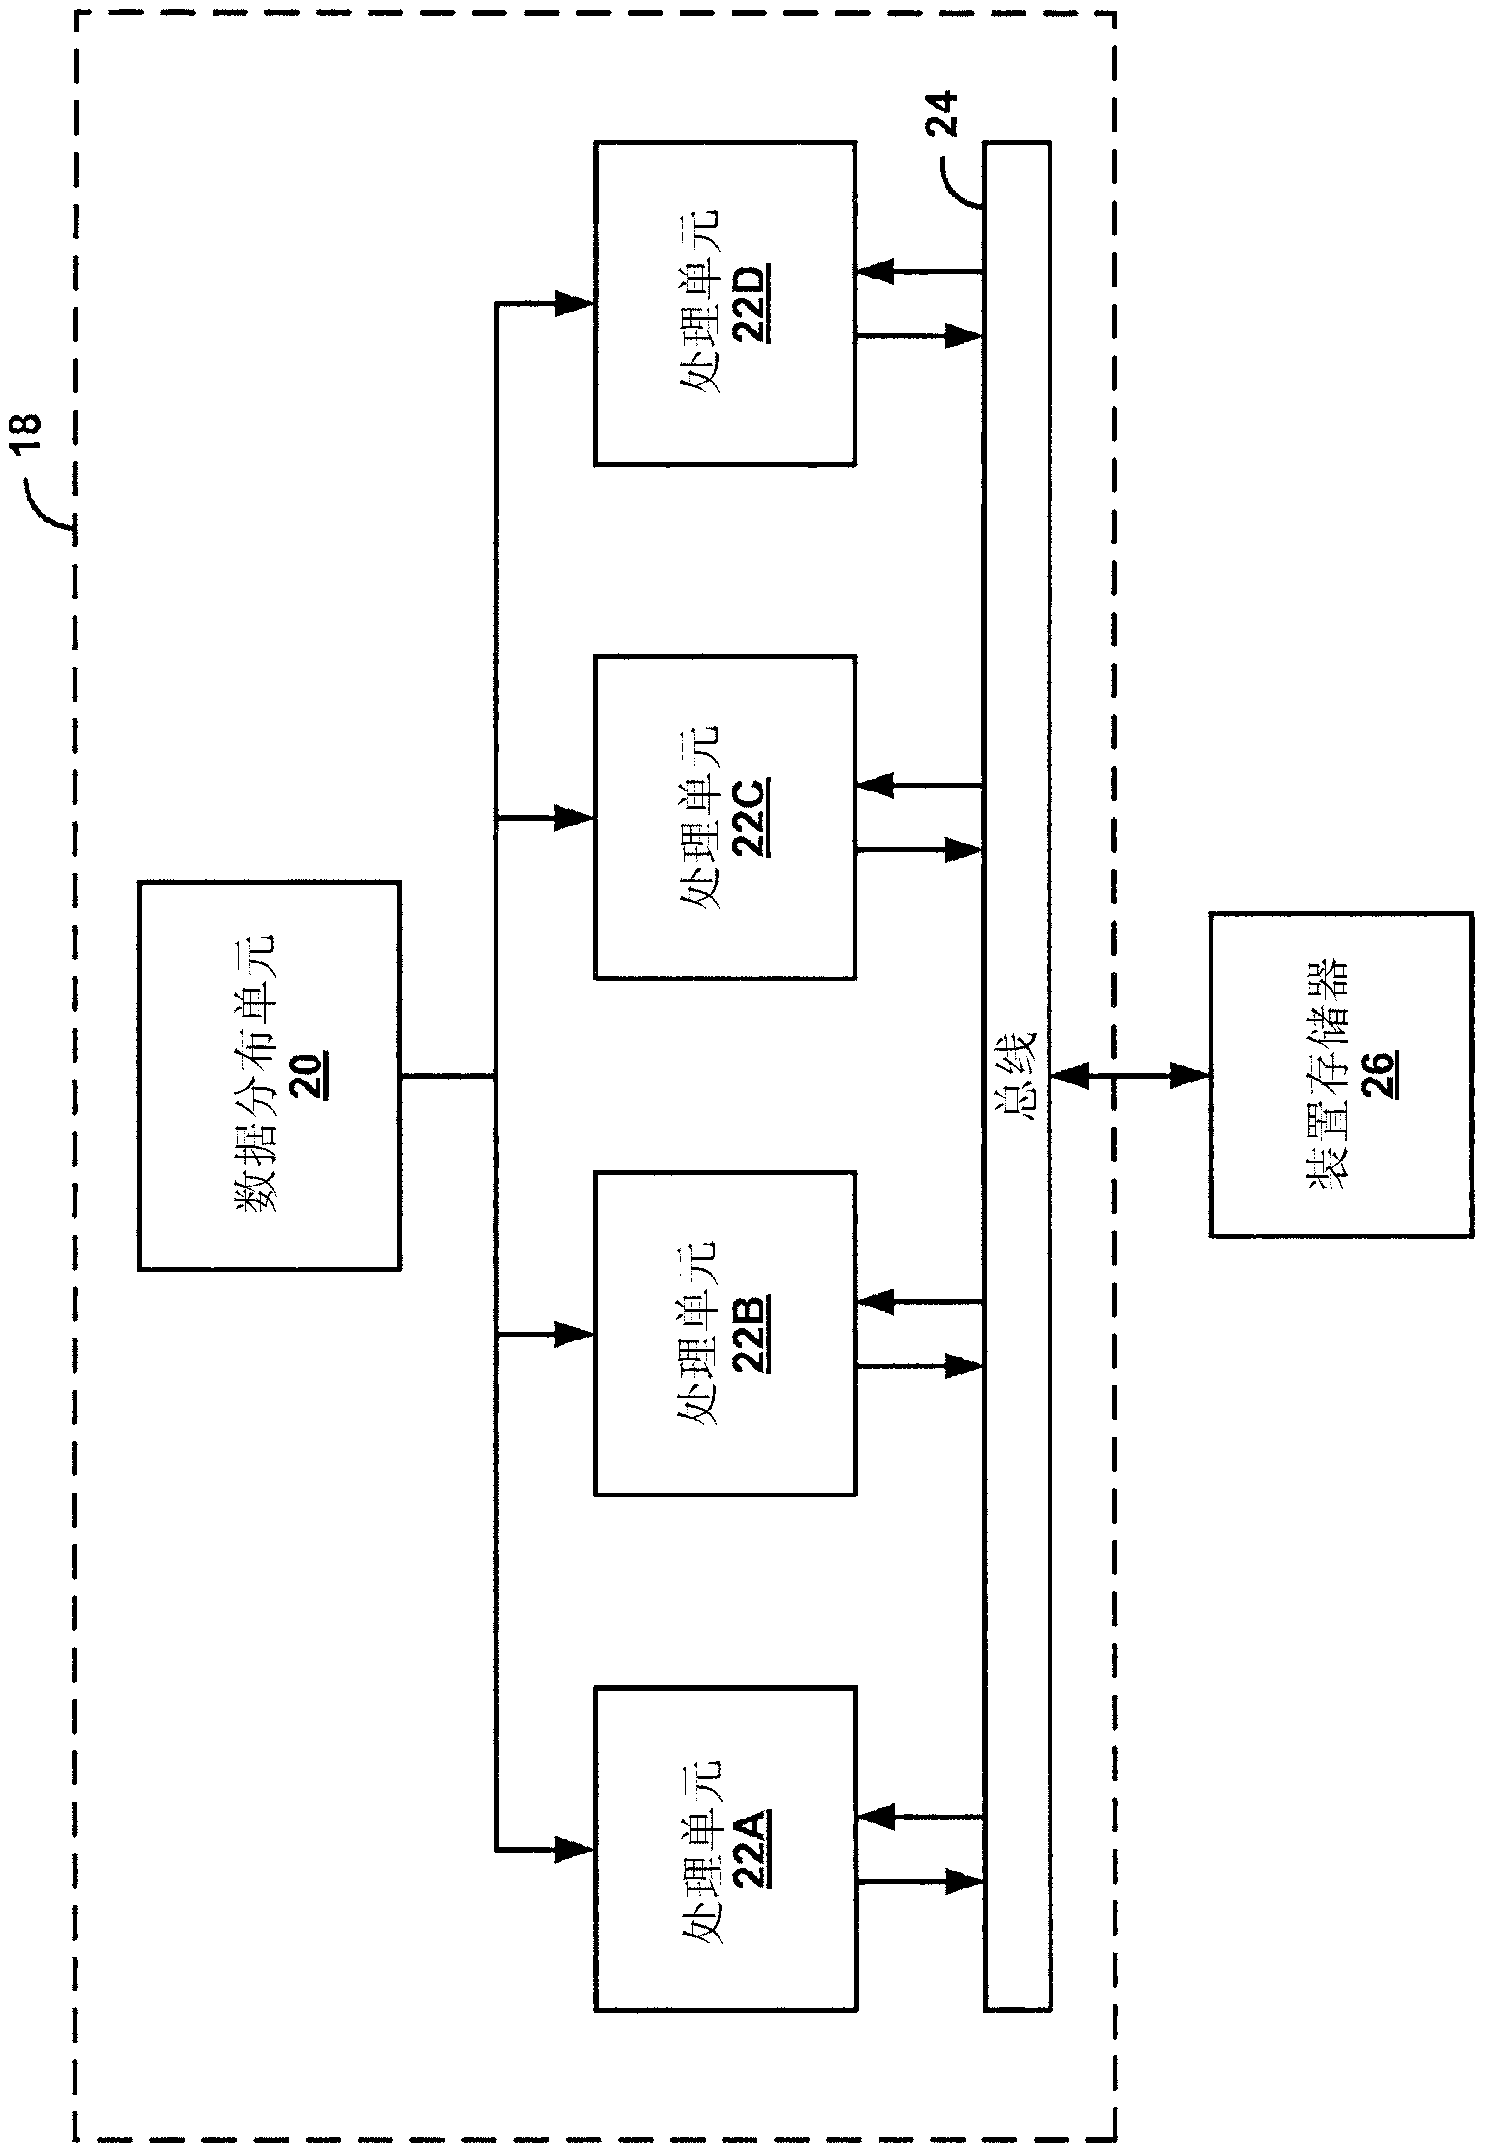
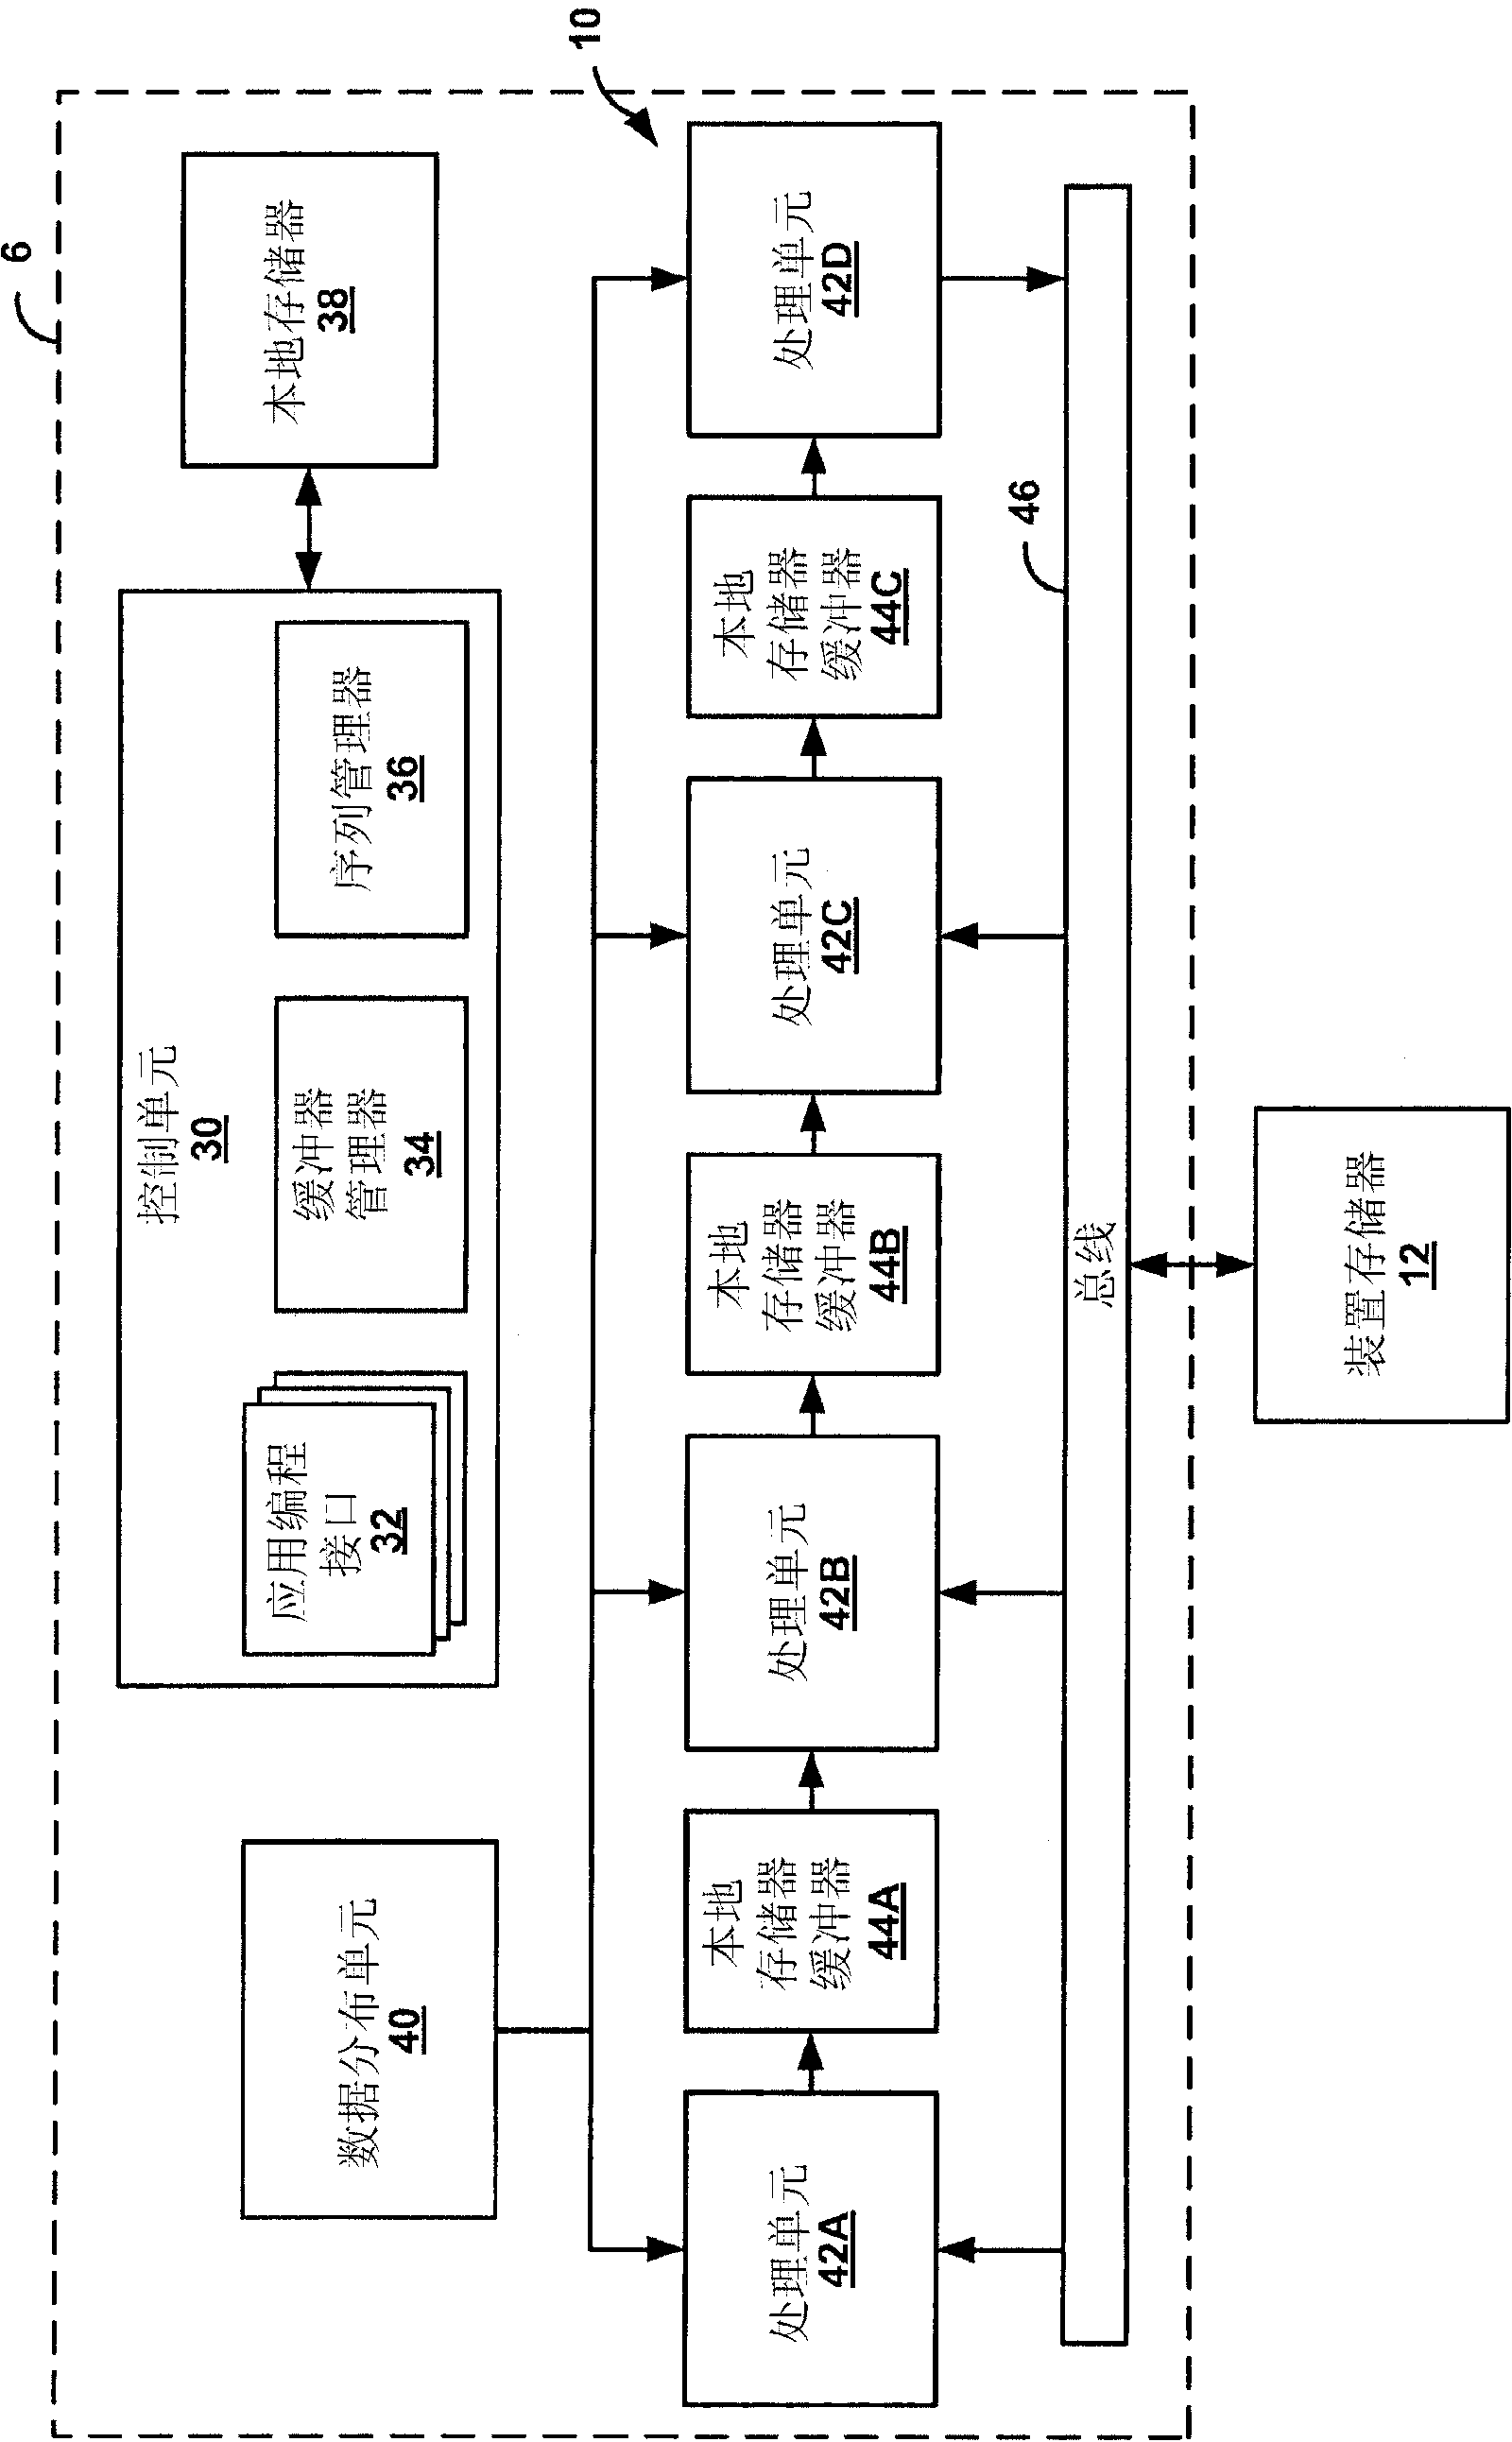
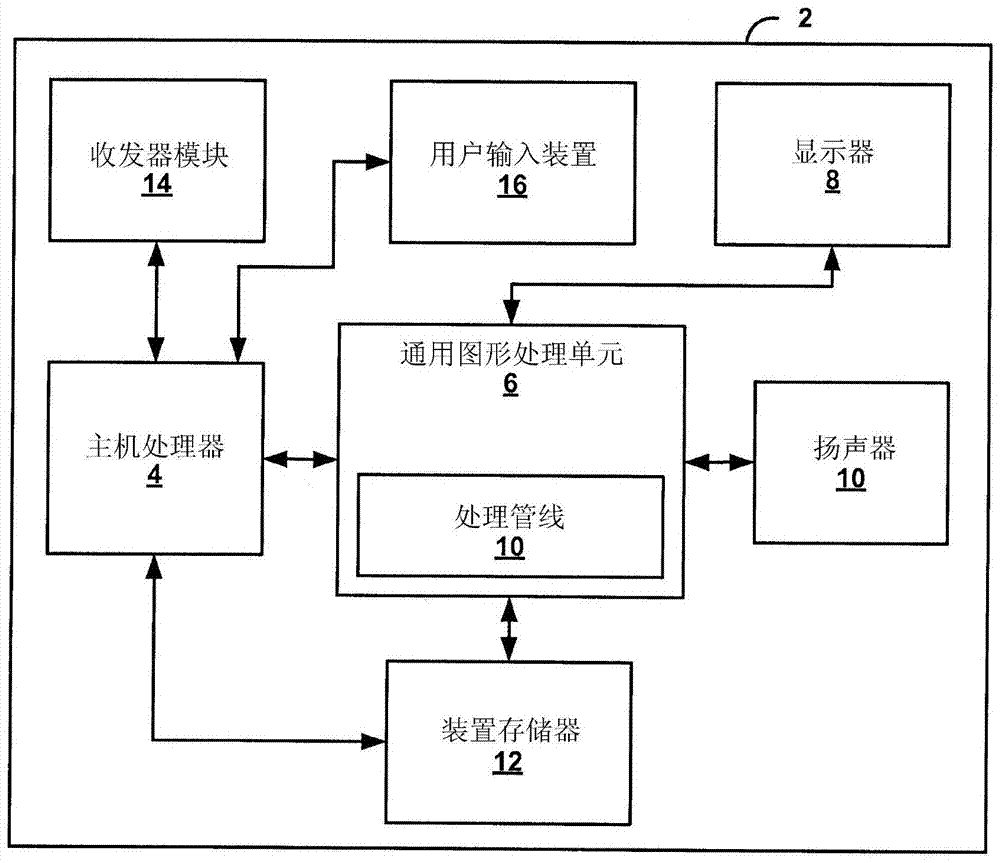
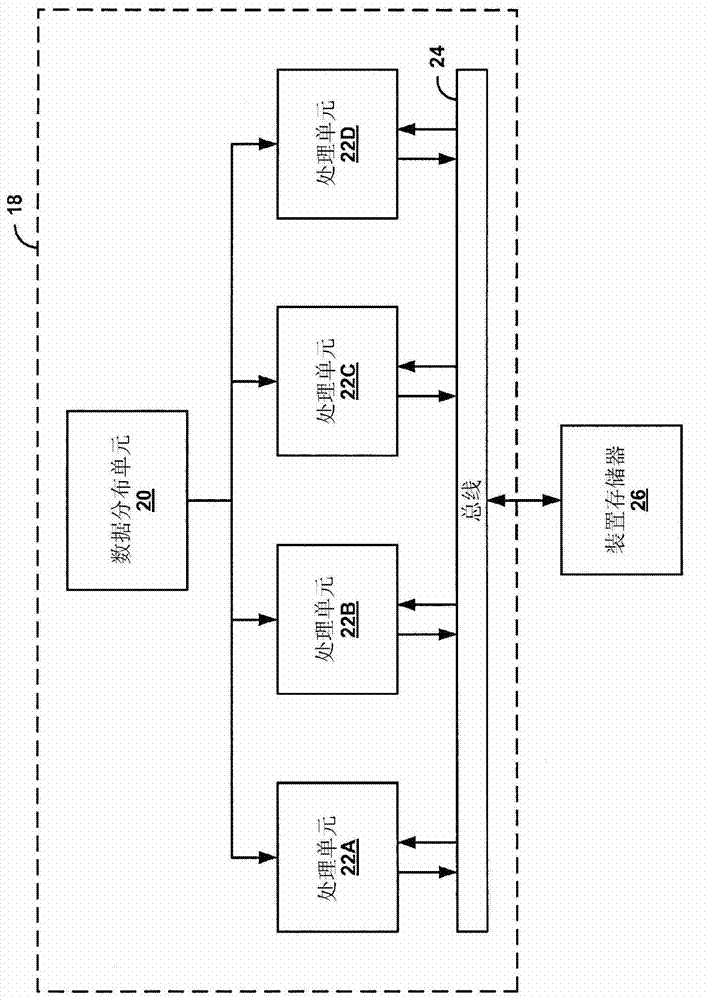
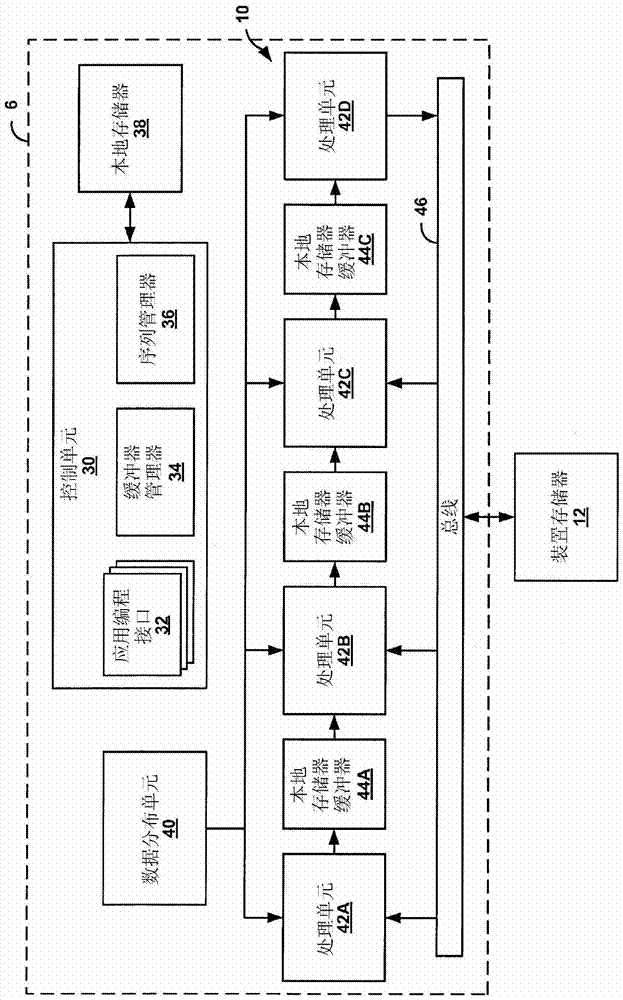
This disclosure describes techniques for extending the architecture of a general purpose graphics processing unit (GPGPU) with parallel processing units to allow efficient processing of pipeline-based applications. The techniques include configuring local memory buffers connected to parallel processing units operating as stages of a processing pipeline to hold data for transfer between the parallel processing units. The local memory buffers allow on-chip, low-power, direct data transfer between the parallel processing units. The local memory buffers may include hardware-based data flow control mechanisms to enable transfer of data between the parallel processing units. In this way, data may be passed directly from one parallel processing unit to the next parallel processing unit in the processing pipeline via the local memory buffers, in effect transforming the parallel processing units into a series of pipeline stages.
Owner:QUALCOMM INC
Inter-thread operand collection strategy and application system
The invention discloses an inter-thread operand collection strategy and an application system, and relates to the technical field of cross-thread data sharing of a GPGPU (General Purpose Graphics Processing Unit). In order to solve the problems of read-write delay and cache occupation caused by synchronous operation of the GPGPU in a data sharing scene, the scheme adopted by the invention comprises a decoding unit, a transmitting unit and a write-back unit, and the three units cooperate with one another to form a complete cross-thread data read-write path. Wherein the decoding unit is responsible for decoding a self-defined instruction and remapping a thread index; the transmitting unit undertakes the tasks of instruction caching, data synchronization control and cross-thread data reading; and the write-back unit is responsible for writing an instruction execution result back to the storage space and updating the state of a related register. According to the method, the parallel performance of the GPGPU in a multi-thread parallel computing scene can be improved.

Owner:SHANDONG INSPUR SCI RES INST CO LTD
Singular value decomposition acceleration method and device based on GPGPU (General Purpose Graphics Processing Unit)
InactiveCN119537381Aensure non-interferenceimprove performanceResource allocationComplex mathematical operationsSingular value decompositionGeneral purpose
The invention discloses a GPGPU (General Purpose Graphics Processing Unit)-based singular value decomposition acceleration method and equipment, belongs to the technical field of computer technologies, and is used for solving the problems that when an SVD (Singular Value Decomposition) technology is applied to hardware, a relatively large calculation amount and a large amount of memory occupation can be caused, and different index strategies influence the parallel operation efficiency of the hardware, so that the hardware performance is poor. And the overall performance of hardware is reduced. The method comprises the steps of obtaining an index sequence of a to-be-decomposed matrix; generating a plurality of groups of index sequence pairs based on the index sequence; sending a kernel function kernel to the GPGPU, and traversing each group of index sequence pairs through each block in the kernel function kernel; decomposing matrix data corresponding to the first group of index sequences in the to-be-decomposed matrix through the queue in each block to obtain a first decomposed matrix; and decomposing matrix data corresponding to the second group of index sequences in the first decomposition matrix to obtain a second decomposition matrix, and so on until the last group of decomposition matrix is obtained, thereby obtaining a singular value decomposition result.

Owner:SHANDONG INSPUR SCI RES INST CO LTD
Cryptographic computations on general purpose graphics processing units
ActiveUS8106916B1Release resourcesCryptographic computations are performed faster and more efficientlyUnauthorized memory use protectionHardware monitoringGeneral purposeGraphics processing unit
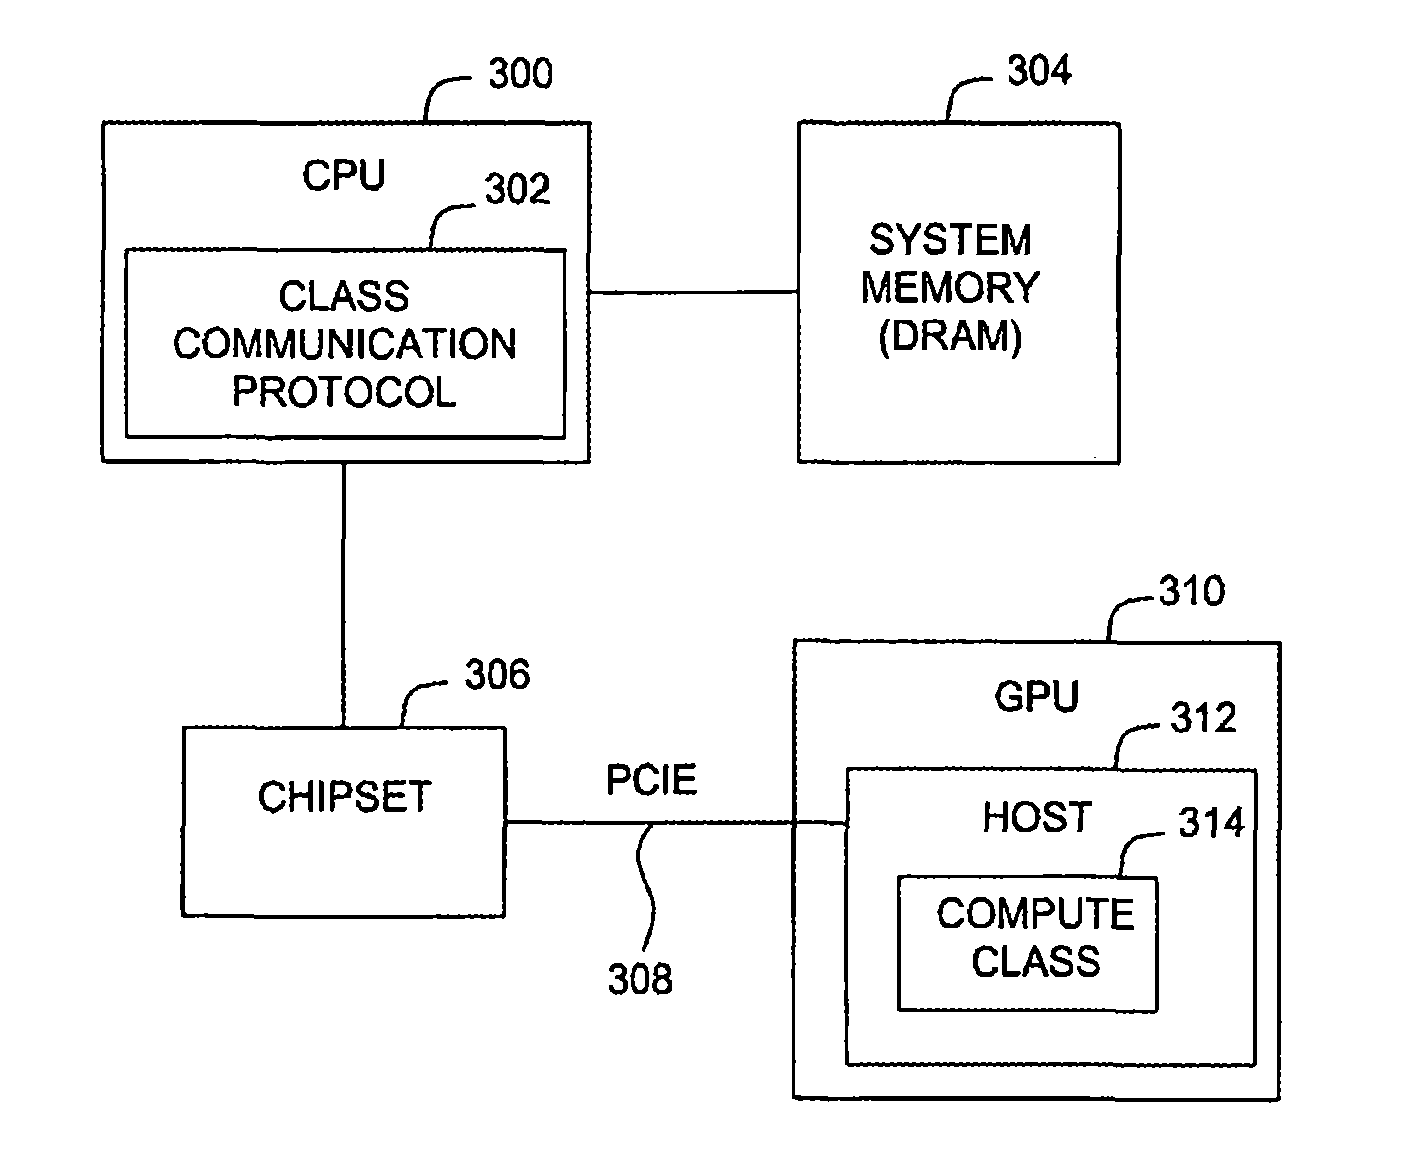
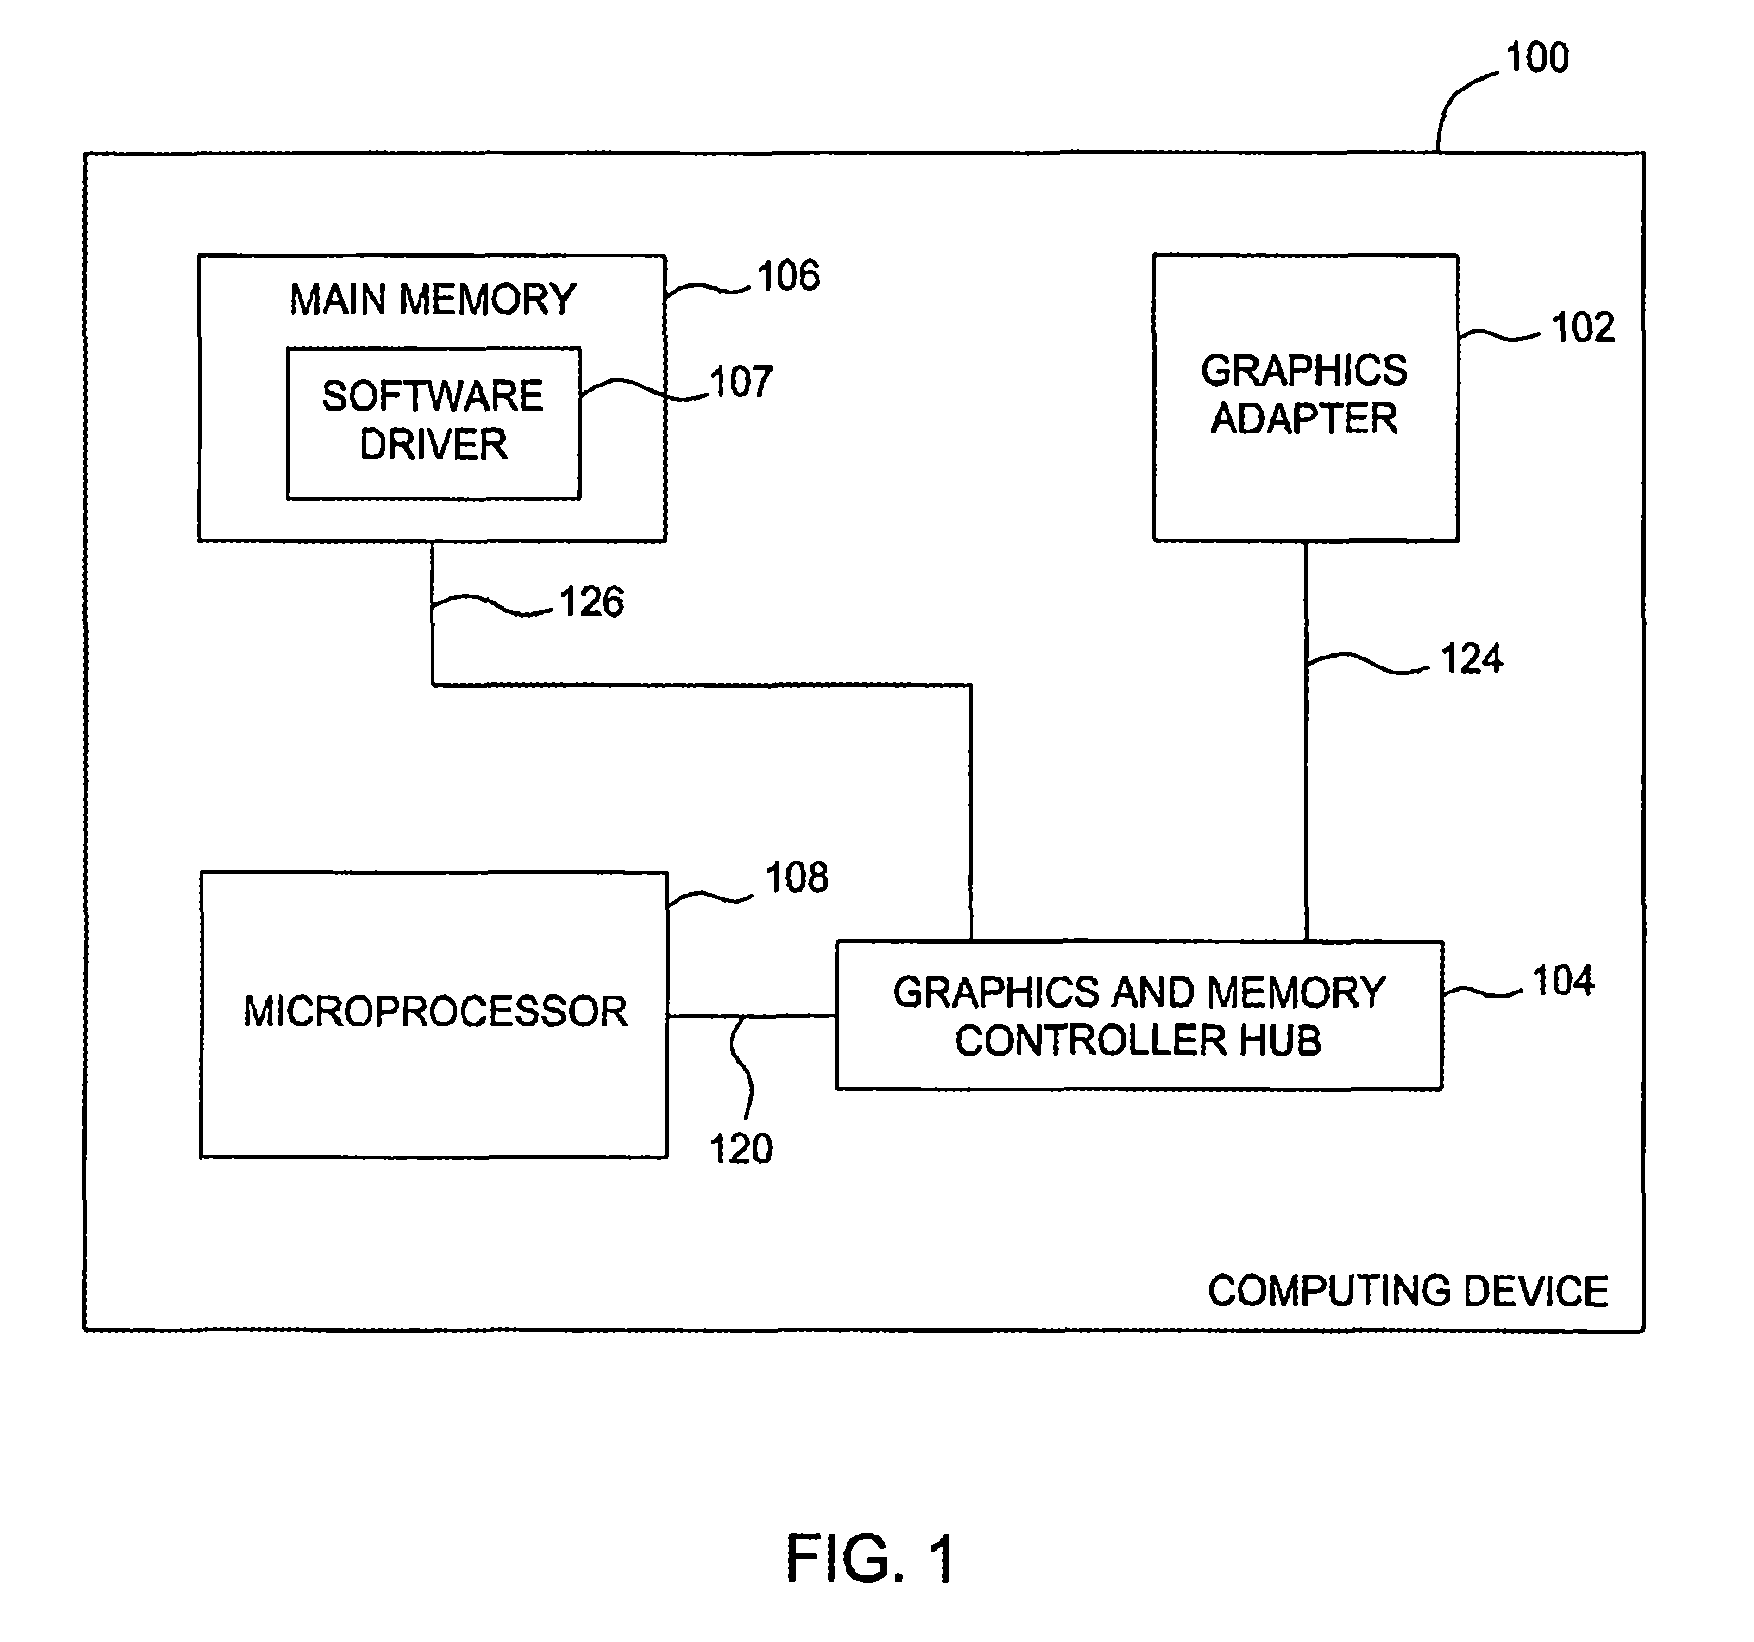
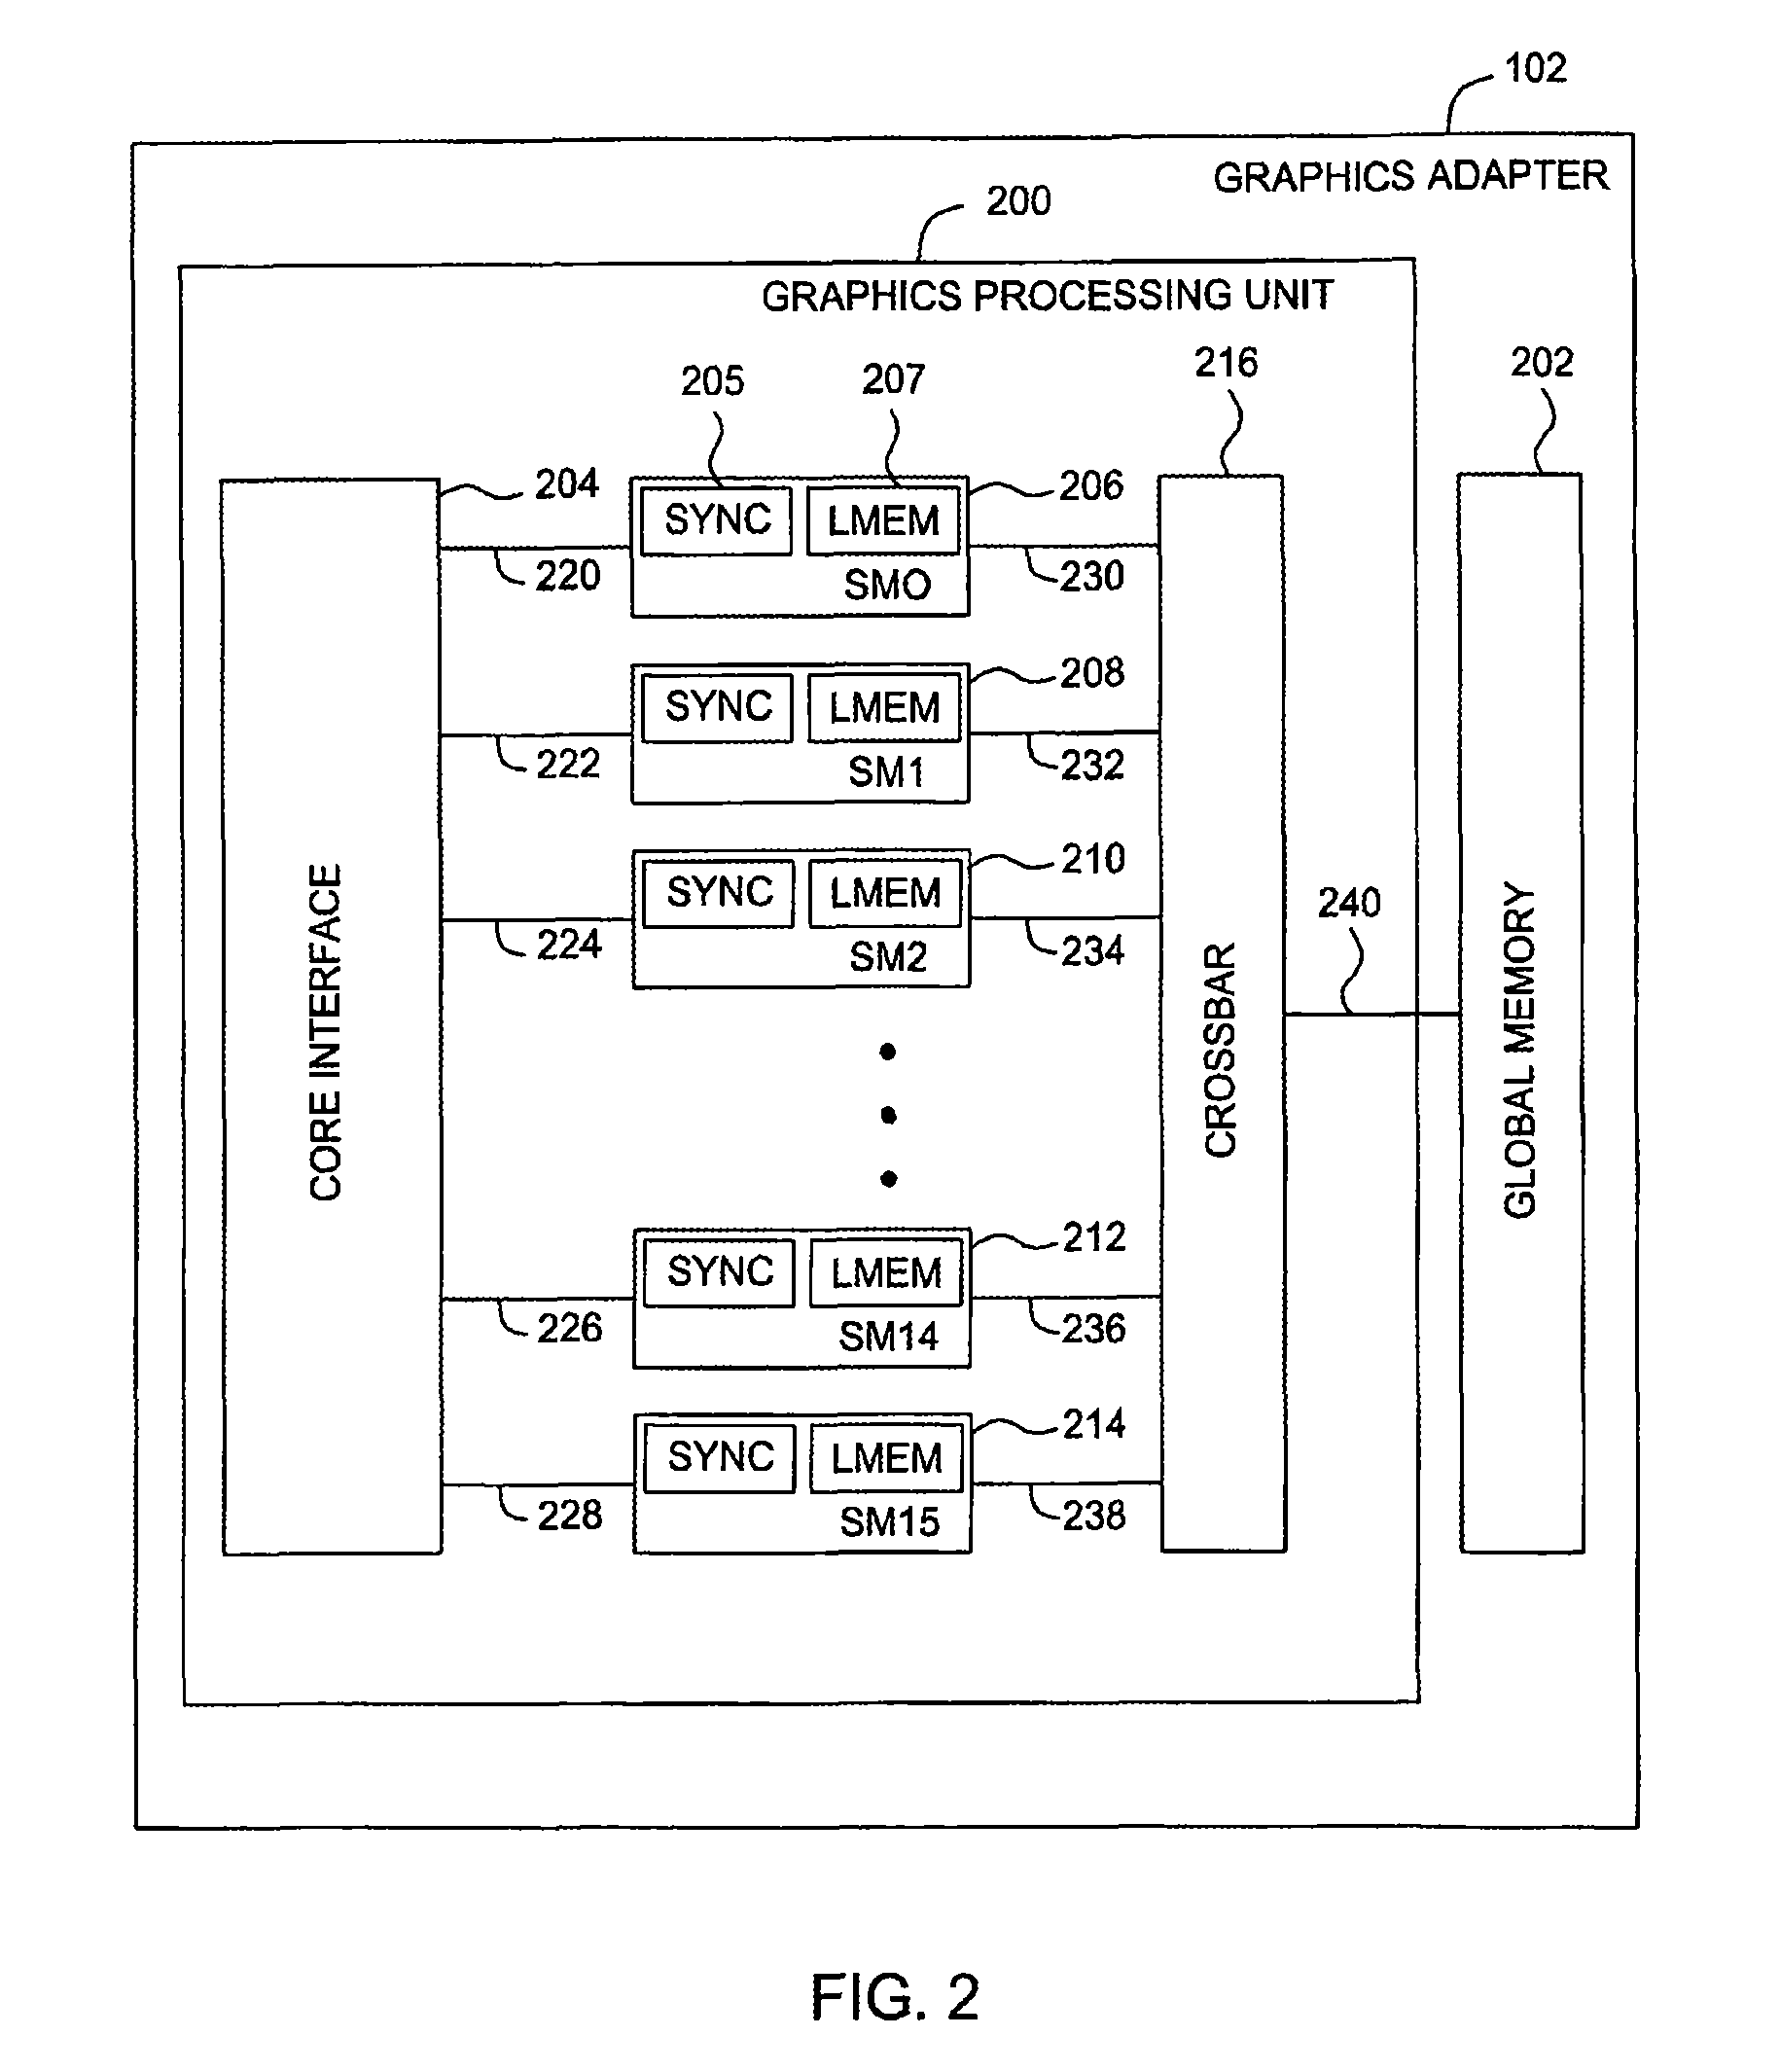
One embodiment of the invention sets forth a computing system for performing cryptographic computations. The computing system comprises a central processing unit, a graphics processing unit, and a driver. The central processing requests a cryptographic computation. In response, the driver downloads microcode to perform the cryptographic computation to the graphics processing unit and the graphics processing unit executes microcode. This offloads cryptographic computations from the CPU. As a result, cryptographic computations are performed faster and more efficiently on the GPU, freeing resources on the CPU for other tasks.
Owner:NVIDIA CORP
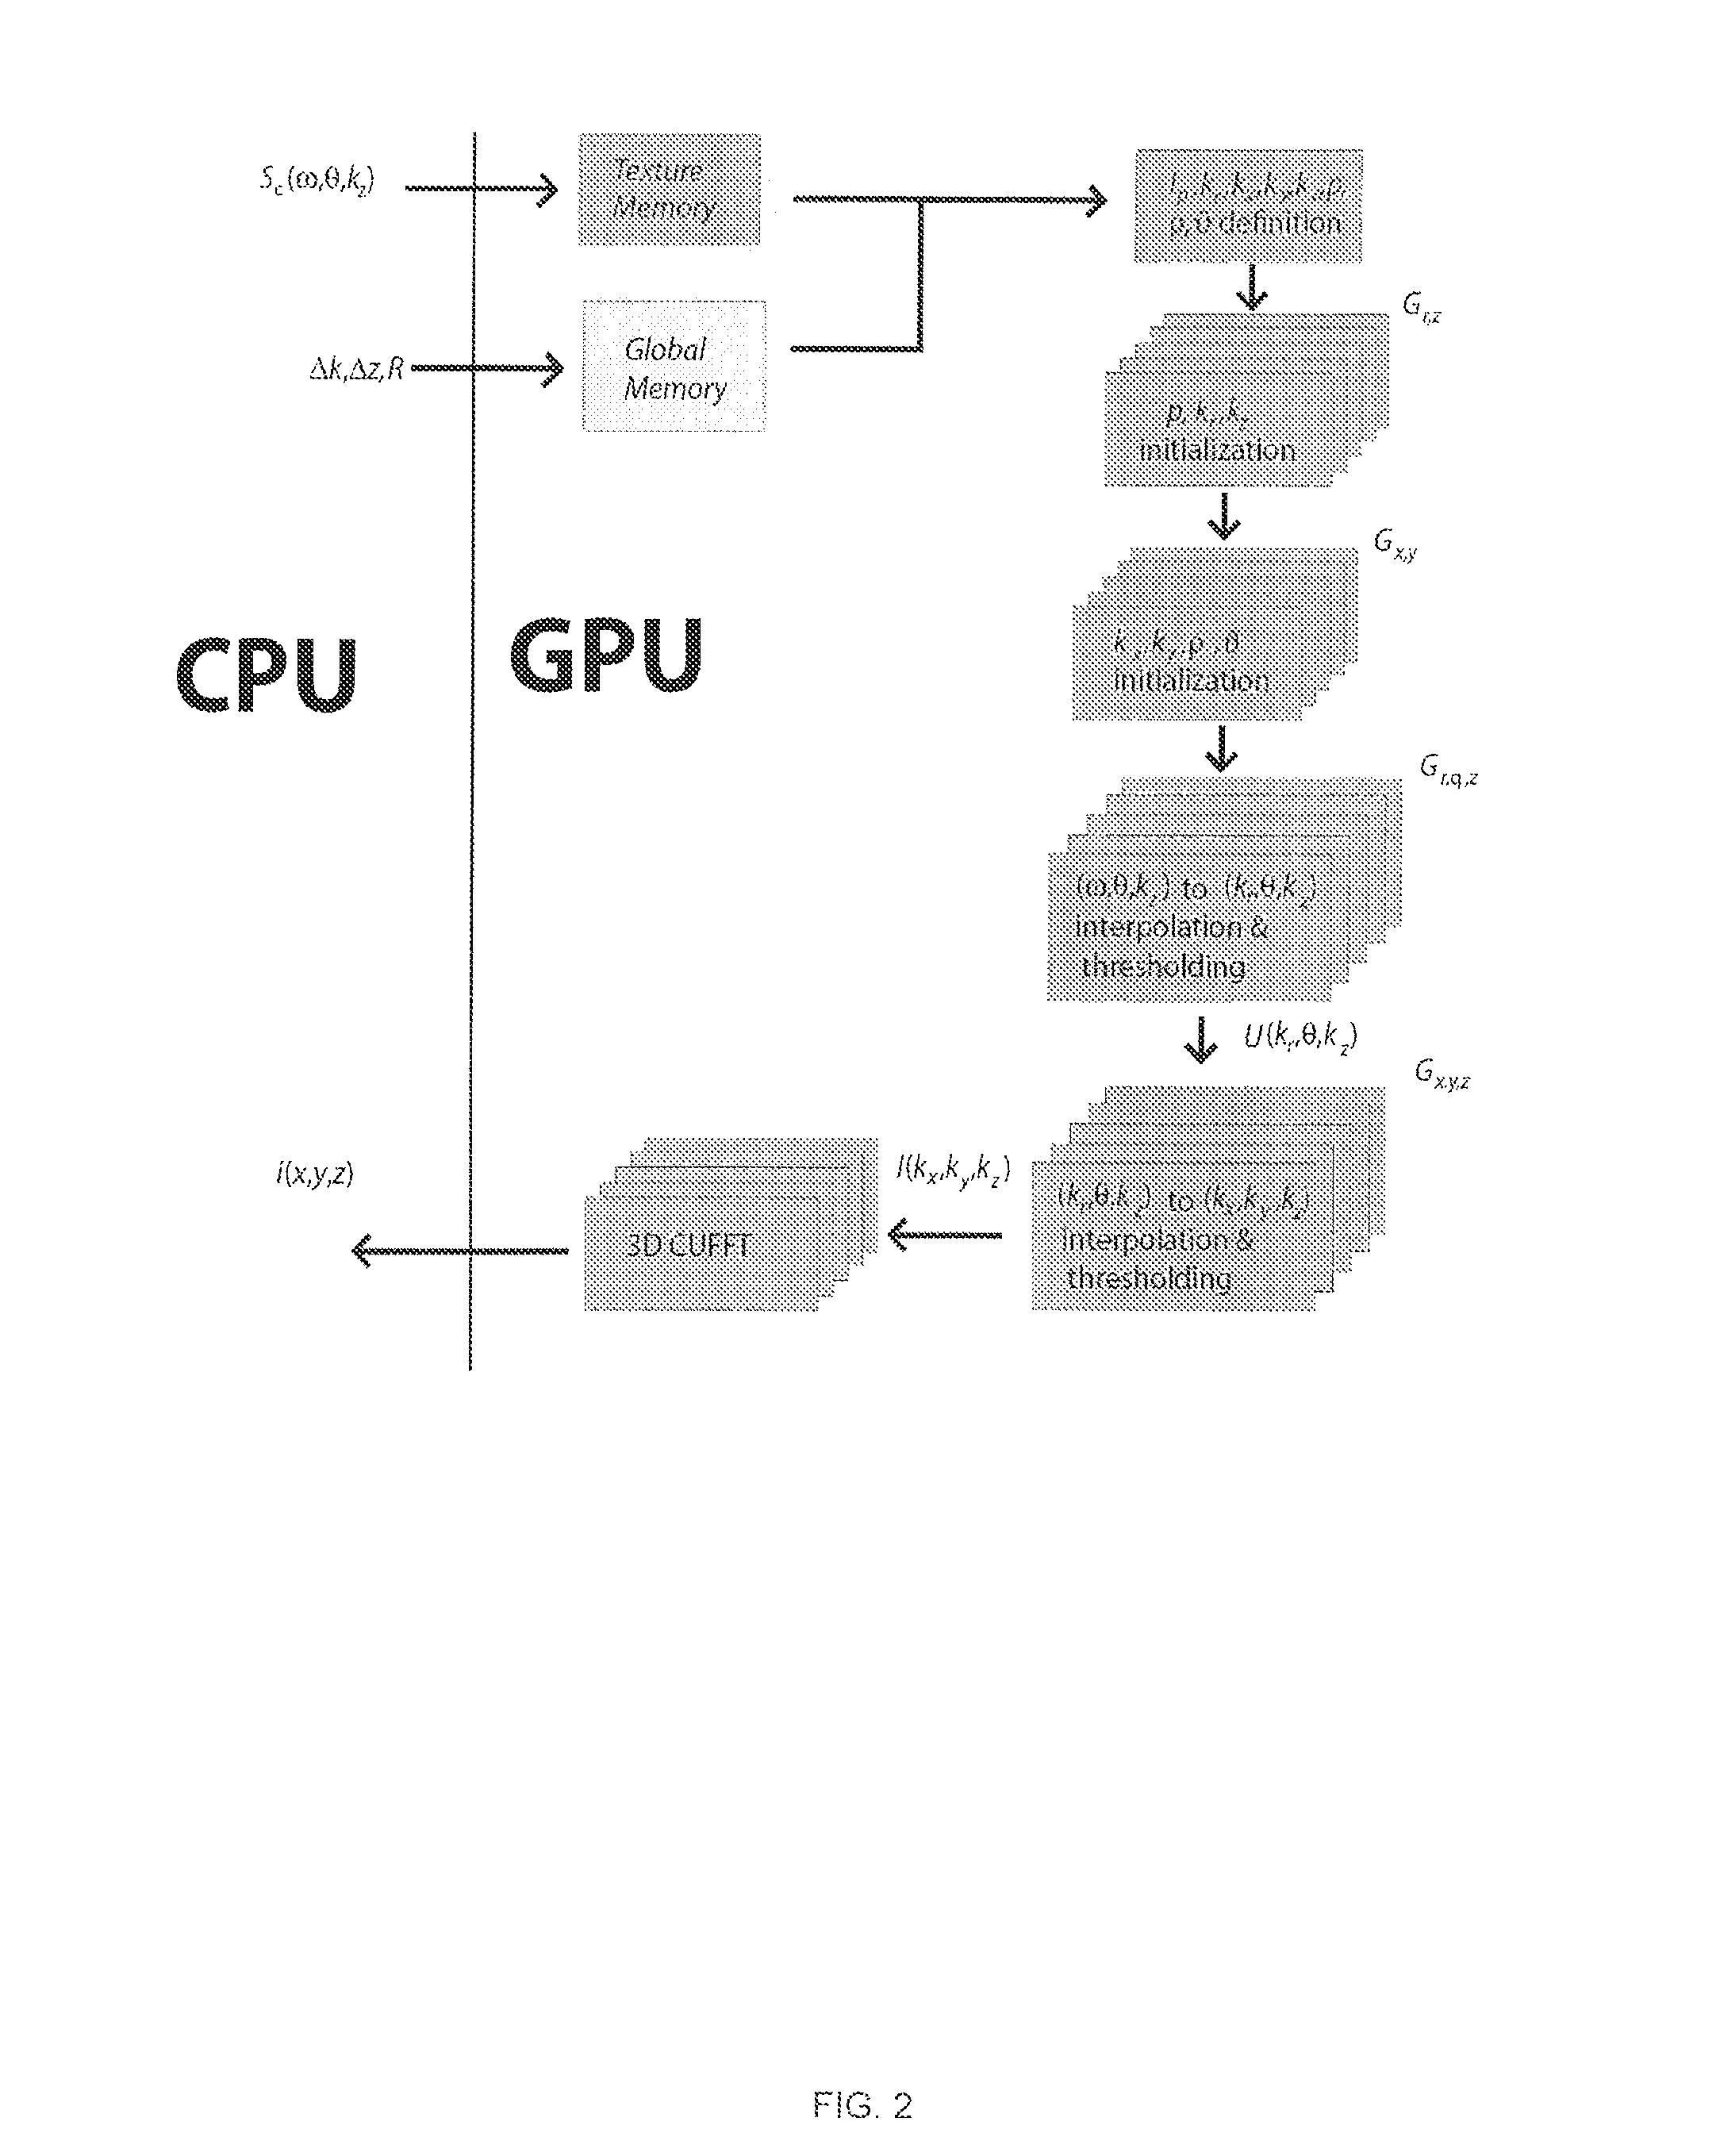
Real time reconstruction of 3D cylindrical near field radar images using a single instruction multiple data interpolation approach
InactiveUS8872697B2Low costHigh bandwidthDetection using electromagnetic wavesRadio wave reradiation/reflectionPerformance computingSignal-to-quantization-noise ratio
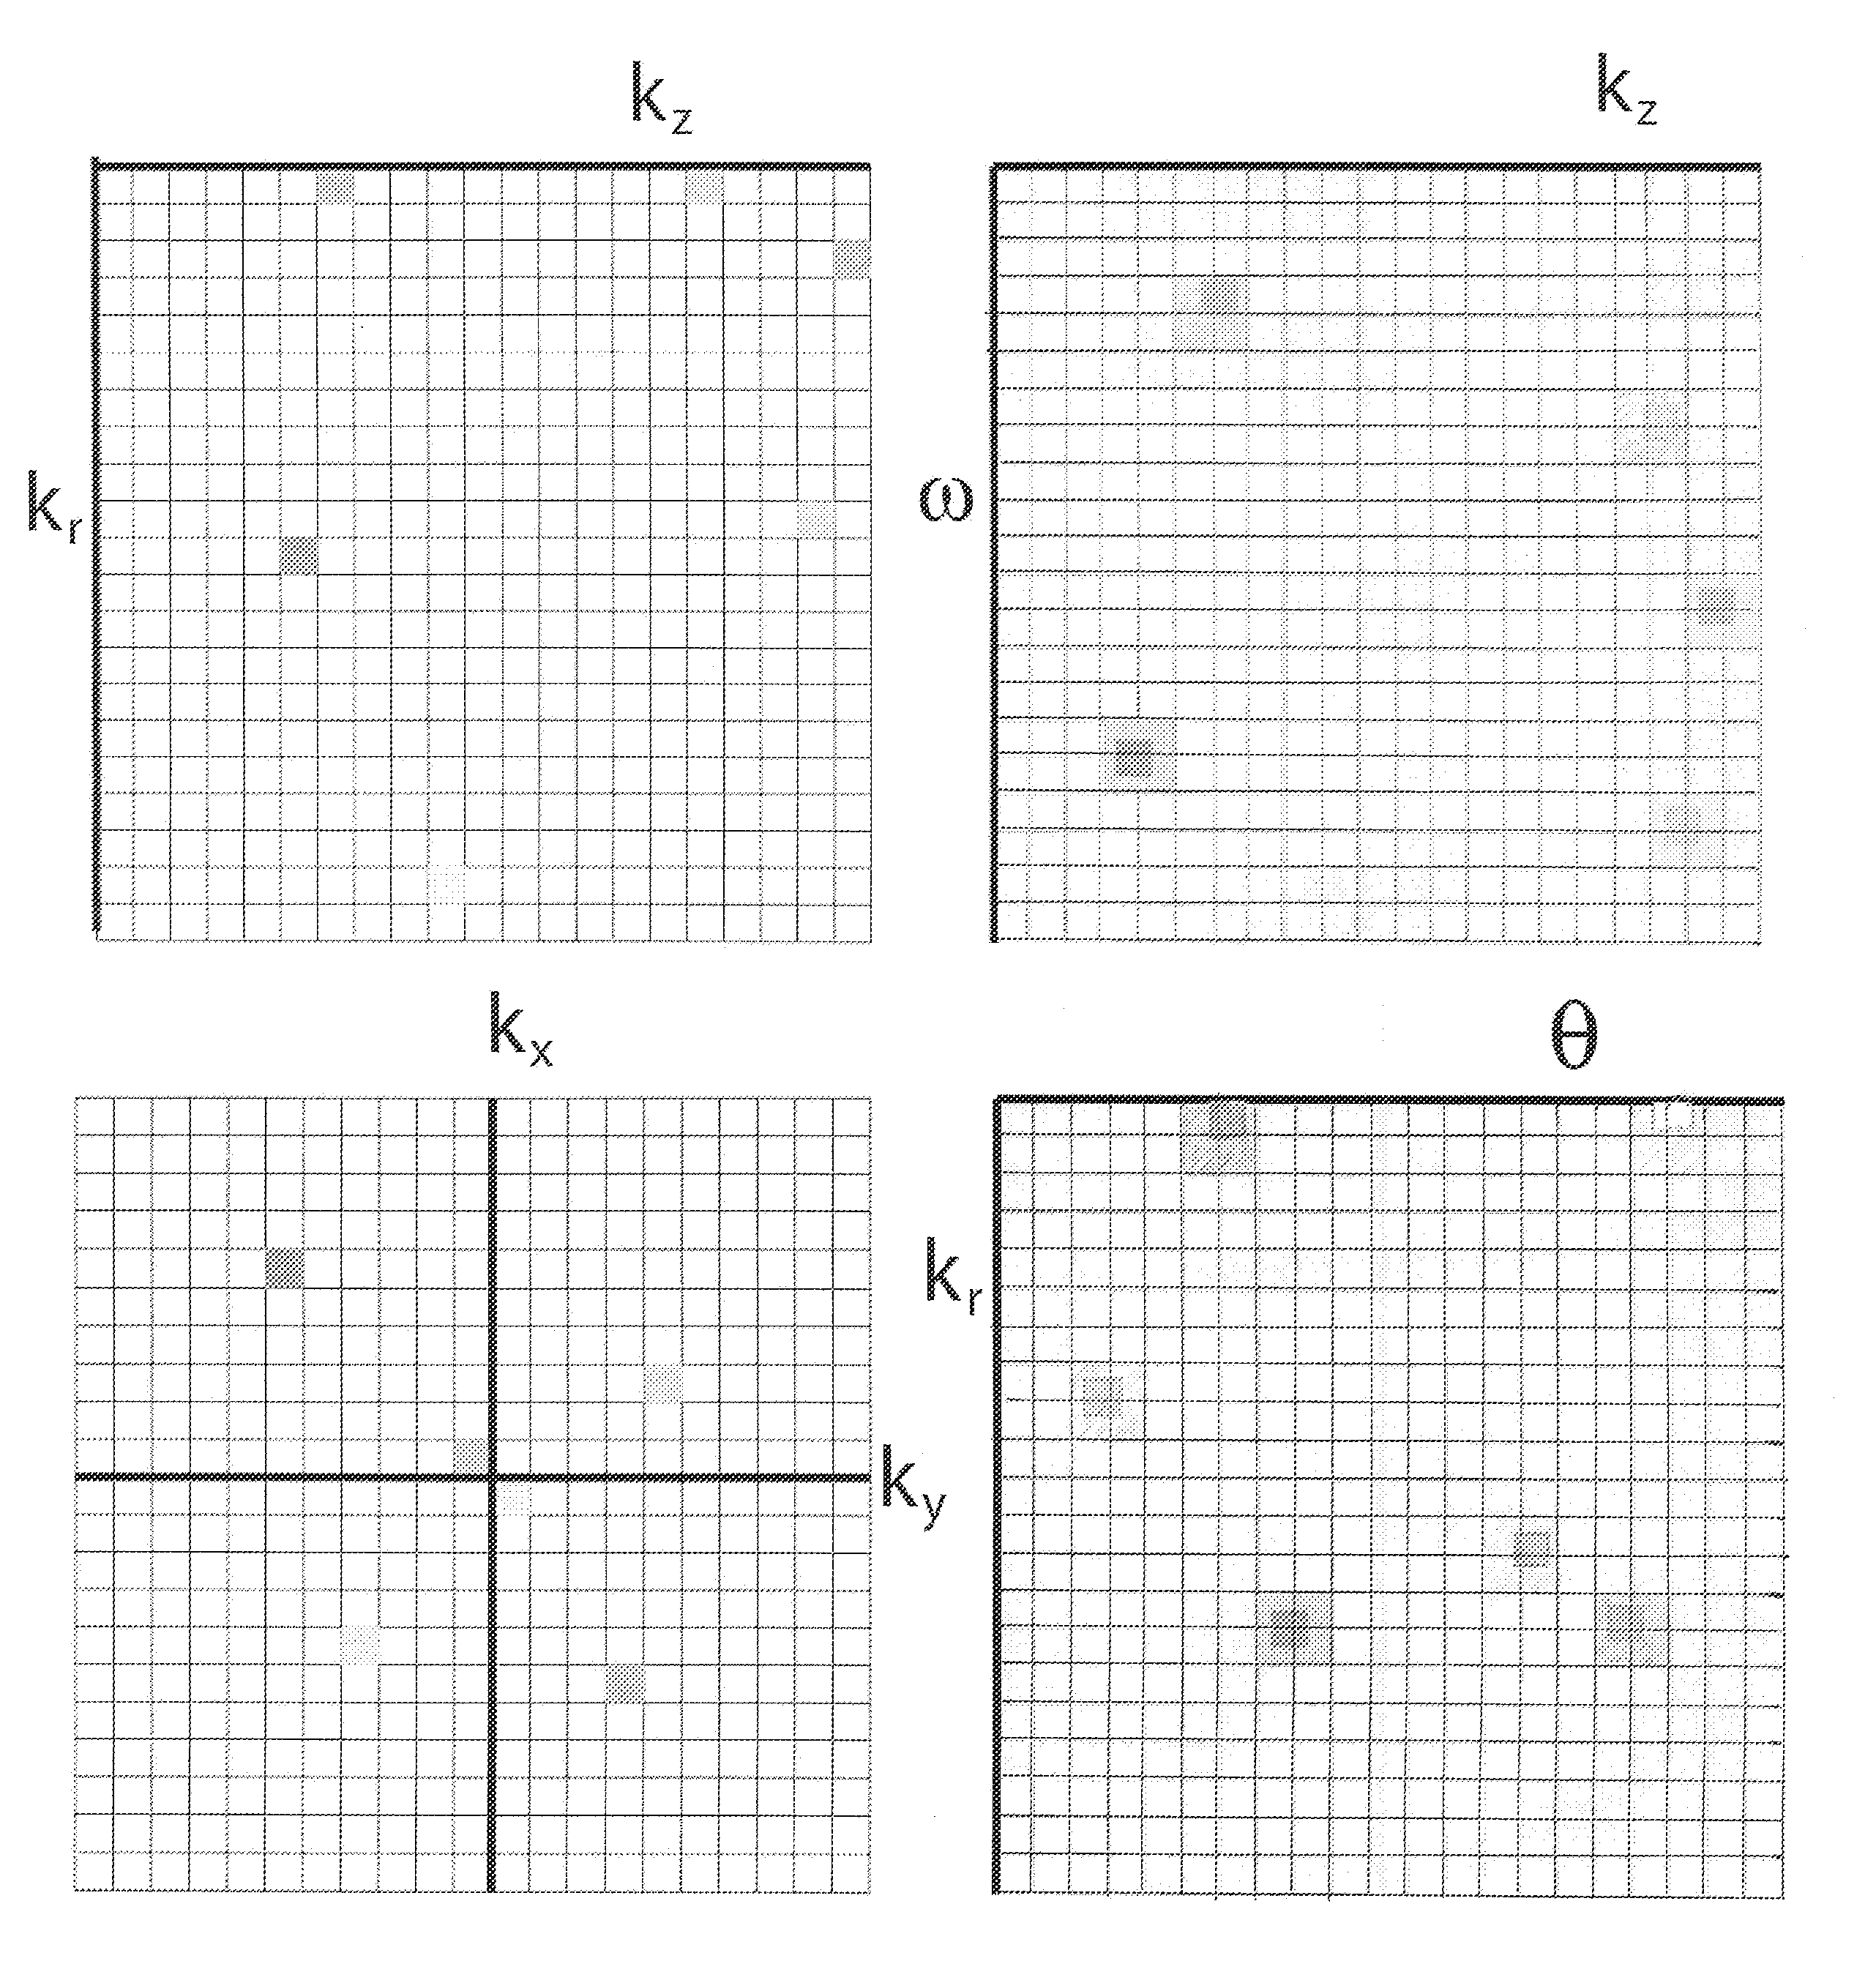
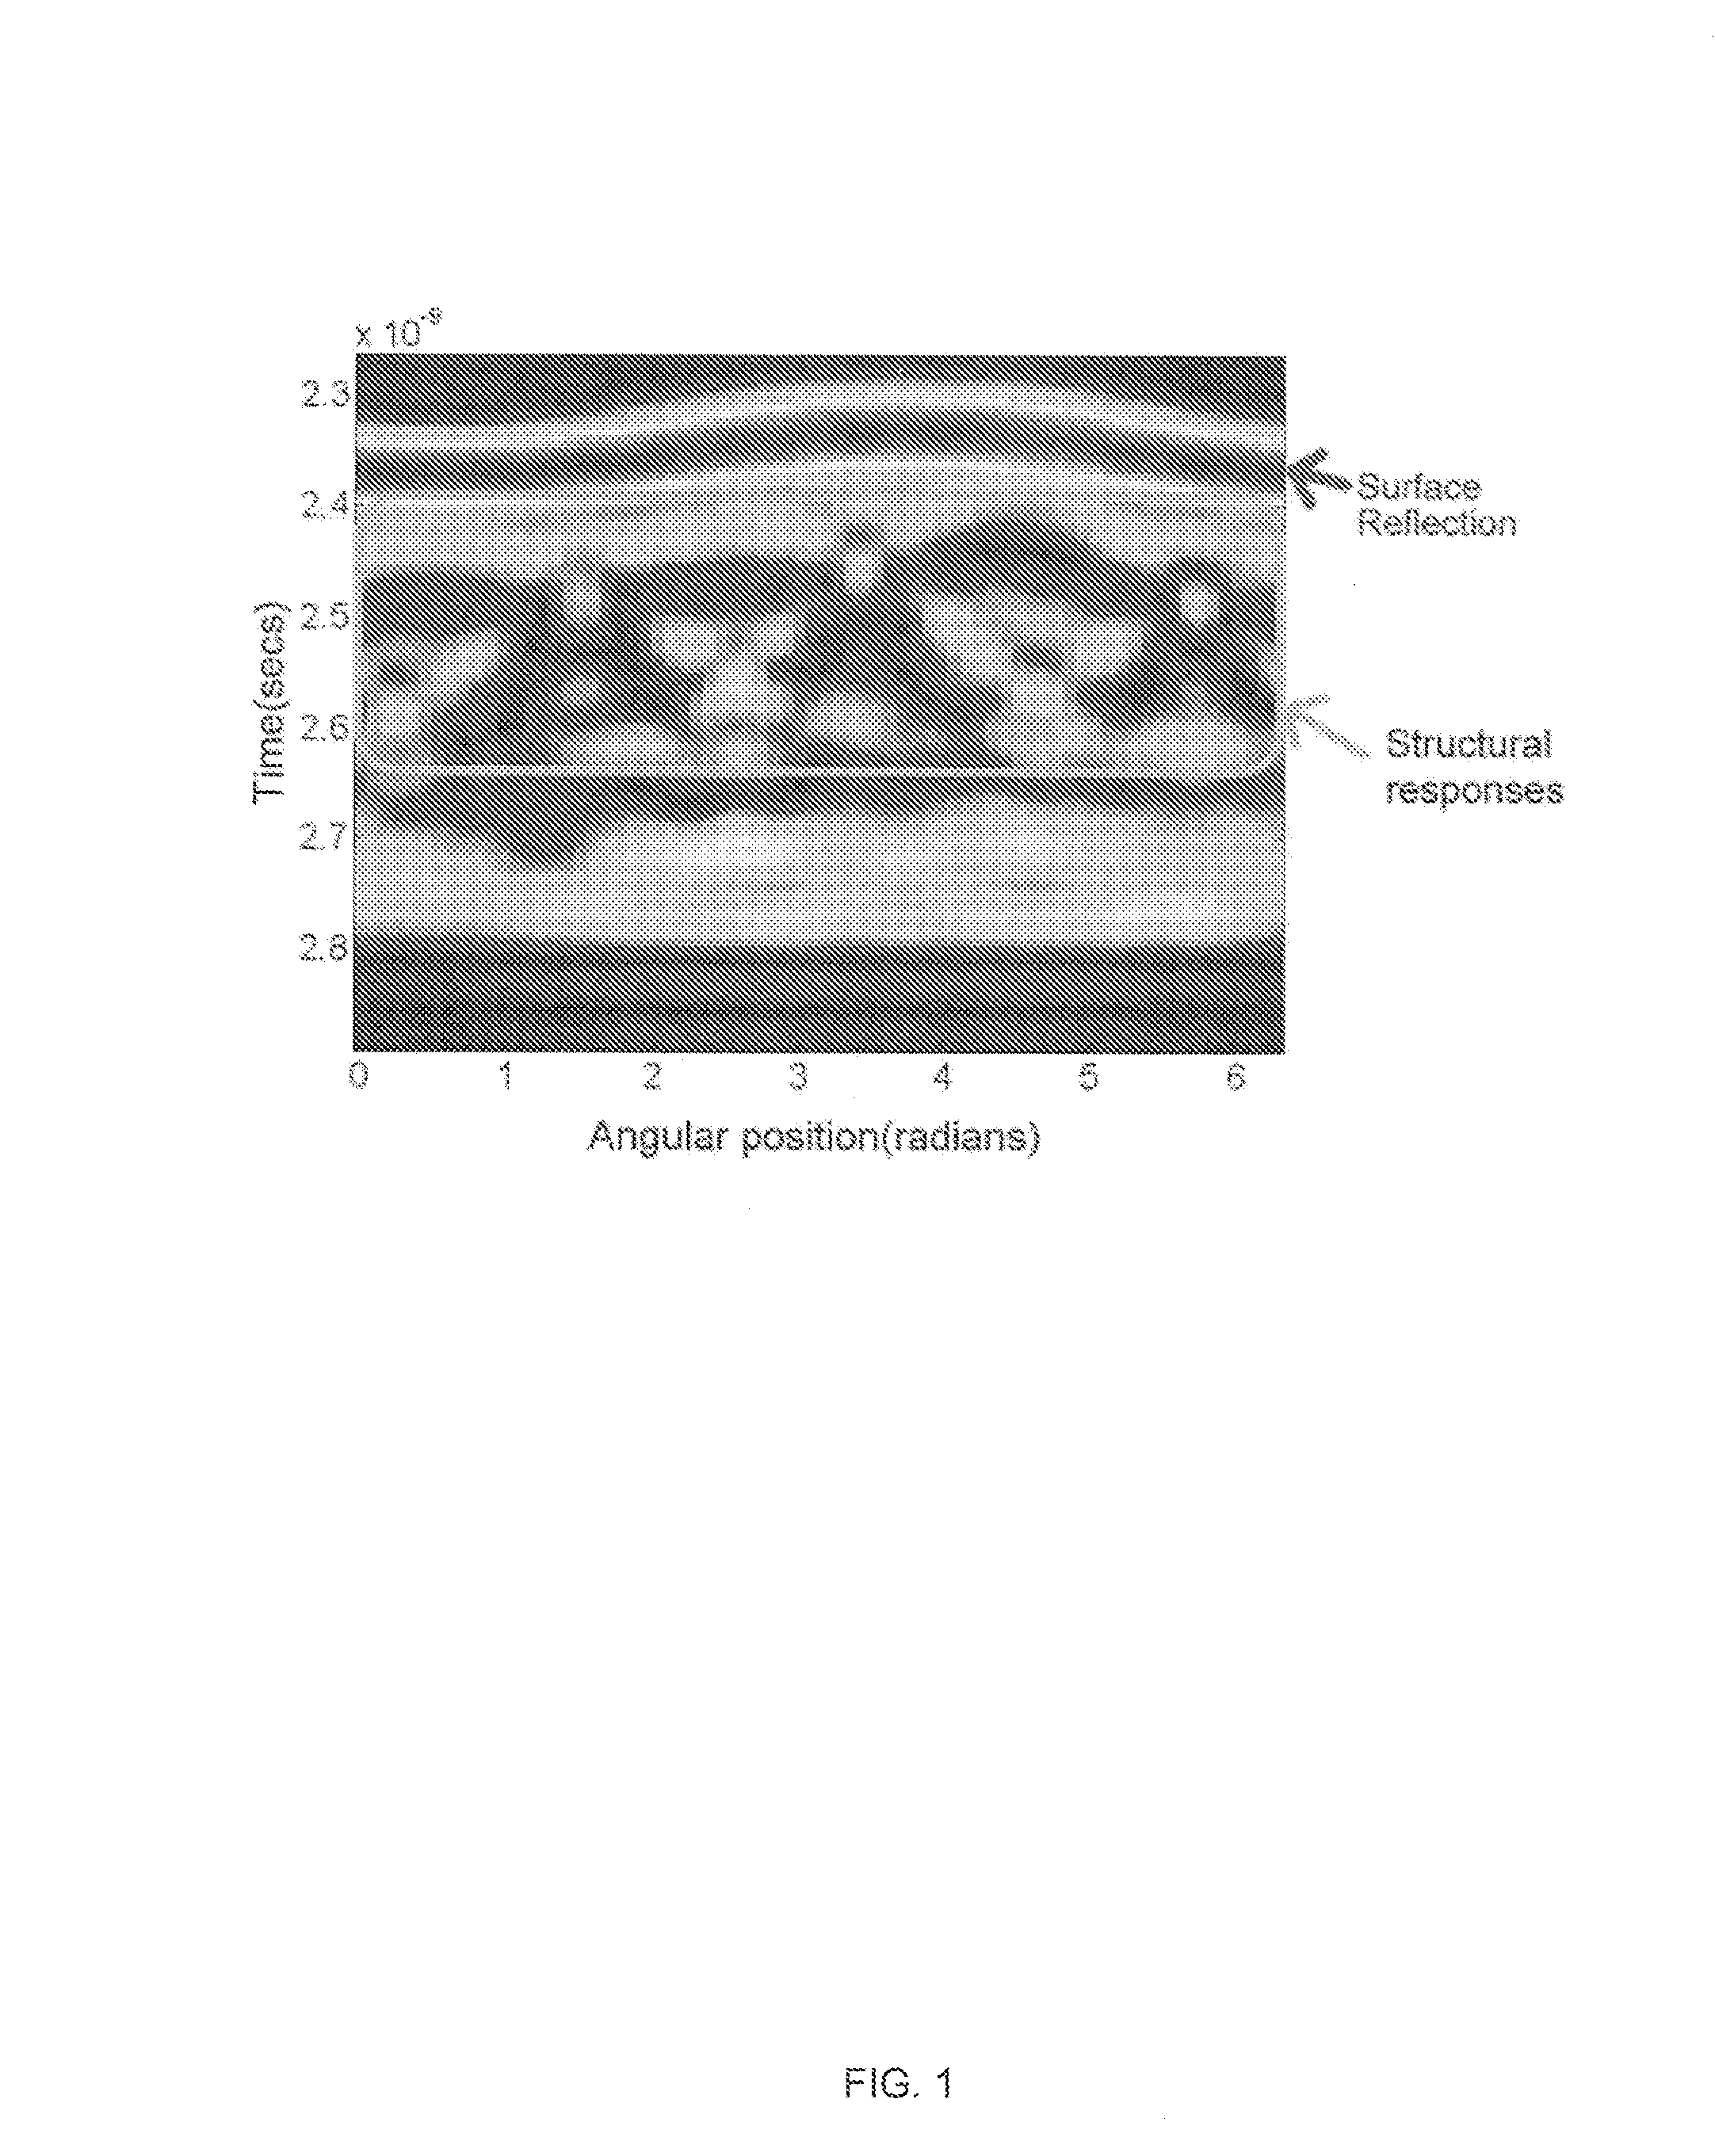
The present invention uses a Single Instruction Multiple Data (SIMD) architecture to form real time 3D radar images recorded in cylindrical near field scenarios using a wavefront reconstruction approach. A novel interpolation approach is executed in parallel, significantly reducing the reconstruction time without compromising the spatial accuracy and signal to noise ratios of the resulting images. Since each point in the problem space can be processed independently, the proposed technique was implemented using an approach on a General Purpose Graphics Processing Unit (GPGPU) to take advantage of the high performance computing capabilities of this platform.
Owner:TAPIA DANIEL FLORES +1
GPGPU (General Purpose Graphics Processing Unit) thread block synchronization method and equipment based on thread lock and medium
ActiveCN119557115Aimprove accuracyImprove efficiencyProgram synchronisationEnergy efficient computingDigital dataGeneral purpose
The invention discloses a GPGPU thread block synchronization method and device based on a thread lock and a medium, and relates to the technical field of electric digital data processing. The method comprises the following steps: a thread block scheduling module allocates thread blocks for each stream multiprocessor and calculates a thread start ID (Identity) to maintain a corresponding thread lock table; analyzing whether a dependency relationship exists between the memory access request and a thread in the currently occupied thread block or not under the condition that the memory access requirement exists, and if yes, adding the memory access request with the dependency relationship to a lock queue; querying a thread lock state of a thread having a dependency relationship with the memory access request in a corresponding thread lock table so as to add the thread lock state to an entry state corresponding to the lock queue; and dequeuing the memory access request from the lock queue under the condition that the entry states of all the threads with the entries in the lock queue and the thread bundle having the dependency relationship are unlocked, and performing memory access according to the memory access request to realize synchronization of GPGPU thread blocks.

Owner:YUANQIXIN (SHANDONG) SEMICONDUCTOR TECHNOLOGY CO LTD
Global memory allocation method and device for GPGPU (General Purpose Graphics Processing Unit) and medium
ActiveCN119557104Aavoid wastingEfficient use ofResource allocationEnergy efficient computingComputer hardwareGeneral purpose
The invention discloses a global memory allocation method and device for a GPGPU (General Purpose Graphics Processing Unit) and a medium, belongs to the technical field of GPGPU memory allocation, and is used for solving the technical problem that in the data transmission cooperative work process of an existing host and a GPGPU device, the real-time performance of a task is easily influenced, and a large device memory space is possibly occupied, so that the memory space is wasted. The method comprises the following steps: performing data block division processing on each piece of input data required by an input task to obtain input data blocks; performing operation processing of the device end on the first group of input data to obtain an operation result of the first group of input data; if the operation state of the device end is completed before the host end finishes sending the second group of input data, performing first operation completion control on the device end to obtain a first operation result of the second group of input data; and if the operation state of the device end is completed after the host end finishes sending the second group of input data, obtaining a post-operation result of the second group of input data.

Owner:YUANQIXIN (SHANDONG) SEMICONDUCTOR TECHNOLOGY CO LTD
High-dimensional-data-oriented vocabulary tree building method based on heterogeneous platform
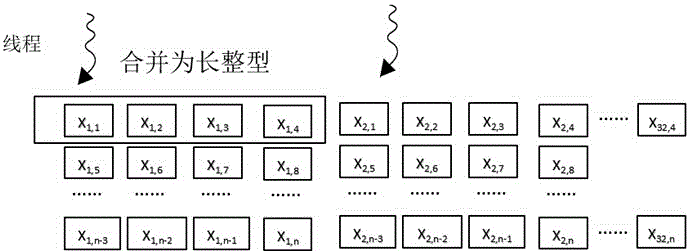
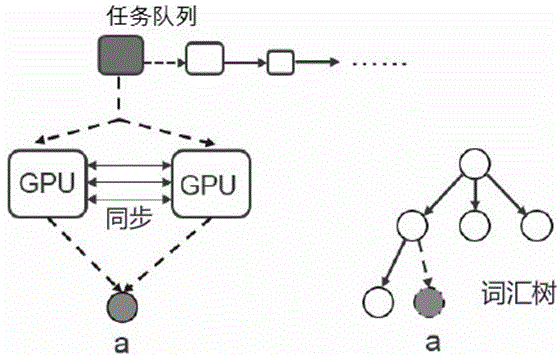
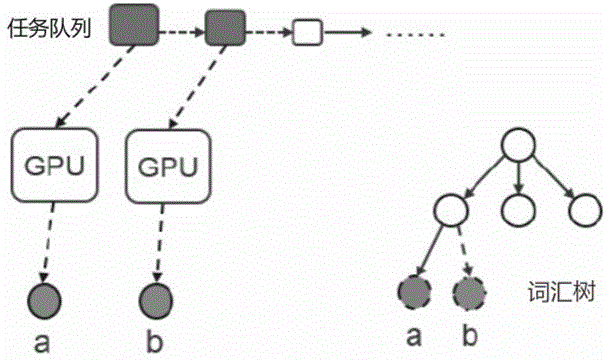
The invention belongs to the technical field of a parallel processing unit, and particularly relates to a high-dimensional-data-oriented vocabulary tree building method based on a heterogeneous platform. According to the method, the strong parallel calculation capability and the programmability of a graphics processing unit arranged on a heterogeneous processing platform (a mixed architecture of a general purpose processor and a GPGPU (General Purpose Graphics Processing Unit)) are used for accelerating the speed of the building process of a high-dimensional vocabulary tree. The characteristic of high concurrency of the graphics processing unit is used for accelerating the speed of the core process of a high-dimensional vocabulary tree algorithm; the characteristics of the high-dimensional vocabulary tree algorithm and the memory access mode of the graphics processing unit are used for optimizing the memory accessing process of the algorithm; and a coordination strategy of a host and the graphics processing unit in the operation process of the high-dimensional vocabulary tree algorithm is designed. The method has the advantage that the building speed of the high-dimensional-data-oriented vocabulary tree can be effectively accelerated.
Owner:FUDAN UNIV
Pipelining Computational Resources in General-Purpose Graphics Processing Units
ActiveCN103348320BMultiprogramming arrangementsConcurrent instruction executionData streamGeneral purpose graphic processing unit
This disclosure describes techniques for extending the architecture of a general-purpose graphics processing unit, GPGPU, with parallel processing units to allow efficient processing of pipeline-based applications. The technique includes configuring local memory buffers connected to parallel processing units operating as stages of a processing pipeline to hold data for transfer between the parallel processing units. The local memory buffers allow on-chip, low power, direct data transfer between the parallel processing units. The local memory buffer may include a hardware-based data flow control mechanism to enable transfer of data between the parallel processing units. In this way, data can be passed directly from one parallel processing unit to the next parallel processing unit in the processing pipeline via the local memory buffer, effectively transforming the parallel processing unit into a series of pipeline stages.
Owner:QUALCOMM INC
GPGPU (General Purpose Graphics Processing Unit) stream multiprocessor node source scheduling method, equipment and medium
ActiveCN119537038AImprove efficiencyreduce power consumptionProgram initiation/switchingResource allocationComputational scienceGeneral purpose
The invention discloses a GPGPU (General Purpose Graphics Processing Unit) stream multiprocessor source-saving scheduling method, equipment and a medium, belongs to the technical field of GPGPU scheduling execution, and is used for solving the technical problems that in the existing GPGPU scheduling execution process, the energy efficiency utilization rate of an intensive load is low, memory contention is easy to form, waste of resources and energy consumption is caused, and power consumption is not favorably saved. The method comprises the following steps of: performing all activation processing on the stream multiprocessor unit connected with the thread block scheduling unit; performing category judgment on the task load related to the intensive load, and determining a memory access SM core corresponding to the memory access intensive load; performing suspension processing on the stream multiprocessor unit corresponding to the memory access SM core; computing control is carried out on a computing SM core in the residual stream multiprocessor unit to obtain a computing execution state of the computing SM core; and performing activation control on the stream multiprocessor unit corresponding to the memory access SM core to obtain a task execution state of the current task load.

Owner:SHANDONG INSPUR SCI RES INST CO LTD