

Patents
Literature
942 results about "3d space" patented technology
Efficacy Topic
Property
Owner
Technical Advancement
Application Domain
Technology Topic
Technology Field Word
Patent Country/Region
Patent Type
Patent Status
Application Year
Inventor
Extracting features from sensor data
PCT designated stage expiredWO2025093754A1Character and pattern recognitionPattern recognitionCamera image
In a first aspect, a computer-implemented method of fusing visual features obtained with multiple sensor modalities comprises extracting from a camera image using a visual feature extractor a plurality of camera feature vectors at respective camera plane locations in a camera image plane; receiving sensor data of a non-camera sensor modality; processing the sensor data to compute a plurality of second feature vectors in a target plane lying non- parallel to the camera image plane in 3D space; and computing a plurality of fused feature vectors at a plurality of target plane locations in the target plane, without applying monocular depth detection to the camera image. In a second aspect, the fused feature vectors are computed using a transformer neural network cross-attention between the camera feature vectors and the second feature vectors.

Owner:FIVE AI LTD
Occupancy prediction using forward-backward view transformation
Apparatuses, systems, and techniques of using one or more machine learning processes (e.g., neural network(s)) to predict occupancy using an image input. In at least one embodiment, image data is processed using a neural network to predict occupancy in a 3D voxel space. In at least one embodiment, image data is processed using a neural network to detect objects in a 3D space.

Owner:NVIDIA CORP
Image processing method and device and computer storage medium
PendingCN111368941ACharacter and pattern recognitionComplex mathematical operationsConvolutionAlgorithm
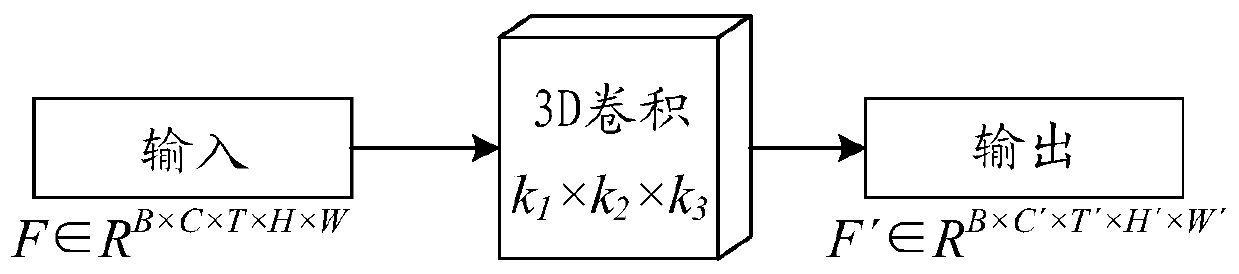
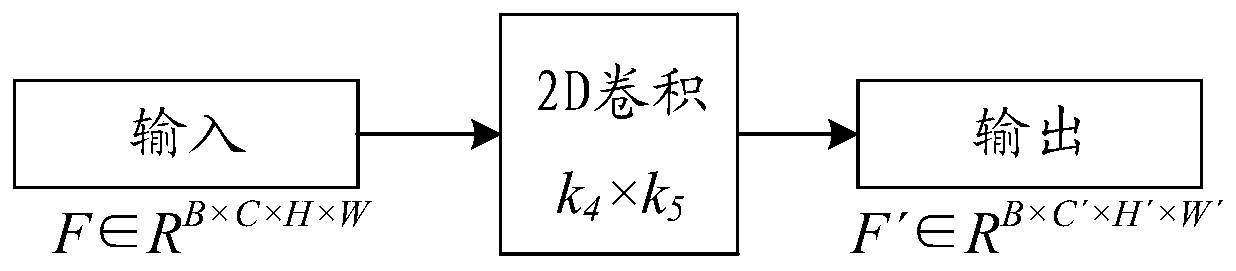
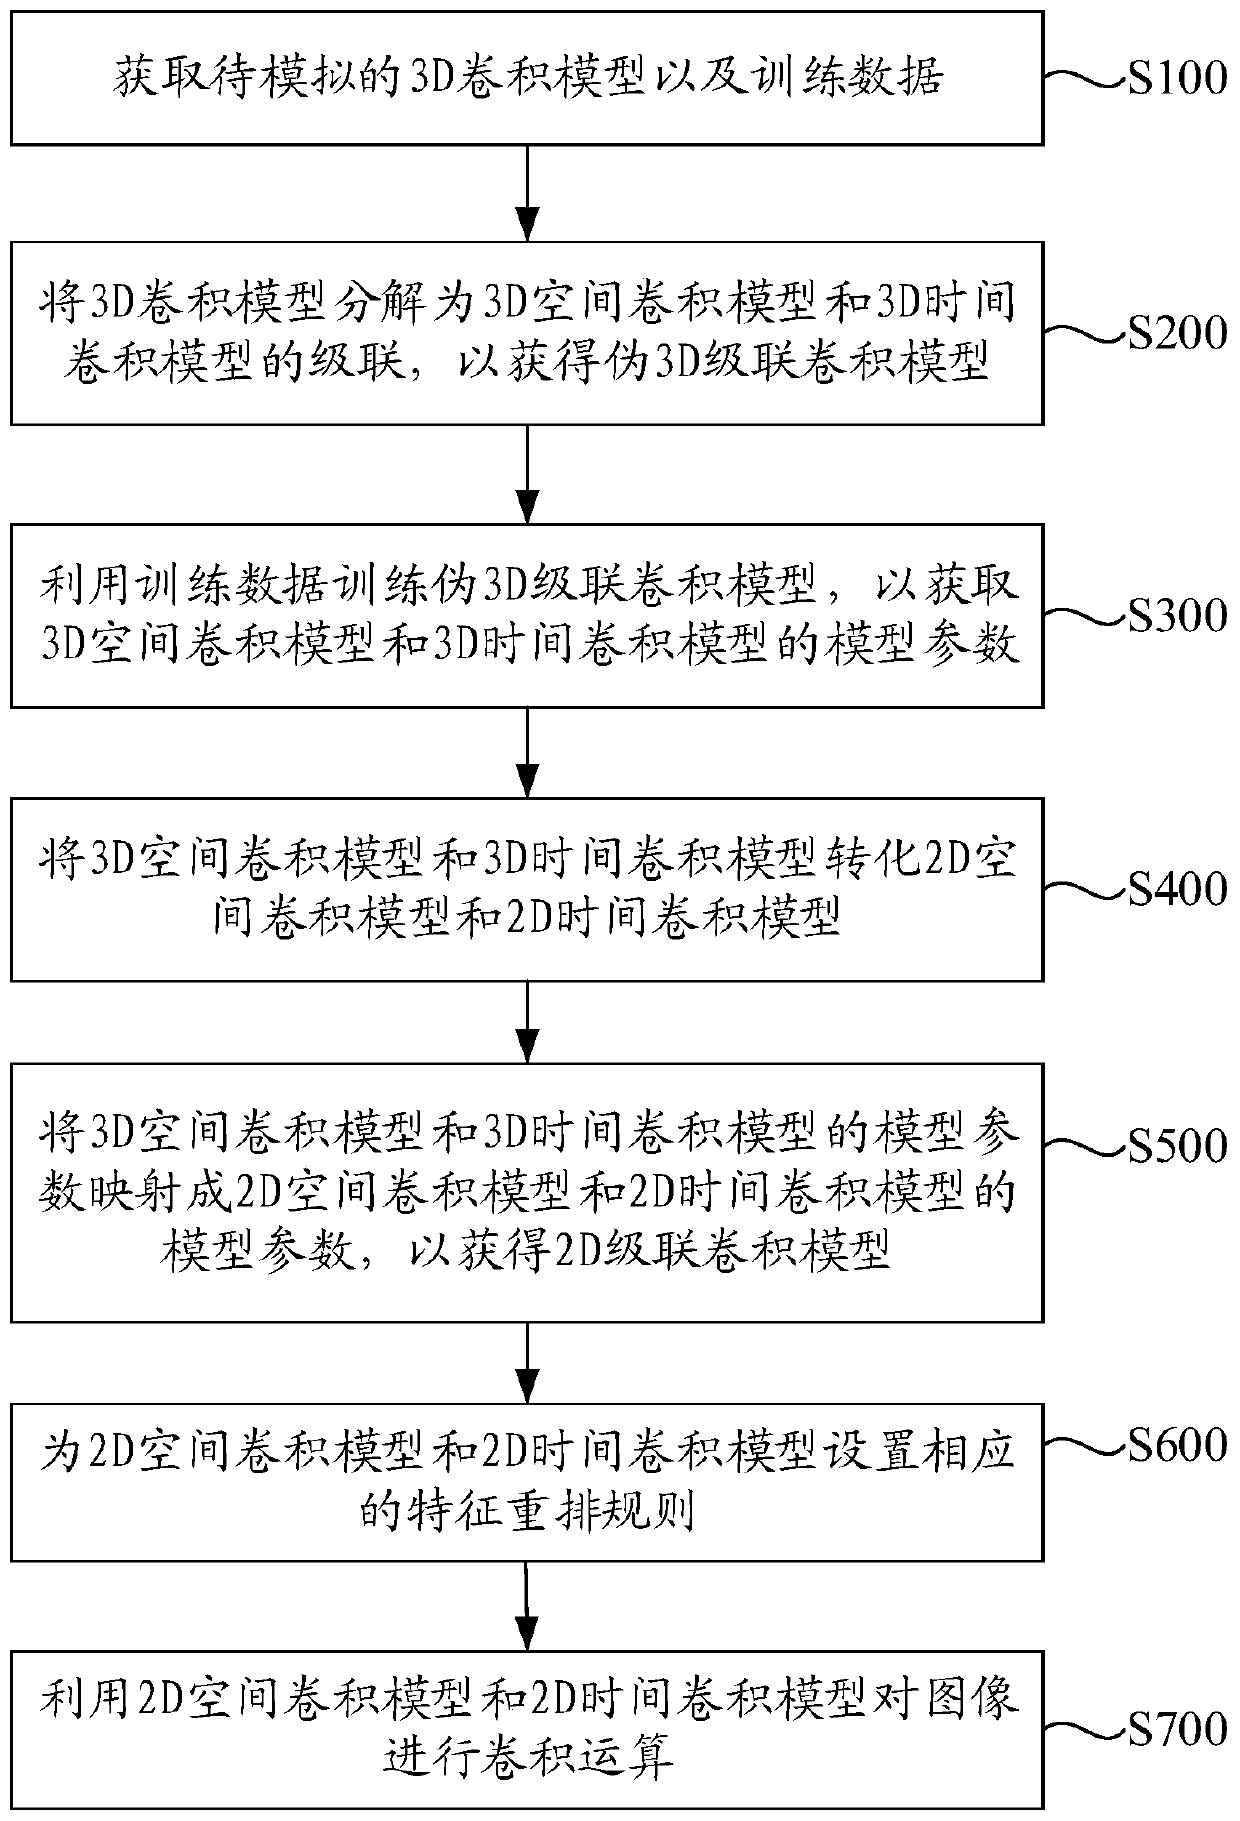
The invention discloses an image processing method and device and a storage medium. The method comprises the steps of obtaining a to-be-simulated 3D convolution model and training data; decomposing the 3D convolution model into cascading of a 3D space convolution model and a 3D time convolution model to obtain a pseudo 3D cascading convolution model; training a pseudo 3D cascade convolution modelby using the training data, and obtaining parameters of a 3D spatial convolution model and a 3D time convolution model; converting the 3D space convolution model and the 3D time convolution model intoa 2D space convolution model and a 2D time convolution model; setting a feature rearrangement rule for the 2D spatial convolution model and the 2D time convolution model; mapping model parameters ofthe 3D spatial convolution model and the 3D time convolution model into parameters of a 2D spatial convolution model and a 2D time convolution model to obtain a 2D cascaded convolution model; and performing convolution operation on the image by using the 2D spatial convolution model and the 2D time convolution model. By means of the mode, image processing conducted through 3D convolution operationcan be achieved through the 2D convolution model.
Owner:ZHEJIANG DAHUA TECH
Object and camera localization system and localization method for mapping of the real world
An object and camera localization system and localization method for mapping of the real world. The mapping can be done in real-time or near real-time to the detection of the real objects by a camera device which is used to capture one or more images of an object. The localization method can be used to generate an object label of the object and a bounding box of the object in the image. The localization method can be used to generate anchor points in real world coordinates of the real 3D space of the object, a cuboid of the object, and a centroid of the cuboid. A virtual 3D map can be generated which includes the location and pose of the real object in the real-world coordinates.

Owner:AWE
3D object detection using temporal inputs
Apparatuses, systems, and techniques of using one or more machine learning processes (e.g., neural network(s)) to detect objects from a plurality of image frames. In at least one embodiment, a plurality of image frames are fused into a feature map using one or more neural networks. In at least one embodiment, a plurality of image frames are processed using one or more neural networks to detect objects in a 3D space.


Owner:NVIDIA CORP
Simplified robotic welding using traced profile, and robotic welding system
A robotic welding system having detection means for in one embodiment detecting a path of a ferro-magnetic, light-reflective or radioactive material traced over a weld seam, and a controller for providing machine commands to cause a torch tip electrode to move the weld seam. Alternatively the detection means comprises means for detecting and tracking a) a position in 3D space of a pointer tip which is in known positional relationship to determined GPS coordinates of a reference point on the welder when traced along a desired weld seam; b) the path of a point source of light when traced along a location of a desired weld seam; c) the path of light-reflective material traced or positioned over the desired weld seam; or d) a path of a tip of a digitized pointer object when traced along a desired weld seam. Methods of operating such robotic welder also disclosed.

Owner:649119 N B INC
Tunnel fracture identification method based on three-dimensional live-action reconstruction and orderly reacquisition of virtual camera
The invention discloses a tunnel fracture recognition method based on three-dimensional live-action reconstruction and ordered re-acquisition of a virtual camera. The method specifically comprises the following steps: acquiring a multi-view rock fracture image; acquiring three-dimensional point cloud data of a tunnel wall surface according to the acquired rock mass fracture image, reconstructing a geometrical shape of the tunnel, mapping acquired texture information to a three-dimensional grid vertex through an image processing algorithm, and generating a three-dimensional tunnel model; setting parameters of the virtual camera, orderly collecting to form a virtual image, and enabling the position of the virtual camera to correspond to the real position of the model; and extracting information of the crack of the virtual image, and projecting the coordinates of the two-dimensional image back to the three-dimensional space through the projection matrix to obtain the space coordinates of the crack. A virtual image is generated by combining a texture mapping technology of a three-dimensional model, so that the limitation of a visual angle, illumination and space in actual image acquisition is overcome, and high-precision identification of tunnel cracks is realized.

Owner:XIAN UNIV OF TECH
Sports action recognition method based on 3D space-time attention and slowfast network
PendingCN119851348AInternal combustion piston enginesCharacter and pattern recognitionHuman bodyFeature extraction
The invention discloses a sports motion recognition method based on 3D space-time attention and a slowfast network, and the method comprises the steps: obtaining an original human body motion video, sampling the original human body motion video through different frame rates, generating Slow branch and Fast branch input images, and taking the Slow branch and Fast branch input images as training samples; constructing a dual-branch network based on spatio-temporal feature extraction; designing a loss function, and training the dual-branch network based on spatial-temporal feature extraction by using the training sample; and sampling a to-be-identified human body behavior video through different frame rates to obtain corresponding video frame images, and inputting the video frame images into the trained dual-branch network based on spatial-temporal feature extraction to obtain an identified human body behavior category. According to the sports action recognition method based on the 3D space-time attention and slowfast network, the problems that in the prior art, the locality of the dependency relationship between the features in the space-time dimension is captured, and the model complexity is high are solved.

Owner:XIAN UNIV OF TECH
Three-dimensional reconstruction method and device, and storage medium
ActiveUS12165241B1Reconstruction from projectionImage generationPattern recognitionComputer graphics (images)
A three-dimensional (3D) reconstruction method is provided. The method includes obtaining a two-dimensional (2D) pixel coordinate of a pixel in a 2D image of an object and a direction of a ray; projecting the 2D pixel coordinate to a 3D space to obtain a plurality of 3D points on the ray; for each 3D point of the plurality of 3D points: predicting a signed distance value for the 3D point; predicting a validity probability for the 3D point; and predicting an intensity value for the 3D point; obtaining a rendering loss based on the predicted signed distance values, the validity probabilities, and the intensity values of the plurality of 3D points to update a 3D reconstruction network; and extracting a 3D model of the object based on the updated 3D reconstruction network.

Owner:TENCENT AMERICA LLC
Estimation method for earth surface biomass of typical grassland in temperate zone
The invention relates to the field of unmanned aerial vehicle multispectral remote sensing image analysis and inversion model construction based on a machine learning algorithm, in particular to a temperate zone typical grassland surface biomass estimation method. A multi-rotor unmanned aerial vehicle is used for carrying a multi-spectral sensor, multi-band spectral reflection information of a pasture is obtained from a near low altitude, a physical spectral reflection model is constructed to calculate real and accurate reflectivity data of a same-band spectrum, vegetation coverage, soil attributes and pasture canopy information of a sampling area are recorded, and the earth surface biomass is measured by cutting a sample; according to the method, a plurality of vegetation indexes and a 3D space model are combined with a multi-modal input structure, data enhancement and small sample learning strategies are adopted, a biomass inversion model is constructed through an MANBA machine learning framework, the precision of grassland biomass estimation is improved, and effective technical support is provided for grassland ecological monitoring and management.

Owner:CHINA AGRI UNIV
Visual encoding and decoding of 3D gaussian splats
PCT designated stageWO2025171956A1Image codingDigital video signal modificationAlgorithmTheoretical computer science
An encoder projects a scene represented by 3D gaussian splats into 2D representation(s), where the 2D representation(s) store different parameters of the 3D gaussian splats, along with associated metadata describing transformation from 3D space into 2D representations. The encoder forms the 2D representation(s) and the associated metadata into bitstream(s). The encoder outputs the bitstreams. The decoder receives the bitstream(s) encoding 2D representation(s) and associated metadata. The decoder applies decoding to corresponding individual bitstreams to form the 2D representation(s) and the associated metadata. The decoder reprojects, as described by the associated metadata, the 2D representations) into the scene represented by the 3D gaussian splats. The decoder outputs the scene for rendering, or renders the scene, to a viewer.

Owner:NOKIA TECHNOLOGIES OY
Input Recognition System that Preserves User Privacy
PendingUS20240402801A1Input/output for user-computer interactionComputer security arrangementsUser privacyEvent data
Devices, systems, and methods that interpret user activity as user interactions with virtual elements (e.g., UI elements) positioned within in a 3D space such as an XR environment. Some implementations use an architecture that receives application UI geometry in a system or shared simulation area and outputs interaction events data (e.g., less than all user activity data) for an application to use to recognize input to the application. An OS process may be configured to provide an input support process to support recognizing input intended for one or more separately-executing applications, for example, by providing some input recognition tasks to recognize user activity as input for the applications or by converting user activity data into a format that can be more easily, accurately, efficiently, or effectively interpreted by the applications and / or in a way that facilitates preservation of user privacy.

Owner:APPLE INC
Three dimensional gaussian splatting with exact perspective transformation
Three-dimensional Gaussian splatting mechanisms that initialize a set of 3D Gaussian distributions, un-project pixels from two-dimensional (2D) planes to 3D space by applying queries to the 3D Gaussians at expected un-projected ray depth positions, and splat the 3D Gaussian distributions on the 2D planes based on the expected un-projected ray depth positions.

Owner:NVIDIA CORP
3D zero sample anomaly detection method and device based on 2D multi-mode large model
The invention discloses a 3D zero sample anomaly detection method and device based on a 2D multi-mode large model. Based on a 2D multi-modal model CLIP, 3D anomaly detection is realized under the condition of not depending on a target domain sample, and point cloud information from 3D and 2D is integrated through the following modes: firstly, point cloud is rendered from multiple perspectives through the CLIP, and 2D representation of the point cloud is acquired; projecting the 2D representation back to the 3D space, thereby understanding the 3D representation of the point cloud; additional regularization is performed on the 2D representation to further enhance the understanding of the frame on the 3D representation. After the point information and the pixel information of the point cloud are represented, the invention provides a mixed representation learning method, generalization abnormal modes in the point cloud and the pixels are captured into learnable text prompts, and accurate detection of 3D anomalies is realized. According to the method, high-precision zero-sample anomaly detection for 3D data is realized for the first time, and the method has high innovativeness and industrial application value.

Owner:ZHEJIANG UNIV
Systems and methods for generating a digital representation of a 3D object
The present disclosure relates to a dental scanning system for generating a digital three-dimensional representation of a dental object, the system comprising an intraoral scanning device comprising one or more projector units configured to project a pattern on a surface of the dental object; and two or more cameras configured to acquire one or more sets of images; wherein the scanning system further comprises one or more processors configured to determine one or more image features within each set of images; solve a correspondence problem within each set of images such that points in 3D space are determined based on the image features, wherein said points form a solution to the correspondence problem, wherein the correspondence problem is solved for groups of pattern features; and generate a digital three-dimensional representation of the dental object, wherein the solution to the correspondence problem is used to generate the three-dimensional representation.

Owner:3SHAPE AS
Three-dimensional space GPS navigation system
ActiveCN120084340AInternal combustion piston enginesNavigational calculation instrumentsGrowth plantGps navigation
The invention discloses a three-dimensional space GPS navigation system. A three-dimensional space GPS navigation system comprises: a map information collection device for acquiring a GPS satellite map of a target area; the unmanned aerial vehicle flying device flies to the high altitude of the target area and is in signal connection with the signal base station or a GPS satellite so as to position the position of the unmanned aerial vehicle in the high altitude; the high-altitude image acquisition module is used for acquiring high-altitude image data of the target area and establishing a three-dimensional scene model based on the high-altitude image data; and the navigation information generation module is used for determining the position in the three-dimensional scene model based on the position of the unmanned aerial vehicle and generating a target route according to the three-dimensional scene model. The navigation scheme provided by the invention can effectively reduce the influence of natural plant growth on navigation when being used in the field, and can accurately find the satellite route through the constructed three-dimensional scene model.

Owner:SHANDONG NORMAL UNIV
Video data processing method and system based on digital twinborn scene
ActiveCN120321433ACharacter and pattern recognitionClosed circuit television systemsFrame sequenceComputer graphics (images)
The invention provides a video data processing method and system based on a digital twin scene. The method comprises the following steps: performing spatial-temporal feature extraction on a video frame sequence to determine a first spatial-temporal feature matrix; segmenting a plurality of video elements from the video frame sequence, and generating an element segmentation mask corresponding to each video element; generating a second spatial-temporal characteristic matrix; obtaining a 2D motion track corresponding to the dynamic element based on the second spatial-temporal characteristic matrix; mapping the 2D motion trails of the dynamic elements into a 3D space to create or update a target virtual 3D scene model, and generating a predicted video frame sequence through the target virtual 3D scene model; and adjusting model parameters in the target virtual 3D scene model according to a comparison result of the predicted video frame sequence and the video frame sequence decomposed by the video data. According to the technical scheme provided by the invention, the video data processing efficiency can be effectively improved.

Owner:BEIJING ZHIHUI YUNZHOU TECH CO LTD
Holographically displaying live scenes including three-dimensional objects
ActiveUS12293687B2Static indicating devicesHolographic optical componentsComputer graphics (images)Radiology
Methods, apparatus, devices, subsystems, and systems for holographically displaying live scenes including one or more three-dimensional (3D) objects are provided. In one aspect, a system includes a holographic capturing system and a holographic display system. The holographic capturing system includes: an optical system configured to generate an optical hologram of a live scene that comprises one or more three-dimensional (3D) objects, and an optical sensor configured to capture sequential optical holograms of the live scene and output sequential hologram data associated with the sequential optical holograms of the live scene, each optical hologram being associated with respective hologram data. The holographic display system is configured to optically reconstruct the live scene in a 3D space based on at least part of the sequential hologram data.

Owner:PACIFIC LIGHT & HOLOGRAM INC
Unmanned system maneuver controller systems and methods
ActiveUS12242284B2Remote controlled aircraftVehicle position/course/altitude controlThree-dimensional space3d space
An unmanned system maneuver controller (USMC) includes an inertial navigation system (INS) for state estimation of the USMC in three-dimensional (3D) space, a communications device configured to communicate with an unmanned system, and a processor configured to receive, via the communications device, flight, maneuver, or dive data from the unmanned system, and generate flight, maneuver, or dive control instructions based at least on the flight, maneuver, or dive data and data received from the INS. The flight, maneuver, or dive control instructions are configured to pilot the unmanned system based on movement of the USMC in 3D space. A remote may selectively control an operation of the USMC. The USMC may be mounted to a weapon or observation device, such that movement of the weapon or observation device in 3D space controls a movement of the unmanned system. Additional systems and associated methods are also provided.

Owner:KNIGHTWERX INC
Low-illumination scene image three-dimensional reconstruction method and device based on 3D Gaussian ball, and electronic equipment
The invention discloses a low-illumination scene image three-dimensional reconstruction method and device based on a 3D Gaussian ball, and electronic equipment. The method comprises the following steps: 1) obtaining a low-illumination scene image; 2) initializing information of a 3D Gaussian ball in a 3D space according to camera parameters and a volume rendering technology to obtain an initial position, an initial radius and an initial color of the 3D Gaussian ball, and writing the initialized 3D Gaussian ball information into the enhanced image; 3) constructing an illumination adjustment network based on the convolutional neural network fused with the attention mechanism; 4) inputting the enhanced image obtained in the step 2) into an illumination adjustment network, and predicting an illumination weight value of each 3D Gaussian ball by using the illumination adjustment network; and 5) based on the initial information of the 3D Gaussian ball and the illumination weight value, performing three-dimensional scene reconstruction by using a three-dimensional reconstruction algorithm to obtain a three-dimensional scene reconstruction view Cnor under normal illumination. According to the invention, the illumination can be dynamically adjusted through the illumination adjusting network, and the real restoration of the low-illumination scene is realized.

Owner:CHONGQING UNIV
Robot with smart trajectory recording
An embodiment includes a robotic welding system for generating a motion program, having a programmable robot controller of a robot having a computer processor and a computer memory. The programmable robot controller is configured to digitally record, in the computer memory, a plurality of spatial points along an operator path in a 3D space taken by a calibrated tool center point (TCP) of the robot as an operator manually moves a robot arm of the robot along the operator path from a start point to a destination point within the 3D space. The programmable robot controller is also configured to identify and eliminate extraneous spatial points from the plurality of spatial points as digitally recorded, leaving a subset of the plurality of spatial points as digitally recorded, where the extraneous spatial points are a result of extraneous movements of the robot arm by the operator.

Owner:LINCOLN GLOBAL INC
Three-dimensional point clouds based on images and depth data
Techniques are discussed herein for generating three-dimensional (3D) representations of an environment based on two-dimensional (2D) image data, and using the 3D representations to perform 3D object detection and other 3D analyses of the environment. 2D image data may be received, along with depth estimation data associated with the 2D image data. Using the 2D image data and associated depth data, an image-based object detector may generate 3D representations, including point clouds and / or 3D pixel grids, for the 2D image or particular regions of interest. In some examples, a 3D point cloud may be generated by projecting pixels from the 2D image into 3D space followed by a trained 3D convolutional neural network (CNN) performing object detection. Additionally or alternatively, a top-down view of a 3D pixel grid representation may be used to perform object detection using 2D convolutions.

Owner:ZOOX INC
Method and apparatus for dynamic gaussian splatting
A method and apparatus generate a 2-dimensional (2D) image. A method for generating a 2-dimensional (2D) image includes obtaining a time index and a view. The method further includes obtaining first coding indices and a first codebook for canonical 3D Gaussians, wherein the canonical 3D Gaussians are 3D Gaussians corresponding to a reference time index, and represent a 3D space corresponding to the reference time index. The method also includes obtaining second encoding indices and a second codebook for a parameter offset, wherein the parameter offset indicates a difference between the canonical 3D Gaussians and 3D Gaussians for the time index. The method further includes reconstructing the canonical 3D Gaussians based on the first coding indices and the first codebook. The method also includes reconstructing parameter offsets of the 3D Gaussians for the time index based on the second coding indices and the second codebook. The method further includes adding the reconstructed canonical 3D Gaussians and the reconstructed parameter offset to reconstruct the 3D Gaussians for the time index. The method also includes generating a second image for the view based on the reconstructed 3D Gaussians.

Owner:ELECTRONICS & TELECOMM RES INST +1
Holographically displaying live scenes including three-dimensional objects
Methods, apparatus, devices, subsystems, and systems for holographically displaying live scenes are provided. In one aspect, a method includes optically generating an optical hologram of a live scene including one or more three-dimensional (3D) objects; capturing sequential optical holograms of the live scene and generating sequential hologram data associated with the sequential optical holograms of the live scene, each optical hologram being associated with respective hologram data; processing the at least part of the sequential hologram data based on a mathematical function to remove low frequency components to generate digital holograms associated with the live scene; and reconstructing the live scene in a 3D space based on the digital holograms.

Owner:PACIFIC LIGHT & HOLOGRAM INC
Holographically displaying live scenes including three-dimensional objects
Methods, apparatus, devices, subsystems, and systems for holographically displaying live scenes including one or more three-dimensional (3D) objects are provided. In one aspect, a system includes a holographic capturing system and a holographic display system. The holographic capturing system includes: an optical system configured to generate an optical hologram of a live scene that comprises one or more three-dimensional (3D) objects, and an optical sensor configured to capture sequential optical holograms of the live scene and output sequential hologram data associated with the sequential optical holograms of the live scene, each optical hologram being associated with respective hologram data. The holographic display system is configured to optically reconstruct the live scene in a 3D space based on at least part of the sequential hologram data.

Owner:PACIFIC LIGHT & HOLOGRAM INC
Naked eye three-dimensional image display method and device, computer equipment and storage medium
The embodiment of the invention discloses a naked eye three-dimensional image display method and device, computer equipment and a storage medium. The method comprises the following steps: acquiring a plurality of three-dimensional virtual sub-objects and initial display parameters corresponding to the plurality of three-dimensional virtual sub-objects in a target naked-eye three-dimensional scene, wherein the plurality of three-dimensional virtual sub-objects have a logic association relationship; displaying initial naked-eye three-dimensional pictures corresponding to the plurality of three-dimensional virtual sub-objects in the naked-eye three-dimensional display screen according to the initial display parameters; generating space display parameters of the plurality of three-dimensional virtual sub-objects according to the logic association relationship; and dynamically adjusting the three-dimensional space positions of at least part of the three-dimensional virtual sub-objects in the plurality of three-dimensional virtual sub-objects according to the space display parameters so as to update the initial naked-eye three-dimensional picture to obtain a target naked-eye three-dimensional picture. In this way, the spatial display parameters are generated through the logic incidence relation to adjust the three-dimensional space position of the three-dimensional virtual sub-object, and simulation stimulation of the human brain in the three-dimensional space can be achieved when the human eyes watch the three-dimensional virtual sub-object.

Owner:SHENZHEN LITITONG TECH CO LTD
Systems and methods for integrating spatial audio into point clouds
Spatial audio integrated point clouds expand the definition of point cloud points to include acoustic characteristics in addition to positional coordinates for the positioning of the points in a three-dimensional (3D) space and visual characteristics for how the individual points are presented at their respective positions in the 3D space. A system may generate a 3D scene based on the positioning of the points, and may track a path for sound that is emitted from a sound source. The system determines that the path reaches a position of one or more of the points, and performs a first adjustment to the sound according to the defined acoustic characteristics of the one or more points.

Owner:MIRIS INC
Autonomous Control Of Powered Earth-Moving Vehicles To Control Calibration Operations For On-Vehicle Sensors
PendingUS20250171983A1Soil-shifting machines/dredgersVehicle position/course/altitude controlMobile vehicleData set
Systems and techniques are described for implementing autonomous control of powered earth-moving vehicles, including to automatically calibrate sensors on a powered earth-moving vehicle, such as to determine position and orientation of directional sensors on movable vehicle parts. For example, an on-vehicle sensor to be calibrated may include a LIDAR sensor located on the powered earth-moving vehicle, such as on a movable component part of the vehicle (e.g., a hydraulic arm, a tool attachment, etc.), and a global common frame of reference is determined for different datasets gathered at different times from such a sensor in order to combine or compare the datasets, such as by determining the sensor position in 3D space at a time of dataset gathering (e.g., relative to another reference point on the vehicle with a known location in the global common frame of reference, such as by using one or more determined transforms).

Owner:AIM INTELLIGENT MACHINES INC
Zero-sample open vocabulary scene understanding method based on semantic instance generation
ActiveCN119478387Aaccurate descriptionReduce storage footprintOther databases indexingEnergy efficient computingPoint cloudSemantic feature
The invention relates to a zero-sample open vocabulary scene understanding method based on semantic instance generation, and the method comprises the steps: obtaining multi-frame image data including depth information, obtaining 2D mask information through segmentation for each frame of image data, carrying out the semantic feature extraction of a 2D mask, projecting the semantic feature to a 3D space, obtaining a 3D point cloud segment, and carrying out the segmentation of the 3D point cloud segment; combining the 3D point cloud fragments into 3D instances through time sequence grouping combination by adopting a semantic-guided under-segmentation filtering and combination threshold linear attenuation strategy to obtain a 3D instance set; for semantic features of each instance in the 3D instance set, performing feature aggregation processing on the premise of considering intra-class similarity and inter-class difference; and based on the 3D instance set after feature aggregation, constructing a hybrid octree-graph structure to realize zero-sample open vocabulary scene understanding. Compared with the prior art, the problems of inaccurate instance segmentation, inaccurate feature aggregation and low spatial representation efficiency are effectively relieved.

Owner:SHANGHAI ARTIFICIAL INTELLIGENCE INNOVATION CENT +1
Three-dimensional scene interactive semantic segmentation method based on online feature distillation
InactiveCN119360011AInternal combustion piston enginesCharacter and pattern recognitionPattern recognitionVisual technology
The invention discloses a three-dimensional scene interactive semantic segmentation method based on online feature distillation, which does not need semantic truth value data, and is characterized in that features of a pre-trained three-dimensional scene semantic segmentation large model are distilled into a three-dimensional grid for coding, and semantic features of any view angle of a three-dimensional scene are directly obtained through rendering. A three-dimensional scene semantic segmentation large model encoder does not need to be operated, and a high-quality semantic segmentation result can be obtained only by operating a decoder; the method can be used for tasks such as positioning and single object extraction based on a 3D space, and belongs to the technical field of computer vision. By adopting the technical scheme of the invention, the processing speed can be greatly improved while the semantic segmentation quality is kept.

Owner:PEKING UNIV