
Patents
Literature
1111 results about "Numeric Value" patented technology
Efficacy Topic
Property
Owner
Technical Advancement
Application Domain
Technology Topic
Technology Field Word
Patent Country/Region
Patent Type
Patent Status
Application Year
Inventor
Information in the form of a numeral contained in a data field.
Self-adaptive prefix key value cache compression method and device and electronic equipment
The invention provides a self-adaptive prefix key value cache compression method and device and electronic equipment, relates to the technical field of computers, and aims to solve the defects of an existing key value cache compression method in the aspect of ensuring high reasoning performance and high task precision. The method comprises the steps that mark sequences corresponding to image information and text information are input into a large model for multi-layer attention interaction, and the attention score of each mark in each layer is obtained; according to the attention score of each mark, determining the importance proportion of each key value cache vector of each layer; taking the importance proportion of the key value cache vectors as a priority numerical value, and performing descending sort on the key value cache vectors in each layer to obtain a priority sequence of the key value cache vectors of each layer; determining a target information retention ratio based on the target compression ratio budget; and according to the target information retention ratio, determining a retained key value cache vector from the priority sequence of the key value cache vector of each layer.

Owner:TSINGHUA UNIVERSITY +1
Keyword selection for skills inference
PendingUS20250053585A1Special data processing applicationsText database queryingArtificial intelligenceData mining
A method, computer program product, and computer system for determining keywords from raw data. A first trained artificial intelligence (AI) model is used to extract, from text associated with first and second persons, a first and second plurality of keywords for each first and second person, respectively. A second AI model is used to determine, for each keyword, a similarity score which is zero for each keyword consisting of a single word and is a numerical measure of similarity between the two words in each keyword consisting of two words. A composite score is computed as a function of a keyword frequency rank, a similarity rank, and a person frequency rank for each keyword. A final list of keywords is generated and consists of keywords in the second plurality of keywords based on the composite score of all of the keywords in both the first and second plurality of keywords.

Owner:INTERNATIONAL BUSINESS MACHINE CORPORATION
Language model training method and device, text processing method and device, equipment and medium
The invention provides a language model training method and device, a text processing method and device, equipment and a medium, and relates to the technical field of natural language processing, and the method comprises the steps: predicting a first probability matrix corresponding to each data unit in a sample text based on a teacher model; the first probability matrix comprises a probability value of each data unit belonging to each lexical element in the first word list; according to the numerical value of each probability value in the first probability matrix, compressing the first probability matrix to obtain a second probability matrix corresponding to each data unit; performing alignment operation on the second word list according to lexical elements corresponding to probability values in the second probability matrix to obtain a third word list; and according to the third word list and the second probability matrix, carrying out distillation training on the student model to obtain a target language model, thereby reducing the storage cost, improving the distillation training efficiency, and enabling the target language model trained according to the method to better adapt to different model architectures and text processing scenes while keeping high performance.

Owner:IFLYTEK CO LTD
Model Compression Method and Apparatus, and Related Device
InactiveUS20250200348A1Physical realisationNeural learning methodsAlgorithmTheoretical computer science
A model compression method includes obtaining a first weight of each layer of a neural network model, where the first weight of each layer is a value of a floating-point type; and quantizing the first weight of each layer based on a quantization parameter to obtain a second weight of each layer. The second weight of each layer is a multi-bit integer. Quantities of bits of second weights of at least a part of layers are different. A quantity of quantization bits of a second weight of a layer with high sensitivity to a quantization error is greater than a quantity of quantization bits of a second weight of a layer with low sensitivity to the quantization error.

Owner:HUAWEI TECH CO LTD
Distribution encoding for quantizing model weights
PendingUS20250077945A1Digital data processing detailsMachine learningAlgorithmTheoretical computer science
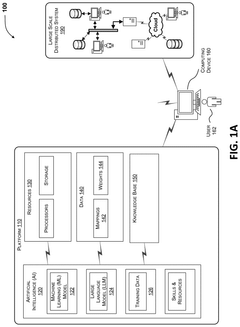
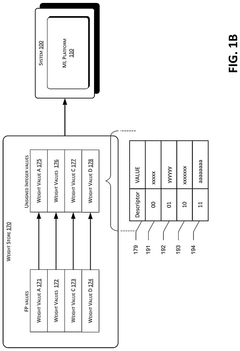
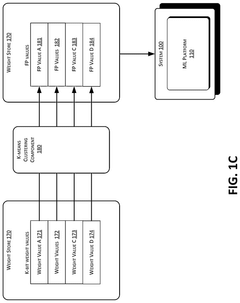
Methods are described for improving processing and storage efficiencies in large language models (LLMs) while also improving numerical accuracy. The methods are referred as distribution encoding. The disclosed distribution encoding techniques exploit the non-uniform distribution of model weights to provide improved numerical accuracy and compression, and consequently can reduce the number of GPU's needed for inferencing. This in turn enables the reduction of resources and cost necessary to implement such models.
Owner:MICROSOFT TECHNOLOGY LICENSING LLC
Graph path prediction and masked language modelling joint training algorithm for language models
ActiveUS20250060951A1Other databases indexingSpecial data processing applicationsLinguistic modelAlgorithm
In an embodiment providing natural language processing (NLP), a computer generates a histogram that correctly represents a graph that represents a lexical text, and generates a token sequence encoder that is trainable and untrained. During training such as pretraining, the token sequence encoder infers an encoded sequence that incorrectly represents the lexical text, and the encoded sequence is dense and saves space. To increase the accuracy of the sequence encoder by learning, the token sequence encoder is adjusted based on, as discussed herein, an indirectly measured numeric difference between the encoded sequence that incorrectly represents the lexical text and the histogram that correctly represents the graph.


Owner:ORACLE INT CORP
Natural language character and numerical value general solution system and method based on 4HPU and application of natural language character and numerical value general solution system and method
PendingCN120386847ANatural language data processingSpecial data processing applicationsCode generationChinese characters
The invention discloses a 4HPU-based natural language character and numerical value general solution system and method and application thereof, and aims to solve the technical problem of realizing unification, universality and reasonability of natural language character and numerical value codes. A main coding path for realizing coding generation and structure nesting is arranged; the method comprises the following steps of: constructing a basic coding unit, judging the types and codes of numerical values, letters, Chinese characters or symbols; compared with the prior art, the method has the advantages that natural numbers, letters, Chinese characters and symbols are subjected to structured coding in a right-to-left nesting mode, complete coded word strings are obtained, structural expression and path reasoning are clear, dynamic expansion and compression can be achieved, and the coding efficiency is improved. And a more excellent basic coding method is provided for application scenes of data recovery and reverse recognition, natural language processing, intelligent communication and low-power-consumption equipment.

Owner:SHENZHEN QIANHE JIJI HEALTH IND CO LTD
Dynamic speculation sampling method and system for large model reasoning
The invention relates to a dynamic speculation sampling method and system for large model reasoning. The method comprises the following steps: processing requests for multiple groups of input test data of similar scenes based on a predetermined application scene reasoned by the large model, obtaining the maximum throughput data volume of the throughput data volume of the target model in the conventional sampling mode and the maximum throughput data volume of the throughput data volume of the target model in the speculation sampling mode, wherein the maximum throughput data volume is larger than or equal to the maximum throughput data volume of the throughput data volume of the corresponding conventional sampling mode. Configuring a request number span sequence which is used for dynamic speculation sampling and is arranged from large to small and a draft token number sequence which is arranged from small to large and has corresponding length; aiming at a specific data processing request, determining a span value interval formed by adjacent request values of the current survival request number in the request number span sequence according to the current survival request number, and setting a draft token number for each request in the current survival request number based on a draft token value in a draft token number sequence corresponding to a lower request value of the span value interval.

Owner:BEIJING SILICONFLOW TECHNOLOGY CO LTD
Three-dimensional data encoding method, three-dimensional data decoding method, three-dimensional data encoding device, and three-dimensional data decoding device
A three-dimensional data encoding method includes: calculating coefficient values from pieces of attribute information of three-dimensional points included in point cloud data; generating a second code sequence including first information and second information, the first information indicating a total number of zero coefficient values consecutive in a first code sequence in which the coefficient values are arranged, the second information indicating whether each of the coefficient values is 0, the zero coefficient values being included in the coefficient values and having a value of 0; and generating a bitstream including the second code sequence.

Owner:PANASONIC INTELLECTUAL PROPERTY CORP OF AMERICA
Code review method, system and device, storage medium and program product
PendingCN119576740AImprove development efficiencyshorten the timeDigital data information retrievalSemantic analysisTheoretical computer scienceWebhook
The invention discloses a code review method, system and device, a storage medium and a program product, and the method comprises the steps: cleaning a to-be-reviewed code snippet, and obtaining an incremental code snippet and position information; vectorizing the incremental code snippets; semantic query is conducted on the vectorized incremental code snippet data based on an ES database according to the cosine law, development rules of similar semantics are obtained and ranked from high to low according to similarity values, and a preset number of first several snippets are obtained; recombining cue words, wherein the recombining cue words comprise incremental code snippets and a preset number of development rules; and sending the recombined cue word to a general generative large model to obtain an examination suggestion. The code snippets to be examined are pushed to the gilab warehouse by a developer, and are cleaned by the gilab warehouse through webhook triggering. According to the review method, the whole process is automatic, the review efficiency is high, review can be conducted according to the development rules in the team, knowledge sharing is achieved, the review result is objective, and the problem that the text exceeds the upper limit is avoided.

Owner:BEIJING ZHUZHE INFORMATION TECHNOLOGY CO LTD
Data processing method and device and electronic equipment
The invention provides a data processing method and apparatus, and an electronic device. The method comprises the steps of obtaining a linked list array of a specified size and a to-be-updated P2L reverse mapping table; determining the number of an L2P forward mapping table to which each logic offset address belongs; for each L2P forward mapping table, calculating relative offset between each logic offset address belonging to the table and a specified logic offset address, and calculating a remainder value obtained by dividing the number by a specified size; adding each relative offset corresponding to the L2P forward mapping table to a linked list corresponding to the remainder value; and updating the physical offset address corresponding to the logic offset address indicated by each relative offset in each linked list. According to the mode, the linked list array with the specified size is used, each relative offset corresponding to the L2P forward mapping table is uniformly recorded in each linked list by adopting the mode that the specified size is remainder by adopting the serial number of the L2P forward mapping table to which the logic offset address belongs, so that the query efficiency can be improved, and the consumption of a memory is reduced.

Owner:SHENZHEN CITY TECHWIN SEMICONDUCTOR COMPANY LIMITED
Configuration method and device of system memory management unit, equipment and storage medium
The invention provides a system memory management unit configuration method and device, electronic equipment and a computer readable storage medium, and the method comprises the steps: distributing corresponding external equipment for each virtual machine according to a preset configuration file, and storing the external equipment in a preset table recording the information of the external equipment; acquiring a numerical value of a first specified data bit of a table item corresponding to the distributed external equipment, before the virtual machine is started, setting the numerical value of the first specified data bit as a preset value, and after the virtual machine is started, adjusting the numerical value of the first specified data bit as a first numerical value, the method comprises the following steps: when a virtual machine accesses a memory through an input operation of an external device, obtaining a physical address of the input operation, obtaining a target memory address matched with the physical address of the input operation from a corresponding relationship between the physical address recorded in a page table corresponding to the virtual machine to which the external device belongs and the memory address, and according to the target memory address, storing the target memory address in the external device; and the memory is accessed by the input operation, so that the probability of unsafe memory access is reduced.

Owner:BEIJING INSTITUTE OF OPEN SOURCE CHIP
LLM-based multi-source heterogeneous data intelligent fusion and adaptive processing method
The invention relates to the technical field of data processing, in particular to an LLM-based multi-source heterogeneous data intelligent fusion and self-adaptive processing method, which comprises the following steps of: receiving multi-source heterogeneous data, matching character sequences of mailbox fields and identity card number fields in records one by one by adopting a preset regular expression model, according to a preset key value pair mapping dictionary, items are uniformly converted, data records which cannot pass format verification, type conversion and value domain mapping are marked as doubt, and data records which cannot be processed or are marked as suspicious are separated. According to the method, a hierarchical processing flow is constructed, and deterministic format verification, type conversion and value domain mapping are arranged at the front end of a processing link, so that most simple data quality problems can be quickly processed with low calculation overhead. Then, numeric statistics and character string comparison are used to carry out fuzzy correction on the data, and spelling errors and numeric abnormities which cannot be covered by rules are further solved.

Owner:GUANGXI BEITOU SOFTWARE CO LTD
Cross-network file ferrying system
ActiveCN119835077AEnergy efficient computingSecuring communicationComputer hardwareFile transmission
The invention discloses a cross-network file ferrying system, and relates to the technical field of file transmission, a user side end is set to obtain a target file selected and uploaded by a target user, a cross-network file transmission module is set to execute a pre-processing operation on the target file to obtain a pre-processed file, and then a grouping operation is executed on the pre-processed file; after the grouping operation is completed, executing an addition operation of a binary algorithm on two adjacent groups of block arrays, recording carry bits in the execution of the addition operation, and determining the execution carry type of each block array according to the characteristic whether the numerical value of the carry bits is continuous or not and whether the carry bits exist or not; according to the method and the device, the block array is selected, then the carry state sequence and the reverse array of the block array are determined according to the execution carry type, and the target file is encrypted in this way, so that on one hand, encryption and decryption of data obtained after encryption depend on data characteristics of the file and get rid of key dependence, and the risk of key loss is avoided; and safer cross-network file transmission is realized.

Owner:ZHILIAN INFORMATION TECH CO LTD
Calculation method of rolling mill roll change pressing position
PendingCN119623009Aaccurate calculationDesign optimisation/simulationSpecial data processing applicationsWork rollProcess engineering
The invention relates to a method for calculating a rolling mill roll changing pressing position, and belongs to the technical field of rolling mill roll changing methods. According to the technical scheme, the method comprises the steps that CAD modeling is carried out, a constraint relation is established to simulate field reality, indication marking lines and a size relation are set, key parameter sizes are displayed in real time, related size links are established, data calculation and automatic correction are carried out through a set logic relation, and calculation and inspection of key parameters such as the rolling mill roll changing pressing position are completed. And meanwhile, a numerical value displayed on an operation interface is compared with a calculation result, and data is manually corrected. The method has the beneficial effects that key parameters such as an optimal screw-down position value can be displayed only by inputting diameter data by using the model when the supporting roll is replaced every time, so that the screw-down position corresponding to each set of supporting roll is suitable for working rolls in all diameter ranges, tedious calculation is avoided, and the method has the advantages of simplicity, rapidness, high calculation precision and the like, and is suitable for popularization and application. The method can effectively solve the problem of accurate calculation of the rolling mill roll change screw-down position.

Owner:HANDAN IRON & STEEL GROUP CO LTD +1
Model reasoning method and device, electronic equipment, storage medium and program product
The invention provides a model reasoning method and device, electronic equipment, a storage medium and a program product. The method comprises the following steps: performing attention calculation on inferred tokens by adopting first numerical precision through a large language model to obtain a first attention score corresponding to each inferred token; screening a target tokens from the inferred tokens based on the first attention score; reasoning the input sequence by adopting second numerical precision through the large language model to obtain a reasoning result output by the large language model; the input sequence comprises a target token and tokens to be input corresponding to the token to be inferred; the tokens to be input are tokens pre-selected from the inferred tokens according to a preset rule; the first numerical precision is lower than the second numerical precision. According to the method, the sparse processing of the token is realized by adopting mixed precision calculation, so that the reasoning efficiency of the large language model is improved.

Owner:NANJING ILUVATAR COREX TECH CO LTD (DBA ILUVATAR COREX INC NANJING)
Edge construction method and device of graph database
ActiveCN119691234AOther databases indexingOther databases queryingAlgorithmTheoretical computer science
The invention discloses an edge construction method and device of a graph database. The edge construction method of the graph database comprises the steps of generating character strings based on attribute values of edges in the graph database; converting a character at a preset position in the character string into a long integer to obtain a numeric long integer identifier of the edge; and writing the numeric long integer identifier into the graph database as an identifier of the edge. According to the method, the unknown edge identifier can be changed into the known edge identifier through the edge construction method, so that the action of querying the edge before the edge is updated or rewritten can be avoided, and the performance of updating or rewriting the edge is improved.

Owner:ZHEJIANG DAHUA TECH CO LTD
Part monitoring method, electronic equipment, storage medium and product
The invention discloses a part monitoring method, an electronic device, a storage medium and a product, and relates to the technical field of servers, the method is applied to a data processing unit card, the data processing unit card comprises N parts, N is a positive integer greater than or equal to 2, and the method comprises the following steps: obtaining the health state of each part in the N parts; a binary number corresponding to each component is generated based on the health state of each component, N binary numbers are obtained, each binary number is a first numerical value or a second numerical value, the first numerical value is used for indicating that the health state of each component is healthy, and the second numerical value is used for indicating that the health state of each component is abnormal; forming a binary character string by the N binary numbers according to a preset rule; and when a monitoring request sent by a substrate management controller at a host side is received, sending the binary character string to the substrate management controller. Multiple query command monitoring components do not need to be sent frequently, and occupation of a large number of system resources and network bandwidth is avoided.

Owner:INSPUR SUZHOU INTELLIGENT TECH CO LTD
Message recombination compression method and device, equipment and storage medium
PendingCN119484427AImprove positioning speedReduce storage space requirementsTransmissionComputer hardwareCompression method
The embodiment of the invention provides a message recombination compression method and device, equipment and a storage medium, which are applied to the technical field of computers, and the method comprises the following steps: obtaining a plurality of continuous messages, and analyzing each message to obtain a plurality of fields in each message; obtaining classification information of the fields, and grouping the fields according to the classification information to obtain field groups; extracting numerical value distribution information of each field group, and determining a target compression mode of the current field group based on the numerical value distribution information; compressing the current field group according to the target compression mode to obtain a compressed field; message collection information is extracted from the message, and file header information is obtained through calculation according to the message collection information; and assembling the file header information and the compressed field to obtain a packaged file of the message, and according to the method and the device, through disassembling and recombining the continuous message, filtering and compressing the duplicate value and the similar value, the requirement of a storage space is remarkably reduced.

Owner:CHONGQING JINKANG NEW ENERGY VEHICLE CO LTD
Data processing method for chip, chip and electronic equipment
The embodiment of the invention provides a data processing method for a chip, the chip and electronic device.The method comprises the steps that in response to a target triggering condition, counting values of all performance counters in the chip are grouped and collected, and multiple sets of counting data are obtained; each group of counting data comprises counting values of a plurality of performance counters; performing compression processing on the multiple groups of counting data to obtain multiple groups of compressed counting data; and respectively sending the plurality of groups of compressed counting data to a memory. Therefore, on one hand, the dumping efficiency of the count value of the performance counter can be improved, and the overall performance of the chip is improved; on the other hand, the problem that the counting data of each group cannot be matched easily due to too many groups can be improved, and the accuracy after the counting value data dumped in groups are recombined is improved; and on the other hand, time consumed by the user to wait for numerical value dump of the performance counter can be reduced, and user experience is improved.

Owner:MOORE THREADS TECH CO LTD
Communication method and device
PendingCN119835118AModulated-carrier systemsBaseband system detailsInterference (communication)Terminal equipment
The invention relates to a communication method and device, in the communication method, an offset and a first numerical value indicated by first information are associated with a first index value and a second index value, which indicates that both the first index value and the second index value are determined based on the offset and the first numerical value, and the offset and the first numerical value are changed. The first index value and the second index value also change. Meanwhile, the first index value and the second index value are associated with the first sequence, which means that the terminal device can simultaneously control the first index value and the second index value used for determining the first sequence based on the first information, so that the first sequence can be selected from a larger selectable sequence set, thereby having better interference randomization performance. This reduces the situation that the first sequence determined by the terminal device is the same as the sequence of the adjacent cell, resulting in that the adjacent cell adopts the same reference signal. Therefore, the interference problem caused by adopting the same reference signal by the adjacent cells is reduced, so that the accuracy of channel estimation can be improved.

Owner:HUAWEI TECH CO LTD
Load prediction method and device, storage medium and electronic equipment
PendingCN119543109AImprove forecast accuracySolve technical problems with low accuracyLoad forecast in ac networkForecastingLoad forecastingAlgorithm
The invention discloses a load prediction method and device, a storage medium and electronic equipment, and relates to the field of smart power grids and prediction analysis. The method comprises the following steps: acquiring a historical load sequence and first data of a first time period and second data of a second time period; decomposing the historical load sequence into N first components and M second components through target operation; dividing the N first components into Z sequences according to the numerical value change condition of each first component; adding the first data and the second data into each sequence of the Z sequences, and taking the sequence added with the first data and the second data as a target sequence to obtain Z target sequences; and determining a target load prediction result of the second time period according to the Z target sequences and the M second components. According to the invention, the technical problem of low accuracy of a load prediction result caused by difficulty in processing nonlinear and non-stationary data in a traditional prediction method is solved.

Owner:STATE GRID BEIJING ELECTRIC POWER CO +1
Apparatus for processing incoming and / or outgoing data-elements
The invention relates to an apparatus (200) for processing incoming and / or outgoing data-elements (11) cyclically, the data-elements (11) representing numerical and / or logical values that are linked to an upper-layer application.

Owner:TECONCEPT GMBH
System and Method for Data Compaction and Encryption of Anonymized Data Records
A system and method for data compaction and encryption of anonymized data records. A dataset may be pre-processed by dividing into sourceblocks at reasonable intervals and tallying each sourceblock's frequency, creating a tally record of tokens and count values. This tally record may then be anonymized and transmitted to a data deconstruction engine which combined with a library manager creates a codebook and performs optimization techniques on the codebook. The data deconstruction engine and library manager may be distributed across multiple nodes or devices. The received anonymized tally record may be parsed into individual tokens by identifying the tokens with the highest count value. The tokens may then be sent descending order of count value to the library manger where each token may be assigned a codeword. A half-backed codebook is then created using the tokens and each token's unique codeword, before sending the half-backed codebook to a system user.

Owner:ATOMBEAM TECH INC
Storage and calculation integrated processor and processing method based on POSIT format
ActiveCN120670371ADigital data processing detailsArchitecture with single central processing unitData classComputation complexity
According to the storage and calculation integrated processor based on the POSIT format and the processing method, the calculation complexity during network training can be greatly reduced by utilizing the improved POSIT data format, meanwhile, due to the fact that the characteristic of dynamic bit width is reserved, the numerical value representation range is widened, the neural network training precision is guaranteed, and the processing efficiency is improved. The problems that in the prior art, low-precision training supports multiple floating points or integer data formats, and POSIT data types are not supported are solved. And a large number of optimization means are needed to ensure the precision, so that the technical scheme is complicated, the data format lacks flexibility, and network parameters cannot be effectively represented.

Owner:XIDIAN UNIV HANGZHOU RES INST +1
Data processing method and device, equipment, storage medium and program product
PendingCN119921782AModulated-carrier systemsCode conversionData compressionTheoretical computer science
The embodiment of the invention provides a data processing method and device, a storage medium and a program product. In the method, a data compression device obtains data to be compressed; and performing L times of iterative approximation on the to-be-compressed data. Wherein the L times of iteration approximation comprises the following steps: respectively selecting L column vectors from L codebook matrixes to approximate the data to be compressed, wherein elements in the L codebook matrixes comprise two different numerical values; and generating compressed data after the to-be-compressed data is compressed based on the L column numbers of the L column vectors in the L codebook matrixes. Therefore, the original signal is approximated by using the two small codebooks with different numerical values, the search and storage overhead is reduced, and the execution efficiency is improved.

Owner:HUAWEI TECH CO LTD
Physical calculation question correcting method and device, related equipment and computer program product
PendingCN119493859ABiological modelsSpecial data processing applicationsAlgorithmTheoretical computer science
The invention discloses a physical calculation question correction method and device, related equipment and a computer program product. The physical calculation question correction method comprises the steps of obtaining a question, a standard answer and an answer text; formulae in the standard answer and the answer text and answers corresponding to the formulae are extracted respectively, the types of the formulae are determined, and the types at least comprise pure symbol formulae and pure numerical formulae; on the basis of the questions, performing physical quantity reduction on formulas of pure numerical formula types contained in the standard answers and the answer texts so as to reduce the formulas into symbol formulas; and determining a correction result of the answer text based on symbol formulas contained in the question, the standard answer and the answer text and corresponding answers. The method provided by the invention is more suitable for the physical calculation question correction task, and the obtained correction result is more accurate.

Owner:IFLYTEK CO LTD
Session quality evaluation method, system, equipment and medium
PendingCN119539819Aeffective calculationimprove accuracyMathematical modelsDigital data information retrievalUndirected graphData science
The invention provides a session quality evaluation method, system and device and a medium, and relates to the technical field of data analysis, the method comprises the following steps: determining candidate keywords based on session information of a current session; determining the keyword weight of each candidate keyword based on the undirected graph, selecting a preset number of candidate keywords as keywords based on the values of the keyword weights, and determining the sentiment weight of each keyword according to the sentiment tendency and sentiment intensity corresponding to each keyword under each evaluation dimension; according to the dynamic change condition of the emotional tendency and / or emotional intensity corresponding to each keyword in the session information, dynamically adjusting the emotional weight of each keyword; and in combination with the occurrence frequency, the emotion weight and the keyword weight of each keyword, performing weighted summation on the score of each score dimension to obtain a session quality score of the current session. According to the method, the session quality can be accurately and quickly evaluated.

Owner:SHENZHEN WEIYING TECHNOLOGY CO LTD
Code quality automatic evaluation method and related equipment
PendingCN120029627AError detection/correctionNeural learning methodsAlgorithmTheoretical computer science
The invention discloses a code quality automatic evaluation method and device, a server, a computer readable storage medium and a computer program product. The method comprises the following steps: generating a token sequence of an evaluated target code, converting the token sequence into a word vector, performing semantic correlation extraction on adjacent tokens in the word vector, constructing code representation, converting original code tokens from text information into numerical vector information, and inputting a code representation vector into a feedforward neural network model for regression prediction, so as to obtain the target code. And the code quality is automatically scored. According to the method, code representation is applied to code segment score prediction, grammar and semantic information contained in a code token sequence is fully utilized, hidden representation contained in a code segment is mined and used for predicting the quality score of the code segment, objective and fine-grained accurate one-key scoring can be achieved, and low-cost, high-efficiency and automatic intelligent code evaluation is achieved.

Owner:DUXIAOMAN TECH (BEIJING) CO LTD
Method for disguising and hiding data in memory address
InactiveCN120469942AUnauthorized memory use protectionDigital data protectionMemory addressAlgorithm
The invention discloses a method for disguising and hiding data in a memory address, and relates to the technical field of data protection and memory management. The method comprises the steps of obtaining a real numerical value of a target variable needing to be protected; splitting the real numerical value into a plurality of sub-numerical values, and storing the plurality of sub-numerical values in a group of newly allocated storage units in a memory; and when the target variable needs to be used, restoring the real numerical value of the target variable from the plurality of sub-numerical values. The target variable still allocates an address in the memory, but stores the disguise value. The sub-values can be generated through multiple attenuation modes and written into a protection array which is the same as the target variable data in type. The sub-values can be stored in a random index or sequential storage mode, and the protection array can be re-declared during each assignment or reused when conditions are met. According to the method, the hiding performance and the tamper-resistant capability of the data in the memory are effectively improved, and the method is suitable for an application scene in which safety protection is carried out on the local operation data.

Owner:ZHONGBO INFORMATION TECH RES INST CO LTD