
Patents
Literature
8361results about "Physical realisation" patented technology
Efficacy Topic
Property
Owner
Technical Advancement
Application Domain
Technology Topic
Technology Field Word
Patent Country/Region
Patent Type
Patent Status
Application Year
Inventor
AI Serving Hardware and Software Frontier Enhancements
PendingUS20250390352A1Memory architecture accessing/allocationResource allocationComputer hardwareComputer architecture
A computer system implements a unified framework integrating an adaptive elastic funnel (AEF) with a convergent intelligence fabric (CIF) for multi-agent AI collaboration. The system provides a universal multi-modal key-value subsystem for sharing partial computations, implements hybrid placement strategies for dynamic memory management, and incorporates quantum-resistant secure enclaves. The architecture integrates hardware acceleration through GPU-FPGA hybrid caching and neuromorphic processors, applies adaptive energy and thermal management across hardware generations, and implements autonomous flash resource orchestration with multi-dimensional wear management. The system orchestrates tensor workflows using hierarchical scheduling, enables cross-agent collaboration with privacy preservation, and supports continuous learning without catastrophic forgetting. This integration delivers unprecedented computational efficiency and security in high-dimensional decision-making environments while supporting incremental adoption through modular interfaces.

Owner:QOMPLX INC
Dynamic Latent Space Adaptation Based on Spatiotemporal Kernal Context for Multiscale Rendering
ActiveUS20260010729A1Mathematical modelsDigital data information retrievalPattern recognitionMetric tensor
A system for dynamic latent space adaptation using spatiotemporal kernel context for multiscale rendering with hierarchical and Lorentzian autoencoders. The Spatiotemporal Kernel Estimator (SKE) analyzes media through motion field, temporal recurrence, frequency band, and scene semantics analyzers to generate adaptive kernel parameters encoding content-specific importance distributions. The system dynamically adapts latent manifold geometry by modifying metric tensor properties according to kernel context, enabling content-aware compression that allocates representational capacity based on visual significance. A multiscale cache implements kernel-adaptive retention policies prioritizing important regions. An adaptive renderer provides intelligent level-of-detail selection based on zoom level and kernel-estimated importance, optimizing processing allocation. The self-optimizing architecture continuously refines kernel context and geometric adaptation based on user interaction and performance feedback, achieving superior compression ratios and perceptual quality. Applications include bandwidth-efficient video streaming, virtual reality, scientific visualization, and cognitive video analytics requiring intelligent context-aware visual processing.

Owner:ATOMBEAM TECH INC
Method and apparatus for efficient access to multidimensional data structures and / or other large data blocks
ActiveUS12499052B2Memory architecture accessing/allocationProgram synchronisationMemory addressComputer architecture
A parallel processing unit comprises a plurality of processors each being coupled to a memory access hardware circuitry. Each memory access hardware circuitry is configured to receive, from the coupled processor, a memory access request specifying a coordinate of a multidimensional data structure, wherein the memory access hardware circuit is one of a plurality of memory access circuitry each coupled to a respective one of the processors; and, in response to the memory access request, translate the coordinate of the multidimensional data structure into plural memory addresses for the multidimensional data structure and using the plural memory addresses, asynchronously transfer at least a portion of the multidimensional data structure for processing by at least the coupled processor. The memory locations may be in the shared memory of the coupled processor and / or an external memory.

Owner:NVIDIA CORP
End-side multi-mode large model accelerated reasoning method and system
The invention provides an end-side multi-modal large model accelerated reasoning method and system, and the method comprises the steps: carrying out the two-stage screening and rearrangement of visual tokens based on the CLS attention and text-to-visual attention in a visual encoder and pre-filling stage, and constructing a sparse attention and sparse key value cache; in a decoding stage, an important neuron set is judged according to activation gating or historical statistics, only a corresponding feedforward network weight is pulled and calculated, missed weights are loaded on demand through asynchronous I / O, and hot neurons are maintained in a high-speed memory to utilize model sparsity, so that video memory / memory occupancy and calculation overhead are remarkably reduced on an end side; throughput and time delay performance are improved. According to the method, the internal memory and computing resources required by reasoning of the multi-modal large language model are reduced from two dimensions by utilizing the endogenous sparsity of the end-side large language model in input and the model, so that a higher reasoning speed is achieved by utilizing fewer resources on the premise of keeping the size of the model unchanged, and the performance of the whole system is improved.

Owner:SHANGHAI JIAOTONG UNIV
Neural network execution streams
ActiveUS12443831B1Program synchronisationInterprogram communicationApplication programming interfaceGraph Node
Apparatuses, systems, and techniques to perform a neural network. In at least one embodiment, an application programming interface schedules two or more graph nodes to be performed by two or more parallel processing pipelines based, at least in part, on an order of layers in the neural network.

Owner:NVIDIA CORP
Parameter-efficient large-language fine-tuning federated learning framework
Provided in the present invention is a parameter-efficient large-language fine-tuning federated learning framework, comprising the following steps: performing modeling on LoRA adapters of different edge clouds; since different weights exhibit different average performances on the LoRA adapters, using singular values to quantify the importance of the weights, and therefore, before each round of independent training of the LoRA adapters using N edge clouds, using a matrix singular value to decompose a BA matrix in the LoRA adapter for each trainable weight; configuring heterogeneous LoRA adapters on the basis of the importance of the weights; and using different numbers of quantization bits to quantize a pre-trained model, and performing high-precision inverse quantization on the pre-trained model only when matrix multiplication is executed, wherein the pre-trained model is quantized to the maximum number of quantization bits on the basis of the memory budget of the edge clouds. The present invention has the following beneficial effects: the present invention determines the optimal fine-tuning model structure, thereby improving the performance of LLM fine-tuning, and adapts to heterogeneous and resource-constrained edge clouds.

Owner:FUDAN UNIVERSITY
Distributed training of machine learning models
A resource set which includes multiple servers with a respective plurality of training computing devices is identified for training a machine learning model. The resource set is subdivided into partition groups, such that each partition group can store a respective replica of state information of the model. The model is trained using the partition groups. The training comprises a multi-stage gathering of a portion of the state information at training computing devices of a particular partition group. Different types of communication channels between training computing devices are used in respective stages of the gathering, including inter-server communication channels in one stage and an intra-server communication channel during another stage. A trained version of the model is stored.

Owner:AMAZON TECH INC
In-memory computing circuit chip based on magnetic cache and computing device
PendingCN113539318AHigh densityLarge capacityDigital storageNeural architecturesData needsEngineering
The embodiment of the invention discloses an in-memory computing circuit based on a magnetic cache, and the circuit comprises at least one magnetic cache unit, at least one in-memory computing unit, and a timer. The magnetic cache unit in the at least one magnetic cache unit is used for caching data output by the corresponding in-memory computing unit as to-be-processed data within the corresponding data retention time; the timer is used for respectively setting data retention time for the at least one magnetic cache unit; and the in-memory computing unit in the at least one in-memory computing unit is used for extracting the data to be processed from the corresponding magnetic cache unit for calculation and outputting the computed data to other magnetic cache units. According to the embodiment of the invention, the invention achieves the flexible adjustment of the data retention time of the magnetic cache unit in various in-memory calculation scenes, and achieves the provision of a high-capacity cache for the data needed by in-memory computing under the lower power consumption.
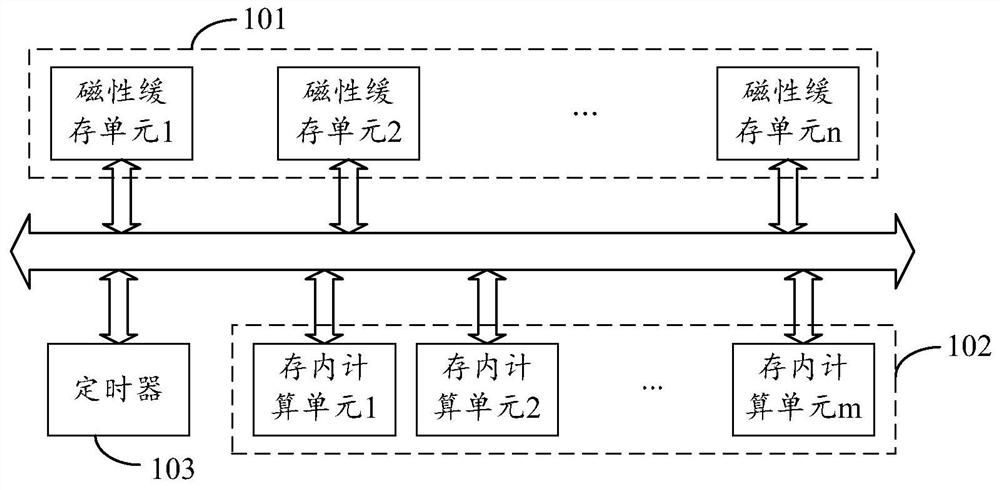
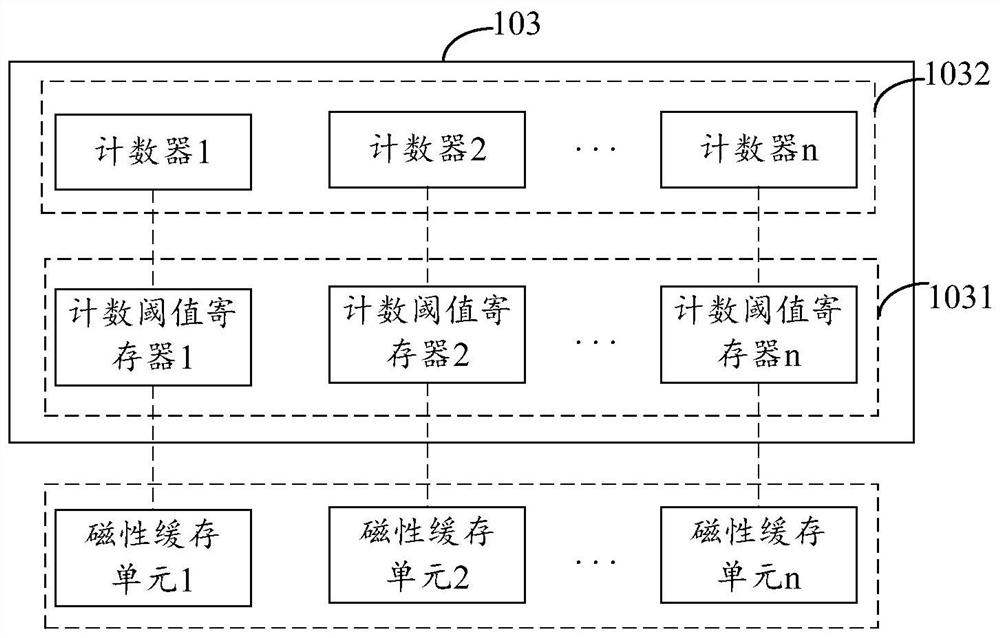
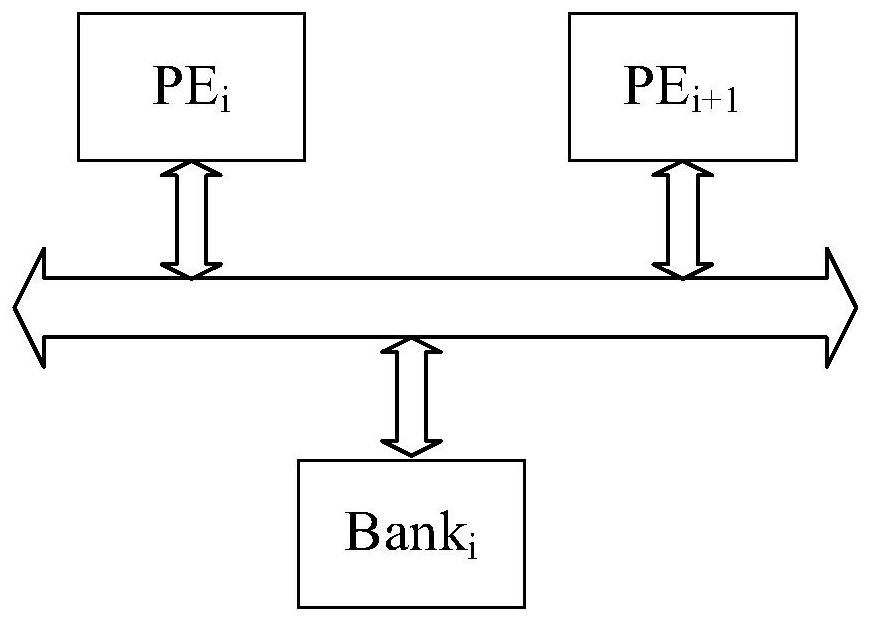
Owner:NANJING HOUMO TECH CO LTD
Target recognition model reasoning optimization method and device
The invention provides a target recognition model reasoning optimization method and device, and the method comprises the steps: firstly carrying out the structural analysis and sensitivity evaluation of a pre-training model, extracting the structural features of each network layer, activating the distribution features, carrying out the quantitative sensitivity scoring, and constructing a data set reflecting the hierarchical features and fault-tolerant capability; and querying a quantitative configuration knowledge base based on the data set to generate a heterogeneous quantitative strategy. Layered low-bit quantization is executed according to the strategy, and a layered weighted loss function is introduced to carry out quantization perception training, so that precision loss caused by bit width compression is effectively compensated. According to the method, through hierarchical heterogeneous quantification, the model recognition precision is preserved to the maximum extent while high compression ratio and reasoning acceleration are achieved, and particularly, the performance of a high-sensitivity layer is protected. The generated heterogeneous quantitative model remarkably reduces memory occupation and power consumption, is suitable for an edge hardware platform with limited resources, forms a set of complete automatic process from analysis and configuration to training compensation, and has good universality and engineering practical value.

Owner:CHINA WEAPON EQUIP RES INST
Mixed data precision matrix multiplication and addition unit and calculation method
The invention provides a mixed data precision matrix multiplication and addition unit and a calculation method, the matrix multiplication and addition unit comprises a calculation unit, and the calculation unit comprises a format division module, a multiplication array module, an addition tree module, an accumulator module, a normalization module and a shift register module. The calculation unit converts the first input matrix and the second input matrix into input data in a middle floating point format; executing parallel multiplication operation on the input data to generate an intermediate product result; performing index alignment and accumulation on the intermediate product result to generate an intermediate accumulated value; accumulating the intermediate product result and the value of the third input matrix in a form of accumulating an intermediate accumulated value, and outputting an accumulated result; and converting an accumulation result into a normalized result and outputting the normalized result. The format division module supports various precisions and converts data with different widths into an intermediate floating point format, so that other hardware units can be reused, and the problems that hardware resources are complex and different model reasoning scenes are difficult to meet are solved.

Owner:NANJING UNIV
Temporal dynamics simulation in matmul-free neural architectures
InactiveUS20260004150A1Neural architecturesPhysical realisationNeural network systemSpiking neural network
A method is provided for processing data in a neural network system. The method includes receiving input data; processing the input data through a first set of neural network layers configured to perform data processing using MatMul-free techniques to produce intermediate data; further processing the intermediate data through a second set of neural network layers configured to simulate spiking neural network (SNN) functionalities using MatMul-free techniques; and outputting a result based on the processed data from the second set of neural network layers.

Owner:LEPTUDE INC
Intelligent scheduling method and system for Huaan Atlas heterogeneous computing resources based on dynamic load awareness
The invention belongs to the technical field of computing resource scheduling, and particularly relates to an intelligent scheduling method and system for Huaan Atlas heterogeneous computing resources based on dynamic load awareness. The method comprises the steps that the real-time state of multi-dimensional hardware data is collected, and a basic data source is provided for subsequent steps; dynamically adapting tasks and hardware characteristics through a matching degree matrix, modeling aiming at various basic data, and constructing a state vector required by reinforcement learning; predicting a fault risk score through a lightweight prediction model deployed at each computing node; and a deep Q network is adopted as a model architecture, a state vector and a fault risk score are input, reinforcement learning training is performed through a reward function in a multi-target vector form, a final scheduling model is obtained, and a task allocation decision is output. The problems that in the prior art, the hardware state cannot be sensed in real time, hardware characteristic matching is ignored, consequently, the computing resource utilization rate is insufficient, and fault recovery is passive are solved.

Owner:SHANDONG ZHIYANG ELECTRIC
Persistent Artificial Intelligence Agents
Techniques include generating, by an artificial intelligence agent, a request for artificial intelligence data. The techniques further include presenting the request via a user interface. The techniques further include receiving the artificial intelligence data. The techniques further include providing the artificial intelligence data to the artificial intelligence agent for at least one of training or inference.

Owner:AVAULTI INC
Large language model accelerator architecture based on three-dimensional NAND flash memory
The invention discloses a large language model accelerator architecture based on a three-dimensional NAND flash memory, and belongs to the technical field of calculation, reckoning or counting. The architecture comprises a three-dimensional NAND flash memory used for executing feedforward neural network calculation; the auxiliary calculation unit is used for executing attention mechanism calculation; the DRAM chip is used for storing attention mechanism related weights and KV cache; and the interconnection resource is used for realizing data interaction among the components. Wherein the three-dimensional NAND flash memory comprises a logic chip and an NAND array chip, the logic chip is used for controlling and executing calculation, and the NAND array chip is used for storing weights and participating in calculation. The invention further provides a scheduling method based on KV cache awareness. The scheduling method comprises decomposition and dynamic allocation of calculation tasks. Through collaborative design of the hardware architecture and the scheduling method, the memory wall bottleneck in large language model calculation can be relieved, the energy consumption is reduced, and the overall calculation performance is improved.

Owner:SOUTHEAST UNIV
Graph neural network execution on neural processing unit
PendingUS20250307656A1Inference methodsPhysical realisationTheoretical computer scienceComputational model
Workloads for executing a graph neural network (GNN) may be divided among various processing units, such as a central processing unit (CPU) and a neural processing unit (NPU). The NPU may include a data processing unit (DPU) and a digital signal processor (DSP). The CPU may perform precomputation, model optimization, hardware optimization, and compilation. For example, the CPU may precompute a parameter matrix and use the parameter matrix as internal parameters of a GNN. The CPU may also perform node padding, approximation computation, or transfer of DSP operations to DPU to optimize the GNN. The CPU may also perform sparsity data compute and storage, vertical fusion of DSP operations and DPU operations, or data quantization to optimize performance of the NPU. The compiled GNN may be provided to the NPU, and the DPU and DSP may perform the operations in the compiled GNN to produce a prediction of the GNN.

Owner:INTEL CORP
Sidecar Security Pattern for Agent Communications
ActiveUS20250321992A1Mathematical modelsDigital data information retrievalCommunications systemInternet privacy
Systems and methods for securing agent communications in a multi-agent system including deploying an agent to communicate with external servers, instantiating a sidecar security service in communication with the agent and including at least one of a guardrails service, a security layer, an encryption module, and an integrity checker configured to validate resources tools using hash-based verification mechanisms. Communications including messages between the primary and the external servers are intercepted by the sidecar security service, which then performs at least one of filtering the one or more messages by the guardrails service, authenticating one or more server connections by the security layer, encrypting one or more outbound requests by the encryption module, or verifying an integrity of resources and tool definitions by the integrity checker.

Owner:MADISETTI VIJAY
Zoom factor processing module, processor and electronic equipment
The invention discloses a zoom factor processing module, a processor and electronic equipment. The scaling factor processing module comprises: an index extraction unit configured to receive a target tensor and determine an index portion of a target scaling factor corresponding to the target tensor; the multi-scale processing unit is configured to determine a plurality of candidate scaling factors according to the exponential part of the target scaling factor; the first processing unit is configured to execute quantization operation and inverse quantization operation respectively based on the multiple candidate scaling factors and the target tensor, and determine inverse quantization results corresponding to the multiple candidate scaling factors respectively; and the second processing unit is configured to select a target candidate scaling factor as a target scaling factor corresponding to the target tensor according to the inverse quantization results corresponding to the plurality of candidate scaling factors. According to the scaling factor processing module provided by the invention, precise quantization can be efficiently realized on hardware, and the quantization precision is improved.

Owner:SHANGHAI BIREN TECH CO LTD
Dynamic agents with real-time alignment
An example may receive at least one input via at least one device. An example may use the at least one input to determine an objective. An example may use the objective, a multi-agent system, and an automated agent to cause at least one first sub-agent of the multi-agent system to generate and execute a first plan including one or more tasks to achieve the objective. An example may cause at least one second sub-agent of the multi-agent system to execute a second plan to supervise the at least one first sub-agent in accordance with a supervision level that indicates a level of supervision of the automated agent by an entity associated with the objective.


Owner:MICROSOFT TECHNOLOGY LICENSING LLC
Apparatuses for encoding and decoding a sequence of integer values, methods for encoding and decoding a sequence of integer values and computer program for implementing these methods
ActiveUS12431916B2Code conversionDigital video signal modificationAlgorithmTheoretical computer science

Owner:FRAUNHOFER GESELLSCHAFT ZUR FORDERUNG DER ANGEWANDTEN FORSCHUNG EV
Neural network large model efficient reasoning method based on multiple GPGPUs
ActiveCN121722544AResource allocationInterprogram communicationPerformance computingOverhead (computing)
The invention belongs to the technical field of artificial intelligence and high-performance computing, and particularly relates to a neural network large model efficient reasoning method based on multiple GPGPUs. The method aims to solve the problems of high communication overhead, non-uniform load, low resource utilization rate, high data transmission delay and the like among multiple processors. Dividing a calculation task into a plurality of sub-graphs through static analysis and mixed granularity partitioning of a model calculation graph; distributing the sub-graphs to the optimal GPGPU based on a weighted cost function in combination with heterogeneous resource perception and a dynamic mapping strategy; a global pipeline scheduling plan is constructed by using communication topology perception, and calculation and communication overlap are maximized; data are loaded in advance through a host side hierarchical caching and asynchronous prefetching mechanism, and transmission delay is hidden; multi-stream concurrent execution and event-based lightweight synchronization are adopted on each GPGPU, so that waiting overhead is reduced. According to the method, the reasoning delay can be remarkably reduced, the throughput and the hardware utilization rate are improved, and the method has good adaptivity and expandability.

Owner:BEIJING TOPMOO TECH
Task processing method and related apparatus
PCT designated stageWO2025218290A1Natural language data processingKnowledge representationEngineeringArtificial intelligence
A task processing method, which is applied to the field of artificial intelligence (AI). In the task processing method, a corresponding token is added before a prompt on the basis of a task type, and the added token can be converted into a corresponding vector, so that knowledge strongly related to a task can be added on the basis of a task input, thereby improving the precision of model output results. In addition, for different types of tasks, it is only necessary to add corresponding tokens for the different types of tasks and add into a target word vector table vectors that correspond to the tokens, so that the precision of models in processing various types of tasks can be improved, and it is not necessary to adjust weight parameters of the models themselves, thereby achieving isolation between different tasks, and thus ensuring that the models can process different types of tasks in batches.

Owner:HUAWEI TECH CO LTD
GPU cluster scheduling strategy optimization system based on deep reinforcement learning
The invention discloses a GPU cluster scheduling strategy optimization system based on deep reinforcement learning, which comprises a simulation environment layer, a reinforcement learning layer and a strategy evaluation layer, and is characterized in that the simulation environment layer is used for providing a real and credible GPU cluster scheduling environment, reproducing a core mechanism of actual cluster scheduling and simultaneously providing controllable experiment conditions; comparative evaluation and iterative optimization of strategies are facilitated; the reinforcement learning layer converts a GPU cluster scheduling problem into a Markov decision process based on a deep neural network, and obtains an optimal scheduling strategy by applying a reinforcement learning strategy; and the strategy evaluation layer counts each key index, compares and analyzes a plurality of scheduling strategies, and visually displays an analysis result to realize optimization of the GPU cluster scheduling strategy. The system solves the time sequence short view problem of a traditional scheduler, so that the scheduling decision can consider the influence on the future, global optimization instead of local optimization is realized, and the overall resource utilization efficiency is improved.

Owner:UNIV OF SCI & TECH OF CHINA
Neural network using dynamically compressed and decompressed weights
A method for training or performing inference using a neural network involves performing per-layer decompression and compression of neural network weights. More particularly, compressed weights are retrieved for a particular layer of the neural network. The weights correspond to neurons in the layer. The compressed weights are decompressed, and input data for that layer is subsequently processed using the decompressed weights. This dynamic decompression and recompression of weights allows memory, and in particular random access memory of graphical processing units, to be efficiently used.

Owner:ROYAL BANK OF CANADA
Neural network trajectory prediction

Owner:NVIDIA CORP
User Behavior Modeling for Detecting and Containing Malicious Activity in a Storage System
An illustrative method includes monitoring operations performed with respect to a storage system by an entity using an identity associated with a particular role, the particular role providing the entity with a set of permissions associated with the storage system; determining, based on the monitoring, that one or more operations of the operations deviate from an expected activity profile associated with the role by more than a threshold; and performing, based on the determining that the one or more operations deviate from the expected activity by more than the threshold, a remedial action with respect to the entity.

Owner:PURE STORAGE INC
Techniques for tensor memory allocation
ActiveUS12423007B1Input/output to record carriersKnowledge representationAlgorithmTheoretical computer science
Apparatuses, systems, and techniques to generate a memory allocation plan for a set of tensors. In at least one embodiment, tensor data corresponding to the set of tensors is stored into memory locations at run time based, at least in part, on the memory allocation plan generated at a compile time.

Owner:NVIDIA CORP
Multi-thread low-power-consumption intelligent monitoring system based on AI processor
The invention relates to the technical field of intelligent monitoring, in particular to a multi-thread low-power-consumption intelligent monitoring system based on an AI processor. The method has the advantages that aiming at the problems of unbalanced computing power and power consumption, high multi-task processing delay and strong hardware dependence in the prior art, the NPU module of the RK3588 processor is combined with the INT8 quantitative model, so that the power consumption is lower than 10W under the 6TOPS computing power; a dynamic multi-thread scheduling mechanism is designed, parallel processing of more than eight paths of video streams is supported through binding of a priority queue and an NPU core, and end-to-end delay is compressed to be within 200 ms; a zero-copy video stream architecture is constructed, data transfer is eliminated through memory mapping, and preprocessing time consumption is reduced by 90%; an energy efficiency control module is integrated, the NPU voltage frequency is dynamically adjusted according to the load, and the energy efficiency ratio reaches 0.83 TOPS / W; space-time alignment of multi-model reasoning results is realized by adopting a frame ID synchronization technology, and the mismatching rate is lower than 0.1%.

Owner:FOCALCREST LTD
Gated sparse encoder neural networks
PCT designated stageWO2025226963A1Physical realisationNeural learning methodsAlgorithmNetwork generation
Methods, systems, and apparatuses, including computer programs encoded on computer storage media, for using a gated sparse encoder neural network to generate sparse representations of new inputs to the gated sparse encoder neural network. In particular, the described techniques include receiving a new input, then processing the new input using a magnitude encoder neural and a gating encoder neural network. Then, determining, for each of a set of features, whether the feature is active based on the respective gating value for the feature before generating a sparse representation of the new input that includes the respective feature values for the features that have been determined to be active. The described techniques are useful for improving a neural network's task performance, interpretability, or both by generating sparse representations of inputs using a gated sparse encoder neural network.


Owner:GDM HOLDING LLC
Neural network inference circuit with piecewise linear activation circuit
Some embodiments provide a neural network inference circuit for executing a neural network that includes computation nodes. Each respective computation node of a set of the computation nodes includes (i) a respective linear function that includes a respective dot product of input values for the computation node and weight values for the computation node and (ii) a respective non-linear activation function. The neural network inference circuit includes a set of dot product circuits to compute the dot product for a computation node and a post-processing circuit to compute (i) a result of the linear function for the computation node based on the dot product for the computation node and (ii) an output for the computation node by applying a piecewise linear function to the result of the linear function for the computation node to apply the non-linear activation function for the computation node.

Owner:AMAZON COM SERVICES LLC
Internet-of-things senile disease nursing system supporting equipment state monitoring
The invention discloses an internet-of-things senile disease nursing system supporting equipment state monitoring, and relates to the technical field of internet-of-things senile nursing. An acquisition module realizes multi-index monitoring by using a flexible sensor and a non-invasive technology; the edge computing unit fuses the neuromorphic architecture and federal learning; the equipment monitoring module predicts faults in combination with acoustic emission and thermal imaging technologies; the health assessment engine carries out disease early warning through causal reasoning and a knowledge graph; the early warning system realizes hierarchical response and multi-terminal linkage; and the block chain platform ensures data security and sharing. Through multi-module collaborative innovation, precise collection of elderly health data and real-time monitoring of equipment states are realized, diseases and equipment faults are early warned in advance, an intelligent evaluation engine can predict complications, multi-modal early warning improves response efficiency, a block chain technology guarantees data security, medical resource sharing is supported, and the system is suitable for popularization and application. And the safety, timeliness and intelligent degree of senile disease nursing are comprehensively improved.

Owner:ANHUI ZHENGWEI JIANAN INFORMATION TECHNOLOGY CO LTD