
Patents
Literature
1766 results about "Visual positioning" patented technology
Efficacy Topic
Property
Owner
Technical Advancement
Application Domain
Technology Topic
Technology Field Word
Patent Country/Region
Patent Type
Patent Status
Application Year
Inventor
Laser engraving method and system for automatically correcting coordinates of galvanometer and camera
The invention relates to the technical field of laser engraving, and discloses a laser engraving method and system capable of automatically correcting coordinates of a galvanometer and a camera, and the method comprises the following steps: calculating a target conversion coefficient based on a calibration size and a pixel size of an image collected by the camera, and controlling the galvanometer to perform laser etching on a cross mark on the surface of a PCB (Printed Circuit Board), recording origin data of a galvanometer coordinate system; adjusting the position of the camera to enable the cross center of the view of the camera to coincide with the cross mark, and calculating the coordinate offset; coordinate space transformation is carried out on all the points to be machined, and galvanometer marking coordinate data are obtained; after laser engraving is carried out on the galvanometer marking coordinate data, an engraving area image is collected, the position residual error and the size proportion deviation are calculated, laser engraving is carried out again, and a laser engraving result is obtained. The technical problem that the visual positioning coordinate and the galvanometer marking coordinate in the laser engraving system are not consistent is effectively solved.

Owner:SHENZHEN ZHENHUAXING INTELLIGENT TECH CO LTD
Unmanned aerial vehicle indoor and outdoor seamless navigation method and system integrating Beidou and visual positioning
PendingCN121026146ANavigational calculation instrumentsNavigation by speed/acceleration measurementsObservation dataUncrewed vehicle
The invention relates to the technical field of unmanned aerial vehicle navigation and control, and discloses an unmanned aerial vehicle indoor and outdoor seamless navigation method fusing Beidou and visual positioning. Comprising the following steps: S1, synchronously acquiring original observation data of a Beidou satellite navigation system of an unmanned aerial vehicle, an image sequence acquired by a visual sensor and inertial data of an inertial measurement unit; s2, processing the original observation data of the Beidou satellite navigation system to obtain the position of the unmanned aerial vehicle, according to the unmanned aerial vehicle indoor and outdoor seamless navigation method and system fusing Beidou and visual positioning, through a self-adaptive fusion filter module, the fusion weight of the unmanned aerial vehicle and visual positioning is dynamically adjusted according to the Beidou signal quality; smooth transition of indoor and outdoor navigation main sources is achieved, pose jump is effectively avoided, a tight coupling depth fusion algorithm is adopted, the precision and robustness of the system are improved, the continuous and stable flight capacity of the unmanned aerial vehicle in complex indoor and outdoor environments is ensured, and the application scene is expanded.

Owner:QINGDAO CHENGYITONG TECHNOLOGY & TRADE CO LTD
Pathological image visual positioning method and system, equipment and storage medium
The invention provides a pathological image visual positioning method and system, equipment and a storage medium, and belongs to the technical field of image recognition, and the method comprises the steps: extracting visual features based on a target pathological image, and determining a semantic feature vector and a knowledge feature vector based on first text description; the target pathological image is a pathological image to be subjected to target area positioning, and the knowledge feature vector is used for representing knowledge information associated with the content of the target pathological image; fusing the semantic feature vector and the knowledge feature vector to obtain a fused text feature; performing cross-modal fusion on the fused text features and the visual features to obtain fused multi-modal features, and obtaining fusion representation based on the fused multi-modal features; and based on the fusion representation, positioning a target area in the target pathological image through a multi-layer perceptron to obtain position information of a bounding box of the target area. The method can improve the capability of accurately and flexibly positioning the pathological image region level.

Owner:XIEHE HOSPITAL ATTACHED TO TONGJI MEDICAL COLLEGE HUAZHONG SCI & TECH UNIV
Tin ring automatic focusing laser tin soldering fixing and 3D welding spot detecting system
ActiveCN121267295AMetal working apparatusSoldering auxillary devicesVisual recognitionVisual positioning
The invention relates to a tin ring automatic focusing laser soldering tin fixing and 3D welding spot detecting system, and belongs to the technical field of industrial automatic laser processing. The system is characterized in that a tin ring preparation module identifies pins in real time and dynamically optimizes winding parameters through visual positioning and a self-adaptive winding head, and performs defect identification and pre-repair analysis through multispectral imaging; the soldering tin positioning module is used for switching stations through a rotary table, and precise positioning and clamping of a product are realized by combining laser contour sensing and a focusing compensation algorithm; the laser tin soldering module can visually identify tin materials and automatically call welding parameters, laser power and action time are regulated and controlled in real time by establishing a regional heat conduction model, and gradient cooling is implemented after welding; and the 3D detection module adopts dual-mode scanning, constructs a welding spot three-dimensional model based on fusion data, recognizes microcracks through super-resolution processing, and discriminates the welding spot quality. And automation and intellectualization of the whole process from tin ring preparation to welding spot quality detection are achieved.


Owner:YOULI AUTOMATION TECH (SHANGHAI) CO LTD
Virtual actor based on 4D Gaussian splashing and XR and on-site immersive real-time presentation system and method thereof
The invention belongs to the technical field of augmented reality (XR) and computer vision crossing, relates to fusion application in immersive digital performance, and provides a virtual actor reconstruction and immersive presentation system based on 4D Gaussian splash modeling and XR space positioning. The system comprises a set of spherical multi-camera-position high-synchronization camera shooting matrix used for capturing dynamic images of actors; performing dynamic modeling on the multi-angle image through a 4D Gaussian splashing technology, and outputting a virtual actor point cloud model which can be used by XR equipment; vPS visual positioning and an SLAM tracking module are combined, and precise mapping positioning of a performance space is achieved in AR / MR equipment. The method supports the immersive watching of the actor image at the audience end at a 360-degree free visual angle, and realizes the natural presentation of the virtual actor without dead angles and wearing in cooperation with shielding judgment and a real-time rendering engine. The system is widely applicable to on-site entertainment scenes such as immersive theaters, text travel performances, brand activities, concerts and television programs.

Owner:SHANGHAI SHICHEN CULTURAL COMMUNICATION CO LTD
Material weighing and conveying control method and system
The invention discloses a material weighing and conveying control method and system, and relates to the technical field of self-adaptive control systems. The method comprises the following steps: setting a visual positioning identifier in an unloading area, and configuring an identification code for a material; establishing an information management database, associating the identification codes of the materials with material attributes, and generating a material association attribute table; collecting an identification code of the material, and calling a material association attribute table based on the identification code; and based on the information management database, obtaining a production line state table of each production line and a warehouse state table of the current warehouse, generating a candidate transportation list, determining a comprehensive priority score of each candidate transportation target point, and selecting the candidate transportation target point with the highest score as a final transportation target point. Compared with the prior art in which fixed rules are used for scheduling, the material transportation targets can be dynamically distributed according to real-time production requirements, manual intervention is avoided, the logistics efficiency is improved, high-requirement materials are preferentially distributed, and production interruption caused by material shortage is prevented.

Owner:TIANJIN SHINHOO FOOD CO LTD
Red tide anomaly detection method and system based on improved multi-mode Transform
ActiveCN120913074ACharacter and pattern recognitionBiological modelsAnomaly detectionFeature learning
The invention relates to the technical field of red tide anomaly detection, in particular to a red tide anomaly detection method and system based on an improved multi-mode Transform. The method comprises the following steps: acquiring a remote sensing image and text data; respectively carrying out data preprocessing according to the obtained remote sensing image and text data; performing visual positioning and text selection based on the preprocessed data; performing cross-modal feature learning on the basis of a hierarchical Transform of a multi-modal capsule mechanism; guiding an attention mechanism based on a semantic path to carry out image-semantic feature alignment optimization; and carrying out multi-modal knowledge distillation on the optimized features. According to the method, an image and text preprocessing module, a visual positioning module, a keyword extraction module and other modules are combined, multi-angle accurate perception of a complex red tide scene is achieved, and the bottleneck that a red tide area is difficult to accurately recognize under the condition that data are single and information dimensions are limited in a traditional method is broken through.

Owner:SHANDONG MARINE RESOURCE AND ENVIRONMENT RESEARCH INSTITUTE (SHANDONG MARINE ENVIRONMENTAL MONITORING CENTER SHANDONG AQUATIC PRODUCTS QUALITY INSPECTION CENTER)
Multi-modal multi-scale retrieval enhancement generation method, system and equipment applied to external knowledge questions and answers and medium
PendingCN121765049ACharacter and pattern recognitionText database indexingPattern recognitionLinguistic model
The invention discloses a multi-modal multi-scale retrieval enhancement generation method, system and device applied to external knowledge questions and answers and a medium. The method comprises question perception, multi-modal multi-scale query fusion coding, dense recall and answer generation. Analyzing a key query phrase from the question through a fine-tuned instruction language model, and accurately positioning a region of interest corresponding to the phrase in an image by using an open set visual positioning model; multi-source information is compressed and distilled into an optimal query vector through a deep fusion network integrating multi-head self-attention and an information bottleneck theory; executing a maximum inner product search to recall related knowledge; guiding the large language model to synthesize all information to generate a final answer; the system, the equipment and the medium directly perform feature fusion in the vector space based on the method, so that challenges such as information loss and cascading errors caused by a traditional normal form can be effectively dealt with, high correlation and high accuracy of retrieval knowledge are ensured, and accurate and reliable image-text questions and answers are realized.

Owner:XI AN JIAOTONG UNIV
Intelligent bin unblocking method and system based on visual identification and air cannon linkage
The embodiment of the invention provides a warehouse body intelligent unblocking method and system based on visual identification and air cannon linkage, and the method comprises the steps: collecting images in a warehouse in real time through a plurality of high-definition anti-explosion cameras disposed in the warehouse, carrying out the fusion processing of the collected images in the warehouse, and constructing a warehouse three-dimensional dynamic model; based on the warehouse three-dimensional dynamic model, key features are extracted by adopting a neural network; taking the extracted key features as input, analyzing associated parameters through a time sequence of a long-short-term memory network, establishing a congestion cause knowledge base, and labeling congestion types in a classified manner; constructing a congestion risk grading model based on the congestion cause library and a machine learning algorithm; and activating a corresponding air cannon based on the level corresponding to the three-level early warning and a visual positioning matching result, dynamically adjusting injection parameters, and executing unblocking operation according to an optimized time sequence. According to the embodiment of the invention, closed-loop intelligence from visual perception, reason modeling, artificial intelligence decision making to accurate execution is constructed.

Owner:XIAN THERMAL POWER RES INST CO LTD
Omnidirectional vision positioning system and method and unmanned aerial vehicle
PendingCN121089720ANavigational calculation instrumentsNavigation by speed/acceleration measurementsEngineeringOmnidirectional vision
The invention belongs to the technical field of unmanned aerial vehicles, and provides an omni-directional vision positioning system and method and an unmanned aerial vehicle, the omni-directional vision positioning system is installed on a fuselage of the unmanned aerial vehicle, and the omni-directional vision positioning system comprises an image acquisition device used for acquiring a real-time scene image in an omni-directional range in the flight process of the unmanned aerial vehicle; the inertial measurement sensor is connected with the image acquisition equipment and is used for synchronously acquiring motion state data of the unmanned aerial vehicle; the navigation system is connected with the image acquisition equipment and the inertial measurement sensor and is configured to execute at least one of distortion correction processing and feature extraction processing on the real-time scene image to obtain a processed image; and according to the motion state data and the processed image, determining current pose information of the unmanned aerial vehicle in a space coordinate system constructed by taking a take-off point of the unmanned aerial vehicle as an original point. The positioning precision and robustness of the unmanned aerial vehicle in a complex environment are improved, and the requirement of high-precision autonomous flight is met.

Owner:CHINA GENERAL NUCLEAR POWER OPERATION
Multi-modal remote sensing visual positioning method and device based on scene knowledge enhancement and medium
The invention discloses a multi-modal remote sensing visual positioning method and device based on scene knowledge enhancement and a medium, and relates to the technical field of remote sensing visual positioning. The method comprises the following steps: firstly, preprocessing a plurality of remote sensing images, generating scene knowledge enhanced text description, forming a visual positioning data set, and dividing the visual positioning data set into a training set, a verification set and a test set; constructing a visual positioning model, and obtaining an optimal model through training, verification and testing; inputting a to-be-queried text to obtain remote sensing image coordinates. According to the method, cross-modal fusion of knowledge enhancement is realized, scene knowledge is embedded into a visual positioning framework, and the problem of inference of implicit semantics in a remote sensing scene is solved; multi-scale image features and scene knowledge are fused layer by layer through multi-round cross-modal attention iteration, and semantic understanding from coarse granularity to fine granularity is achieved; a similarity threshold is introduced to screen a high-correlation image region, and background interference is reduced in combination with loss constraints. The LLaMA2 is subjected to efficient fine tuning in combination with the LoRA technology, end-to-end coordinate generation is supported, and both performance and calculation efficiency are considered.

Owner:WUHAN UNIV
Image local enhancement super-resolution method based on text prompt
The invention relates to the technical field of image processing, in particular to an image local enhancement super-resolution method based on text prompt. According to the technical scheme, the method comprises the steps of obtaining a low-resolution image and a text prompt provided by a user; and inputting the low-resolution image and the text prompt into a visual positioning model to generate a region-of-interest mask which is used for identifying the position of a target region corresponding to the text prompt in the image. According to the invention, the visual positioning model is driven to automatically identify the region of interest of the image through text prompt, fine reconstruction branches are configured for the region of interest, lightweight reconstruction branches are configured for the background, and global visual consistency is guaranteed in combination with the fusion module, so that the readability and the identifiability of details of the region of interest are remarkably improved; the method is advantaged in that accurate requirements of intelligent monitoring, document OCR, medical image and other scenes are satisfied, calculation resource distribution is substantially optimized, calculation power waste of a background area is avoided, and image super-resolution efficiency and practicality are improved.

Owner:INST OF ENERGY HEFEI COMPREHENSIVE NAT SCI CENT (ANHUI ENERGY LAB)
Intelligent hand-eye calibration and adaptive correction system and method
The invention relates to the field of robot vision positioning, and discloses an intelligent hand-eye calibration and self-adaptive correction system and method. According to the method, a mechanical arm is controlled to drive a camera to collect multi-modal calibration data, a convolutional neural network is utilized to identify a calibration plate mark point, and a three-dimensional coordinate under a camera coordinate system is calculated in combination with depth information; meanwhile, on the basis of an encoder and torque data, flexible deformation of the mechanical arm is compensated through a kinematic model and a self-adaptive rigidity model, and three-dimensional coordinates under a base coordinate system are obtained. And obtaining a hand-eye transformation matrix by solving a transformation relation between the two point sets. And repeatedly calibrating before and after operation, inputting the difference of the two transformation matrixes into the fault diagnosis neural network, outputting fault type probability distribution, and generating a maintenance strategy. According to the invention, high-precision hand-eye calibration, automatic compensation of flexible deformation and intelligent diagnosis of system state change can be realized, so that the long-term precision and reliability of a visual positioning system are improved.

Owner:SHANGHAI DALI ROBOT TECHNOLOGY CO LTD
Multi-source information fusion robot positioning method and system for unstructured environment
PendingCN114689037AAchieve tight couplingGuaranteed stable operationNavigational calculation instrumentsNavigation by speed/acceleration measurementsSevere weatherEngineering
According to the multi-source information fusion robot positioning method and system for the unstructured environment provided by the invention, fusion processing is carried out on multi-source information data such as laser point cloud, environment image information and acceleration which are acquired in real time, so that the multi-source information fusion robot positioning method and system for the unstructured environment can be realized in a severe weather state and a dynamic unstructured environment. Carrying out high-robustness real-time positioning under the condition of violent illumination change; in a geometrically degraded roadway area, registration positioning of laser point cloud emission fails due to lack of enough external characteristics, and at the moment, the visual positioning module can still work normally and complete robot repositioning by detecting matched image information; in an environment lacking enough illumination, the laser point cloud and acceleration information can still provide enough positioning fusion data input for the computing unit.
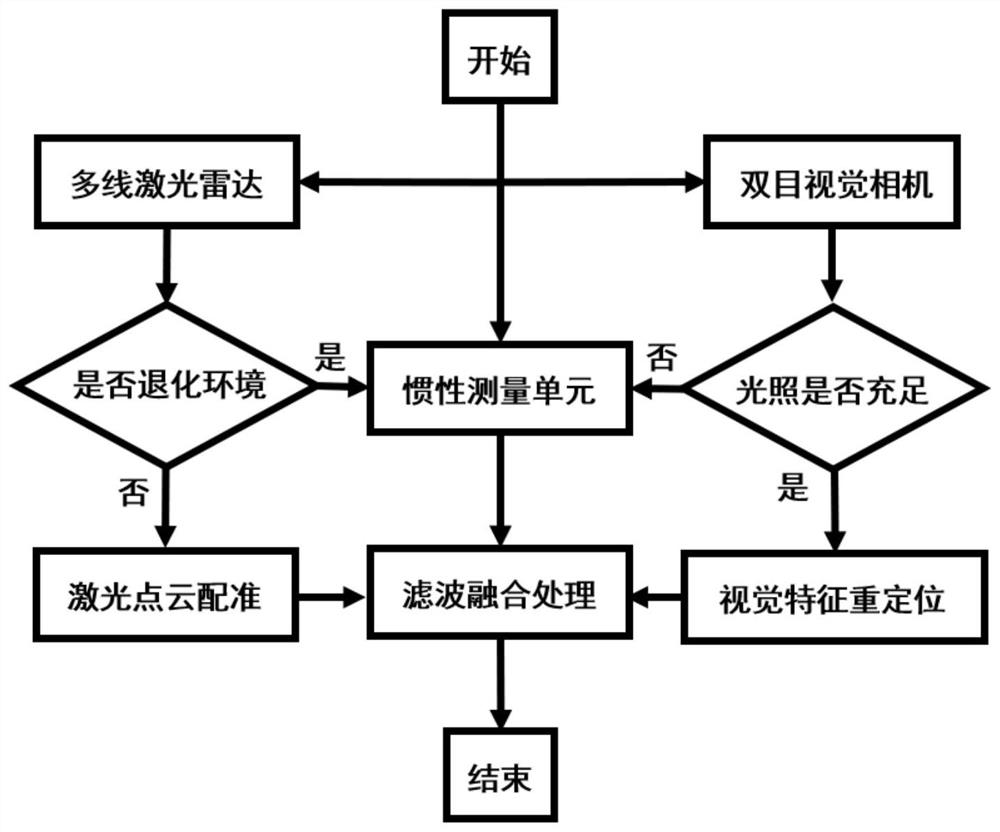
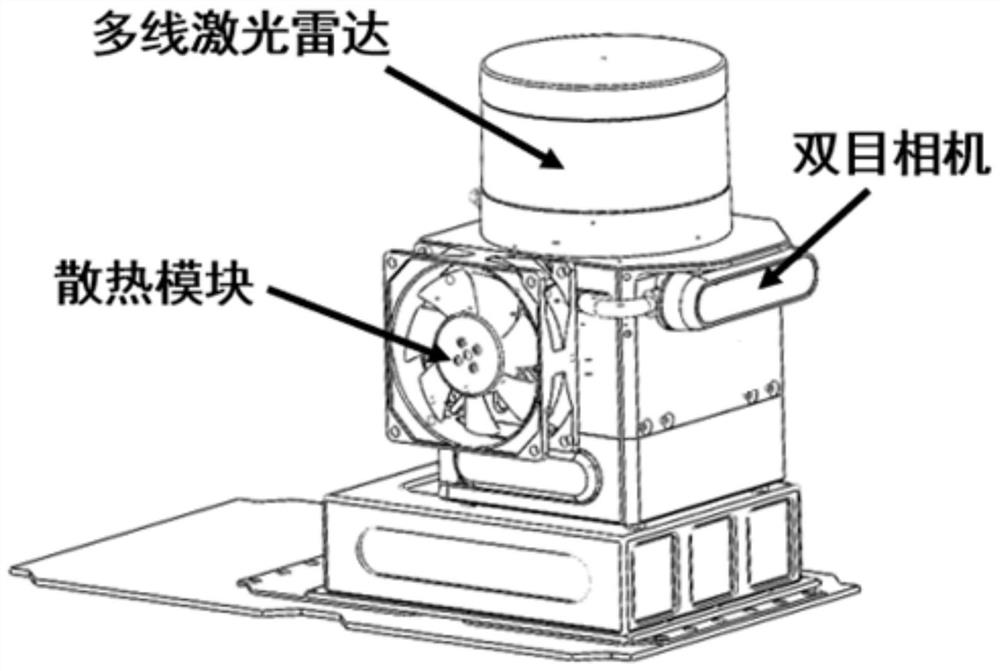
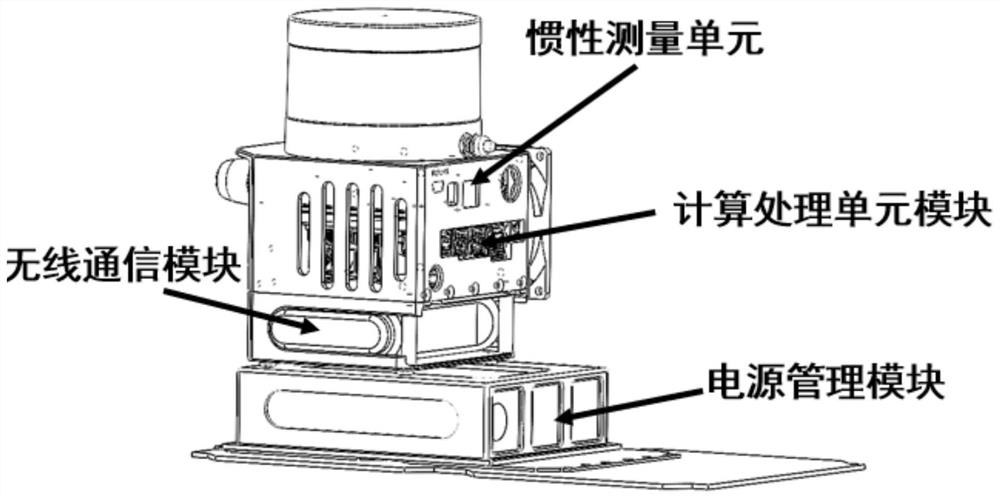
Owner:SHANDONG YOUBAOTE INTELLIGENT ROBOTICS CO LTD
Manipulator cross-modal sensing control system for chemical emergency disposal
The invention relates to the technical field of mechanical arms, in particular to a chemical emergency disposal-oriented manipulator cross-modal sensing control system which comprises an environment scanning module, a visual positioning module, an obstacle avoidance planning module, a pose compensation module, a decision mapping module and a grabbing updating module. Obtaining environment state information; an operation view angle image of the manipulator is collected, visual features of the operation view angle image are solved, and pose information is obtained; obstacle avoidance correction is conducted on the motion trail of the mechanical arm, and a collision-free approaching path is obtained; the operation view angle image and the multi-mode micro-touch signal are fused, error compensation is carried out on the pose information, and an accurate grabbing pose is obtained; mapping object surface physical attributes sensed by the multi-mode micro-tactile signals to obtain a self-adaptive grabbing instruction; the manipulator is controlled to conduct grabbing through the self-adaptive grabbing instruction, and environment state information is updated; according to the invention, the accuracy of cross-modal sensing control of the manipulator can be improved.

Owner:HULUNBEIER VOCATIONAL & TECH COLLEGE
Web interface element identification method, system, equipment and medium
The invention discloses a Web interface element recognition method, system and device and a medium, belongs to the technical field of artificial intelligence and Web interface development, and aims to solve the technical problem of how to improve the recognition rate of dynamic elements and CSS hidden elements so as to enable Web interface element positioning to be more accurate. Performing screenshot by using a playwright screenshot function, converting the screenshot into a Base64 coded character string by using a function after the screenshot is completed, inputting the character string and a url into an intelligent agent, calling a DeepSeek-VL2 visual model by the intelligent agent, analyzing the screenshot and outputting identified structured element data; dOM structure analysis: inputting a page url address, and generating DOM structure data by using a DOM analysis function; dOM tree analysis and visual element matching: calling an element matching function, performing visual element and DOM structure matching, and obtaining all successfully matched element data; interface element extraction and positioning generation; and element application.

Owner:INSPUR QILU SOFTWARE IND
Multi-robot dieless forming and laser shock peening combined machining system and method
PendingCN120962353AProgramme-controlled manipulatorOther manufacturing equipments/toolsControl systemMachining system
The invention provides a multi-robot dieless forming and laser shock peening combined machining system and method, and relates to the technical field of manufacturing and machining. A thin-wall workpiece to be machined is placed on a workpiece clamping platform, a central control system controls a vacuum chuck array to generate negative pressure of a corresponding area according to the size and the shape of the workpiece, the central control system introduces a three-dimensional model of the workpiece, the motion trails of a forming robot and a forming and strengthening robot are planned based on the technological requirements of forming and strengthening, and the forming and strengthening process is completed. Determining a sequence area of dieless forming and a corresponding area of laser shock peening; then collaborative processing is carried out, the collaborative processing comprises a forming stage and a strengthening stage, that is, every time a forming robot completes forming of one sub-area, a forming strengthening robot immediately strengthens the sub-area, and the central control system carries out collaborative processing according to the forming precision and strengthening effect fed back by the visual positioning module; and parameters of the subsequent forming area and laser energy of the strengthening area are dynamically corrected till machining of the whole workpiece is completed.

Owner:SHENYANG INST OF AUTOMATION - CHINESE ACAD OF SCI
UWB navigation system and method based on visual feature fusion
ActiveCN121026102ANavigational calculation instrumentsPosition fixationPattern recognitionFruit tree
The invention discloses a UWB navigation system and method based on visual feature fusion, the system comprises a UWB positioning module, a visual perception module, a data fusion processing module and a navigation control module, the UWB positioning module adaptively generates UWB anchor point layout, calculates UWB coordinates in real time, and then obtains UWB positioning data according to fruit tree coverage rate and soil humidity calibration; the visual perception module collects orchard images to recognize fruit trees and obstacles, obtains visual coordinates and corrects the visual coordinates to obtain visual positioning data; the data fusion processing module calculates weights of the UWB positioning data and the visual positioning data, fuses the UWB positioning data and the visual positioning data according to the weights to obtain fusion coordinates, and performs error correction to obtain optimal coordinates; and the navigation control module calculates a target path point according to the optimal coordinate, the obstacle recognition result and the weeding operation path, and controls the weeding robot to run to the target path point. According to the invention, high-precision navigation of the weeding robot in a complex orchard environment is realized.

Owner:HUNAN AGRI UNIV
Visual positioning and grabbing force control method of intelligent manufacturing industry palletizing robot
The invention provides a visual positioning and grabbing force control method for a palletizing robot in the intelligent manufacturing industry, and relates to the technical field of intelligent manufacturing. The multispectral visual positioning module at least comprises a visible light imaging unit, a near-infrared imaging unit and a structured light imaging unit; s2, on the basis of the material three-dimensional information, fitting a material motion track through a motion trend prediction model, and calculating a target grabbing position in advance; through visible light + near infrared + structured light multispectral fusion, the problem of interference of dust and haze on visual positioning is solved, and the positioning error is reduced to be within 1mm in combination with an adaptive weight algorithm; and meanwhile, the grabbing position is calculated in advance through the motion trend prediction model, the dynamic positioning response speed is increased, compared with the prior art, the performance is higher, and the high-speed dynamic stacking requirement is met.

Owner:维徕智能科技东台有限公司
Cross-view fusion multi-person detection and tracking method for outdoor view variety
The invention relates to the technical field of image processing and target tracking, in particular to a cross-view fusion multi-person detection and tracking method for outdoor view variety, which comprises the following steps of: reconstructing a multi-view picture into three-dimensional / BEV space priori under a unified world coordinate, and feeding back the priori to each camera position feature by using space enhancement attention to obtain a consistent and steady multi-person detection result; then, carrying out online iteration updating on the three-dimensional position and posture of the figure in a tracking mode, introducing OKS-3D gating to combine the 2D key point consistency with the BEV spatial distance, and keeping a uniform ID and a continuous track across cameras; the method solves the problem that the prior art cannot effectively meet the requirements of real-time, accurate and stable target detection, tracking and identity association of an outdoor variety in a complex shooting environment, realizes time-space structured output of accurate detection, stable tracking, unified ID and visual positioning, can directly serve for director scheduling and post-production, and is high in practicability. And the overall manufacturing level and quality of the exterior variety are improved.

Owner:LETIAN ZHIZUO (HUNAN) FILM & TELEVISION TECH SERVICE CO LTD
Position self-adaption AI regulation and control method and system for fastener continuous heat treatment
The invention relates to the technical field of crossing of artificial intelligence and intelligent manufacturing, discloses a position self-adaptive AI regulation and control method and system for continuous heat treatment of a fastener, and aims to solve the problems of non-uniform temperature field, high hardness dispersion, increase of quenching cracking rate and the like caused by lack of position perception and dynamic compensation lag in the prior art. According to the method, in-furnace coordinates of fasteners are tracked in real time through a high-speed visual positioning device, a thermal demand prediction neural network model with space-time convolution mixed with a gating circulation unit is constructed in combination with the conveying speed, thermal environment parameters and material characteristics, and an instantaneous thermal power instruction is output; the system comprises a high-speed visual positioning module, a motion state monitoring module, a thermal environment sensing module, a thermal demand prediction module and the like, and drives a high-density partitioned infrared heating array to realize millisecond-level local thermal compensation. According to the method, the temperature deviation of the junction of the temperature zones can be controlled within + / -8 DEG C, the hardness dispersion and the cracking rate are remarkably reduced, and the heat treatment consistency and the finished product yield are improved.

Owner:HANGZHOU XINYAN FASTENER CO LTD
Visual positioning method based on semantic comprehension and attribute distinguishing enhancement
The invention belongs to the technical field of visual positioning, and relates to a visual positioning method based on semantic comprehension and attribute distinguishing enhancement. The framework mainly comprises a feature coding module, a semantic sensitive data enhancement module, a fine-grained attribute guiding module and a multi-stage cross-modal decoder module. Specifically, the feature coding module performs feature coding on an input graph. The semantic sensitive data enhancement module generates a plurality of queries which are consistent with long text semantics by keeping the consistency of spatial relation words in combination with a large language model, so that a training data set for the long text is expanded. The fine-grained attribute guiding module extracts attribute prior information from a text query in combination with a text graph model and an image encoder, constructs a visual feature representation with higher discrimination by using the information guiding model, and generates a target query with attribute difference at the same time.

Owner:DALIAN UNIV OF TECH
Wafer back cutting visual positioning system and positioning method
The invention discloses a wafer back cutting visual positioning system and a positioning method. Comprising a mobile platform, a rotary positioning mechanism, a prism assembly, an image capturing mechanism and a laser generator. A rotary positioning mechanism and prism assemblies are arranged on the mobile platform, and the prism assemblies are arranged on the periphery of the rotary positioning mechanism in the circumferential direction; the prism assembly comprises a prism module, and the prism module moves in the X-axis direction, the Y-axis direction and the Z-axis direction. The rotary positioning mechanism comprises a rotary motor and a ceramic suction cup, the ceramic suction cup is arranged at the output end of the rotary motor, and visual avoiding holes are evenly formed in the ceramic suction cup in the circumferential direction. The image taking mechanism comprises a high-power camera and a back-to-back camera, the two ends of the prism module are arranged opposite to the vision avoiding hole and the back-to-back camera respectively, the high-power camera is used for shooting a wafer back image, and the back-to-back camera shoots a wafer front image through the prism module and obtains the center coordinates of the image. According to the invention, the to-be-cut cutting channel on the back surface of the wafer is positioned.

Owner:SUZHOU HAIJIEXING TECH CO LTD
Vision-language model training method and device and related equipment
The invention provides a visual-language model training method and device and related equipment, and the method comprises the steps: constructing a training data set comprising an image-text alignment task, a text-driven visual positioning task and a plain text reasoning task through determining a visual encoder and a heterogeneous language model which form a multi-modal heterogeneous recognition model; carrying out dimension dynamic alignment adaptation on the heterogeneous language model, enabling a parameter architecture of the heterogeneous language model to be matched with a visual feature dimension output by a visual encoder, and carrying out supervision and fine adjustment on the visual-language model by adopting a freezing-unfreezing two-stage training strategy based on a training data set; and performing parameter training on a cross-modal alignment module connected with the visual encoder and the heterogeneous language model so as to obtain a trained visual-language model. According to the training method, time consumed by model training is saved, and the convergence speed is increased. Through dimension dynamic alignment and hierarchical weight mapping, the pre-training language ability is reserved to the maximum extent, the plain text task performance loss is reduced, and disastrous forgetting of the model is avoided.

Owner:AISINO CORPORATION
Highway hazardous chemical substance liquid leakage accident monitoring method and system based on computer vision
ActiveCN120913390ADetection of traffic movementTraffic control supervisionSimulationMonitoring system
The invention discloses a highway hazardous chemical substance liquid leakage accident monitoring method and a highway hazardous chemical substance liquid leakage accident monitoring system based on computer vision. The method comprises the following steps: arranging and installing an identifier configured for hazardous chemical substance vehicle identification on a vehicle for loading and transporting hazardous chemical substances; the identifier comprises an optical identifier configured to be used for improving the visual identification degree of the dangerous goods vehicle and a digital identifier configured to realize encrypted storage and quick reading of vehicle information; on the basis of an existing road monitoring system, a lightweight identification model configured for detecting the states of an optical identifier and a digital identifier in real time is deployed and loaded in the existing road monitoring system; performing visual positioning on the road surface projection pattern through a camera, and calculating the real-time position of the vehicle by combining map coordinates so as to supplement the positioning blind area of the GPS in the tunnel mountain area; accident probability calculation is carried out based on the identification state to determine whether the vehicle is suspected to have an accident; and when the accident is judged to be suspected, triggering an accident response process. And the accident response efficiency is obviously improved.

Owner:CCCC HIGHWAY CONSULTANTS CO LTD +1
Multi-modal large model training method based on position reflection thinking chain
The invention discloses a multi-modal large model training method based on a position reflection thinking chain, and the method comprises the following steps: S1, constructing position reflection type thinking chain data, and associating the position reflection type thinking chain data with the coordinates of a chart visual region through distinguishing the data extraction and logical reasoning steps in the thinking chain; automatically generating position annotation data through drawing code editing, re-rendering verification and image analysis technologies; and S2, training a structured reasoning model, constructing a multi-type instruction data set containing visual positioning and logical reasoning, jointly optimizing generation of answer prediction, position positioning and reasoning steps by adopting a multi-task loss function, and enhancing the perception ability of the model to chart elements through a bounding box reflection mechanism. According to the method, the problems of numerical illusion and lack of visual interaction of the thinking chain due to the fact that an existing model depends on OCR are effectively solved, the chart understanding accuracy and the thinking chain interpretation are improved, and the performance is remarkably superior to that of an existing method on the mainstream basis.

Owner:TSINGHUA SHENZHEN INTERNATIONAL GRADUATE SCHOOL
Intelligent task allocation method based on multi-device state coupling analysis
PendingCN121481072AData processing applicationsTotal factory controlTask completionDistribution control
The invention provides a laser cutting production line task automatic allocation control method based on multi-device state coupling analysis, and belongs to the technical field of intelligent manufacturing and industrial automation. The method comprises the following steps: constructing a dynamic closed-loop control process through a central control scheduling system: receiving a task information packet of an MES; constructing an equipment state vector based on a real-time station state, and introducing a dynamic weight factor set to generate a weighted state vector; performing task triggering judgment through a coupling triggering judgment function in combination with the task dependency graph and historical task records; when the conditions are met, a task instruction is issued to the target station; and feeding back the state and updating the historical record after the task is completed. The invention further relates to AGV intelligent scheduling, visual positioning compensation, process parameter dynamic adjustment, predictive conflict detection, weight self-optimization and the like. According to the method, the production line cooperation efficiency is remarkably improved, manual intervention and system delay are reduced, and the method is suitable for an intelligent laser processing scene in which multiple devices run in parallel.

Owner:WUHAN FARLEY PLASMA CUTTING SYS CO LTD
Hub visual positioning method applied to laser sand opening system
The invention provides a hub visual positioning method applied to a laser sand opening system, and relates to the technical field of automatic sand opening in a hub machining system.The hub visual positioning method comprises the following steps that a visual image of a to-be-positioned hub is obtained, and the target hub type of the to-be-positioned hub is recognized; calling and traversing a hub template database to obtain hub template data corresponding to the target hub type, detecting an actual calibration point of the to-be-positioned hub from the visual image, and obtaining the to-be-positioned hub based on the image coordinates of the actual calibration point, the first template coordinates of the theoretical calibration point, the second template coordinates of the theoretical center point and the structural feature information. Calculating the current attitude deviation of the hub to be positioned; according to the current posture deviation, the rotating platform is controlled to adjust the posture of the to-be-positioned hub; and repeating the steps until the current attitude deviation is smaller than a preset tolerance threshold, and completing positioning. According to the method, extremely high positioning angle precision is achieved, it is ensured that the laser machining track is perfectly matched with the molded surface of the hub, and the sand opening quality is fundamentally guaranteed.

Owner:LANGFANG NORTH TIANYU ELECTROMECHANICAL TECH
Courtyard water pool floating object automatic salvage system based on image recognition
The invention discloses an automatic courtyard pool floating object salvage system based on image recognition, and relates to the technical field of intelligent robots, and the system comprises an image sequence acquisition module which is used for continuously capturing and transmitting an image sequence; the hydrological state sensing module is used for quantifying the dynamic and morphological characteristics of the water surface to obtain an average drift velocity vector and a water surface gradient field; the visual target positioning module is used for detecting a floating object to obtain an apparent two-dimensional coordinate vector; the trajectory fusion prediction module is used for fusing the average drift velocity vector, the water surface gradient field and the apparent two-dimensional coordinate vector, and calculating predicted physical coordinates; and the salvage operation execution module is used for receiving the predicted physical coordinates and driving the mechanical arm to complete salvage operation. According to the method, hydrological perception and visual positioning are fused, visual errors caused by dynamic disturbance of the water surface are corrected, the floating object track is predicted in combination with system delay, salvage operation is innovated from passive following to active interception, and the success rate and efficiency are remarkably improved.

Owner:ANHUI XINMAI TECH CO LTD